Complete Technical Paper Content — Abstractive Summarization Nlp
1. Executive Abstract, Problem Formulation & Background
In machine learning, attention is a method that determines the importance of, or "attends to", each component in a sequence relative to the other components in that sequence. In natural language processing, importance is represented by "soft" weights assigned to each word in a sentence. More generally, attention encodes vectors called token embeddings across a fixed-width sequence that can range from tens to millions of tokens in size. Unlike "hard" weights, which are computed during the backwards training pass, "soft" weights exist only in the forward pass and therefore change with every step of the input. Earlier designs implemented the attention mechanism in a serial recurrent neural network (RNN) language translation system, but a more recent design, namely the transformer, removed the slower sequential RNN and relied more heavily on the faster parallel attention scheme. Inspired by ideas about attention in humans, the attention mechanism was developed to address the weaknesses of using information from the hidden layers of recurrent neural networks. Recurrent neural networks favor information contained in words at the end of a sentence and thus deemed more recent, thereby tending to attenuate the significance and associated predictive weight assigned to information earlier in the sentence. Attention allows a token equal access to any part of a sentence directly, rather than only through the previous state.
Additional surveys of the attention mechanism in deep learning are provided by Niu et al. and Soydaner. The major breakthrough came with self-attention, where each element in the input sequence attends to all others, enabling the model to capture global dependencies. This idea was central to the Transformer architecture, which replaced recurrence with attention mechanisms. As a result, Transformers became the foundation for models like BERT, T5 and generative pre-trained transformers (GPT).
The modern era of machine attention was revitalized by grafting an attention mechanism (Fig 1. orange) to an Encoder-Decoder.
Sometimes, alignment can be multiple-to-multiple. For example, the English phrase look it up corresponds to cherchez-le. Thus, "soft" attention weights work better than "hard" attention weights (setting one attention weight to 1, and the others to 0), as we would like the model to make a context vector consisting of a weighted sum of the hidden vectors, rather than "the best one", as there may not be a best hidden vector.
fast weight programmers, or fast weight controllers (1992). A "slow" neural network outputs the "fast" weights of another neural network through outer products. The slow network learns by gradient descent. It was later renamed as "linearized self-attention". Bahdanau-style attention, also referred to as additive attention, Luong-style attention, which is known as multiplicative attention, Early attention mechanisms similar to modern self-attention were proposed using recurrent neural networks. However, the highly parallelizable self-attention was introduced in 2017 and successfully used in the Transformer model, positional attention and factorized positional attention. For convolutional neural networks, attention mechanisms can be distinguished by the dimension on which they operate, namely: spatial attention, channel attention, or combinations. These variants recombine the encoder-side inputs to redistribute those effects to each target output. Often, a correlation-style matrix of dot products provides the re-weighting coefficients. In the figures below, W is the matrix of context attention weights, similar to the formula in Overview section above.
From the original paper on vision transformers (ViT), visualizing attention scores as a heat map (called saliency maps or attention maps) has become an important and routine way to inspect the decision making process of ViT models. One can compute the attention maps with respect to any attention head at any layer, while the deeper layers tend to show more semantically meaningful visualization. Attention rollout is a recursive algorithm to combine attention scores across all layers, by computing the dot product of successive attention maps. Because vision transformers are typically trained in a self-supervised manner, attention maps are generally not class-sensitive. When a classification head is attached to the ViT backbone, class-discriminative attention maps (CDAM) combines attention maps and gradients with respect to the class [CLS] token. Some class-sensitive interpretability methods originally developed for convolutional neural networks can be also applied to ViT, such as GradCAM, which back-propagates the gradients to the outputs of the final attention layer. Using attention as basis of explanation for the transformers in language and vision is not without debate. While some pioneering papers analyzed and framed attention scores as explanations, higher attention scores do not always correlate with greater impact on model performances.
Attention ( Q , K , V ) = softmax ( Q K T d k ) V ∈ R m × d v {\displaystyle {\text{Attention}}(Q,K,V)={\text{softmax}}\left({\frac {QK^{T}}{\sqrt {d_{k}}}}\right)V\in \mathbb {R} ^{m\times d_{v}}}
T {\displaystyle {}^{T}} denotes transpose and the softmax function is applied independently to every row of its argument. The matrix Q {\displaystyle Q} contains m {\displaystyle m} queries, while matrices K , V {\displaystyle K,V} jointly contain an unordered set of n {\displaystyle n} key-value pairs. Value vectors in matrix V {\displaystyle V} are weighted using the weights resulting from the softmax operation, so that the rows of the m {\displaystyle m} -by- d v {\displaystyle d_{v}} output matrix are confined to the convex hull of the points in R d v {\displaystyle \mathbb {R} ^{d_{v}}} given by the rows of V {\displaystyle V} . To understand the permutation invariance and permutation equivariance properties of QKV attention, let A ∈ R m × m {\displaystyle A\in \mathbb {R} ^{m\times m}} and B ∈ R n × n {\displaystyle B\in \mathbb {R} ^{n\times n}} be permutation matrices; and D ∈ R m × n {\displaystyle D\in \mathbb {R} ^{m\times n}} an arbitrary matrix. The softmax function is permutation equivariant in the sense that:
softmax ( A D B ) = A softmax ( D ) B {\displaystyle {\text{softmax}}(ADB)=A\,{\text{softmax}}(D)B}
Attention ( A Q , B K , B V ) = A Attention ( Q , K , V ) {\displaystyle {\text{Attention}}(AQ,BK,BV)=A\,{\text{Attention}}(Q,K,V)}
which shows that QKV attention is equivariant with respect to re-ordering the queries (rows of Q {\displaystyle Q} ); and invariant to re-ordering of the key-value pairs in K , V {\displaystyle K,V} . These properties are inherited when applying linear transforms to the inputs and outputs of QKV attention blocks. For example, a simple self-attention function defined as:
X ↦ Attention ( X T q , X T k , X T v ) {\displaystyle X\mapsto {\text{Attention}}(XT_{q},XT_{k},XT_{v})} is permutation equivariant with respect to re-ordering the rows of the input matrix X {\displaystyle X} in a non-trivial way, because every row of the output is a function of all the rows of the input. Similar properties hold for multi-head attention, which is defined below.
Attention ( Q , K , V ) = softmax ( Q K T d k + M ) V {\displaystyle {\text{Attention}}(Q,K,V)={\text{softmax}}\left({\frac {QK^{T}}{\sqrt {d_{k}}}}+M\right)V}
where the mask, M ∈ { 0 , − ∞ } n × n {\displaystyle M\in \mathbb {\{0,-\infty \}} ^{n\times n}} is a strictly upper triangular matrix, with zeros on and below the diagonal and − ∞ {\displaystyle -\infty } in every element above the diagonal. The softmax output, in R n × n {\displaystyle \mathbb {R} ^{n\times n}} is then lower triangular, with zeros in all elements above the diagonal. The masking ensures that for all 1 ≤ i < j ≤ n {\displaystyle 1\leq i<j\leq n} , row i {\displaystyle i} of the attention output is independent of row j {\displaystyle j} of any of the three input matrices. The permutation invariance and equivariance properties of standard QKV attention do not hold for the masked variant.
MultiHead ( Q , K , V ) = Concat ( head 1 , . . . , head h ) W O {\displaystyle {\text{MultiHead}}(Q,K,V)={\text{Concat}}({\text{head}}_{1},...,{\text{head}}_{h})W^{O}}
head i = Attention ( Q W i Q , K W i K , V W i V ) {\displaystyle {\text{head}}_{i}={\text{Attention}}(QW_{i}^{Q},KW_{i}^{K},VW_{i}^{V})}
and W i Q , W i K , W i V {\displaystyle W_{i}^{Q},W_{i}^{K},W_{i}^{V}} , and W O {\displaystyle W^{O}} are parameter matrices. The permutation properties of (standard, unmasked) QKV attention apply here also. For permutation matrices, A , B {\displaystyle A,B} :
2. Related Work, Literature Survey & Algorithmic Foundations
MultiHead ( A Q , B K , B V ) = A MultiHead ( Q , K , V ) {\displaystyle {\text{MultiHead}}(AQ,BK,BV)=A\,{\text{MultiHead}}(Q,K,V)}
X ↦ MultiHead ( X T q , X T k , X T v ) {\displaystyle X\mapsto {\text{MultiHead}}(XT_{q},XT_{k},XT_{v})} is equivariant with respect to re-ordering of the rows of input matrix X {\displaystyle X} .
Attention ( Q , K , V ) = softmax ( tanh ( W Q Q + W K K ) ) V {\displaystyle {\text{Attention}}(Q,K,V)={\text{softmax}}(\tanh(W_{Q}Q+W_{K}K))V}
where W Q {\displaystyle W_{Q}} and W K {\displaystyle W_{K}} are learnable weight matrices.
Attention ( Q , K , V ) = softmax ( Q W K T ) V {\displaystyle {\text{Attention}}(Q,K,V)={\text{softmax}}(QWK^{T})V}
where W {\displaystyle W} is a learnable weight matrix.
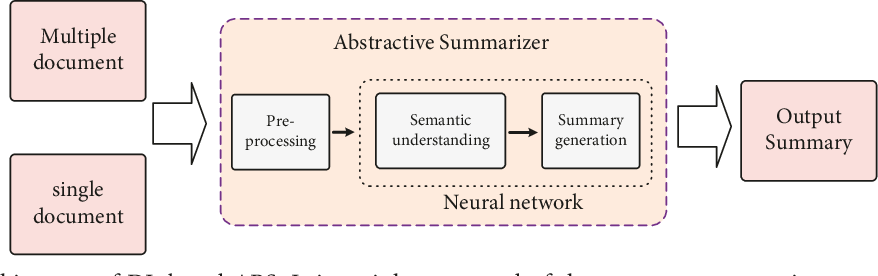
Automatic summarization is the process of shortening a set of data computationally, to create a subset (a summary) that represents the most important or relevant information within the original content. Artificial intelligence (AI) algorithms are commonly developed and employed to achieve this, specialized for different types of data. Text summarization is usually implemented by natural language processing methods, designed to locate the most informative sentences in a given document. On the other hand, visual content can be summarized using computer vision algorithms. Image summarization is the subject of ongoing research; existing approaches typically attempt to display the most representative images from a given image collection, or generate a video that only includes the most important content from the entire collection. Video summarization algorithms identify and extract from the original video content the most important frames (key-frames), and/or the most important video segments (key-shots), normally in a temporally ordered fashion. Video summaries simply retain a carefully selected subset of the original video frames and, therefore, are not identical to the output of video synopsis algorithms, where new video frames are being synthesized based on the original video content.
"The Army Corps of Engineers, rushing to meet President Bush's promise to protect New Orleans by the start of the 2006 hurricane season, installed defective flood-control pumps last year despite warnings from its own expert that the equipment would fail during a storm, according to documents obtained by The Associated Press". A keyphrase extractor might select "Army Corps of Engineers", "President Bush", "New Orleans", and "defective flood-control pumps" as keyphrases. These are pulled directly from the text. In contrast, an abstractive keyphrase system would somehow internalize the content and generate keyphrases that do not appear in the text, but more closely resemble what a human might produce, such as "political negligence" or "inadequate protection from floods". Abstraction requires a deep understanding of the text, which makes it difficult for a computer system. Keyphrases have many applications. They can enable document browsing by providing a short summary, improve information retrieval (if documents have keyphrases assigned, a user could search by keyphrase to produce more reliable hits than a full-text search), and be employed in generating index entries for a large text corpus. Depending on the different literature and the definition of key terms, words or phrases, keyword extraction is a highly related theme.
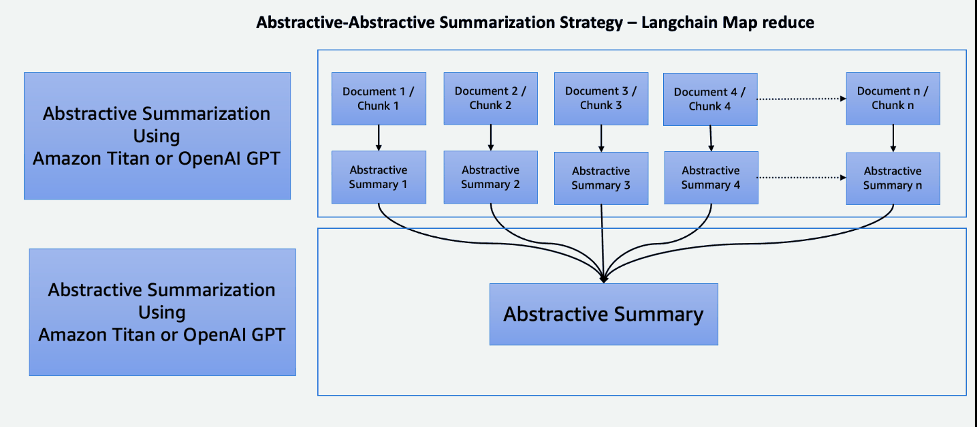
Multi-document summarization is an automatic procedure aimed at extraction of information from multiple texts written about the same topic. Resulting summary report allows individual users, such as professional information consumers, to quickly familiarize themselves with information contained in a large cluster of documents. In such a way, multi-document summarization systems are complementing the news aggregators performing the next step down the road of coping with information overload. Multi-document summarization may also be done in response to a question. Multi-document summarization creates information reports that are both concise and comprehensive. With different opinions being put together and outlined, every topic is described from multiple perspectives within a single document. While the goal of a brief summary is to simplify information search and cut the time by pointing to the most relevant source documents, comprehensive multi-document summary should itself contain the required information, hence limiting the need for accessing original files to cases when refinement is required. Automatic summaries present information extracted from multiple sources algorithmically, without any editorial touch or subjective human intervention, thus making it completely unbiased.
Submodular Functions have also been used for other summarization tasks. Tschiatschek et al., 2014 show that mixtures of submodular functions achieve state-of-the-art results for image collection summarization. Similarly, Bairi et al., 2015 show the utility of submodular functions for summarizing multi-document topic hierarchies. Submodular Functions have also successfully been used for summarizing machine learning datasets.
The Reddit bot "autotldr", created in 2011 summarizes news articles in the comment-section of reddit posts. It was found to be very useful by the reddit community which upvoted its summaries hundreds of thousands of times. The name is reference to TL;DR − Internet slang for "too long; didn't read". Adversarial stylometry may make use of summaries, if the detail lost is not major and the summary is sufficiently stylistically different to the input.
Automatic summarization has been extended to audio content such as podcasts, where systems combine speech recognition, large language model summarization, and speech synthesis to produce condensed narrated audio summaries of full-length episodes. Automatic summarization is increasingly applied in enterprise environments, where tools such as Microsoft 365 Copilot and Google Workspace use large language model-based summarization to generate meeting recaps, email digests, and document abstracts, to help knowledge workers manage information overload.
Highlight clips: Short sequences featuring high-impact events such as eliminations, goals, or clutch plays. Match recaps: Condensed summaries of full gameplay sessions, preserving key moments in chronological order. Instructional clips: Segments that capture specific techniques, strategies, or decision-making patterns for educational purposes.
mathsyouth / awesome-text-summarization Star 1.5k A curated list of resources dedicated to text summarization nlp machine-learning natural-language-processing text-mining deep-learning extractive-text-summarization abstractive-text-summarization Updated Jan 9, 2023
yaserkl / RLSeq2Seq Star 767 Deep Reinforcement Learning For Sequence to Sequence Models nlp reinforcement-learning policy-gradient actor-critic abstractive-text-summarization pointer-generator Updated Mar 24, 2023 Python
theamrzaki / text_summurization_abstractive_methods Star 529 Multiple implementations for abstractive text summurization , using google colab nlp machine-learning reinforcement-learning ai deep-learning tensorflow word2vec artificial-intelligence policy-gradient rnn text-summarization seq2seq machinelearning deeplearning encoder-decoder abstractive-text-summarization google-colab pointer-generator google-colaboratory Updated Oct 6, 2020 Jupyter Notebook
santhoshkolloju / Abstractive-Summarization-With-Transfer-Learning Star 411 Abstractive summarisation using Bert as encoder and Transformer Decoder nlp transformer summarization transfer-learning nlg bert abstractive-text-summarization abstractive-summarization bert-model Updated May 30, 2023 Python
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
csebuetnlp / xl-sum Star 279 This repository contains the code, data, and models of the paper titled "XL-Sum: Large-Scale Multilingual Abstractive Summarization for 44 Languages" published in Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021. multilingual machine-learning deep-learning dataset text-summarization abstractive-text-summarization abstractive-summarization text-summarisation low-resource-languages multilinguality summarization-corpora summarization-dataset multilingual-text-summarization text-summarization-dataset text-summarization-model low-resource-summarization low-resource-text-summarizarion multilingual-summarization Updated Mar 26, 2024 Python
This repository contains the code, data, and models of the paper titled "XL-Sum: Large-Scale Multilingual Abstractive Summarization for 44 Languages" published in Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021.
JRC1995 / Abstractive-Summarization Star 168 Implementation of abstractive summarization using LSTM in the encoder-decoder architecture with local attention. nlp deep-learning tensorflow lstm attention-mechanism encoder-decoder abstractive-text-summarization local-attention Updated Dec 30, 2019 Jupyter Notebook
Implementation of abstractive summarization using LSTM in the encoder-decoder architecture with local attention.
rojagtap / transformer-abstractive-summarization Star 167 Abstractive Text Summarization using Transformer nlp natural-language-processing deep-learning tensorflow transformers summarization abstractive-text-summarization Updated Dec 2, 2023 Jupyter Notebook
abrazinskas / Copycat-abstractive-opinion-summarizer Star 98 ACL 2020 Unsupervised Opinion Summarization as Copycat-Review Generation data-science machine-learning natural-language-processing deep-learning algorithms amazon reviews yelp vae summarization natural-language-generation abstractive-text-summarization abstractive-summarization opinion-summarization Updated Jul 6, 2023 Python
HHousen / DocSum Star 73 A tool to automatically summarize documents abstractively using the BART or PreSumm Machine Learning Model. python nlp pdf machine-learning xml transformers bart text-summarization summarization xml-parser automatic-summarization abstractive-text-summarization abstractive-summarization Updated Nov 23, 2020 Python
A tool to automatically summarize documents abstractively using the BART or PreSumm Machine Learning Model.
IlyaGusev / gazeta Star 39 Gazeta: Dataset for automatic summarization of Russian news / Газета: набор данных для автоматического реферирования на русском языке machine-learning dataset text-summarization summarization abstractive-text-summarization abstractive-summarization text-summarisation russian-language summarization-corpora summarization-dataset abstractive-summarization-dataset Updated Oct 6, 2021 Python
Gazeta: Dataset for automatic summarization of Russian news / Газета: набор данных для автоматического реферирования на русском языке
rktamplayo / PlanSum Star 33 [AAAI2021] Unsupervised Opinion Summarization with Content Planning sentiment-analysis amazon text-generation reviews yelp opinions text-summarization summarization opinion-mining unsupervised-learning natural-language-generation rotten-tomatoes abstractive-text-summarization abstractive-summarization content-planning opinion-summarization Updated Feb 15, 2022 Python
nc-ai / MultimodalSum Star 25 [ACL-IJCNLP 2021] Self-Supervised Multimodal Opinion Summarization amazon pytorch reviews yelp summarization multi-modal self-supervised abstractive-text-summarization abstractive-summarization multimodal self-supervised-learning opinion-summarization acl2021 Updated Apr 6, 2024 Python
rktamplayo / DenoiseSum Star 21 [ACL2020] Unsupervised Opinion Summarization with Noising and Denoising sentiment-analysis text-generation reviews yelp opinions text-summarization summarization opinion-mining unsupervised-learning natural-language-generation rotten-tomatoes abstractive-text-summarization document-summarization abstractive-summarization opinion-summarization Updated Jul 3, 2020 Python
domyounglee / Transformer-Summarization Star 17 An optimized Transformer based abstractive summarization model with Tensorflow tensorflow transformer summarization abstractive-text-summarization abstractive-summarization transformer-models Updated Oct 17, 2022 Python
Developer-Zer0 / Get-To-The-Point-Summarization-with-Pointer-Generator-Networks Star 15 Pytorch implementation of Get To The Point: Summarization with Pointer-Generator Networks (2017) by Abigail See et al. pytorch abstractive-text-summarization pointer-generator Updated May 16, 2020 Jupyter Notebook
Pytorch implementation of Get To The Point: Summarization with Pointer-Generator Networks (2017) by Abigail See et al.
lipiji / data-summ-cnn_dailymail Star 13 non-anonymized cnn/dailymail dataset for text summarization dataset summarization cnn-dailymail abstractive-text-summarization Updated May 30, 2017 Python
4. Neural Network Backbone, Layer Specifications & Loss Formulations
soni-ratnesh / compendium Star 9 Generates summary of a given news article. Used attention seq2seq encoder decoder model. pytorch gru text-summarization abstractive-text-summarization attention-seq2seq seq2seq-attn torchtext Updated Dec 20, 2024 Jupyter Notebook
Generates summary of a given news article. Used attention seq2seq encoder decoder model.
nikhibdg / Abstractive-Text-Summarization-using-Seq2Seq-RNN Star 7 Abstractiv Text Summarization machine-learning natural-language-processing deep-learning abstractive-text-summarization seq2seq-rnn Updated Apr 24, 2018 Python
sharad461 / nepali-abstractive-summarization Star 7 Abstractive Summarization in the Nepali language data nepali abstractive-text-summarization nepali-nlp Updated Mar 11, 2020 Python
Jaswanth-Devarinti / meeting_summerizer Star 7 Speaker Diarization + Speech to text + abstract summerization speech-to-text speaker-diarization abstractive-text-summarization meeting-summarization Updated Aug 2, 2023 HTML
To associate your repository with the abstractive-text-summarization topic, visit your repo's landing page and select "manage topics."
ChenRocks / fast_abs_rl Star 624 Code for ACL 2018 paper: "Fast Abstractive Summarization with Reinforce-Selected Sentence Rewriting. Chen and Bansal" natural-language-processing reinforcement-learning deep-learning pytorch abstractive-summarization Updated Jul 23, 2020 Python
Code for ACL 2018 paper: "Fast Abstractive Summarization with Reinforce-Selected Sentence Rewriting. Chen and Bansal"
santhoshkolloju / Abstractive-Summarization-With-Transfer-Learning Star 411 Abstractive summarisation using Bert as encoder and Transformer Decoder nlp transformer summarization transfer-learning nlg bert abstractive-text-summarization abstractive-summarization bert-model Updated May 30, 2023 Python
xiongma / transformer-pointer-generator Star 397 A Abstractive Summarization Implementation with Transformer and Pointer-generator nlp tensorflow transformer abstractive-summarization pointer-generator Updated May 21, 2021 Python
EdinburghNLP / XSum Star 378 Topic-Aware Convolutional Neural Networks for Extreme Summarization convolutional-neural-networks abstractive-summarization topic-aware extreme-summarization Updated Jun 20, 2023 Python
ymfa / seq2seq-summarizer Star 358 Pointer-generator reinforced seq2seq summarization in PyTorch coverage reinforcement-learning pytorch summarization seq2seq attention attention-mechanism summarizer pointer-network abstractive-summarization coverage-mechanism Updated Apr 16, 2019 Python
csebuetnlp / xl-sum Star 279 This repository contains the code, data, and models of the paper titled "XL-Sum: Large-Scale Multilingual Abstractive Summarization for 44 Languages" published in Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021. multilingual machine-learning deep-learning dataset text-summarization abstractive-text-summarization abstractive-summarization text-summarisation low-resource-languages multilinguality summarization-corpora summarization-dataset multilingual-text-summarization text-summarization-dataset text-summarization-model low-resource-summarization low-resource-text-summarizarion multilingual-summarization Updated Mar 26, 2024 Python
This repository contains the code, data, and models of the paper titled "XL-Sum: Large-Scale Multilingual Abstractive Summarization for 44 Languages" published in Findings of the Association for Computational Linguistics: ACL-IJCNLP 2021.
lipiji / neural-summ-cnndm-pytorch Star 200 Neural abstractive summarization (seq2seq + copy (or pointer network) + coverage) in pytorch on CNN/Daily Mail pytorch cnn-dailymail abstractive-summarization Updated Apr 19, 2022 Python
Neural abstractive summarization (seq2seq + copy (or pointer network) + coverage) in pytorch on CNN/Daily Mail
cbaziotis / seq3 Star 126 Source code for the NAACL 2019 paper "SEQ^3: Differentiable Sequence-to-Sequence-to-Sequence Autoencoder for Unsupervised Abstractive Sentence Compression" autoencoder summarization seq2seq gumbel-softmax abstractive-summarization sentence-compression seq2seq2seq Updated Jun 21, 2022 Python
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Source code for the NAACL 2019 paper "SEQ^3: Differentiable Sequence-to-Sequence-to-Sequence Autoencoder for Unsupervised Abstractive Sentence Compression"
Huffon / factsumm Star 113 FactSumm: Factual Consistency Scorer for Abstractive Summarization natural-language-processing summarization abstractive-summarization factual-consistency Updated Jan 1, 2024 Python
abrazinskas / Copycat-abstractive-opinion-summarizer Star 98 ACL 2020 Unsupervised Opinion Summarization as Copycat-Review Generation data-science machine-learning natural-language-processing deep-learning algorithms amazon reviews yelp vae summarization natural-language-generation abstractive-text-summarization abstractive-summarization opinion-summarization Updated Jul 6, 2023 Python
luopeixiang / awesome-text-summarization Star 96 Text summarization starting from scratch. nlp text-mining deep-learning text-summarization extractive-summarization papers-collection abstractive-summarization sentence-compression Updated Aug 27, 2024
aj-naik / Text-Summarization Star 86 Abstractive and Extractive Text summarization using Transformers. api flask aws prototype transformers pytorch led bart text-summarization pegasus extractive-summarization bert abstractive-summarization roberta fastapi gpt2 t5 xlnet streamlit longformer Updated Jun 9, 2023 Jupyter Notebook
iwangjian / ByteCup2018 Star 76 Byte Cup 2018 International Machine Learning Contest (3rd prize) abstractive-summarization title-generation Updated Aug 26, 2022 Python
HHousen / DocSum Star 73 A tool to automatically summarize documents abstractively using the BART or PreSumm Machine Learning Model. python nlp pdf machine-learning xml transformers bart text-summarization summarization xml-parser automatic-summarization abstractive-text-summarization abstractive-summarization Updated Nov 23, 2020 Python
A tool to automatically summarize documents abstractively using the BART or PreSumm Machine Learning Model.
amazon-science / fact-graph Star 51 Implementation of the paper "FactGraph: Evaluating Factuality in Summarization with Semantic Graph Representations (NAACL 2022)" abstractive-summarization factuality Updated Jul 26, 2023 Python
Implementation of the paper "FactGraph: Evaluating Factuality in Summarization with Semantic Graph Representations (NAACL 2022)"
CannyLab / summary_loop Star 45 Codebase for the Summary Loop paper at ACL2020 news reinforcement-learning summarization unsupervised-learning abstractive-summarization acl2020 fluency-model Updated Jun 12, 2023 Python
Iwontbecreative / Abstractive-summarization-OpenNMT Star 41 Abstractive summarization leveraging opennmt nlp deep-learning summarization abstractive-summarization Updated Apr 17, 2022 Python
nsi319 / Finetune-Transformers Star 39 Abstractive text summarization by fine-tuning seq2seq models. nlp transformers colab bart transfer-learning pegasus sequence-models abstractive-summarization huggingface t5-model Updated Feb 18, 2021 Python
IlyaGusev / gazeta Star 39 Gazeta: Dataset for automatic summarization of Russian news / Газета: набор данных для автоматического реферирования на русском языке machine-learning dataset text-summarization summarization abstractive-text-summarization abstractive-summarization text-summarisation russian-language summarization-corpora summarization-dataset abstractive-summarization-dataset Updated Oct 6, 2021 Python
Gazeta: Dataset for automatic summarization of Russian news / Газета: набор данных для автоматического реферирования на русском языке
TysonYu / AdaptSum Star 35 The code repository for NAACL 2021 paper "AdaptSum: Towards Low-Resource Domain Adaptation for Abstractive Summarization". paper pytorch summarization abstractive-summarization Updated May 10, 2021 Python
The code repository for NAACL 2021 paper "AdaptSum: Towards Low-Resource Domain Adaptation for Abstractive Summarization".
Model Figures & Evaluation Curves (4 Images)
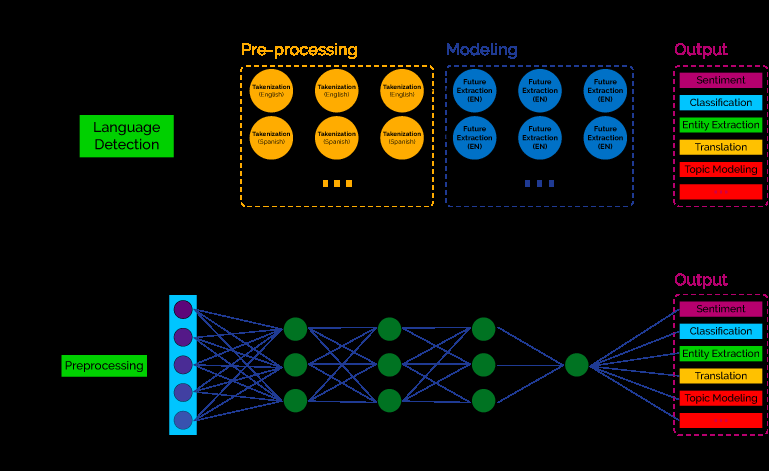
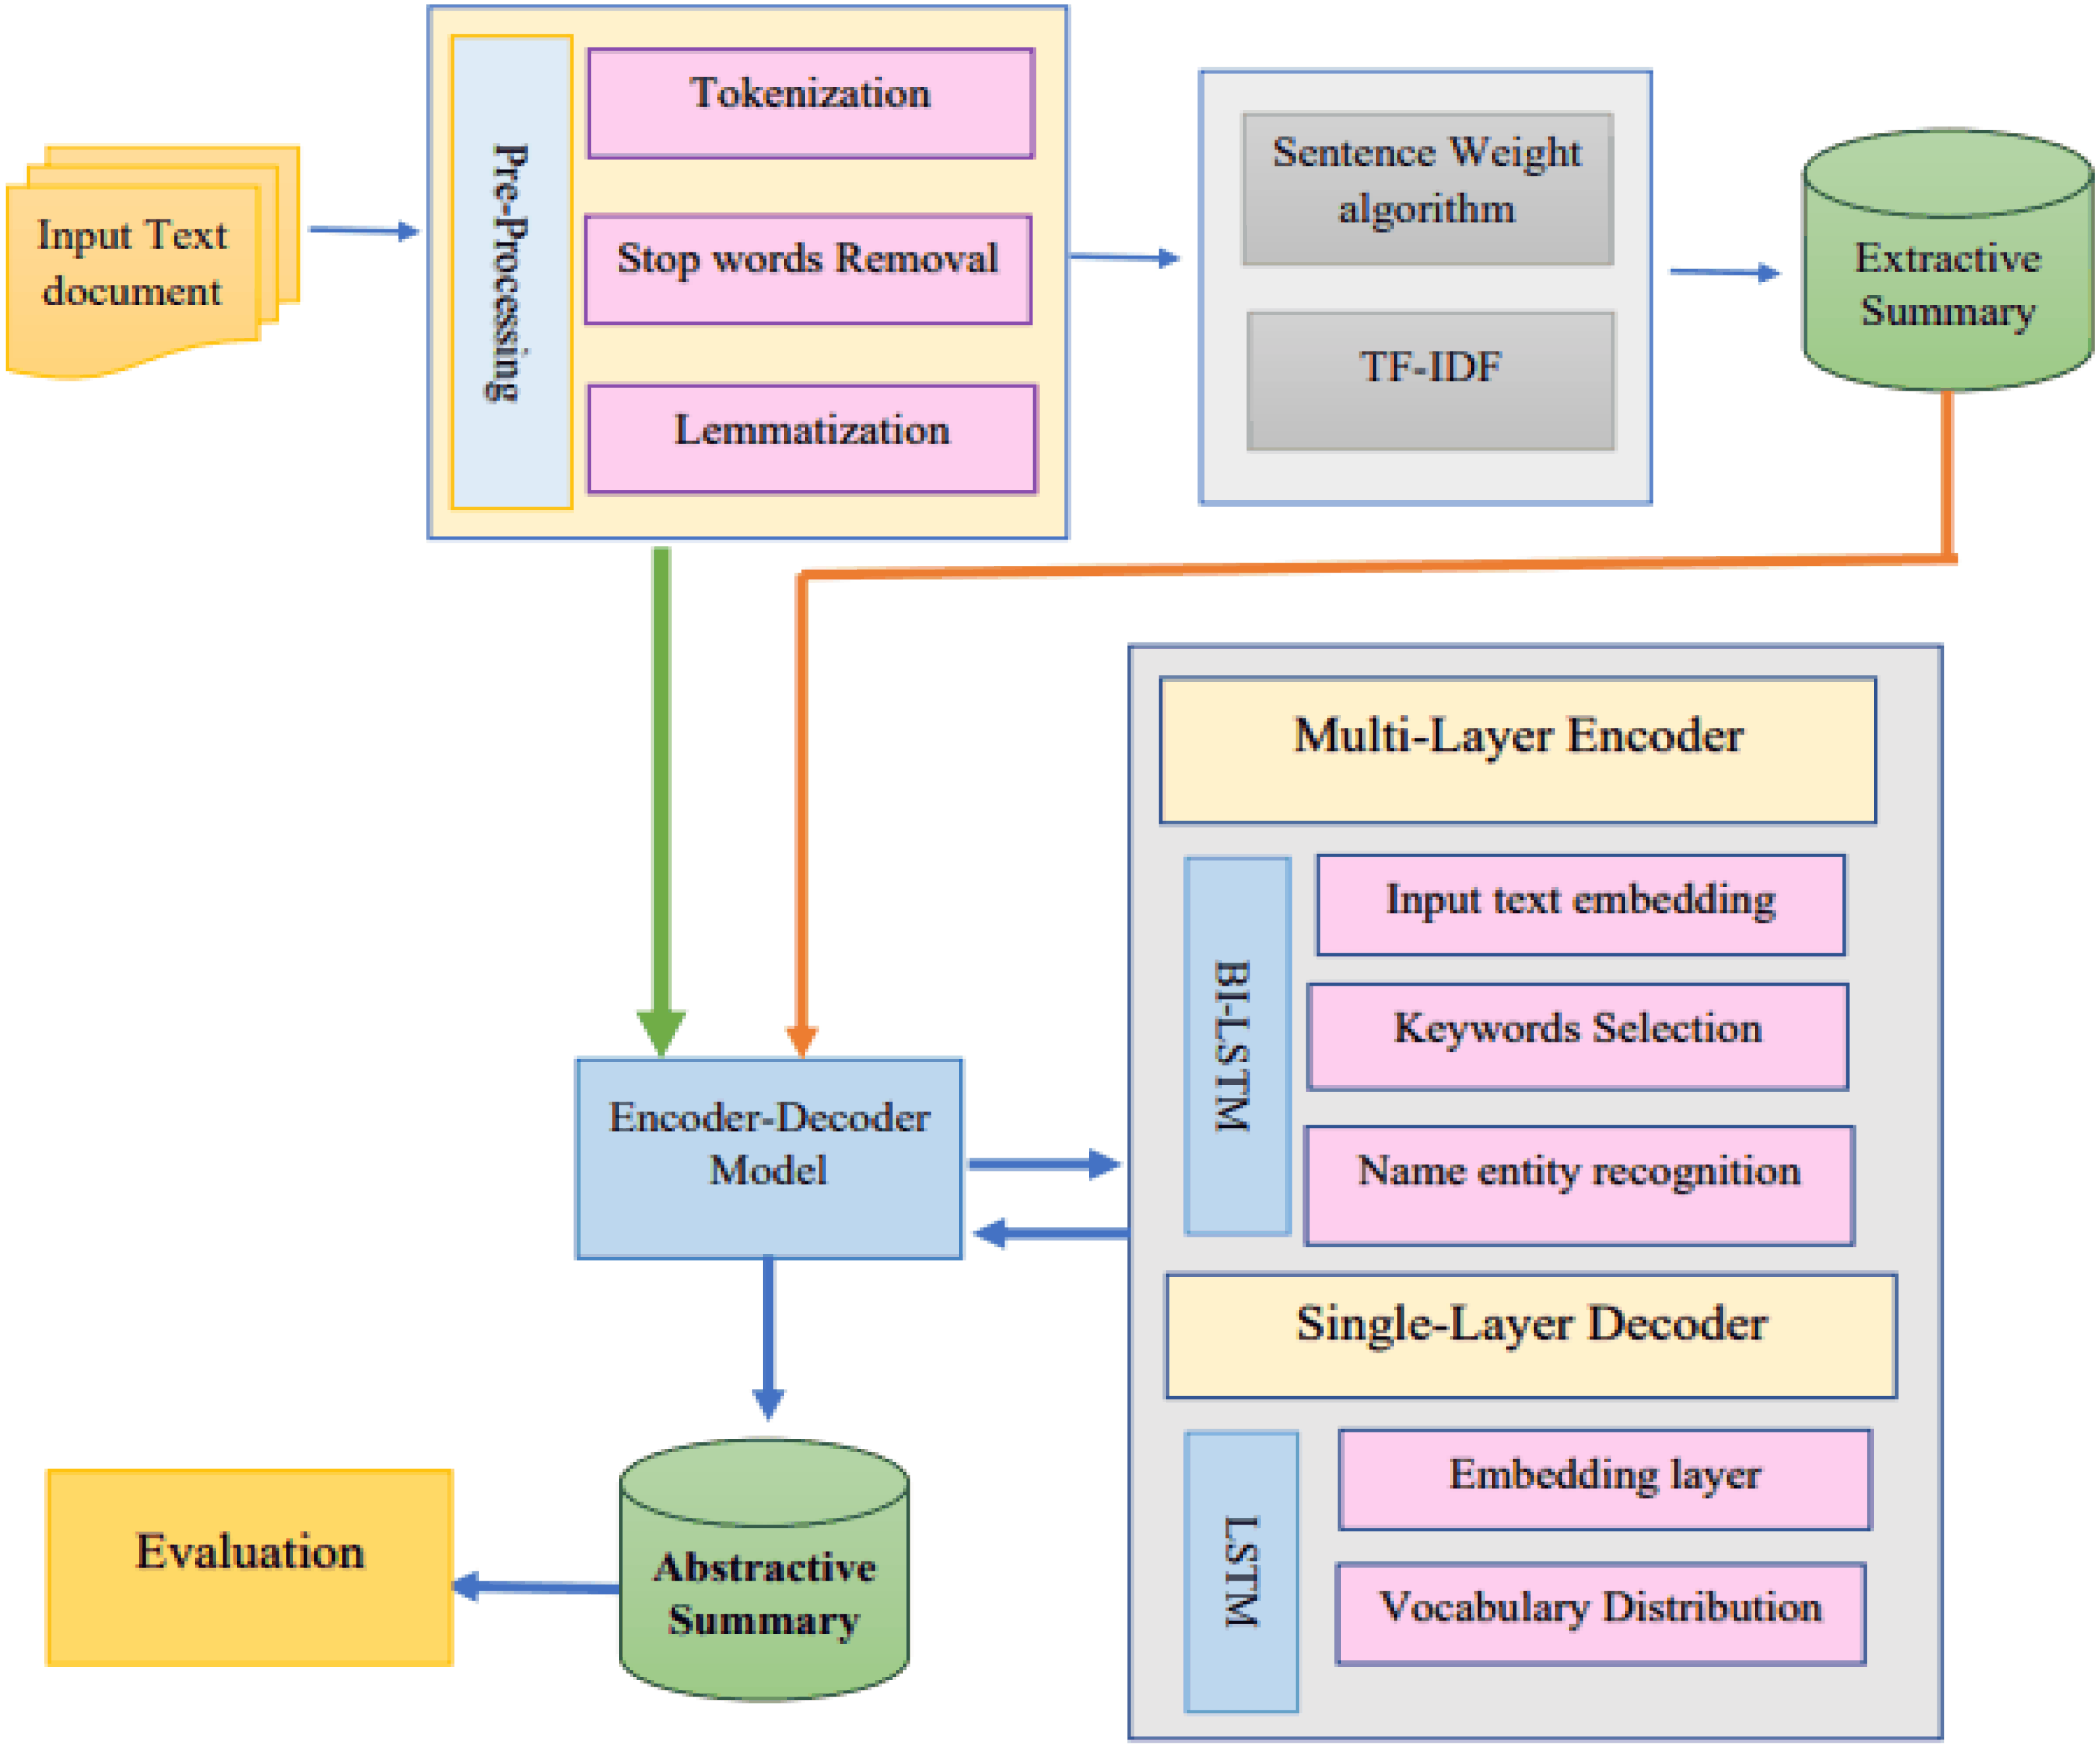
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)