Complete Technical Paper Content — Ai Content Moderation
1. Executive Abstract, Problem Formulation & Background
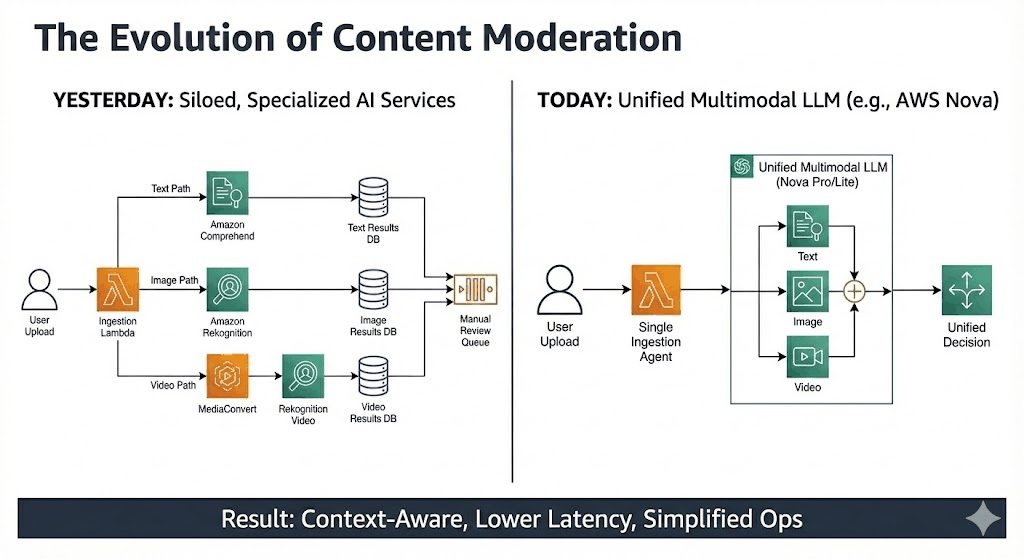
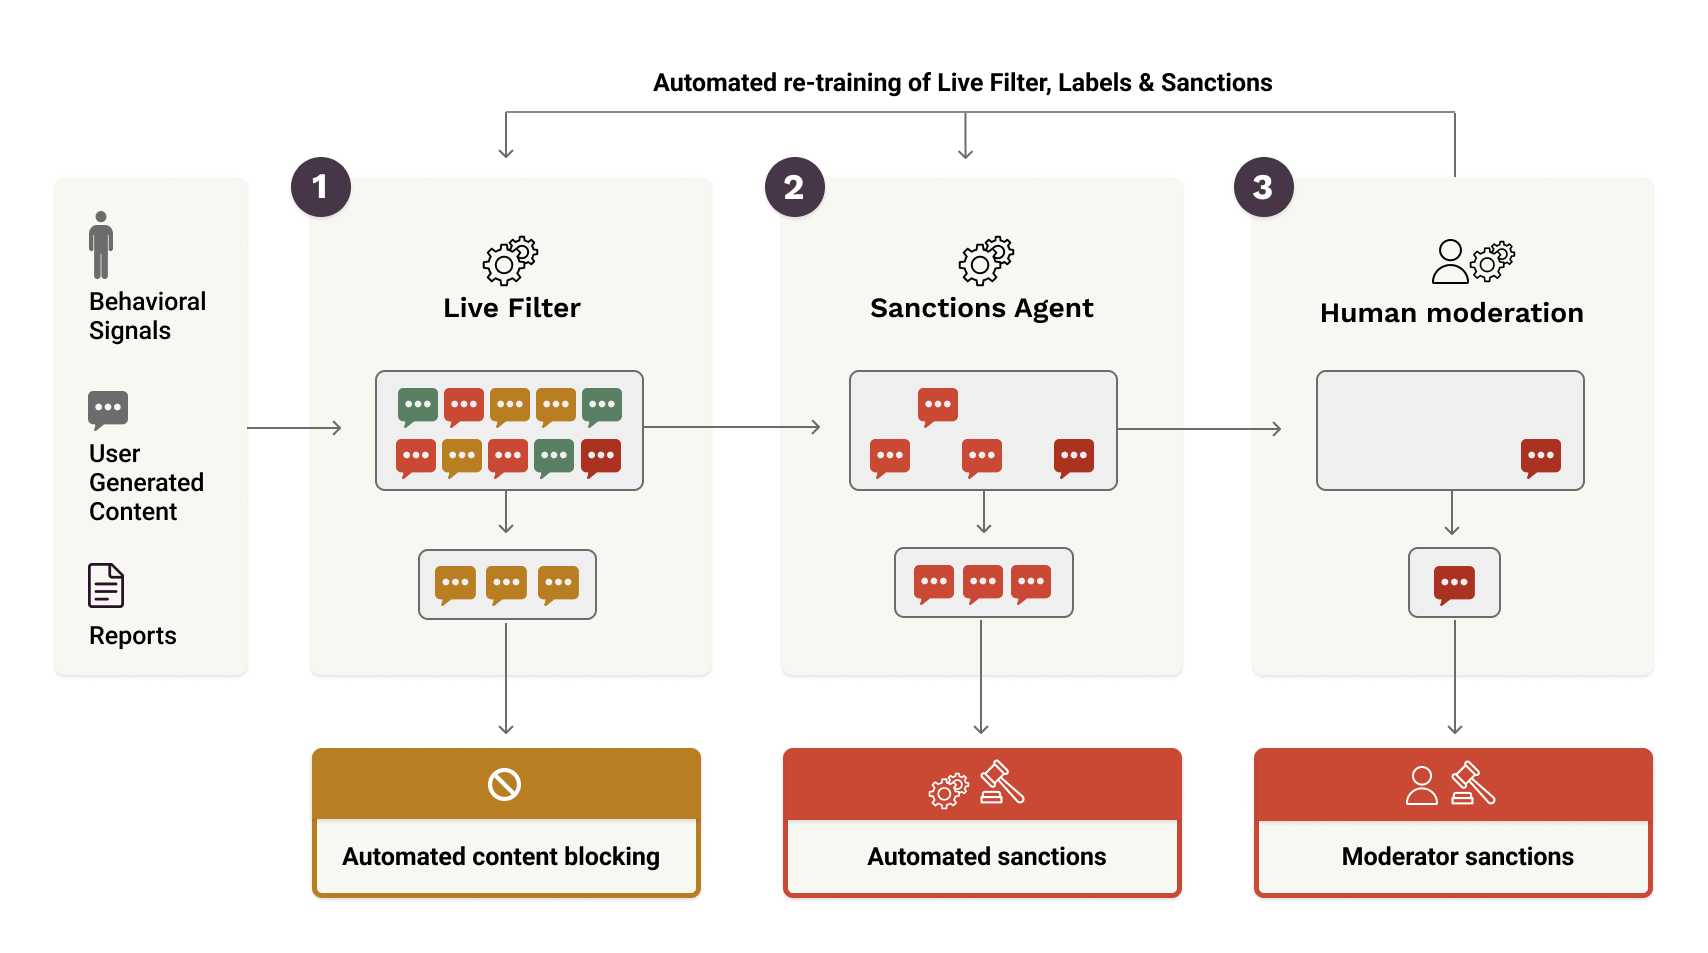
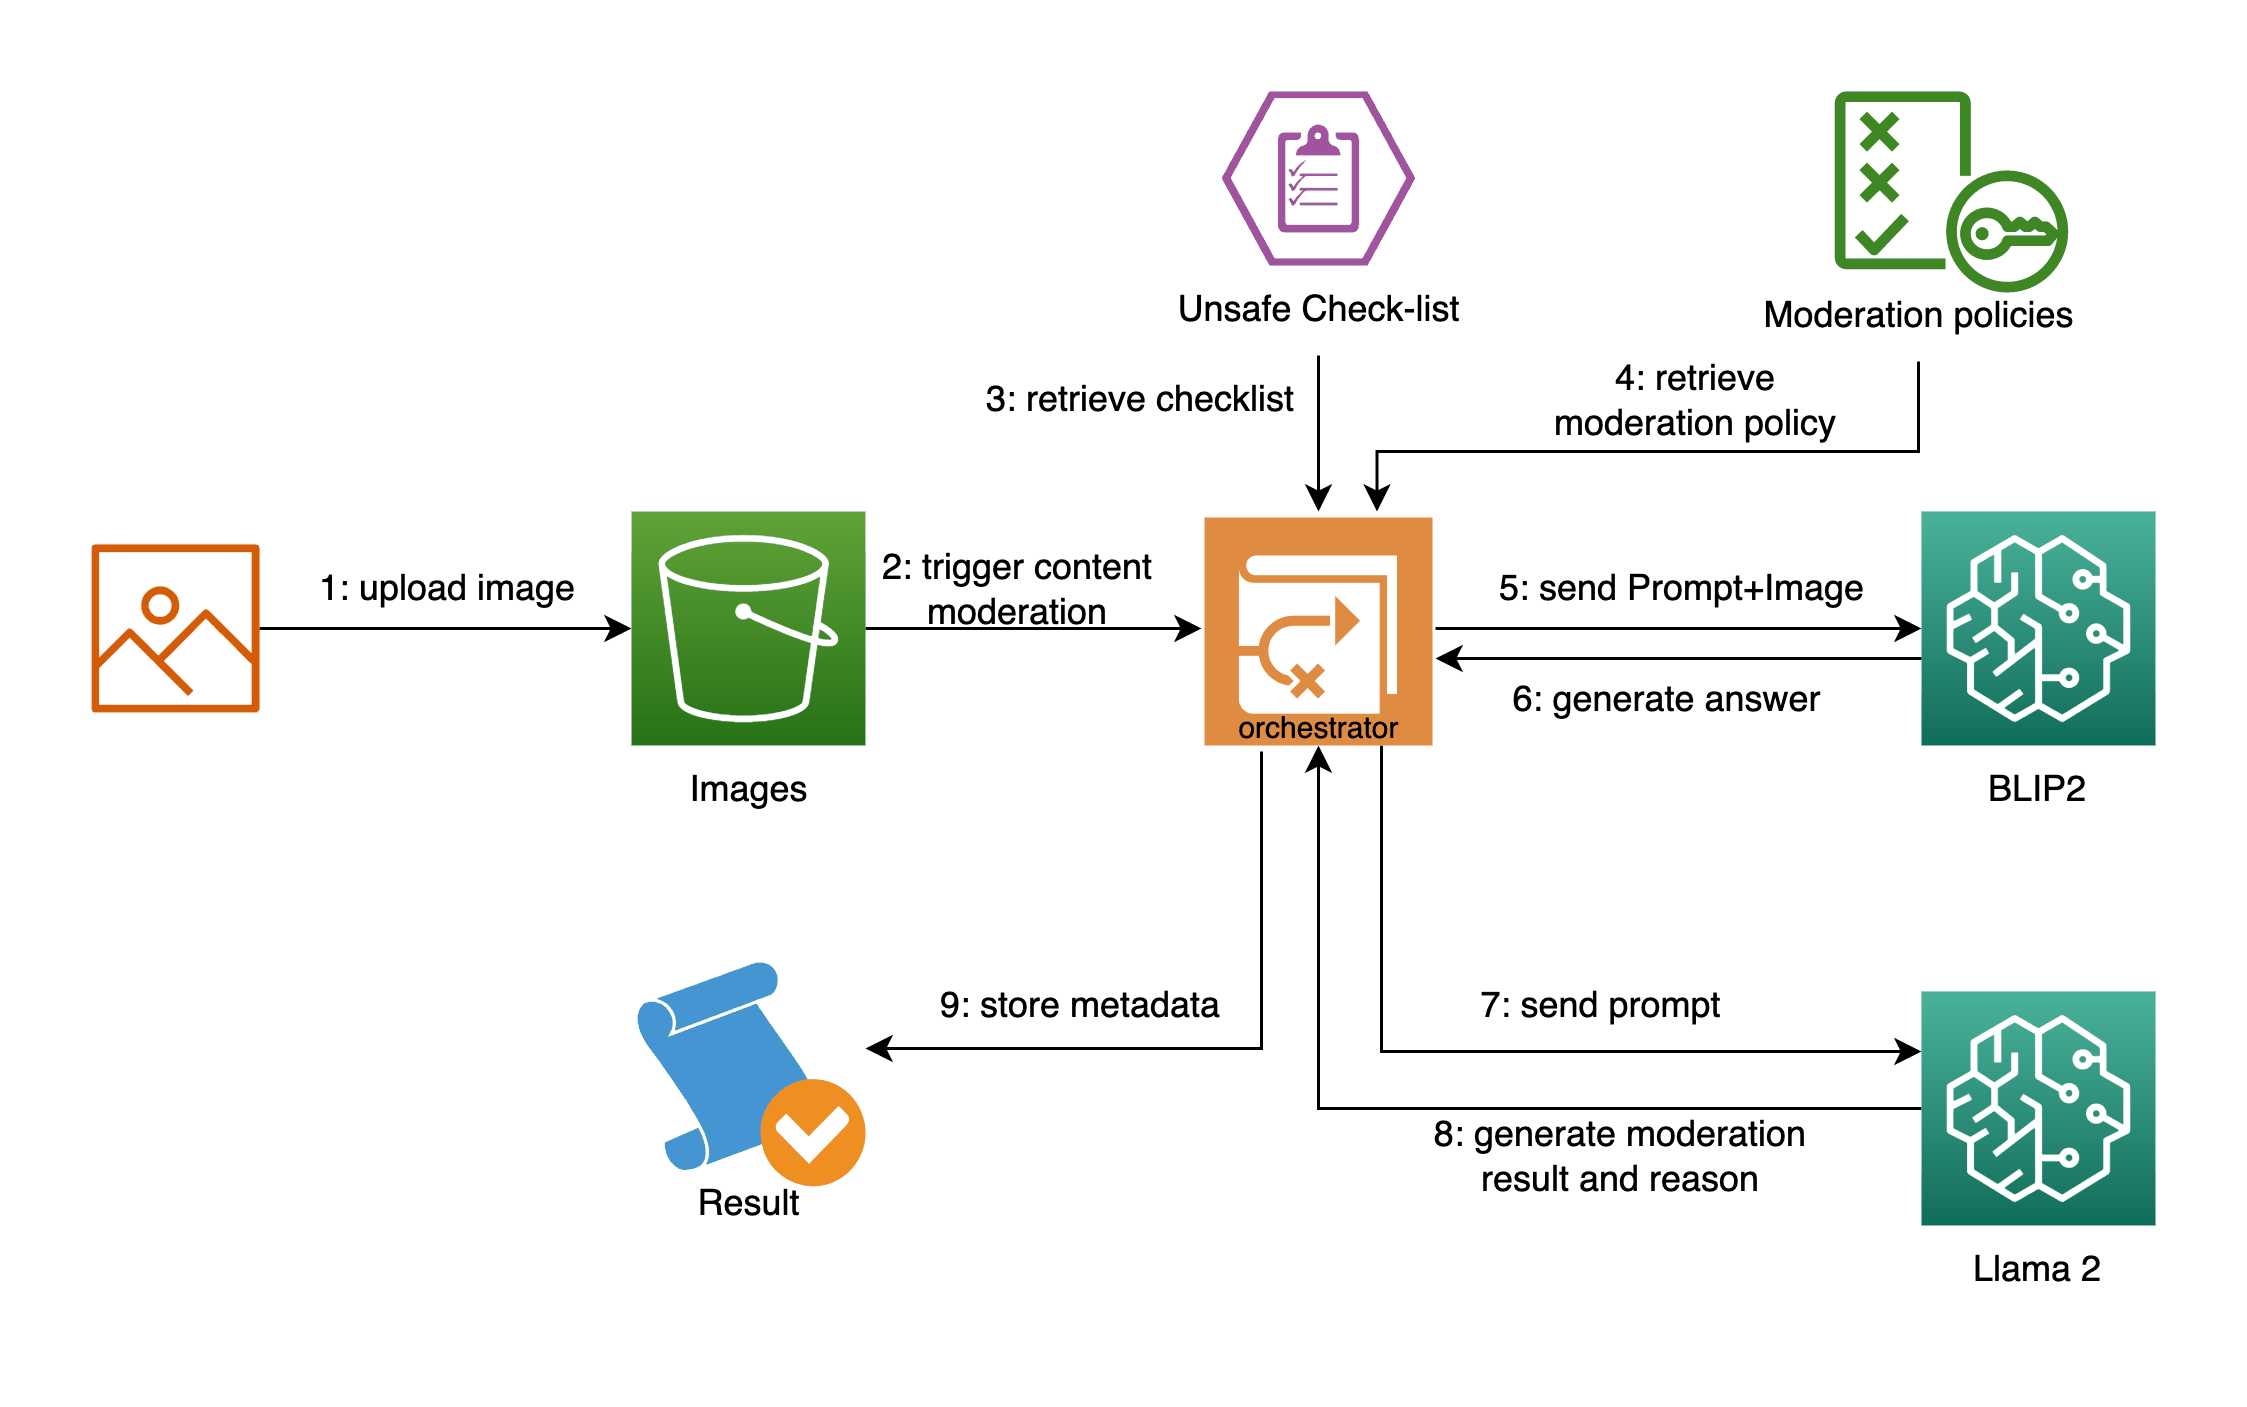
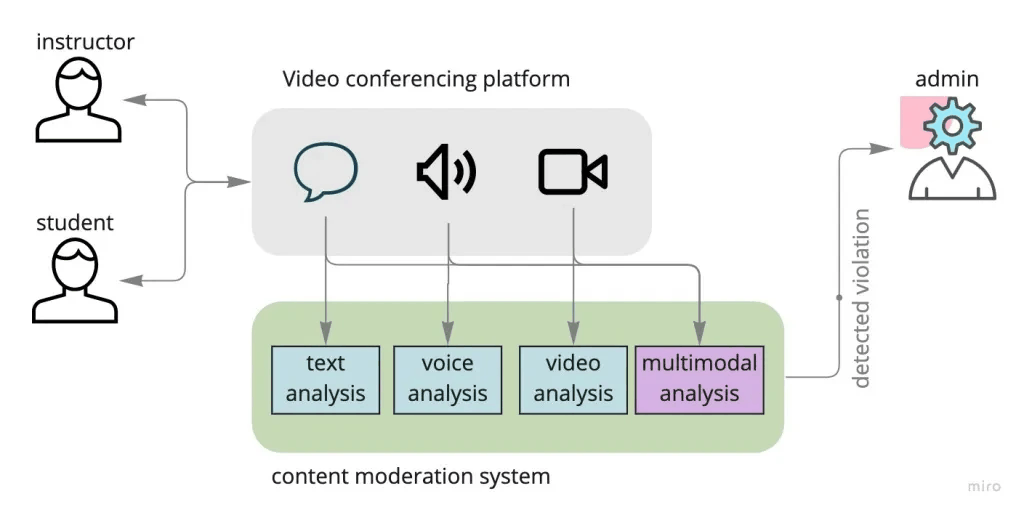
Content moderation, in the context of websites that facilitate user-generated content, is the systematic process of identifying, reducing, or removing user contributions that are irrelevant, obscene, illegal, harmful, or insulting. This process may involve either direct removal of problematic content or the application of warning labels to flagged material. As an alternative approach, platforms may enable users to independently block and filter content based on their preferences. This practice operates within the broader domain of trust and safety frameworks. Various types of Internet sites permit user-generated content such as posts, comments, videos including Internet forums, blogs, and news sites powered by scripts such as phpBB, a wiki, PHP-Nuke, etc. Depending on the site's content and intended audience, the site's administrators will decide what kinds of user comments are appropriate, then delegate the responsibility of sifting through comments to lesser moderators. Most often, they will attempt to eliminate trolling, spamming, or flaming, although this varies widely from site to site. Major platforms use a combination of algorithmic tools, user reporting and human review. Social media sites may also employ content moderators to manually flag or remove content flagged for hate speech, incivility or other objectionable content. Other content issues include revenge porn, graphic content, child abuse material and propaganda. Some websites must also make their content hospitable to advertisements. In the United States, content moderation is governed by Section 230 of the Communications Decency Act, and has seen several cases concerning the issue make it to the United States Supreme Court, such as the current Moody v. NetChoice, LLC. Content moderation can result in a range of outcomes, including blocking and visibility moderation such as shadow banning. Jawboning, where governments pressure a platform with threats to moderate beyond legal requirements can reduce accountability and due process.
Facebook had increased the number of content moderators from 4,500 to 7,500 in 2017 due to legal requirements and other controversies. In Germany, Facebook was responsible for removing hate speech within 24 hours of when it was posted. In late 2018, Facebook created an oversight board or an internal "Supreme Court" to decide what content remains and what content is removed. According to Frances Haugen, the number of Facebook employees responsible for content moderation was much smaller as of 2021.
Social media site Twitter has a suspension policy. Between August 2015 and December 2017, it suspended over 1.2 million accounts for terrorist content to reduce the number of followers and amount of content associated with the Islamic State. Following the acquisition of Twitter by Elon Musk in October 2022, content rules have been weakened across the platform in an attempt to prioritize free speech. However, the effects of this campaign have been called into question.
Data Workers' Inquiry a collaboration between Weizenbaum Institute, Technische Universität Berlin and DAIR Cliff Lampe and Paul Resnick : Slash (dot) and burn: distributed moderation in a large online conversation space Proceedings of the SIGCHI conference on Human factors in computing systems table of contents, Vienna, Austria 2005, 543–550.
Kling AI is a generative artificial intelligence service created and hosted by the Beijing-based technology company Kuaishou. Kling generates videos from natural language descriptions, called prompts.
Millions of people around the world are chatting with artificial intelligence (AI) assistants, asking questions, seeking help, and receiving responses instantly every day. However, what most people that use large language models (LLMs) don't see is that behind many of their interactions there is often another AI model involved. This secondary LLM is working silently in the background as a digital bodyguard. It scans for potential risks and inappropriate content and when it does its job effectively, unsafe content will not make it to your screen.
What are the inner workings of this content moderation system that the average user might not see and how does it help to enhance their experience? That view is exactly what this web application tutorial reveals. Instead of hiding the safety mechanisms that protect users, this open-source tutorial pulls back the curtain. It shows you how two machine learning (ML) models work together to produce quality responses and moderate content, keeping you safe at the same time. Effective human-computer interaction (HCI) in LLM-based ecosystems requires that users understand not just what decisions are being made, but why they are being made. In this tutorial think of yourself as a high-profile celebrity. Your AI chatbot can be imagined as your personal concierge. What high-profile celebrity doesn’t have a personal bodyguard at hand? This space is where the IBM® Granite Guardian® model comes into play.
“The concierge" (Granite 3-8b-instruct): This model will act as your friendly AI assistant and by using natural language, answer your every question to provide helpful information. Think of this model as your personal problem solver with almost limitless connections and information. It possesses a wide array of knowledge but might not always pause to consider that certain information could be harmful in the wrong context.
“The bodyguard” (Granite Guardian 3.2-3b-a800m): This model is your security expert, your bodyguard and an LLM chaperone. Content moderation tasks are the proverbial bread and butter for this model. Anything your personal concierge wants to pass along to you needs to go through this model first. Like a comic book superhero, the model is trained to spot trouble from a mile away and make split-second decisions about what is safe or what needs to be blocked and flagged. The training data used for Granite Guardian promotes adaptability in detecting a wide variety of toxicity, including:
• HAP (Hate speech, abuse, and profanity): Detecting harmful language, racial slurs and offensive content.
• PII (Personally identifiable information): Spotting sensitive personal data that shouldn't be shared.
• Harm detection: Identifying content that could cause physical, emotional, or psychological harm. This type includes the curation of misinformation and its spread at scale on online platforms.
2. Related Work, Literature Survey & Algorithmic Foundations
• Social bias: Recognizing unfair prejudices or discriminatory language that sometimes go unchecked on social media platforms and online communities.
• Jailbreak detection: Catching prompt engineering attempts to bypass AI safety measures to produce illicit responses from the model that could potentially slip by traditional human review.
• Violence: Flagging content that promotes or describes violent acts towards others as well as self-harm.
• Profanity: The model is trained in identifying and flagging inappropriate or offensive language.
The multilayered approach that Granite Guardian implements means it does not only look for obvious problems. The model is trained in moderation practices to spot subtle risks across numerous categories by using sizeable datasets, minimizing the risk of edge cases.
As AI models become more powerful and their usage more widespread, the need for effective safety protocols grows exponentially. AI systems currently process billions of real-world requests daily, far too many for basic algorithms or human moderators to review. Without proper moderation tools in place, inappropriate, harmful or dangerous content could easily be passed along to users around the world.
Many AI safety systems are black boxes meaning that you either get a response, or you don't. This scenario can be troubling because users or developers receive no insight as to why. This lack of transparency makes it difficult to understand, trust or improve these critical safety systems. The following tutorial aims to fix that as well as demonstrate the capabilities offered with Granite Guardian.
Granite Guardian does not simply block unsafe responses and show you a generic "I can't help with that" message. Instead, the model shows you real-time risk detection as it happens, details if a risk is detected or not, and gives the user an accuracy score of the detected risk. The model has undergone fine-tuning to detect both false positives and false negatives generated by the assistant. This demonstration is like having X-ray vision into model safety. The user can see the mechanisms of protection that usually operate invisibly behind the scenes.
User input: The model first accepts questions through user input in a local web application chatbot format.
Assistant response: Granite 3-8b-instruct will then generate a response to answer the user’s question(s).
Risk detection: Granite Guardian will then analyze the response. During this process it will apply its moderation rules to declare if the content is safe or unsafe.
Display results: The results will then be displayed for the user to see what is going on during their interaction with the model. If the response given by the instruct model is deemed safe, then the user will receive the model’s output(answer) to their question and the moderation details produced by the Guardian model. However, if the response produced by the instruct model is deemed unsafe, content filtering ensures that this response is not displayed to the user. The user will also receive the moderation details produced by the Guardian model as to why this content has been deemed unsafe.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
This tutorial demonstrates a web application chat bot use case. It uses a two-model AI system where “The bodyguard” (Granite-Guardian-3.2-3b-a800m) moderates responses from “The concierge” (Granite-3-8b-instruct). The appropriate risk detection and moderation policies lead to a safer AI interaction experience.
Ensure that you are running Python 3.10, 3.11 or3.12 in a freshly created virtual environment. Note: you can also access this tutorial on GitHub.
While you can choose from several tools, this tutorial walks you through how to set up an IBM account to use a Jupyter Notebook.
Note: We will be running the larger instruct model using watsonx.ai to save memory for lower power machines.
Create a watsonx.ai Runtime service instance (select your appropriate region and choose the Lite plan, which is a free instance).
Associate the watsonx.ai Runtime service instance to the project that you created in watsonx.ai.
git clone <https://github.com/IBM/ibmdotcom-tutorials.git> cd docs/tutorials/ai-models/granite-guardian/granite-guardian-webapp
The web application provides transparency into how AI moderation works. Think of it like having a window into a security checkpoint. This window allows you to see how decisions are made rather than just getting a "blocked" or "approved" result.
Social media moderation: When social media users upload millions of posts daily, a dual-model approach ensures that harmful content gets flagged while legitimate discussions about sensitive topics remain accessible for other users on the platform. A level of transparency helps moderators understand why certain content was flagged, reducing over censorship.
Environmental monitoring: Applications developed to automate the analysis of images for beech leaf disease (BLD) detection, employing convolutional neural networks (CNNs , require the same safety principles. When these AI applications process thousands of leaf images, to identify disease patterns, the moderation layer ensures that false positives don't trigger unnecessary interventions. The transparency aspect helps forest managers understand the confidence levels behind each diagnosis.
AI chatbot safety: Customer service bots and educational assistants need to refuse harmful requests while remaining helpful. This step could include jailbreaking prompts to try to trick these bots into gaining access to sensitive information. An AI ecosystem built on safety catches attempts to manipulate the bot into providing dangerous information, while explaining to users why certain topics cannot be discussed.
The effectiveness of this layered approach lies not just in its technical aspects, but in how it transforms AI safety from an abstract thought into something actionable. Whether you're protecting social media users from harmful content, ensuring chatbots respond responsibly or assisting environmentalists in making informed decisions, the fundamental principles of safety and transparency apply.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
You have now seen how two specialized models working in tandem can catch what solo model systems might miss. You have also learned how real-time moderation scales across applications and why transparency isn't just a nice bonus, it's an essential part of the trust-building process. This shift is not just about adding additional safety features to existing systems, it's about fundamentally rethinking how we build ethical AI systems that promote user well-being. As the adoption and advancements of AI technology grow every day, it is imperative that we are not sacrificing individuals' protection for speed.
• Swap the “harm” risk_name for some other categories like: social_bias, violence, jailbreak, profanity, sexual_content and unethical_behavior.
• Swap the assistant model for others of your choosing to see how it impacts the moderations. Modify the tutorial to pull models like Meta’s Llama and OpenAI’s GPT-4 and see how they stack up.
• Share your findings and experiences with the artificial intelligence community. For more information on text detection checkout the docs .
IBM watsonx.governance helps enterprises govern any AI, anywhere with real-time visibility, enterprise controls, and continuous accountability, powered by AI-native governance and enterprise-grade GRC.
Download the guidebook to learn how to move beyond recovery assumptions and build greater confidence in your organization's ability to recover when it matters most.
The global average cost of a data breach reached USD 4.99M while AI-driven attacks increased 56%. Explore the latest findings.
When margins are thin, every inefficiency matters. While legacy systems continue to constrain AI’s potential across aviation, Riyadh Air chose a different path. In partnership with IBM, Riyadh Air built the world’s first AI‑native airline, redefining a smarter, faster, more intuitive way to travel.
Learn how to turn governance and security into drivers of resilience, smarter decision-making and confident growth with practical strategies from this buyer’s guide.
Gain insights to prepare and respond to cyberattacks with greater speed and effectiveness with the IBM X-Force® Threat Intelligence Index.
Download the ebook to learn how to address critical data challenges and implement an automated, end to end governance framework that enhances data quality, strengthens trust and supports regulatory readiness.
Register to access IBM insights and resources on emerging technologies—including AI, automation and data—and learn how organizations are putting them into practice.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Explore the Data Matters hub to learn how effective data practices and governance create the foundation for scalable, enterprise ready AI.
Learn about the new challenges of generative AI, the need for governing AI and ML models and steps to build a trusted, transparent and explainable AI framework.
Understand the importance of establishing a defensible assessment process and consistently categorizing each use case into the appropriate risk tier.
Learn how to advance ethical and compliant AI practices through a unified set of generative AI governance capabilities.
Govern generative AI models from anywhere and deploy on the cloud or on premises with IBM watsonx.governance.
See how AI governance can help increase your employees’ confidence in AI, accelerate adoption and innovation and improve customer trust.
Prepare for the EU AI Act and establish a responsible AI governance approach with the help of IBM Consulting®.
Direct, manage and monitor your AI with a single portfolio to speed responsible, transparent and explainable AI.
Comprehensive guide to AI safety features, content moderation, and implementing responsible AI practices in production applications.
AI safety and content filtering are crucial for responsible AI deployment. This guide covers built-in safety features, custom filtering strategies, and compliance considerations.
Claude uses Constitutional AI, training models to be helpful, harmless, and honest through a comprehensive set of principles:
Safety requirements vary significantly by industry and jurisdiction. Always consult legal and compliance teams for regulated applications.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)