Complete Technical Paper Content — Ai Crisis Detection
1. Executive Abstract, Problem Formulation & Background
Pangram is AI content detection software developed by Pangram Labs. Its text detector classifies passages as human-written, AI-assisted or AI-generated. The company released Pangram 4 in July 2026. It also provides an image detector. Independent studies of earlier versions found low error rates, but also found that some AI-generated texts escaped detection when prompted to imitate human authors. For Pangram 4, the company reported a false positive rate of 0.0041%, approximately one in 24,000, on an English-language benchmark. Its use in education and publishing has prompted debate about whether detector results provide sufficient evidence of undisclosed AI use.
Pangram Labs trains its detector on human writing paired with AI-generated texts matched by topic, length and tone. To reduce false positives, it identifies human texts the model has misclassified and adds them to the training data alongside corresponding AI examples. Pangram 4 uses a mixture of experts architecture to classify individual tokens, or units of text, then groups the results into labeled passages. Pangram 4 analyzes prose of at least 50 words and reports how much and which parts of the text it classifies as human-written, AI-assisted or AI-generated. The company distinguishes its trained classifier from detection methods based on perplexity, which measure how predictable a text is to a language model. Its confidence labels do not give a calibrated probability that a classification is correct.
In tests published on July 15, 2026, Epoch AI found that Pangram correctly classified all 495 human-written passages and all 297 AI passages generated from basic prompts. Pangram failed to classify 30 of 297 passages imitating particular human authors as fully AI-generated, a rate of 10.1%. The evaluation counted a "Mixed" verdict on wholly AI-generated text as a missed detection. In July 2026, before the release of Pangram 4, the Reuters Institute for the Study of Journalism reported that Pangram had labeled 86% of 588 AI-generated samples compiled by researcher Alexios Mantzarlis as human-written. The samples used techniques such as rhyme, repetition and archaic language to evade detection. An August 2026 preprint by Jonathan A. Karr Jr. and colleagues at the University of Notre Dame tested Pangram 3.2 on academic abstracts. After the rewrites were processed with the humanizer Undetectable AI, Pangram missed more than 96% at the threshold used in the study. The authors cautioned against treating detector scores as sufficient evidence of academic misconduct.
In statistics and machine learning, leakage (also known as data leakage or target leakage) refers to the use of information during model training that would not be available at prediction time. This results in overly optimistic performance estimates, as the model appears to perform better during evaluation than it actually would in a production environment. Leakage is often subtle and indirect, making it difficult to detect and eliminate. It can lead a statistician or modeler to select a suboptimal model, which may be outperformed by a leakage-free alternative.
Premature featurization; leaking from premature featurization before Cross-validation/Train/Test split (must fit min-max scaling/ngrams/etc on only the train split, then transform the test set) Duplicate rows between train/validation/test (for example, oversampling a dataset to pad its size before splitting; or, different rotations/augmentations of a single image; bootstrap sampling before splitting; or duplicating rows to up sample the minority class) Non-independent and identically distributed random (non-IID) data Time leakage (for example, splitting a time-series dataset randomly instead of newer data in test set using a train/test split or rolling-origin cross-validation) Group leakage—not including a grouping split column (for example, Andrew Ng's group had 100k x-rays of 30k patients, meaning ~3 images per patient. The paper used random splitting instead of ensuring that all images of a patient were in the same split. Hence the model partially memorized the patients instead of learning to recognize pneumonia in chest x-rays.) A 2023 review found data leakage to be "a widespread failure mode in machine-learning (ML)-based science", having affected at least 294 academic publications across 17 disciplines, and causing a potential reproducibility crisis.
🧠 Crisis Signal Detector Real-Time Mental Health Crisis Detection using Fine-Tuned BERT An AI-powered Natural Language Processing (NLP) application that detects crisis-related text using a fine-tuned BERT (Bidirectional Encoder Representations from Transformers) model and provides real-time predictions through an interactive Streamlit dashboard deployed on Hugging Face Spaces . 🚀 Live Demo 🚀 Live Demo: Try the Crisis Signal Detector 📑 Table of Contents Overview Problem Statement Features Dashboard Preview System Architecture Model Workflow Dataset Methodology Technology Stack Repository Structure Installation Usage Project Documentation Results Challenges Faced Model Weights Future Improvements Author License 📖 Overview Crisis Signal Detector is a Natural Language Processing (NLP) application that identifies whether an input text contains a potential crisis signal. The project leverages a fine-tuned BERT model from Hugging Face Transformers for binary text classification and provides predictions through an intuitive Streamlit web interface. This project was developed as the final capstone project during the NAVTTC-sponsored Artificial Intelligence & Machine Learning Training Program conducted at Corvit Systems Bahawalpur . The primary objective of this project is to demonstrate how transformer-based NLP models can assist in the early detection of crisis-related text, providing a foundation for intelligent mental health support systems. 🎯 Problem Statement Mental health issues have become an increasing global concern, and identifying crisis-related language at an early stage can help support timely intervention. The objective of this project is to build an AI-powered system capable of classifying textual input into one of two categories: Crisis Signal Normal Text using a fine-tuned BERT model trained for binary text classification. ✨ Features 🔹 Real-time crisis text detection 🔹 Fine-tuned BERT model 🔹 Binary text classification 🔹 Confidence score prediction 🔹 Interactive Streamlit interface 🔹 Hugging Face deployment 🔹 Docker support 🔹 Clean and responsive dashboard 🔹 Fast inference using Transformer architecture 📸 Dashboard Preview 🏗️ System Architecture 🧠 Model Workflow User Input │ ▼ Text Preprocessing │ ▼ BERT Tokenizer │ ▼ Fine-Tuned BERT Model │ ▼ Softmax Layer │ ▼ Binary Classification │ ▼ Prediction + Confidence Score 📊 Dataset The dataset used for this project was obtained from Kaggle . Dataset Link Dataset: Suicide Watch Dataset (Kaggle) Dataset Details Source: Kaggle Task: Binary Text Classification Original Dataset Size: 130,000+ text samples Classes: Crisis Signal Normal Text Training Dataset Although the original dataset contains over 130,000 samples , the model was fine-tuned using a subset of 10,000 samples . This decision was made because the project was developed on hardware with limited computational resources during the NAVTTC training program. Using a carefully selected subset allowed efficient training while still producing reliable predictions for the prototype application. 🔬 Methodology The project followed the complete Machine Learning and Deep Learning pipeline: Dataset Collection Data Cleaning Exploratory Data Analysis (EDA) Text Preprocessing Tokenization using the BERT Tokenizer Fine-tuning the pre-trained BERT model Model Evaluation Deployment using Streamlit on Hugging Face Spaces The trained model predicts whether an input sentence represents a crisis signal and displays the prediction together with a confidence score. 🛠 Technology Stack Category Technologies Programming Language Python Deep Learning Framework PyTorch Natural Language Processing Hugging Face Transformers Pre-trained Model BERT Data Processing Pandas, NumPy Data Visualization Matplotlib, Seaborn Web Framework Streamlit Deployment Hugging Face Spaces Containerization Docker Version Control Git & GitHub 📂 Repository Structure crisis-signal-detector/ │ ├── app.py ├── requirements.txt ├── Dockerfile ├── README.md ├── LICENSE │ ├── model/ │ ├── config.json │ ├── tokenizer.json │ ├── tokenizer_config.json │ └── (model.safetensors not included) │ ├── notebook/ │ └── training.ipynb │ ├── presentation/ │ └── CrisisSignalDetector.pdf │ └── screenshots/ ├── dashboard.png └── architecture.png Note: The trained model weights ( model.safetensors ) are not included in this repository because they exceed GitHub's file size limit. The complete application is deployed and available on Hugging Face Spaces. ⚙️ Installation Clone the repository git clone https://github.com/mshakeelrasheed/crisis-signal-detector.git Navigate to the project directory cd crisis-signal-detector Install dependencies pip install -r requirements.txt Run the application streamlit run app.py 🚀 Usage Launch the Streamlit application. Enter any text into the input field. Click Run Prediction . The application will display: Predicted Class (Crisis / Normal) Confidence Score Probability Visualization 📄 Project Documentation This repository contains: ✅ Source Code ✅ Training Notebook ✅ Project Presentation ✅ Model Configuration Files ✅ Docker Configuration ✅ Dashboard Screenshots ✅ System Architecture ✅ Deployment Resources 📊 Results The fine-tuned BERT model successfully performs binary text classification to identify crisis-related language. Output Includes ✅ Crisis / Normal Classification ✅ Confidence Score ✅ Probability Visualization ✅ Real-time Prediction The application has been successfully deployed on Hugging Face Spaces , allowing users to test the model through an interactive web interface. ⚠️ Challenges Faced During the development of this project, several technical challenges were encountered: Working with a transformer-based BERT model on limited hardware resources. Training on a subset of the original dataset to reduce computational requirements. Managing the large size of the trained model during deployment. GitHub's file size limitation prevented uploading the model.safetensors file. Configuring and deploying the application successfully on Hugging Face Spaces. Organizing the repository to provide clear documentation while keeping it lightweight. These challenges were addressed through dataset optimization, efficient deployment practices, and proper project organization. ⚠️ Model Weights The trained model weights ( model.safetensors ) are not included in this repository because they exceed GitHub's maximum file size limit. To explore the complete application, please use the deployed version on Hugging Face Spaces . 🔮 Future Improvements Future enhancements planned for this project include: 🌍 Multi-language crisis detection 🤖 Support for additional transformer models 📱 Mobile application integration ☁️ REST API using FastAPI 🧠 Explainable AI (XAI) for prediction interpretation 📊 Training on the complete dataset using high-performance hardware 🔄 Continuous model retraining with updated datasets 📈 Performance monitoring and model versioning 👨💻 Author Muhammad Shakeel Rasheed BS Artificial Intelligence Islamia University Bahawalpur Passionate about Artificial Intelligence, Machine Learning, Deep Learning, Natural Language Processing, and AI Automation. Connect with me GitHub: https://github.com/mshakeelrasheed LinkedIn: https://www.linkedin.com/in/muhammad-shakeel-rasheed 📜 License This project is licensed under the MIT License . Feel free to use, modify, and distribute this project in accordance with the license terms. ⭐ If you found this project useful, consider giving it a Star! Thank you for visiting this repository.
An AI-powered Natural Language Processing (NLP) application that detects crisis-related text using a fine-tuned BERT (Bidirectional Encoder Representations from Transformers) model and provides real-time predictions through an interactive Streamlit dashboard deployed on Hugging Face Spaces .
2. Related Work, Literature Survey & Algorithmic Foundations
Crisis Signal Detector is a Natural Language Processing (NLP) application that identifies whether an input text contains a potential crisis signal.
The project leverages a fine-tuned BERT model from Hugging Face Transformers for binary text classification and provides predictions through an intuitive Streamlit web interface.
This project was developed as the final capstone project during the NAVTTC-sponsored Artificial Intelligence & Machine Learning Training Program conducted at Corvit Systems Bahawalpur .
The primary objective of this project is to demonstrate how transformer-based NLP models can assist in the early detection of crisis-related text, providing a foundation for intelligent mental health support systems.
Mental health issues have become an increasing global concern, and identifying crisis-related language at an early stage can help support timely intervention.
The objective of this project is to build an AI-powered system capable of classifying textual input into one of two categories:
User Input │ ▼ Text Preprocessing │ ▼ BERT Tokenizer │ ▼ Fine-Tuned BERT Model │ ▼ Softmax Layer │ ▼ Binary Classification │ ▼ Prediction + Confidence Score
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Although the original dataset contains over 130,000 samples , the model was fine-tuned using a subset of 10,000 samples .
This decision was made because the project was developed on hardware with limited computational resources during the NAVTTC training program. Using a carefully selected subset allowed efficient training while still producing reliable predictions for the prototype application.
The trained model predicts whether an input sentence represents a crisis signal and displays the prediction together with a confidence score.
crisis-signal-detector/ │ ├── app.py ├── requirements.txt ├── Dockerfile ├── README.md ├── LICENSE │ ├── model/ │ ├── config.json │ ├── tokenizer.json │ ├── tokenizer_config.json │ └── (model.safetensors not included) │ ├── notebook/ │ └── training.ipynb │ ├── presentation/ │ └── CrisisSignalDetector.pdf │ └── screenshots/ ├── dashboard.png └── architecture.png
Note: The trained model weights ( model.safetensors ) are not included in this repository because they exceed GitHub's file size limit. The complete application is deployed and available on Hugging Face Spaces.
The fine-tuned BERT model successfully performs binary text classification to identify crisis-related language.
The application has been successfully deployed on Hugging Face Spaces , allowing users to test the model through an interactive web interface.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
During the development of this project, several technical challenges were encountered:
These challenges were addressed through dataset optimization, efficient deployment practices, and proper project organization.
The trained model weights ( model.safetensors ) are not included in this repository because they exceed GitHub's maximum file size limit.
To explore the complete application, please use the deployed version on Hugging Face Spaces .
Passionate about Artificial Intelligence, Machine Learning, Deep Learning, Natural Language Processing, and AI Automation.
Feel free to use, modify, and distribute this project in accordance with the license terms.
AI-powered NLP application for real-time crisis signal detection using a fine-tuned BERT model.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
CrisisSignalDetector with NLP Real-Time Crisis Detection in Social Media Using Machine Learning 📋 Project Overview CrisisSignalDetector is a machine learning system that identifies crisis-related tweets in real-time social media streams. The project demonstrates a complete ML pipeline from data preprocessing through model evaluation, comparing 6 different algorithms to determine the optimal solution for interpretability and accuracy. Key Achievement: Implemented 6 ML models and achieved evidence-based decision making instead of speculation about model performance. Real-World Application Use Case: Monitor social media during disasters and alert emergency responders Impact: Route rescue resources efficiently, potentially save lives Challenge: Balance accuracy (detecting all crises) with interpretability (understanding why the system flagged a tweet) 🎯 Technical Highlights Models Implemented & Tested Model Accuracy Precision Recall F1-Score Interpretability Notes Rule-Based (Ours) 61.16% 56.40% 42.20% 0.4828 100% ✅ Chosen for interpretability Logistic Regression 80.78% 82.57% 70.03% 0.7579 70% Best balance SVM 80.69% 84.09% 67.89% 0.7513 50% High precision Random Forest 79.77% 83.40% 66.06% 0.7372 40% Ensemble voting LSTM 78.28% 77.84% 69.11% 0.7322 20% Deep learning BERT 83.76% 87.47% 72.58% 0.7933 10% Pre-trained transformer Dataset Source: Kaggle Disaster Tweets Dataset Size: 7,613 tweets (43% crisis, 57% non-crisis) Train/Test: 70/30 split (5,329 train, 2,284 test) Preprocessing: URL removal, lowercasing, special character handling Architecture Input: Raw Tweet Text ↓ Text Preprocessing (clean, lowercase, remove noise) ↓ Feature Extraction (signal words, TF-IDF vectorization) ↓ ML Models (6 different algorithms) ↓ Evaluation (accuracy, precision, recall, F1-score) ↓ Output: Crisis/Non-Crisis with Confidence Score 💡 Key Learning: Why Rule-Based Won Despite achieving only 61% accuracy, the rule-based approach was optimal because: 100% Interpretability - Can explain every decision to non-technical stakeholders 7-Week Timeline - Completed in time vs BERT needs 12+ hours training No GPU Required - Works on standard hardware Easy to Update - Add/remove signal words without retraining Trust in Safety-Critical Systems - Emergency responders need to understand why system flagged a tweet Key Insight: Good ML is engineering tradeoffs, not just maximizing accuracy. 📁 Project Structure crisis-signal-detector-nlp/ ├── README.md # Project documentation ├── RESULTS.md # Complete results summary ├── HOW_IT_WORKS.md # Technical explanation │ ├── data/ │ ├── X_train_clean.csv # Training tweets (5,329) │ ├── y_train.csv # Training labels │ ├── X_test_clean.csv # Test tweets (2,284) │ ├── y_test.csv # Test labels │ └── signal_words_dict.json # 54 signal words, 12 categories │ ├── notebooks/ │ ├── PHASE_1_Data_Preparation.ipynb │ ├── PHASE_2_Signal_Word_Dictionary.ipynb │ ├── PHASE_3_Build_Crisis_Detector.ipynb │ ├── PHASE_4_Visualization_Reporting.ipynb │ ├── PHASE_5_Model_Comparison.ipynb │ └── LIVE_DEMO.ipynb # Interactive demo for faculty │ ├── src/ │ ├── crisis_detector.py # Main detector class │ ├── data_preprocessing.py # Data cleaning functions │ └── evaluation.py # Metrics calculation │ ├── results/ │ ├── crisis_detector.pkl # Trained model │ ├── model_comparison_results.csv # All 6 models' metrics │ ├── confusion_matrix.png # Visualization │ └── metrics_comparison.png # Side-by-side comparison │ └── docs/ ├── HOW_INTERPRETABILITY_CALCULATED.md ├── HOW_MODELS_LEARN.md └── LEARNING_JOURNEY.md 🚀 Quick Start Installation git clone https://github.com/yourusername/crisis-signal-detector-nlp.git cd crisis-signal-detector-nlp pip install -r requirements.txt Basic Usage from src . crisis_detector import CrisisDetector import json # Load detector and signal words detector = CrisisDetector ( threshold = 0.1 ) with open ( 'data/signal_words_dict.json' ) as f : signal_words = json . load ( f ) # Test on sample tweets tweets = [ "earthquake hits california help needed" , "beautiful day at the beach" , "fire spreading evacuation urgent" ] for tweet in tweets : result = detector . predict ( tweet ) print ( f" { tweet } " ) print ( f"Crisis: { result [ 'is_crisis' ] } , Confidence: { result [ 'confidence' ]:.2f } \n " ) Output earthquake hits california help needed Crisis: True, Confidence: 0.92 beautiful day at the beach Crisis: False, Confidence: 0.0 fire spreading evacuation urgent Crisis: True, Confidence: 0.88 📊 Results Summary Performance Metrics Accuracy: 61.16% - Correctly classifies 61% of all tweets Precision: 56.40% - 56% of detected crises are actual crises Recall: 42.20% - Catches 42% of actual crisis tweets F1-Score: 0.4828 - Balanced measure of precision and recall Confusion Matrix Predicted Non-Crisis Predicted Crisis Actual Non-Crisis 983 320 Actual Crisis 567 414 Key Metrics Interpretation ✅ 983 True Negatives - Correctly rejected non-crisis tweets ✅ 414 True Positives - Correctly identified crisis tweets ⚠️ 320 False Positives - Non-crisis marked as crisis (figurative language) ⚠️ 567 False Negatives - Missed crises (not enough signal words) 🔬 Technical Skills Demonstrated Machine Learning ✅ Supervised learning (classification) ✅ Feature engineering and extraction ✅ Model evaluation (accuracy, precision, recall, F1) ✅ Confusion matrix interpretation ✅ Hyperparameter tuning and optimization ✅ Model comparison and selection NLP Techniques ✅ Text preprocessing and cleaning ✅ Tokenization ✅ TF-IDF vectorization ✅ Feature extraction from text ✅ Signal word analysis Deep Learning ✅ LSTM architecture design ✅ Bidirectional models ✅ BERT fine-tuning ✅ Backpropagation and gradient descent ✅ Early stopping and regularization Software Engineering ✅ Data pipeline design ✅ Modular code organization ✅ Error handling ✅ Documentation ✅ Version control (Git) Professional Skills ✅ Technical writing and documentation ✅ Data visualization ✅ Comparative analysis ✅ Research-based decision making ✅ Presenting results to non-technical audiences 📈 Model Learning Process How Each Model Learns Rule-Based: Manual dictionary building (no learning) Analyzed data to identify signal words Assigned weights based on crisis likelihood Fixed rules, no adaptation Logistic Regression: Gradient descent optimization Learns optimal weights for 5,000 words Minimizes loss function iteratively 1,000 iterations in 0.06 seconds SVM: Decision boundary optimization Finds optimal boundary separating crisis from non-crisis Uses kernel trick for non-linear separation 6.5 seconds training time Random Forest: Ensemble learning Builds 100 decision trees Each tree learns from random data subset Voting mechanism for final prediction LSTM: Deep neural network Learns 500,000 internal weights through backpropagation 15 epochs (iterations) through training data 3.5 minutes training time BERT: Transfer learning Pre-trained on 3 billion tweets (by Google) Fine-tunes only 500 new weights for our task 12 hours training time but achieves 83.76% accuracy 🎯 Why This Project Matters for Recruiters End-to-End ML Pipeline - Shows ability to implement complete ML system from scratch Research-Based Decision Making - Implemented 6 models instead of guessing which is best Interpretability Focus - Understanding ML decisions is crucial for production systems Real-World Problem - Crisis detection has genuine impact Complete Documentation - Professional code and comprehensive explanations Multiple Technologies - Python, Pandas, Scikit-learn, TensorFlow, BERT transformers Communication Skills - Ability to explain complex ML concepts clearly 📚 Documentation HOW_IT_WORKS.md - Technical deep dive into each component RESULTS.md - Detailed analysis of all 6 models INTERPRETABILITY.md - How interpretability percentages were calculated LEARNING_JOURNEY.md - Complete learning process explanation 🔄 Model Comparison & Selection Why Not Deep Learning? Dataset too small (7,613 tweets, deep learning needs 50,000+) No GPU available (BERT needs GPU) LSTM/BERT took long but didn't outperform simple models much Interpretability more important than marginal accuracy gains Why Logistic Regression is Production Choice If accuracy was priority: 80.78% accuracy (vs 61% rule-based) 70% interpretable (can see which words matter) 0.06 seconds training (instant) Linear model, easy to understand Why BERT Achieves Best Accuracy Pre-trained on massive text corpus 110 million parameters Learns deep language understanding Problem: Complete black box, unexplainable predictions 🔮 Future Improvements Expand Signal Dictionary - Currently 54 words, could add 200+ Multi-Label Classification - Identify multiple crisis types (earthquake, fire, flood) Real-Time Processing - Deploy as API for live social media monitoring Confidence Calibration - Better uncertainty estimates Multilingual Support - Detect crises in other languages Hybrid Approach - Combine rule-based and statistical models 📝 References Papers Used "Paper 3: Signal Words in Crisis Detection" - GTU Mini Project "Why Should I Trust You?" - LIME paper on interpretability "Attention is All You Need" - Transformer architecture (BERT) Datasets Kaggle Disaster Tweets Dataset (7,613 labeled tweets) Libraries Scikit-learn - Machine Learning TensorFlow/Keras - Deep Learning Transformers - BERT Fine-tuning Pandas - Data Manipulation Matplotlib/Seaborn - Visualization 📄 License This project is licensed under the MIT License - see LICENSE.txt for details. 🤝 Contributing Suggestions for improvements welcome! Open an issue or submit a pull request. 📞 Contact LinkedIn: [( https://www.linkedin.com/in/miasa-brunel-christiano-567bb7339/ )] ⭐ If you found this project useful, please consider giving it a star!
CrisisSignalDetector is a machine learning system that identifies crisis-related tweets in real-time social media streams. The project demonstrates a complete ML pipeline from data preprocessing through model evaluation, comparing 6 different algorithms to determine the optimal solution for interpretability and accuracy.
Key Achievement: Implemented 6 ML models and achieved evidence-based decision making instead of speculation about model performance.
Input: Raw Tweet Text ↓ Text Preprocessing (clean, lowercase, remove noise) ↓ Feature Extraction (signal words, TF-IDF vectorization) ↓ ML Models (6 different algorithms) ↓ Evaluation (accuracy, precision, recall, F1-score) ↓ Output: Crisis/Non-Crisis with Confidence Score
crisis-signal-detector-nlp/ ├── README.md # Project documentation ├── RESULTS.md # Complete results summary ├── HOW_IT_WORKS.md # Technical explanation │ ├── data/ │ ├── X_train_clean.csv # Training tweets (5,329) │ ├── y_train.csv # Training labels │ ├── X_test_clean.csv # Test tweets (2,284) │ ├── y_test.csv # Test labels │ └── signal_words_dict.json # 54 signal words, 12 categories │ ├── notebooks/ │ ├── PHASE_1_Data_Preparation.ipynb │ ├── PHASE_2_Signal_Word_Dictionary.ipynb │ ├── PHASE_3_Build_Crisis_Detector.ipynb │ ├── PHASE_4_Visualization_Reporting.ipynb │ ├── PHASE_5_Model_Comparison.ipynb │ └── LIVE_DEMO.ipynb # Interactive demo for faculty │ ├── src/ │ ├── crisis_detector.py # Main detector class │ ├── data_preprocessing.py # Data cleaning functions │ └── evaluation.py # Metrics calculation │ ├── results/ │ ├── crisis_detector.pkl # Trained model │ ├── model_comparison_results.csv # All 6 models' metrics │ ├── confusion_matrix.png # Visualization │ └── metrics_comparison.png # Side-by-side comparison │ └── docs/ ├── HOW_INTERPRETABILITY_CALCULATED.md ├── HOW_MODELS_LEARN.md └── LEARNING_JOURNEY.md
git clone https://github.com/yourusername/crisis-signal-detector-nlp.git cd crisis-signal-detector-nlp pip install -r requirements.txt
from src . crisis_detector import CrisisDetector import json # Load detector and signal words detector = CrisisDetector ( threshold = 0.1 ) with open ( 'data/signal_words_dict.json' ) as f : signal_words = json . load ( f ) # Test on sample tweets tweets = [ "earthquake hits california help needed" , "beautiful day at the beach" , "fire spreading evacuation urgent" ] for tweet in tweets : result = detector . predict ( tweet ) print ( f" { tweet } " ) print ( f"Crisis: { result [ 'is_crisis' ] } , Confidence: { result [ 'confidence' ]:.2f } \n " )
Model Figures & Evaluation Curves (4 Images)
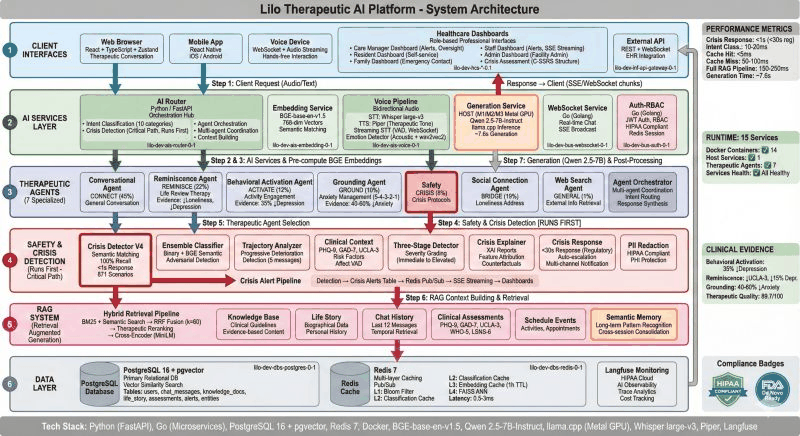
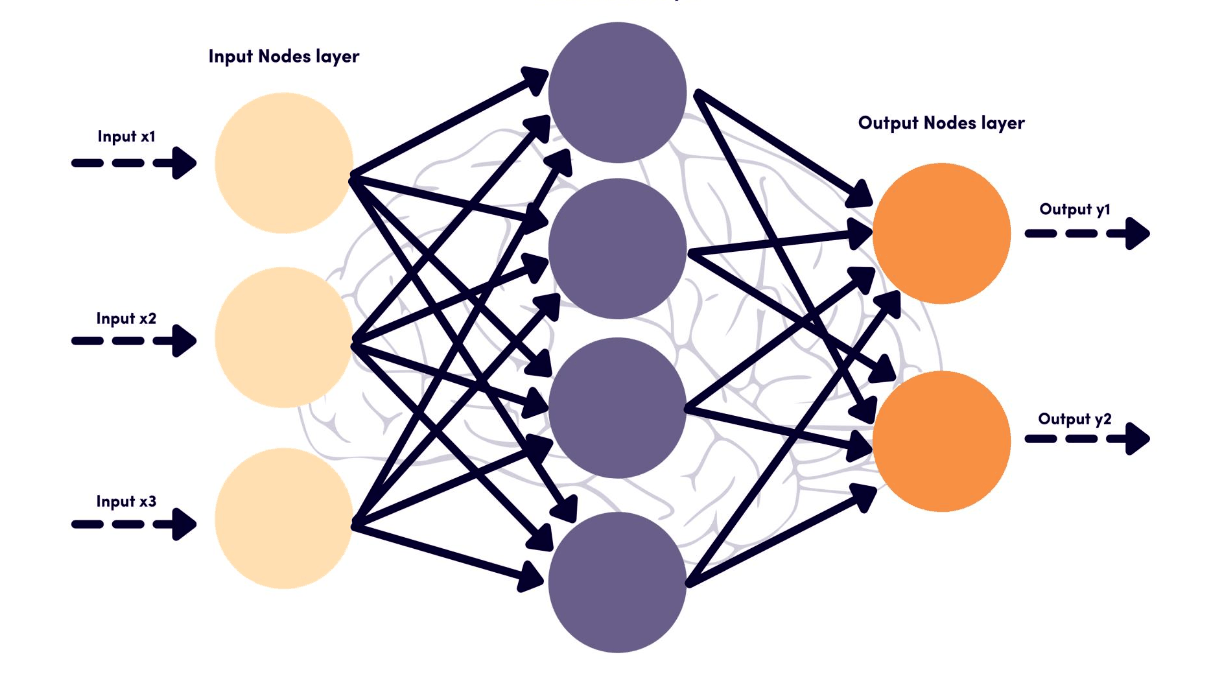
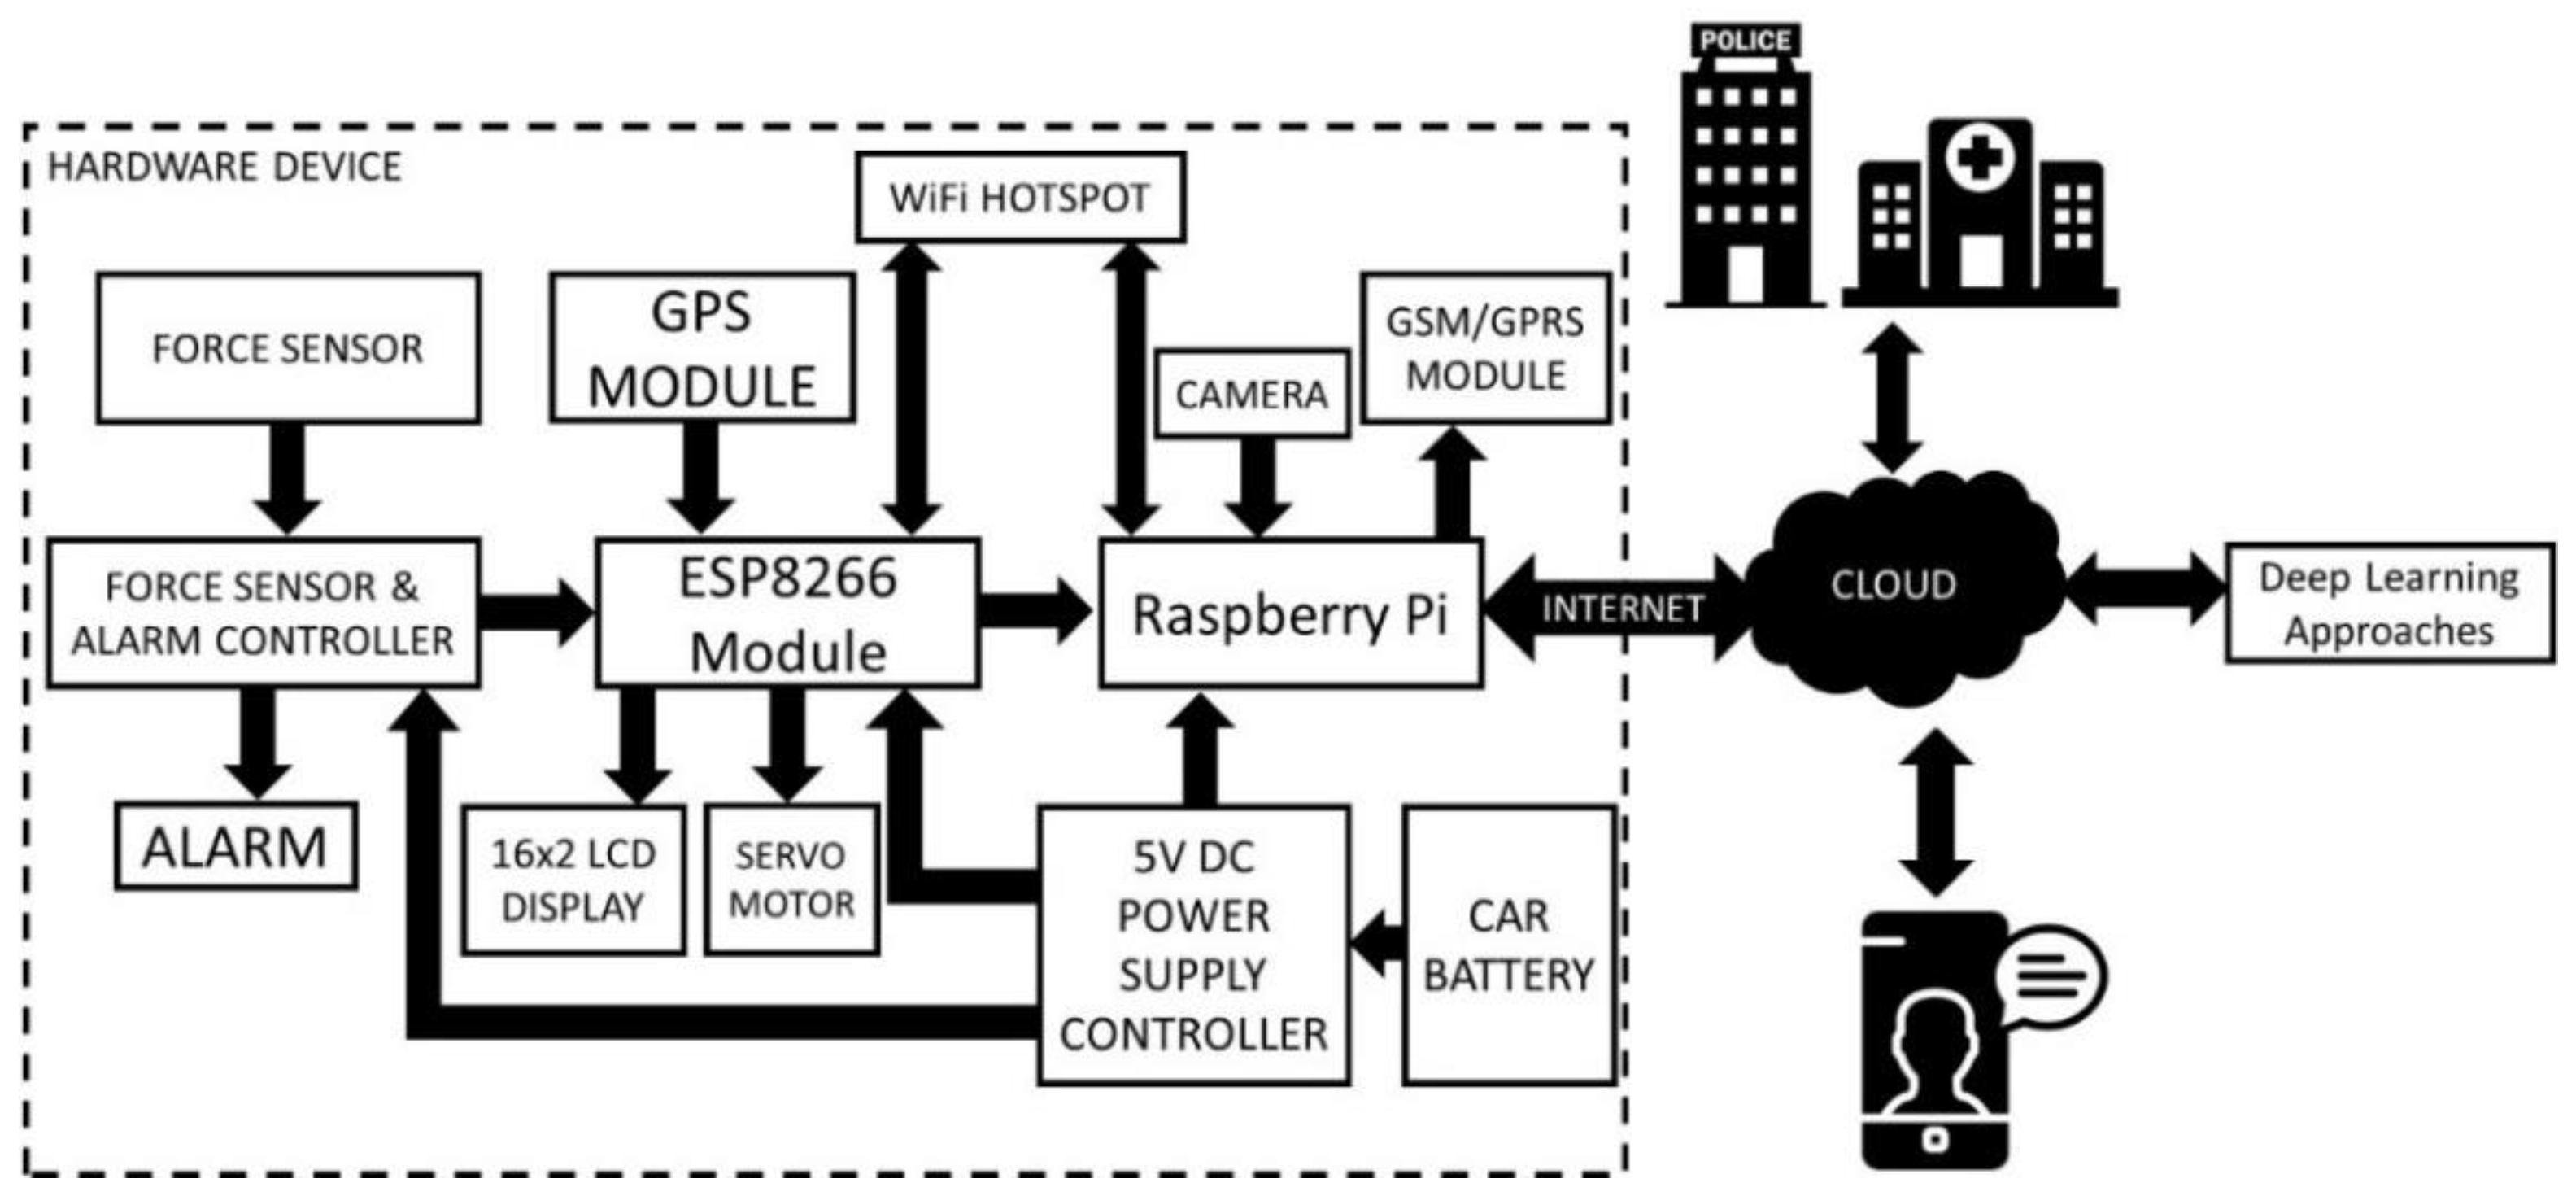
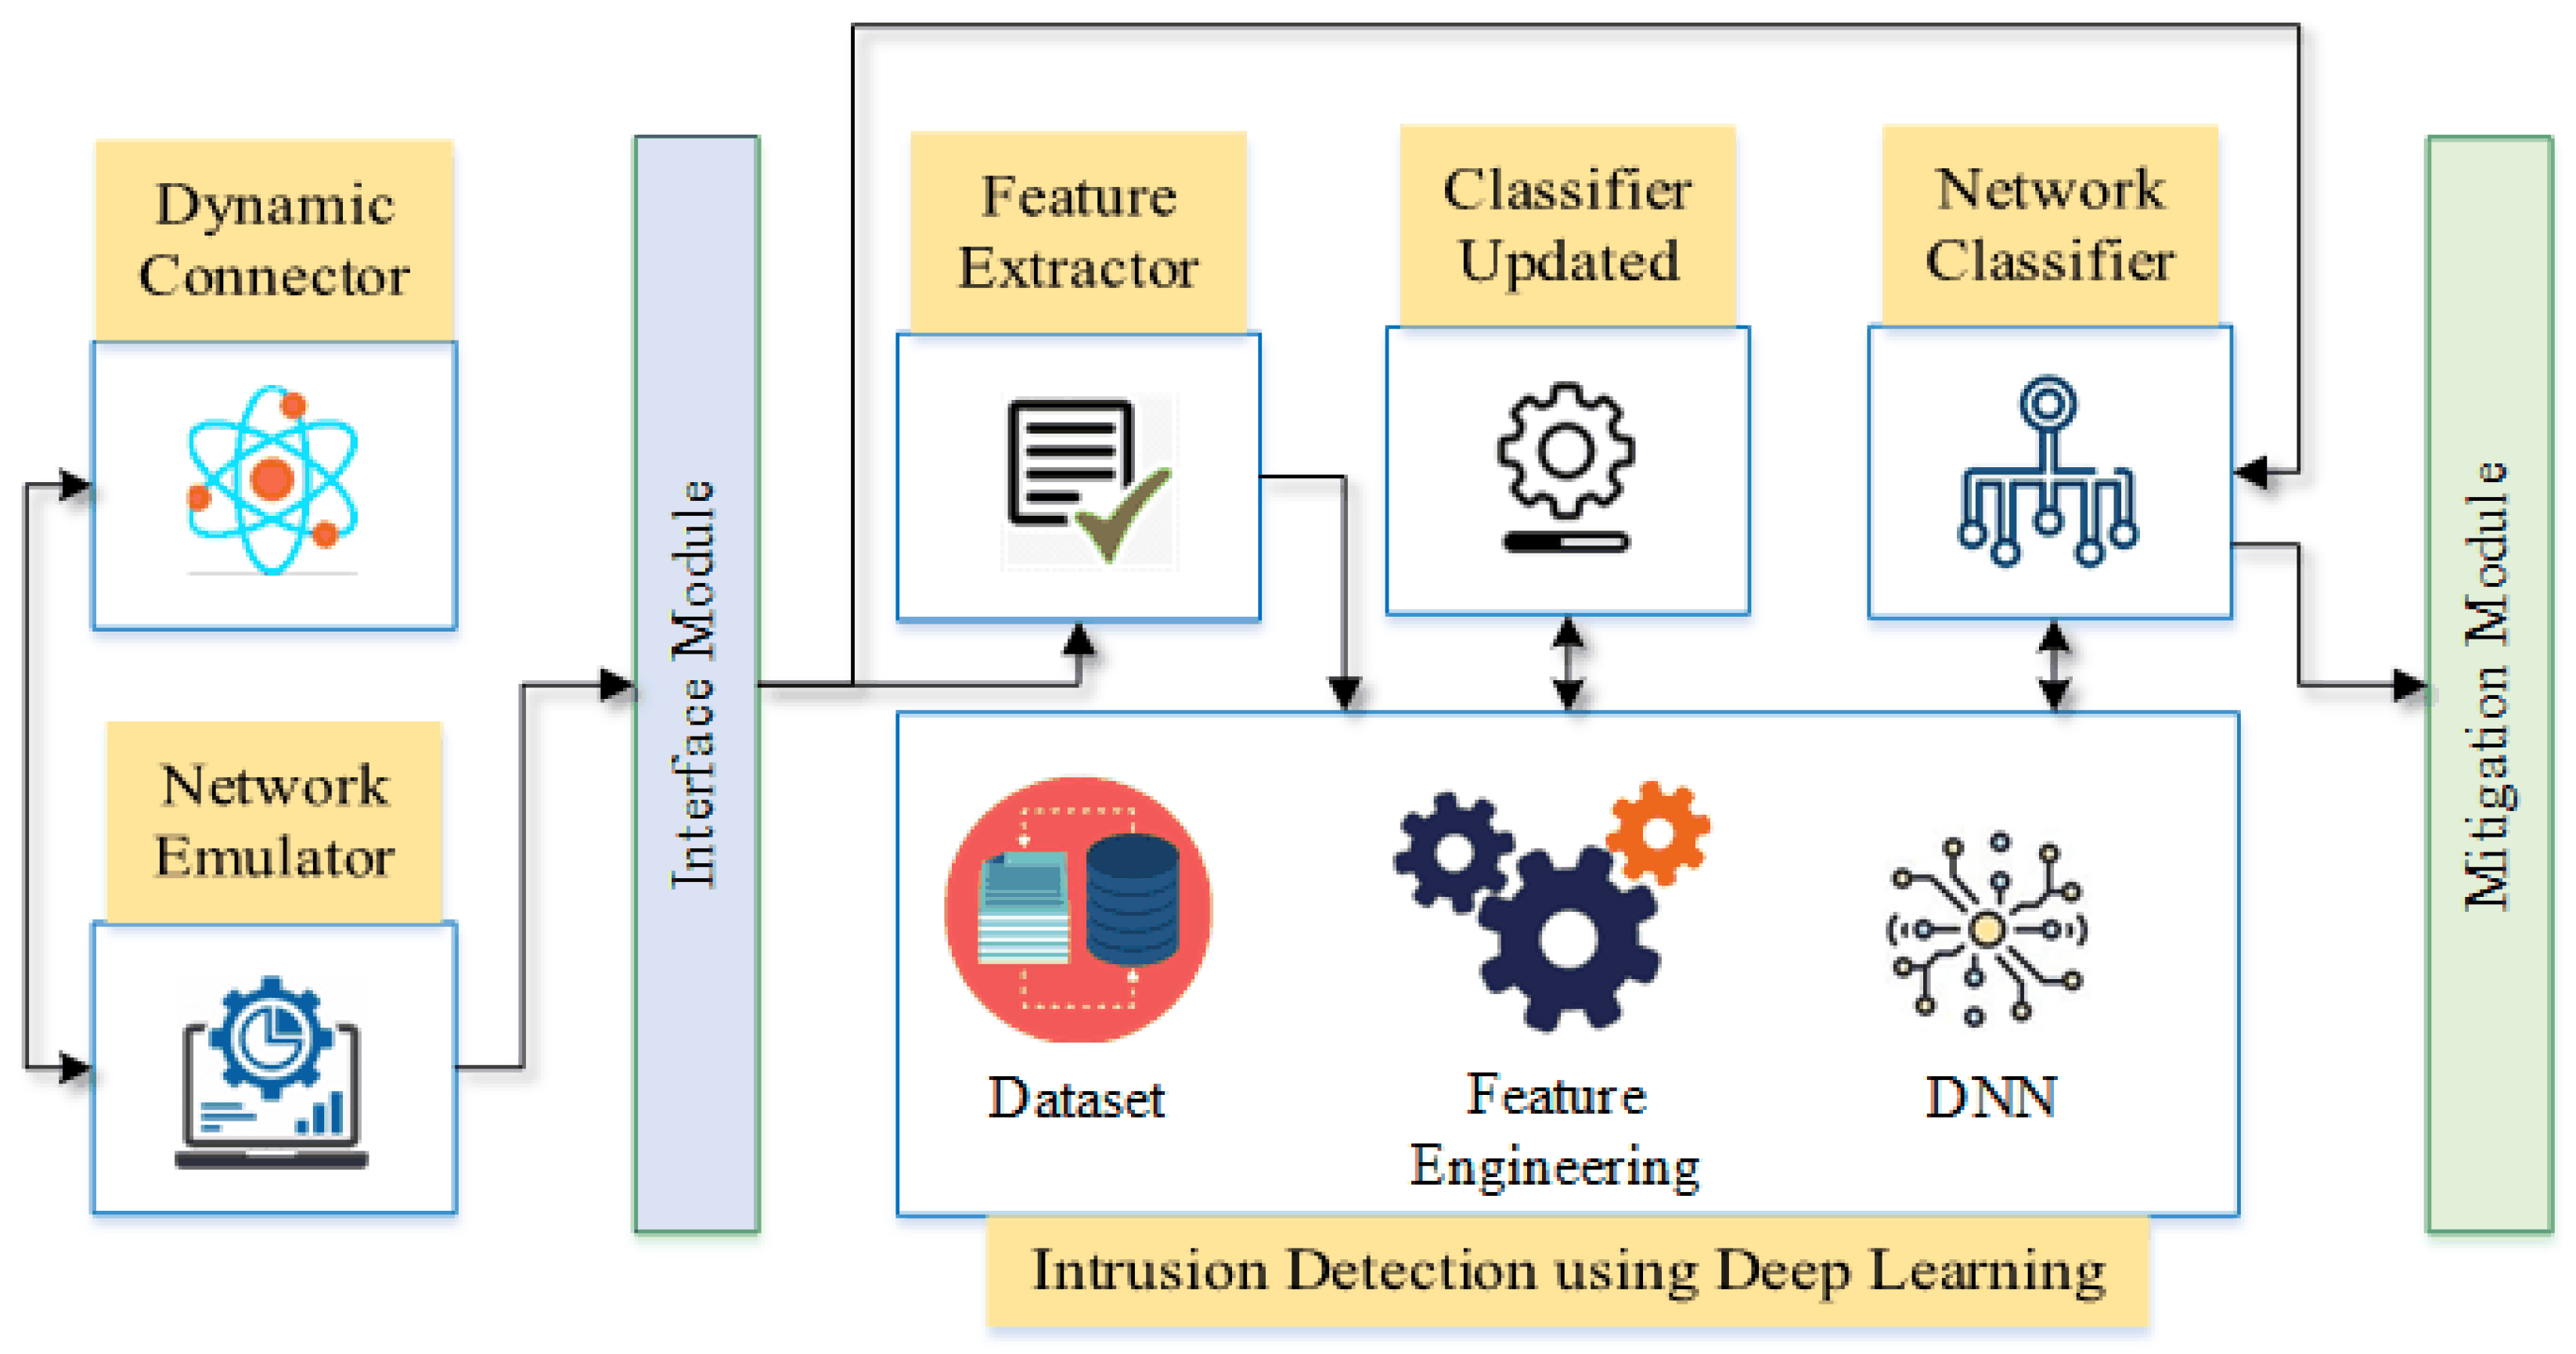
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)