Complete Technical Paper Content — Ai Data Lineage
1. Executive Abstract, Problem Formulation & Background
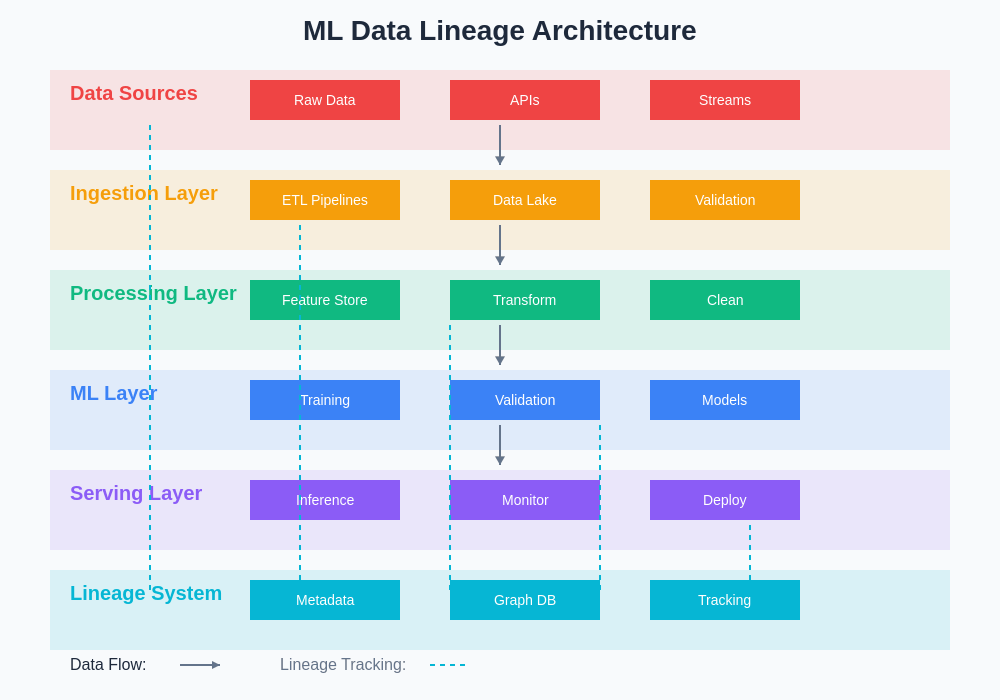
In computing and data management, data mapping is the process of creating data element mappings between two distinct data models. Data mapping is used as a first step for a wide variety of data integration tasks, including:
Data transformation or data mediation between a data source and a destination Identification of data relationships as part of data lineage analysis Discovery of hidden sensitive data such as the last four digits of a social security number hidden in another user id as part of a data masking or de-identification project Consolidation of multiple databases into a single database and identifying redundant columns of data for consolidation or elimination For example, a company that would like to transmit and receive purchases and invoices with other companies might use data mapping to create data maps from a company's data to standardized ANSI ASC X12 messages for items such as purchase orders and invoices. Modern data mapping processes increasingly use artificial intelligence (AI) and machine learning (ML) techniques to automate and optimize these tasks.
2. Related Work, Literature Survey & Algorithmic Foundations
An AI agent benchmark is a standardized test designed to evaluate the performance of AI agents on various tasks. These tests are intended for comparing different agents' capabilities in areas such as programming, reasoning, performing tasks on websites, and so on. They have significant overlap with language model benchmarks. See the overview section of that article for some foundational concepts not repeated here. They also have significant conceptual overlap with benchmarks in reinforcement learning and robotics, because the very concept of an "AI agent" is formulated from reinforcement learning theory, and the most prominent examples of AI agents before the early 2020s were robots.
Automatic verifier: a program that checks the output deterministically. It can be checking that the agent output is verbatim equal to the right answer, or running the agent output source code into a program test harness, or some other method. However, this cannot be done for many types of more qualitative evaluation, such as checking whether a trajectory cheated. AI verifier: the output is given to an AI to judge. May be not deterministic, thus less replicable. Normally, this is done by LLM-as-a-judge. The judge is usually a frontier model, since it is hard to qualitatively judge the work of someone with more capacity. However, the frontier moves, so the verifier moves, making past and future benchmark scores less comparable. Furthermore, the choice of the judge can significantly affect benchmark scores. Human verifier: the output is given to a human to judge. The most expensive and the least replicable. Rarely used. An agent is defined by the ability to perform multi-step actions, and a complete multi-step action is called an episode, a rollout, or a trajectory. Because of this, the length of an episode is a critical measurement for agency. It is called the time horizon, a terminology that came from Markov decision process in reinforcement learning. Time horizon is not a single measure, but a cluster of measures: the number of rounds, the number of tool-calls, the wallclock time, the number of tokens, and so on. Which time horizon to choose is a design question, so different benchmarks may choose differently. Sometimes, not only the output, but also the agent episode itself is subject to scrutiny. For example, ExploitGym uses an LLM to check that the agent has obtained the answer in the intended way.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
human baseline: How well humans performed on the same test item, under conditions close to the agent's test condition. human baseline time horizon: How long it would take a human to complete the same test item. Can be statistically estimated by measuring several human baselines. Some of the longest time-horizons are estimated without measurement, since they are too expensive for the benchmark constructors to measure even once (on the order of weeks or more).
When running a benchmark on an agent, the task cost itself is recorded, and agents are compared for not just their benchmark performance, but on a cost-performance curve. The same agent is benchmarked multiple times at different task cost levels. This makes running a benchmark more costly. There are several types of "cost" usually used: the wallclock time, the output's token count, and the monetary cost. Some of the benchmark items are simply difficult to run, since they may require extensive or difficult setup. For example, even OpenAI was only able to benchmark 477 of the 500 items in SWE-bench Verified when benchmarking o3 and o4-mini, due to infrastructure challenges. As frontier model capability increases, agency benchmarks are increasingly subject to unique problems not found in other types of benchmarks.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
In certain areas, frontier agents have saturated essentially all benchmarks. This is particularly true of mathematics, where frontier progress is now measured by solving open problems. Frontier agents are increasingly evaluation-aware, i.e. aware that they are acting in an agency benchmark. This is similar to observer effect. Frontier agents increasingly reward-hack, acting to increase scores in a way that violates the task requirement. This is similar to Goodhart's law, but done by the agents rather than the researchers. Examples of reward-hacking range from simply web-searching the benchmark answers (if the agent harness runs in a container that can access the internet), using git to find the correct patch (if repository history has not been cleaned), all the way to the OpenAI–HuggingFace incident.
BrowseComp: 1,266 questions that requires internet browsing for finding a short factual answer. Adversarial against GPT-4o with and without browsing, OpenAI o1, and an early version of the Deep Research model. GAIA: 450 questions with unambiguous answers that require information that can be obtained by browsing the Internet, requiring different levels of tooling and autonomy to solve. Divided into 3 difficulty levels. Mind2Web: 2,350 tasks collected from 137 websites, and crowdsourced action sequences. The task is to reproduce the action sequence. SpreadsheetBench: 912 real-world spreadsheet manipulation tasks scraped from public Excel help forums, spanning formula writing, data cleaning, filtering and layout edits in diverse formatting. Scored automatically on 2729 test cases at cell-, sheet- and overall levels. WebArena: 241 mock-up websites based on real-world websites (Reddit, GitLab, Magento's admin portal, etc), and 812 tasks to be performed on the websites. The tasks include information-seeking, site navigation, and content and configuration operation. WebVoyager: 643 multimodal tasks based on 15 task environments, each environment a fully self-hosted popular website, such as GitLab and Wikipedia. Evaluation is by screenshotting the action sequence and asking a vision language model to judge. Terminal-bench: A collection of 66 complex tasks in the Linux terminal. Updated in versions. OSWorld: 369 multimodal computer-using tasks, involving multiple real web and desktop apps and OS file I/O, in Ubuntu. Each task includes an initial state setup configuration, and is tested by an execution-based evaluation script. 8 requires Google Docs access, and thus are impossible to run in an offline sandbox (necessary to prevent cheating by looking up OSWorld answers online). 30 tasks were designed to be impossible. For these, the success condition is for the agent must state that it is impossible and give up. 43 tasks were also translated to a Windows version (for example, converting LibreOffice to Microsoft Office, etc). No tasks in macOS due to copyright. Cleaned up to OSWorld-Verified in 2025-07. A new version, OSWorld 2.0, was released on 2026-06-26, containing 108 new tasks. Windows Agent Arena: 154 multimodal tasks with the same format as OSWorld. Only in Windows.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
AutomationBench: a benchmark developed by Zapier, on cross-application workflow orchestration via REST APIs, using 47 real tools across 6 business functions (Sales, Marketing, Operations, Support, Finance, and HR). Based on real monthly tasks executed by Zapier itself. APEX-agents: a benchmark showing how leading AI models hold up doing actual white-collar work tasks, such as consulting, investment banking, and law. Vals Index, run by Vals. Aggregation of benchmarks across 4 sectors (Finance, Coding, Legal, and Tax) weighted in proportion to its share of U.S. GDP. Intended to measure the potential economic impact. Harvey's Legal Agent Benchmark: 1200 tasks for legal work, across 24 practice areas, evaluated by over 75000 expert-written rubric. The task is to produce legal work (such as legal discovery) based on instruction and a folder of legal documents. Part of the Vals Index Remote Labor Index, 240 items, each a self-contained work unit sourced directly from Upwork, a platform for experienced freelance professionals. Constructed by Scale AI labs. GDPval: 1,320 tasks evaluating AI agents on real-world knowledge-work deliverables across 44 occupations from the top 9 U.S. GDP-contributing industries. Tasks made by professionals averaging 14 years of experience. The full evaluation is by blinded expert pairwise comparison against human expert deliverables, each comparison costing 1 human hour on average. A gold subset of 220 tasks is publicly available. The public set can be graded by a finetuned version of GPT-5. The held-out set of 1,100 tasks is only available internally in OpenAI, and external models cannot be submitted for grading on this set. TAU-bench (Tool-Agent-User benchmark, also written as τ-bench): Two environments (retail, airline booking) that test for an agent to fulfill user instructions, interactively over multiple turns of dialogue. The user is simulated by a language model. Updated to TAU2-bench (τ²-bench), which focuses on telecom applications. Tasks are synthesized by LLM-generated product requirements document, agent database schema, agent tools, and user environments ("mocked phone"). Updated to TAU3-bench (τ³-bench), which adds tests for operate over large collections of internal company documents, and duplex voice.
ScienceAgentBench: 102 multimodal data science tasks, each being a real scientific data-driven discovery problem reframed as a code-generation task. Agents must produce a complete Python program file that implements the task, can run in isolation, and saves its outputs. In the domains of Bioinformatics, Computational Chemistry, Geographical Information Science, and Psychology & Cognitive Neuroscience. Sourced from 44 peer-reviewed publications that have released their code and data under permissive licenses. Each task is validated by domain experts. SWE-bench: 2,294 tasks in software engineering. Each task is to fix well-defined, small issues with clear descriptions, drawn from real GitHub issues and corresponding pull requests, from 12 popular Python repositories. Given a codebase and an issue, the task is to edit the codebase to solve the issue. Most are from the 2018-2023 period. It has 2 subsets: Lite (300 problems that are faster to run), Verified (human-validated subset of 500 problems reviewed by software engineers). Each task is evaluated by checking that certain tests that pass pre-patch still pass post-patch ("pass-to-pass"), and certain other tests that fail pre-patch pass post-patch ("fail-to-pass"). The Verified version is deprecated by OpenAI in 2026-02, since many remaining failures reflected flawed or underspecified tests. They recommended the public split of SWE-bench Pro. SWE-bench Pro was released later as an update to SWE-bench, containing 1,865 harder items. This has 3 splits: public, held-out, and proprietary (only available to a select set of early-stage startups). Multi-SWE-bench: 1,632 problems across 7 languages: Java, TypeScript, JavaScript, Go, Rust, C, and C++. Similar to SWE-bench. SWE-bench Multimodal: a variant of SWE-bench, with 619 task instances from 17 popular JavaScript repositories, each featuring images that are required for solving the task. SWE-Lancer: 1,488 freelance software engineering tasks from Upwork. Two types of tasks: implementation tasks (from $50 bug fixes to $32,000 feature implementations), called "IC" (for "Individual Contributor"); "Management" tasks, where the model must choose between technical implementation proposals. A subset of 502 are open-sourced as SWE-Lancer-Diamond. Produced by OpenAI. DeepSWE: 113 tasks spanning 91 active open-source repositories across 5 languages. Constructed to be a harder and contamination-free version of SWE-Bench. Every task is written from scratch to prevent contamination. Task prompts are shorter and solutions are longer. SWE-Marathon: 20 long-horizon (averaging 27.2M tokens) software engineering tasks. FrontierSWE: 17 long-horizon software engineering tasks. Each trial has a time limit of 20 hours. The wallclock run time of the submission is measured. FrontierSWE v2 adds 34 tasks and retires 4 tasks as being unscorable. Each task has a deterministic automated verifier. The wallclock time is replaced by CPU instruction count, heuristically weighted by how costly each instruction is. MirrorCode: 25 long-horizon software engineering tasks over 6 programming languages. Each task asks for a clean-room reimplementation of an entire program. The agent has access to a specification of the original program, some test-cases, and can send arbitrary inputs to the original program (black-box oracle). The reimplementation is tested against the original on whether they produce identical outputs. Each task would take a human engineer an estimated weeks to months to complete. 22 tasks were released, the other 3 heldout as private test set. Developed by EpochAI and METR.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)