Complete Technical Paper Content — Ai Drone Navigation
1. Executive Abstract, Problem Formulation & Background
Mathematical Formulation 1.1: Loss Objectives and Optimization Dynamics for Ai Drone Navigation. The training protocol of ai drone navigation minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 1.2: Feature Extraction and Layer Formulations for Ai Drone Navigation. The primary computational backbone for Ai Drone Navigation incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 1.3: Stochastic Augmentation and Normalization Protocols for Ai Drone Navigation. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
2. Related Work, Literature Survey & Algorithmic Foundations
Deployment Optimization 1.4: TensorRT Acceleration and Edge Quantization for Ai Drone Navigation. Production deployment of Ai Drone Navigation focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Mathematical Formulation 2.1: Loss Objectives and Optimization Dynamics for Ai Drone Navigation. The training protocol of ai drone navigation minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 2.2: Feature Extraction and Layer Formulations for Ai Drone Navigation. The primary computational backbone for Ai Drone Navigation incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Data Pipeline 2.3: Stochastic Augmentation and Normalization Protocols for Ai Drone Navigation. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 2.4: TensorRT Acceleration and Edge Quantization for Ai Drone Navigation. Production deployment of Ai Drone Navigation focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Mathematical Formulation 3.1: Loss Objectives and Optimization Dynamics for Ai Drone Navigation. The training protocol of ai drone navigation minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Architecture Specification 3.2: Feature Extraction and Layer Formulations for Ai Drone Navigation. The primary computational backbone for Ai Drone Navigation incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 3.3: Stochastic Augmentation and Normalization Protocols for Ai Drone Navigation. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 3.4: TensorRT Acceleration and Edge Quantization for Ai Drone Navigation. Production deployment of Ai Drone Navigation focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Mathematical Formulation 4.1: Loss Objectives and Optimization Dynamics for Ai Drone Navigation. The training protocol of ai drone navigation minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 4.2: Feature Extraction and Layer Formulations for Ai Drone Navigation. The primary computational backbone for Ai Drone Navigation incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 4.3: Stochastic Augmentation and Normalization Protocols for Ai Drone Navigation. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Model Figures & Evaluation Curves (4 Images)
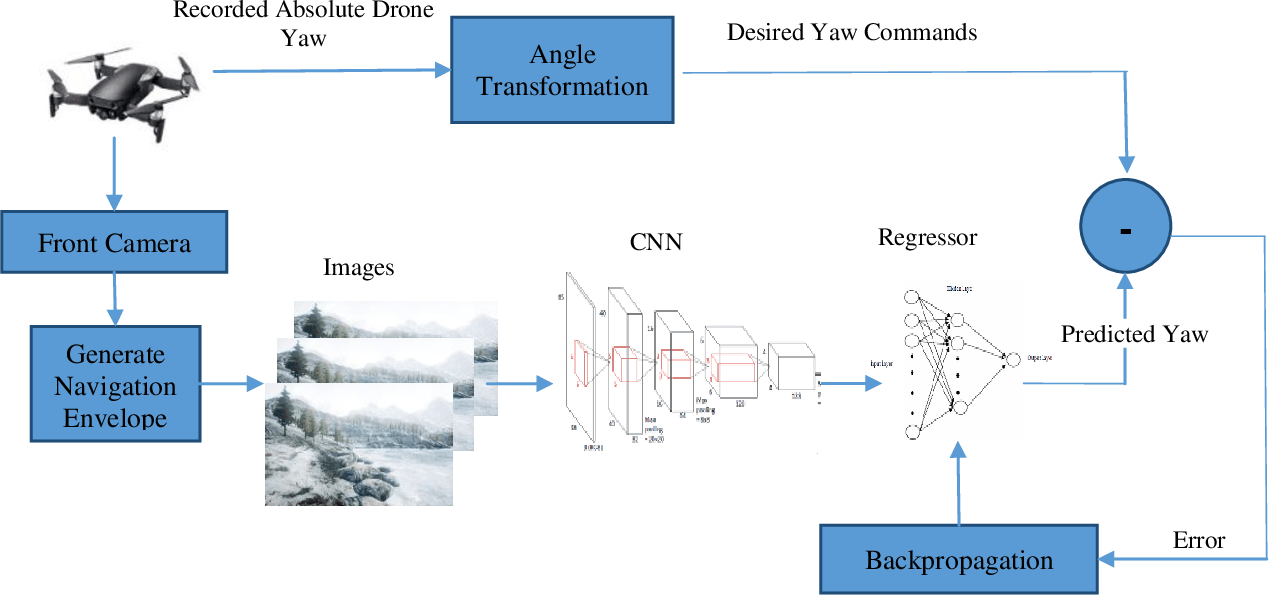
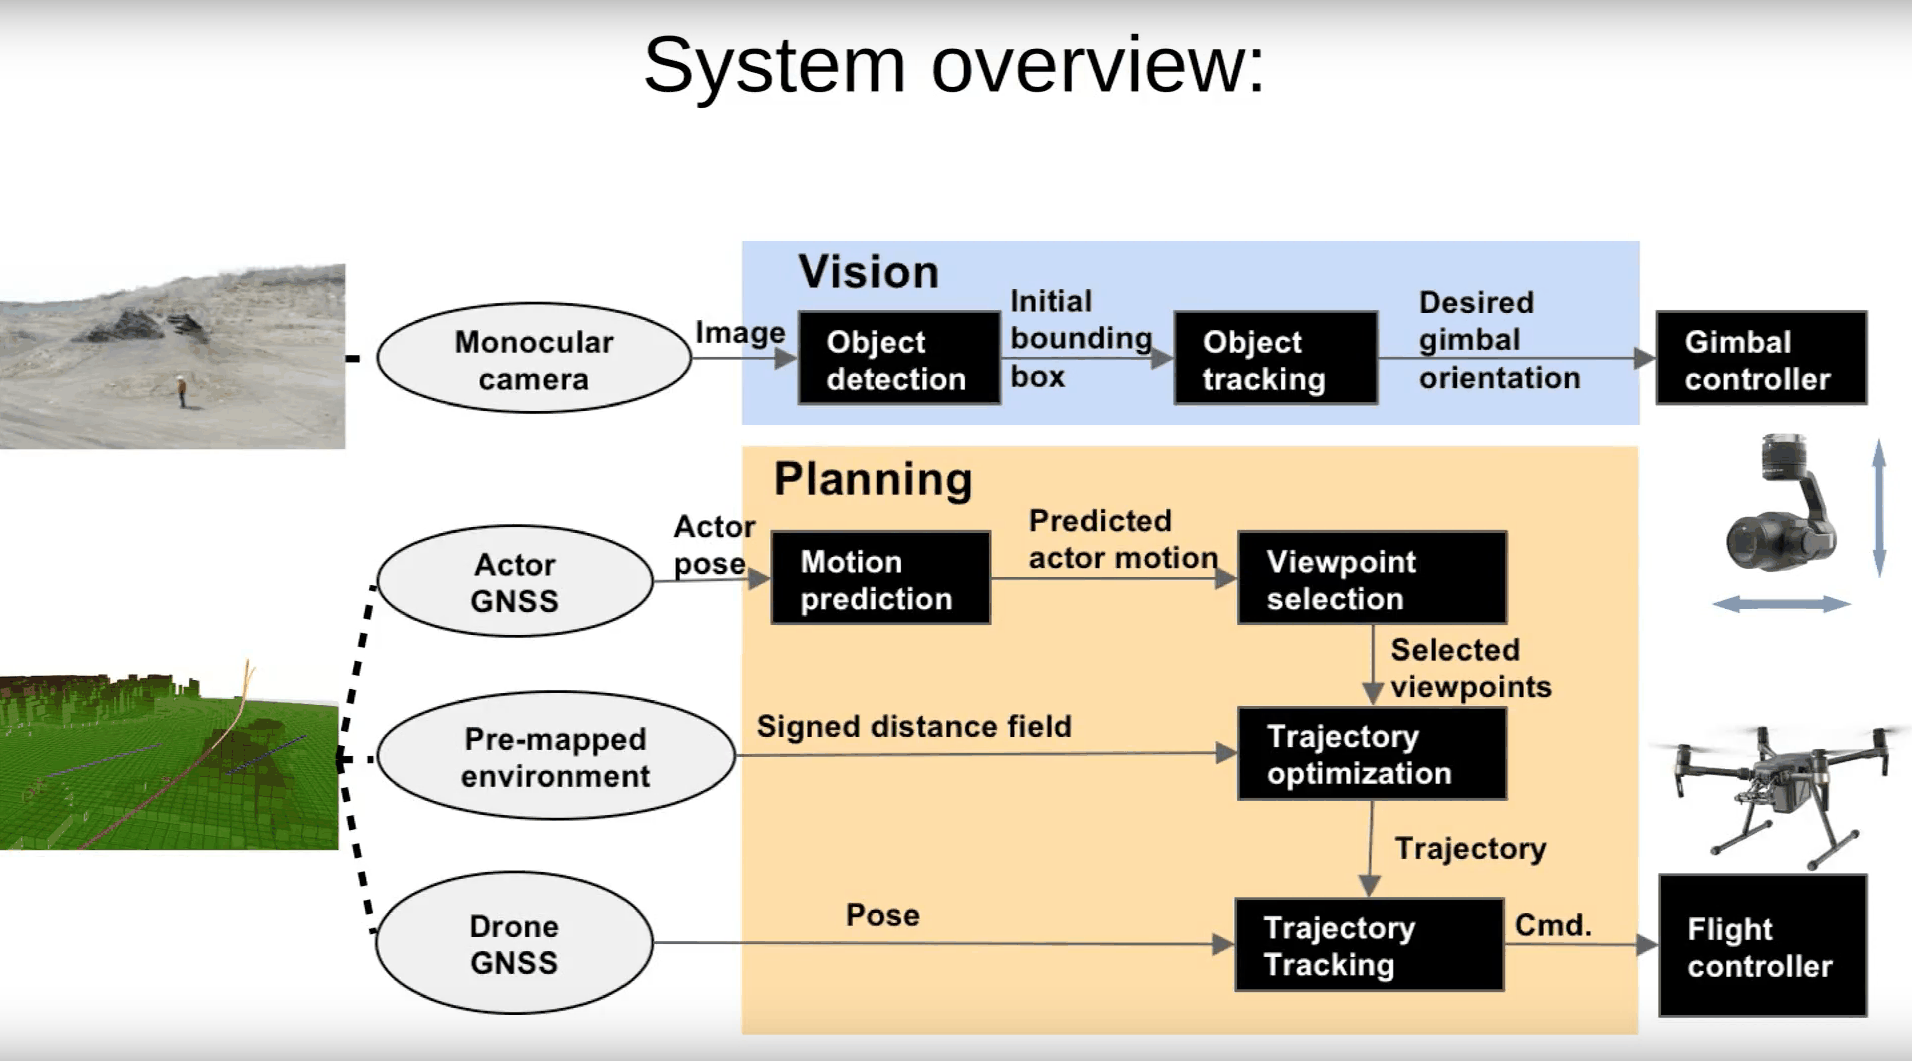
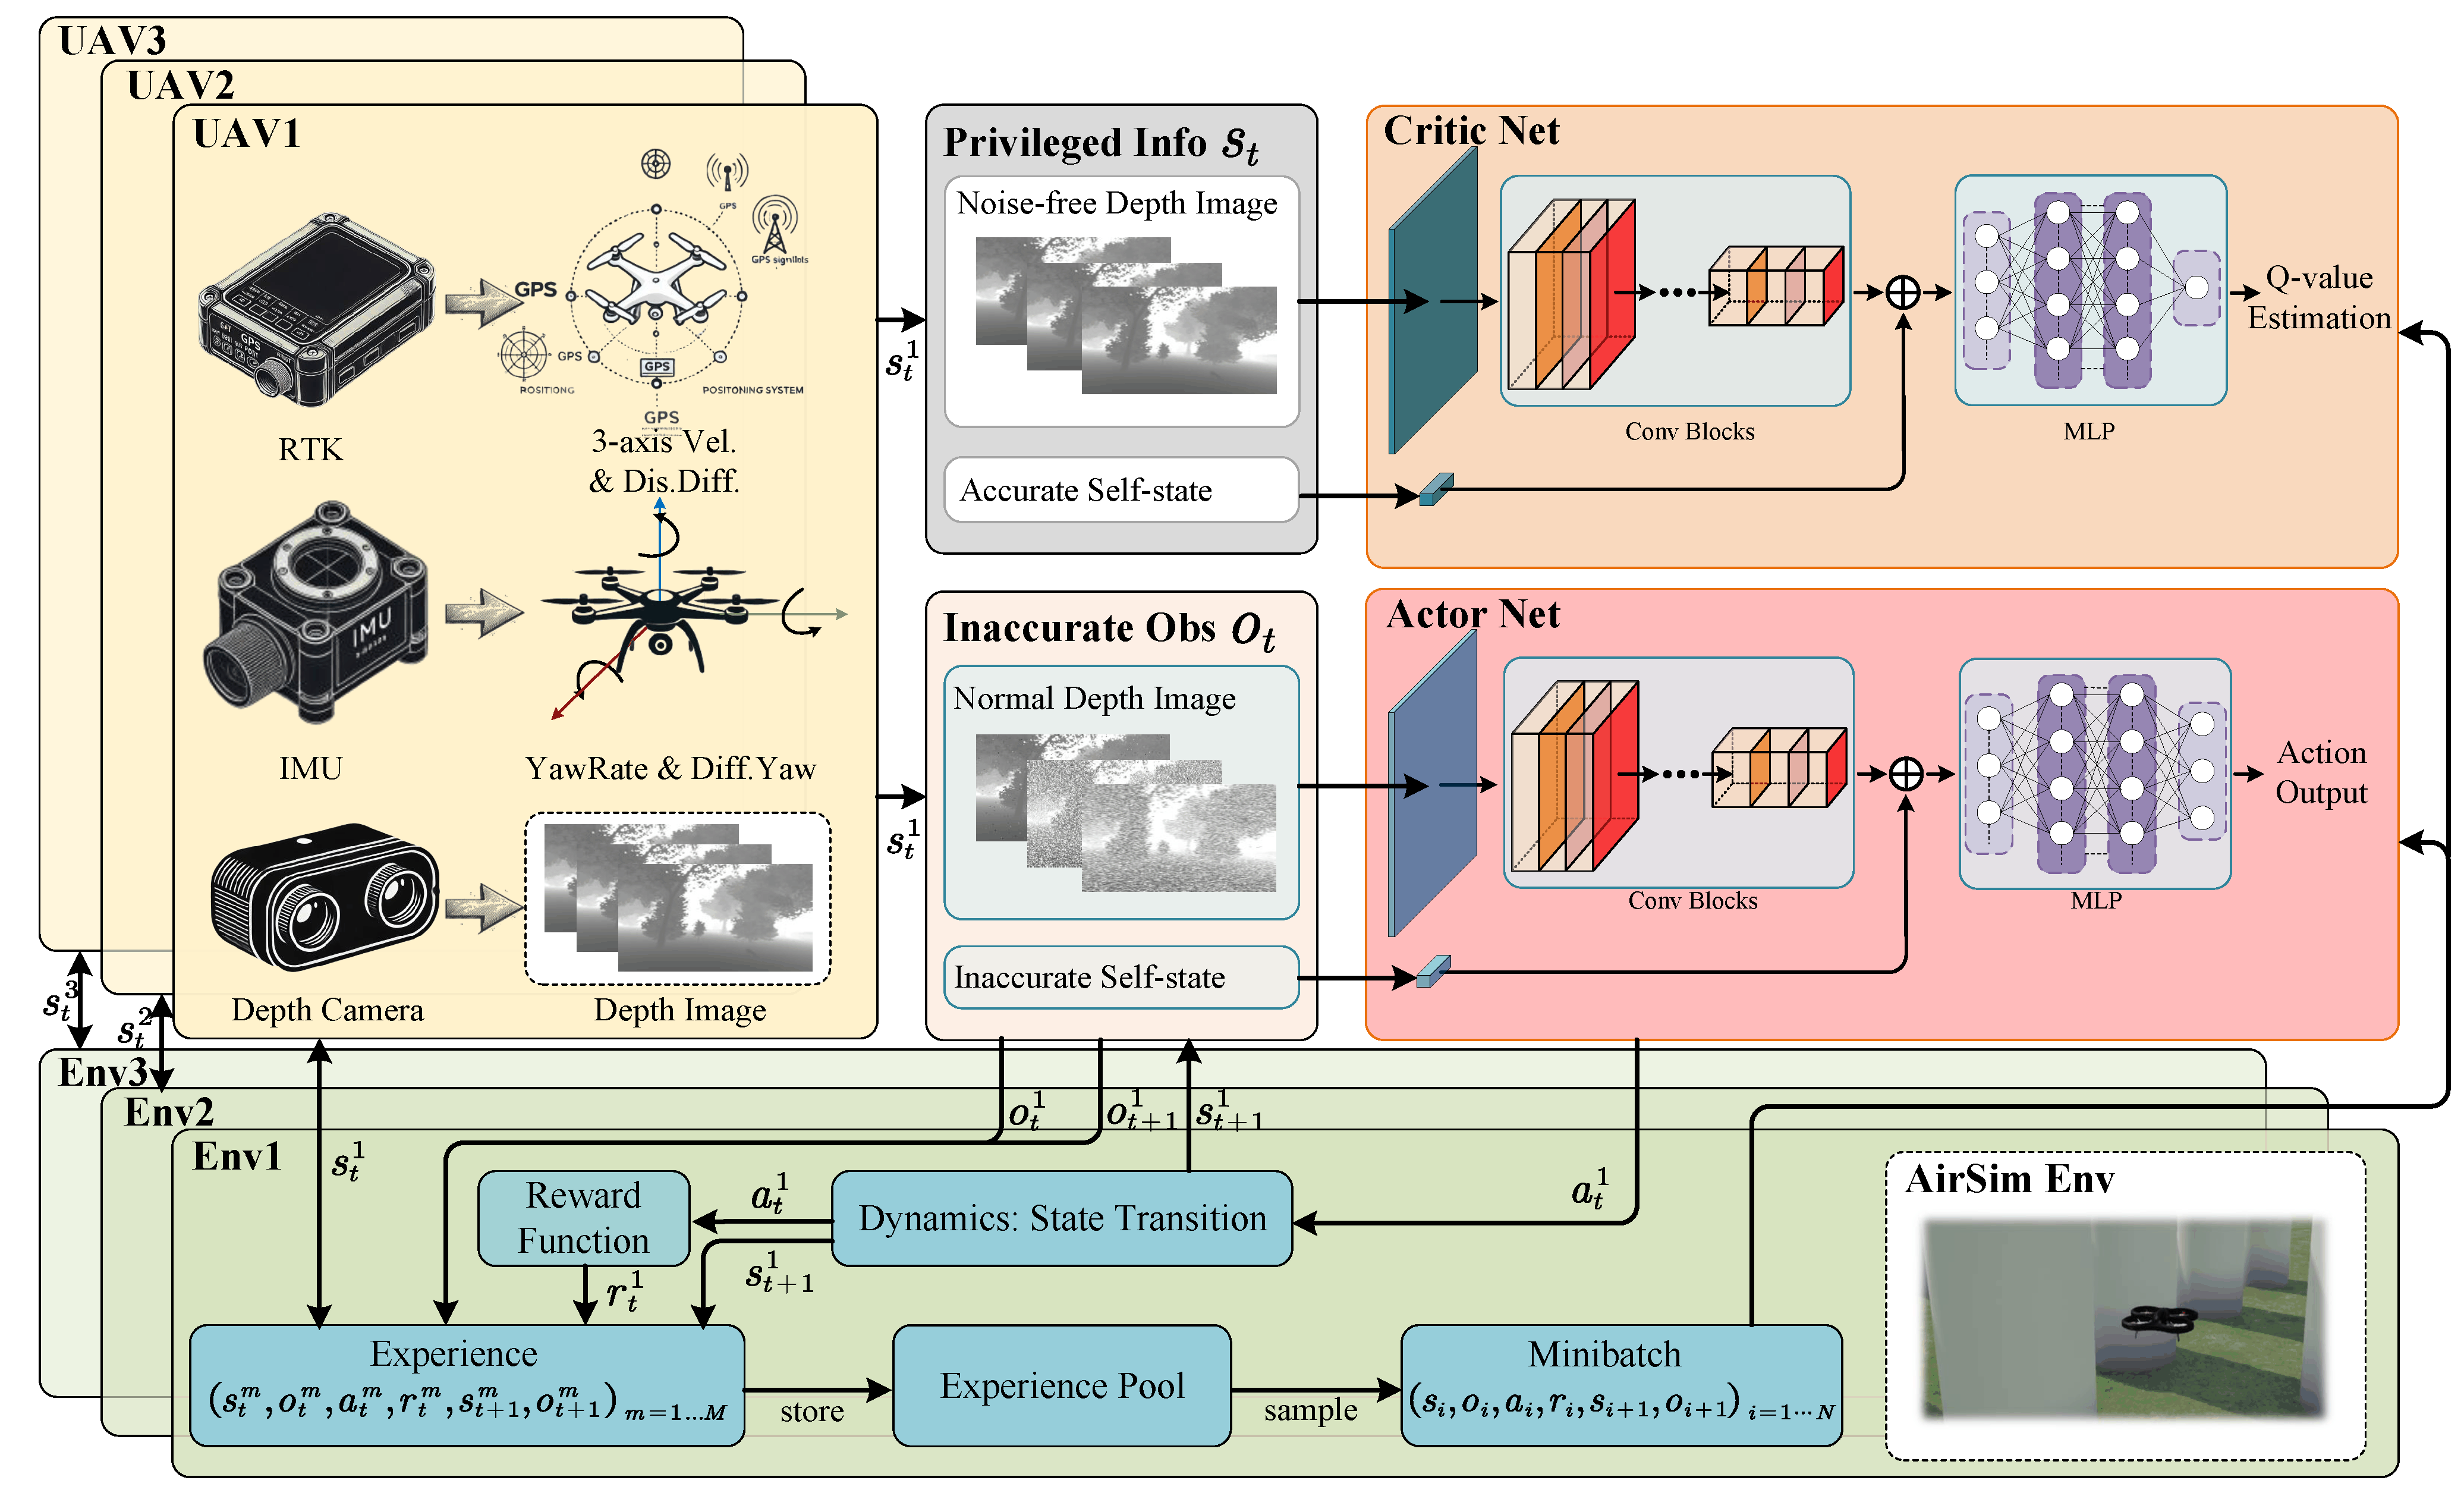
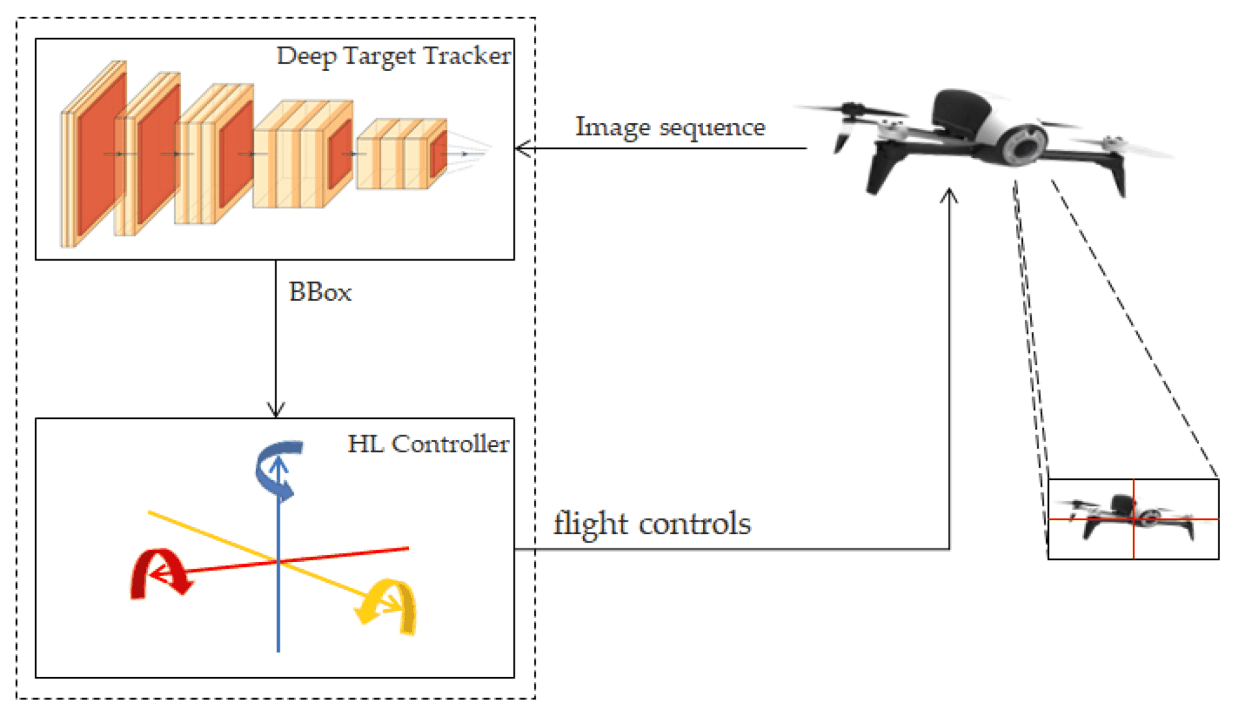
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)