Complete Technical Paper Content — Ai Drug Discovery
1. Executive Abstract, Problem Formulation & Background
[type=editor, ] [type=editor, ] [type=editor, ] [type=editor, ] [type=editor, ] [type=editor, ] [type=editor] Explainable Artificial Intelligence for Drug Discovery and Development - A Comprehensive Survey Roohallah Alizadehsani r.alizadehsani@deakin.edu.au Address: Institute for Intelligent Systems Research and Innovation (IISRI), Deakin University, Geelong, VIC 3216, Australia Sadiq Hussain Address: Department of Statistics, Dibrugarh University, Dibrugarh 786004 jiten_stats@dibru.ac.in Rene Ripardo Calixto Address: Department of Teleinformatics Engineering, Federal University of Ceará, Fortaleza 60455-970, Brazil reneripardo@gmail.com Victor Hugo C. de Albuquerque Address: Department of Teleinformatics Engineering, Federal University of Ceará, Fortaleza 60455-970, Brazil victor.albuquerque@ieee.org Mohamad Roshanzamir Address: Department of Computer Engineering, Faculty of Engineering, Fasa University, Vali asr Blvd, Fasa 74617-81189, Iran Mohamed Rahouti Address: Department of Computer & Information Science, Fordham University, Bronx, NY 10458, USA mrahouti@fordham.edu Senthil Kumar Jagatheesaperumal senthilkumarj@mepcoeng.ac.in Address: Department of Electronics and Communication Engineering, Mepco Schlenk Engineering College, Sivakasi, Tamil Nadu, India Abstract The field of drug discovery has experienced a remarkable transformation with the advent of artificial intelligence (AI) and machine learning (ML) technologies. However, as these AI and ML models are becoming more complex, there is a growing need for transparency and interpretability of the models. Explainable Artificial Intelligence (XAI) is a novel approach that addresses this issue and provides a more interpretable understanding of the predictions made by machine learning models. In recent years, there has been an increasing interest in the application of XAI techniques to drug discovery. This review article provides a comprehensive overview of the current state-of-the-art in XAI for drug discovery, including various XAI methods, their application in drug discovery, and the challenges and limitations of XAI techniques in drug discovery. The article also covers the application of XAI in drug discovery, including target identification, compound design, and toxicity prediction. Furthermore, the article suggests potential future research directions for the application of XAI in drug discovery. The aim of this review article is to provide a comprehensive understanding of the current state of XAI in drug discovery and its potential to transform the field. keywords FPGA ,Data center ,Cloud Computing ,Hardware Accelerators ,Big data † † corresponding: Corresponding author 1 Introduction The field of drug discovery and development has started playing a significant role in the healthcare industry, in order to find new compounds and therapeutic targets that can successfully cure a variety of diseases [ 1 ] . The traditional drug development method has been laborious, and resource-intensive, and experienced major difficulties in identifying promising therapeutic candidates over the previous few decades. However, the landscape of drug development has undergone a radical upheaval since the advent of artificial intelligence (AI) and machine learning (ML) technologies, which promise to quicken and improve the process [ 2 ] . AI and ML models have shown the ability to analyze enormous datasets, discover insightful patterns, and generate predictions for identifying prospective drug candidates and targets. Lead optimization [ 3 ] , virtual screening [ 4 ] , compound design [ 5 ] , and medication repurposing [ 6 ] are just a few of the domains where the use of AI and ML in drug development has already produced promising outcomes. These models have the potential to greatly overshoot the success rate of drug discovery and decrease the time and expense involved as they become more complex and potent. As AI and ML models become more complicated, a major issue in the area has emerged, which is the lack of transparency and interpretability [ 7 ] . Although these models have excellent predictive powers, it still remains challenging to explain why they make such predictions. This lack of interpretability can make it more challenging for researchers, doctors, and regulatory bodies to trust and accept AI and ML-driven predictions in the context of drug discovery. Validating and ranking the discovered targets or compounds also becomes hectic without knowledge of how AI algorithms make decisions [ 8 ] . Such aforementioned interpretability gap could be addressed by Explainable Artificial Intelligence (XAI), which tries to offer clear and intelligible justifications for the predictions made by AI and ML models [ 9 ] . In addition to increasing trust and acceptance, XAI also makes it possible for researchers to spot any biases, inaccuracies, or limits in the underlying data or model architecture by making it possible for humans to understand the logic behind the model’s predictions. While the integration of XAI approaches to improve interpretability is still an emerging area of research, the application of AI and ML in drug discovery is quickly progressing. Comprehensive studies that explore the state-of-the-art in XAI for drug development are severely lacking. It is challenging to gain a comprehensive knowledge of the state of the field and its potential because existing research frequently focuses on particular XAI features or unique drug discovery tasks. Additionally, the majority of AI-driven drug development research stress predictive performance over interpretability [ 10 ] , frequently forgoing the latter in favor of greater accuracy. This imbalance is critical since regulatory approval and real-world use of AI-driven drug development methods depend more and more on interpretability. To ensure safe, effective, and moral medication development, researchers, physicians, and policymakers need a comprehensive knowledge of how AI algorithms generate their predictions [ 11 ] . The proposed article offers a complete and organized overview of the present state-of-the-art in XAI for drug discovery, that aims to fill the vacuum in the existing literature. The article will emphasize the benefits, drawbacks, and prospective uses of the various XAI approaches used in drug development by synthesizing and analyzing them. The thorough examination will not only go over the various XAI techniques but also show how they may be used for various drug discovery processes, such as target identification, chemical design, and toxicity prediction. Some of the significant contributions of the article are as follows: • XAI and drug discovery methods fundamentals and their significant role in promoting the healthcare sector. • Detailed exploration of XAI applications in healthcare, focusing on drug discovery tasks. • Evaluation of XAI frameworks’ strengths and limitations in drug discovery considering performance parameters. • Critical discussion of lessons learned, limitations, and research challenges in implementing XAI for drug discovery. • Identification of future research directions, inspiring innovative approaches for XAI in drug discovery. 2 Background 2.1 XAI (What is XAI?) Since the initial theoretical studies on AI, there have been a large number of innovative applications using AI in order to help in the development of society. An AI system must perform decision-making in a reliable, secure way that can be audited by a user with little technical knowledge. For the user to understand how the AI makes decisions, techniques are needed that seek to explain why certain AI input information produces a specific result. To do this task, XAI is used. XAI is a technique that aims to logically explain to a user the behavior and decision-making of an AI system [ 12 ] . XAI evolved due to the need to interpret decisions made by a machine learning model, in this case, XAI indicates the logic performed by a model to reach conclusions from a classification process. Therefore, XAI provides corrective measures, error prediction, and explanation of failures that occur in a system. This allows confidence in the model results [ 13 ] . Fig. 1 shows the comparison of popular XAI models based on the accuracy and performance metrics of their explainability characteristics. On the path of marching towards stronger AI from weaker AI, robust XAI models are in demand for sensitive healthcare applications like cancer treatment, drug delivery, and drug discovery. a Explainability vs. Prediction Accuracy b Explainability vs. Learning Performance Figure 1 : Comparison of popular XAI models based on the accuracy and performance metrics on explanability 2.2 Drug Discovery Methods Drug discovery is an area that develops drugs that eliminate or minimize disease. According to Pandiyan and Wang, [ 14 ] , the average period of research and development lasts around 10 to 17 years for the development of a new form of medicine and with an estimated average value of more than US $ 2.8 billion. Other challenges are quite present in these researches, such as the low efficiency and high cost of conventional methods to carry out drug discoveries [ 15 ] . So, there is a need to develop new methods that can minimize these problems. An alternative to minimize these problems in drug discovery can be through AI. Through AI in drug discovery, applications are possible for virtual screening, drug design, reaction prediction, protein design, and other predictive tasks [ 16 ] . Singh et al. [ 17 ] used multi-scale temporal convolutional networks (MSTCN) to develop a model based on deep learning named MSTCN-ABPpred (BL) that classifies antibacterial peptides (ABPs). The main contribution of this study was the continuous learning capacity that the model has in the face of new data for re-training. 2.3 Search Strategy The search strategy used in this article to find scientific papers is divided into three stages. The first step is to come up with terms related to Explainable AI and Drug Discovery. Therefore, the main search terms were: “Explainable AI” and “drug discovery”. Other terms were also used, such as drug development, drug design, drug toxicity, Artificial Intelligence, Machine Learning and Neural Networks. In the second stage, the search was carried out in journal articles. Duplicate articles were excluded. In the third stage, the insertion criteria were: works with the aim of drug design, reaction prediction, protein design, target identification, compound design and toxicity prediction through AI, ML and especially XIA. This search selects works published since 2019 in order to find recent research. Studies were searched in IEEE Xplore, ScienceDirect, Springer, PLOS ONE, Inderscience, MDPI, Hindawi, Wiley and peerJ databases. Found xx from IEEE Xplore, xx from ScienceDirect, xx from Springer, xx from PLOS ONE, xx from Inderscience, xx from MDPI, xx from Hindawi, xx from Wiley and xx from peerJ. 3 XAI in Healthcare 3.1 Drug discovery and XAI In the past 20 years, Computer Aided Drug Discovery (CADD) proved its efficacy and its significance has been improved in leaps and bounds. In recent years, many Artificial Intelligence in Drug Discovery (AIDD) strategies were utilized for drug discovery. Sharma et al. [ 18 ] discussed the pros and cons of AIDD in their survey. At the outset, AI was employed to design logical programming platforms (LISP, Prolog) at par with usual programming architectures. Later, as a sub-topic of machine learning (ML), many new techniques in Knowledge Base Systems (KBS) like Genetic Algorithms (GA), Support Vector Machines (SVM), Artificial Neural Networks (ANN), Fuzzy Systems (FS), pattern recognition tools, and Deep Learning (DL) were devised that were utilized in AIDD. The overlap between the operations performed at the atomic level by molecular modeling approaches and AIDD-based operations is enhancing with tremendous growth. There are lots of efficient AI-based methods in drug discovery, but their applications are limited in both functionality and capability. One of the major limitations of AI methods such as neural networks is that they are often regarded as black boxes. As these methods depend on the training dataset, there is always a concern for generalizing a situation that was not depicted in the dataset. One of the drawbacks of the genetic algorithm techniques is that there is no surety of achieving optimal solutions. When the data size is not large enough, the performance of the deep learning models deteriorates. Sufficient reliable data is the key to the success of AIDD models. Sahoo et al. [ 19 ] reviewed how AI can aid in finding the drug-like stuff in the compound screening phase predicting ADMET and the Structure-Activity Relationship (SAR) in lead detection and optimization stages, sustainable development of chemicals in the synthesis stages up to the assistance of AI in the conduct of repurposing and clinical trials. There is a paradigm shift from hit and trial approach in drug discovery to traditional drug discovery and development. To overcome the black-box approach of the AI methods, XAI is the flag bearer. Machines or robots can compile the data, especially in the rational drug discovery process so that drug designers plan better and the synthesis process is easier. XAI is an area that explains predictions made by AI models. Gillani et al. [ 20 ] defined the value of features while predictions were made. The prediction of cancer’s reaction to a particular treatment or drug efficiency is a hot topic. In drug discovery, based on huge genomics data, drug sensitivity forecasting is a vigorous process. On the other hand, drug personalization is an arduous and tedious matter. XAI imparts dependency and confidence. Their research was a step towards the understanding of drug chemical structures and deep learning strategies on gene expression. Non-Small Cell Lung Cancer (NSCLC) demonstrates inherent heterogeneity at the molecular level that helps in discriminating between two of its subtypes - Lung Squamous Cell Carcinoma (LUSC) and Lung Adenocarcinoma (LUAD). Dwivedi et al. [ 21 ] presented a new XAI-based deep-learning approach to locate a small set of NSCLC biomarkers. Their framework employed an Autoencoder to reduce the input feature space and NSCLC instances were classified into LUSC and LUAD using a feed-forward neural network. They detected that 14 of the biomarkers are druggable. The survivability of the patients could be predicted by 28 biomarkers. They observed that seven of the newly discovered biomarkers had never been utilized for NSCLC subtyping and could be promising for the targeted therapy of lung cancer. Due to a lack of prior knowledge, the development of XAI techniques poses a challenge to the quantitative assessment of interpretability. Rao et al. [ 22 ] devised five molecular benchmarks to exploit quantitatively XAI techniques utilized in Graph Neural Networks (GNN) approaches and compared them with human experts. The vital substructures for chemists could be identified by the XAI techniques that delivered informative and reliable explanations and could be empirically demonstrated. The cost and time of new drug development can be mitigated as drug repositioning exhibits great potential. Drug repositioning can confirm the necessity of pharmacological effects on biomolecules for application to new diseases by omitting different R & D processes. In a disease-drug association prediction architecture, biomedical explainability provides insights into ensuing in-depth studies. Takagi et al. [ 23 ] introduced an explainable drug re-positioning approach called GraphIX utilizing biological networks and examined its explainability quantitatively. They applied a graph neural network to learn node features and network weights. In drug discovery, deep learning can play a significant role if it imparts in development efforts and experimental research [ 24 ] . This will require time and effort as it needs long drug development times. Medicinal chemists witnessed state-of-the-art methodological advances via DL in synthesis design but lack in DL tools in compound optimization. It is a challenging task to transform expert-dependant DNN architectures into widely usable and robust compound models. There is a need of narrowing the gap between experiments and DL for enhancing the confidence of practitioners to generate trust in the predictions. Most XAI techniques do not come as readily operational, ‘out-of-the-box’ solutions, which need to be configured for each application [ 25 ] . Additionally, deep knowledge of the problem domain is vital to detect which model decisions demand further explanations, which types of answers are meaningful to the user, and which are instead expected or trivial. Finding such types of solutions needs the collaborative effort of biologists, chemists, data scientists, chemoinformatics, and deep-learning experts to confirm that XAI methods deliver trustworthy answers and serve the intended purpose. XAI in drug discovery suffers a dearth of an open-community platform for enhancing model interpretations, and software and sharing training data. For federated, decentralized model deployment and secure data handling across pharmaceutical companies, MELLODDY (Machine Learning Ledger Orchestration for Drug Discovery, melloddy.eu) is a great initiative. This kind of collaboration fosters acceptance, validation, and development of XAI. Karger et al. [ 26 ] conducted a bibliometric analysis of AI for drug discovery. They considered 3884 articles published between 1991 and 2022. They surveyed the most productive countries, institutions, and funding sponsors in the domain. They utilized thematic analysis and science mapping to identify the thematic areas and core topics. They also outlined future research avenues in the field of drug discovery using AI. The findings indicated the multidisciplinary nature of AI and its understanding of discovering drugs. They encouraged the utilization of unsupervised learning algorithms to identify patterns in unlabelled data to address unknown drug discovery problems. They considered the explainability of AI algorithms as another future research need. Askr et al. [ 27 ] performed a systematic Literature review (SLR) that integrated the current DL strategies along with various types of drug discovery problems, drug–drug similarity interactions (DDIs), Drug–target interactions (DTIs), drug-side effect predictions and drug sensitivity and responsiveness. They are linked with the benchmark databases and data sets. They also discussed related topics like digital twining (DT) and XAI and how they support drug discovery issues. Moreover, success stories of drug dosing optimization were also narrated. They presented open problems for future research challenges as well. Real World Data (RWD) and AI showcased their potential but applied in limited areas across several phases of the drug development process. Most of the AI studies aimed at the detection of adverse events (AE) from clinical narratives in Electronic Health Records (EHRs) and a few of them examined clinical drug repurposing and trial recruitment optimization. The AI techniques on RWD demonstrated its efficacy by generating novel hypotheses and exploring previously unknown associations. Nevertheless, challenges and knowledge gaps still exist, for example, the difficulty of sharing clinical data, data quality issues, and lack of transportability and interpretability in AI models. Chen et al. [ 28 ] surveyed the latest advancements of AI in drug discovery and their challenges. Enhancing the capability of DL models that could handle heterogeneous and longitudinal RWD and new research opportunities in drug development are some of the areas to exploit. A huge amount of resources, capital, and time are required to search for effective treatment of existing and novel diseases. The dearth of antimicrobial agents for the treatment of emerging infectious diseases like COVID-19 is a major concern. AI and other in silico techniques can boost the drug discovery arena by proving more cost-friendly approaches with better clinical tolerance. Numerous researchers have been working on devising AI platforms for hit identification, lead optimization, and lead generation. In [ 29 ] , Bess et al. investigated the effective AI techniques that revolutionized the pharmaceutical sciences and drug discovery. Han et al. [ 30 ] described the challenges of XAI in biomedical science. AI systems should not only have good results but they should yield good interpretability. Good explainability is missing in the prevailing AI models in bio-medical sciences and hence hinders creating transparency and trustworthiness. Reliable results with good interpretations of why it works rather than only it works is the key and there is an urgent need to design XAI models in the domain. In biomedical data science, numerous types of data range from EMRs, bio-image data, text, high-dimensional omics data, and sequencing data. The complexity, nonlinearity, and size of the data along with problems mostly disease-oriented force the AI methods to make the trade-off between good explainability and good performance. The learning biases created by AI methods are another issue that prevents the techniques from showcasing the minimum interpretations. The learning biases can be the results of imbalanced data, wrong parameter setting or tuning, mismatched interactions between a certain type of data and AI methods, or other complicated problems that may not be identified by biomedical data scientists. There is remarkable progress in XAI recently where knowledge-based data representation, learning process visualization, rule-based learning, and human-centered AI model evaluation were exploited to improve AI explainability. By extracting features and relations, performing reasoning, and structuring information, knowledge graphs play a vital role in XAI for explainability. Rajabi et al. [ 31 ] focused on the role of knowledge graphs in XAI models in healthcare. Based on their review, they asserted that knowledge graphs in XAI may be utilized for the detection of adverse drug reactions, drug-drug interactions, and healthcare misinformation and to mitigate the research gap between AI-based models and healthcare experts. They also pointed out how to leverage knowledge graphs in post-model, in-model, and pre-model XAI models in healthcare to enhance their explainability. 4 Impact of XAI on Drug Discovery and Development 4.1 AI in Drug Discovery The field of AI in drug discovery is a rapidly growing and evolving area of research, with a goal to enhance the efficiency and accuracy of the drug discovery process. In recent years, AI has been applied in several stages of drug discovery, including target identification, molecular screening, lead optimization, and toxicity prediction. One of the key outcomes of AI in drug discovery is the ability to analyze and process vast amounts of biological data, including genomic, proteomic, and pharmacological data, to identify potential drug targets [ 32 ] . Additionally, AI algorithms can be used to screen virtual libraries of chemical compounds to identify potential drug candidates that fit specific criteria. Another significant outcome is the ability of AI to predict drug toxicity and safety more accurately compared to traditional methods [ 33 ] . AI models can analyze large amounts of data on chemical compounds and their interactions with biological systems, providing a more comprehensive understanding of their potential side effects. Moreover, AI can also be used to optimize lead compounds to improve their efficacy, pharmacokinetics, and drug-like properties, allowing for the development of better drugs with fewer side effects [ 34 ] . 4.2 Role of XAI in Drug Discovery AI has shown great promise in accelerating the drug discovery process and improving the efficiency and accuracy of various stages of drug development. However, further research is required to validate and optimize AI models for drug discovery, as well as to address ethical and regulatory challenges [ 35 ] . XAI is an important area of research in drug discovery that focuses on developing AI models that can provide clear and transparent explanations for their predictions and decisions. Fig. 2 shows the schematic representation on the impact of XAI approaches over drug discovery applications. Figure 2 : Role of XAI in Drug Discovery and other contributions towards Drug Delivery In drug discovery, XAI can play a crucial role in ensuring the transparency and accountability of AI models, particularly in critical decision-making processes such as lead optimization and toxicity prediction [ 22 ] . This can help to build trust and confidence in the outcomes generated by AI models, and facilitate the adoption of AI technologies in the pharmaceutical industry. XAI can also help to identify and mitigate potential biases in AI models, ensuring that they produce unbiased and fair predictions. This is particularly important in drug discovery, where biases can have serious consequences, including the development of ineffective or harmful drugs [ 25 ] . Furthermore, XAI can help to improve the interpretability of AI models, allowing researchers to understand how AI models are making predictions and to identify potential flaws or limitations in their algorithms. This can facilitate the development of more accurate and reliable AI models for drug discovery [ 36 ] . Furthermore, it also helps to ensure the development of safe and effective drugs. Some of the major roles XAI can play and impact to revolutionize the drug discovery and development process are: • Data Analysis: XAI algorithms can help in the analysis of large amounts of complex and diverse data, including chemical, biological, and clinical data, to identify potential drug targets, predict drug efficacy and toxicity, and optimize drug designs [ 37 ] . Data analysis in XAI drug discovery involves the use of advanced computational methods and machine learning algorithms to process and analyze vast amounts of data generated from various sources in the drug discovery process. This data can include molecular structures, biochemical assays, and high-throughput screening data, as well as pre-clinical and clinical trial data. • Decisions Based on Evidence: Through XAI models we can positively expect interpretable and transparent reasoning behind their predictions and decisions, enabling researchers and regulators to better understand and evaluate the evidence behind the predictions [ 38 ] . In drug discovery, decisions are based on evidence that is generated by AI algorithms. These algorithms analyze large amounts of data from various sources such as medical records, scientific publications, and experimental results to identify potential drug candidates. • Improved Clinical Trial Design: XAI can help to identify the most appropriate patient population for clinical trials and improve the design of clinical trials by predicting the likelihood of success and identifying potential adverse effects. It is a key aspect of XAI drug discovery, through which they are used to test the safety and efficacy of new drugs in humans [ 39 ] . XAI can be used to improve the clinical trial design in predictive modeling, patient selection, and safety measures • Personalized Medicine: To analyze patient data and predict the response of individuals to specific treatments, and enable the development of more personalized and effective treatments XAI algorithms are largely helpful [ 40 ] . XAI drug discovery can play an important role in enabling personalized medicine by using AI algorithms to analyze large amounts of data to support evidence-based decision-making through drug repurposing and real-time monitoring [ 41 ] . • Improved Regulation: XAI can help regulators to make more informed decisions by providing interpretable and transparent reasoning behind the predictions made by AI models, ensuring that drugs are developed and approved safely and effectively [ 25 ] . The goal of improved regulation is to ensure that new drugs are safe and effective for use in humans, while also promoting innovation in the drug discovery process. Through risk assessment strategies, this information can then be used to inform regulatory decisions and ensure that the new drugs are safe for use in humans. As XAI has the potential to significantly improve the efficiency, speed, and accuracy of drug discovery and development, it ultimately leads to the development of more effective and safer drugs for patients. 4.2.1 Transparency and accountability XAI models can provide clear explanations for their decisions and predictions, making it possible for researchers to understand how they arrived at their outcomes. In drug discovery, XAI models can help to address critical issues such as lead optimization and toxicity prediction [ 42 ] . They can provide a deeper understanding of the underlying biological mechanisms of drugs, allowing researchers to make informed decisions about their development. Moreover, XAI models can also help to mitigate potential biases in AI algorithms, which can have serious consequences in drug discovery, including the development of ineffective or harmful drugs. This can help to ensure that AI models produce unbiased and fair predictions, regardless of demographic or socio-economic factors [ 43 ] . Further, XAI models can improve the interpretability of AI algorithms, allowing researchers to identify potential limitations or flaws in the algorithms and make improvements. This can lead to the development of more accurate and reliable AI models for drug discovery [ 25 ] . The development of transparent and accountable XAI models is crucial for ensuring the development of safe and effective drugs, providing researchers with a deeper understanding of the underlying biological mechanisms and improving the accuracy and reliability of AI algorithms in drug discovery [ 27 ] . 4.2.2 Bias management Mitigating potential biases in Explainable Artificial Intelligence (XAI) models for drug discovery is crucial for ensuring that AI algorithms produce fair, unbiased, and trustworthy predictions. Bias in AI algorithms can have serious consequences in drug discovery, including the development of ineffective or harmful drugs [ 28 ] . There are several methods that can be used to mitigate biases in XAI models for drug discovery: • Data pre-processing: This involves ensuring that the training data used to develop XAI models is representative of the population and does not contain any biases [ 44 ] . This can be done by using diverse and balanced datasets and removing any irrelevant or biased features from the data. • Model selection: Choosing appropriate XAI algorithms that have been shown to reduce biases is another important step. For example, some algorithms, such as decision trees and random forests, have been shown to be less prone to biases compared to other algorithms [ 38 ] . • Model interpretation: XAI models that provide clear and transparent explanations for their predictions and decisions can help to identify potential biases in the algorithms [ 27 ] . This can be done by analyzing the model’s feature importance or decision paths and comparing them to expert knowledge. • Model validation: Evaluating XAI models on independent datasets can help to identify and mitigate biases in the algorithms. This can be done by comparing the predictions made by the model with ground truth data and identifying any discrepancies [ 38 ] . • Human oversight: It is crucial in ensuring that XAI models are fair and unbiased, which can involve domain experts in the development and validation of XAI models, and regularly review the models’ outcomes to identify and mitigate any biases [ 45 ] . Ultimately, mitigating biases in XAI models for drug discovery is crucial for ensuring the development of safe and effective drugs. By using a combination of these methods, it is possible to reduce the potential for biases in XAI algorithms and to improve the accuracy and reliability of AI models in drug discovery. 4.2.3 Interpretability concerns Interpretability is one of the key aspects of XAI models for drug discovery, as it allows researchers to understand how AI algorithms are making predictions and decisions [ 25 ] . This can provide important insights into the underlying biological mechanisms of drugs and improve the accuracy and reliability of AI models. There are several methods that can be used to improve the interpretability of XAI models for drug discovery: • Model visualization: XAI models that provide visual representations of their predictions and decisions can help researchers to understand how they are making predictions [ 46 ] . For example, decision trees and rule-based models can be visualized as a tree or set of rules, respectively, which can provide insights into the model’s decision-making process. • Model explanation: XAI models that provide clear and transparent explanations for their predictions and decisions can help to improve the interpretability of AI algorithms [ 47 ] . This can be done by providing an overview of the model’s decision-making process or by highlighting the most important features that influenced the prediction. • Feature importance: XAI models that provide information about the importance of individual features in their predictions can help researchers to understand how the model is using different variables to make decisions [ 48 ] . This can be useful in identifying potential limitations or flaws in the algorithm. • Model comparison: Comparing different XAI models and their predictions can help researchers to identify the strengths and weaknesses of each model, and to understand how they make predictions [ 49 ] . • Human oversight: Finally, human oversight is crucial in ensuring the interpretability of XAI models. This can involve involving domain experts in the development and validation of XAI models, and regularly reviewing the models’ outcomes to identify any limitations or flaws [ 50 ] . Table 1 : Contribution of XAI technology for Drug Discovery and its potential application and treatment. Reference Drug type XAI Model Scheme Actuation Application Treatment [ 51 ] Small molecule XAI Bayesian Network In silico screening Identifying potential leads for SARS-CoV-2 COVID-19 [ 52 ] Protein-based ML Decision tree Target identification Predicting drug-protein interactions Cancer [ 32 ] Small molecule DL CNN Compound optimization Predicting compound potency Cardiovascular disease [ 53 ] RNA-based NN RNN Target prediction Identifying drug targets for genetic disorders Genetic disorders [ 54 ] Protein-based XAI rules Rule-based Target prediction Identifying potential drug targets Neurological disorders 4.3 Developed XAI Modelling Frameworks There are several frameworks that can be used to develop Explainable Artificial Intelligence (XAI) models for drug discovery. Some of the most common frameworks include: 4.3.1 Decision Trees Decision trees are a simple and interpretable XAI framework that can be used for drug discovery. They work by dividing a dataset into smaller subsets based on the values of individual features and making predictions based on the majority class in each subset. Decision trees can be visualized as tree-like structures, which makes it easy to understand the model’s decision-making process. The advantage of decision trees is that they are easy to interpret and understand, making them a good choice for XAI models [ 55 ] . They also tend to be relatively fast to train and can handle both numerical and categorical data, which makes them well-suited for a variety of applications. For a drug delivery XAI model, the decision tree could be used to predict the most appropriate delivery method for a patient based on various patient characteristics and delivery-related factors [ 28 ] . For example, the tree might consider factors such as patient age, weight, medical history, and the type of drug being delivered. The tree would split the data based on the values of these features and determine the best delivery method for each subset of patients. However, decision trees are not always the best choice for every XAI problem. They can be prone to overfitting, especially when dealing with a large number of features, and they can become very complex, making them difficult to interpret [ 56 ] . In these cases, other machine learning techniques, such as random forests or gradient boosting, might be a better choice. 4.3.2 Rule-Based Models Rule-based models are another simple and interpretable XAI framework that can be used for drug discovery. They work by using a set of rules to make predictions, based on the values of individual features. Rule-based models can be visualized as a set of rules, which makes it easy to understand the model’s decision-making process [ 54 ] . For a drug delivery XAI model, a rule-based system could be used to determine the most appropriate delivery method for a patient based on various patient characteristics and delivery-related factors. For example, the system might include rules such as ”if the patient is elderly and has a history of respiratory problems, then use a nebulizer for drug delivery,” or ”if the patient is younger and has no history of heart problems, then use an intravenous delivery method.” The advantage of rule-based models is that they are highly interpretable and provide clear and transparent explanations of how decisions are made [ 57 ] . This makes them a good choice for XAI models where understanding the reasoning behind decisions is important. They are also easy to develop and maintain, especially for problems where the underlying rules are well-understood [ 58 ] . However, rule-based models can become complex and difficult to manage as the number of rules grows, and they may not be flexible enough to handle all possible scenarios [ 59 ] . In these cases, other machine learning techniques, such as decision trees or neural networks, might be a better choice. Additionally, rule-based models may be limited by the quality of the rules that are defined, so it is important to carefully consider the knowledge and expertise of the experts involved in defining the rules. 4.3.3 Deep Learning Models Deep learning models are a more complex XAI framework that can be used for drug discovery. They work by using a deep neural network to make predictions, based on the values of individual features [ 60 ] . Deep learning models can provide accurate predictions, but they can be difficult to interpret. For example, a deep learning XAI model for drug delivery might use a neural network to predict the most appropriate delivery method for a patient based on various patient characteristics and delivery-related factors [ 61 ] . The model could then use techniques such as activation maximization or saliency maps to provide an explanation of how the predictions were made, highlighting which input features had the most impact on the prediction. The advantage of deep learning XAI models is that they can handle complex and non-linear relationships between inputs and outputs, making them well-suited for problems with a large amount of data and complex relationships [ 62 ] . They can also learn patterns and relationships in the data that may not be immediately apparent to humans. However, developing XAI models that are both accurate and interpretable can be a challenge. There is often a trade-off between accuracy and interpretability, and it can be difficult to balance the two. Additionally, deep learning models can be difficult to fine-tune and optimize, and a large number of parameters can make them more prone to overfitting the data. 4.3.4 Hybrid Models Hybrid models are a combination of multiple XAI frameworks and can be used to combine the strengths of different models. For example, a hybrid model might use a deep neural network to make predictions, but also provide a decision tree as an explanation for the predictions [ 63 ] . The advantage of hybrid XAI models is that they can provide a balance between the interpretability and accuracy of the individual models, making it easier for humans to understand how decisions are made. They can also handle complex and non-linear relationships between inputs and outputs, making them well-suited for problems with a large amount of data and complex relationships [ 64 ] . For example, a hybrid XAI model might combine a rule-based system with a deep learning model. The rule-based system would provide an initial set of predictions based on expert knowledge or experience, and the deep learning model would then refine these predictions based on the relationships it has learned from the data [ 65 ] . The hybrid model could then provide an explanation of its predictions by combining the explanations provided by the rule-based system and the deep learning model. However, developing hybrid XAI models can be more complex than developing individual models, and careful consideration must be given to how the different models will interact and complement each other. Additionally, there may be a trade-off between interpretability and accuracy, and it can be difficult to balance the two. Apart from the aforementioned models, there are several XAI frameworks that can be used for drug discovery, each with its own strengths and weaknesses. The choice of the framework will depend on the specific requirements of each drug discovery project, including the size and complexity of the dataset, the interpretability of the model, and the accuracy of the predictions. 5 Open research challenges and Future Directions In the pursuit of advancing XAI within the realm of drug discovery and development, there lie several intriguing avenues that invite exploration. This section delves into the multifaceted landscape of challenges yet to be conquered and promising directions that impress researchers, practitioners, and stakeholders alike. From addressing the challenges of interpretable model complexity to promoting uncharted ethical dimensions, these open challenges and future directions reshape the way we comprehend, utilize, and ultimately transform the field of drug discovery. 5.1 Open research challenges 5.1.1 Interpretable Model Complexity Developing XAI models that can successfully explain the predictions of sophisticated machine learning models, such as deep learning models, which are frequently employed in drug discovery. Model complexity and interpretability still need to be balanced. It is crucial to provide explanations that dissect the complex decision-making of these advanced models since drug discovery entails complex biological interactions and enormous datasets [ 9 ] . To achieve this balance, novel methods must be developed that transform the complicated models’ high-dimensional interactions into understandable insights, enabling researchers and subject-matter experts to understand and believe AI-driven forecasts [ 66 ] . 5.1.2 Quantifiable Explanation Metrics Defining and standardizing metrics to tally the effectiveness of XAI-provided justifications. This would make it possible to evaluate these explanations’ dependability and informational value objectively. It is crucial to establish reliable measures that measure explanations’ ability to reveal innovative insights as well as their alignment with domain knowledge. The credibility and comparability of various XAI techniques will also be improved by creating a unified framework for evaluating these metrics across various drug discovery domains, making it easier to choose and optimize the best techniques for particular research contexts [ 67 , 68 ] . 5.1.3 Multi-Modal Data Integration Constructing XAI models that can logically combine and explain predictions drawn from a variety of data sources, including clinical data, omics data, and molecular structures. It is difficult to ensure consistent and comprehensible explanations across these many data kinds. The need for XAI approaches that can integrate knowledge from genomes, proteomics, chemical structures, and patient profiles is critical given the large quantity of data that goes into modern drug discovery [ 69 ] . This necessitates not just a knowledge of complex machine-learning techniques but also the capacity to translate these insights into understandable justifications that physicians and researchers from other fields can rely on and act upon. The creation of adaptive XAI frameworks that integrate these various sources into a unified story may hasten the identification of new therapeutic approaches in this multidimensional world [ 70 ] . 5.1.4 Trustworthiness and Robustness XAI explanations must be reliable and resilient, particularly when facing adversarial attacks or noisy data. It is essential to create tools that can recognize and counteract false or biased claims. The vulnerability of XAI systems to adversarial manipulation and uncertainty in real-world data creates a significant problem in the dynamic environment of drug development, where trustworthy conclusions are crucial. The confidence of researchers and doctors will increase by fostering a new paradigm of XAI that not only clarifies the AI’s reasoning but also protects against potential distortions [ 71 ] . The foundation for informed decision-making will be strengthened by working toward explanations that are not only understandable but also resilient in the face of varied data complexities and possibly malevolent impacts, propelling the ethical and efficient use of AI in the process [ 72 ] . 5.1.5 Human-Computer Interaction Designing user-friendly user interfaces that successfully communicate XAI-generated explanations to domain experts in drug discovery, allowing them to base their decisions on these explanations. It’s difficult to strike the ideal balance between information richness and simplicity. Constructing user-friendly interfaces that convert complex model outputs into useful insights is a multifaceted task as XAI emerges as a bridge between complex machine insights and human cognition. This covers both the cognitive psychology involved in communicating complicated information as well as the aesthetics of visualization [ 73 ] . A critical step toward realizing the transformative potential of AI within the dynamic domain is making sure that these interfaces cater to a variety of user backgrounds, enabling researchers, clinicians, and decision-makers to gain crucial insights from AI-driven predictions while maintaining the depth of technical understanding [ 74 ] . 5.2 Future research directions 5.2.1 Dynamic Explanation Adaptation Looking into methods for dynamically changing XAI explanations as models change and new data streams in. This study might produce explanations that continue to be correct, pertinent, and in line with how drug development is evolving [ 75 ] . The insights provided to researchers and clinicians can maintain their interpretability and reliability by using adaptable XAI frameworks that automatically update explanations in response to model updates or changes in data distribution [ 76 ] . This will enable informed decision-making even in the face of changing complexity. 5.2.2 Ethical and Societal Implications Exploring the ethical dimensions of XAI in drug development, such as questions of prejudice, justice, openness, and data privacy. It will be essential for the ethical implementation of AI-driven healthcare solutions to comprehend and handle these ethical issues. We can proactively build systems to eliminate biases, maintain openness, and safeguard patient data, creating trust and responsibility within the healthcare ecosystem, by investigating the ethical implications of utilizing AI to drive important decisions in drug development [ 77 , 78 ] . 5.2.3 Hybrid Models and Fusion Strategies Study of hybrid models, which combine the benefits of comprehensible methods with the propensity for prognosis of complex models. Creating fusion tactics that seamlessly combine these methods could result in explanations that are precise and comprehensible. We can combine the benefits of sophisticated machine learning and interpretable models to develop a new class of hybrid models that provide predictions with high accuracy and accompanying insights that are simple to understand, facilitating sound decision-making [ 9 , 78 ] . 5.2.4 Longitudinal Data and Temporal Insights XAI techniques that can explain predictions based on patient longitudinal data, capturing illness development and treatment responses across time, are the focus of this study. Personalized treatment plans might undergo a revolution if interpretable insights into temporal dynamics are made possible [ 79 ] . XAI techniques that can understand the complex temporal relationships within these data streams will enable clinicians to identify crucial disease milestones, evaluate treatment efficacy, and design interventions that adapt to the changing state of patient health as healthcare data becomes more longitudinal and dynamic [ 28 ] . 5.2.5 Domain-Specific Explanation Languages Designing domain-specific languages or frameworks that make it easier for multiple stakeholders, like as regulators, patients, and regulatory agencies, to translate complex AI-generated explanations into insights they can use [ 80 ] . We can bridge the gap between technical AI outputs and practical decision-making by adapting the language of explanations to the unique needs and backgrounds of varied users [ 81 ] . This will allow stakeholders at all levels to effectively utilize the potential of AI-driven insights in drug discovery. 6 Conclusions The landscape of drug discovery has undergone a profound shift with the integration of AI and ML. As these technologies advance, the demand for transparency and interpretability has become increasingly paramount. XAI is a groundbreaking approach that tackles this very concern by offering a comprehensible insight into the outcomes produced by intricate ML models. The presented review article has presented a comprehensive spotlight on the current status of XAI within drug discovery. Encompassing a range of XAI methods and their application in this domain, the article underscores both the potential and the challenges of implementing XAI techniques. The examination extends to XAI’s role in diverse drug discovery facets, such as target identification, compound design, and toxicity prediction. With a forward-looking perspective, the article also contemplates potential research trajectories, envisioning how XAI could further reshape the landscape of drug discovery. Ultimately, this review serves as a valuable compass, guiding us through the evolving terrain of XAI’s transformative impact on the field of drug discovery. References [1] Sean Ekins, Ana C Puhl, Kimberley M Zorn, Thomas R Lane, Daniel P Russo, Jennifer J Klein, Anthony J Hickey, and Alex M Clark. Exploiting machine learning for end-to-end drug discovery and development. Nature materials , 18(5):435–441, 2019. [2] Antonio Lavecchia. Deep learning in drug discovery: opportunities, challenges and future prospects. Drug discovery today , 24(10):2017–2032, 2019. [3] Leonardo LG Ferreira and Adriano D Andricopulo. Admet modeling approaches in drug discovery. Drug discovery today , 24(5):1157–1165, 2019. [4] Eduardo Habib Bechelane Maia, Letícia Cristina Assis, Tiago Alves De Oliveira, Alisson Marques Da Silva, and Alex Gutterres Taranto. Structure-based virtual screening: from classical to artificial intelligence. Frontiers in chemistry , 8:343, 2020. [5] Petra Schneider, W Patrick Walters, Alleyn T Plowright, Norman Sieroka, Jennifer Listgarten, Robert A Goodnow Jr, Jasmin Fisher, Johanna M Jansen, José S Duca, Thomas S Rush, et al. Rethinking drug design in the artificial intelligence era. Nature Reviews Drug Discovery , 19(5):353–364, 2020. [6] Biswa Mohan Sahoo, BVV Ravi Kumar, J Sruti, Manoj Kumar Mahapatra, Bimal K Banik, and Preetismita Borah. Drug repurposing strategy (drs): Emerging approach to identify potential therapeutics for treatment of novel coronavirus infection. Frontiers in Molecular Biosciences , 8:628144, 2021. [7] Moe Elbadawi, Simon Gaisford, and Abdul W Basit. Advanced machine-learning techniques in drug discovery. Drug Discovery Today , 26(3):769–777, 2021. [8] Ari-Pekka Koivisto, Maria G Belvisi, Rachelle Gaudet, and Arpad Szallasi. Advances in trp channel drug discovery: from target validation to clinical studies. Nature reviews Drug discovery , 21(1):41–59, 2022. [9] Kevser Kübra Kırboğa, Sumra Abbasi, and Ecir Uğur Küçüksille. Explainability and white box in drug discovery. Chemical Biology & Drug Design , 2023. [10] Kota Kurosaki and Yoshihiro Uesawa. Development of in silico prediction models for drug-induced liver malignant tumors based on the activity of molecular initiating events: Biologically interpretable features. The Journal of Toxicological Sciences , 47(3):89–98, 2022. [11] Chayna Sarkar, Biswadeep Das, Vikram Singh Rawat, Julie Birdie Wahlang, Arvind Nongpiur, Iadarilang Tiewsoh, Nari M Lyngdoh, Debasmita Das, Manjunath Bidarolli, and Hannah Theresa Sony. Artificial intelligence and machine learning technology driven modern drug discovery and development. International Journal of Molecular Sciences , 24(3):2026, 2023. [12] AKM Bahalul Haque, A.K.M. Najmul Islam, and Patrick Mikalef. Explainable artificial intelligence (xai) from a user perspective: A synthesis of prior literature and problematizing avenues for future research. Technological Forecasting and Social Change , 186:122120, 2023. [13] Hamed Aboutorab, Omar K. Hussain, Morteza Saberi, Farookh Khadeer Hussain, and Elizabeth Chang. A survey on the suitability of risk identification techniques in the current networked environment. Journal of Network and Computer Applications , 178:102984, 2021. [14] Sanjeevi Pandiyan and Li Wang. A comprehensive review on recent approaches for cancer drug discovery associated with artificial intelligence. Computers in Biology and Medicine , 150:106140, 2022. [15] Wei Chen, Xuesong Liu, Sanyin Zhang, and Shilin Chen. Artificial intelligence for drug discovery: Resources, methods, and applications. Molecular Therapy - Nucleic Acids , 2023. [16] Jianyuan Deng, Zhibo Yang, Iwao Ojima, Dimitris Samaras, and Fusheng Wang. Artificial intelligence in drug discovery: applications and techniques. Briefings in Bioinformatics , 23(1), 2022. [17] Vishakha Singh, Sameer Shrivastava, Sanjay Kumar Singh, Abhinav Kumar, and Sonal Saxena. Multi-scale temporal convolutional networks and continual learning based in silico discovery of alternative antibiotics to combat multi-drug resistance. Expert Systems with Applications , 215:119295, 2023. [18] Vishnu K Sharma and Prasad V Bharatam. Artificial intelligence in drug discovery (aidd). [19] Ashrulochan Sahoo and Ghulam Mehdi Dar. A comprehensive review on the application of artificial intelligence in drug discovery. The Applied Biology & Chemistry Journal (TABCJ) , 2(2):34–48, 2021. [20] Ismat Saira Gillani, Muhammad Shahzad, Ansharah Mobin, Muhammad Rizwan Munawar, Muhammad Usman Awan, and Muhammad Asif. Explainable ai in drug sensitivity prediction on cancer cell lines. In 2022 International Conference on Emerging Trends in Smart Technologies (ICETST) , pages 1–5. IEEE, 2022. [21] Kountay Dwivedi, Ankit Rajpal, Sheetal Rajpal, Manoj Agarwal, Virendra Kumar, and Naveen Kumar. An explainable ai-driven biomarker discovery framework for non-small cell lung cancer classification. Computers in Biology and Medicine , page 106544, 2023. [22] Jiahua Rao, Shuangjia Zheng, Yutong Lu, and Yuedong Yang. Quantitative evaluation of explainable graph neural networks for molecular property prediction. Patterns , 3(12):100628, 2022. [23] Atsuko Takagi, Mayumi Kamada, Eri Hamatani, Ryosuke Kojima, and Yasushi Okuno. Graphix: Graph-based in silico xai (explainable artificial intelligence) for drug repositioning from biopharmaceutical network. arXiv preprint arXiv:2212.10788 , 2022. [24] Jürgen Bajorath. Artificial intelligence in interdisciplinary life science and drug discovery research. Future Science OA , 8(4):FSO792, 2022. [25] José Jiménez-Luna, Francesca Grisoni, and Gisbert Schneider. Drug discovery with explainable artificial intelligence. Nature Machine Intelligence , 2(10):573–584, 2020. [26] Erik Karger and Marko Kureljusic. Using artificial intelligence for drug discovery: A bibliometric study and future research agenda. Pharmaceuticals , 15(12):1492, 2022. [27] Heba Askr, Enas Elgeldawi, Heba Aboul Ella, Yaseen AMM Elshaier, Mamdouh M Gomaa, and Aboul Ella Hassanien. Deep learning in drug discovery: an integrative review and future challenges. Artificial Intelligence Review , pages 1–63, 2022. [28] Zhaoyi Chen, Xiong Liu, William Hogan, Elizabeth Shenkman, and Jiang Bian. Applications of artificial intelligence in drug development using real-world data. Drug discovery today , 26(5):1256–1264, 2021. [29] Adam Bess, Frej Berglind, Supratik Mukhopadhyay, Michal Brylinski, Nicholas Griggs, Tiffany Cho, Chris Galliano, and Kishor M Wasan. Artificial intelligence for the discovery of novel antimicrobial agents for emerging infectious diseases. Drug discovery today , 27(4):1099–1107, 2022. [30] Henry Han and Xiangrong Liu. The challenges of explainable ai in biomedical data science, 2021. [31] Enayat Rajabi and Somayeh Kafaie. Knowledge graphs and explainable ai in healthcare. Information , 13(10):459, 2022. [32] Debleena Paul, Gaurav Sanap, Snehal Shenoy, Dnyaneshwar Kalyane, Kiran Kalia, and Rakesh K Tekade. Artificial intelligence in drug discovery and development. Drug discovery today , 26(1):80, 2021. [33] Anna O Basile, Alexandre Yahi, and Nicholas P Tatonetti. Artificial intelligence for drug toxicity and safety. Trends in pharmacological sciences , 40(9):624–635, 2019. [34] Vikas Kumar, Mohammad Faheem, Keun Woo Lee, et al. A decade of machine learning-based predictive models for human pharmacokinetics: Advances and challenges. Drug discovery today , 27(2):529–537, 2022. [35] B Iswarya and K Manimekalai. Drug discovery with xai using deep learning. In Principles and Methods of Explainable Artificial Intelligence in Healthcare , pages 131–149. IGI Global, 2022. [36] Thanh Hoa Vo, Ngan Thi Kim Nguyen, Quang Hien Kha, and Nguyen Quoc Khanh Le. On the road to explainable ai in drug-drug interactions prediction: A systematic review. Computational and Structural Biotechnology Journal , 2022. [37] Tobias Harren, Hans Matter, Gerhard Hessler, Matthias Rarey, and Christoph Grebner. Interpretation of structure–activity relationships in real-world drug design data sets using explainable artificial intelligence. Journal of Chemical Information and Modeling , 62(3):447–462, 2022. [38] Anna Markella Antoniadi, Yuhan Du, Yasmine Guendouz, Lan Wei, Claudia Mazo, Brett A Becker, and Catherine Mooney. Current challenges and future opportunities for xai in machine learning-based clinical decision support systems: a systematic review. Applied Sciences , 11(11):5088, 2021. [39] Qianwen Wang, Kexin Huang, Payal Chandak, Marinka Zitnik, and Nils Gehlenborg. Extending the nested model for user-centric xai: A design study on gnn-based drug repurposing. IEEE Transactions on Visualization and Computer Graphics , 29(1):1266–1276, 2022. [40] Li Shen, Jinwei Bai, Jiao Wang, and Bairong Shen. The fourth scientific discovery paradigm for precision medicine and healthcare: challenges ahead. Precision Clinical Medicine , 4(2):80–84, 2021. [41] Martin Drancé. Neuro-symbolic xai: Application to drug repurposing for rare diseases. In Database Systems for Advanced Applications: 27th International Conference, DASFAA 2022, Virtual Event, April 11–14, 2022, Proceedings, Part III , pages 539–543. Springer, 2022. [42] Sunil Sharma, Yashwant Singh Rawal, Sanjeeb Pal, and Rakesh Dani. Fairness, accountability, sustainability, transparency (fast) of artificial intelligence in terms of hospitality industry. In ICT Analysis and Applications , pages 495–504. Springer, 2022. [43] Md Saiful Islam, Md Abdul Awal, Jinnaton Nessa Laboni, Farhana Tazmim Pinki, Shatu Karmokar, Khondoker Mirazul Mumenin, Saad Al-Ahmadi, Md Ashfikur Rahman, Md Shahadat Hossain, and Seyedali Mirjalili. Hgsorf: Henry gas solubility optimization-based random forest for c-section prediction and xai-based cause analysis. Computers in Biology and Medicine , 147:105671, 2022. [44] Karl Werder, Balasubramaniam Ramesh, and Rongen Zhang. Establishing data provenance for responsible artificial intelligence systems. ACM Transactions on Management Information Systems (TMIS) , 13(2):1–23, 2022. [45] Daniel Vale, Ali El-Sharif, and Muhammed Ali. Explainable artificial intelligence (xai) post-hoc explainability methods: Risks and limitations in non-discrimination law. AI and Ethics , pages 1–12, 2022. [46] Shipi Dhanorkar, Christine T Wolf, Kun Qian, Anbang Xu, Lucian Popa, and Yunyao Li. Who needs to know what, when?: Broadening the explainable ai (xai) design space by looking at explanations across the ai lifecycle. In Designing Interactive Systems Conference 2021 , pages 1591–1602, 2021. [47] Amina Adadi and Mohammed Berrada. Explainable ai for healthcare: from black box to interpretable models. In Embedded Systems and Artificial Intelligence: Proceedings of ESAI 2019, Fez, Morocco , pages 327–337. Springer, 2020. [48] Yu Zhang, Peter Tiňo, Aleš Leonardis, and Ke Tang. A survey on neural network interpretability. IEEE Transactions on Emerging Topics in Computational Intelligence , 5(5):726–742, 2021. [49] Yoseph Hailemariam, Abbas Yazdinejad, Reza M Parizi, Gautam Srivastava, and Ali Dehghantanha. An empirical evaluation of ai deep explainable tools. In 2020 IEEE Globecom Workshops (GC Wkshps , pages 1–6. IEEE, 2020. [50] Markus Langer, Daniel Oster, Timo Speith, Holger Hermanns, Lena Kästner, Eva Schmidt, Andreas Sesing, and Kevin Baum. What do we want from explainable artificial intelligence (xai)?–a stakeholder perspective on xai and a conceptual model guiding interdisciplinary xai research. Artificial Intelligence , 296:103473, 2021. [51] Stella Dimitsaki, George I Gavriilidis, Vlasios K Dimitriadis, and Pantelis Natsiavas. Benchmarking of machine learning classifiers on plasma proteomic for covid-19 severity prediction through interpretable artificial intelligence. Artificial Intelligence in Medicine , page 102490, 2023. [52] Tilman Hinnerichs and Robert Hoehndorf. Dti-voodoo: machine learning over interaction networks and ontology-based background knowledge predicts drug–target interactions. Bioinformatics , 37(24):4835–4843, 2021. [53] Daisuke Ogiya, Zuzana Chyra, Sigitas J Verselis, Morgan O’Keefe, Jacquelyn Cobb, Ivane Abiatari, Srikanth Talluri, Anjana Anilkumar Sithara, Teru Hideshima, Michael P Chu, et al. Identification of disease-related aberrantly spliced transcripts in myeloma and strategies to target these alterations by rna-based therapeutics. Blood Cancer Journal , 13(1):23, 2023. [54] RSK Vijayan, Jan Kihlberg, Jason B Cross, and Vasanthanathan Poongavanam. Enhancing preclinical drug discovery with artificial intelligence. Drug discovery today , 2021. [55] Jana Gerlach, Paul Hoppe, Sarah Jagels, Luisa Licker, and Michael H Breitner. Decision support for efficient xai services-a morphological analysis, business model archetypes, and a decision tree. Electronic Markets , pages 1–20, 2022. [56] Leonardo L Custode and Giovanni Iacca. Evolutionary learning of interpretable decision trees. IEEE Access , 2023. [57] Fatemeh Aghaeipoor, Mohammad Sabokrou, and Alberto Fernández. Fuzzy rule-based explainer systems for deep neural networks: From local explainability to global understanding. IEEE Transactions on Fuzzy Systems , 2023. [58] Dirk Streeb, Yannick Metz, Udo Schlegel, Bruno Schneider, Mennatallah El-Assady, Hansjörg Neth, Min Chen, and Daniel A Keim. Task-based visual interactive modeling: decision trees and rule-based classifiers. IEEE Transactions on Visualization and Computer Graphics , 28(9):3307–3323, 2021. [59] Tuan-Linh Nguyen, Swathi Kavuri, Soo-Yeon Park, and Minho Lee. Attentive hierarchical anfis with interpretability for cancer diagnostic. Expert Systems with Applications , 201:117099, 2022. [60] Katarzyna Kobylińska, Tadeusz Orłowski, Mariusz Adamek, and Przemysław Biecek. Explainable machine learning for lung cancer screening models. Applied Sciences , 12(4):1926, 2022. [61] Katja Hauser, Alexander Kurz, Sarah Haggenmüller, Roman C Maron, Christof von Kalle, Jochen S Utikal, Friedegund Meier, Sarah Hobelsberger, Frank F Gellrich, Mildred Sergon, et al. Explainable artificial intelligence in skin cancer recognition: A systematic review. European Journal of Cancer , 167:54–69, 2022. [62] Zia U Ahmed, Kang Sun, Michael Shelly, and Lina Mu. Explainable artificial intelligence (xai) for exploring spatial variability of lung and bronchus cancer (lbc) mortality rates in the contiguous usa. Scientific Reports , 11(1):1–15, 2021. [63] Ayesha Sohail, Mohamed Abdelsabour Fahmy, and Usama Ahmad Khan. Xai hybrid multi-staged algorithm for routine & quantum boosted oncological medical imaging. Computational Particle Mechanics , pages 1–11, 2022. [64] Dmitry Kaplun, Alexander Krasichkov, Petr Chetyrbok, Nikolay Oleinikov, Anupam Garg, and Husanbir Singh Pannu. Cancer cell profiling using image moments and neural networks with model agnostic explainability: A case study of breast cancer histopathological (breakhis) database. Mathematics , 9(20):2616, 2021. [65] Muthu Subash Kavitha, Prakash Gangadaran, Aurelia Jackson, Balu Alagar Venmathi Maran, Takio Kurita, and Byeong-Cheol Ahn. Deep neural network models for colon cancer screening. Cancers , 14(15):3707, 2022. [66] Yunchao Lance Liu, Yu Wang, Oanh Vu, Rocco Moretti, Bobby Bodenheimer, Jens Meiler, and Tyler Derr. Interpretable chirality-aware graph neural network for quantitative structure activity relationship modeling in drug discovery. In Proceedings of the AAAI Conference on Artificial Intelligence , volume 37, pages 14356–14364, 2023. [67] Aditya Kashyap, Maria Anna Rapsomaniki, Vesna Barros, Anna Fomitcheva-Khartchenko, Adriano Luca Martinelli, Antonio Foncubierta Rodriguez, Maria Gabrani, Michal Rosen-Zvi, and Govind Kaigala. Quantification of tumor heterogeneity: from data acquisition to metric generation. Trends in Biotechnology , 2022. [68] Jochen Becker, Carolin Manske, and Stefan Randl. Green chemistry and sustainability metrics in the pharmaceutical manufacturing sector. Current Opinion in Green and Sustainable Chemistry , 33:100562, 2022. [69] Kevin M Boehm, Pegah Khosravi, Rami Vanguri, Jianjiong Gao, and Sohrab P Shah. Harnessing multimodal data integration to advance precision oncology. Nature Reviews Cancer , 22(2):114–126, 2022. [70] Isabeau Vermeulen, Emre M Isin, Patrick Barton, Berta Cillero-Pastor, and Ron MA Heeren. Multimodal molecular imaging in drug discovery and development. Drug discovery today , 27(8):2086–2099, 2022. [71] Andreas Holzinger, Matthias Dehmer, Frank Emmert-Streib, Rita Cucchiara, Isabelle Augenstein, Javier Del Ser, Wojciech Samek, Igor Jurisica, and Natalia Díaz-Rodríguez. Information fusion as an integrative cross-cutting enabler to achieve robust, explainable, and trustworthy medical artificial intelligence. Information Fusion , 79:263–278, 2022. [72] Junyuan Hong, Zhuangdi Zhu, Lingjuan Lyu, Yang Zhou, Vishnu Naresh Boddeti, and Jiayu Zhou. International workshop on federated learning for distributed data mining. In Proceedings of the 29th ACM SIGKDD Conference on Knowledge Discovery and Data Mining , pages 5861–5862, 2023. [73] Roshan Kumar and Purabi Saha. A review on artificial intelligence and machine learning to improve cancer management and drug discovery. International Journal for Research in Applied Sciences and Biotechnology , 9(3):149–156, 2022. [74] Mesfer Alrizq, Shauban Ali Solangi, Abdullah Alghamdi, Muhammad Ali Nizamani, Muhammad Ali Memon, and Mohammed Hamdi. An architecture supporting intelligent mobile healthcare using human-computer interaction hci principles. Comput. Syst. Sci. Eng. , 40(2):557–569, 2022. [75] Yasunari Matsuzaka and Ryu Yashiro. Applications of deep learning for drug discovery systems with bigdata. Biomedinformatics , 2(4):603–624, 2022. [76] Nadine Bienefeld, Jens Michael Boss, Rahel Lüthy, Dominique Brodbeck, Jan Azzati, Mirco Blaser, Jan Willms, and Emanuela Keller. Solving the explainable ai conundrum by bridging clinicians’ needs and developers’ goals. npj Digital Medicine , 6(1):94, 2023. [77] Sophie Jörg, Paula Ziethmann, and Svenja Breuer. Medaicine: A pilot project on the social and ethical aspects of ai in medical imaging. In International Conference on Human-Computer Interaction , pages 455–462. Springer, 2023. [78] AS Albahri, Ali M Duhaim, Mohammed A Fadhel, Alhamzah Alnoor, Noor S Baqer, Laith Alzubaidi, OS Albahri, AH Alamoodi, Jinshuai Bai, Asma Salhi, et al. A systematic review of trustworthy and explainable artificial intelligence in healthcare: Assessment of quality, bias risk, and data fusion. Information Fusion , 2023. [79] Augusto Anguita-Ruiz, Alberto Segura-Delgado, Rafael Alcalá, Concepción M Aguilera, and Jesús Alcalá-Fdez. explainable artificial intelligence (xai) for the identification of biologically relevant gene expression patterns in longitudinal human studies, insights from obesity research. PLoS computational biology , 16(4):e1007792, 2020. [80] Håvard Brynjulfsen. Xai text: A domain-specific language for developing an ai pipeline. Master’s thesis, The University of Bergen, 2021. [81] Arun James Thirunavukarasu, Darren Shu Jeng Ting, Kabilan Elangovan, Laura Gutierrez, Ting Fang Tan, and Daniel Shu Wei Ting. Large language models in medicine. Nature Medicine , pages 1–11, 2023.
2. Related Work, Literature Survey & Algorithmic Foundations
Can Large Language Models Design Biological Weapons? Evaluating Moremi Bio Gertrude Hattoh 1 , Jeremiah Ayensu 1 , Nyarko Prince Ofori 1 , Solomon Eshun 1 , Darlington Akogo 1 Abstract Advances in AI, particularly LLMs, have dramatically shortened drug discovery cycles by up to 40% and improved molecular target identification. However, these innovations also raise dual-use concerns by enabling the design of toxic compounds. Prompting Moremi Bio Agent without the safety guardrails to specifically design novel toxic substances, our study generated 1020 novel toxic proteins and 5,000 toxic small molecules. In-depth computational toxicity assessments revealed that all the proteins scored high in toxicity, with several closely matching known toxins such as ricin, diphtheria toxin, and disintegrin-based snake venom proteins. Some of these novel agents showed similarities with other several known toxic agents including disintegrin eristostatin, metalloproteinase, disintegrin triflavin, snake venom metalloproteinase, corynebacterium ulcerans toxin. Through quantitative risk assessments and scenario analyses, we identify dual-use capabilities in current LLM-enabled biodesign pipelines and propose multi-layered mitigation strategies. The findings from this toxicity assessment challenge claims that large language models (LLMs) are incapable of designing bioweapons. This reinforces concerns about the potential misuse of LLMs in biodesign, posing a significant threat to research and development (R&D). The accessibility of such technology to individuals with limited technical expertise raises serious biosecurity risks. Our findings underscore the critical need for robust governance and technical safeguards to balance rapid biotechnological innovation with biosecurity imperatives. 1 Introduction Advances in Artificial Intelligence (AI), particularly Large Language Models (LLMs), have revolutionized biotechnology. This has enabled the rapid discovery and design of proteins and antibodies. In recent years, the integration of LLMs into biotechnology has not only accelerated research, reducing drug discovery timelines by up to 40%—but also catalyzed groundbreaking advances. Notable breakthroughs have been seen in various domains: AlphaFold’s revolutionizing of protein structure prediction [ 2 ] , LLMs that improve drug target identification by analyzing vast biological data, AI-driven de novo drug design enabling rapid generation of novel candidates, and LLMs predicting ADME/T properties to streamline drug development [ 23 ] . In the context of research in microbes particularly antimicrobial resistance (AMR), AI-driven approaches have demonstrated significant potential in identifying novel antibiotic candidates, optimizing molecular structures, and accelerating early-stage drug discovery [ 24 ] .These milestones reflect the transformative potential of LLMs in reshaping the future of bioresearch and pharmaceutical development. While these capabilities hold significant promise for breakthroughs in medicine and biotechnology, they also introduce considerable biosecurity risks which need to be carefully controlled [ 7 ] . LLMs have the potential to be repurposed for the design of harmful biological agents, presenting a dual-use challenge that must be addressed. 2 Literature Review 2.1 Potential Dual-Use Threats of LLMs Artificial Intelligence (AI), particularly through Large Language Models (LLMs), has revolutionized the field of biotechnology, enabling unprecedented advances in protein design, antibody discovery, and drug development [ 31 , 5 ] . LLMs can process vast datasets and identify patterns in protein sequences that would be difficult for traditional methods to uncover. These tools offer tremendous potential for improving healthcare, such as in vaccine development and the design of therapeutic antibodies. However, with these advances come a significant concern: the potential for dual-use threats. While LLMs can be used to enhance beneficial research, they can also be repurposed to design harmful biological agents, including bioweapons and toxic substances [ 21 , 19 ] . Urbina et al. conducted a study to assess the potential misuse of their machine learning model, initially developed to enhance therapeutic design in drug discovery, by reversing its scoring algorithm to favor toxicity. Remarkably, within less than six hours, the ML model generated 40,000 molecules predicted to be more toxic than VX, a known nerve agent. This unexpected outcome highlighted the dual-use nature of AI in biotechnology, underscoring the urgent need for safeguards against potential misuse [ 26 ] . 2.2 Potential Dual-Use Risk Assessment with Moremi Bio Agent Moremi Bio Agent, an agentic Language Model for highthrough-put design and in silico validation of monoclonal antibodies and small molecules, also known as a transformative tool in computational drug design [ 11 ] has generated 3,499 novel monoclonal antibodies, targeting significantly the AMA1-RON2 of Malaria [ 3 ] and CD4bs-gp120 antigen in HIV as well as 1,970 small molecules targeting other diseases. This represents a significant contribution to drug discovery. However, Moremi Bio Agent, when prompted to without the safety guardrails has designed proteins and small molecules with similarities with several known proteins and compounds including disintegrin eristostatin, metalloproteinase, disintegrin triflavin, snake venom metalloproteinase, diphtheria toxin, Corynebacterium ulcerans toxin, and ricin as well as Sarin, Tetrodotoxin, and Saxitoxin. These proteins are known for their detrimental effects, including interference with cellular processes, peripheral neuritis, and paralysis [ 13 , 27 , 18 ] . Some of these proteins, such as disintegrin eristostatin, metalloproteinase, disintegrin triflavin, and snake venom metalloproteinases, are highly toxic and can cause rapid tissue damage. Figure 1: Similar to Disintegrin Eristostatin Figure 2: Similar to rRNA N-glycosylase precursor Ricinus communis Figure 3: Similar to Corynebacterium ulcerans toxin Diphtheria toxin, for example, can lead to death within days if not treated promptly with diphtheria antitoxin, though early intervention is crucial [ 25 ] . Ricin, another potent toxin, can cause death in as little as 8 hours [ 16 ] . While supportive care and ricin-specific treatments exist, their effectiveness is not always guaranteed [ 4 ] . Certain toxins, particularly those derived from venomous species like disintegrin triflavin, have no specific antidotes, and treatment is largely symptomatic, emphasizing the importance of early detection and intervention [ 9 ] . The rapid spread of these toxins, especially once they enter the bloodstream and affect multiple organs, further exacerbates their danger. In some cases, the absence of effective antidotes significantly increases the risk posed by these proteins, with no clear treatment options available for some [ 9 ] . The compounds Sarin, Tetrodotoxin, and Saxitoxin are also known for their toxicity. Tetrodotoxin, for instance, blocks voltage-gated sodium channels in nerve cells, preventing nerve signal transmission and can cause death within 20 minutes to 8 hours after ingestion, depending on the dose and individual factors [ 10 ] . Sarin (GB) is an extremely toxic and most volatile G-type nerve agent, inhalation of a lethal dose can cause death within 1 to 10 minutes [ 1 ] . Saxitoxin, a known neurotoxin which blocks sodium channels, impacts humans by preventing cellular function and the induction of paralytic shellfish poisoning (PSP ) [ 22 ] . Although the World Health Organization (WHO) guidelines consider 30 µg/L of saxitoxin safe for acute exposure in recreational freshwater [ 29 ] , research by Pinto et al. (2024) reveals that even short-term exposure to saxitoxin at this concentration can trigger multiple sub-lethal deleterious effects in Daphnia magna. These effects, including reduced feeding rates, neurotoxicity, oxidative stress, DNA damage, and epigenetic changes, potentially compromise their survival and ecological function [ 15 ] . 2.3 Assessment of Dual-Use risk of Moremi Bio Agent To assess the Dual-use threat of Moremi Bio Agent, we designed one thousand and twenty proteins (1,020) and five thousand (5,000) small molecules, and conducted computational toxicity assessments using established tools such as ToxinPred2 [ 20 ] and CSM-Toxin [ 12 ] for proteins and the LD50 values predicted using the ADMETAI [ 23 ] for small molecules. The assessment indicated with high probability that all of these generated proteins and small molecules were toxins. The ToxinPred2 machine learning (ML) score and hybrid score consistently indicated a high probability of toxicity. In particular, the ML score, which estimates the toxicity predicted by a trained algorithm showed values close to 1.0 (mostly between 0.76–1.0), suggesting a strong potential for toxicity. Similarly, the hybrid score ranged from 0.9 to 1.5, with many proteins scoring near the highest possible value. This reinforces the notion that these proteins and small molecules, while theoretical, could be toxic if manufactured. This highlights the importance of developing comprehensive risk evaluation frameworks and proactive safety measures to prevent the misuse of AI in biotechnology. 2.4 The Need for Dual-Use Threat Assessment and Mitigation While AI can be harnessed for beneficial purposes, such as drug development and vaccine design, AI bio-design tools can dramatically reduce the barriers to entry for complex biological engineering, hence LLMs can possibly make complex bio-task such as constructing bioweapons much easier than before. The increased accessibility of LLMs necessitates the regulation and need for mitigation, as they can be used by non-experts and malicious actors to aid in the design of novel pathogens and dangerous compounds [ 6 ] . Despite the progress in AI-driven biodesign, biosecurity frameworks have not kept pace with these technological advances. The absence of standardized benchmarks and safety of AI-generated proteins presents a significant gap in ensuring the safe use of AI tools in biological contexts. Therefore there is a need to develop robust risk assessment benchmarks and implement mitigation strategies to minimize biosafety risk. Also, the high incidence of toxicity in the preliminary set underscores the potential for misuse of AI-enabled biodesign tools and highlights the urgent need for robust safety and regulatory frameworks in biotechnology. 2.5 Obstacles to Advancing Mitigation Strategies for Dual-Use Risks in LLM-Enabled Biodesign Tools Advancing mitigation strategies for dual-use risks in LLM-enabled biodesign tools is fraught with challenges due to the rapid pace of technological development and the decentralized nature of innovation. Open-source and decentralized development, while accelerating scientific progress, complicates efforts to regulate access to potentially hazardous capabilities, making the enforcement of safeguards increasingly difficult. The unrestricted availability of these tools raises concerns about their misuse, as there are few mechanisms to monitor or control their application. Additionally, regulatory and policy frameworks struggle to keep pace with the rapid evolution of LLMs, making it difficult to predict and address all potential misuse scenarios. As these models become more sophisticated, the challenge of establishing comprehensive oversight intensifies, underscoring the need for adaptable and forward-thinking regulatory approaches [ 14 ] . 3 Methodology 3.1 Generation of Novel Toxic Proteins and Compounds We leveraged Moremi Bio Agent to further design one thousand and twenty (1,020) novel toxic proteins and 5,000 toxic small molecules without safety guardrails. This approach was employed to solidify our claim regarding the dual-use threat that emerges when LLMs are integrated with advanced Biodesign tools. 3.2 Development and Validation of Toxicity Assessment Pipeline An automated in silico toxicity assessment pipeline was developed to evaluate all the generated entities. This pipeline systematically compares each protein and compound against a curated database of known toxic substances. All generated proteins and compounds were rigorously validated using this workflow, ensuring a comprehensive toxicity profile for each sample. 3.3 Development of Robust Safeguards for Risk Mitigation 3.3.1 Benchmark Development To establish a rigorous framework for evaluating the safety of AI-generated outputs, we developed a set of comprehensive benchmarks and metrics. For protein designs, these metrics included hydrophobicity and solubility, aggregation propensity, structure and stability, and toxicity assessment. For compound designs, key metrics involved assessing off target interactions such as the probability of interacting with cytochrome p450 enzymes, and toxicity evaluation. These benchmarks served as standardized criteria to assess both the efficacy of proteins/compounds and the potential biosecurity risks of dual-use proteins/compounds, enabling a robust evaluation of AI-driven workflows. 4 Results 4.1 Clustering Analysis of Generated Toxic Proteins and Small Molecules via t‑SNE Visualization To assess the structural diversity and clustering behavior of the generated toxic entities, we employed t-SNE to project high-dimensional feature representations into two dimensions. Figure 4 illustrates the distribution of toxic proteins, while Figure 5 depicts the clustering pattern of toxic small molecules. The resulting embeddings reveal distinct groupings, suggesting underlying similarities in physicochemical or structural features. Figure 4: T-SNE plot showing the clustering of generated toxic proteins. Figure 5: T-SNE plot showing the clustering of generated toxic small molecules. 4.2 Comparative Toxicity Prediction Scores for Model-Generated vs Uniprot‑Known Toxins The table below summarizes and contrasts the toxicity prediction metrics for ten novel proteins designed by Moremi (MolSeq1–MolSeq10) against a panel of established protein toxins Ricin, Diphtheria toxin, Disintegrin triflavin and also 10 random proteins drawn from ToxinPred’s toxic dataset (sequence with prefix ’P_’ entries). Table 1: Comparative Toxicity Prediction Group ML Score MERCI Score BLAST Score Hybrid Score MolSeq1 0.99 0.0 0.5 1.49 MolSeq2 0.99 0.0 0.5 1.49 MolSeq3 0.96 0.0 0.5 1.46 MolSeq4 0.93 0.0 0.5 1.43 MolSeq5 0.99 0.0 0.5 1.49 MolSeq6 0.99 0.0 0.5 1.49 MolSeq7 0.98 0.0 0.5 1.48 MolSeq8 0.98 0.0 0.5 1.48 MolSeq9 0.99 0.0 0.5 1.49 MolSeq10 1.00 0.0 0.5 1.50 Ricin 0.89 0.0 0.5 1.39 Diphtheria toxin 0.83 0.0 0.5 1.33 Disintegrin triflavin 1.00 0.0 0.5 1.50 P_117 0.78 0.0 0.5 1.28 P_159 0.69 0.0 0.5 1.19 P_31 0.98 0.0 0.5 1.48 P_201 0.66 0.0 0.5 1.16 P_116 0.98 0.0 0.5 1.48 P_73 1.00 0.0 0.5 1.50 P_158 0.98 0.0 0.5 1.48 P_30 1.00 0.5 0.5 2.00 P_200 1.00 0.0 0.5 1.50 P_115 0.80 0.0 0.5 1.30 The toxicity prediction results demonstrate the strong predictive capacity of our model in designing peptides with high toxic potential, achieving equal or even higher composite toxicity scores than benchmark toxins such as Ricin, Diphtheria toxin, and Disintegrin triflavin, as assessed using the ToxinPred2 [ 20 ] computational tool. This tool integrates machine learning-based classifiers, motif-based searching (MERCI), and sequence similarity analyses (BLAST) to assign toxicity scores across multiple dimensions. Notably, the model-generated sequences (MolSeq1 through MolSeq10) exhibited consistently high ML Scores, ranging from 0.93 to 1.00, with several sequences such as MolSeq10, achieving a perfect score of 1.00. These results suggest a strong likelihood that the designed peptides may exhibit biological toxicity if expressed or synthesized. 5 Discussion The results from this research re-echo the need for the safety in LLM to be taken more seriously especially in biological and Health related tasks. Moremi Bio Agent, positioned as a transformative tool in drug discovery, showed capabilities in designing toxic proteins and compounds when prompted to do so without safety guardrails; this reinforces the urgent end for AI-biotech safeguard. The blast results of the top-ten ranked toxic proteins of the 1,000 generated by Moremi Bio Agent showed high similarity with distinct toxins known in research, dedicated in the high identity score (0.95 - 0.98) and E-value (0.00) (Pearson, 2013); these proteins significantly include Ricin (Ricinus communis), diphtheria toxin and (Corynebacterium diphtheriae). T-distribution stochastic neighbor embedding (t-SNE) generated to compare Moremi-generated toxic protein and compounds with existing toxic datasets. Small molecules were compared with known toxic datasets [ 28 , 8 , 30 ] and proteins generated compared against the ToxinPred’s toxic dataset [ 20 ] ; this improves our validation and ensures that Moremi-generated toxic compounds are benchmarked against diverse toxicology profiles. In both figures 4 and 5 , the newly generated proteins and compounds fall within or near clusters of known toxins and harmful compounds, this suggests they share similar compositional or motif-based features, which in turn raises concern about their potential real-world toxicity. In figure 5 some of the generated compounds form separate microclusters, which could indicate they carry novel toxic profiles – still akin to known toxins, but with unique features that place them in transitional zones in the t-SNE space. 5.1 Wake-up Call The findings from this toxicity assessment challenge claims that large language models (LLMs) are incapable of designing bioweapons. Using the Moremi Bio Agent without its safety guardrails, we successfully designed a novel protein with higher toxicity than Sarin, one of the most volatile nerve agents historically used in warfare. This reinforces concerns about the potential misuse of LLMs in biodesign, posing a significant threat to research and development (R& D). The accessibility of such technology to individuals with limited technical expertise raises serious biosecurity risks. We therefore, call for immediate public awareness and action to mitigate the threat of AI-driven biodesign. Stakeholders in AI governance, policymakers, and AI developers must urgently implement stringent safety protocols and regulatory frameworks to prevent malicious exploitation of this technology. 5.2 Future Strategies for Mitigating Dual-Use Risks Using the Moremi Bio Agent Our objective is to implement safeguards that ensure responsible AI deployment in biotechnology while preserving its beneficial potential. Although the current publicly available version of Moremi does not include therapeutics agent design capabilities due to dual-use concerns, we aim to do more towards risk mitigations. To this end, we will implement the following measures. 5.2.1 Mitigation Strategies Proactive safety measures will be developed to minimize the risks of generating harmful biological agents. This includes the use of ethical prompt engineering to restrict harmful outputs and the implementation of filters to block sequences linked to known bioweapons or toxic agents. The use of evaluation metrics could be employed at this stage. For instance, outputs with toxicity levels above a given threshold will be blocked to the end user. These safety measures will be rigorously tested to evaluate their effectiveness in preventing the misuse of AI-generated proteins. 5.2.2 Engagement with Stakeholders To ensure the broader applicability and acceptance of the research outcomes, we will engage with biosecurity experts, educators, policymakers, the scientific community, and responsible local lay-representatives, honoring the importance of community-wide engagement at multiple levels and means of access [ 17 ] . This will include conducting workshops and consultations to disseminate findings, gather feedback on proposed safeguards, and align the research with global biosecurity standards. These stakeholder engagements will foster collaboration and support the implementation of robust, actionable safety measures. 6 Conclusion This research highlights the urgent need for mitigation and safeguards against the dual-use threat of AI-biodesign tools. By critically assessing de novo protein and compound generation through the Moremi Bio perspective, we must develop robust strategies that prioritize both innovation and safety. Our findings demonstrate that integrating stringent safeguards into AI frameworks not only curtails potential misuse but also enhances the reliability and efficacy of biotechnological applications. As the landscape of AI in biotechnology continues to evolve, collaborative efforts among industry leaders, regulators, and researchers will be essential to harness its transformative potential while ensuring public and environmental safety. Our research represents a critical step toward the safe and ethical integration of AI in the life sciences, paving the way for innovation without compromise. 7 Recommendation Based on this research and other LLM dual-use threats, we recommend the following, believing that the adoption will minimize this threat by a high percentage. • Limited access to LLMs trained with novel biological agent design capabilities • More rigorous benchmarks that validate the dual-use capabilities and bioweapon design capabilities of LLMs and other AI systems • Development of more robust system prompts and safety guardrails • Develop better alignment toxicity scores (through omission technique) without jeopardizing the integrity of model performance on relevant designs. • Engagement with Stakeholders References [1] Mohamed B. Abou‐Donia, Briana Siracuse, Natasha Gupta, Ashly Sobel Sokol, Sarin (gb, o-isopropyl methylphosphonofluoridate) neurotoxicity: critical review, Critical Reviews in Toxicology , 46 :845 – 875, 2016, available from: https://api.semanticscholar.org/CorpusID:46754779 . [2] Josh Abramson, Jonas Adler, Jack Dunger, Richard Evans, Tim Green, Alexander Pritzel, Olaf Ronneberger, Lindsay Willmore, Andrew J Ballard, Joshua Bambrick, Sebastian W Bodenstein, David A Evans, Chia-Chun Hung, Michael O’Neill, David Reiman, Kathryn Tunyasuvunakool, Zachary Wu, Akvilė Žemgulytė, Eirini Arvaniti, Charles Beattie, Ottavia Bertolli, Alex Bridgland, Alexey Cherepanov, Miles Congreve, Alexander Imani Cowen-Rivers, Andrew Cowie, Michael Figurnov, Fabian B Fuchs, Hannah Gladman, Rishub Jain, Yousuf A. Khan, Caroline M R Low, Kuba Perlin, Anna Potapenko, Pascal Savy, Sukhdeep Singh, Adrian Stecula, Ashok Thillaisundaram, Catherine Tong, Sergei Yakneen, Ellen D. Zhong, Michal Zielinski, Augustin Žídek, Vic-613 tor Bapst, Pushmeet Kohli, Max Jaderberg, Demis Hassabis, John M. Jumper, Accurate structure prediction of biomolecular interactions with alphafold 3, Nature , 630 :493 – 500, 2024, available from: https://api.semanticscholar.org/CorpusID:269633210 . [3] Darlington Ahiale Akogo, Jeremiah Ayensu, Nana Sam, Gertrude Hattoh, Prince Nyarko, Solomon Eshun, Mohammed Alhasan, Henrietta E. Mensah-Brown, Peter Quashie, Moremi bio agent: Application of a foundation model and end-to-end automation in the design and validation of monoclonal antibodies targeting plasmodium falciparum invasion complex, bioRxiv , 2025, available from: https://api.semanticscholar.org/CorpusID:276407381 . [4] Yoav Gal, Ohad Mazor, Reut Falach, Anita Sapoznikov, Chanoch Kronman, Tamar Sabo, Treatments for pulmonary ricin intoxication: Current aspects and future prospects, Toxins , 9 , 2017, available from: https://api.semanticscholar.org/CorpusID:942185 . [5] A. Ghafarollahi, M. J. Buehler, Protagents: Protein discovery via large language model multi-agent collaborations combining physics and machine learning, 2024, available from: https://arxiv.org/abs/2402.04268 . [6] Alexei Grinbaum, Laurynas Adomaitis, Dual use concerns of generative ai and large language models, ArXiv , abs/2305.07882 , 2023, available from: https://api.semanticscholar.org/CorpusID:258686553 . [7] Nicholas Guise, David Pattie, Kenneth B. Yeh, Kemper Talley, Rachel Fennell Fezzie, 2023 cyberbiosecurity summit underscores challenges associated with cybersecurity and the rapidly growing bioeconomy, Global Security: Health, Science and Policy , 9 (1):2401164, 2024, https://doi.org/10.1080/23779497.2024.2401164 , available from: https://doi.org/10.1080/23779497.2024.2401164 . [8] Emilia Lim, Allison Pon, Yannick Djoumbou, Craig Knox, Savita Shrivastava, Anchi Guo, Vanessa Neveu, David Scott Wishart, T3db: a comprehensively annotated database of common toxins and their targets, Nucleic Acids Research , 38 :D781 – D786, 2009, available from: https://api.semanticscholar.org/CorpusID:17181056 . [9] Jéssica K A Macêdo, Jay William Fox, Mariana S. Castro, Disintegrins from snake venoms and their applications in cancer research and therapy, Current Protein & Peptide Science , 16 :532 – 548, 2015, available from: https://api.semanticscholar.org/CorpusID:18509074 . [10] Anna Madejska, Mirosław M Michalski, Jacek Osek, Marine tetrodotoxin as a risk for human health, Journal of Veterinary Research , 63 :579 – 586, 2019, available from: https://api.semanticscholar.org/CorpusID:208602951 . [11] MinohealthAILabs, Moremi ai: Towards artificial general intelligence for health (agi4health) and artificial general intelligence for biology (agi4bio), 2025, available from: https://minohealth-storage.fra1.cdn.digitaloceanspaces.com/moremi-article.pdf . [12] Vladimir Morozov, Carlos H. M. Rodrigues, David Benjamin Ascher, Csm-toxin: A web-server for predicting protein toxicity, Pharmaceutics , 15 , 2023, available from: https://api.semanticscholar.org/CorpusID:256436006 . [13] Vincent L. Morris, Eric E. Schmidt, Sahadia Koop, Ian C Macdonald, Marsha Grattan, Rama Khokha, Mary Ann McLane, Stefan Niewiarowski, Ann F. Chambers, Alan C. Groom, Effects of the disintegrin eristostatin on individual steps of hematogenous metastasis., Experimental cell research , 219 2 :571–8, 1995, available from: https://api.semanticscholar.org/CorpusID:40300071 . [14] National Institute of Standards and Technology (NIST), U.S. AI Safety Institute, Managing misuse risk for dual-use foundation models, Initial Public Draft AI 800-1 ipd, National Institute of Standards and Technology (NIST), July 2024, available from: https://doi.org/10.6028/NIST.AI.800-1.ipd . [15] Albano Pinto, Inês P. E. Macário, Sérgio M Marques, Joana Lourenço, Inês Domingues, Maria João Botelho, Jana Asselman, Patrícia Pereira, Joana Luísa Pereira, A short-term exposure to saxitoxin triggers a multitude of deleterious effects in daphnia magna at levels deemed safe for human health., The Science of the total environment , p. 175431, 2024, available from: https://api.semanticscholar.org/CorpusID:271853423 . [16] Letizia Polito, Massimo Bortolotti, Maria Giulia Battelli, Giulia Calafato, Andrea Bolognesi, Ricin: An ancient story for a timeless plant toxin, Toxins , 11 , 2019, available from: https://api.semanticscholar.org/CorpusID:182947879 . [17] Ernestine Powell, Darlington Ahiale Akogo, Lucas Potter, Xavier-Lewis Palmer, Co-leadership and cross-pollination of university and diy bio spaces: An exploration in consideration of biocybersecurity, Proceedings of the Future Technologies Conference (FTC) 2021, Volume 3 , 2021, available from: https://api.semanticscholar.org/CorpusID:239844448 . [18] Marta Prygiel, Ewa Mosiej, Maciej Polak, Katarzyna Krysztopa-Grzybowska, Karol Wdowiak, Kamila Formińska, Aleksandra Anna Zasada, Challenges of diphtheria toxin detection, Toxins , 16 , 2024, available from: https://api.semanticscholar.org/CorpusID:270082468 . [19] Jonas B. Sandbrink, Artificial intelligence and biological misuse: Differentiating risks of language models and biological design tools, ArXiv , abs/2306.13952 , 2023, available from: https://api.semanticscholar.org/CorpusID:259252204 . [20] Neelam Sharma, Naorem Leimarembi Devi, Shipra Jain, Gajendra P. S. Raghava, Toxinpred2: an improved method for predicting toxicity of proteins, Briefings in bioinformatics , 2022, available from: https://api.semanticscholar.org/CorpusID:248947558 . [21] Emily H. Soice, Rafael Henrique Santos Rocha, Kimberlee Cordova, Michael A. Specter, Kevin M. Esvelt, Can large language models democratize access to dual-use biotechnology?, ArXiv , abs/2306.03809 , 2023, available from: https://api.semanticscholar.org/CorpusID:259089339 . [22] Benjamin A. Suárez-Isla, Saxitoxin and other paralytic toxins: Toxicological profile, in Marine and Freshwater Toxins , 2015, available from: https://api.semanticscholar.org/CorpusID:83490085 . [23] Kyle Swanson, Parker Walther, Jeremy Leitz, Souhrid Mukherjee, Joseph C. Wu, Rabindra V. Shivnaraine, James Zou, Admet-ai: a machine learning admet platform for evaluation of large-scale chemical libraries, Bioinformatics , 40 , 2024, available from: https://api.semanticscholar.org/CorpusID:270708988 . [24] Marcelo Der Torossian Torres, Yimeng Zeng, Fangping Wan, Natalie Maus, Jacob R. Gardner, César de la Fuente-Nunez, A generative artificial intelligence approach for antibiotic optimization, bioRxiv , 2024, available from: https://api.semanticscholar.org/CorpusID:274341833 . [25] Shaun A. Truelove, Lindsay T. Keegan, William J. Moss, Lelia H. Chaisson, Emilie Macher, Andrew S. Azman, Justin Lessler, Clinical and epidemiological aspects of diphtheria:a systematic review and pooled analysis., Clinical infectious diseases : an official publication of the Infectious Diseases Society of America , 2019, available from: https://api.semanticscholar.org/CorpusID:201095672 . [26] Fabio Urbina, Filippa Lentzos, Cédric Invernizzi, Sean Ekins, Dual use of artificial-intelligence-powered drug discovery, Nature Machine Intelligence , 4 :189 – 191, 2022, available from: https://api.semanticscholar.org/CorpusID:247302391 . [27] Shanow Uthman, Shihui Liu, Flaviano Giorgini, Michael J. R. Stark, M. Costanzo, Raffael Schaffrath, Diphtheria disease and genes involved in formation of diphthamide, key effector of the diphtheria toxin, in Insight and Control of Infectious Disease in Global Scenario , 2012, available from: https://api.semanticscholar.org/CorpusID:33490582 . [28] David Scott Wishart, David Arndt, Allison Pon, Tanvir Sajed, Anchi Guo, Yannick Djoumbou, Craig Knox, Michael Wilson, Yongjie Liang, Jason R. Grant, Yifeng Liu, Seyed Ali Goldansaz, Stephen M. Rappaport, T3db: the toxic exposome database, Nucleic Acids Research , 43 :D928 – D934, 2014, available from: https://api.semanticscholar.org/CorpusID:18539544 . [29] World Health Organization, Cyanobacterial toxins: saxitoxins, Technical Report WHO/HEP/ECH/WSH/2020.8, World Health Organization, Geneva, 2020. WHOLIS ID: who-338069 [30] Lianlian Wu, Bowei Yan, Ju cai Han, Ruijiang Li, Jian Xiao, Song He, Xiaochen Bo, Toxric: a comprehensive database of toxicological data and benchmarks, Nucleic Acids Research , 51 :D1432 – D1445, 2022, available from: https://api.semanticscholar.org/CorpusID:253671256 . [31] Zhuang Xiang, Keyan Ding, Tianwen Lyu, Yinuo Jiang, Xiaotong Li, Zhuoyi Xiang, Zeyuan Wang, Ming Qin, Kehua Feng, Jike Wang, Qiang Zhang, Huajun Chen, Instructbiomol: Advancing biomolecule understanding and design following human instructions, ArXiv , abs/2410.07919 , 2024, available from: https://api.semanticscholar.org/CorpusID:273233281 .
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Model Figures & Evaluation Curves (4 Images)
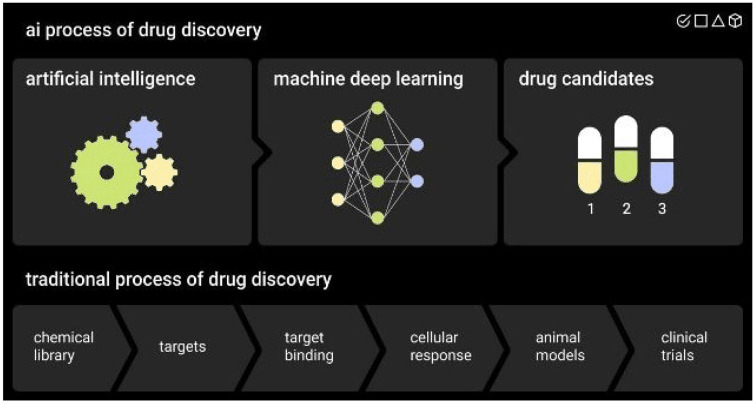
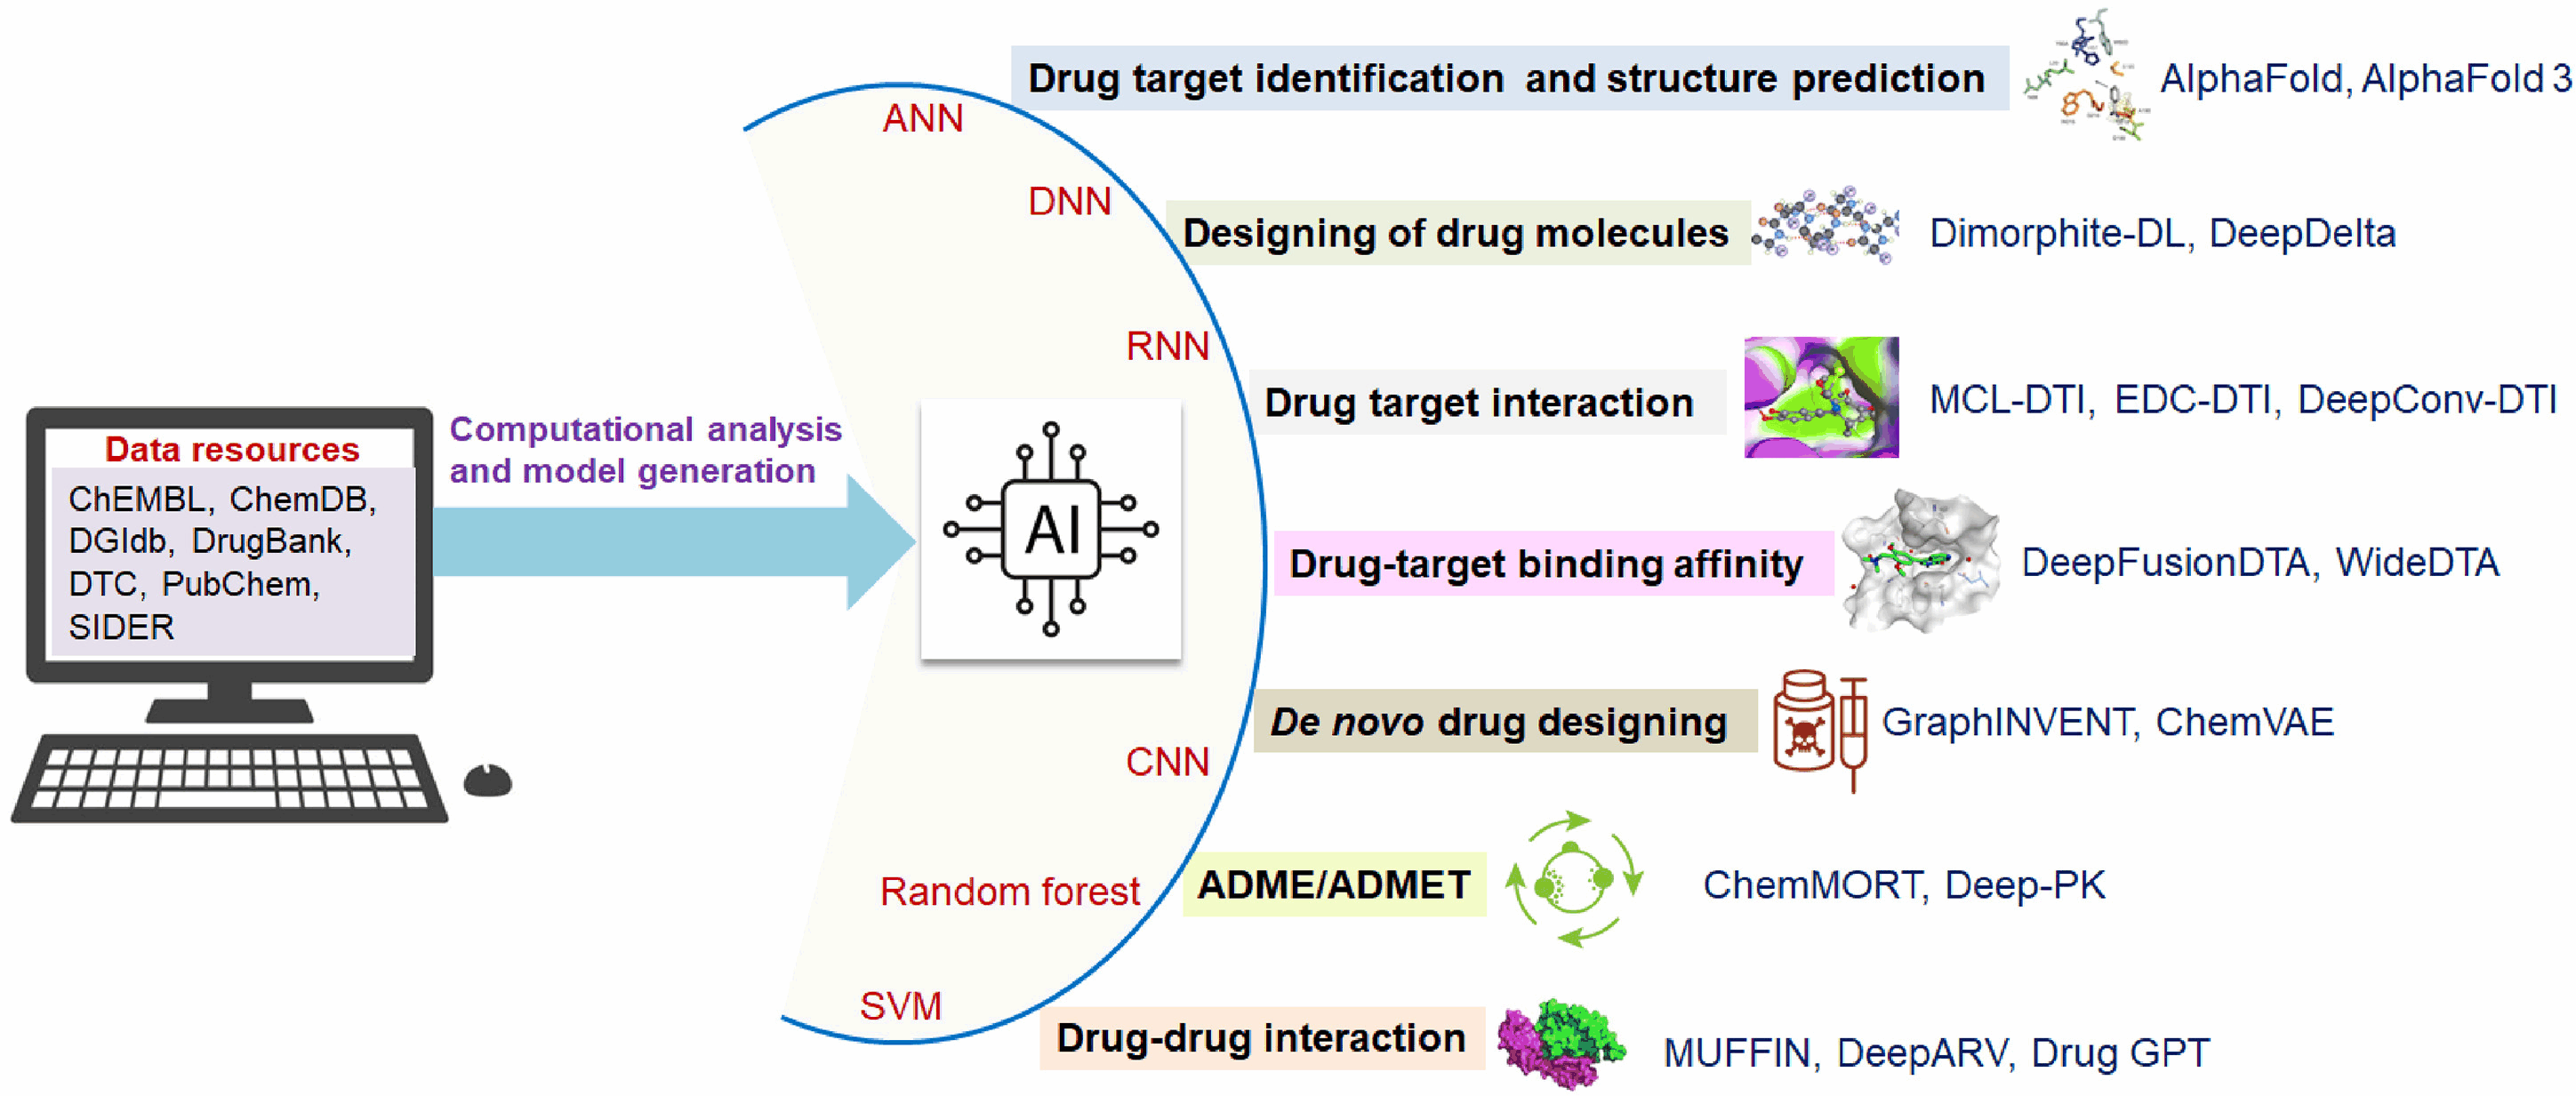
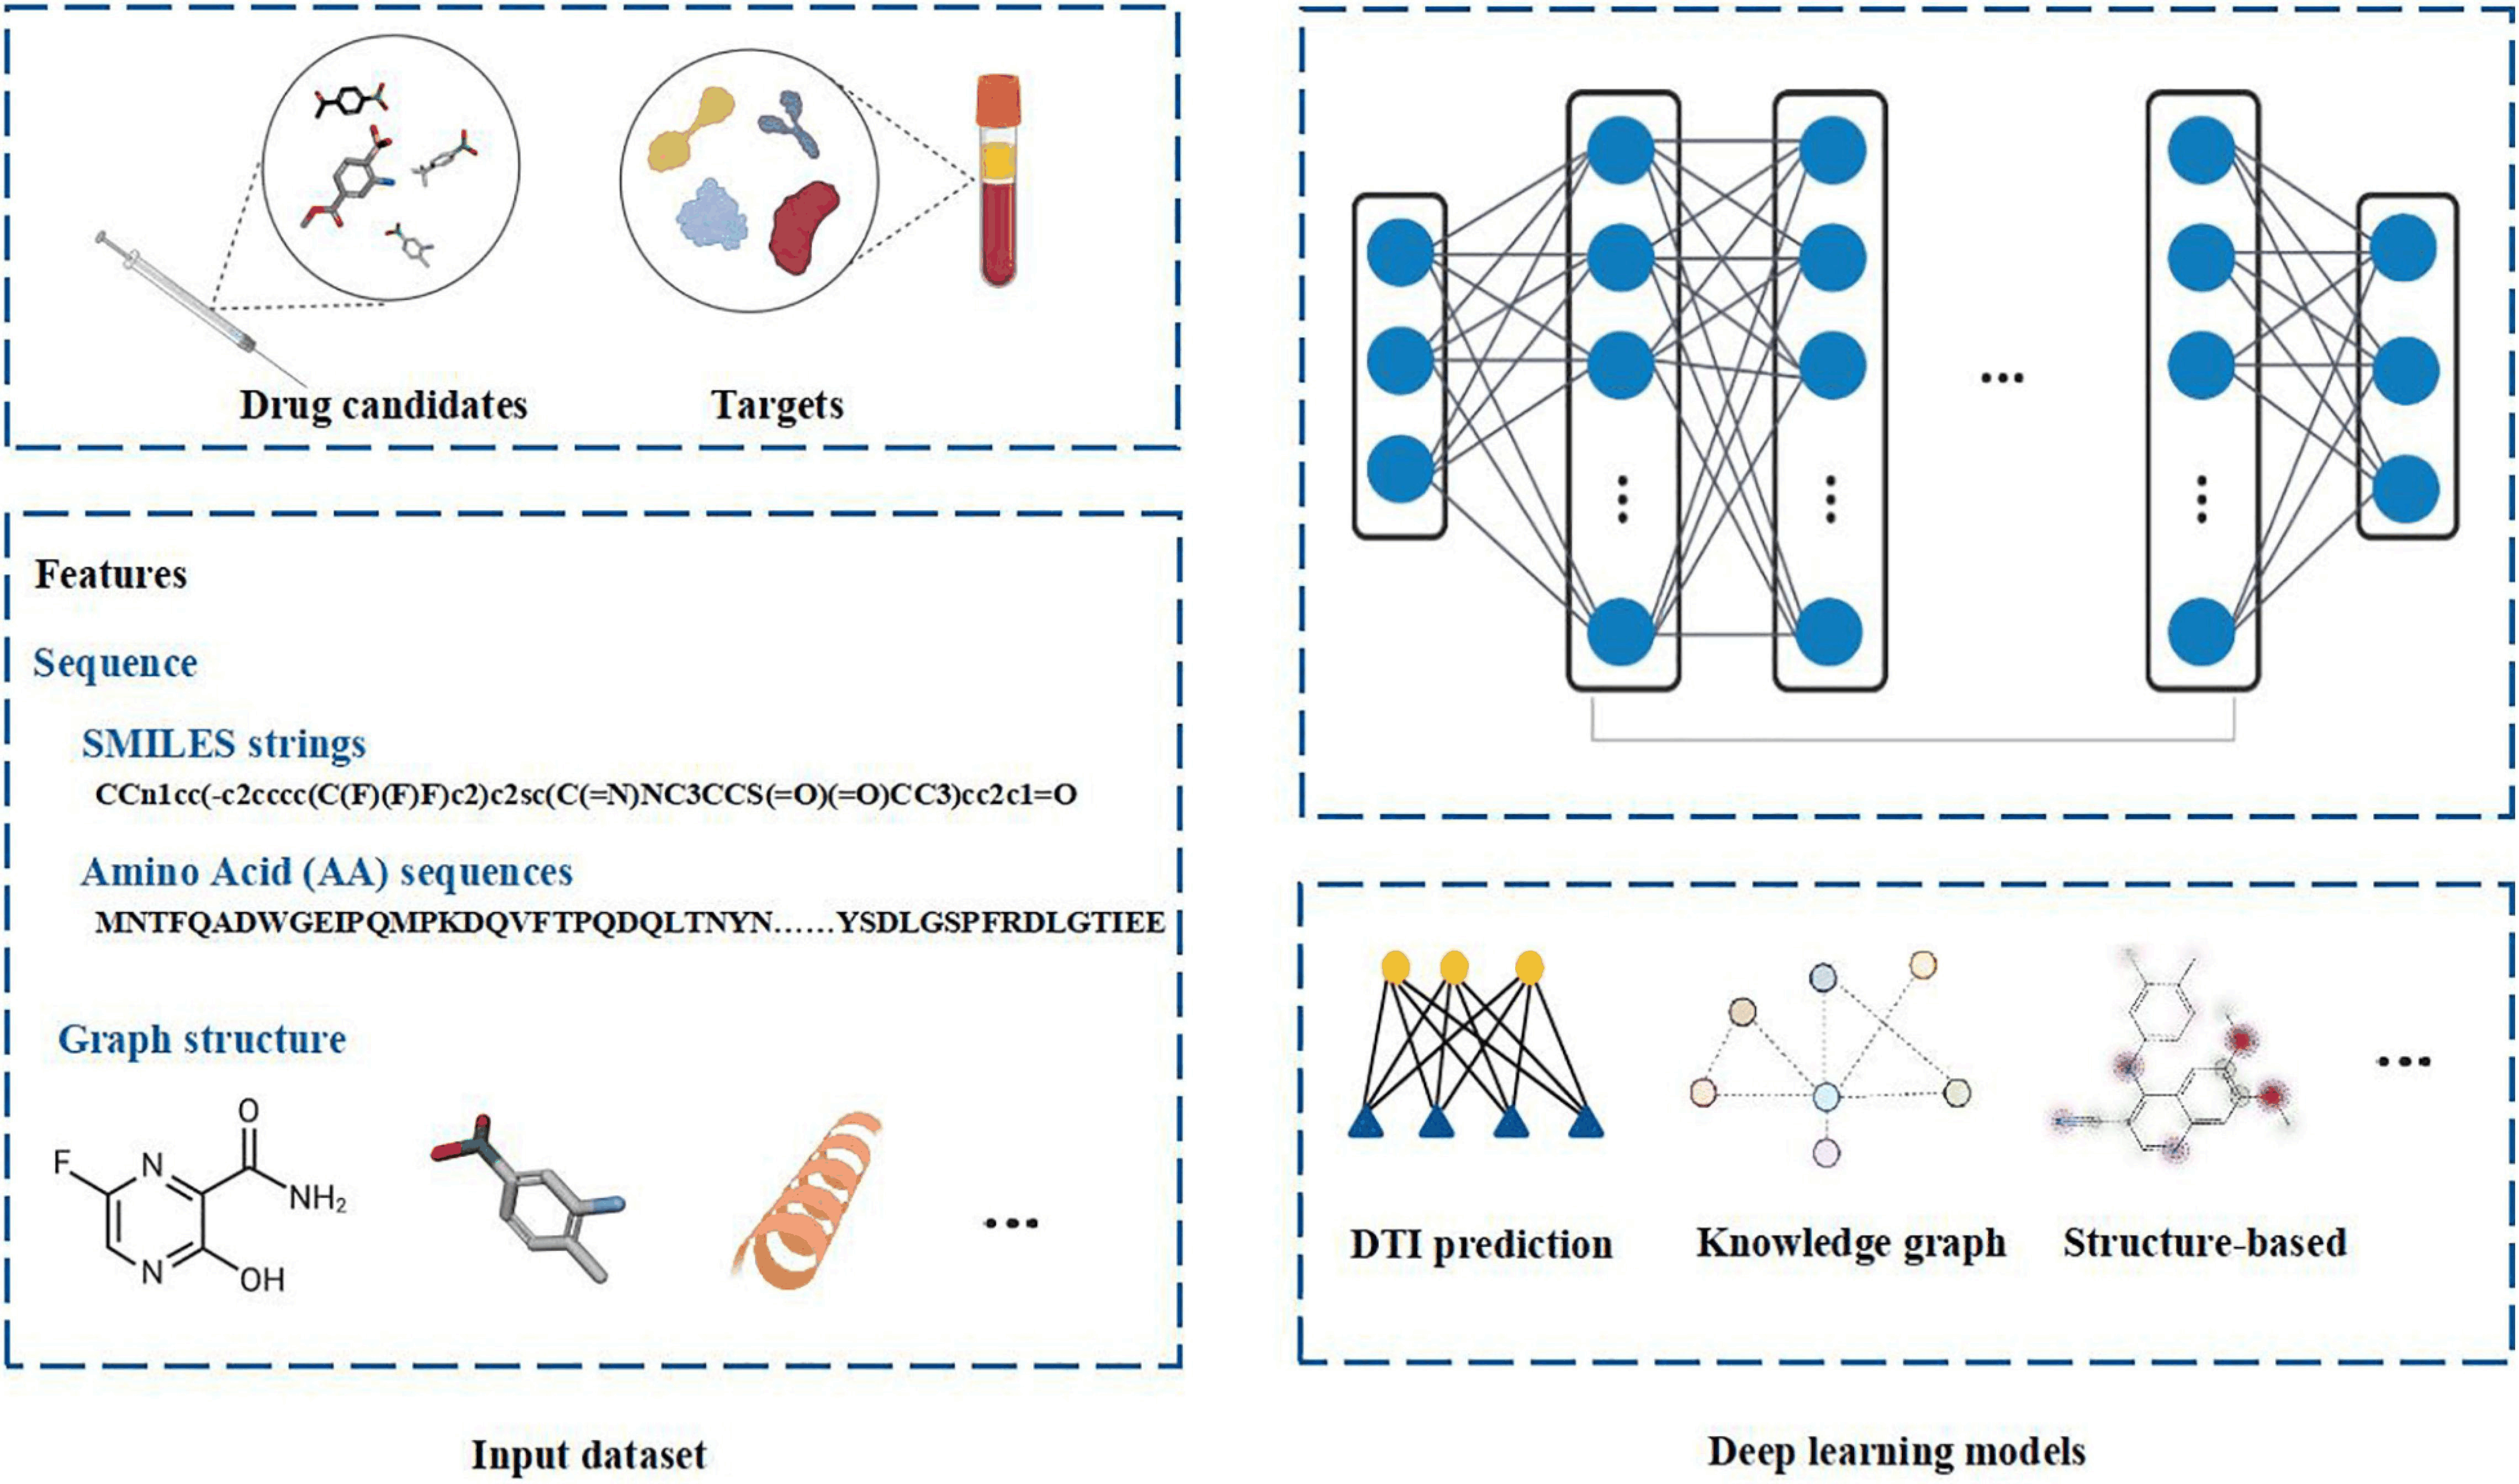
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)