Complete Technical Paper Content — Ai Expense Management
1. Executive Abstract, Problem Formulation & Background
Multi-agent reinforcement learning (MARL) is a sub-field of reinforcement learning. It focuses on studying the behavior of multiple learning agents that coexist in a shared environment. Each agent is motivated by its own rewards, and does actions to advance its own interests; in some environments these interests are opposed to the interests of other agents, resulting in complex group dynamics. Multi-agent reinforcement learning is closely related to game theory and especially repeated games, as well as multi-agent systems. Its study combines the pursuit of finding ideal algorithms that maximize rewards with a more sociological set of concepts. While research in single-agent reinforcement learning is concerned with finding the algorithm that gets the biggest number of points for one agent, research in multi-agent reinforcement learning evaluates and quantifies social metrics, such as cooperation, reciprocity, equity, social influence, language and discrimination.
A set S {\displaystyle S} of environment states. One set A i {\displaystyle {\mathcal {A}}_{i}} of actions for each of the agents i ∈ I = { 1 , … , N } {\displaystyle i\in I=\{1,\dots ,N\}} .
P a → ( s , s ′ ) = Pr ( s t + 1 = s ′ ∣ s t = s , a → t = a → ) {\displaystyle P_{\vec {a}}(s,s')=\Pr(s_{t+1}=s'\mid s_{t}=s,{\vec {a}}_{t}={\vec {a}})} is the probability of transition (at time t {\displaystyle t} ) from state s {\displaystyle s} to state s ′ {\displaystyle s'} under joint action a → {\displaystyle {\vec {a}}} .
R → a → ( s , s ′ ) {\displaystyle {\vec {R}}_{\vec {a}}(s,s')} is the immediate joint reward after the transition from s {\displaystyle s} to s ′ {\displaystyle s'} with joint action a → {\displaystyle {\vec {a}}} . In settings with perfect information, such as the games of chess and Go, the MDP would be fully observable. In settings with imperfect information, especially in real-world applications like self-driving cars, each agent would access an observation that only has part of the information about the current state. In the partially observable setting, the core model is the partially observable stochastic game in the general case, and the decentralized POMDP in the cooperative case.
In pure competition settings, the agents' rewards are exactly opposite to each other, and therefore they are playing against each other. Pure cooperation settings are the other extreme, in which agents get the exact same rewards, and therefore they are playing with each other. Mixed-sum settings cover all the games that combine elements of both cooperation and competition.
Most real-world scenarios involving multiple agents have elements of both cooperation and competition. For example, when multiple self-driving cars are planning their respective paths, each of them has interests that are diverging but not exclusive: Each car is minimizing the amount of time it's taking to reach its destination, but all cars have the shared interest of avoiding a traffic collision. Zero-sum settings with three or more agents often exhibit similar properties to mixed-sum settings, since each pair of agents might have a non-zero utility sum between them. Mixed-sum settings can be explored using classic matrix games such as prisoner's dilemma, more complex sequential social dilemmas, and recreational games such as Among Us, Diplomacy and StarCraft II. Mixed-sum settings can give rise to communication and social dilemmas.
2. Related Work, Literature Survey & Algorithmic Foundations
Stefano V. Albrecht, Filippos Christianos, Lukas Schäfer. Multi-Agent Reinforcement Learning: Foundations and Modern Approaches. MIT Press, 2024. https://www.marl-book.com Kaiqing Zhang, Zhuoran Yang, Tamer Basar. Multi-agent reinforcement learning: A selective overview of theories and algorithms. Studies in Systems, Decision and Control, Handbook on RL and Control, 2021. [1] Yang, Yaodong; Wang, Jun (2020). "An Overview of Multi-Agent Reinforcement Learning from Game Theoretical Perspective". arXiv:2011.00583 [cs.MA].
AI observability is the practice of collecting and analyzing telemetry, data such as logs, metrics, and traces that a system automatically records as it runs, from artificial intelligence systems deployed in production, in order to understand how they behave and how well they perform in terms of accuracy, cost, and safety. It applies the idea of observability, which comes from control theory and software engineering, to systems based on machine learning models, and in particular to large language models (LLMs) and autonomous agents. In control theory, observability is a measure of how well the internal state of a system can be inferred from its external outputs. AI observability is often distinguished from conventional monitoring. Where monitoring relies on predefined metrics, thresholds, and alerts to signal that a problem has occurred, observability aims to provide enough context to understand why it occurred. The distinction matters for AI systems in particular, because a system can appear healthy by standard infrastructure measures, such as latency or error rate, while still producing answers that are wrong, irrelevant, or unsafe. One of the signals that AI observability tracks is the change in a model's behavior over time, a phenomenon studied in machine learning under the name of concept drift. AI observability is closely related to MLOps (machine learning operations), and it is sometimes treated as one of its parts. When it is applied specifically to language models or to agent-based systems, it is also called LLM observability or agent observability.
Inputs and outputs: the prompts sent to a model and the responses it returns. These are sometimes stored in full so that problems can be studied later. Cost and resource usage: how many tokens a request uses and how much it costs, together with latency. These are common measures of inference efficiency and help identify waste and unexpected expense. Performance: latency, throughput, and error rate, as in traditional application performance management. Output quality: how relevant, accurate, and well aligned with the prompt the answer is. These properties usually cannot be checked by normal code, and they include the rate of hallucinations. Behavior over time: changes in the model, known as drift, and worse results after a model or prompt change. Safety and policy: finding policy violations, unsafe content, and unusual usage. For agent-based systems, more signals are needed because the work happens in many steps. These signals record the intermediate reasoning steps, the calls to external tools and APIs, and the retrieval-augmented generation chains.
End to end tracing of requests as they move through pipelines, chains, or agent steps, so that each stage of the execution becomes visible. Structured logging of events, including model identifiers, timestamps, and request and response pairs. Anomaly detection over the telemetry, in order to surface unexpected behavior. Synthetic monitoring, in which predefined test prompts are sent repeatedly, for example after a model or prompt update, to detect regressions. Automated evaluation, including the use of one language model to assess the output of another, an approach often called "LLM-as-a-judge", for qualities that are difficult to measure with conventional code. Human-in-the-loop review at important checkpoints.
The observability of autonomous agents is often treated as a distinct sub-area, because agents navigate multi-step workflows, make autonomous decisions, and invoke external tools, producing execution paths that are more complex than those of single-prompt model calls. Practitioners distinguish evaluation, which tests whether an agent can perform a task before or during deployment, from observability, which monitors whether it is performing correctly once deployed. Tracing an agent execution is typically structured as a hierarchy of spans, in which each model invocation, tool call, memory access, or delegation to a sub-agent constitutes a child span of the enclosing request. This structure allows the latency, cost, and error state of each individual step to be examined in isolation, and makes it possible to identify which step in a multi-step pipeline produced an incorrect or unsafe intermediate result. Capturing the intermediate reasoning that an agent produces before committing to an action is also treated as a distinct telemetry signal, because it allows operators to assess not only what the system did but why it chose to do it.
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs .
Mathematical Formulation 1.1: Loss Objectives and Optimization Dynamics for Ai Expense Management. The training protocol of ai expense management minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 1.2: Feature Extraction and Layer Formulations for Ai Expense Management. The primary computational backbone for Ai Expense Management incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 1.3: Stochastic Augmentation and Normalization Protocols for Ai Expense Management. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 1.4: TensorRT Acceleration and Edge Quantization for Ai Expense Management. Production deployment of Ai Expense Management focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Mathematical Formulation 2.1: Loss Objectives and Optimization Dynamics for Ai Expense Management. The training protocol of ai expense management minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 2.2: Feature Extraction and Layer Formulations for Ai Expense Management. The primary computational backbone for Ai Expense Management incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 2.3: Stochastic Augmentation and Normalization Protocols for Ai Expense Management. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 2.4: TensorRT Acceleration and Edge Quantization for Ai Expense Management. Production deployment of Ai Expense Management focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Mathematical Formulation 3.1: Loss Objectives and Optimization Dynamics for Ai Expense Management. The training protocol of ai expense management minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 3.2: Feature Extraction and Layer Formulations for Ai Expense Management. The primary computational backbone for Ai Expense Management incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Data Pipeline 3.3: Stochastic Augmentation and Normalization Protocols for Ai Expense Management. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 3.4: TensorRT Acceleration and Edge Quantization for Ai Expense Management. Production deployment of Ai Expense Management focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Mathematical Formulation 4.1: Loss Objectives and Optimization Dynamics for Ai Expense Management. The training protocol of ai expense management minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 4.2: Feature Extraction and Layer Formulations for Ai Expense Management. The primary computational backbone for Ai Expense Management incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 4.3: Stochastic Augmentation and Normalization Protocols for Ai Expense Management. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 4.4: TensorRT Acceleration and Edge Quantization for Ai Expense Management. Production deployment of Ai Expense Management focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Model Figures & Evaluation Curves (4 Images)
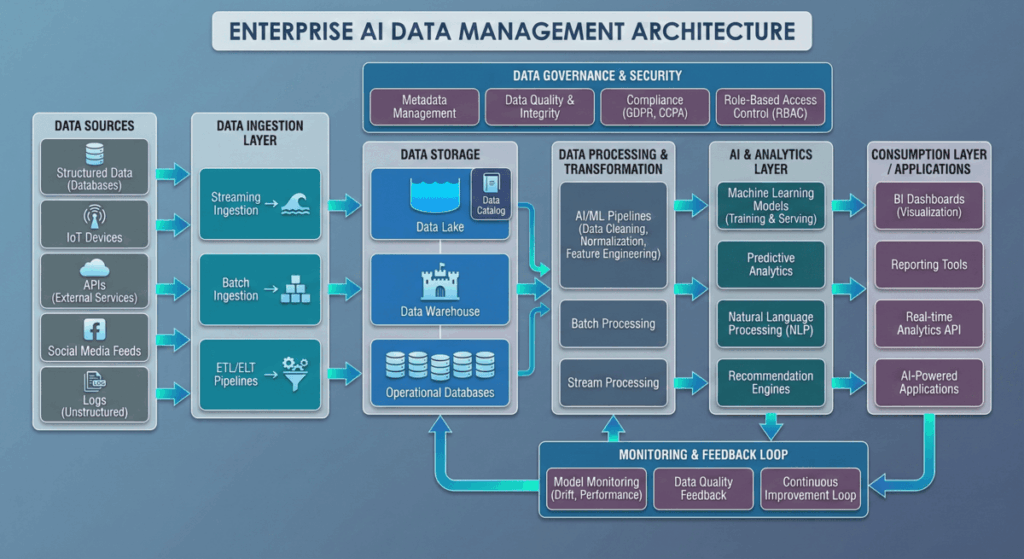
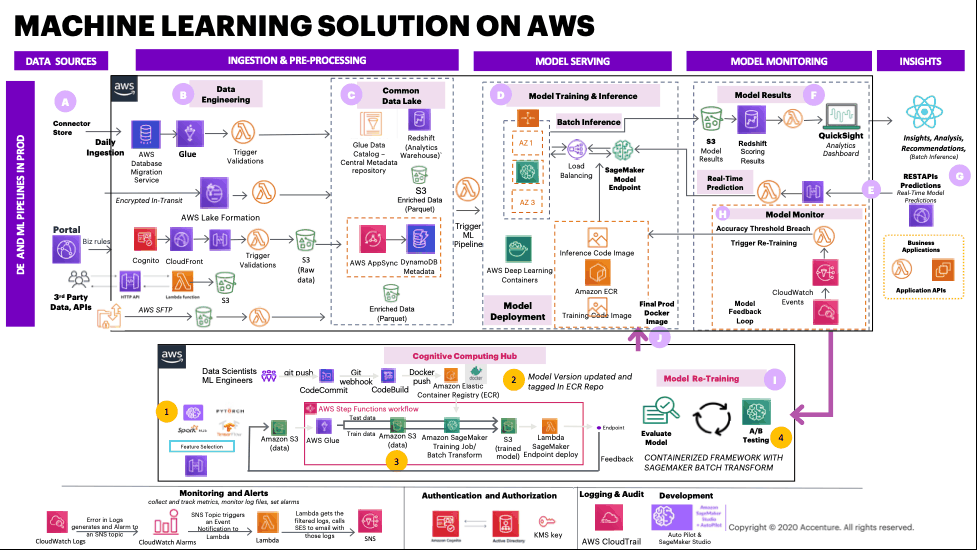
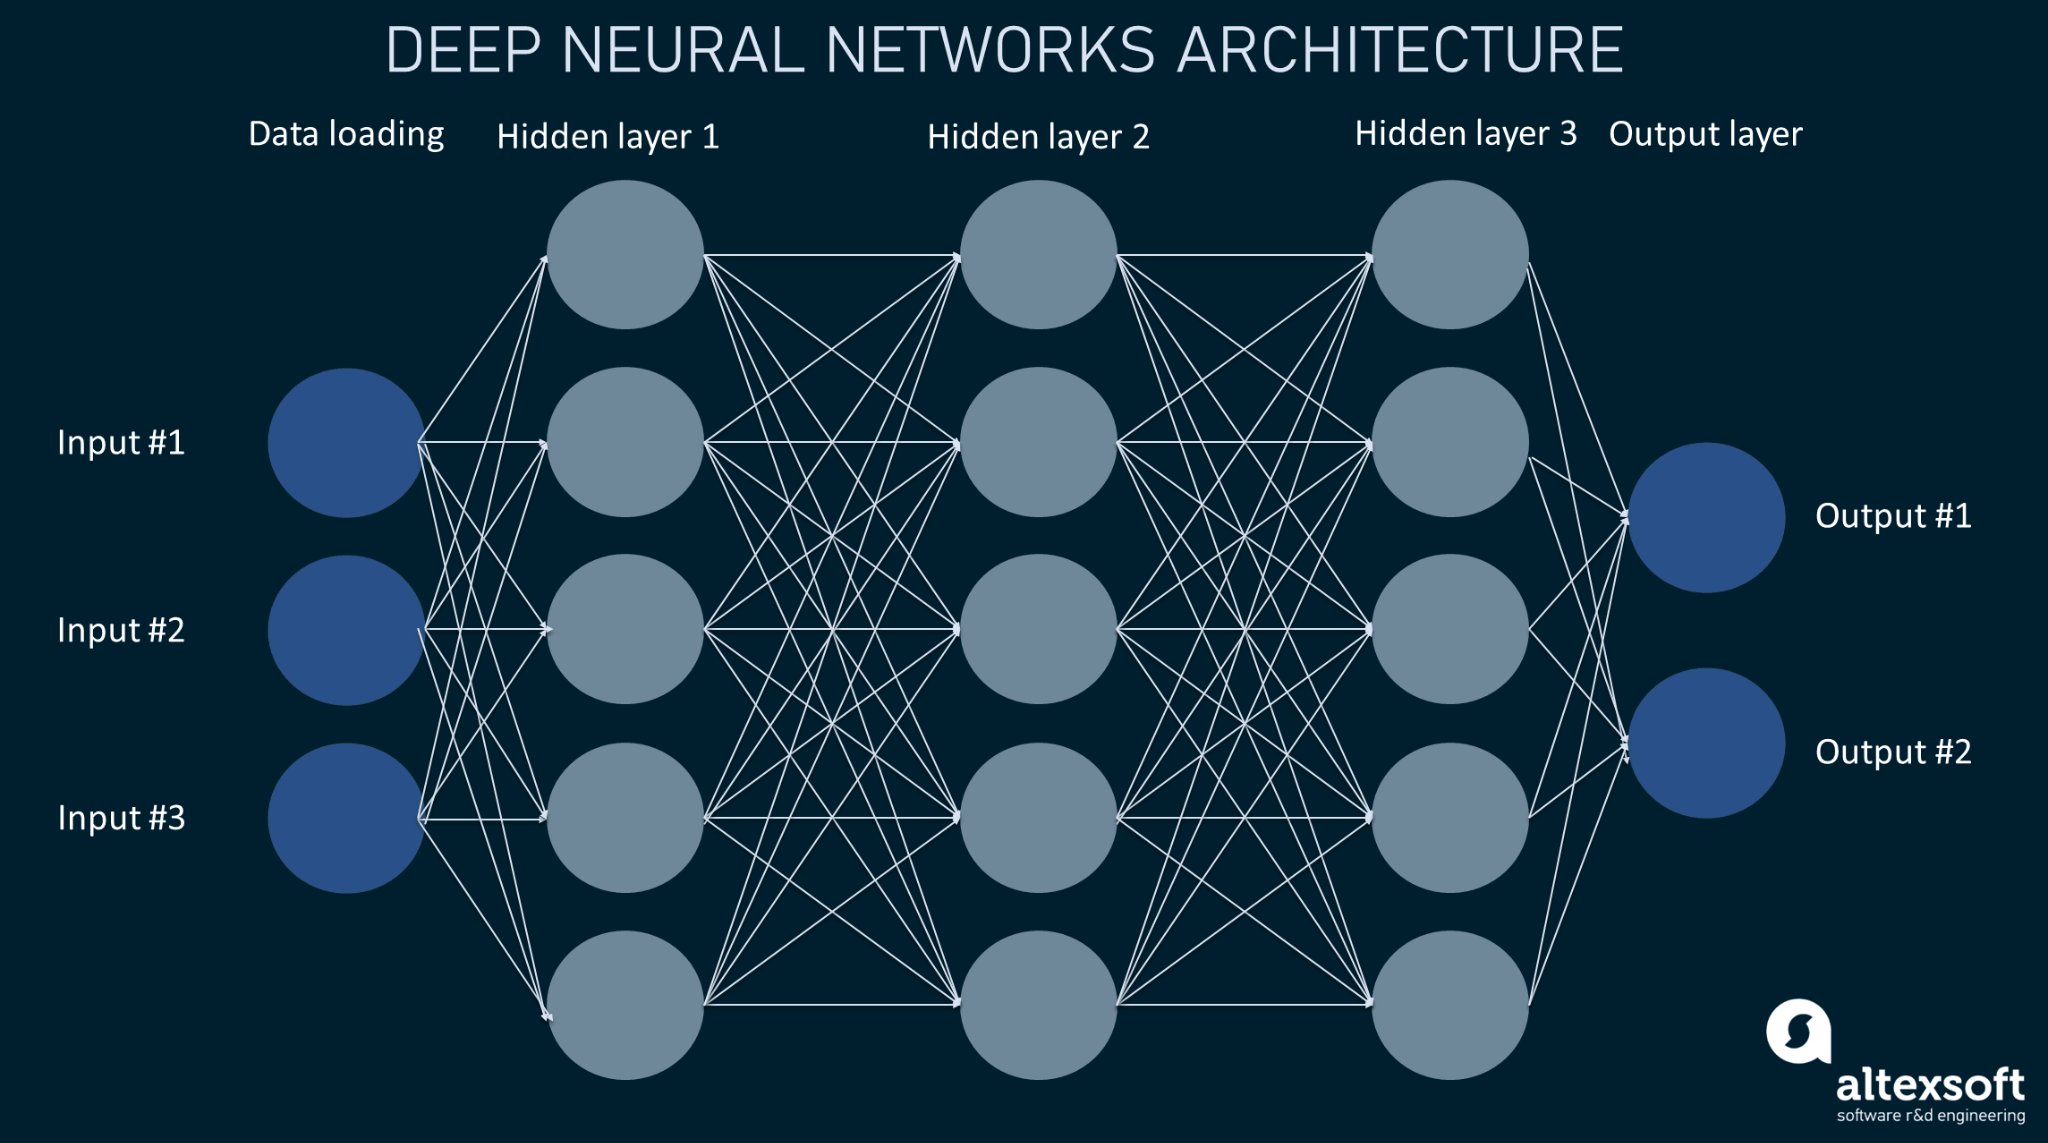
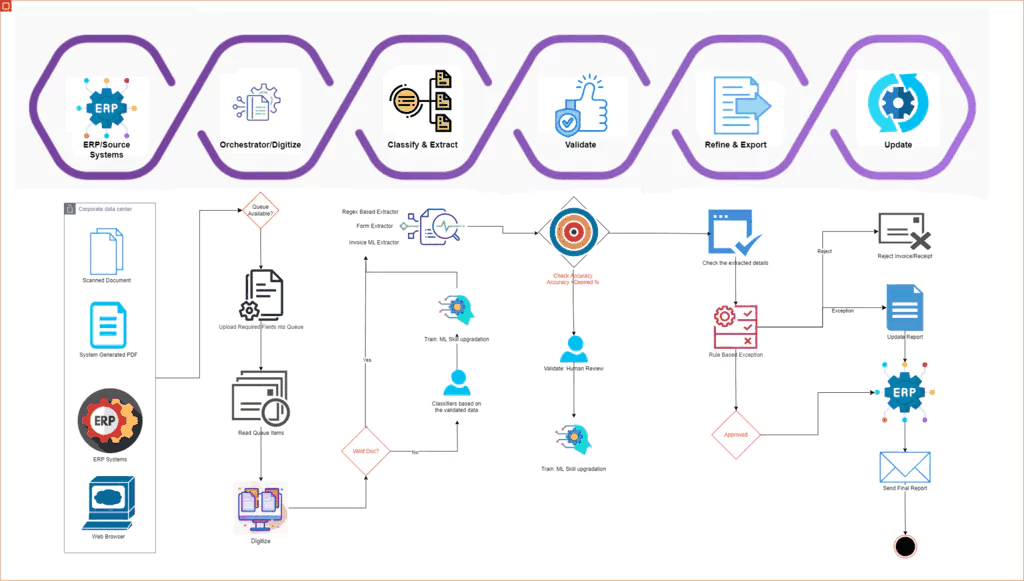
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)