Complete Technical Paper Content — Ai Fashion Recommendation
1. Executive Abstract, Problem Formulation & Background
In machine learning, deep learning (DL) focuses on utilizing multilayered neural networks to perform tasks such as classification, regression, and representation learning. The field takes inspiration from biological neuroscience and revolves around stacking artificial neurons into layers and "training" them to process data. The adjective "deep" refers to the use of multiple layers (ranging from three to several hundred or thousands) in the network. Methods used can be supervised, semi-supervised or unsupervised. Some common deep learning network architectures include fully connected networks, deep belief networks, recurrent neural networks, recurrent Random neural networks, convolutional neural networks, generative adversarial networks, transformers, and neural radiance fields. These architectures have been applied to fields including computer vision, speech recognition, natural language processing, machine translation, bioinformatics, drug design, medical image analysis, climate science, material inspection and board game programs, where they have produced results comparable to and in some cases surpassing human expert performance. Early forms of neural networks were inspired by information processing and distributed communication nodes in biological systems, particularly the human brain. However, current neural networks do not intend to model the brain function of organisms, and are generally seen as low-quality models for that purpose.
The universal approximation theorem for deep neural networks concerns the capacity of networks with bounded width but the depth is allowed to grow. Lu et al. proved that if the width of a deep neural network with ReLU activation is strictly larger than the input dimension, then the network can approximate any Lebesgue integrable function; if the width is smaller or equal to the input dimension, then a deep neural network is not a universal approximator. The probabilistic interpretation derives from the field of machine learning. It features inference, as well as the optimization concepts of training and testing, related to fitting and generalization, respectively. More specifically, the probabilistic interpretation considers the activation nonlinearity as a cumulative distribution function. The probabilistic interpretation led to the introduction of dropout as regularizer in neural networks. The probabilistic interpretation was introduced by researchers including Hopfield, Widrow and Narendra and popularized in surveys such as the one by Bishop.
. In recent years, new developments of the Random neural network that have large and dense clusters of recurrent neurons with Deep Learning, have resulted in highly accurate algorithms for cyberattack detection and mitigation
, as well as for the real-time control of smart homes. In the 1980s, backpropagation did not work well for deep learning with long credit assignment paths. To overcome this problem, in 1991, Jürgen Schmidhuber proposed a hierarchy of RNNs pre-trained one level at a time by self-supervised learning where each RNN tries to predict its own next input, which is the next unexpected input of the RNN below. This "neural history compressor" uses predictive coding to learn internal representations at multiple self-organizing time scales. This can substantially facilitate downstream deep learning. The RNN hierarchy can be collapsed into a single RNN, by distilling a higher level chunker network into a lower level automatizer network. In 1993, a neural history compressor solved a "Very Deep Learning" task that required more than 1000 subsequent layers in an RNN unfolded in time. The "P" in ChatGPT refers to such pre-training. Sepp Hochreiter's diploma thesis (1991) implemented the neural history compressor, and identified and analyzed the vanishing gradient problem. Hochreiter proposed recurrent residual connections to solve the vanishing gradient problem. This led to the long short-term memory (LSTM), published in 1995. LSTM can learn "very deep learning" tasks with long credit assignment paths that require memories of events that happened thousands of discrete time steps before. That LSTM was not yet the modern architecture, which required a "forget gate", introduced in 1999, which became the standard RNN architecture. In 1991, Jürgen Schmidhuber also published adversarial neural networks that contest with each other in the form of a zero-sum game, where one network's gain is the other network's loss. The first network is a generative model that models a probability distribution over output patterns. The second network learns by gradient descent to predict the reactions of the environment to these patterns. This was called "artificial curiosity". In 2014, this principle was used in generative adversarial networks (GANs). During 1985–1995, inspired by statistical mechanics, several architectures and methods were developed by Terry Sejnowski, Peter Dayan, Geoffrey Hinton, etc., including the Boltzmann machine, restricted Boltzmann machine, Helmholtz machine, and the wake-sleep algorithm. These were designed for unsupervised learning of deep generative models. However, those were more computationally expensive compared to backpropagation. Boltzmann machine learning algorithm, published in 1985, was briefly popular before being eclipsed by the backpropagation algorithm in 1986. (p. 112 ). A 1988 network became state of the art in protein structure prediction, an early application of deep learning to bioinformatics. Both shallow and deep learning (e.g., recurrent nets) of ANNs for speech recognition have been explored for many years. These methods never outperformed non-uniform internal-handcrafting Gaussian mixture model/Hidden Markov model (GMM-HMM) technology based on generative models of speech trained discriminatively. Key difficulties have been analyzed, including gradient diminishing and weak temporal correlation structure in neural predictive models. Additional difficulties were the lack of training data and limited computing power. Most speech recognition researchers moved away from neural nets to pursue generative modeling. An exception was at SRI International in the late 1990s. Funded by the US government's NSA and DARPA, SRI researched in speech and speaker recognition. The speaker recognition team led by Larry Heck reported significant success with deep neural networks in speech processing in the 1998 NIST Speaker Recognition benchmark. It was deployed in the Nuance Verifier, representing the first major industrial application of deep learning. The principle of elevating "raw" features over hand-crafted optimization was first explored successfully in the architecture of deep autoencoder on the "raw" spectrogram or linear filter-bank features in the late 1990s, showing its superiority over the Mel-Cepstral features that contain stages of fixed transformation from spectrograms. The raw features of speech, waveforms, later produced excellent larger-scale results.
The period of significant growth in both the adoption and performance of deep learning in the 2010s was driven by the emergence of efficient implementations of CNNs on GPU hardware. Although CNNs trained by backpropagation had been around for decades and GPU implementations of NNs for years, including CNNs, faster implementations of CNNs on GPUs were needed to progress on computer vision. Later, as deep learning becomes widespread, specialized hardware and algorithm optimizations were developed specifically for deep learning. A key advance for the deep learning revolution was hardware advances, especially GPU. Some early work dated back to 2004. In 2009, Raina, Madhavan, and Andrew Ng reported a 100M deep belief network trained on 30 Nvidia GeForce GTX 280 GPUs, an early demonstration of GPU-based deep learning. They reported up to 70 times faster training. In 2011, a CNN named DanNet by Dan Ciresan, Ueli Meier, Jonathan Masci, Luca Maria Gambardella, and Jürgen Schmidhuber achieved for the first time superhuman performance in a visual pattern recognition contest, outperforming traditional methods by a factor of 3. It then won more contests. They also showed how max-pooling CNNs on GPU improved performance significantly. In 2012, Andrew Ng and Jeff Dean created an FNN that learned to recognize higher-level concepts, such as cats, only from watching unlabeled images taken from YouTube videos. In October 2012, AlexNet by Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton won the large-scale ImageNet competition by a significant margin over shallow machine learning methods. Further incremental improvements included the VGG-16 network by Karen Simonyan and Andrew Zisserman and Google's Inceptionv3. In 2013, Tomáš Mikolov and colleagues developed word2vec, a method for efficiently learning word embeddings from large text corpora. The resulting vector representations were shown to capture syntactic and semantic relationships between words. A subsequent paper introduced negative sampling as an efficient method for training such models. The success in image classification was then extended to the more challenging task of generating descriptions (captions) for images, often as a combination of CNNs and LSTMs. In 2014, the state of the art was training a "very deep neural network" with 20 to 30 layers. Stacking too many layers led to a steep reduction in training accuracy, known as the "degradation" problem. In 2015, two techniques were developed to train very deep networks: the highway network was published in May 2015, and the residual neural network (ResNet) in Dec 2015. ResNet behaves like an open-gated Highway Net. Around the same time, deep learning started impacting the field of art. Early examples included Google DeepDream (2015), and neural style transfer (2015), both of which were based on pretrained image classification neural networks, such as VGG-19. Generative adversarial network (GAN) by (Ian Goodfellow et al., 2014) (based on Jürgen Schmidhuber's principle of artificial curiosity) became state of the art in generative modeling during 2014-2018 period. Excellent image quality is achieved by Nvidia's StyleGAN (2018) based on the Progressive GAN by Tero Karras et al. Here the GAN generator is grown from small to large scale in a pyramidal fashion. Image generation by GAN reached popular success, and provoked discussions concerning deepfakes. Diffusion models (2015) eclipsed GANs in generative modeling since then, with systems such as DALL·E 2 (2022) and Stable Diffusion (2022). In 2015, Google's speech recognition improved by 49% by an LSTM-based model, which they made available through Google Voice Search on smartphone. Deep learning is part of state-of-the-art systems in various disciplines, particularly computer vision and automatic speech recognition (ASR). Results on commonly used evaluation sets such as TIMIT (ASR) and MNIST (image classification), as well as a range of large-vocabulary speech recognition tasks have steadily improved. Convolutional neural networks were superseded for ASR by LSTM. but are more successful in computer vision. Yoshua Bengio, Geoffrey Hinton and Yann LeCun were awarded the 2018 Turing Award for "conceptual and engineering breakthroughs that have made deep neural networks a critical component of computing".
Artificial neural networks (ANNs) or connectionist systems are computing systems inspired by the biological neural networks that constitute animal brains. Such systems learn (progressively improve their ability) to do tasks by considering examples, generally without task-specific programming. For example, in image recognition, they might learn to identify images that contain cats by analyzing example images that have been manually labeled as "cat" or "no cat" and using the analytic results to identify cats in other images. They have found most use in applications difficult to express with a traditional computer algorithm using rule-based programming. An ANN is based on a collection of connected units called artificial neurons, (analogous to biological neurons in a biological brain). Each connection (synapse) between neurons can transmit a signal to another neuron. The receiving (postsynaptic) neuron can process the signal(s) and then signal downstream neurons connected to it. Neurons may have state, generally represented by real numbers, typically between 0 and 1. Neurons and synapses may also have a weight that varies as learning proceeds, which can increase or decrease the strength of the signal that it sends downstream. Typically, neurons are organized in layers. Different layers may perform different kinds of transformations on their inputs. Signals travel from the first (input), to the last (output) layer, possibly after traversing the layers multiple times. The original goal of the neural network approach was to solve problems in the same way that a human brain would. Over time, attention focused on matching specific mental abilities, leading to deviations from biology such as backpropagation, or passing information in the reverse direction and adjusting the network to reflect that information. Neural networks have been used on a variety of tasks, including computer vision, speech recognition, machine translation, social network filtering, playing board and video games and medical diagnosis. As of 2017, neural networks typically have a few thousand to a few million units and millions of connections. Despite this number being several order of magnitude less than the number of neurons on a human brain, these networks can perform many tasks at a level beyond that of humans (e.g., recognizing faces, or playing "Go").
2. Related Work, Literature Survey & Algorithmic Foundations
Large-scale automatic speech recognition is the first and most convincing successful case of deep learning. LSTM RNNs can learn "Very Deep Learning" tasks that involve multi-second intervals containing speech events separated by thousands of discrete time steps, where one time step corresponds to about 10 ms. LSTM with forget gates is competitive with traditional speech recognizers on certain tasks. The initial success in speech recognition was based on small-scale recognition tasks based on TIMIT. The data set contains 630 speakers from eight major dialects of American English, where each speaker reads 10 sentences. Its small size lets many configurations be tried. More importantly, the TIMIT task concerns phone-sequence recognition, which, unlike word-sequence recognition, allows weak phone bigram language models. This lets the strength of the acoustic modeling aspects of speech recognition be more easily analyzed. The error rates listed below, including these early results and measured as percent phone error rates (PER), have been summarized since 1991.
The debut of DNNs for speaker recognition in the late 1990s and speech recognition around 2009-2011 and of LSTM around 2003–2007, accelerated progress in eight major areas:
Scale-up/out and accelerated DNN training and decoding Sequence discriminative training Feature processing by deep models with solid understanding of the underlying mechanisms Adaptation of DNNs and related deep models Multi-task and transfer learning by DNNs and related deep models CNNs and how to design them to best exploit domain knowledge of speech RNN and its rich LSTM variants Other types of deep models including tensor-based models and integrated deep generative/discriminative models. More recent speech recognition models use Transformers or Temporal Convolution Networks with significant success and widespread applications. All major commercial speech recognition systems (e.g., Microsoft Cortana, Xbox, Skype Translator, Amazon Alexa, Google Now, Apple Siri, Baidu and iFlyTek voice search, and a range of Nuance speech products, etc.) are based on deep learning.
A common evaluation set for image classification is the MNIST database data set. MNIST is composed of handwritten digits and includes 60,000 training examples and 10,000 test examples. As with TIMIT, its small size lets users test multiple configurations. A comprehensive list of results on this set is available. Deep learning-based image recognition has become "superhuman", producing more accurate results than human contestants. This first occurred in 2011 in recognition of traffic signs, and in 2014, with recognition of human faces. Deep learning-trained vehicles now interpret 360° camera views. Another example is Facial Dysmorphology Novel Analysis (FDNA) used to analyze cases of human malformation connected to a large database of genetic syndromes.
Closely related to the progress that has been made in image recognition is the increasing application of deep learning techniques to various visual art tasks. DNNs have proven themselves capable, for example, of
identifying the style period of a given painting Neural Style Transfer – capturing the style of a given artwork and applying it in a visually pleasing manner to an arbitrary photograph or video generating striking imagery based on random visual input fields.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Neural networks have been used for implementing language models since the early 2000s. LSTM helped to improve machine translation and language modeling. Other key techniques in this field are negative sampling and word embedding. Word embedding, such as word2vec, can be thought of as a representational layer in a deep learning architecture that transforms an atomic word into a positional representation of the word relative to other words in the dataset; the position is represented as a point in a vector space. Using word embedding as an RNN input layer allows the network to parse sentences and phrases using an effective compositional vector grammar. A compositional vector grammar can be thought of as probabilistic context free grammar (PCFG) implemented by an RNN. Recursive auto-encoders built atop word embeddings can assess sentence similarity and detect paraphrasing. Deep neural architectures provide the best results for constituency parsing, sentiment analysis, information retrieval, spoken language understanding, machine translation, contextual entity linking, writing style recognition, named-entity recognition (token classification), text classification, and others. Recent developments generalize word embedding to sentence embedding. Google Translate (GT) uses a large end-to-end long short-term memory (LSTM) network. Google Neural Machine Translation (GNMT) uses an example-based machine translation method in which the system "learns from millions of examples". It translates "whole sentences at a time, rather than pieces". Google Translate supports over one hundred languages. The network encodes the "semantics of the sentence rather than simply memorizing phrase-to-phrase translations". GT uses English as an intermediate between most language pairs.
A large percentage of candidate drugs fail to win regulatory approval. These failures are caused by insufficient efficacy (on-target effect), undesired interactions (off-target effects), or unanticipated toxic effects. Research has explored use of deep learning to predict the biomolecular targets, off-targets, and toxic effects of environmental chemicals in nutrients, household products and drugs. AtomNet is a deep learning system for structure-based rational drug design. AtomNet was used to predict novel candidate biomolecules for disease targets such as the Ebola virus and multiple sclerosis. In 2017 graph neural networks were used for the first time to predict various properties of molecules in a large toxicology data set. In 2019, generative neural networks were used to produce molecules that were validated experimentally all the way into mice.
Recommendation systems have used deep learning to extract meaningful features for a latent factor model for content-based music and journal recommendations. Multi-view deep learning has been applied for learning user preferences from multiple domains. The model uses a hybrid collaborative and content-based approach and enhances recommendations in multiple tasks.
An autoencoder ANN was used in bioinformatics, to predict gene ontology annotations and gene-function relationships. In medical informatics, deep learning was used to predict sleep quality based on data from wearables and predictions of health complications from electronic health record data. Deep neural networks have shown unparalleled performance in predicting protein structure, according to the sequence of the amino acids that make it up. In 2020, AlphaFold, a deep-learning based system, achieved a level of accuracy significantly higher than all previous computational methods.
An epigenetic clock is a biochemical test that can be used to measure age. Galkin et al. used deep neural networks to train an epigenetic aging clock of unprecedented accuracy using >6,000 blood samples. The clock uses information from 1000 CpG sites and predicts people with certain conditions older than healthy controls: IBD, frontotemporal dementia, ovarian cancer, obesity. The aging clock was planned to be released for public use in 2021 by an Insilico Medicine spinoff company Deep Longevity.
A main criticism concerns the lack of theory surrounding some methods. Learning in the most common deep architectures is implemented using well-understood gradient descent. However, the theory surrounding other algorithms, such as contrastive divergence is less clear. (e.g., Does it converge? If so, how fast? What is it approximating?) Deep learning methods are often looked at as a black box, with most confirmations done empirically, rather than theoretically. In further reference to the idea that artistic sensitivity might be inherent in relatively low levels of the cognitive hierarchy, a published series of graphic representations of the internal states of deep (20-30 layers) neural networks attempting to discern within essentially random data the images on which they were trained demonstrate a visual appeal: the original research notice received well over 1,000 comments, and was the subject of what was for a time the most frequently accessed article on The Guardian's website. With the support of Innovation Diffusion Theory (IDT), a study analyzed the diffusion of deep learning in BRICS and OECD countries using data from Google Trends.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Artificial intelligence (AI) and its subfields have been used in applications throughout industry and academia. Machine learning has been used for various scientific and commercial purposes, including language translation, image recognition, decision-making, credit scoring, and e-commerce. Since the 2020s, massive advancements have been made in the field of generative AI (GenAI) as a result of the 2017 inception of Transformer Model architecture. GenAI has the ability to create text, images, voice, music, videos, and other forms of data from chat-based prompting.
In agriculture, AI has been proposed as a way for farmers to identify areas that need irrigation, fertilization, or pesticide treatments to increase yields, thereby improving efficiency. AI has been used to attempt to classify livestock pig call emotions, automate greenhouses, detect diseases and pests, and optimize irrigation.
A 2019 study found that generative AI increased productivity by 15% in contact centers. Another 2019 study found it increased productivity by up to 40% for writing tasks. An August 2025 review by MIT found that of surveyed companies, 95% did not report any improvement in revenue from the use of AI. In September 2025, a Harvard Business Review article described how increased use of AI does not automatically lead to increases in revenue or actual productivity. Referring to "AI generated work content that masquerades as good work, but lacks the substance to meaningfully advance a given task", the article coined the term workslop. Per studies done in collaboration with the Stanford Social Media Lab, workslop does not improve productivity and undermines trust and collaboration among colleagues. In telehealth, agentic AI is reportedly facilitating the creation of large business models (millions in annual profit) with 1–2 employees, such as MEDVi, which as of August 2025 only had 2 employees and ~$75M in annual profit for GLP-1 weight-loss telehealth services.
Research and development of quantum computers has been performed with machine learning algorithms. For example, there is a prototype, photonic, quantum memristive device for neuromorphic computers (NC)/artificial neural networks and NC-using quantum materials with some variety of potential neuromorphic computing-related applications. The use of quantum machine learning for quantum simulators has been proposed for solving physics and chemistry problems.
Artificial intelligence and machine learning are used in electronic design automation to assist with integrated circuit design, including floorplanning, placement, routing, functional verification, and optimization of power, performance, and chip area.
Time sharing Interactive interpreters Graphical user interfaces and the computer mouse Rapid application development environments The linked list data structure Automatic storage management Symbolic programming Functional programming Dynamic programming Object-oriented programming Optical character recognition Constraint satisfaction
5. Training Protocol, Convergence Behavior & Experimental Evaluation
AI programs have been used in hiring processes to screen resumes and rank candidates based on their qualifications, predict a candidate's likelihood of success in a given role, and automate repetitive communication tasks using chatbots. Studies on these programs have identified tendencies for gender bias, favoring male names and male-coded characteristics, as well as bias against disabled candidates and racial minorities.
AI underlies avatars (automated online assistants) on web pages. It can reduce operation and training costs. In 2016, Pypestream automated customer service for its mobile application to streamline communication with customers. A Google app analyzes language and converts speech into text. The platform can identify angry customers through their language and respond appropriately. Amazon uses a chatbot for customer service that can perform tasks like checking the status of an order, cancelling orders, offering refunds, and connecting the customer with a human representative.
In educational institutions, AI has been used to automate routine tasks such as attendance tracking, grading, and marking. AI tools have also been used to monitor student progress and analyze learning behaviors, with the goal of facilitating timely interventions for students facing academic challenges. As of 2025 and 2026, respectively, about 80% of high school students and nearly 60% of college students were also using AI. Some schools and universities proposed restrictions on students' usage due to issues with increased cheating, over-reliance on AI tools, and widening of digital inequities.
The U.S. Department of Energy wrote in an April 2024 report that AI may have applications in modeling power grids, reviewing federal permits with large language models (LLMs), predicting levels of renewable energy production, and improving the planning process for electrical vehicle charging networks. Other studies have suggested that machine learning can be used for energy consumption prediction and scheduling (e.g., to help with renewable energy intermittency management).
The late 1980s and early 1990s saw expert systems used in technical and environmental domains. For example, researchers built a fishway design advisor to recommend fish passage structures under varying hydraulic and biological conditions using the VP-Expert shell. Transportation researchers applied the same shell to balance airport capacity with noise-mitigation plans. In agriculture, a potato insect expert system (PIES) supported pest management decisions for Colorado potato beetle. The U.S. Environmental Protection Agency's CORMIX system for modeling pollutant discharges combined rules with Fortran hydrodynamic models. Autonomous ships that monitor the ocean, AI-driven satellite data analysis, passive acoustics or remote sensing and other applications of environmental monitoring make use of machine learning. For example, "Global Plastic Watch" is an AI-based satellite-monitoring platform for analysis/tracking of plastic waste sites to help with the prevention of plastic pollution—primarily ocean pollution—by helping identify who mismanages plastic waste and where dumping into oceans occurs.
AI applications analyze media content such as movies, TV programs, advertisement videos, and user-generated content. The solutions often involve computer vision. Typical scenarios include the analysis of images using object recognition or facial recognition techniques, or the analysis of video for recognizing scenes, objects, or faces. AI-based media analysis can facilitate media search, the creation of descriptive keywords for content, content policy monitoring (such as verifying the suitability of content for a particular TV viewing time), speech to text for archival or other purposes, and the detection of logos, products, or celebrity faces for ad placement.
Model Figures & Evaluation Curves (4 Images)
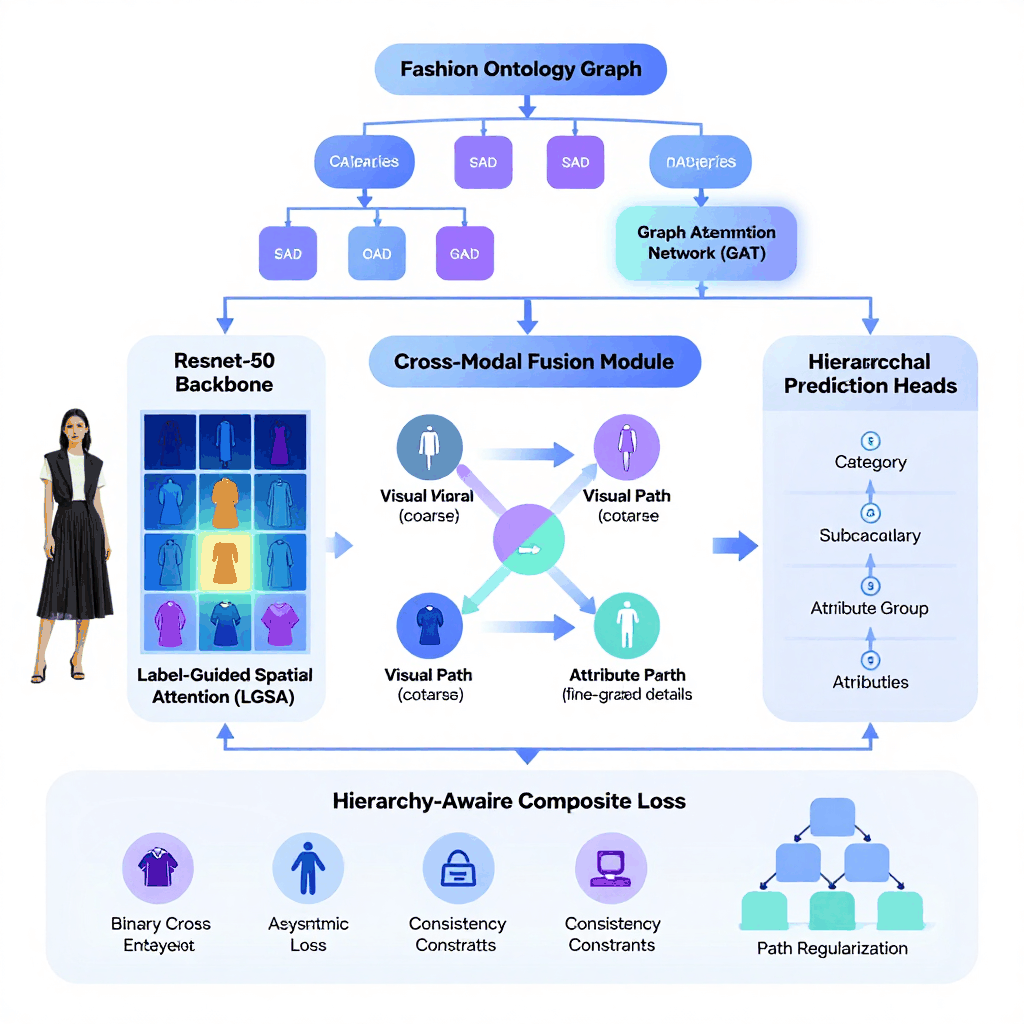
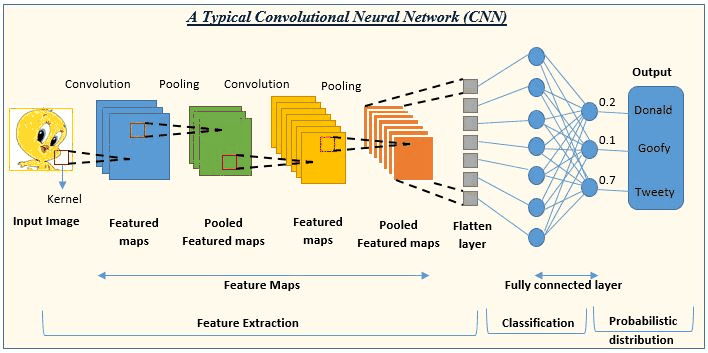
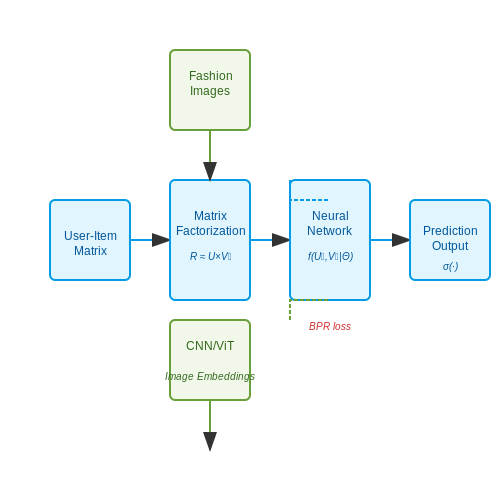
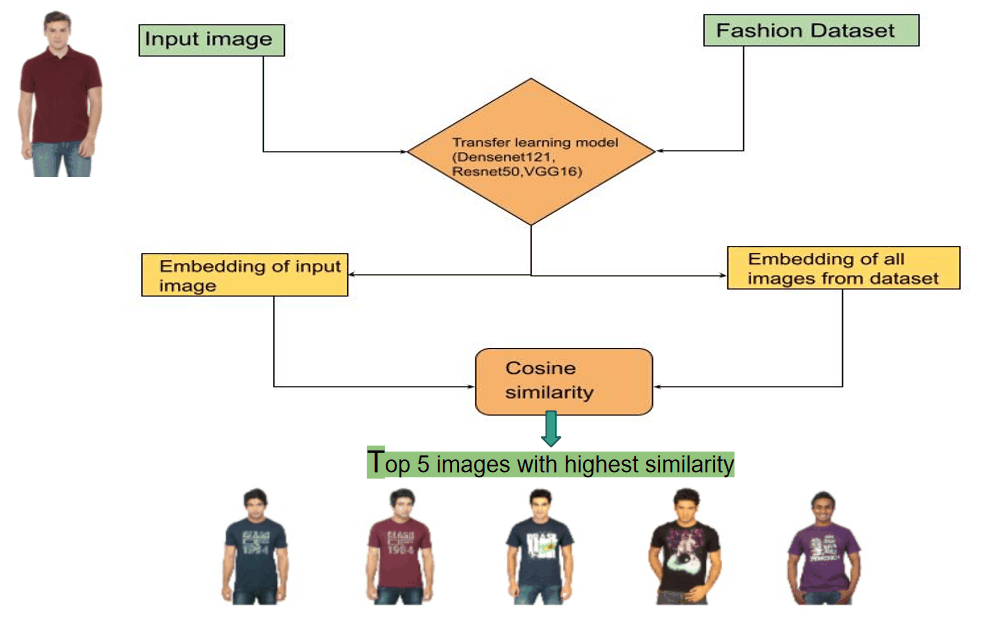
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)