Complete Technical Paper Content — Ai Google Vertex Ai
1. Executive Abstract, Problem Formulation & Background
Gemini, sometimes marketed as Google Gemini and originally known as Bard, is a generative artificial intelligence chatbot and virtual assistant developed by Google. It is powered by the family of large language models (LLMs) of the same name, previously based on LaMDA and PaLM 2. The Gemini chatbot can process and generate text, computer code, images, audio, and video simultaneously. Google distributes the technology via multiple platforms, ranging from smaller on-device versions ("Nano") and more affordable, high-throughput variants ("Flash") to high-compute models designed for complex tasks ("Pro" and "Ultra"). Gemini was first announced on December 6, 2023, as part of the company's response against the launch of OpenAI's ChatGPT, and replaced existing Google branding for AI services. In February 2024, the Bard chatbot was renamed Gemini, and the "Duet AI" branding for Google Cloud and Workspace was retired in favor of the Gemini identifier. The models are accessed via the Gemini mobile app on Android devices and through the Vertex AI platform for third-party developers. At launch, Gemini was criticized for unreliable outputs. In early 2024, Google suspended the model's ability to generate images of people after users reported historical inaccuracies and bias in its depictions of human subjects. Subsequent updates, including the Gemini 1.5 and 3 series released throughout 2025, attempted to reduce hallucinations, improve latency, and improve capabilities for research and software development.
In November 2022, OpenAI launched ChatGPT, a chatbot based on the GPT-3 family of large language models (LLMs). ChatGPT gained worldwide attention, becoming a viral Internet sensation. Alarmed by ChatGPT's potential threat to Google Search, Google executives issued a "code red" alert, reassigning several teams to assist in the company's artificial intelligence (AI) efforts. Sundar Pichai, the CEO of Google and parent company Alphabet, was widely reported to have issued the alert, but Pichai later denied this to The New York Times. In a rare move, Google co-founders Larry Page and Sergey Brin, who had stepped down from their roles as co-CEOs of Alphabet in 2019, attended emergency meetings with company executives to discuss Google's response to ChatGPT. Brin requested access to Google's code in February 2023, for the first time in years. Google had unveiled LaMDA, a prototype LLM, earlier in 2021, but it was not released to the public. When asked by employees at an all-hands meeting whether LaMDA was a missed opportunity for Google to compete with ChatGPT, Pichai and Google AI chief Jeff Dean said that while the company's chatbot had similar capabilities to ChatGPT, there were risks to introducing an LLM that might spread false information, so they decided to wait. In January 2023, Google Brain's sister company DeepMind CEO Demis Hassabis hinted at plans for a ChatGPT rival, and Google employees were instructed to accelerate progress on a ChatGPT competitor, intensively testing "Apprentice Bard" and other chatbots. Pichai assured investors during Google's quarterly earnings investor call in February that the company had plans to expand LaMDA's availability and applications.
Google opened up early access for Bard on March 21, 2023, in a limited capacity, allowing users in the US and the UK to join a waitlist. Unlike Microsoft's approach with Bing Chat, Bard was launched as a standalone web application featuring a text box and a disclaimer that the chatbot "may display inaccurate or offensive information that doesn't represent Google's views". Three responses are then provided to each question, with users prompted to submit feedback on the usefulness of each answer. Google vice presidents Sissie Hsiao and Eli Collins framed Bard as a complement to Google Search and stated that the company had not determined how to make the service profitable. Among those granted early access were those enrolled in Google's "Pixel Superfans" loyalty program, users of its Pixel and Nest devices, and Google One subscribers. Bard is trained by third-party contractors hired by Google, including Appen and Accenture workers, whom Business Insider and Bloomberg News reported were placed under extreme pressure, overworked, and underpaid. Bard is also trained on data from publicly available sources, which Google disclosed by amending its privacy policy. Shortly after Bard's initial launch, Google reorganized the team behind Google Assistant, the company's virtual assistant, to focus on Bard instead. Google researcher Jacob Devlin resigned from the company after claiming that Bard had surreptitiously leveraged data from ChatGPT; Google denied the allegations. Meanwhile, a senior software engineer at the company published an internal memo warning that Google was falling behind in the AI "arms race", not to OpenAI but to independent researchers in open-source communities. Pichai revealed on March 31 that the company intended to "upgrade" Bard by basing it on PaLM, a newer and more powerful LLM from Google, rather than LaMDA. The same day, Krawczyk announced that Google had added "math and logic capabilities" to Bard. Bard gained the ability to assist in coding in April, being compatible with more than 20 programming languages at launch. Microsoft also began running advertisements in the address bar of a developer build of the Edge browser, urging users to try Bing whenever they visit the Bard web app. 9to5Google reported that Google was working to integrate Bard into its ChromeOS operating system and Pixel devices.
On December 6, 2023, Google announced Gemini, a larger, multimodal LLM. A specially tuned version of the mid-tier Gemini Pro was integrated into Bard, while the larger Gemini Ultra was used for "Bard Advanced" in 2024. The Wall Street Journal reported that Bard was then averaging around 220 million monthly visitors. Google ended its contract with Appen in January 2024, while image generation was added to Bard the next month, using Google Brain's Imagen 2 text-to-image model. On February 8, 2024, Bard and Duet AI were unified under the Gemini brand, with a mobile app launched on Android and the service integrated into the Google app on iOS. On Android, users who downloaded the app saw Gemini replace Assistant as their device's default virtual assistant, though Assistant remained a standalone service. Google also launched "Gemini Advanced with Ultra 1.0", available via a "Google One AI Premium" subscription, incorporated Gemini into its Messages app on Android, and announced a partnership with Stack Overflow. Gemini again took center stage at the 2024 Google I/O keynote. Google announced that Gemini would be integrated into several products, including Android, Chrome, Photos, and Workspace. Gemini Advanced was upgraded to the "Gemini 1.5 Pro" language model, with Google previewing Gemini Live, a voice chat mode, and Gems, the ability to create custom chatbots.
2. Related Work, Literature Survey & Algorithmic Foundations
Following the Gemini 1.0 launch in December 2023, Google released successive generations of the underlying model at an accelerating pace. In February 2024, Google introduced Gemini 1.5 Pro in a limited preview, notable for its one-million-token context window, which allowed it to process roughly an hour of video, 11 hours of audio, or 30,000 lines of code in a single prompt. Gemini 1.5 Flash, a faster and more cost-efficient variant aimed at developers, was announced at Google I/O in May 2024 alongside the expansion of Gemini Advanced. On December 11, 2024, Google announced Gemini 2.0 Flash as the first model in the Gemini 2.0 generation, framing it as the beginning of an "agentic era" in which AI models could take autonomous multi-step actions. Unlike previous Gemini models, 2.0 Flash supported native multimodal outputs, including generated images and text-to-speech audio, in addition to multimodal inputs. It also introduced Deep Research for Gemini Advanced users, enabling the model to autonomously browse and synthesize information across sources. Gemini 2.0 Flash became generally available on February 5, 2025, alongside release of Gemini 2.0 Pro and the budget-oriented Gemini 2.0 Flash-Lite. Gemini 2.5 Pro Experimental was released on March 25, 2025, as Google's first explicitly designated "thinking model", capable of reasoning through steps before responding using chain-of-thought techniques. It debuted at the top of the LMArena leaderboard, a benchmark measuring human preference for AI responses, where it remained for several months. Gemini 2.5 Flash was unveiled at Google I/O in May 2025 and reached general availability in June 2025 alongside the cost-optimized Gemini 2.5 Flash-Lite. On November 18, 2025, Google launched Gemini 3 Pro, describing it as its most intelligent model to date and marking a departure from the company's previous staged release patterns, with the model made immediately available across the Gemini app, Google Search, Google AI Studio, and Vertex AI on launch day. A more capable "Deep Think" reasoning mode began rolling out to Google AI Ultra subscribers in the weeks that followed. Gemini 3 Flash, a speed-optimized variant, followed in December 2025, becoming the new default model in the Gemini app. In February 2026, Google released a major upgrade to Gemini 3 Deep Think, which it described as targeting practical applications in science, research, and engineering. On February 19, 2026, Google launched Gemini 3.1 Pro in preview, characterizing it as a step forward in core reasoning. The model achieved an ARC-AGI-2 score of 77.1 percent, more than double that of Gemini 3 Pro, and 80.6 percent on SWE-bench Verified, a benchmark for autonomous software engineering tasks.
In February 2024, social media users reported that Gemini was generating images that featured people of color and women in historically inaccurate contexts—such as Vikings, Nazi soldiers, and the Founding Fathers—and refusing prompts to generate images of white people. These images were derided on social media, including by conservatives who cited them as evidence of Google's "wokeness". The business magnate Elon Musk, whose company xAI operates the chatbot Grok, was among those who criticized Google, denouncing its suite of products as biased and racist. Musk and other users targeted Jack Krawczyk, resurfacing his past comments discussing race, leading Krawczyk to withdraw from X and LinkedIn. The conservative-leaning tabloid New York Post ran a cover story on the incident in the print edition of its newspaper. In response, Krawczyk said that Google was "working to improve these kinds of depictions immediately", and Google paused Gemini's ability to generate images of people. Raghavan released a lengthy statement addressing the controversy, explaining that Gemini had "overcompensate[d]" amid its efforts to strive for diversity and acknowledging that the images were "embarrassing and wrong". In an internal memo to employees, Pichai called the debacle offensive and unacceptable, promising structural and technical changes. Several employees in Google's trust and safety team were laid off days later. Hassabis stated that Gemini's ability to generate images of people would be restored within two weeks; it was ultimately relaunched in late August, powered by its new Imagen 3 model. The market reacted negatively, with Google's stock falling by 4.4 percent. Pichai faced growing calls to resign, including from technology analysts Ben Thompson and Om Malik. House Republicans led by Jim Jordan subpoenaed Google, accusing the company of colluding with the Biden administration to censor speech. In light of the fiasco and Google's overall response to OpenAI, Business Insider's Hugh Langley and Lara O'Reilly declared that Google was fast going "from vanguard to dinosaur". Bloomberg columnist Parmy Olson suggested that Google's "rushed" rollout of Gemini was the cause of its woes, not "wokeness". Martin Peers, writing for The Information, opined that Google needed a leader like Mark Zuckerberg to defuse the situation. Hugging Face scientist Sasha Luccioni and Surrey University professor Alan Woodward believed that the incident had "deeply embedded" roots in Gemini's training corpus and algorithms, making it difficult to rectify. Jeremy Kahn of Fortune called for researchers focused on safety and responsibility to work together to develop better guardrails. New York magazine contributor John Herrman wrote: "It's a spectacular unforced error, a slapstick rake-in-the-face moment, and a testament to how panicked Google must be by the rise of OpenAI and the threat of AI to its search business."
DeepMind Technologies Limited, trading as Google DeepMind or simply DeepMind, is a British-American artificial intelligence (AI) research laboratory which is a subsidiary of Alphabet Inc. Founded in the UK in 2010, it was acquired by Google in 2014, and merged with Google AI's Google Brain division to become Google DeepMind in April 2023. The company is headquartered in London, with research centres in the United States, Canada, France, Germany, and Switzerland. In 2014, DeepMind introduced neural Turing machines (neural networks that can access external memory like a conventional Turing machine). The company has created many neural network models trained with reinforcement learning to play video games and board games. It made headlines in 2016 after its AlphaGo program beat Lee Sedol, a Go world champion, in a five-game match, which was later featured in the documentary AlphaGo. A more general program, AlphaZero, beat the most powerful programs playing go, chess and shogi (Japanese chess) after a few days of play against itself using reinforcement learning. DeepMind has since trained models for game-playing (MuZero, AlphaStar), for mathematics (AlphaGeometry, FunSearch), and for algorithm discovery (AlphaEvolve, AlphaDev, AlphaTensor). In 2020, DeepMind made significant advances in the problem of protein folding with AlphaFold, which achieved state of the art records on benchmark tests for protein folding prediction. In July 2022, it was announced that over 200 million predicted protein structures, representing virtually all known proteins, would be released on the AlphaFold database. Google DeepMind has become responsible for the development of two large language model families: the proprietary Gemini and open-weight Gemma, as well as other generative AI models, such as Imagen (text-to-image), Veo (text-to-video), and Lyria (text-to-music).
Major venture capital firms Horizons Ventures and Founders Fund invested in the company, as well as entrepreneurs Scott Banister, Peter Thiel, and Elon Musk. Jaan Tallinn was an early investor and an adviser to the company. DeepMind needed a well-funded backer to pay its employees, provide compute resources and further expand. It was courted by Facebook, Musk, Google and some others. On 26 January 2014, Google confirmed its acquisition of DeepMind for a price reportedly ranging between $400 million and $650 million. The company was afterwards renamed Google DeepMind and kept that name for about two years. In 2014, DeepMind received the "Company of the Year" award from Cambridge Computer Laboratory. Looking for opportunities to benefit society, DeepMind started a pilot program with the NHS to modernize its information systems which were often still using plain paper and fax machines. In September 2015, DeepMind and the Royal Free NHS Trust signed their initial information sharing agreement to co-develop a clinical task management app, Streams. After Google's acquisition the company established an artificial intelligence ethics board. The ethics board for AI research was a mystery, with both Google and DeepMind declining to reveal who sat on the board. DeepMind opened a new unit called DeepMind Ethics and Society and focused on the ethical and societal questions raised by artificial intelligence featuring prominent philosopher Nick Bostrom as advisor. In October 2017, DeepMind launched a new research team to investigate AI ethics. In December 2019, co-founder Suleyman announced he would be leaving DeepMind to join the parent company Google, working in a policy role. In April 2023, DeepMind merged with Google AI's Google Brain division to form Google DeepMind, as part of the company's continued efforts to accelerate work on AI in response to OpenAI's release of ChatGPT to the general public. This marked the end of a years-long struggle from DeepMind executives to secure greater autonomy from Google. In the summer of 2026, DeepMind moved into Google's Platform 37 building in King's Cross Central.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
In October 2015, a computer Go program called AlphaGo, developed by DeepMind, beat the European Go champion Fan Hui, a 2 dan (out of 9 dan possible) professional, five to zero. This was the first time an artificial intelligence (AI) defeated a professional Go player. Previously, computers were only known to have played Go at "amateur" level. Go is considered much more difficult for computers to win compared to other games like chess, due to the much larger number of possibilities, making it prohibitively difficult for traditional AI methods such as brute-force. In March 2016 it beat Lee Sedol, a 9-dan professional player, with a score of 4 to 1 in a five-game match. In the 2017 Future of Go Summit, AlphaGo won a three-game match with Ke Jie, who had been the world's highest-ranked player for two years. In 2017, an improved version, AlphaGo Zero, defeated AlphaGo in a hundred out of a hundred games. Later that year, AlphaZero, a modified version of AlphaGo Zero, gained superhuman abilities at chess and shogi. In 2019, DeepMind released a new model named MuZero that mastered the domains of Go, chess, shogi, and Atari 2600 games without human data, domain knowledge, or known rules. AlphaGo technology was developed based on deep reinforcement learning, making it different from the AI technologies then on the market. The data fed into the AlphaGo algorithm consisted of various moves based on historical tournament data. The number of moves was increased gradually until over 30 million of them were processed. The aim was to have the system mimic the human player, as represented by the input data, and eventually become better. It played against itself and learned from the outcomes; thus, it learned to improve itself over the time and increased its winning rate as a result. AlphaGo used two deep neural networks: a policy network to evaluate move probabilities and a value network to assess positions. The policy network trained via supervised learning, and was subsequently refined by policy-gradient reinforcement learning. The value network learned to predict winners of games played by the policy network against itself. After training, these networks employed a lookahead Monte Carlo tree search, using the policy network to identify candidate high-probability moves, while the value network (in conjunction with Monte Carlo rollouts using a fast rollout policy) evaluated tree positions. In contrast, AlphaGo Zero was trained without being fed data of human-played games. Instead it generated its own data, playing millions of games against itself. It used a single neural network, rather than separate policy and value networks. Its simplified tree search relied upon this neural network to evaluate positions and sample moves. A new reinforcement learning algorithm incorporated lookahead search inside the training loop. AlphaGo Zero employed around 15 people and millions in computing resources. Ultimately, it needed much less computing power than AlphaGo, running on four specialized AI processors (Google TPUs), instead of AlphaGo's 48. It also required less training time, being able to beat its predecessor after just three days, compared with months required for the original AlphaGo. Similarly, AlphaZero also learned via self-play. Researchers applied MuZero to solve the real world challenge of video compression with a set number of bits with respect to Internet traffic on sites such as YouTube, Twitch, and Google Meet. The goal of MuZero is to optimally compress the video so the quality of the video is maintained with a reduction in data. The final result using MuZero was a 6.28% average reduction in bitrate.
In 2016, Hassabis discussed the game StarCraft as a future challenge, since it requires strategic thinking and handling imperfect information. In January 2019, DeepMind introduced AlphaStar, a program playing the real-time strategy game StarCraft II. AlphaStar used reinforcement learning based on replays from human players, and then played against itself to enhance its skills. At the time of the presentation, AlphaStar had knowledge equivalent to 200 years of playing time. It won 10 consecutive matches against two professional players, although it had the unfair advantage of being able to see the entire field, unlike a human player who has to move the camera manually. A preliminary version in which that advantage was fixed lost a subsequent match. In July 2019, AlphaStar began playing against random humans on the public 1v1 European multiplayer ladder. Unlike the first iteration of AlphaStar, which played only Protoss v. Protoss, this one played as all of the game's races, and had earlier unfair advantages fixed. By October 2019, AlphaStar had reached Grandmaster level on the StarCraft II ladder on all three StarCraft races, becoming the first AI to reach the top league of a widely popular esport without any game restrictions.
In 2016, DeepMind turned its artificial intelligence to protein folding, a long-standing problem in molecular biology. In December 2018, DeepMind's AlphaFold won the 13th Critical Assessment of Techniques for Protein Structure Prediction (CASP) by successfully predicting the most accurate structure for 25 out of 43 proteins. "This is a lighthouse project, our first major investment in terms of people and resources into a fundamental, very important, real-world scientific problem," Hassabis said to The Guardian. In 2020, in the 14th CASP, AlphaFold's predictions achieved an accuracy score regarded as comparable with lab techniques. Andriy Kryshtafovych, one of the panel of scientific adjudicators, described the achievement as "truly remarkable", and said the problem of predicting how proteins fold had been "largely solved". In July 2021, the open-source RoseTTAFold and AlphaFold2 were released to allow scientists to run their own versions of the tools. A week later DeepMind announced that AlphaFold had completed its prediction of nearly all human proteins as well as the entire proteomes of 20 other widely studied organisms. The structures were released on the AlphaFold Protein Structure Database. In July 2022, it was announced that the predictions of over 200 million proteins, representing virtually all known proteins, would be released on the AlphaFold database. The most recent update, AlphaFold3, was released in May 2024, predicting the interactions of proteins with DNA, RNA, and various other molecules. In a particular benchmark test on the problem of DNA interactions, AlphaFold3's attained an accuracy of 65%, significantly improving the previous state of the art of 28%. In October 2024, Hassabis and John Jumper received half of the 2024 Nobel Prize in Chemistry jointly for protein structure prediction, citing AlphaFold2 achievement.
Gemini is a multimodal large language model which was released on 6 December 2023. It is the successor of Google's LaMDA and PaLM 2 language models and sought to challenge OpenAI's GPT-4. Gemini comes in 3 sizes: Nano, Pro, and Ultra. Gemini is also the name of the chatbot that integrates Google Gemini and which was previously called Google Bard. On 12 December 2024, Google released Gemini 2.0 Flash, the first model in the Gemini 2.0 series. It notably features expanded multimodality, with the ability to also generate images and audio, and is part of Google's broader plans to integrate advanced AI into autonomous agents. On 25 March 2025, Google released Gemini 2.5, a reasoning model that stops to "think" before giving a response. Google announced that all future models will also have reasoning ability. On 30 March 2025, Google released Gemini 2.5 to all free users. On 18 November 2025, Google released Gemini 3 Pro, a reasoning model which is fully multimodal. It was fully integrated with Google Search and AI Mode the same day.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Gemma is a collection of open-weight large language models. The first ones were released on 21 February 2024 and are available in two distinct sizes: a 7 billion parameter model optimized for GPU and TPU usage, and a 2 billion parameter model designed for CPU and on-device applications. Gemma models were trained on up to 6 trillion tokens of text, employing similar architectures, datasets, and training methodologies as the Gemini model set. In June 2024, Google started releasing Gemma 2 models. In December 2024, Google introduced PaliGemma 2, an upgraded vision-language model. In February 2025, they launched PaliGemma 2 Mix, a version fine-tuned for multiple tasks. It is available in 3B, 10B, and 28B parameters with 224px and 448px resolutions. In March 2025, Google released Gemma 3, calling it the most capable model that can be run on a single GPU. It has four available sizes: 1B, 4B, 12B, and 27B. In March 2025, Google introduced TxGemma, an open-source model designed to improve the efficiency of therapeutics development. In April 2025, Google introduced DolphinGemma, a research artificial intelligence model designed to hopefully decode dolphin communication. They want to train a foundation model that can learn the structure of dolphin vocalizations and generate novel dolphin-like sound sequences.
In 2024, Google Deepmind published the results of an experiment where they trained two large language models to help identify and present areas of overlap among a few thousand group members they had recruited online using techniques like sortition to get a representative sample of participants. The project is named in honor of Jürgen Habermas. In one experiment, the participants rated the summaries by the AI higher than the human moderator 56% of the time.
In May 2024, a multimodal video generation model called Veo was announced at Google I/O 2024. Google claimed that it could generate 1080p videos beyond a minute long. In December 2024, Google released Veo 2, available via VideoFX. It supports 4K video generation, and has an improved understanding of physics. In April 2025, Google announced that Veo 2 became available for advanced users on Gemini App. In May 2025, Google released Veo 3, which not only generates videos but also creates synchronized audio — including dialogue, sound effects, and ambient noise — to match the visuals. Google also announced Flow, a video-creation tool powered by Veo and Imagen.
Google DeepMind developed Lyria, a text-to-music model. As of August 2025, it is available on Vertex AI and the Gemini API. On February 18, 2026, DeepMind released Lyria 3. On March 25, 2026, DeepMind released Lyria 3 Pro which allows users to create longer tracks with more structural awareness.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
In March 2024, DeepMind introduced "Genie" (Generative Interactive Environments), an AI model that can generate game-like, action-controllable virtual worlds based on textual descriptions, images, or sketches. Built as an autoregressive latent diffusion model, Genie enables frame-by-frame interactivity without requiring labelled action data for training. Its successor, Genie 2, released in December 2024, expanded these capabilities to generate diverse and interactive 3D environments. Genie 3 was released in August 2025, with higher-resolution world generations and multiple minutes of visual consistency. On January 29, 2026, DeepMind released Project Genie to AI Ultra subscribers.
AlphaGeometry is a neuro-symbolic AI that was able to solve 25 out of 30 geometry problems of the International Mathematical Olympiad, a performance comparable to that of a gold medalist. Traditional geometry programs are symbolic engines that rely exclusively on human-coded rules to generate rigorous proofs, which makes them lack flexibility in unusual situations. AlphaGeometry combines such a symbolic engine with a specialized large language model trained on synthetic data of geometrical proofs. When the symbolic engine doesn't manage to find a formal and rigorous proof on its own, it solicits the large language model, which suggests a geometrical construct to move forward. However, it is unclear how applicable this method is to other domains of mathematics or reasoning, because symbolic engines rely on domain-specific rules and because of the need for synthetic data.
In June 2023, Deepmind announced that AlphaDev, which searches for improved computer science algorithms using reinforcement learning, discovered a more efficient way of coding a sorting algorithm and a hashing algorithm. The new sorting algorithm was 70% faster for shorter sequences and 1.7% faster for sequences exceeding 250,000 elements, and the new hashing algorithm was 30% faster in some cases. The sorting algorithm was accepted into the C++ Standard Library sorting algorithms, and was the first change to those algorithms in more than a decade and the first update to involve an algorithm discovered using AI. The hashing algorithm was released to an opensource library. Google estimates that these two algorithms are used trillions of times every day.
In May 2025, Google DeepMind unveiled AlphaEvolve, an evolutionary coding agent using LLMs like Gemini to design optimized algorithms. AlphaEvolve begins each optimization process with an initial algorithm and metrics to evaluate the quality of a solution. At each step, it uses the LLM to generate variations of the algorithms or combine them, and selects the best candidates for further iterations. AlphaEvolve has made several algorithmic discoveries, including in matrix multiplication. According to Google, when tested on 50 open mathematical problems, AlphaEvolve was able to match the efficiency of state-of-the-art algorithms in 75% of cases, and discovered improved solutions 20% of the time, such as with the kissing number in 11 dimensions. It also developed a new heuristic for data centre scheduling, recovering on average 0.7% of Google's worldwide compute resources.
Model Figures & Evaluation Curves (4 Images)
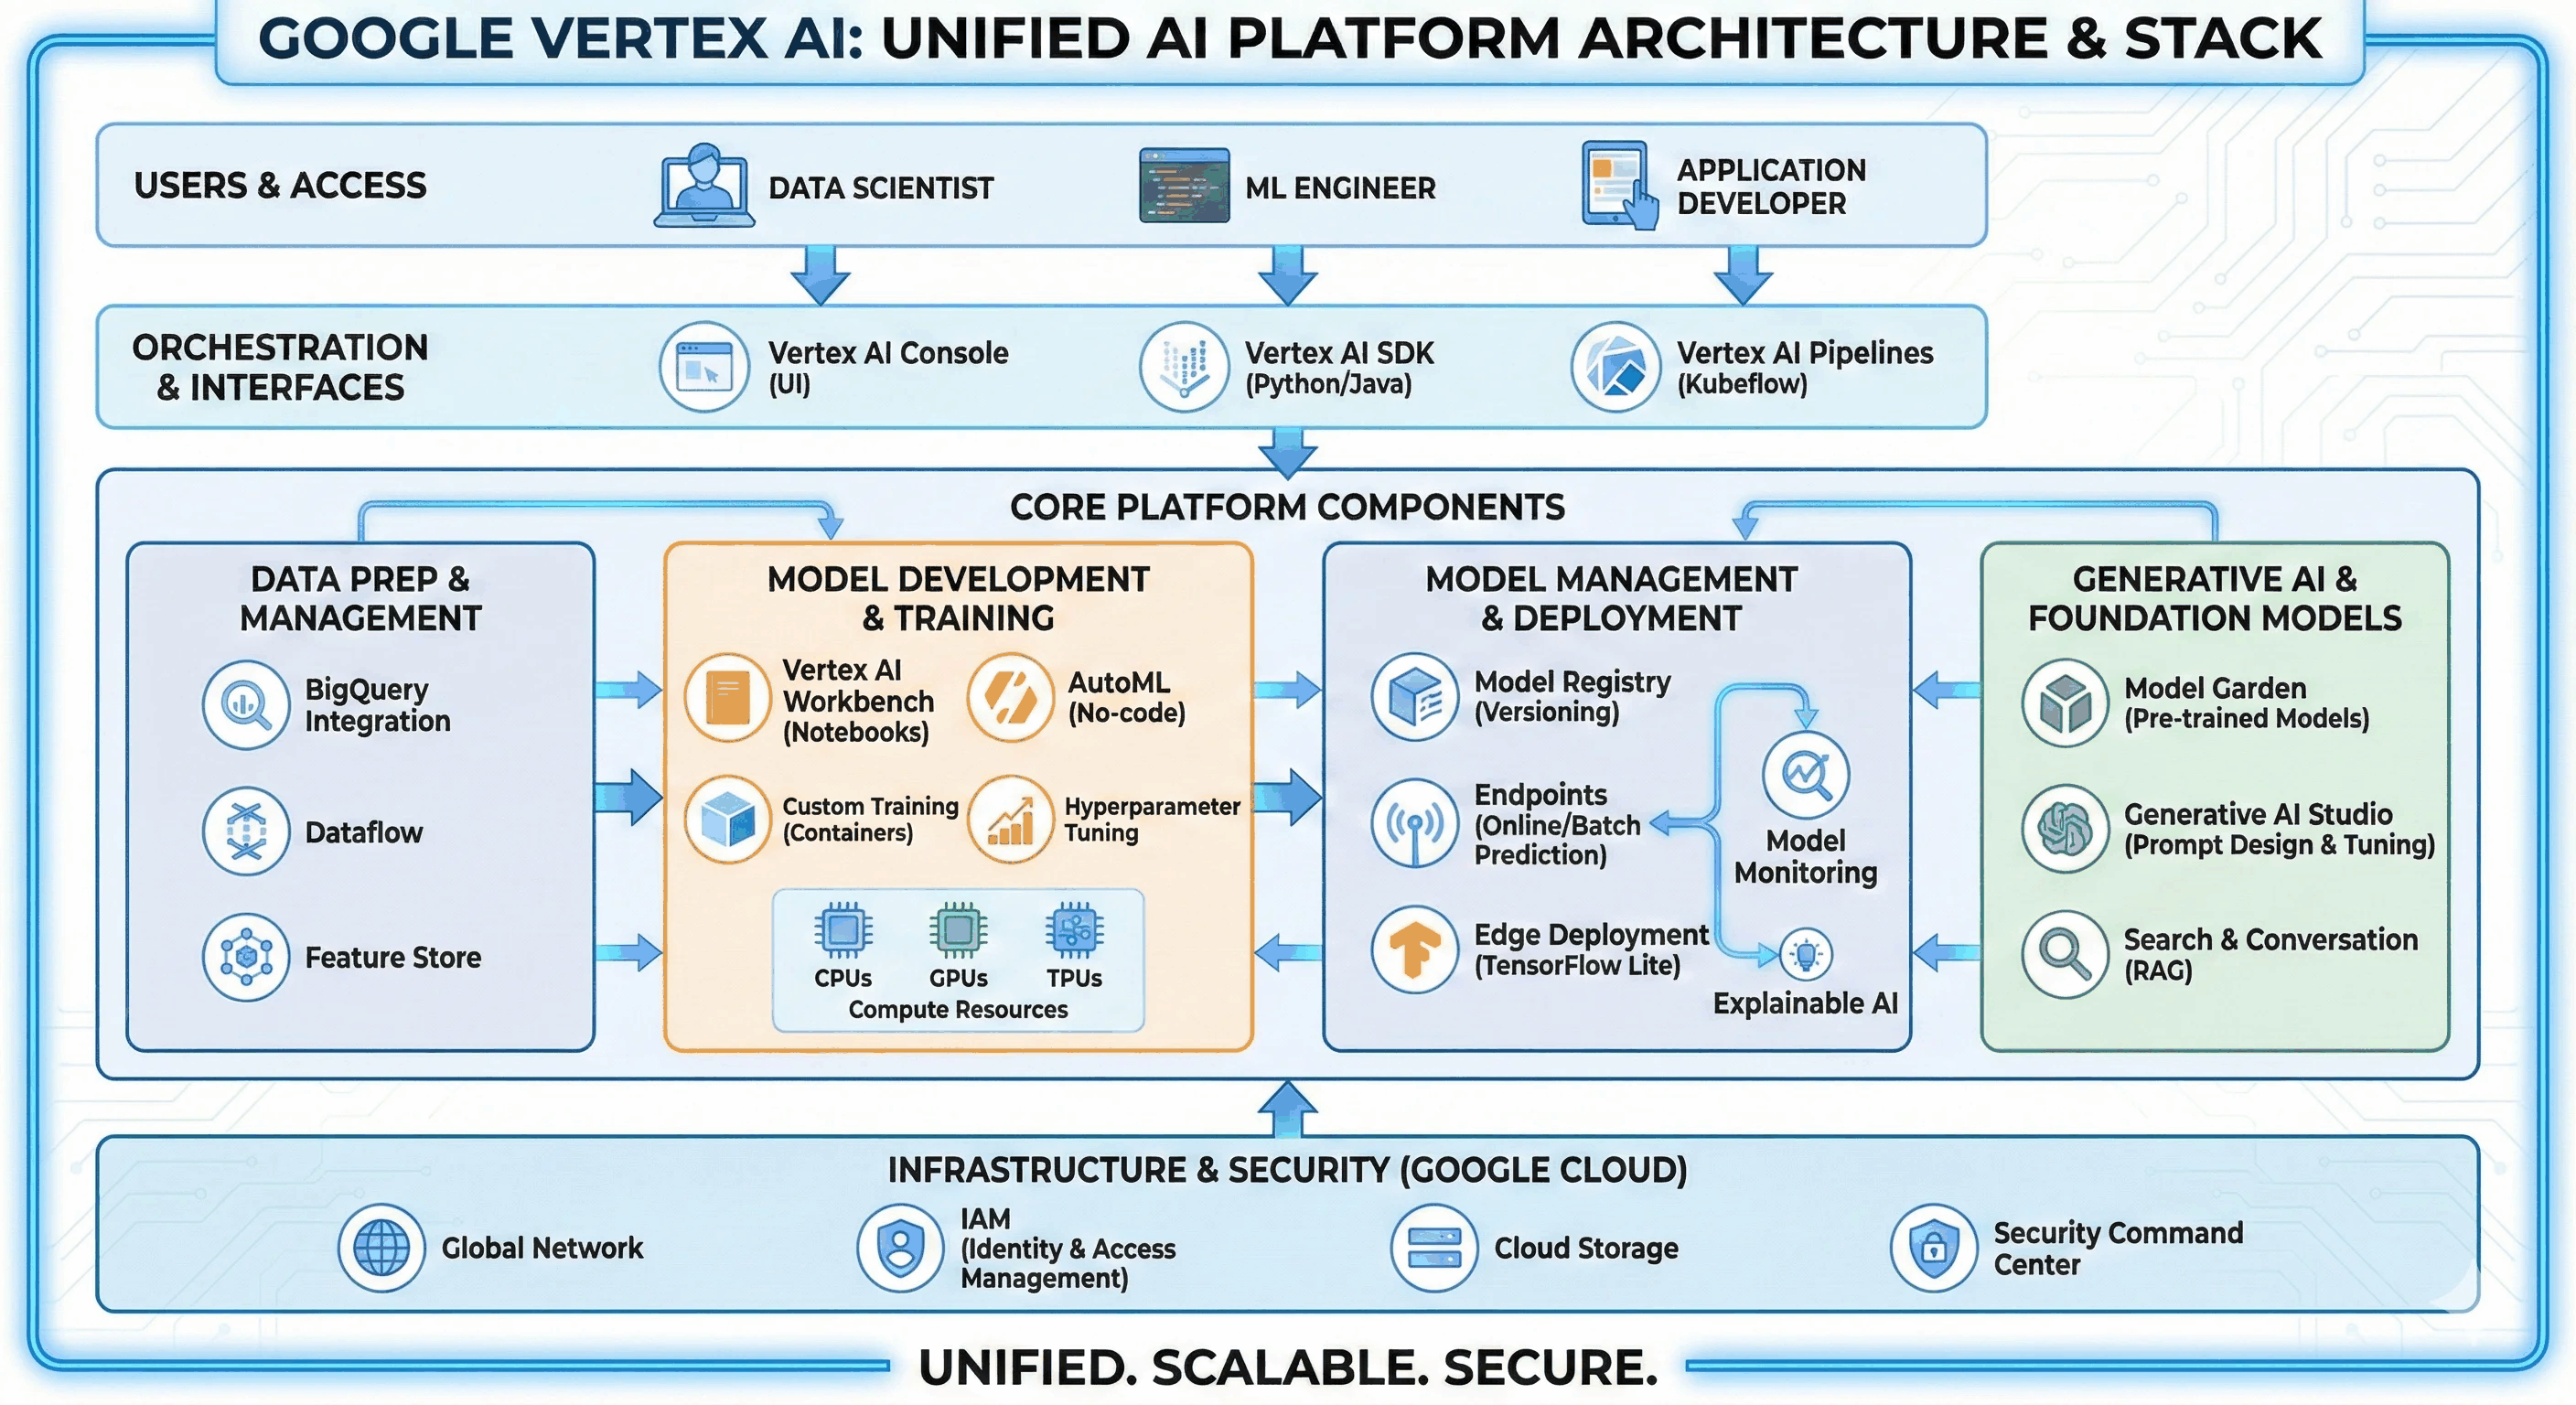
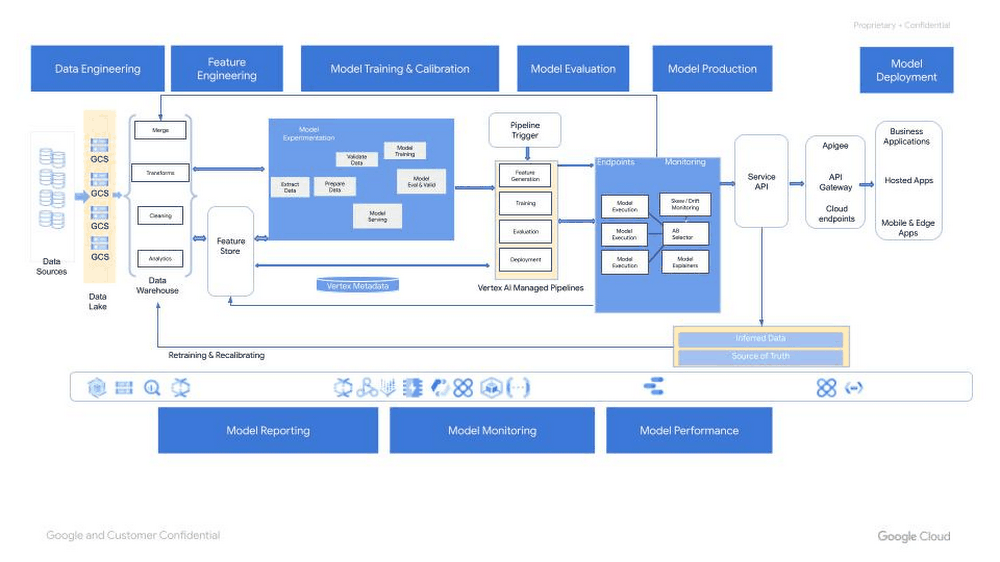
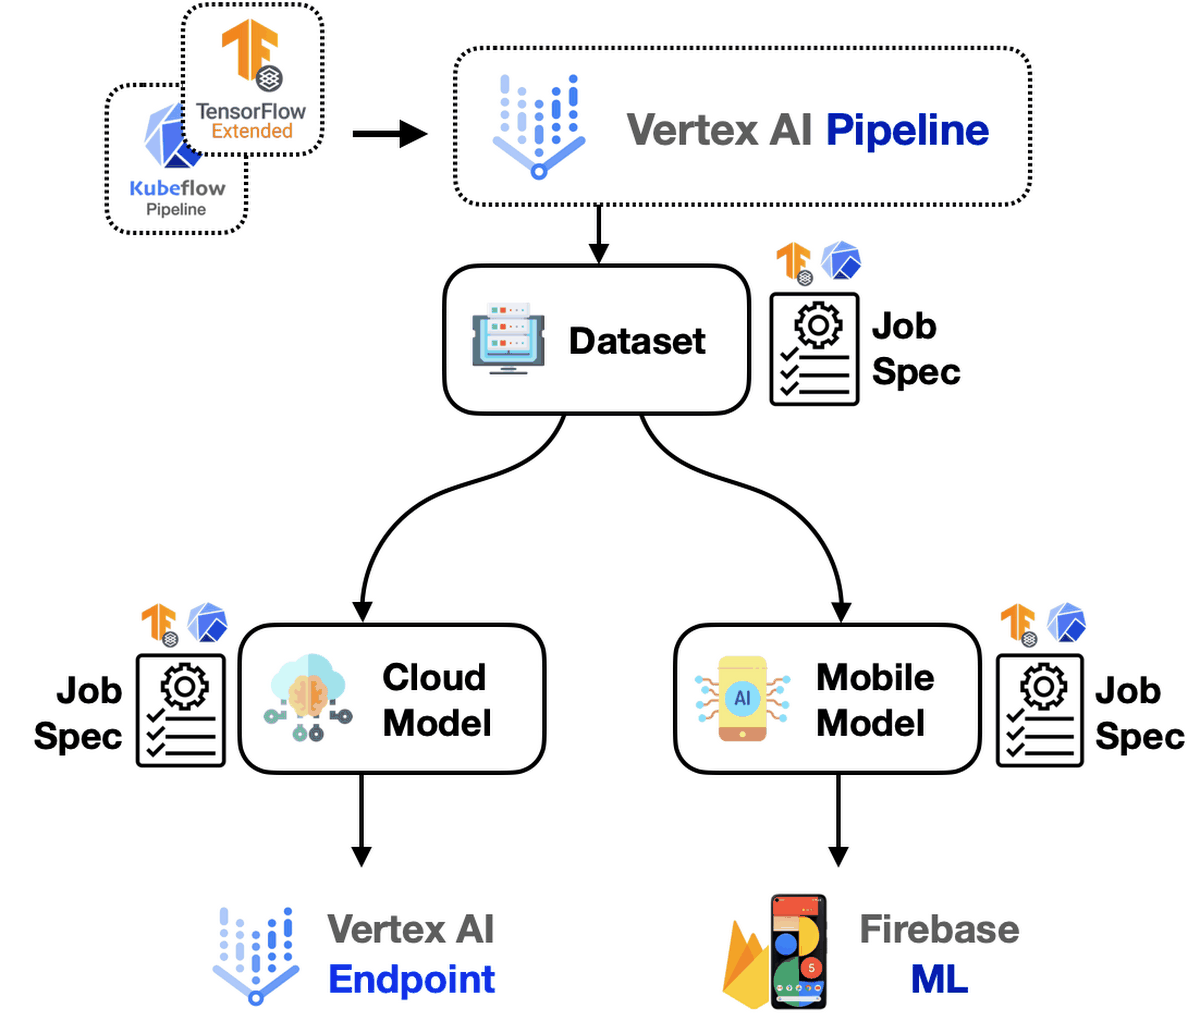
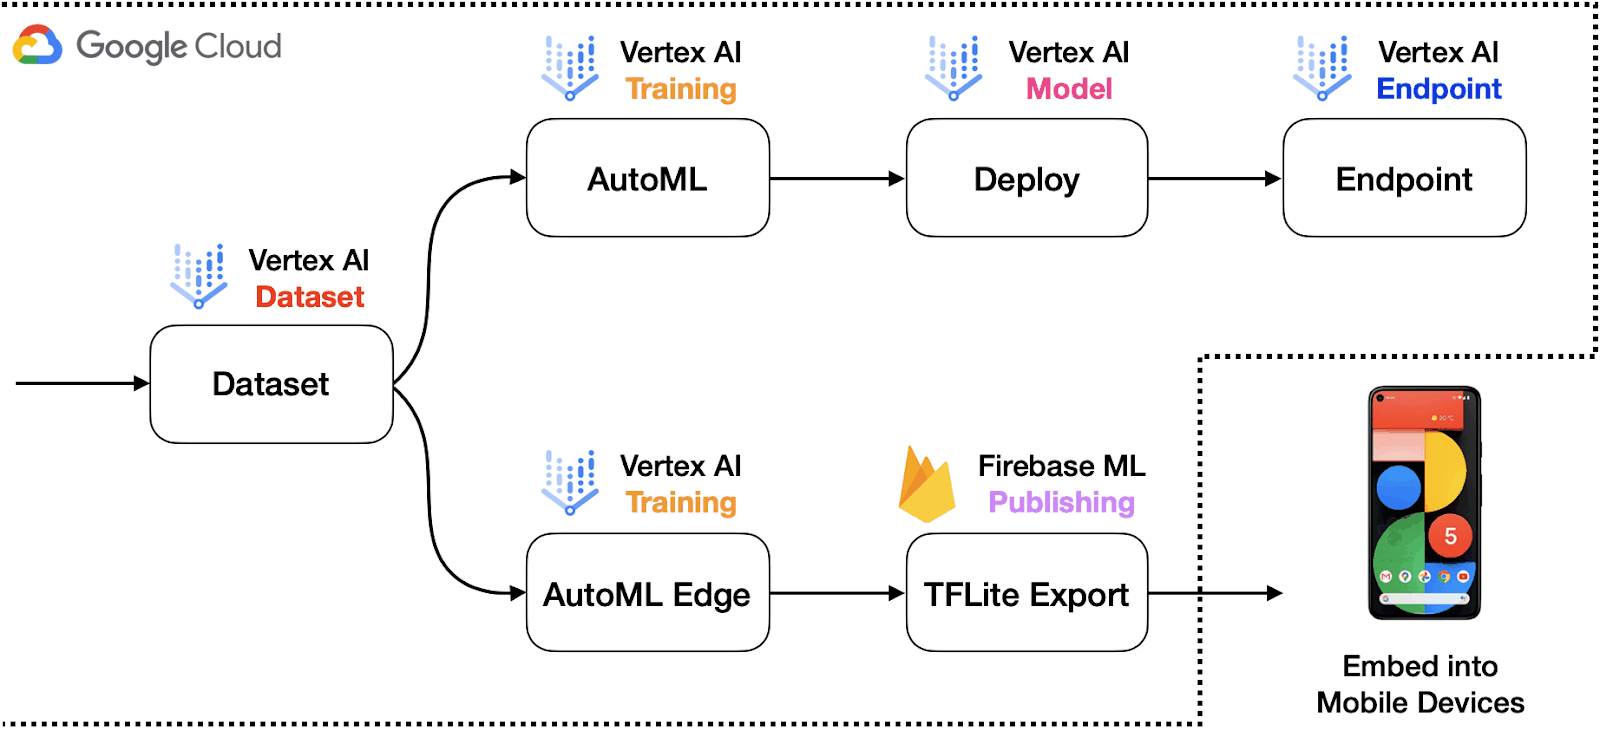
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)