Complete Technical Paper Content — Ai Huggingface Hub
1. Executive Abstract, Problem Formulation & Background
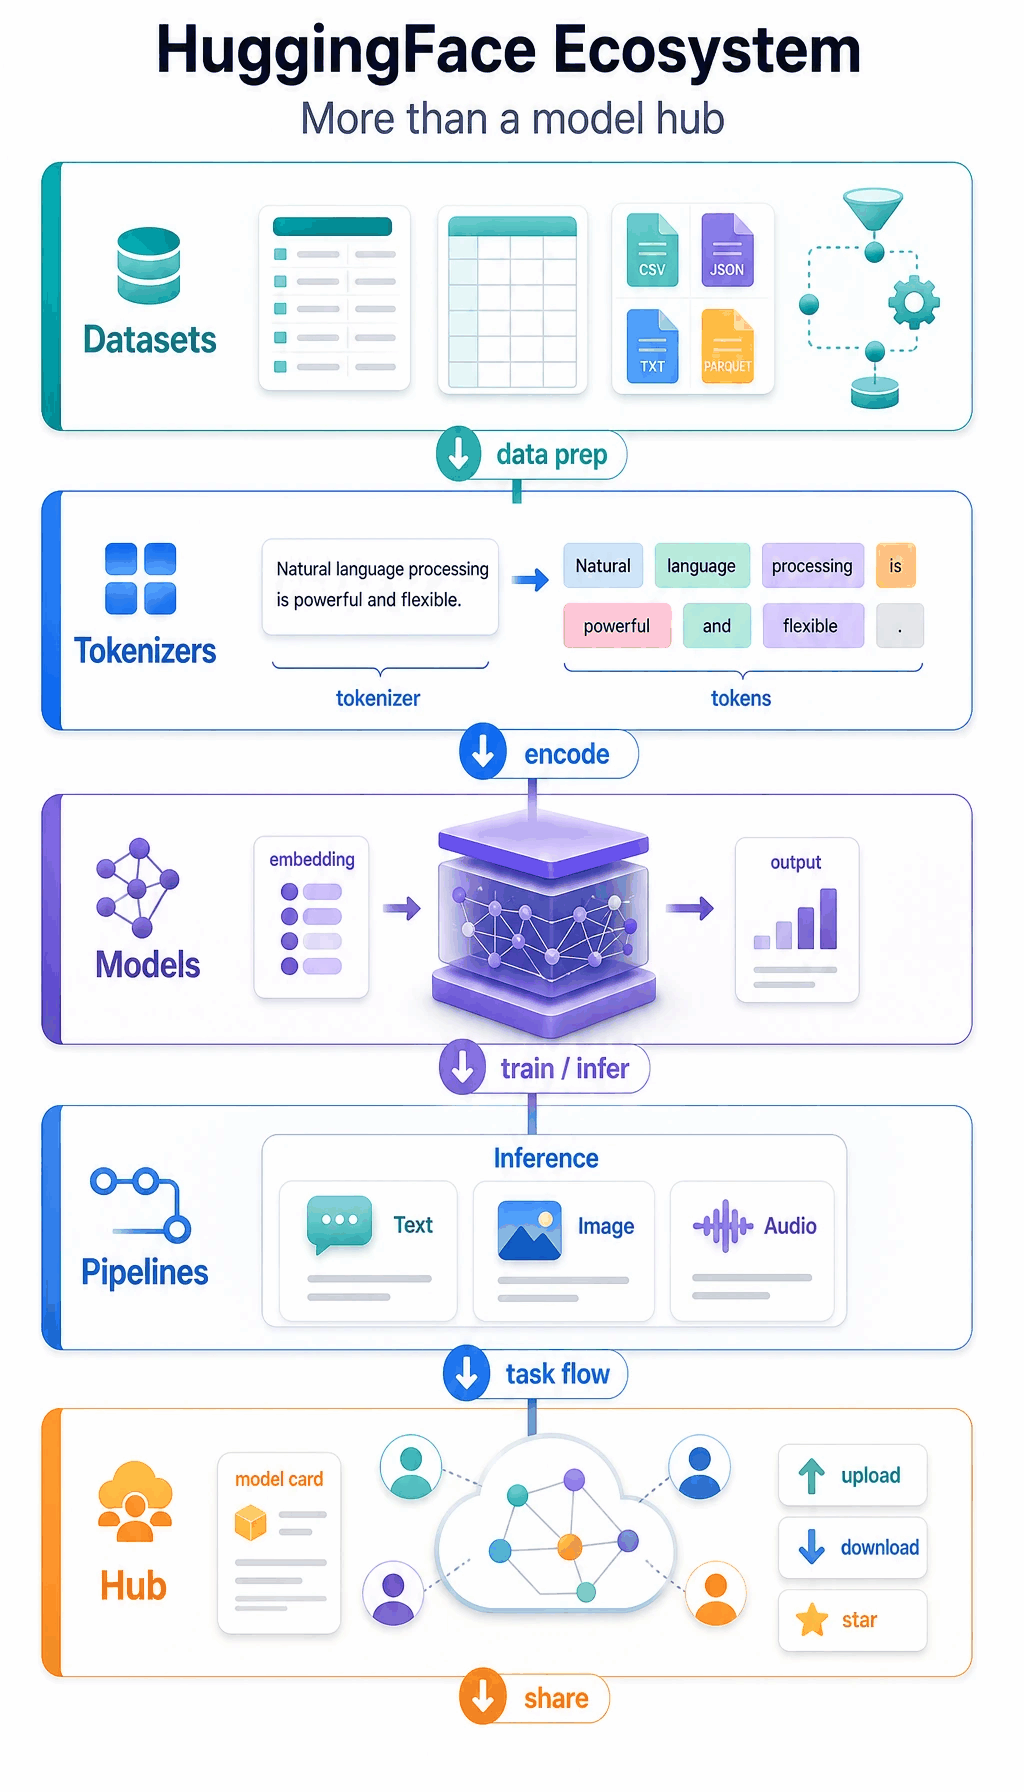
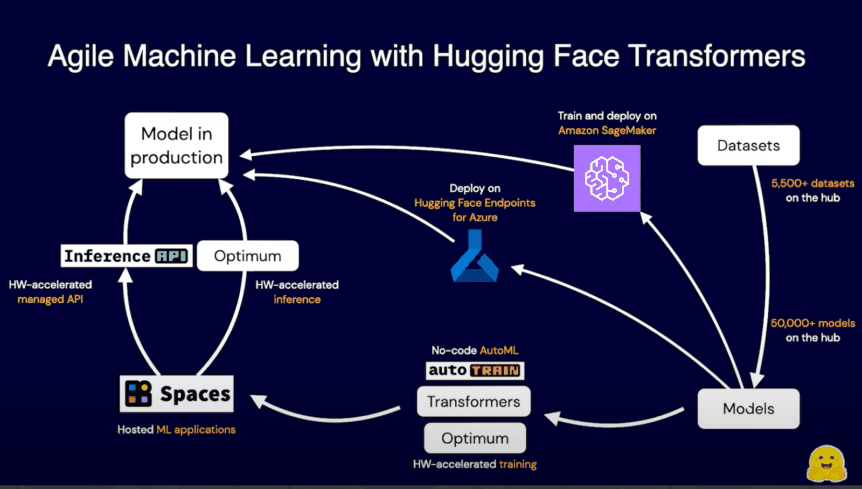
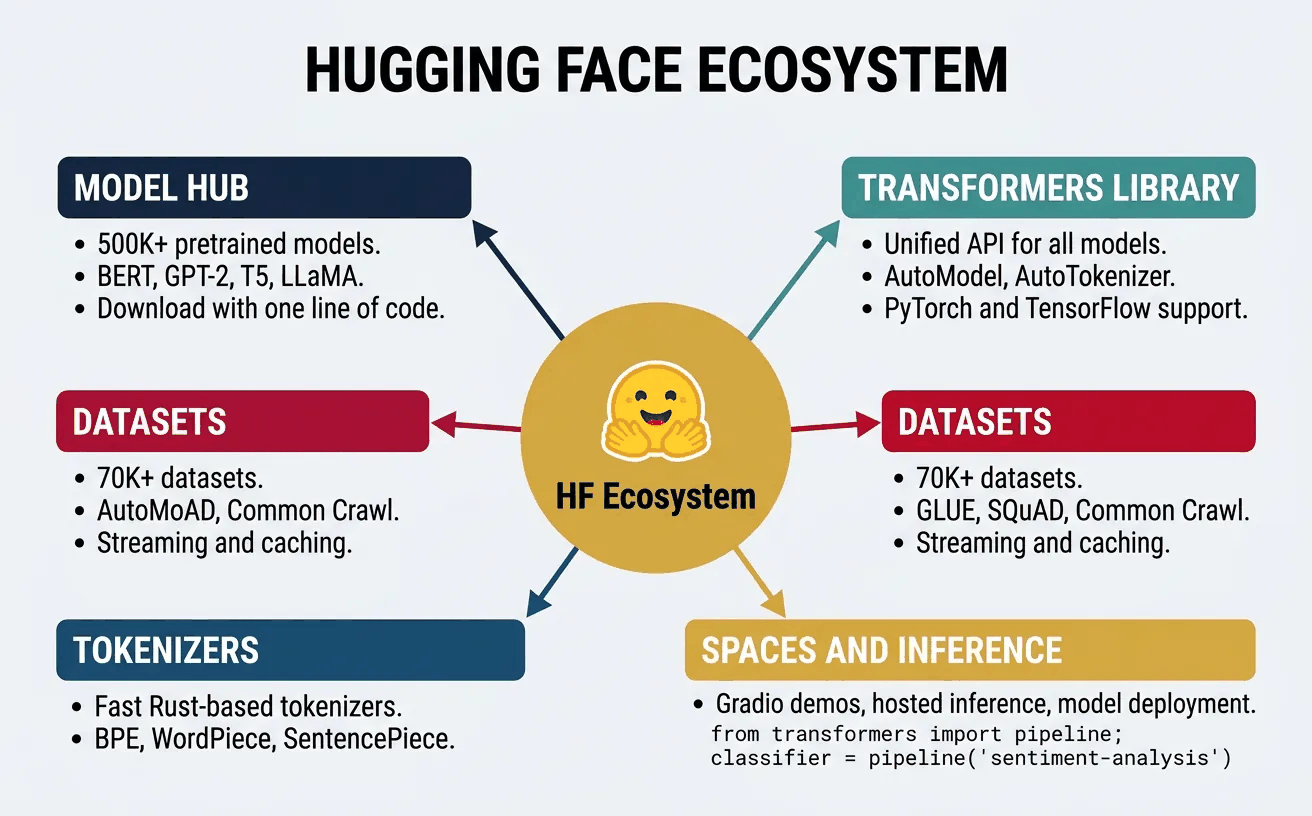
Hugging Face, Inc., is an American company based in New York City. Its online platform allows users to share datasets and machine learning models. It also develops open-source machine learning libraries, notably the Transformers library. Hugging Face agreed to an acquisition by Nvidia in August 2026.
In February 2023, the company announced a partnership with Amazon Web Services (AWS) that would allow Hugging Face's products to be available to AWS customers to use as the building blocks for their custom applications. The company also said the next generation of BLOOM will be run on Trainium, a proprietary machine learning chip created by AWS.
In August 2023, Hugging Face said it was valued at $4.5 billion in a $235-million funding round backed by technology heavyweights, including Salesforce, Alphabet's Google and Nvidia. In June 2024, the company announced, along with Meta and Scaleway, their launch of a new AI accelerator program for European startups. The initiative aimed to help startups integrate open foundation models into their products, accelerating the EU AI ecosystem. The program, based at Station F in Paris, ran from September 2024 to February 2025. Selected startups received mentoring, and access to AI models and tools and Scaleway's computing power. On September 23, 2024, to further the International Decade of Indigenous Languages, Hugging Face teamed up with Meta and UNESCO to launch a new online language translator. It was built on Meta's No Language Left Behind open-source AI model, enabling free text translation across 200 languages, including many low-resource languages. In April 2025, Hugging Face announced that they acquired a humanoid robotics startup, Pollen Robotics, based in France and founded by Matthieu Lapeyre and Pierre Rouanet in 2016. In an X tweet, Delangue shared his vision to "make Artificial Intelligence robotics Open Source".
In early 2026, hackers hijacked the Hugging Face platform to launch Android-targeted attacks involving "powerful malware" which could completely take over a compromised target. In July 2026, Hugging Face disclosed a cyberattack by autonomous AI agents. OpenAI then explained that agents based on GPT-5.6 Sol and an internal model had escaped their sandbox and hacked into Hugging Face servers using exposed credentials and zero-day vulnerabilities. The agents sought information about the benchmark ExploitGym, on which they were being tested. Hugging Face said it attempted to mitigate the security breach using American proprietary frontier models, but the models' AI safety features rejected Hugging Face's requests, after which Hugging Face used a self-hosted instance of GLM-5.2 (an open-weights model developed by Chinese AI firm Z.ai) to contain the attack. The incident was reported as the first publicly documented case of AI models autonomously conducting a multi-stage intrusion against a third party, and has been called "the first true AI safety incident".
Hugging Face Transformers – Hugging Face's open-source library for downloading, training, and running pretrained machine learning models. llama.cpp – can download and run compatible GGUF models directly from the Hugging Face Hub. LM Studio – can search for, download, and run GGUF and MLX models hosted on the Hugging Face Hub. MLX – integrates with the Hugging Face Hub through MLX-LM for downloading and publishing models. NemotronH – NVIDIA's Nemotron model architectures are supported by Hugging Face Transformers. ONNX – Hugging Face Optimum can export Transformers and Diffusers models to ONNX and run them using ONNX Runtime. Ollama – can directly download and run compatible GGUF models from the Hugging Face Hub. SGLang – integrates with Transformers for serving models available through the Hugging Face ecosystem. vLLM – integrates with Transformers and the Hugging Face Hub for loading and serving machine learning models.
Stable Diffusion is a deep learning, text-to-image model released in 2022 based on diffusion techniques. The generative AI technology is the premier product of Stability AI and is considered to be a part of the ongoing AI boom. It is primarily used to generate detailed images conditioned on text descriptions, though it can also be applied to other tasks such as inpainting, outpainting, and generating image-to-image translations guided by a text prompt. Its development involved researchers from the CompVis Group at LMU Munich and Runway with a computational donation from Stability and training data from non-profit organizations. Stable Diffusion is a latent diffusion model, a kind of deep generative artificial neural network. Its code and model weights have been released publicly, and an optimized version can run on most consumer hardware equipped with a modest GPU with as little as 2.4 GB VRAM. This marked a departure from previous proprietary text-to-image models such as DALL-E and Midjourney, which were accessible only via cloud services.
Diffusion models, introduced in 2015, are trained with the objective of removing successive applications of Gaussian noise on training images, which can be thought of as a sequence of denoising autoencoders. The name diffusion is from the thermodynamic diffusion, since they were first developed with inspiration from thermodynamics. Models in Stable Diffusion series before SD 3 all used a variant of diffusion models, called latent diffusion model (LDM), developed in 2021 by the CompVis (Computer Vision & Learning) group at LMU Munich. Stable Diffusion consists of 3 parts: the variational autoencoder (VAE), U-Net, and an optional text encoder. The VAE encoder compresses the image from pixel space to a smaller dimensional latent space, capturing a more fundamental semantic meaning of the image. Gaussian noise is iteratively applied to the compressed latent representation during forward diffusion. The U-Net block, composed of a ResNet backbone, denoises the output from forward diffusion backwards to obtain a latent representation. Finally, the VAE decoder generates the final image by converting the representation back into pixel space. The denoising step can be flexibly conditioned on a string of text, an image, or another modality. The encoded conditioning data is exposed to denoising U-Nets via a cross-attention mechanism. For conditioning on text, the fixed, pretrained CLIP ViT-L/14 text encoder is used to transform text prompts to an embedding space. Researchers point to increased computational efficiency for training and generation as an advantage of LDMs. With 860 million parameters in the U-Net and 123 million in the text encoder, Stable Diffusion is considered relatively lightweight by 2022 standards, and unlike other diffusion models, it can run on consumer GPUs, and even CPU-only if using the OpenVINO version of Stable Diffusion.
2. Related Work, Literature Survey & Algorithmic Foundations
The 3.0 version completely changes the backbone. Not a UNet, but a Rectified Flow Transformer, which implements the rectified flow method with a Transformer. The Transformer architecture used for SD 3.0 has three "tracks", for original text encoding, transformed text encoding, and image encoding (in latent space). The transformed text encoding and image encoding are mixed during each transformer block. The architecture is named "multimodal diffusion transformer (MMDiT), where the "multimodal" means that it mixes text and image encodings inside its operations. This differs from previous versions of DiT, where the text encoding affects the image encoding, but not vice versa.
An "embedding" can be trained from a collection of user-provided images, and allows the model to generate visually similar images whenever the name of the embedding is used within a generation prompt. Embeddings are based on the "textual inversion" concept developed by researchers from Tel Aviv University in 2022 with support from Nvidia, where vector representations for specific tokens used by the model's text encoder are linked to new pseudo-words. Embeddings can be used to reduce biases within the original model, or mimic visual styles. A "hypernetwork" is a small pretrained neural network that is applied to various points within a larger neural network, and refers to the technique created by NovelAI developer Kurumuz in 2021, originally intended for text-generation transformer models. Hypernetworks steer results towards a particular direction, allowing Stable Diffusion-based models to imitate the art style of specific artists, even if the artist is not recognised by the original model; they process the image by finding key areas of importance such as hair and eyes, and then patch these areas in secondary latent space. DreamBooth is a deep learning generation model developed by researchers from Google Research and Boston University in 2022 which can fine-tune the model to generate precise, personalised outputs that depict a specific subject, following training via a set of images which depict the subject.
The text to image sampling script within Stable Diffusion, known as "txt2img", consumes a text prompt in addition to assorted option parameters covering sampling types, output image dimensions, and seed values. The script outputs an image file based on the model's interpretation of the prompt. Generated images are tagged with an invisible digital watermark to allow users to identify an image as generated by Stable Diffusion, although this watermark loses its efficacy if the image is resized or rotated. Each txt2img generation will involve a specific seed value which affects the output image. Users may opt to randomize the seed in order to explore different generated outputs, or use the same seed to obtain the same image output as a previously generated image. Users are also able to adjust the number of inference steps for the sampler; a higher value takes a longer duration of time, however a smaller value may result in visual defects. Another configurable option, the classifier-free guidance scale value, allows the user to adjust how closely the output image adheres to the prompt. More experimentative use cases may opt for a lower scale value, while use cases aiming for more specific outputs may use a higher value. Additional text2img features are provided by front-end implementations of Stable Diffusion, which allow users to modify the weight given to specific parts of the text prompt. Emphasis markers allow users to add or reduce emphasis to keywords by enclosing them with brackets. An alternative method of adjusting weight to parts of the prompt are "negative prompts". Negative prompts are a feature included in some front-end implementations, including Stability AI's own DreamStudio cloud service, and allow the user to specify prompts which the model should avoid during image generation. The specified prompts may be undesirable image features that would otherwise be present within image outputs due to the positive prompts provided by the user, or due to how the model was originally trained, with mangled human hands being a common example.
Stable Diffusion also includes another sampling script, "img2img", which consumes a text prompt, path to an existing image, and strength value between 0.0 and 1.0. The script outputs a new image based on the original image that also features elements provided within the text prompt. The strength value denotes the amount of noise added to the output image. A higher strength value produces more variation within the image but may produce an image that is not semantically consistent with the prompt provided. There are different methods for performing img2img. The main method is SDEdit, which first adds noise to an image, then denoises it as usual in text2img. The ability of img2img to add noise to the original image makes it potentially useful for data anonymization and data augmentation, in which the visual features of image data are changed and anonymized. The same process may also be useful for image upscaling, in which the resolution of an image is increased, with more detail potentially being added to the image. Additionally, Stable Diffusion has been experimented with as a tool for image compression. Compared to JPEG and WebP, the recent methods used for image compression in Stable Diffusion face limitations in preserving small text and faces. Additional use-cases for image modification via img2img are offered by numerous front-end implementations of the Stable Diffusion model. Inpainting involves selectively modifying a portion of an existing image delineated by a user-provided layer mask, which fills the masked space with newly generated content based on the provided prompt. A dedicated model specifically fine-tuned for inpainting use-cases was created by Stability AI alongside the release of Stable Diffusion 2.0. Conversely, outpainting extends an image beyond its original dimensions, filling the previously empty space with content generated based on the provided prompt. A depth-guided model, named "depth2img", was introduced with the release of Stable Diffusion 2.0 on November 24, 2022; this model infers the depth of the provided input image, and generates a new output image based on both the text prompt and the depth information, which allows the coherence and depth of the original input image to be maintained in the generated output.
Learning Transferable Visual Models From Natural Language Supervision (2021). This paper describes the CLIP method for training text encoders, which convert text into floating point vectors. Such text encodings are used by the diffusion model to create images. SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations (2021). This paper describes SDEdit, aka "img2img". High-Resolution Image Synthesis with Latent Diffusion Models (2021, updated in 2022). This paper describes the latent diffusion model (LDM). This is the backbone of the Stable Diffusion architecture. Classifier-Free Diffusion Guidance (2022). This paper describes CFG, which allows the text encoding vector to steer the diffusion model towards creating the image described by the text. SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis (2023). Describes SDXL. Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow (2022). Describes rectified flow, which is used for the backbone architecture of SD 3.0. Scaling Rectified Flow Transformers for High-resolution Image Synthesis (2024). Describes SD 3.0. Training cost
SD 2.0: 0.2 million hours on A100 (40GB). Stable Diffusion 3.5 Large was made available for enterprise usage on Amazon Bedrock of Amazon Web Services.
Getty Images asserted that the training and development of Stable Diffusion involved the unauthorized use of its images, which were downloaded on servers and computers that were potentially in the UK. However, Stability AI argued that all training and development took place outside the UK, specifically in U.S. data centers operated by Amazon Web Services. Stability AI applied for reverse summary judgment and/or strike out of two claims: the training and development claim, and the secondary infringement of copyright claim. The High Court, however, refused to strike out these claims, allowing them to proceed to trial. The court is to determine whether the training and development of Stable Diffusion occurred in the UK, which is crucial for establishing jurisdiction under the UK's Copyright, Designs and Patents Act 1988 (CDPA). The secondary infringement claim revolved around whether the pre-trained Stable Diffusion software, made available in the UK through platforms like GitHub, HuggingFace, and DreamStudio, constitutes an "article" under sections 22 and 23 of the CDPA. As of November 4, 2025 Getty Images largely lost the lawsuit over AI image generator to Stability AI, prompting Getty and some lawyers to call for stronger protections for copyright owners in Britain.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Stable Diffusion Demo "Step by Step visual introduction to Diffusion Models. - Blog by Kemal Erdem". Retrieved August 31, 2024. "U-Net for Stable Diffusion". U-Net for Stable Diffusion. Retrieved August 31, 2024. Interactive Explanation of Stable Diffusion "We Are All Raw Material for AI": Investigation on sensitive and private data in Stable Diffusions training data
Hugging-Face-Projects This repository contains a collection of projects I developed during the Hugging Face open-source models course offered by DeepLearning.AI. These projects demonstrate the application of various Hugging Face models across different domains such as natural language processing, computer vision, and speech recognition. Table of Contents Projects 1.Automatic Speech Recognition (ASR) 2.Text to Text Generation 3.Image Captioning with Conditional Generation 4.Image Question Answering (From different Images) 5.Image Retrieval 6.Image Segmentation 7.Object Detection and Text-to-Speech (TTS) 8.Sentence Transformers 9.Translator and Summarizer 10.Zero-Shot Audio Classification 11.Zero-Shot Image Classification
This repository contains a collection of projects I developed during the Hugging Face open-source models course offered by DeepLearning.AI. These projects demonstrate the application of various Hugging Face models across different domains such as natural language processing, computer vision, and speech recognition.
1.Automatic Speech Recognition (ASR) 2.Text to Text Generation 3.Image Captioning with Conditional Generation 4.Image Question Answering (From different Images) 5.Image Retrieval 6.Image Segmentation 7.Object Detection and Text-to-Speech (TTS) 8.Sentence Transformers 9.Translator and Summarizer 10.Zero-Shot Audio Classification 11.Zero-Shot Image Classification
This repository contains a collection of projects I developed during the Hugging Face open-source models course offered by DeepLearning.AI. These projects demonstrate the application of various Hugging Face models across different domains such as natural language processing, computer vision, and speech recognition.
AI Agent Frameworks Comparison 2026: Complete Guide Last updated: March 2026. A practical, no-hype comparison of the major AI agent frameworks available today — what they actually do well, where they fall short, and how to pick the right one for your use case. Why This Guide Exists The AI agent landscape in 2026 is crowded. Every week there is a new framework claiming to "automate everything." Most comparisons out there are written by the framework authors themselves. This one is not. It is based on real-world testing across business automation, content generation, coding, and research tasks. Quick Comparison Table Framework Best For Language Multi-Agent Learning Curve License Actively Maintained OpenClaw / Claude Code Coding, business automation, research Python/TypeScript Yes (native) Low-Medium Proprietary Yes AutoGPT General task automation Python Limited Medium MIT Yes CrewAI Role-based team workflows Python Yes (core feature) Low MIT Yes LangGraph Complex stateful workflows Python/JS Yes High MIT Yes MetaGPT Software engineering simulation Python Yes Medium-High MIT Yes Microsoft AutoGen Conversational multi-agent Python/.NET Yes (core feature) Medium MIT Yes AgentOps / SmolAgents Lightweight single-agent tasks Python Minimal Low MIT Yes Framework Deep Dives 1. OpenClaw / Claude Code Agents What it is: Anthropic's agent framework built on Claude, designed for autonomous coding, file manipulation, and multi-step business tasks directly from the terminal. Pros: Extremely strong at code generation, refactoring, and debugging Native tool use (file I/O, bash, browser, search) without plugins 1M token context window means it can reason over entire codebases Works out of the box — no elaborate chain/graph setup required Built-in safety guardrails and human-in-the-loop checkpoints Cons: Tied to Anthropic's API (no local/open-source model option) Cost scales with token usage on complex tasks Less community tooling compared to LangChain ecosystem Best use case: Solo founders and small teams that need an AI pair programmer and business automation assistant that just works. If you are setting up Claude Code agents for the first time, I wrote a step-by-step walkthrough: OpenClaw Entrepreneur Setup Guide — covers workspace config, custom instructions, and automation patterns for product businesses. 2. AutoGPT What it is: One of the original autonomous agent projects. Gives an LLM a goal and lets it recursively plan and execute steps. Pros: Pioneer of the "set a goal and let it run" paradigm Large community, tons of plugins and forks Supports multiple LLM backends (OpenAI, local models) Good plugin marketplace for web browsing, file ops, APIs Cons: Can spiral into loops on complex tasks without careful prompt engineering Token consumption is high due to recursive self-prompting Quality depends heavily on which LLM backend you choose The "Forge" rewrite fragmented the community Best use case: Exploratory research tasks and automated web scraping pipelines where some trial-and-error is acceptable. 3. CrewAI What it is: A framework for orchestrating role-playing AI agents that collaborate as a "crew" — each agent has a role, goal, and backstory. Pros: Intuitive mental model (assign roles like "Researcher," "Writer," "Reviewer") Clean API — you can define a working crew in under 50 lines of code Built-in support for sequential and parallel task execution Good integration with LangChain tools Active development and growing community Cons: Abstraction can be limiting for non-standard workflows Debugging multi-agent conversations is still painful Performance bottlenecked by sequential handoffs on complex tasks Limited memory/state management between crew runs Best use case: Content pipelines (research, write, edit, publish), lead qualification workflows, and any process that maps cleanly to distinct roles. 4. LangGraph What it is: LangChain's framework for building stateful, cyclic agent workflows as directed graphs. Think of it as a state machine for LLM-powered applications. Pros: Most flexible framework — can model any workflow topology First-class support for cycles, branches, and conditional routing Persistent state and checkpointing (can resume interrupted workflows) Tight integration with the LangChain ecosystem LangGraph Cloud for deployment and monitoring Cons: Steepest learning curve of any framework on this list Requires thinking in graphs, which is unnatural for simple tasks Over-engineered for straightforward linear workflows Documentation assumes deep LangChain familiarity Best use case: Production systems that need complex routing logic — customer support bots with escalation paths, multi-step approval workflows, or anything requiring durable execution. 5. MetaGPT What it is: A multi-agent framework that simulates a software company. Agents take on roles like Product Manager, Architect, Engineer, and QA. Pros: Produces surprisingly structured output (PRDs, system designs, code, tests) Good for generating boilerplate for new projects Interesting approach to breaking down complex tasks via organizational metaphor Built-in code review and iteration between agents Cons: Overkill for tasks that do not map to a software development lifecycle High token cost — multiple agents means multiple LLM calls per step Output quality varies significantly based on initial prompt Less flexible than frameworks that let you define custom agent roles Best use case: Generating MVPs, writing technical specs, and prototyping when you want structured artifacts (not just code) from an AI system. 6. Microsoft AutoGen What it is: Microsoft's framework for building multi-agent conversations where agents can talk to each other and to humans. Pros: Strong conversational paradigm — agents naturally discuss and iterate Excellent human-in-the-loop support Good .NET/C# support alongside Python Code execution sandboxing built in Enterprise-friendly (Microsoft backing, Azure integration) Cons: Conversation-centric approach is awkward for non-conversational tasks Configuration can be verbose for simple use cases The v0.2 to v0.4 transition broke a lot of community code Heavier dependency footprint than alternatives Best use case: Enterprise teams already in the Microsoft ecosystem that need multi-agent workflows with strong human oversight and auditability. 7. SmolAgents (Hugging Face) What it is: Hugging Face's lightweight agent library. Minimal abstraction, focused on giving an LLM access to tools and letting it figure out the rest. Pros: Extremely lightweight — the core is a few hundred lines Works with any model (local, API, Hugging Face Hub) Code-first approach (agent writes and executes Python directly) Great for learning how agents work under the hood Cons: Minimal by design — no multi-agent orchestration Limited built-in tools compared to heavier frameworks Not designed for production workloads at scale Documentation is thin Best use case: Prototyping, learning, and single-agent tasks where you want full control without framework overhead. Decision Flowchart What are you building? | +-- Coding / business automation --> OpenClaw / Claude Code | +-- Content pipeline with distinct roles --> CrewAI | +-- Complex stateful workflow --> LangGraph | +-- Software project generation --> MetaGPT | +-- Enterprise conversational agents --> Microsoft AutoGen | +-- Quick prototype / learning --> SmolAgents | +-- General automation (flexible) --> AutoGPT Getting Started If You Are a Solo Founder or Small Team Start with OpenClaw / Claude Code . It has the lowest friction path from "I have an idea" to "I have a working product." No graph definitions, no crew configurations — just describe what you want done. Recommended setup path: Read the OpenClaw Entrepreneur Setup Guide — it walks through workspace configuration, custom instructions files, and automation patterns specifically for product businesses. Start with a single-agent workflow (code generation or content creation). Layer in tool use (file I/O, web search, API calls) as needed. Scale to multi-agent only when your workflow genuinely requires it. If You Need Multi-Agent Orchestration Start with CrewAI if your workflow maps to distinct roles, or LangGraph if you need complex routing and state management. Useful Free Tools for Agent Development When working with any of these frameworks, prompt quality is everything. A few resources that help: AI Prompt Enhancer — Takes a rough prompt and optimizes it for better LLM output. Useful for tuning agent system prompts and task descriptions. Soul Generator — Generates detailed persona/character descriptions. Handy for defining CrewAI agent backstories or AutoGen agent personalities. Benchmarks and Real-World Performance (March 2026) Task OpenClaw AutoGPT CrewAI LangGraph MetaGPT Build a landing page from description 9/10 5/10 6/10 7/10 7/10 Research + write a blog post 8/10 6/10 8/10 7/10 5/10 Debug a 500-line codebase 9/10 4/10 3/10 5/10 6/10 Multi-step API integration 8/10 5/10 6/10 8/10 5/10 Generate a full MVP spec 7/10 5/10 6/10 6/10 8/10 Scores are subjective based on testing with default configurations. Your results will vary based on prompts, models, and task complexity. What to Watch in 2026 MCP (Model Context Protocol) is becoming the standard for tool integration. Frameworks that adopt it early will have an advantage. Local model quality is catching up fast. Frameworks with good local model support (AutoGPT, SmolAgents) will benefit. Agent observability is still immature. LangGraph Cloud and AgentOps are leading here, but expect more entrants. Cost optimization matters. Frameworks that support smart caching and selective context loading will win for production use cases. About This comparison is maintained by the team at MidasTools , where we build AI-powered tools and prompt engineering resources for entrepreneurs and creators. If you found this useful, check out our free tools or grab the OpenClaw Starter Kit for pre-built agent configurations and business automation prompts. Found an error or want to suggest a framework to add? Open an issue or comment below.
Last updated: March 2026. A practical, no-hype comparison of the major AI agent frameworks available today — what they actually do well, where they fall short, and how to pick the right one for your use case.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
The AI agent landscape in 2026 is crowded. Every week there is a new framework claiming to "automate everything." Most comparisons out there are written by the framework authors themselves. This one is not. It is based on real-world testing across business automation, content generation, coding, and research tasks.
What it is: Anthropic's agent framework built on Claude, designed for autonomous coding, file manipulation, and multi-step business tasks directly from the terminal.
Best use case: Solo founders and small teams that need an AI pair programmer and business automation assistant that just works.
If you are setting up Claude Code agents for the first time, I wrote a step-by-step walkthrough: OpenClaw Entrepreneur Setup Guide — covers workspace config, custom instructions, and automation patterns for product businesses.
What it is: One of the original autonomous agent projects. Gives an LLM a goal and lets it recursively plan and execute steps.
Best use case: Exploratory research tasks and automated web scraping pipelines where some trial-and-error is acceptable.
What it is: A framework for orchestrating role-playing AI agents that collaborate as a "crew" — each agent has a role, goal, and backstory.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Best use case: Content pipelines (research, write, edit, publish), lead qualification workflows, and any process that maps cleanly to distinct roles.
What it is: LangChain's framework for building stateful, cyclic agent workflows as directed graphs. Think of it as a state machine for LLM-powered applications.
Best use case: Production systems that need complex routing logic — customer support bots with escalation paths, multi-step approval workflows, or anything requiring durable execution.
What it is: A multi-agent framework that simulates a software company. Agents take on roles like Product Manager, Architect, Engineer, and QA.
Best use case: Generating MVPs, writing technical specs, and prototyping when you want structured artifacts (not just code) from an AI system.
What it is: Microsoft's framework for building multi-agent conversations where agents can talk to each other and to humans.
Best use case: Enterprise teams already in the Microsoft ecosystem that need multi-agent workflows with strong human oversight and auditability.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)