Complete Technical Paper Content — Ai Identity Verification
1. Executive Abstract, Problem Formulation & Background
Age verification, also known as age gating, age assurance or age checking is the use of any technical system that externally verifies a person's age. These systems are used primarily to restrict access to content classified, either voluntarily or by local laws, as being inappropriate for users under a specific age, such as alcohol, tobacco, gambling, video games with objectionable content, pornography, or to remain in compliance with internet privacy laws that regulate the collection of personal information from minors, such as COPPA in the United States. Following the publication of The Anxious Generation, which proposes that governments globally should take action against minors using the internet, as well as the passing of the Online Safety Act 2023 in the UK, laws that mandate age verification via the utilization of AI facial scans and government IDs significantly increased around the globe since late 2024 when Australia announced a ban on social media for those under 16, as well as subsequent introductions of similar laws in France, eight U.S. states including Texas, California, Utah, and proposals at the national level in the U.S., Canada, Denmark, the EU, and many other countries across the globe. Age verification for inappropriate content on social networking services apply for those in the UK, Australia, Brazil and some U.S. states. Some online platforms such as Roblox and Discord also mandated digital age checks for their users worldwide. Age verification via government ID for those over 16 to access social media apply in the countries of Australia Indonesia, Malaysia and across all of the internet in Brazil as of June 2026. Age verification can be categorized into parental responsibility and online service provider responsibility. Online age verification is considered controversial and criticized by privacy rights organizations, with its push in recent years causing a moral panic. Age-based online segregation requires technical and legal frameworks which enable governments to segregate and censor groups. Extending the verification frameworks beyond age or towards mandatory digital identity enables online political repression and techno-authoritarianism. Age verification through online providers was associated with a general public distrust of the government.
The most basic form of age verification is to require a person to input their date of birth on a form or to click a button to declare they are above a certain age. However, this depends on an honor system that assumes the honesty of the end user. The person may, for instance, be a minor who fraudulently inserts a valid date that meets the age criteria, rather than their own. For this reason the system has been described as ineffective.
On August 30, 2021, the State Press and Publication Administration issued the Notice of the State Press and Publication Administration on Further Strict Management to Effectively Prevent Minors from Being Addicted to Online Games, which stipulates that all online game enterprises may only provide online game services to minors for one hour from 20:00 to 21:00 daily on Fridays, Saturdays, Sundays and legal holidays, and may not provide online game services to minors in any form at other times.
2. Related Work, Literature Survey & Algorithmic Foundations
With the passing of the Digital Economy Act 2017, the United Kingdom passed a law containing a legal mandate on the provision of age verification. Under the act, websites that publish pornography on a commercial basis would have been required to implement a "robust" age verification system. The British Board of Film Classification (BBFC) was charged with enforcing this legislation. After a series of setbacks and public backlash, the planned scheme was eventually abandoned in 2019. While the UK government abandoned this legislation, age verification continues to be monitored and enforced by regulatory bodies including Ofcom and the ICO. Other standards are emerging for age assurance systems, such as PAS1296:2018. The ISO standard for age assurance systems (PWI 7732) is also being developed by the Age Check Certificate Scheme, the Age Verification Providers’ Association, and other Conformity Assessment Bodies. In 2023, Parliament passed the Online Safety Act 2023; as part of the mandatory duty of care to protect children, all service providers must use age verification or estimation to prevent children from accessing "primary priority content that is harmful to children", which includes pornographic images. The provisions took effect on 25 July 2025, and apply to all services that host such content, including social networks. A 2025 YouGov opinion poll found among adults in the United Kingdom 39% strongly support, 35% somewhat support and 19% oppose banning social media under the age of 16.
Some websites of alcoholic beverage companies attempt to verify the age of visitors so that they can confirm they are at least the American legal drinking age of 21. In 2000, the Children's Online Privacy Protection Act (COPPA) took effect at the federal level, resulting in some websites adding age verification for visitors under the age of 13, and some websites disallowing accounts for users under the age of 13. Companies such as YouTube and ByteDance have received large fines from the Federal Trade Commission (FTC) for not complying with COPPA. In 2022, Louisiana became the first state to require age verification for accessing adult websites. Usage of LA Wallet, the state's digital ID and mobile drivers license app, subsequently spiked, as LA Wallet allows for remote identification via MindGeek, the owner of many major porn sites. In 2023, several states, including Arkansas and Utah, passed social media addiction bills requiring users of social media platforms to be over the age of 18 or have parental consent, with these bills prescribing that age verification be used to enforce this requirement. One such bill is the Utah Social Media Regulation Act, which is scheduled to take effect in 2024, and attempts to prevent minors from using social media from 10:30 PM to 6:30 AM. In May 2023, a law passed in Utah requiring that pornography websites verify the ages of their visitors, although it has a clause that bars it from taking effect until five other states also implement similar measures. A few days before the law passed, in order to protest the bill, Pornhub blocked their website from being viewed in Utah. The trade group Free Speech Coalition filed a lawsuit against the state of Utah, claiming the law violated the First Amendment. The lawsuit was dismissed by U.S. District Court Judge Ted Stewart on August 1, 2023; however, the Free Speech Coalition stated they would appeal this ruling. In contrast, on August 31, 2023, U.S. District Judge David Ezra invalidated a Texas law passed in June mandating age verification and health warnings before accessing pornographic websites following a lawsuit from the Free Speech Coalition, and barred the state attorney general's office from enforcing the law on the grounds that it violates the right to free speech and is overly broad and vague. The Texas Attorney General's office stated they would appeal the ruling. The 5th Circuit Court of Appeals overturned the injunction pending a full hearing. The case eventually progressed to the Supreme Court, who ruled 6–3 in favor of the age verification law, holding that it "only incidentally burdens the protected speech of adults". A new variant of these laws began to surface in late-2025, which requires all operating system vendors to include functionality for securely storing a user's date of birth in their account, and include an age attestation API producing a "digital signal" communicating the user's age or age range to applications which request it. They also require all application vendors to request the age signal whenever software is downloaded or launched on the device. While these bills do not explicitly require that the user's age be verified or that content be filtered, the age signals themselves are legally considered to be actual knowledge of the user's age, thus making vendors liable under other state and federal laws. The first of these bills, the Digital Age Assurance Act, was signed into law by California in October 2025. The bill faced criticism for its wide reach, including free and open-source software platforms who may not have the necessary infrastructure to implement the requirements, and operating systems not always used for general computing (such as embedded systems and servers).
Machine learning (ML) is a field of study in artificial intelligence concerned with the development and study of statistical algorithms that can learn from data and generalize to unseen data, and thus perform tasks without being explicitly programmed. Statistics and mathematical optimisation methods compose the foundations of machine learning. Data mining is a related field of study, focusing on exploratory data analysis (EDA) through unsupervised learning. From a theoretical viewpoint, probably approximately correct learning provides a mathematical and statistical framework for describing machine learning. Most traditional machine learning and deep learning algorithms can be described as empirical risk minimisation under this framework. Advances in the field of deep learning have allowed neural networks, a class of statistical algorithms, to surpass many previous machine learning approaches in performance. The resulting dominance of machine learning within the field of AI from the late 2000s and early 2010s onwards was such that the terms "machine learning" and "artificial intelligence" are now often used interchangeably, even though they are not synonymous.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
The term machine learning was coined in 1959 by Arthur Samuel, an IBM employee and pioneer in the field of computer gaming and artificial intelligence. The synonym self-teaching computers was also used during this time period. The earliest machine learning program was introduced in the 1950s, when Samuel invented a computer program that calculated the chance of winning in checkers for each side, but the history of machine learning is rooted in decades of efforts to study human cognitive processes. In 1949, Canadian psychologist Donald Hebb published the book The Organization of Behavior, in which he introduced a theoretical neural structure formed by certain interactions among nerve cells. The Hebbian theory of neuron interaction set the groundwork for how many machine learning algorithms work, with connected artificial neurons changing the strength of their connections based on data. Other researchers who have studied human cognitive systems contributed to the modern machine learning technologies as well, including Walter Pitts and Warren McCulloch, who proposed the first mathematical model of neural networks including algorithms that mirror human thought processes. By the early 1960s, an experimental "learning machine" with punched tape memory, called Cybertron, had been developed by Raytheon Company to analyse sonar signals, electrocardiograms, and speech patterns using rudimentary reinforcement learning. It was repetitively "trained" by a human operator/teacher to recognise patterns and equipped with a "goof" button to cause it to reevaluate incorrect decisions. A representative book on research into machine learning during the 1960s was Nils Nilsson's book "Learning Machines", dealing mostly with machine learning for pattern classification. Interest related to pattern recognition continued into the 1970s, as described by Duda and Hart in 1973. In 1981, a report was given on using teaching strategies so that an artificial neural network learns to recognise 40 characters (26 letters, 10 digits, and 4 special symbols) from a computer terminal. Tom M. Mitchell provided a widely quoted, more formal definition of the algorithms studied in the machine learning field: "A computer program is said to learn from experience E with respect to some class of tasks T and performance measure P if its performance at tasks in T, as measured by P, improves with experience E." This definition of the tasks in which machine learning is concerned is fundamentally operational rather than defining the field in cognitive terms. This follows Alan Turing's proposal in his paper "Computing Machinery and Intelligence", in which the question, "Can machines think?", is replaced by asking whether machines can convincingly imitate a human in its responses to human-posed questions. In 2012, AlexNet, developed by Alex Krizhevsky, Ilya Sutskever, and Geoffrey Hinton, achieved substantially improved results in the ImageNet image recognition competition, contributing to the wider adoption of deep neural networks. In 2013, Tomáš Mikolov and colleagues introduced word2vec, techniques for efficiently learning distributed vector representations of words from large text corpora. In 2014, Ian Goodfellow and colleagues introduced generative adversarial networks (GANs), a framework for training generative models through an adversarial process. In 2016, AlphaGo became the first computer program to defeat a professional human Go player without handicaps on a full-sized board, using deep neural networks and reinforcement learning. In 2017, Ashish Vaswani and colleagues introduced the Transformer, a neural network architecture based primarily on attention rather than recurrence or convolution.
As a scientific endeavour, machine learning grew out of the quest for artificial intelligence (AI). In the early days of AI as an academic discipline, some researchers were interested in having machines learn from data. They attempted to approach the problem with various symbolic methods, as well as what were then termed "neural networks"; these were mostly perceptrons and other models that were later found to be reinventions of the generalised linear models of statistics. Probabilistic reasoning was also employed, especially in automated medical diagnosis. However, an increasing emphasis on the logical, knowledge-based approach caused a rift between AI and machine learning. Probabilistic systems were plagued by theoretical and practical problems of data acquisition and representation. By 1980, expert systems had come to dominate AI, and statistics was out of favour. Work on symbolic/knowledge-based learning continued within AI, leading to inductive logic programming (ILP), but the more statistical line of research was now outside the field of AI proper, in pattern recognition and information retrieval. Neural network research was abandoned by AI and computer science around the same time. This subfield, termed "connectionism", was continued by researchers from other disciplines, including John Hopfield, David Rumelhart, and Geoffrey Hinton. Their main success came in the mid-1980s with the reinvention of backpropagation. Machine learning (ML), reorganised and recognised as its own field, started to flourish in the 1990s. The field changed its goal from achieving artificial intelligence to tackling solvable problems of a practical nature. It shifted focus away from the symbolic approaches it had inherited from AI, and toward methods and models borrowed from statistics, fuzzy logic, and probability theory.
A core objective of a learner is to generalise from its experience. Generalisation in this context is the ability of a learning machine to perform accurately on new, unseen examples/tasks after having experienced a learning data set. The training examples come from some generally unknown probability distribution (considered representative of the space of occurrences) and the learner has to build a general model about this space that enables it to produce sufficiently accurate predictions in new cases. The computational analysis of machine learning algorithms and their performance is a branch of theoretical computer science known as computational learning theory. One major framework is the probably approximately correct learning model. Because training sets are finite and the future is uncertain, learning theory usually does not yield guarantees of the performance of algorithms. Instead, probabilistic bounds on the performance are quite common. The bias–variance decomposition is one way to quantify generalisation error. For the best performance in the context of generalisation, the complexity of the hypothesis should match the complexity of the function underlying the data. If the hypothesis is less complex than the function, then the model has underfitted the data. If the complexity of the model is increased in response, then the training error decreases. But if the hypothesis is too complex, then the model is subject to overfitting and generalisation will be poorer. In addition to performance bounds, learning theorists study the time complexity and feasibility of learning. In computational learning theory, a computation is considered feasible if it can be done in polynomial time. There are two kinds of time complexity results: Positive results show that a certain class of functions can be learned in polynomial time. Negative results show that certain classes cannot be learned in polynomial time.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Machine learning approaches are traditionally divided into three broad categories, which correspond to learning paradigms, depending on the nature of the "signal" or "feedback" available to the learning system:
Supervised learning: The computer is presented with example inputs and their desired outputs, given by a "teacher", and the goal is to learn a general rule that maps inputs to outputs. Unsupervised learning: No labels are given to the learning algorithm, leaving it on its own to find structure in its input. Unsupervised learning can be a goal in itself (discovering hidden patterns in data) or a means towards an end (feature learning). Reinforcement learning: A computer program interacts with a dynamic environment in which it must perform a certain goal (such as driving a vehicle or playing a game against an opponent). As it navigates its problem space, the program is provided rewards as feedback, which it tries to maximize, thus resulting in the program learning from experience. Although each algorithm has advantages and limitations, no single algorithm works for all problems.
Supervised learning algorithms build a mathematical model of a set of data that contains both the inputs and the desired outputs. The data, known as training data, consists of a set of training examples. Each training example has one or more inputs and the desired output, also known as a supervisory signal. In the mathematical model, each training example is represented by an array or vector, sometimes called a feature vector, and the training data is represented by a matrix. Through iterative optimisation of an objective function, supervised learning algorithms learn a function that can be used to predict the output associated with new inputs. An optimal function allows the algorithm to correctly determine the output for inputs that were not a part of the training data. An algorithm that improves the accuracy of its outputs or predictions over time is said to have learned to perform that task. Types of supervised-learning algorithms include active learning, classification and regression. Classification algorithms are used when the outputs are restricted to a limited set of values, while regression algorithms are used when the outputs can take any numerical value within a range. For example, in a classification algorithm that filters emails, the input is an incoming email, and the output is the folder in which to file the email. In contrast, regression is used for tasks such as predicting a person's height based on factors like age and genetics or forecasting future temperatures based on historical data. Similarity learning is an area of supervised machine learning closely related to regression and classification, but the goal is to learn from examples using a similarity function that measures how similar or related two objects are. It has applications in ranking, recommendation systems, visual identity tracking, face verification, and speaker verification.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Unsupervised learning algorithms find structures in data that has not been labelled, classified or categorised. Instead of responding to feedback, unsupervised learning algorithms identify commonalities in the data and react based on the presence or absence of such commonalities in each new piece of data. Central applications of unsupervised machine learning include clustering, dimensionality reduction, and density estimation. Cluster analysis is the assignment of a set of observations into subsets (called clusters) so that observations within the same cluster are similar according to one or more predesignated criteria, while observations drawn from different clusters are dissimilar. Different clustering techniques make different assumptions on the structure of the data, often defined by some similarity metric and evaluated, for example, by internal compactness, or the similarity between members of the same cluster, and separation, the difference between clusters. Other methods are based on estimated density and graph connectivity. A special type of unsupervised learning called self-supervised learning involves training a model by generating the supervisory signal from the data itself.
Semi-supervised learning falls between unsupervised learning (without any labelled training data) and supervised learning (with completely labelled training data). Some of the training examples are missing training labels, yet many machine-learning researchers have found that unlabelled data, when used in conjunction with a small amount of labelled data, can produce a considerable improvement in learning accuracy. In weakly supervised learning, the training labels are noisy, limited, or imprecise; however, these labels are often cheaper to obtain, resulting in larger effective training sets.
Reinforcement learning is an area of machine learning concerned with how software agents ought to take actions in an environment to maximise some notion of cumulative reward. Due to its generality, the field is studied in many other disciplines, such as game theory, control theory, operations research, information theory, simulation-based optimisation, multi-agent systems, swarm intelligence, statistics and genetic algorithms. In reinforcement learning, the environment is typically represented as a Markov decision process (MDP). Many reinforcement learning algorithms use dynamic programming techniques. Reinforcement learning algorithms do not assume knowledge of an exact mathematical model of the MDP and are used when exact models are infeasible. Reinforcement learning algorithms are used in autonomous vehicles or in learning to play a game against a human opponent.
Model Figures & Evaluation Curves (4 Images)
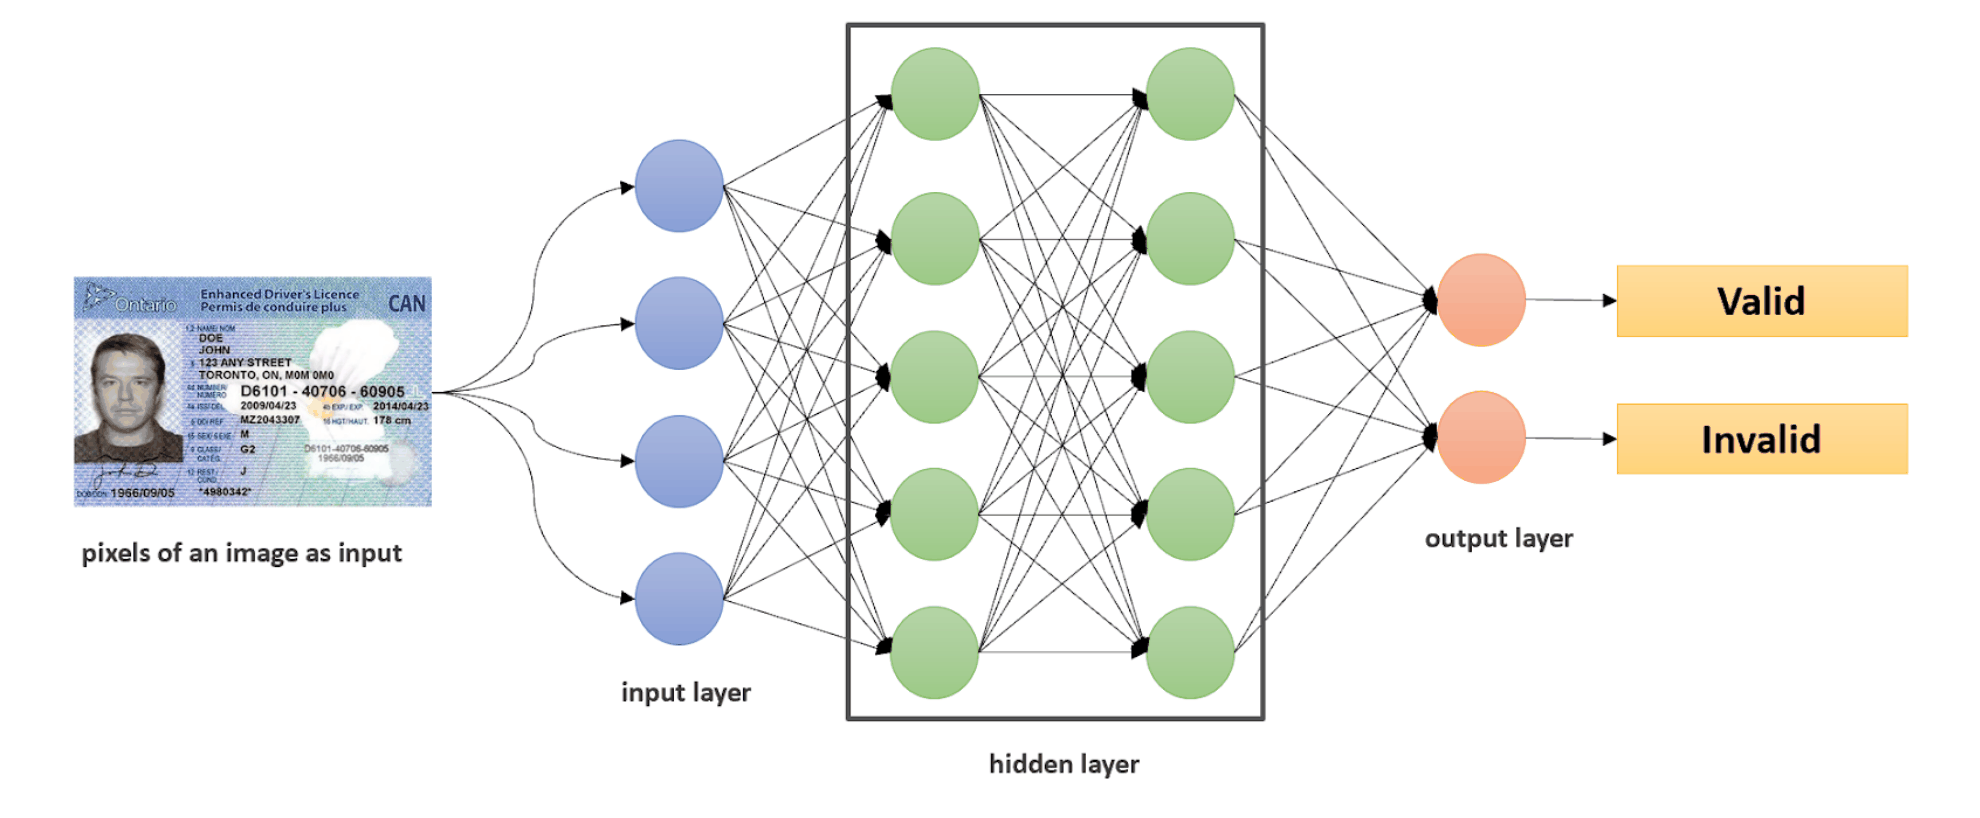
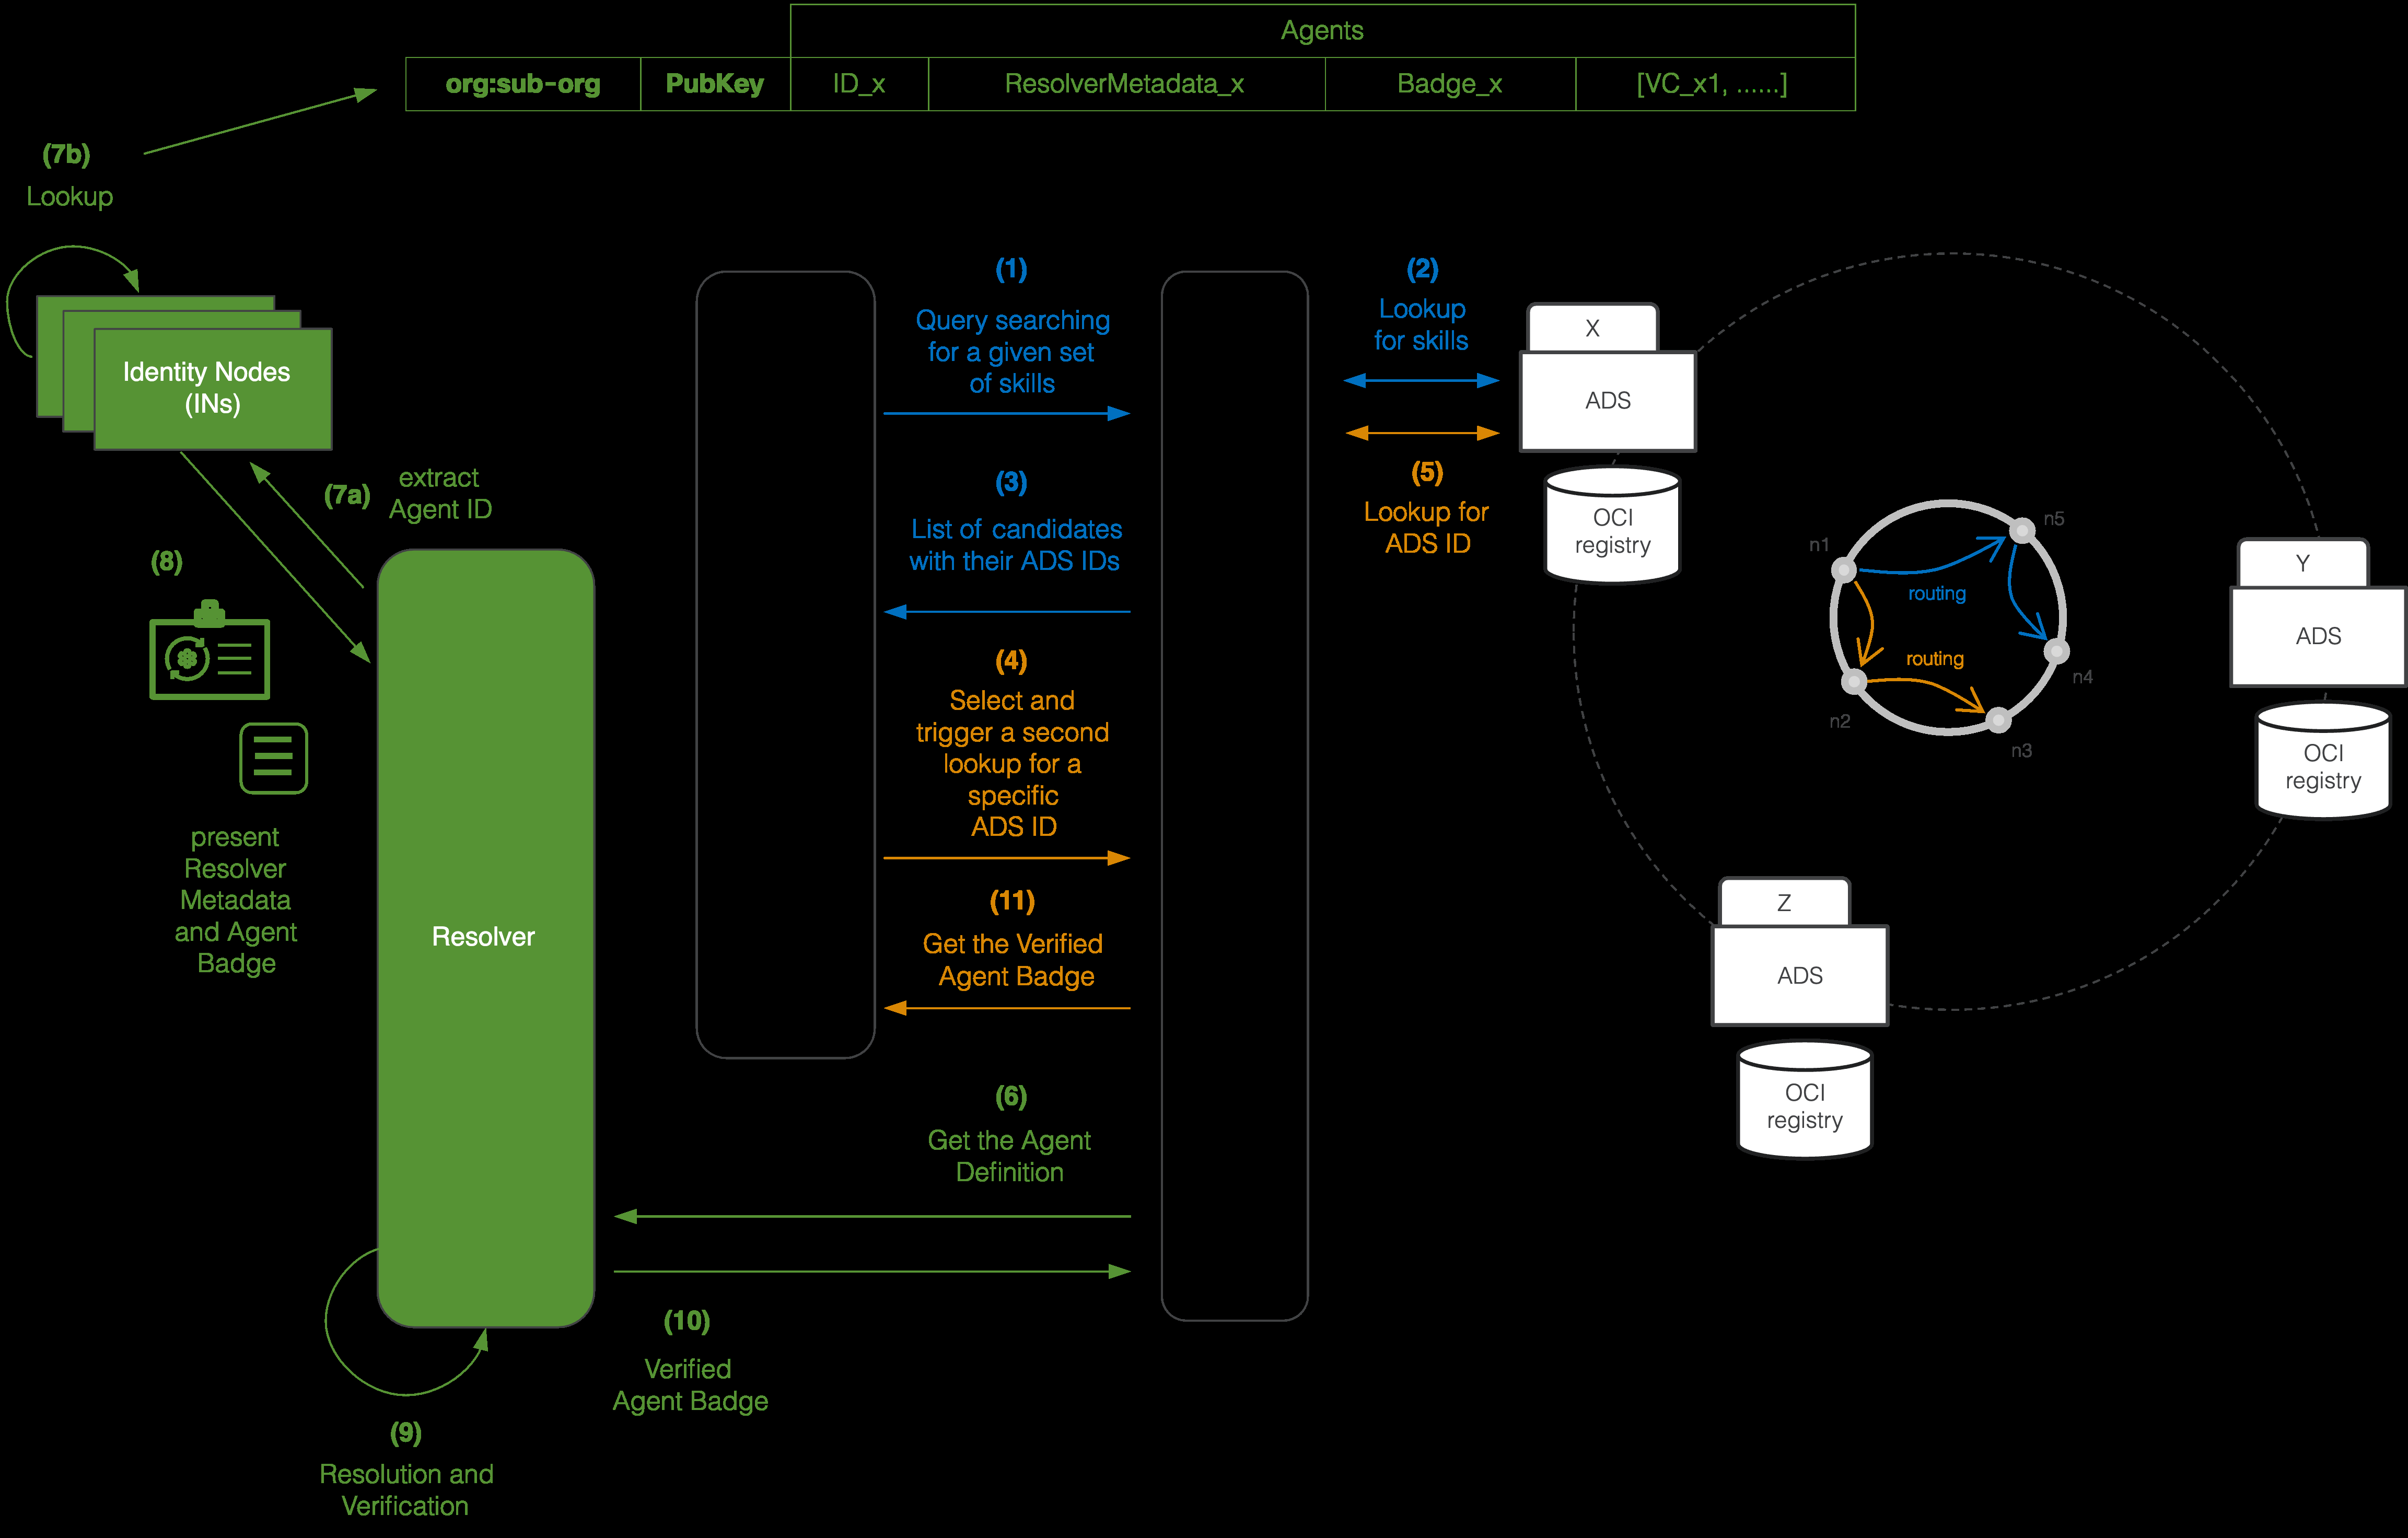
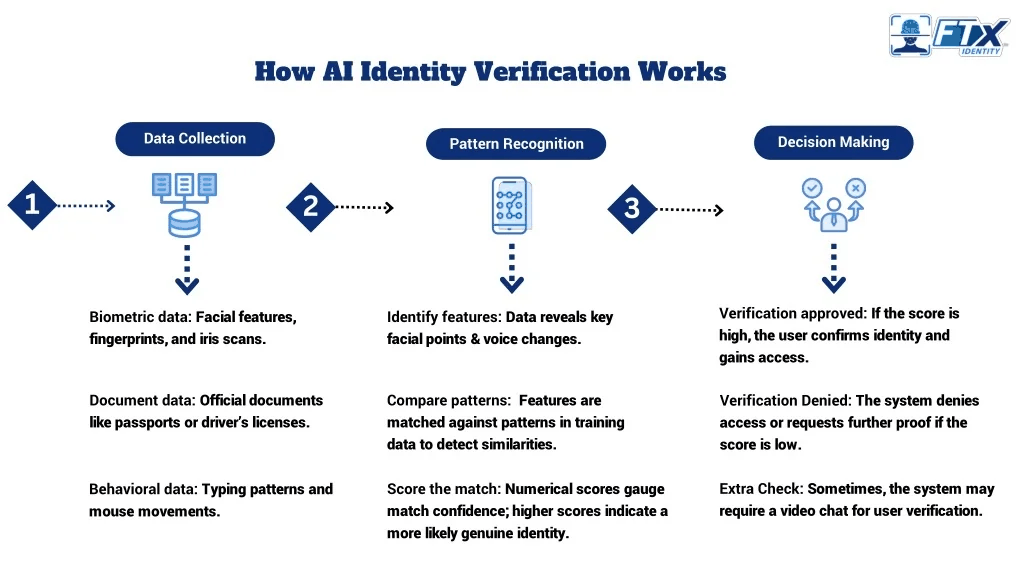
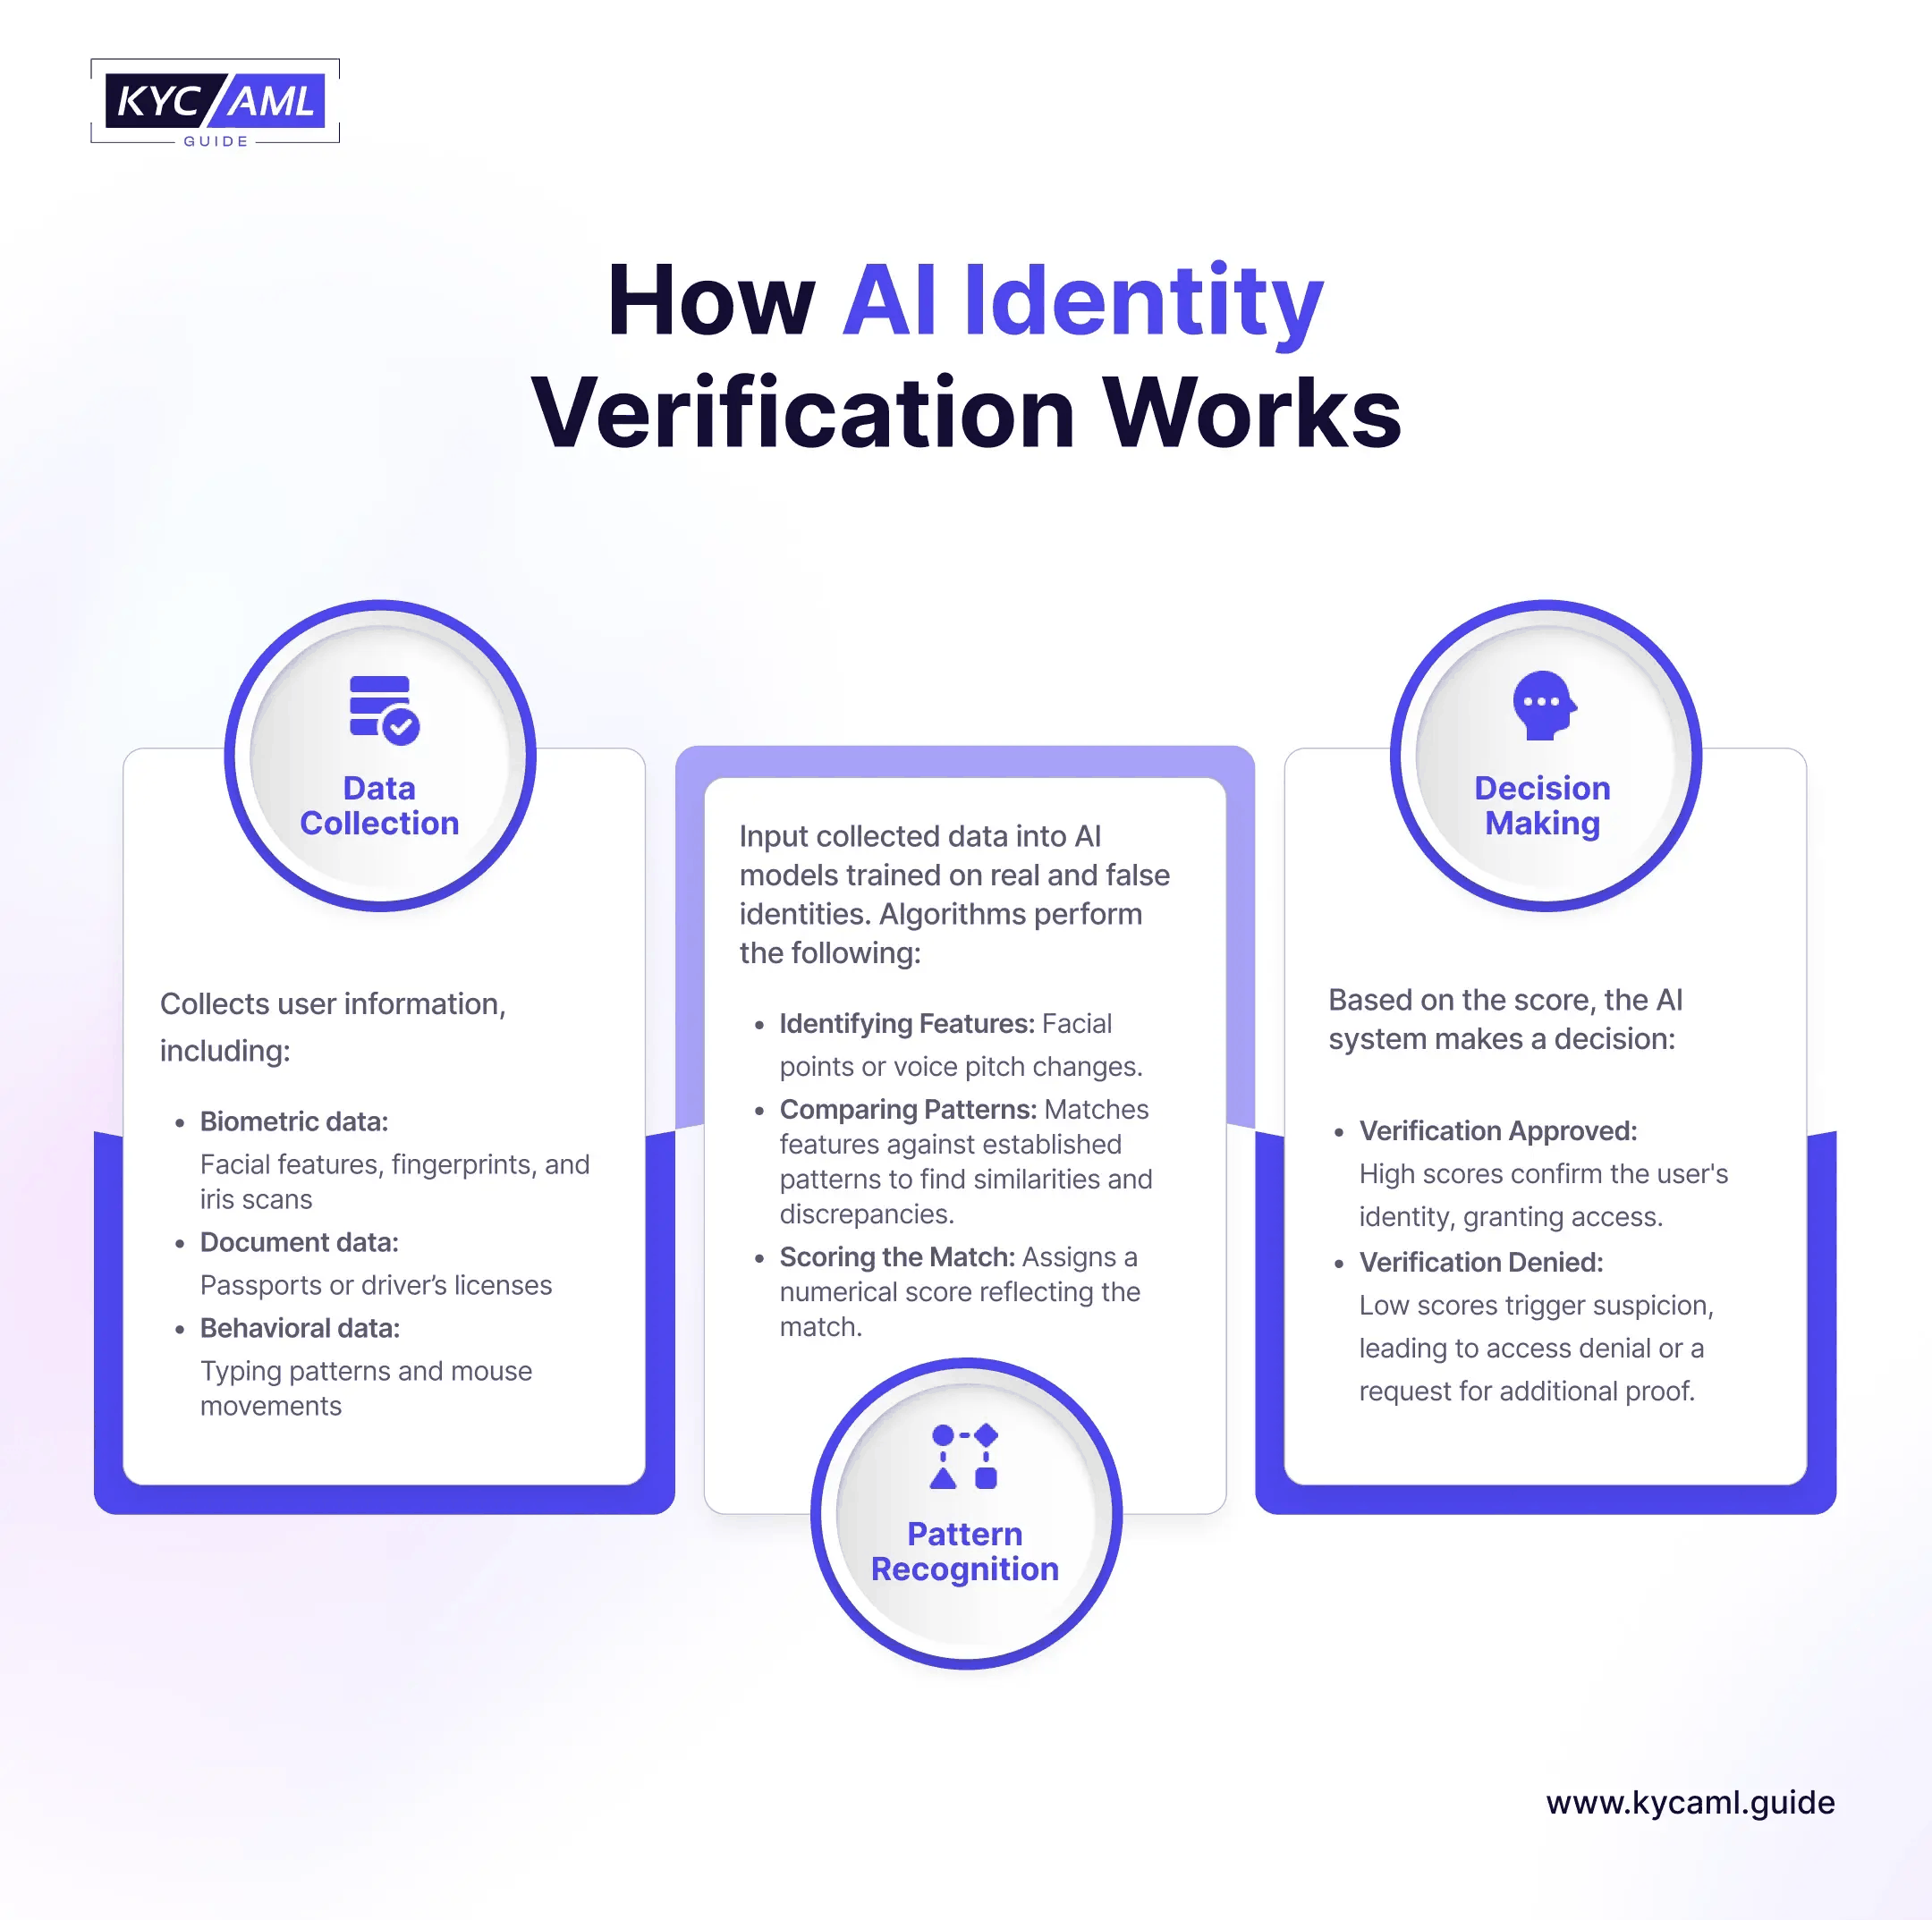
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)