Complete Technical Paper Content — Ai Kyc Automation
1. Executive Abstract, Problem Formulation & Background
COVID-19 apps include mobile-software applications for digital contact-tracing—i.e. the process of identifying persons ("contacts") who may have been in contact with an infected individual—deployed during the COVID-19 pandemic. Numerous tracing applications have been developed or proposed, with official government support in some territories and jurisdictions. Several frameworks for building contact-tracing apps have been developed. Privacy concerns have been raised, especially about systems that are based on tracking the geographical location of app users. Less overtly intrusive alternatives include the co-option of Bluetooth signals to log a user's proximity to other cellphones. (Bluetooth technology has form in tracking cell-phones' locations.)) On 10 April 2020, Google and Apple jointly announced that they would integrate functionality to support such Bluetooth-based apps directly into their Android and iOS operating systems. India's COVID-19 tracking app Aarogya Setu became the world's fastest growing application—beating Pokémon Go—with 50 million users in the first 13 days of its release.
Contact tracing is an important tool in infectious disease control, but as the number of cases rises time constraints make it more challenging to effectively control transmission. Digital contact tracing, especially if widely deployed, may be more effective than traditional methods of contact tracing. In a March 2020 model by the University of Oxford Big Data Institute's Christophe Fraser's team, a coronavirus outbreak in a city of one million people is halted if 80% of all smartphone users take part in a tracking system; in the model, the elderly are still expected to self-isolate en masse, but individuals who are neither symptomatic nor elderly are exempt from isolation unless they receive an alert that they are at risk of carrying the disease. Some proponents advocate for legislation exempting certain COVID-19 apps from general privacy restrictions.
surveillance would have to be "lawful, necessary and proportionate"; extensions of monitoring and surveillance would have to have sunset clauses; the use of data would have to be limited to COVID-19 purposes; data security and anonymity would have to be protected and shown to be protected based on evidence; digital surveillance would have to address the risk of exacerbating discrimination and marginalisation; any sharing of data with third parties would have to be defined in law; there would have to be safeguards against abuse and the rights of citizens to respond to abuses; "meaningful participation" by all "relevant stakeholders" would be required, including that of public health experts and marginalised groups. The German Chaos Computer Club (CCC) and Reporters Without Borders also issued checklists. The Exposure Notification service intends to address the problem of persistent surveillance by removing the tracing mechanism from their device operating systems once it is no longer needed. On 20 April 2020, it was reported that over 300 academics had signed a statement favouring decentralised proximity tracing applications over centralised models, given the difficulty in precluding centralised options being used "to enable unwarranted discrimination and surveillance." In a centralised model, a central database records the ID codes of meetings between users. In a decentralised model, this information is recorded on individual phones, with the role of the central database being limited to identifying phones by their ID code when an alert needs to be sent. In Moscow use of the tracking app was made mandatory during the lockdowns in April 2020 when most Muscovites were mostly required to stay indoors. Vladimir Putin signed laws introducing criminal penalties, including up to seven years imprisonment, for quarantine violations that led to others being infected. Moscow also implemented government-issued QR codes that were made mandatory. It was not disclosed what information the codes contain, but they must be shown to police when requested. Opposition members were uncomfortable with the Russian government's introduction of COVID surveillance tools. In May 2020 Human Rights Watch reported that the authorities in Moscow had wrongly fined hundreds of Muscovites for breaching self-quarantine. The dubious behavioral interpretations recorded by the social monitoring tracking application led to the mistaken fining of hundreds of people in Moscow. Contact-tracing apps were deployed rapidly by governments and other organisations in spring and summer 2020. Initial releases were found to come with incongruent privacy policies, hidden built-in surveillance and location-tracing functions, and generally contained few cues about a proper specification and quality assurance process. Code quality in several apps was found to be poor, while hardly any of 28 apps surveyed in May and June 2020 managed to address all privacy principles laid forth in the EU's GDPR.
Privacy-preserving contact tracing is a well-established concept, with a substantial body of research literature dating back to at least 2013. On 17 March 2020 the CEN protocol developed by Covid Watch, later renamed the TCN Protocol, was first released. Covid Watch was the first organization to develop and open source an anonymous, decentralized Bluetooth digital contact tracing protocol, publishing their white paper on the subject in March 2020. The group was founded as a research collaboration between Stanford University and the University of Waterloo. On 1 April 2020, the CEN Protocol was presented at Stanford HAI's COVID-19 and AI virtual conference. As of 1 April 2020, a group of European researchers, including from the Fraunhofer Heinrich Hertz Institute and École Polytechnique Fédérale de Lausanne (EPFL), were under the umbrella of the Pan-European Privacy-Preserving Proximity Tracing (PEPP-PT) project, developing a BLE-based app to serve this purpose that is designed to avoid the need for intrusive surveillance by the state. However, PEPP-PT is a co-ordination effort which contains both centralised and decentralised approaches. As of 7 April 2020, over a dozen expert groups were working on privacy-friendly solutions, such as using Bluetooth Low Energy (BLE) to log a user's proximity to other cellphones. Users then receive a message if they've been in close contact with someone who has tested positive for COVID-19. On 9 April 2020, the Singaporean government announced that it had open-sourced a reference implementation of the BlueTrace protocol, used by TraceTogether, its official government app. As of 23 March 2020, Mary-Louise McLaws, professor at the University of New South Wales' School of Public Health and Community Medicine in Australia, a technical adviser to the World Health Organization's Infection Prevention and Control Global Unit and a member of European, US and UK epidemiology and infection control bodies recommended the idea for wider adoption. On 17 April 2020, EPFL and the ETH Zurich pulled out of PEPP-PT, criticizing PEPP-PT for a lack of transparency and openness, and for not respecting personal privacy enough. Later it was reported that KU Leuven, the CISPA Helmholz Center for Information Security, the European Laboratory for Learning and Intelligent Systems and the Technical University of Denmark, also withdrew from the project. On 26 April 2020, Germany switched to decentralised approach to support solutions like DP-3T.
On 10 April 2020, Google and Apple, the companies that control the Android and iOS mobile platforms, announced an initiative for contact tracing, which they stated would preserve privacy, based on a combination of Bluetooth Low Energy technology and privacy-preserving cryptography. They also published specifications of the core technologies used in the system. According to Apple and Google, the system is intended to be rolled out in three stages:
API specification and publication rollout of tools to enable governments to create official privacy-preserving coronavirus tracing apps integration of this functionality directly into iOS and Android Google and Apple plan to address the take-up and persistent surveillance problems by first distributing the system through operating system updates, and later removing it in the same way once the threat has passed. The ACLU stated the Google and Apple's approach "appears to mitigate the worst privacy and centralization risks, but there is still room for improvement". By 20 April 2020, Google and Apple described the systems as "Exposure Notification" rather than "contact tracing", stating the system should be "in service of broader contact tracing efforts by public health authorities". The name change was received positively by journalists in Vox/Recode and Salon, who stated "Exposure notification schemes like the Apple-Google system aren't true contact tracing systems because they don't allow public health authorities to identify people who have been exposed to infected individuals."
2. Related Work, Literature Survey & Algorithmic Foundations
The NHS COVID-19 contact tracing app for England and Wales was released on 24 September 2020. The NHS app uses Google/Apple exposure notification technology. (The NHS previously tried a centralised system rather than a decentralised approach). Scotland and Northern Ireland contact tracing apps were launched in the weeks prior to England & Wales. To aid contract tracing, the NHS COVID-19 contact tracing app for England and Wales allows users to scan official NHS QR code posters at businesses, venues and transport hubs. To ensure data integrity, the QR code is constructed from a JSON Web Signature (JWS). On 28 September 2021, the Citizen Lab published an analysis of COVID-19 data collection practices in Canada, the United Kingdom, and the United States. As of 27 April 2023 the NHS COVID-19 App was discontinued.
Note: This table should list only apps that are either supported by citations from third-party reliable sources or are from or supported by independently notable organizations such as national governments, industrial collaborations, major universities, NGOs, or one of the framework collaborations listed above. MIT Technology Review also maintained a Google spreadsheet listing of contact tracing and exposure notification apps that are being used around the world.
🧠 AI-KYC Identity Verification System An AI-powered KYC (Know Your Customer) verification system that automates identity authentication using OCR, Face Recognition, Liveness Detection, Blur Analysis, and AI-driven Risk Scoring. Built with Python, Flask, OpenCV, Tesseract, Deep Learning , and a secure admin dashboard. 📌 Features 🔍 Identity Processing OCR-based text extraction from ID documents Automatic Name & DOB extraction using regex + NLP Face Recognition using DeepFace / face_recognition Liveness Detection using Haar Cascades Blur Detection using Laplacian variance Size-based quality checks 🤖 AI Decision Engine Computes a combined risk score Suggests: APPROVED / PENDING / FLAGGED Multi-factor scoring (OCR + Face + Liveness + Blur) 🛠️ Admin Dashboard Approve / Reject / Mark Pending PDF Report Generator Audit Logs Search + Filter Statistics (Total, Pending, Approved, Flagged) 🧱 Backend Python Flask Application SQLite Database Secure Admin Auth Upload Handling + Validation 🏗️ System Architecture User Upload → OCR Layer → Face Recognition → Liveness → Blur Detection → Risk Engine → AI Decision → Admin Dashboard → SQLite DB 🗂️ Folder Structure AI-KYC-Identity-Verification-System/ │── app.py │── requirements.txt │── README.md │── .gitignore │ ├── assets/ │ └── architecture_diagram.png │ ├── docs/ │ ├── AI_KYC_Hackathon_Submission.docx │ └── AI_KYC_Project_Report.pdf │ ├── uploads/ │ └── .gitkeep │ ├── static/ └── templates/ 🧰 Technology Stack Python 3.10+ Flask OpenCV Tesseract OCR face_recognition / DeepFace NumPy, Pillow SQLite Bootstrap 5 ReportLab PDF Generator 🔧 Installation Clone the repository: git clone https://github.com/UnnayanSingh/AI-KYC-Identity-Verification-System.git cd AI-KYC-Identity-Verification-System Install dependencies: pip install -r requirements.txt Windows Tesseract Setup: Set TESSERACT_CMD=C:\Program Files\Tesseract-OCR esseract.exe ▶️ Run the Application python app.py Open browser at: http://127.0.0.1:5000/ 🗄️ Database Structure Applicants Table id, name, dob, id_image, selfie face_conf, liveness, blur risk_score, ai_suggestion, final_status created_at Admins Table id, username, password_hash, created_at Audit Logs Table id, admin_username, action, app_id, timestamp 🎥 Demo Video (Add your YouTube / Google Drive link here) 📄 Documentation Full Project Report PDF 📜 License This project is open-source under the MIT License .
An AI-powered KYC (Know Your Customer) verification system that automates identity authentication using OCR, Face Recognition, Liveness Detection, Blur Analysis, and AI-driven Risk Scoring. Built with Python, Flask, OpenCV, Tesseract, Deep Learning , and a secure admin dashboard.
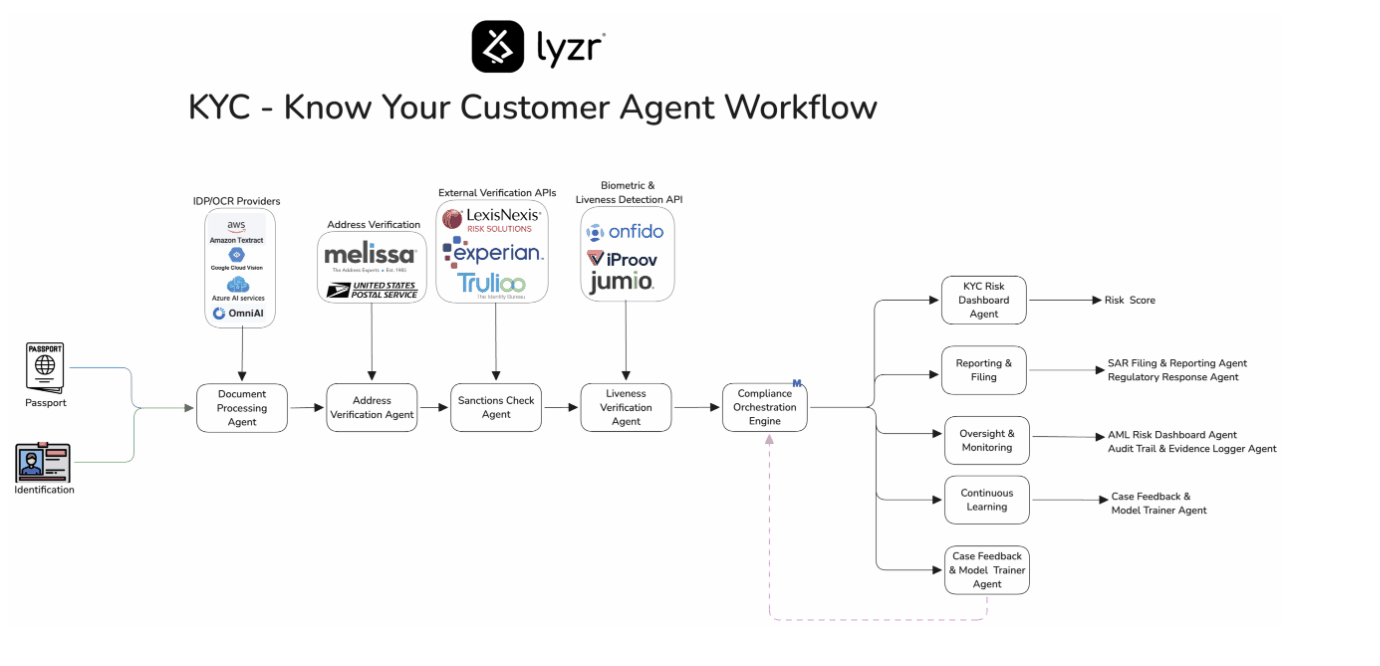
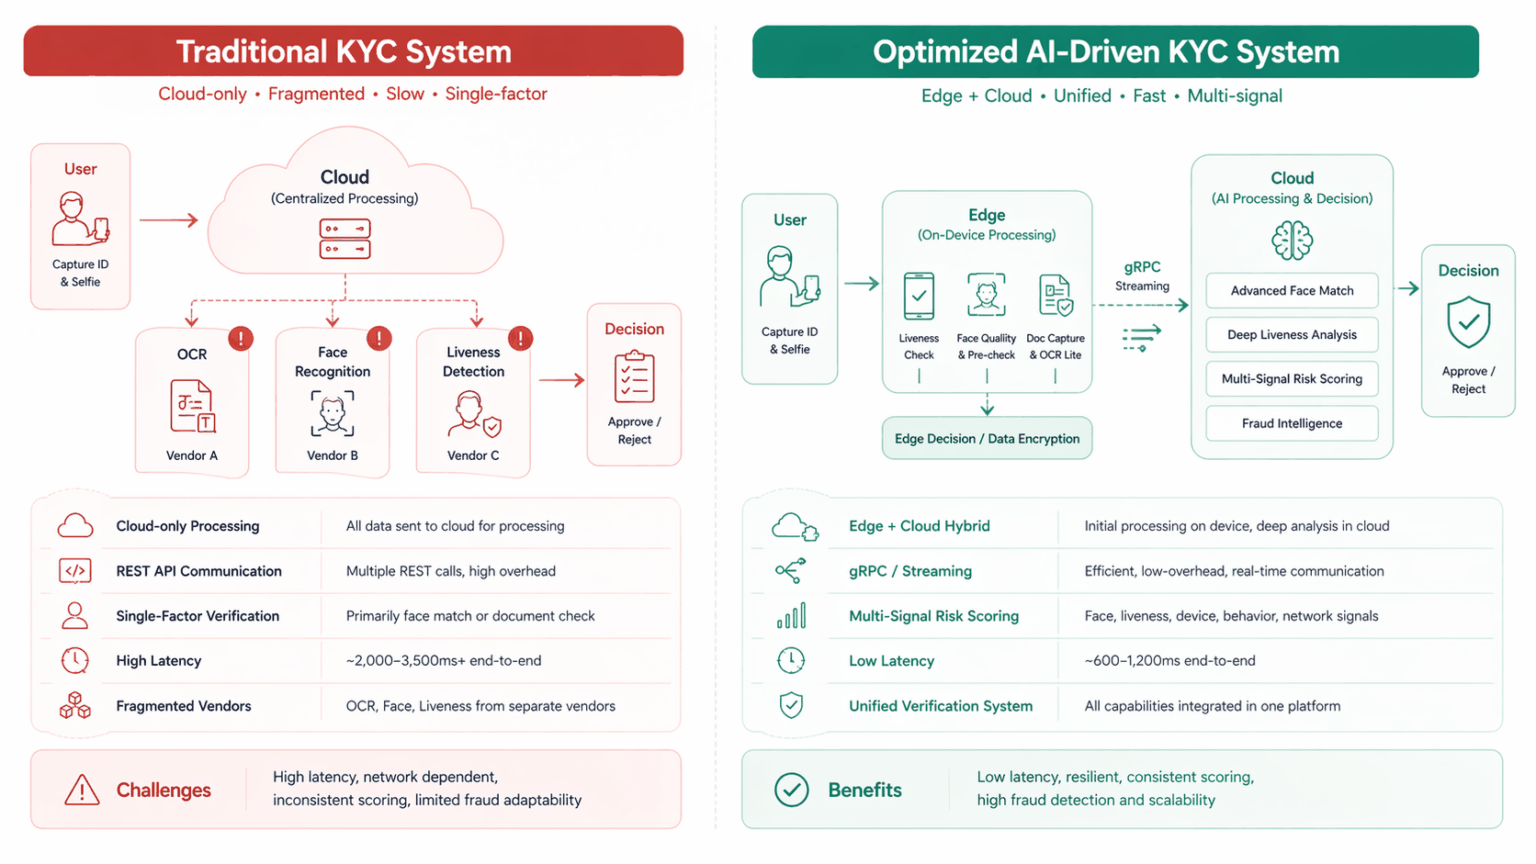
User Upload → OCR Layer → Face Recognition → Liveness → Blur Detection → Risk Engine → AI Decision → Admin Dashboard → SQLite DB
AI-KYC-Identity-Verification-System/ │── app.py │── requirements.txt │── README.md │── .gitignore │ ├── assets/ │ └── architecture_diagram.png │ ├── docs/ │ ├── AI_KYC_Hackathon_Submission.docx │ └── AI_KYC_Project_Report.pdf │ ├── uploads/ │ └── .gitkeep │ ├── static/ └── templates/
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
git clone https://github.com/UnnayanSingh/AI-KYC-Identity-Verification-System.git cd AI-KYC-Identity-Verification-System
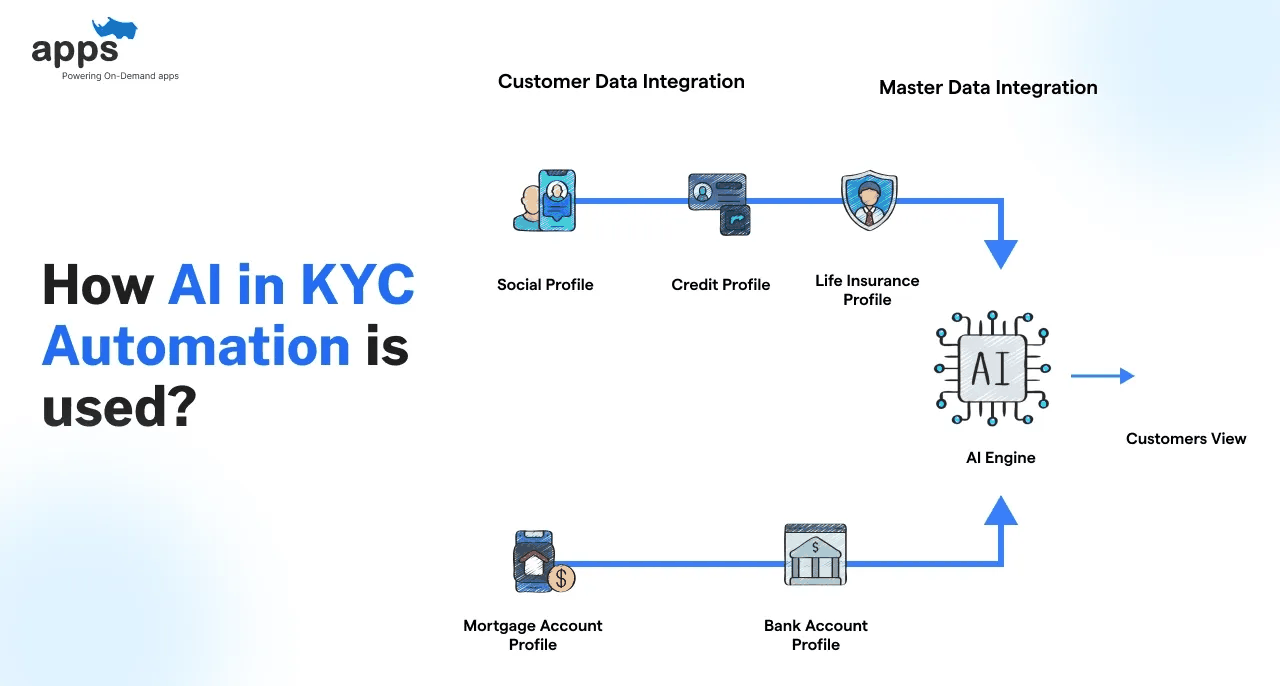
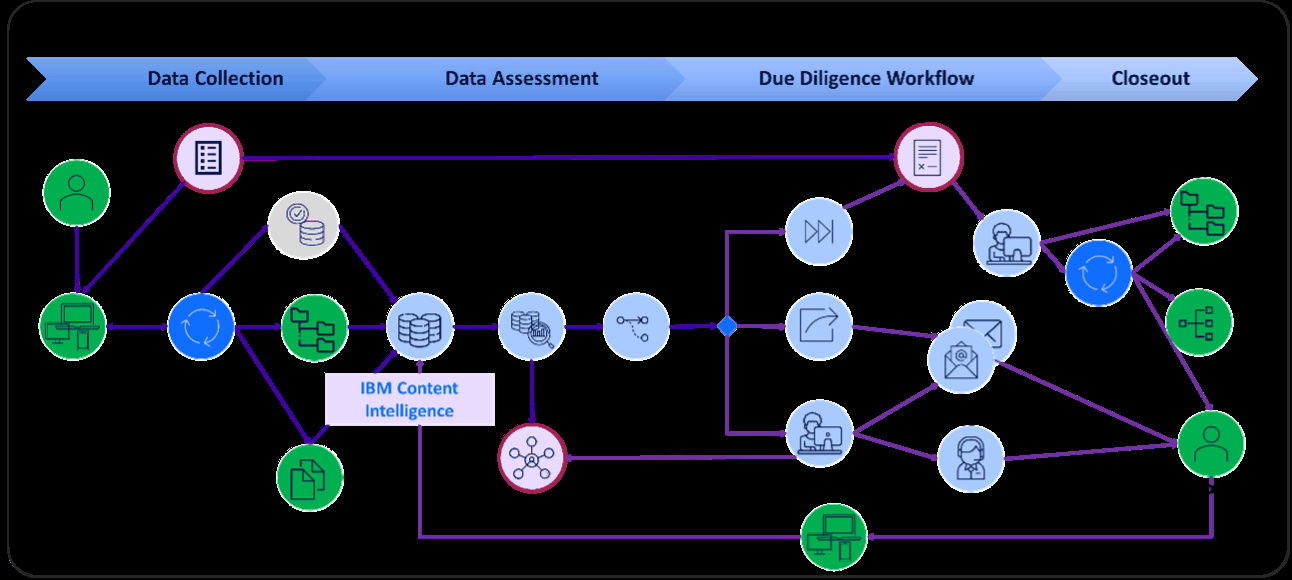
AI-KYC system: OCR + Face Recognition + Liveness + Risk Scoring + Admin Dashboard. Fully automated identity verification pipeline.
AI KYC Verification System Overview AI KYC Verification System is a Machine Learning and Computer Vision based project designed to automate Know Your Customer (KYC) verification processes. The system extracts information from identity documents using OCR, validates the extracted data, and is designed to support advanced verification features such as face matching, fraud detection, and multi-document verification. Currently, the project supports PAN Card verification using Tesseract OCR and is being expanded to support Aadhaar Cards and additional identity documents. Features Current Features PAN Card OCR using Tesseract Automatic extraction of: PAN Number Full Name Date of Birth PAN Number format validation Image preprocessing using OpenCV Structured JSON output Upcoming Features Aadhaar Card OCR Face Verification (Selfie vs Document Photo) Multi-Document Verification Cross-Document Data Matching Fraud Detection Document Classification KYC Risk Scoring FastAPI Backend Integration Database Storage Technology Stack Programming Language Python Computer Vision OpenCV OCR Engine Tesseract OCR Machine Learning Scikit-learn TensorFlow (Planned) Backend FastAPI (Planned) Database PostgreSQL (Planned) Project Workflow User uploads a PAN Card image. Image is preprocessed using OpenCV. Tesseract OCR extracts text from the document. Required fields are identified and extracted. PAN Number is validated. Verification results are generated. Future workflow: Document Upload → OCR Extraction → Face Verification → Data Validation → Fraud Detection → KYC Approval/Rejection Project Structure AI_KYC_Verification_System/ ├── data/ │ ├── input_images/ │ └── output/ │ ├── models/ │ ├── ocr/ │ ├── pan_ocr.py │ └── aadhaar_ocr.py │ ├── verification/ │ ├── pan_validation.py │ ├── aadhaar_validation.py │ └── face_verification.py │ ├── utils/ │ ├── app.py ├── requirements.txt └── README.md Installation Clone Repository git clone https://github.com/Kamlesh-Kumar-ai/AI_KYC_Verification_System.git cd AI_KYC_Verification_System Create Virtual Environment python -m venv venv Activate Environment Windows: venv \S cripts \a ctivate Linux/Mac: source venv/bin/activate Install Dependencies pip install -r requirements.txt Tesseract Installation Download and install Tesseract OCR. After installation, configure the executable path: import pytesseract pytesseract . pytesseract . tesseract_cmd = r"path_to_tesseract_executable" Future Roadmap Phase 1 PAN OCR Verification ✅ Phase 2 Aadhaar OCR Support Phase 3 Face Verification Phase 4 Multi-Document Verification Phase 5 Fraud Detection Phase 6 Complete KYC Automation Platform Learning Objectives This project was built to gain hands-on experience in: Optical Character Recognition (OCR) Computer Vision Machine Learning Identity Verification Systems Fraud Detection FastAPI Development AI-based KYC Automation Author Kamlesh Kumar Python Developer | Machine Learning Engineer | AI Enthusiast GitHub: https://github.com/Kamlesh-Kumar-ai
AI KYC Verification System is a Machine Learning and Computer Vision based project designed to automate Know Your Customer (KYC) verification processes.
The system extracts information from identity documents using OCR, validates the extracted data, and is designed to support advanced verification features such as face matching, fraud detection, and multi-document verification.
Currently, the project supports PAN Card verification using Tesseract OCR and is being expanded to support Aadhaar Cards and additional identity documents.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Document Upload → OCR Extraction → Face Verification → Data Validation → Fraud Detection → KYC Approval/Rejection
AI_KYC_Verification_System/ ├── data/ │ ├── input_images/ │ └── output/ │ ├── models/ │ ├── ocr/ │ ├── pan_ocr.py │ └── aadhaar_ocr.py │ ├── verification/ │ ├── pan_validation.py │ ├── aadhaar_validation.py │ └── face_verification.py │ ├── utils/ │ ├── app.py ├── requirements.txt └── README.md
git clone https://github.com/Kamlesh-Kumar-ai/AI_KYC_Verification_System.git cd AI_KYC_Verification_System
import pytesseract pytesseract . pytesseract . tesseract_cmd = r"path_to_tesseract_executable"
KYC_using deep learning Intelligent KYC & Document Verification Pipeline with Multimodal Deep Learning A complete end-to-end pipeline for Know Your Customer (KYC) document verification, featuring document classification, OCR extraction, MRZ parsing, face matching, and liveness detection. Architecture Module Description Model/Method Quality Gate Blur detection via Laplacian variance Threshold-based Orientation Rotation correction (0/90/180/270) Custom CNN (trained from scratch) Detection Document, face, text region detection YOLOv8 + heuristic fallback Classification Document type identification 3-step comparison (see below) OCR Field extraction from documents Tesseract (eng+ara) + CLAHE preprocessing MRZ Parsing Machine Readable Zone extraction Regex-based TD1/TD3 parser Face Matching Document photo vs selfie comparison FaceNet (InceptionResnetV1) Liveness Anti-spoofing (4 methods explored) Optical Flow (pipeline) + 3 experimental Interpretability Model decision visualization Grad-CAM heatmaps Final Submission Instructions: Model Files: The trained models ( best_scratch.pt , best_resnet18.pt , best_resnet18_ft.pt ) are located in the checkpoints/ directory. These are generated deterministically and are included in the submission. Reproducibility: You do not need to download a zip of the dataset. Simply run just prepare-data , and the pipeline will automatically fetch the real passport images from HuggingFace, driving licenses from GitHub, and augment local templates. After that, running just train will train the models and just evaluate will perfectly reproduce the reported metrics within ±0% (thanks to strict deterministic seeding). Constraints & Restrictions: Language: OCR is currently constrained to English ( eng ). Input Format: Images should be standard formats ( .jpg , .png ). For Liveness (Optical Flow), a short 2-3 second video is required. If only a single selfie frame is provided, the pipeline falls back to an instruction-based heuristic. 3-Step Training Comparison Following the standard methodology for DL with Limited Data , the classifier is trained using a 3-step comparison: Step Model Strategy Expected Outcome 1 SimpleDocumentClassifier (5-layer CNN) Train from scratch, no augmentation Struggles — small data not enough 2 ResNet-18 (frozen backbone) Transfer learning, no augmentation Overfits — high train acc, low test acc 3 ResNet-18 (layer3+4 unfrozen) Fine-tuning + document-safe augmentation Best results — correct approach Document-Safe Augmentations No horizontal/vertical flips (text would be mirrored). Instead: RandomRotation(8) — documents can be slightly tilted RandomResizedCrop(224, scale=(0.9, 1.0)) — zoom variation ColorJitter(brightness=0.15, contrast=0.15) — lighting variation Six augmentation levels are available: none , basic , intermediate , intermediate_gentle (default), advanced , advanced_gentle . Training Data Training uses real document images from multiple public sources (no synthetic data): Source Class Description HuggingFace ( akashsalmuthe/ind_passport ) passport Real Indian passport images GitHub ( iAmmarTahir/MASK-RCNN-Dataset ) passport Additional real passport images Local templates (augmented) emirates_id 3 real UAE Emirates IDs → 40+ augmented GitHub ( BangladeshiATM/Driving-License-Dataset ) driver_license Real driving license images - descoped You can also place your own images in data/raw/{emirates_id,passport,driver_license}/ for additional training data. Split: 70% train / 15% val / 15% test (deterministic seed = 42) Liveness Detection — 4 Methods Explored Method Type Input In Pipeline Trained Anti-Spoofing CNN ResNet-18 fine-tuned on NUAA Single frame No (dataset unavailable) Optical Flow (Farneback) Micro-movement analysis 2-3s video Yes (Primary) Instruction-Based Haar cascade challenge-response Single frame Yes (Fallback) rPPG Pulse Detection Green channel FFT 3-5s video No (demo only) Design Decision: While a trained anti-spoofing CNN would be ideal, the required NUAA dataset was unavailable. Therefore, we integrated Dense Optical Flow as the primary video-based liveness detector because it requires no training and effectively detects static screen/print attacks. We use a Haar cascade challenge-response heuristic as a fallback when only a single selfie frame is available. Quick Start # 1. Install dependencies just install # 2. Prepare real training data (auto-fetches from HuggingFace + GitHub) just prepare-data # 3. Train all 3 models (3-step comparison) just train # 4. Evaluate on test set (confusion matrices, comparison charts) just evaluate # 5. Launch the Gradio web UI just ui just interpret # Generate Grad-CAM visualizations just tensorboard # Launch TensorBoard (port 6006) just compare # Run evaluation and immediately open comparison charts Individual Training Steps just train-scratch # Step 1: CNN from scratch just train-tl # Step 2: Frozen ResNet-18 just train-ft # Step 3: Fine-tuned ResNet-18 + augmentation Liveness Training - Descoped just prepare-liveness # Prepare anti-spoofing data just train-liveness # Train liveness CNN (3-step comparison) just demo image_path=path/to/document.jpg # CLI demo just test # Run 37 unit tests just full-pipeline # Everything end-to-end Project Structure KYC_DL_SUNDARA/ ├── pyproject.toml # Dependencies (uv sync) ├── justfile # Task automation ├── .env.example # Environment variables template ├── README.md │ ├── src/ │ ├── config.py # Pydantic Settings (single source of truth) │ ├── pipeline.py # Unified pipeline orchestrator │ ├── ocr_engine.py # OCR with Emirates ID support + MRZ parsing │ ├── train.py # 3-step training comparison + TensorBoard │ ├── train_liveness.py # Liveness CNN training (3-step) │ ├── evaluate.py # Confusion matrix + comparison metrics │ ├── interpretability.py # Grad-CAM visualization │ ├── demo.py # CLI demo │ ├── app.py # Gradio UI (VIZ, NORM, MRZ, VERIF, JSON + LIVENESS) │ │ │ ├── models/ │ │ ├── classifier.py # SimpleDocumentClassifier + ResNet18Classifier (3 modes) │ │ ├── orientation.py # OrientationCNN (from scratch) │ │ ├── detector.py # YOLOv8 wrapper + heuristic fallback │ │ ├── face_matcher.py # FaceNet face matching │ │ └── liveness.py # 4 liveness methods (trained CNN + optical flow + instruction + rPPG) │ │ │ ├── data/ │ │ ├── prepare_real_data.py # Multi-source data download + preparation │ │ ├── dataset.py # PyTorch Dataset + DataLoader factory │ │ └── transforms.py # 6 augmentation levels (document-safe) │ │ │ ├── schemas/ │ │ └── contracts.py # Pydantic v2 data contracts │ │ │ └── utils/ │ ├── logger.py # Loguru structured logging │ └── helpers.py # Seed, device, directory utilities │ ├── tests/ │ ├── test_models.py # Model creation + freeze/unfreeze tests │ ├── test_contracts.py # Pydantic schema tests │ └── test_ocr.py # OCR engine tests │ ├── data/ │ ├── raw/ # Raw images (auto-fetched + manual) │ │ └── emirates_id_templates/ # Your real Emirates ID images │ ├── processed/ # Train/val/test splits (auto-generated) │ └── test_samples/ # Sample images for demo │ ├── checkpoints/ # Saved model weights ├── outputs/ # Evaluation results, plots, JSON ├── runs/ # TensorBoard logs ├── logs/ # Loguru log files └── docs/ # Reports and documentation Outputs After training and evaluation, the outputs/ directory contains: File Description training_curves_scratch.png Step 1 loss/accuracy curves training_curves_resnet18.png Step 2 loss/accuracy curves training_curves_resnet18_ft.png Step 3 loss/accuracy curves comparison_3step.png Side-by-side accuracy comparison confusion_matrix_scratch.png Step 1 confusion matrix confusion_matrix_resnet18.png Step 2 confusion matrix confusion_matrix_resnet18_ft.png Step 3 confusion matrix evaluation_comparison.png Bar chart comparing all metrics evaluation_comparison.json Full metrics in JSON interpretability/ Grad-CAM heatmaps Design Decisions No hardcoded values — all parameters flow through src/config.py (Pydantic Settings) Real training data — HuggingFace passports + GitHub driver licenses + augmented Emirates ID templates Document-safe augmentations — no flips, gentle rotations only Per-model checkpoints — best_scratch.pt , best_resnet18.pt , best_resnet18_ft.pt Hybrid classification — CNN + OCR pattern detection with confidence-based arbitration Structured logging — Loguru replaces all print() statements Typed contracts — all data flows through Pydantic v2 models Reproducibility — deterministic seed, fixed splits, saved training history TensorBoard integration — training metrics, activation stats, gradient flow Grad-CAM interpretability — visualize what the CNN looks at CosineAnnealingWarmRestarts — advanced LR scheduler Configuration All settings are in src/config.py and can be overridden via .env file: LEARNING_RATE = 0.001 BATCH_SIZE = 32 NUM_EPOCHS = 10 AUGMENTATION_LEVEL = intermediate_gentle IMAGE_SIZE = 224 RANDOM_SEED = 42 Requirements Python >= 3.13 uv for dependency management just for task automation Tesseract OCR ( brew install tesseract on macOS) Author Sundara Moorthy Jeyaprakash — MBZUAI
Following the standard methodology for DL with Limited Data , the classifier is trained using a 3-step comparison:
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Six augmentation levels are available: none , basic , intermediate , intermediate_gentle (default), advanced , advanced_gentle .
You can also place your own images in data/raw/{emirates_id,passport,driver_license}/ for additional training data.
Design Decision: While a trained anti-spoofing CNN would be ideal, the required NUAA dataset was unavailable. Therefore, we integrated Dense Optical Flow as the primary video-based liveness detector because it requires no training and effectively detects static screen/print attacks. We use a Haar cascade challenge-response heuristic as a fallback when only a single selfie frame is available.
# 1. Install dependencies just install # 2. Prepare real training data (auto-fetches from HuggingFace + GitHub) just prepare-data # 3. Train all 3 models (3-step comparison) just train # 4. Evaluate on test set (confusion matrices, comparison charts) just evaluate # 5. Launch the Gradio web UI just ui just interpret # Generate Grad-CAM visualizations just tensorboard # Launch TensorBoard (port 6006) just compare # Run evaluation and immediately open comparison charts
just train-scratch # Step 1: CNN from scratch just train-tl # Step 2: Frozen ResNet-18 just train-ft # Step 3: Fine-tuned ResNet-18 + augmentation
just prepare-liveness # Prepare anti-spoofing data just train-liveness # Train liveness CNN (3-step comparison) just demo image_path=path/to/document.jpg # CLI demo just test # Run 37 unit tests just full-pipeline # Everything end-to-end
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)