Complete Technical Paper Content — Ai Learning Path Recommendation
1. Executive Abstract, Problem Formulation & Background
🎓 Learning Path Recommendation System A Machine Learning-based recommendation system that suggests personalized learning courses and generates structured learning paths for interns using Collaborative Filtering and Matrix Factorization (Truncated SVD) . 📌 Project Overview This project analyzes intern-course interaction data and predicts which courses an intern is most likely to prefer based on historical learning patterns. The system also creates intelligent learning paths by organizing recommended courses according to: Difficulty progression Course duration The project includes: Recommendation Engine Learning Path Generator Streamlit Web Application Matrix Factorization Model 🚀 Features Personalized course recommendations Learning path generation Collaborative filtering Matrix factorization using Truncated SVD Difficulty-based filtering Category-based filtering Interactive Streamlit dashboard Scalable object-oriented architecture 🧠 Machine Learning Technique This project uses: Collaborative Filtering with: Matrix Factorization (Truncated SVD) The interaction matrix is decomposed into latent factors: [ R \approx P Q^T ] Where: (R) = Intern-Course Interaction Matrix (P) = Intern Latent Features (Q) = Course Latent Features The model learns hidden learning patterns such as: AI/ML interests Web development preferences Beginner vs advanced learner behavior 📂 Dataset Structure 1. Course Metadata Dataset course_metadata.csv Example course_id title category difficulty duration_hours C001 Python Basics AI/ML Beginner 20 2. Intern Ratings Dataset intern_ratings.csv Example intern_id course_id rating 1 C001 5 🛠️ Technologies Used Technology Purpose Python Programming Language Pandas Data Processing NumPy Numerical Computation Scikit-learn Machine Learning Streamlit Web Application TruncatedSVD Matrix Factorization 📦 Installation Install required libraries: pip install pandas numpy scikit-learn streamlit ▶️ Run the Streamlit App streamlit run streamlit_app.py 📖 Usage Step 1 — Upload Datasets Upload: course_metadata.csv intern_ratings.csv through the Streamlit sidebar. Step 2 — Select Recommendation Settings Choose: Intern ID Number of recommendations Difficulty filter Category filter Learning path strategy Step 3 — Generate Recommendations The system predicts personalized courses for the selected intern. Step 4 — Generate Learning Path The system creates an ordered learning sequence. 🛤️ Learning Path Strategies 1. Difficulty Ascending Orders courses as: Beginner → Intermediate → Advanced 2. Shortest First Orders courses by: Lowest duration → Highest duration 📊 Example Output course_id title category difficulty predicted_score C003 Deep Learning AI/ML Advanced 0.94 C021 AWS Cloud Cloud Intermediate 0.91 🔮 Future Improvements Hybrid Recommendation Systems Deep Learning Recommendation Models Real-time Recommendation Updates Course Completion Tracking User Authentication Web Deployment Content-Based Filtering Reinforcement Learning 🌍 Applications This project can be used in: E-learning platforms Internship programs Corporate training systems Personalized education platforms Online academies ✅ Conclusion This project demonstrates how Machine Learning and Collaborative Filtering can be used to build personalized educational recommendation systems. The recommendation engine intelligently predicts intern interests and generates structured learning paths using Matrix Factorization and latent feature learning. The project also demonstrates: Recommendation Systems Matrix Factorization Object-Oriented Programming Data Processing Scalable ML Architecture Interactive ML Applications
A Machine Learning-based recommendation system that suggests personalized learning courses and generates structured learning paths for interns using Collaborative Filtering and Matrix Factorization (Truncated SVD) .
This project analyzes intern-course interaction data and predicts which courses an intern is most likely to prefer based on historical learning patterns.
The system also creates intelligent learning paths by organizing recommended courses according to:
This project demonstrates how Machine Learning and Collaborative Filtering can be used to build personalized educational recommendation systems.
The recommendation engine intelligently predicts intern interests and generates structured learning paths using Matrix Factorization and latent feature learning.
AI Learning Path Recommendation System Personalized Learning Path Recommendation for Learners An AI-powered learning path recommendation system that analyzes learner-module interaction patterns and recommends suitable next learning modules. The system is built using the Open University Learning Analytics Dataset (OULAD) and combines sequential module-transition patterns with collaborative filtering to generate personalized learning recommendations. 1. Project Objective The objective of this project is to build a recommendation system capable of suggesting personalized learning modules based on historical learner behavior. The system analyzes: Learner-module interactions Learning activity Assessment performance Module enrollment patterns Previous module sequences Collaborative learning behavior The final system combines transition-based recommendation with collaborative filtering to generate a personalized learning path. 2. Dataset This project uses the Open University Learning Analytics Dataset (OULAD). The raw dataset contains seven primary CSV files: assessments.csv courses.csv studentAssessment.csv studentInfo.csv studentRegistration.csv studentVle.csv vle.csv These datasets were mapped through learner, module, presentation, assessment, and VLE interaction relationships. 3. Data Architecture The major relationships used in the preprocessing pipeline are: studentInfo | | id_student v studentRegistration | | id_student + id_site v studentVle | | id_site v vle | | code_module + code_presentation v courses Assessment information is connected through: studentInfo | | id_student v studentAssessment | | id_assessment v assessments The resulting information is aggregated into learner-module interaction records. 4. Final Dataset After preprocessing: Learners: 26,074 Modules: 7 Learner-module interaction records: 29,228 Final feature columns: 17 The processed dataset is stored at: data/processed/learner_module_interactions.csv 5. Main Features The final recommendation dataset contains information including: learner_id module_id presentation_id total_clicks average_score assessment_count interaction_score date_registration date_unregistration gender region highest_education age_band num_of_prev_attempts studied_credits final_result module_duration_days 6. Recommendation Pipeline The complete pipeline is: Raw OULAD Data ↓ Data Validation ↓ Data Preprocessing ↓ Learner-Module Interaction Dataset ↓ Learner × Module Matrix ↓ Collaborative Filtering ↓ Matrix Factorization ↓ Transition Model ↓ Final 80/20 Recommendation Model ↓ Evaluation ↓ Interactive Streamlit Application 7. Collaborative Filtering Collaborative filtering is used to identify relationships between learners and learning modules. A learner-module interaction matrix is constructed from historical interaction scores. The collaborative filtering component uses matrix factorization to represent learner-module interactions in a lower-dimensional latent space. Matrix Factorization Results Learners used for CF: 2,151 Modules: 7 Latent dimensions: 3 Reconstruction RMSE: 0.1330 8. Transition Recommendation The transition model analyzes historical module sequences. For learners who studied multiple modules, the system calculates how frequently one module follows another. For example: CCC → EEE CCC → DDD CCC → FFF The transition probabilities are then used to estimate the learner's most likely next module. 9. Final Recommendation Model The final recommendation system combines: Transition model: 80% Collaborative filtering: 20% The final score is calculated as: Final Score = 0.80 × Transition Score + 0.20 × Collaborative Filtering Score This model was selected based on the final validation results. 10. Model Evaluation A leave-one-out evaluation strategy was used to evaluate the recommendation models. The main ranking metrics were: Precision@K Recall@K NDCG@K Final Model Results Metric Final 80/20 Model Precision@1 0.4550 Recall@1 0.4550 NDCG@1 0.4550 Precision@3 0.2225 Recall@3 0.6674 NDCG@3 0.5756 Precision@5 0.1358 Recall@5 0.6792 NDCG@5 0.5802 Comparison With Transition Model Model Precision@5 Recall@5 NDCG@5 Transition 0.1354 0.6771 0.5775 Final 80/20 0.1358 0.6792 0.5802 The Final 80/20 model achieved the highest NDCG@5 among the evaluated final models and was therefore selected as the final validated model. 11. Interactive Application The project includes an interactive Streamlit application. The application allows a user to: Select a learner ID. View the learner's previous modules. Generate personalized recommendations. View recommended modules ranked by final score. Inspect transition and collaborative-filtering scores. View the generated learning path. 12. Running the Project Step 1 — Install Python Python 3.11 is recommended for this project environment. Step 2 — Install Dependencies python -m pip install -r requirements.txt
An AI-powered learning path recommendation system that analyzes learner-module interaction patterns and recommends suitable next learning modules.
The system is built using the Open University Learning Analytics Dataset (OULAD) and combines sequential module-transition patterns with collaborative filtering to generate personalized learning recommendations.
The objective of this project is to build a recommendation system capable of suggesting personalized learning modules based on historical learner behavior.
The final system combines transition-based recommendation with collaborative filtering to generate a personalized learning path.
These datasets were mapped through learner, module, presentation, assessment, and VLE interaction relationships.
studentInfo | | id_student v studentRegistration | | id_student + id_site v studentVle | | id_site v vle | | code_module + code_presentation v courses
Raw OULAD Data ↓ Data Validation ↓ Data Preprocessing ↓ Learner-Module Interaction Dataset ↓ Learner × Module Matrix ↓ Collaborative Filtering ↓ Matrix Factorization ↓ Transition Model ↓ Final 80/20 Recommendation Model ↓ Evaluation ↓ Interactive Streamlit Application
Collaborative filtering is used to identify relationships between learners and learning modules.
A learner-module interaction matrix is constructed from historical interaction scores.
The collaborative filtering component uses matrix factorization to represent learner-module interactions in a lower-dimensional latent space.
For learners who studied multiple modules, the system calculates how frequently one module follows another.
The transition probabilities are then used to estimate the learner's most likely next module.
The Final 80/20 model achieved the highest NDCG@5 among the evaluated final models and was therefore selected as the final validated model.
AI-powered personalized learning path recommendation system using OULAD data, transition modeling, collaborative filtering, and machine learning evaluation.
This is an incomplete, ever-changing curated list of content to assist people into the worlds of Data Science and Machine Learning. If you have a recommendation for something to add, please let me know. If something isn't here, it doesn't mean I don't recommend it, I just may not have had a chance to review it yet or not. I will generally list things in order of easier to more formal/challenging content. It may feel like there is an overwhelming amount of stuff for you to learn (because there is). But, there is a guided path that will get you there in time. You need to focus on Linear Algebra, Calculus, Statistics and probably Python (or R). Your best bet is to get a Safari Books Online account ( https://www.safaribooksonline.com ) which you may already have access to through school or work. If not, it is a reasonable way to get access to a tremendous number of books and videos. I'm not saying you will get what you need out of everything here, but I have read/watched at least some of all of the following and have found them useful. Use your brain, the more expensive books are going to be more formal/academic. The O'Reilly books will be more developer friendly. Some of the self-published Kindle books are of varying quality but may still have some interesting examples (and are usually very cheap or free through Kindle Unlimited). New to Everything If you are completely new to everything, then you will need to start with some math and programming basics. Books: Review your Algebra and Trigonometry: https://www.amazon.com/Algebra-Trigonometry-Prepare-Calculus-College/dp/1523959614 Calculus: https://www.amazon.com/Calculus-Intuitive-Physical-Approach-Mathematics-ebook/dp/B00CB2MK6C Linear Algebra: https://www.amazon.com/Linear-Algebra-Step-Kuldeep-Singh/dp/0199654441 Courses: Videos: 3Blue1Brown: Essence of Linear Algebra https://www.youtube.com/playlist?list=PLZHQObOWTQDPD3MizzM2xVFitgF8hE_ab 3Blue1Brown: Essence of Calculus https://www.youtube.com/playlist?list=PLZHQObOWTQDMsr9K-rj53DwVRMYO3t5Yr https://ocw.mit.edu/resources/res-18-006-calculus-revisited-single-variable-calculus-fall-2010/ https://ocw.mit.edu/resources/res-18-007-calculus-revisited-multivariable-calculus-fall-2011/ https://ocw.mit.edu/resources/res-18-008-calculus-revisited-complex-variables-differential-equations-and-linear-algebra-fall-2011/ https://ocw.mit.edu/courses/mathematics/18-065-matrix-methods-in-data-analysis-signal-processing-and-machine-learning-spring-2018/video-lectures/ Sites: Learn Python: http://www.learnpython.org David Beazley's Excellent Python Tutorials: https://dabeaz-course.github.io/practical-python/ Google's Python class: https://developers.google.com/edu/python/ Learn R: http://tryr.codeschool.com Self-directed R tutorial: https://cran.r-project.org/doc/manuals/r-release/R-intro.html https://openstax.org/subjects/math New to Statistics Books: https://www.amazon.com/Practical-Statistics-Data-Scientists-Essential/dp/1491952962 http://www.greenteapress.com/thinkstats/ https://www.amazon.com/Seven-Pillars-Statistical-Wisdom/dp/0674088913 https://www.amazon.com/Hypothesis-Testing-Introduction-Statistical-Significance-ebook/dp/B019N212NE https://www.amazon.com/Introductory-Statistics-R-Computing/dp/0387790535 http://www-bcf.usc.edu/~gareth/ISL/ https://www.amazon.com/Computer-Age-Statistical-Inference-Mathematical/dp/1107149894 https://www.amazon.com/Elements-Statistical-Learning-Prediction-Statistics/dp/0387848576 http://www.dartmouth.edu/~chance/teaching_aids/books_articles/probability_book/amsbook.mac.pdf https://web.stanford.edu/~hastie/ElemStatLearn/ Sites: https://www.openintro.org Courses: https://lagunita.stanford.edu/courses/HumanitiesSciences/StatLearning/Winter2016/about https://www.probabilitycourse.com New to Data Science Books: https://www.amazon.com/Bad-Data-Handbook-Cleaning-Back/dp/1449321887 https://www.amazon.com/Python-Data-Analysis-Wrangling-IPython/dp/1491957662 https://www.amazon.com/Doing-Data-Science-Straight-Frontline/dp/1449358659 https://www.amazon.com/Data-Science-Scratch-Principles-Python/dp/149190142X https://jakevdp.github.io/PythonDataScienceHandbook/ https://www.amazon.com/Data-Science-Mindset-Methodologies-Misconceptions-ebook/dp/B074R7HL2W Courses: https://www.lynda.com/Python-tutorials/Python-Data-Science-Essential-Training/520233-2.html New to Machine Learning Books: https://www.amazon.com/Introduction-Machine-Learning-Python-Scientists/dp/1449369413 https://www.amazon.com/Machine-Learning-Hackers-Studies-Algorithms/dp/1449303714 https://www.amazon.com/Hands-Machine-Learning-Scikit-Learn-TensorFlow/dp/1491962291 https://www.amazon.com/Bayesian-Methods-Hackers-Probabilistic-Addison-Wesley/dp/0133902838 https://www.amazon.com/Think-Bayes-Bayesian-Statistics-Python/dp/1449370780 https://www.amazon.com/Understanding-Machine-Learning-Theory-Algorithms/dp/1107057132 Courses: https://github.com/dair-ai/ML-YouTube-Courses https://github.com/jakevdp/sklearn_tutorial https://developers.google.com/machine-learning/crash-course/ https://machinelearningmastery.com Videos: http://www.3blue1brown.com/videos/2017/10/9/neural-network https://github.com/dair-ai/ML-YouTube-Courses New to Deep Learning Approach to Grokking Deep Learning https://blog.paperspace.com/a-practical-guide-to-deep-learning-in-6-months/ Books: https://www.amazon.com/Deep-Learning-Illustrated-Intelligence-Addison-Wesley/dp/0135116694/ https://www.manning.com/books/deep-learning-with-python https://www.manning.com/books/deep-learning-with-javascript https://www.amazon.com/Deep-Learning-Adaptive-Computation-Machine-ebook/dp/B01MRVFGX4 Classes: https://atcold.github.io/pytorch-Deep-Learning/ https://www.fast.ai Sites: https://d2l.ai/chapter_appendix-mathematics-for-deep-learning/index.html http://neuralnetworksanddeeplearning.com http://www.deeplearningpatterns.com/doku.php?id=overview http://jalammar.github.io/visual-interactive-guide-basics-neural-networks/ https://jalammar.github.io/feedforward-neural-networks-visual-interactive/ Videos: https://sebastianraschka.com/blog/2021/dl-course.html https://www.youtube.com/watch?v=BR9h47Jtqyw New to Deep Reinforcement Learning Relevant Papers https://spinningup.openai.com/en/latest/spinningup/keypapers.html
2. Related Work, Literature Survey & Algorithmic Foundations
This is an incomplete, ever-changing curated list of content to assist people into the worlds of Data Science and Machine Learning. If you have a recommendation for something to add, please let me know. If something isn't here, it doesn't mean I don't recommend it, I just may not have had a chance to review it yet or not.
It may feel like there is an overwhelming amount of stuff for you to learn (because there is). But, there is a guided path that will get you there in time. You need to focus on Linear Algebra, Calculus, Statistics and probably Python (or R). Your best bet is to get a Safari Books Online account ( https://www.safaribooksonline.com ) which you may already have access to through school or work. If not, it is a reasonable way to get access to a tremendous number of books and videos.
I'm not saying you will get what you need out of everything here, but I have read/watched at least some of all of the following and have found them useful. Use your brain, the more expensive books are going to be more formal/academic. The O'Reilly books will be more developer friendly. Some of the self-published Kindle books are of varying quality but may still have some interesting examples (and are usually very cheap or free through Kindle Unlimited).
If you are completely new to everything, then you will need to start with some math and programming basics.
Review your Algebra and Trigonometry: https://www.amazon.com/Algebra-Trigonometry-Prepare-Calculus-College/dp/1523959614
Calculus: https://www.amazon.com/Calculus-Intuitive-Physical-Approach-Mathematics-ebook/dp/B00CB2MK6C
Linear Algebra: https://www.amazon.com/Linear-Algebra-Step-Kuldeep-Singh/dp/0199654441
3Blue1Brown: Essence of Linear Algebra https://www.youtube.com/playlist?list=PLZHQObOWTQDPD3MizzM2xVFitgF8hE_ab
3Blue1Brown: Essence of Calculus https://www.youtube.com/playlist?list=PLZHQObOWTQDMsr9K-rj53DwVRMYO3t5Yr
https://ocw.mit.edu/resources/res-18-006-calculus-revisited-single-variable-calculus-fall-2010/
https://ocw.mit.edu/resources/res-18-007-calculus-revisited-multivariable-calculus-fall-2011/
https://ocw.mit.edu/resources/res-18-008-calculus-revisited-complex-variables-differential-equations-and-linear-algebra-fall-2011/
https://ocw.mit.edu/courses/mathematics/18-065-matrix-methods-in-data-analysis-signal-processing-and-machine-learning-spring-2018/video-lectures/
David Beazley's Excellent Python Tutorials: https://dabeaz-course.github.io/practical-python/
Self-directed R tutorial: https://cran.r-project.org/doc/manuals/r-release/R-intro.html
https://www.amazon.com/Hypothesis-Testing-Introduction-Statistical-Significance-ebook/dp/B019N212NE
https://www.amazon.com/Elements-Statistical-Learning-Prediction-Statistics/dp/0387848576
http://www.dartmouth.edu/~chance/teaching_aids/books_articles/probability_book/amsbook.mac.pdf
https://lagunita.stanford.edu/courses/HumanitiesSciences/StatLearning/Winter2016/about
https://www.amazon.com/Data-Science-Mindset-Methodologies-Misconceptions-ebook/dp/B074R7HL2W
https://www.lynda.com/Python-tutorials/Python-Data-Science-Essential-Training/520233-2.html
https://www.amazon.com/Bayesian-Methods-Hackers-Probabilistic-Addison-Wesley/dp/0133902838
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
https://www.amazon.com/Deep-Learning-Illustrated-Intelligence-Addison-Wesley/dp/0135116694/
While admittedly near-adjacent, https://aischool.microsoft.com/ has served some folks well from a few field reports.
According to me the best podcasts for Machine Learning, Data Science and Statistics are:
On a local terminal, or a non-TTY local process that can still reach a browser (for example, a desktop OS, or Linux with a display or browser signal), the default authentication mode is a browser-based web flow: the CLI opens your browser to authorize, then captures the result on a local loopback callback. On a remote terminal (for example, SSH, GitHub Codespaces, or a dev container) or in CI, the CLI defaults to the OAuth device code flow instead, since the browser typically can't reach the loopback port. Use --web-flow or --device-code to override the automatically selected flow.
After completion, an authentication token is stored securely in the system credential store. If a credential store is not found, the token is stored in a plain text configuration file under ~/.copilot/ (or the directory specified by COPILOT_HOME if set).
Alternatively, Copilot CLI will use an authentication token found in environment variables. The following are checked in order of precedence: COPILOT_GITHUB_TOKEN , GH_TOKEN , GITHUB_TOKEN . This method is most suitable for headless use such as automation.
Supported token types include fine-grained personal access tokens (v2 PATs) with the "Copilot Requests" permission, OAuth tokens from the Copilot CLI app, and OAuth tokens from the GitHub CLI ( gh ) app. Classic personal access tokens ( ghp_ ) are not supported.
# Authenticate with github.com copilot login # Authenticate with GitHub Enterprise Cloud (data residency) copilot login --host https://example.ghe.com # Force the device code flow, for example on a remote terminal copilot login --device-code # Force the browser (web) flow, for example on a local terminal copilot login --web-flow # Read a token from standard input, bypassing the OAuth flow entirely copilot login --with-token < mytoken.txt # Use a fine-grained PAT via environment variable COPILOT_GITHUB_TOKEN=github_pat_... copilot
The command copilot completion SHELL outputs a script for the specified shell (bash, zsh, or fish).
By sourcing this script (or writing it to your shell's completion directory) you can enable tab completion in your terminal for copilot subcommands, command options, and known value choices for command options. For copilot config , completion also covers setting keys, boolean and enum values, and files or directories for path-valued settings.
Zsh — write the output to a directory on your $fpath. Restart the shell after running this command:
Use copilot plugin to install, list, update, enable, disable, and uninstall plugins from the command line, without opening an interactive session. copilot plugins (plural) is a legacy alias for the same command. For the full command and option reference, see GitHub Copilot CLI plugin reference .
Run copilot config to read and change Copilot settings from the command line, outside an interactive session. This is the non-interactive counterpart to the /settings (or /config ) slash command. For more information about the settings file and its keys, see GitHub Copilot CLI configuration directory .
# Print a setting copilot config theme # Set a nested value (dot notation) copilot config footer.showQuota off # Append an item to a list setting (added only if not already present) copilot config allowedUrls github.com # Append an item that starts with a dash copilot config powershellFlags -- -NoProfile # Remove a key, or one list item copilot config -- rm theme copilot config -- rm allowedUrls github.com # List settings as key=value lines, or as JSON copilot config --list copilot config --repo --list --json
Values must match the setting's type: on / off or true / false for booleans, a number for numeric settings, or an accepted choice for enums. Reading a list prints one item per line; reading a group prints JSON. An unset key exits with status 1 . Secret values are redacted from output.
Commands use your user settings file ( settings.json in ~/.copilot , or in $COPILOT_HOME when set) by default. --repo and --local accept only the settings a repository can override—see GitHub Copilot CLI configuration directory . Run copilot help config for the available settings.
Run copilot instruction list to non-interactively list custom instruction sources discovered for the current working directory. This replaces the retired copilot plugins list --kind instruction .
Each --json entry has the shape { id, label, description?, location, type, sourcePath, defaultDisabled, applyTo? } . This listing resolves plugin-contributed instructions against your global user settings only—an instruction enabled by a trusted repository or by managed settings might not appear here even though a live session applies it.
Run copilot lsp list to non-interactively list configured language servers. This replaces the retired copilot plugins list --kind lsp . This command is inspect-only; use the /lsp slash command in an interactive session to start, stop, or reload a language server.
Custom agents and session-scoped hooks aren't covered by copilot instruction , copilot lsp , copilot plugin , copilot mcp , or copilot skill . All require a live session.
Use copilot memories import to validate and import user-level preferences and repository-level facts from a JSONL file.
If any line fails schema validation, no records are submitted. After validation succeeds, records are submitted individually, so a service failure can result in a partial import. Check the per-record results and retry only failed records. The --on-conflict skip option skips duplicate IDs within the input file and conflicts reported by the memory service. It does not guarantee that repeating an import will avoid duplicate memories. For the file format and examples, see Manually creating memories for GitHub Copilot .
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Run a dynamic workflow provided by an extension, without opening an interactive session:
WORKFLOW-NAME is the name registered by the extension, not a path to an extension file. The command starts a run and waits for it to finish, pause, or otherwise stop.
Relative argument-file and result-file paths are resolved from the working directory. Without --silent , output includes phases and progress messages reported by the workflow.
The command uses the CLI's authentication, model, permission, and sandbox settings. Permission options such as --allow-tool and --allow-url apply to the workflow's agents. It does not display permission approval prompts.
Prompt and session-mode options cannot be combined with this command. Examples include -p , -i , --agent , --fleet , --autopilot , --resume , and --continue . Piped standard input is not used as a prompt or as workflow arguments.
For more information, see Using dynamic workflows and GitHub Copilot CLI programmatic reference .
Run copilot sandbox ca to manage the sandbox's proxy certificate authority from outside an interactive session—for example, when provisioning managed devices without a TTY. This mirrors the /sandbox ca slash commands ( create , trust , rotate , remove ), plus a status check.
copilot sandbox ca status copilot sandbox ca create copilot sandbox ca trust copilot sandbox ca rotate copilot sandbox ca remove
Run these commands as the user who runs Copilot CLI, not elevated, as SYSTEM , or as root , because the certificate authority is stored in that user's Copilot CLI home directory. Run copilot sandbox ca trust --help for unattended setup guidance. --config-dir (or COPILOT_HOME ) targets a non-default Copilot CLI home for these commands, the same as the rest of the CLI.
The sessions sidebar is a panel docked beside your current conversation that provides a quick way of working with your local GitHub Copilot CLI sessions.
The color names above are a guide. The exact shades depend on your terminal's color scheme and the theme you have set with /theme . For example, the github theme uses its own fixed colors, and the colorblind theme uses blue and yellow in place of green and red. On terminals without full color support, the dots use your terminal's own green, blue, and yellow.
The colors named above relate to the default chat mode. Plan mode and autopilot mode tint some dots differently. The session name's text color also changes in those modes. Because color can shift with your terminal, theme, and mode, the steady or pulsing shape and the ! , ? , and ○ markers are the most reliable cues.
Use the /settings sidebar slash command in an interactive CLI session to adjust these settings for the sessions sidebar.
For more information about the sessions sidebar, see Working with multiple GitHub Copilot CLI sessions .
In local sessions, you can queue prompts, shell commands, and supported slash commands to run in order after the current task finishes. Press Ctrl + Q to queue the current input while the agent is running. Queued entries display a "pending" label and can be canceled individually before they run.
With an empty prompt box, press ↑ to recall the most recently queued or steering prompt back into the prompt box for editing before it's resubmitted. A "recall" hint appears next to the queue when this is available. Use Ctrl + P instead for nondestructive navigation through submitted command history.
In a local session, pressing Esc twice on a submitted prompt whose turn the model hasn't started answering puts your prompt back in the prompt box and removes it from the conversation. If the model has already started answering, the same second Esc press instead interrupts the running turn. Afterward, with an empty prompt box, pressing ↑ restores the prompt to the prompt box.
Subagents that spawn their own nested subagents appear as an indented tree; the row you're teleported into is highlighted as "current." While drilled into a subagent's view, you can send it a steering message from the prompt box the same way you would the main session.
If a session was still open when its CLI process went away—for example, due to a crash or a machine restart—the next copilot startup can offer to restore it, letting you choose which sessions to bring back or start fresh instead. A session whose agent was mid-turn automatically resumes that work once restored.
This restore behavior is temporarily opt-in while its startup dialog is reworked. Set the COPILOT_ENABLE_INTERRUPTED_SESSION_RESTORE environment variable to 1 to enable it. See Environment variables .
Sessions already open in another window float to the top in all non-relevance sort modes. When no working-directory context is available, the relevance mode is skipped.
Before you send the first message in a new session, press Ctrl + E in an empty prompt box to choose where the conversation will run: on your local machine, or in a cloud environment. The environment is provisioned when you send your first message.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
The environment picker requires cloud sessions to be available on your account—the same requirement as the --remote , --no-remote , --remote-export , --no-remote-export , and --connect options. See Command-line options .
Once a conversation has started, Ctrl + E reverts to its other behaviors: moving the cursor to the end of the line while typing, or expanding all items in the timeline on an empty prompt box. See Navigation shortcuts in the interactive interface and Timeline shortcuts in the interactive interface .
The current-session sidebar lets you browse and switch between sessions without leaving the one you're in. With an empty prompt box, ← / → walk a three-state focus cycle: closed, timeline-focused, and sidebar-focused. Disable the sidebar entirely with the sidebar setting—see GitHub Copilot CLI configuration directory .
The sidebar's divider can be dragged to resize it, and it auto-collapses below a minimum usable width. Each card shows a status dot, the session name, and its Git branch (or working directory when there is no branch). The foreground session's title is highlighted in accent color, and its card carries a persistent subtle fill.
Dots indicate a session's status. For what each dot means, see Session status indicators .
The active sort order ( recent , created , name , or none for insertion order) persists across restarts.
Mouse actions mirror the keyboard: click a card to switch the foreground session, double-click a card or empty rail space to focus the sidebar, and click the timeline pane while the sidebar is focused to return focus to it.
The Sessions tab lists the current session plus your full resumable session history under a "Resumable" divider:
Remote (cloud) rows in the Sessions tab also show online or offline status and the repository.
Pressing x twice on a row closes a running session or, for a local resumable row, permanently deletes that session's stored history. Pressing Esc , pressing any other key, moving the highlight, or a timeout cancels the pending confirmation.
These are the slash commands you can use from within an interactive CLI session. A subset of these slash commands is available to clients that use the CLI via its ACP server. For more information, see Copilot CLI ACP server .
For a complete list of available slash commands enter /help in the CLI's interactive interface.
In the schedule manager opened by a bare /every or /after , use ↑ / ↓ to select an entry and x to remove it. Schedules can only be added from the prompt input using /every or /after with arguments—the dialog itself is read-and-remove only.
The footer shows an "N scheduled" indicator by default whenever the session has active schedules, even if /every and /after are not enabled for you.
/plugin flags an installed plugin or marketplace when a newer version is available upstream, and offers an Update action from the dashboard.
/mcp list / ls and /plugin list / ls (including bare /plugin ) are read-only and can run while the agent is busy processing a turn. All other /mcp and /plugin subcommands are blocked until the turn finishes.
The experimental /plugins command was removed. Its resources have been moved to /plugin , /mcp , and /skills . Use /subagents and /instructions for agents and instructions.
Use /collect-debug-logs [file|gist|share] [PATH] to gather debug logs for troubleshooting:
/collect-debug-logs share , and the feedback-with-logs route offered from /feedback , first save a local archive, then ask for fresh consent (defaulting to No ) before uploading it to GitHub. Uploading is currently available only to GitHub staff and internal users, and isn't generally available yet. Users outside GitHub continue to use the existing archive and gist routes, and the existing public feedback route.
Remote session features require availability on your account. The legacy --remote option is not an interactive-session control, and --no-remote is no longer supported.
To enable remote control during an interactive session, use /remote on . To end the remote connection, use /remote off .
If a session was still open when its CLI process went away, for example due to a crash or a machine restart, the next time you start copilot you're offered the option to restore it. You can review the sessions available to restore or start a fresh session instead. A restored session whose agent was mid-turn automatically resumes that work.
Model Figures & Evaluation Curves (4 Images)
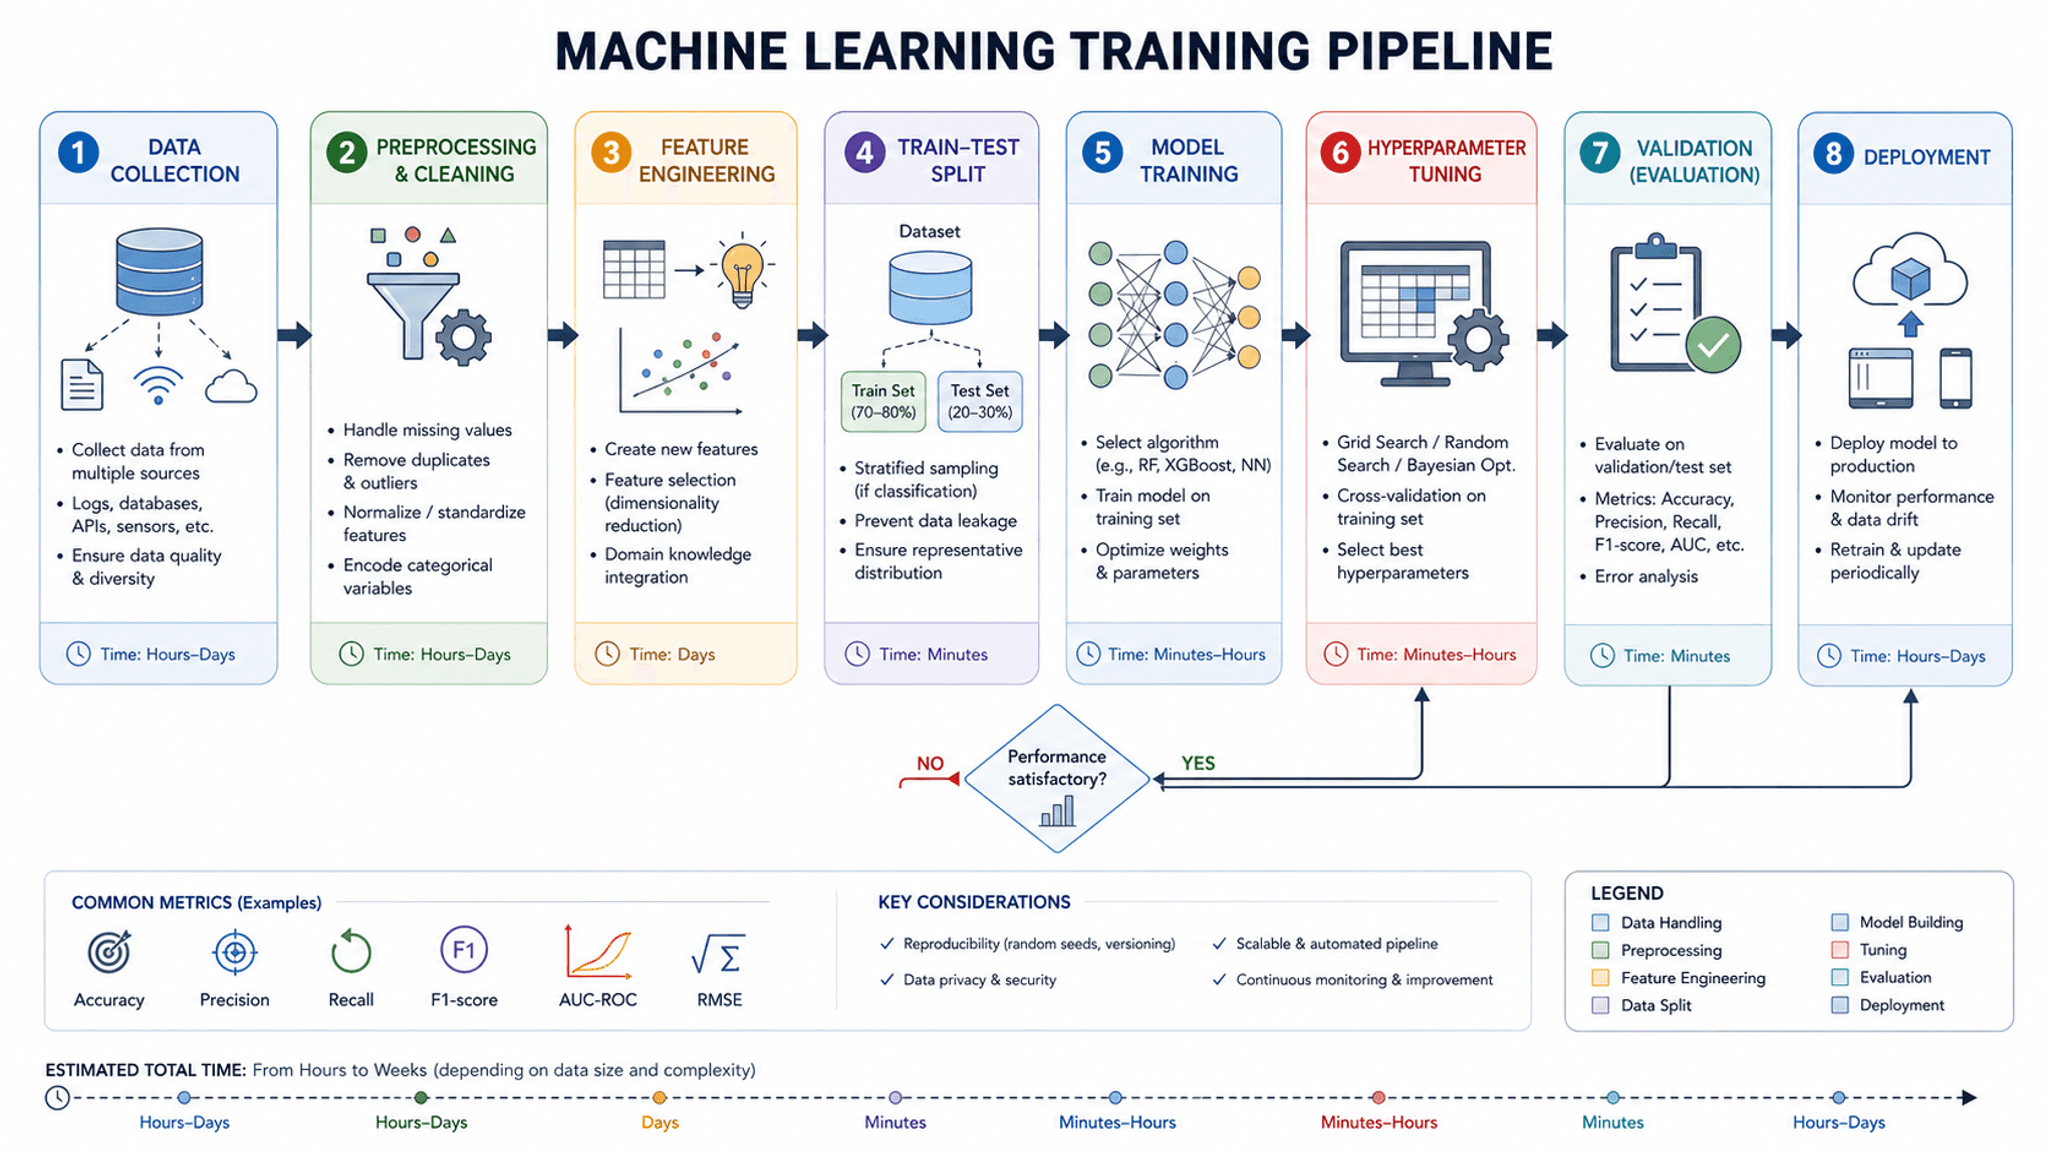
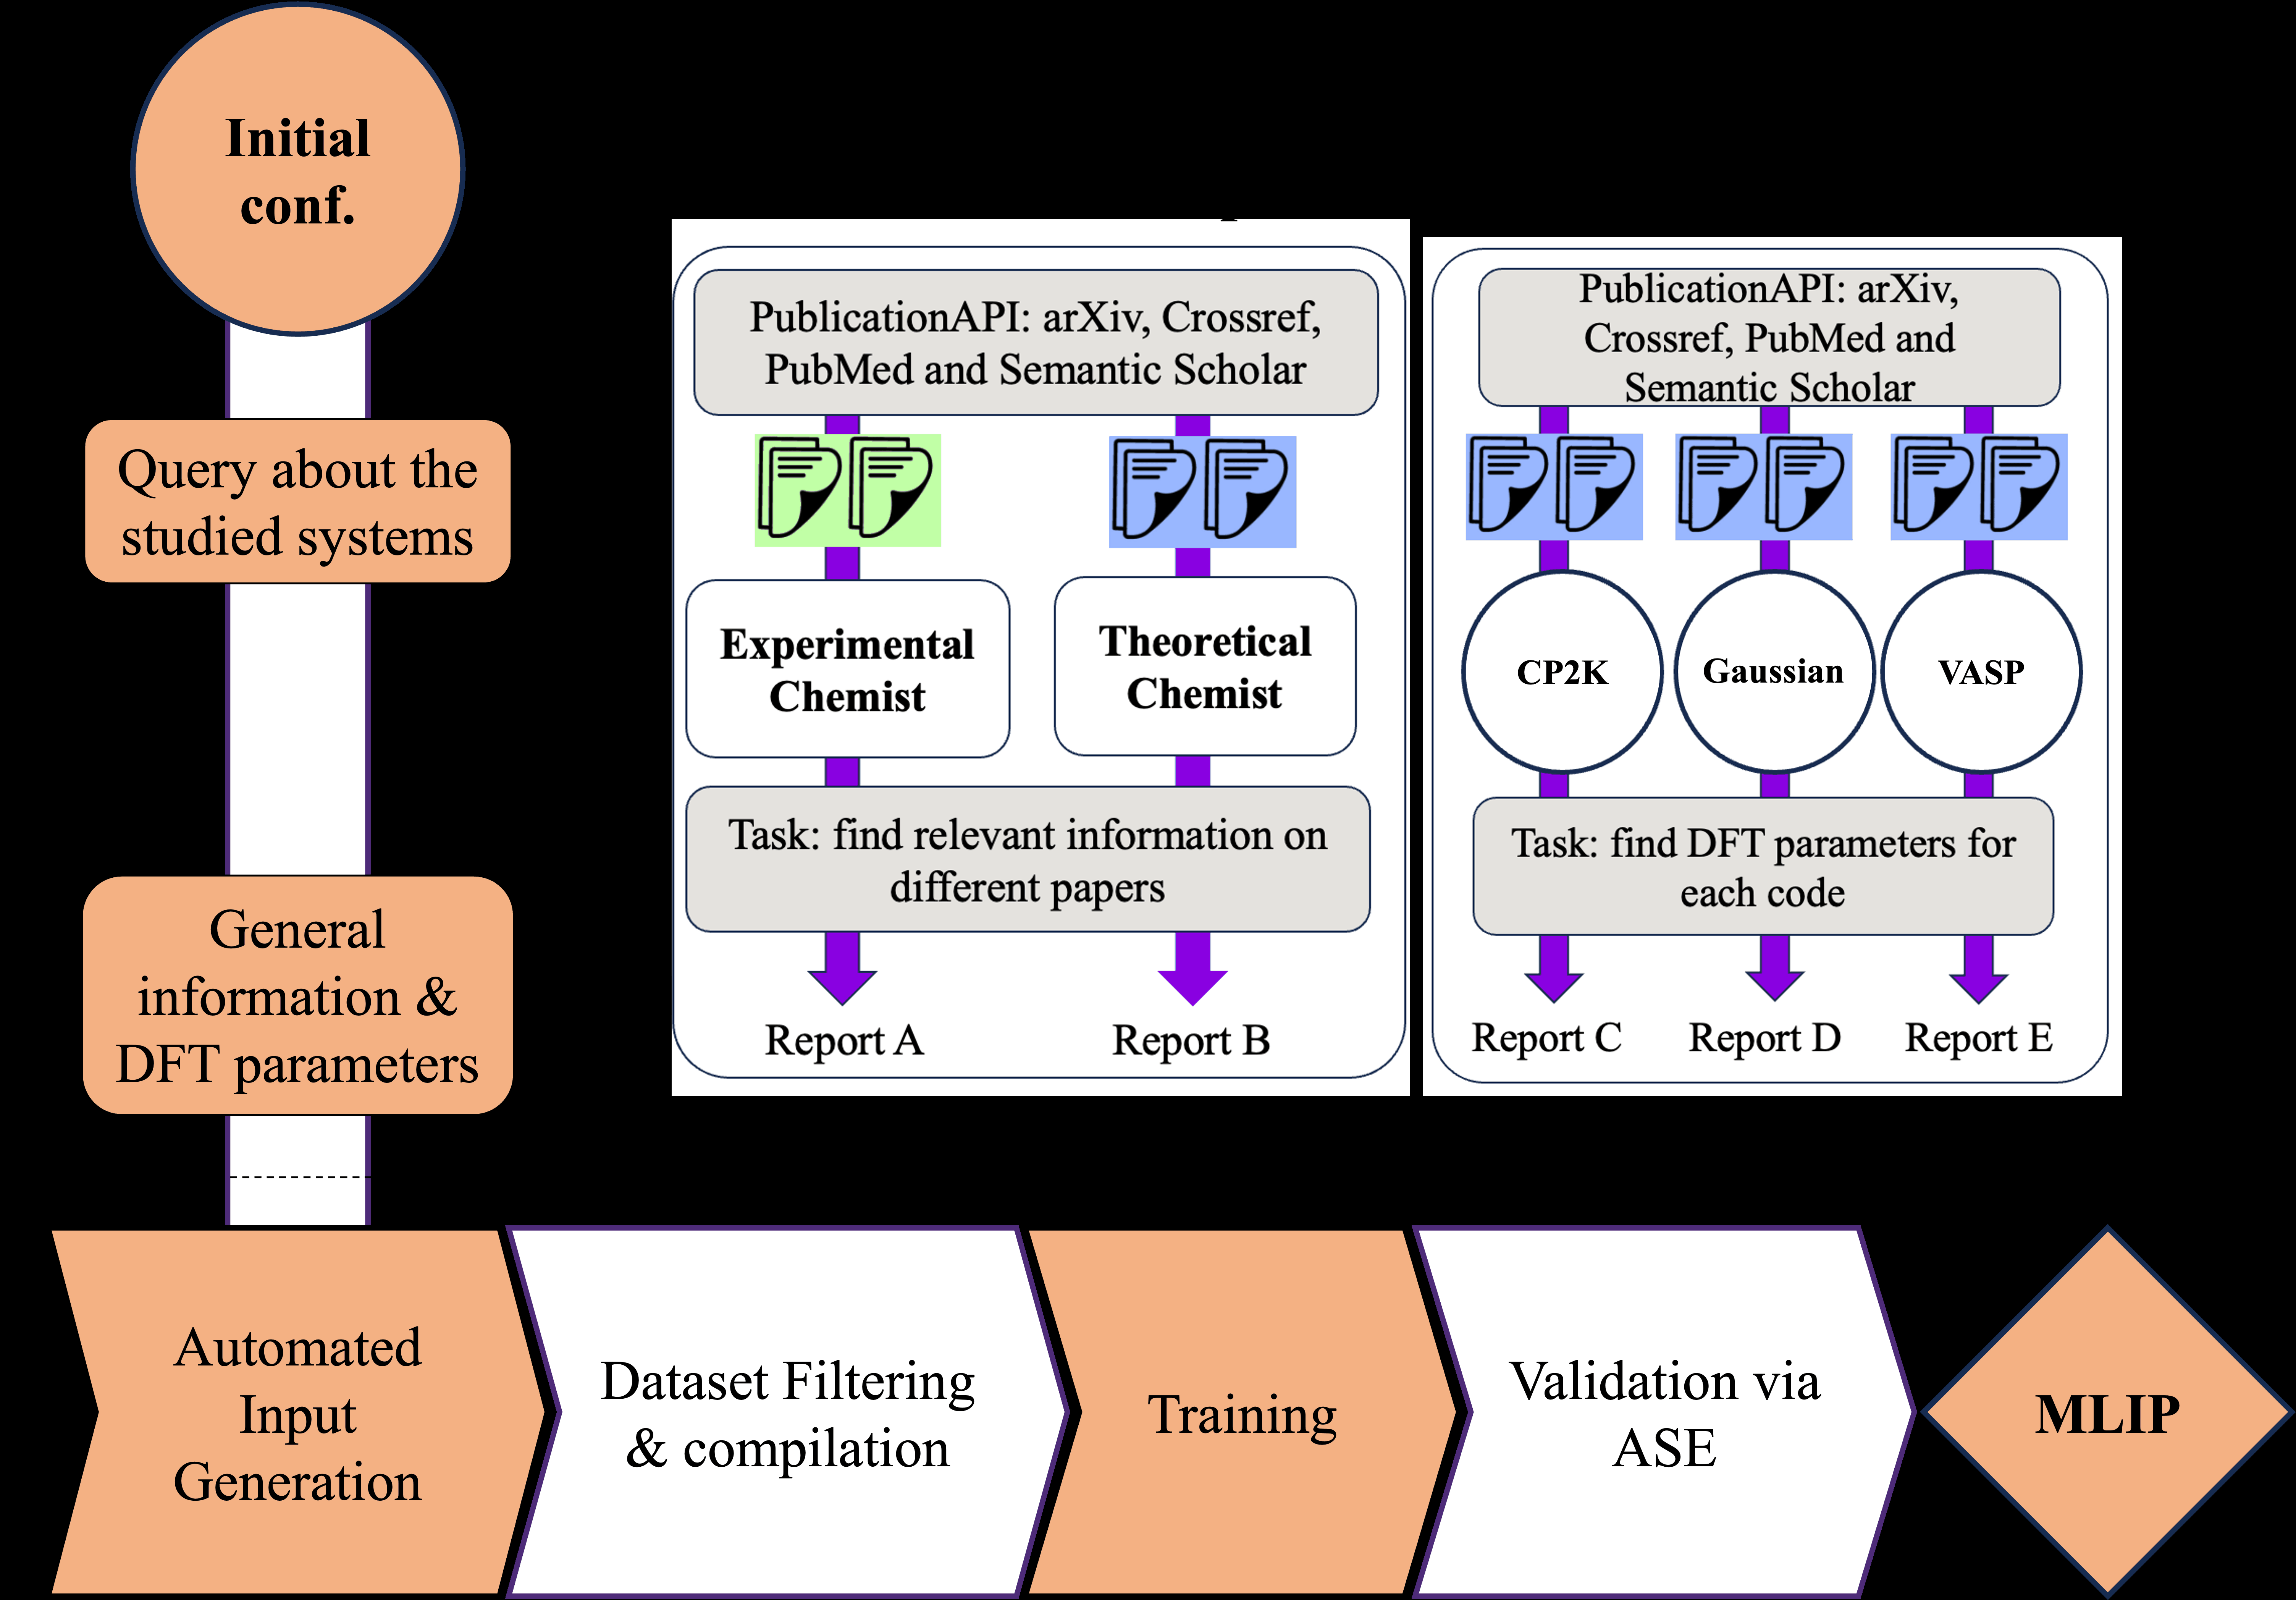
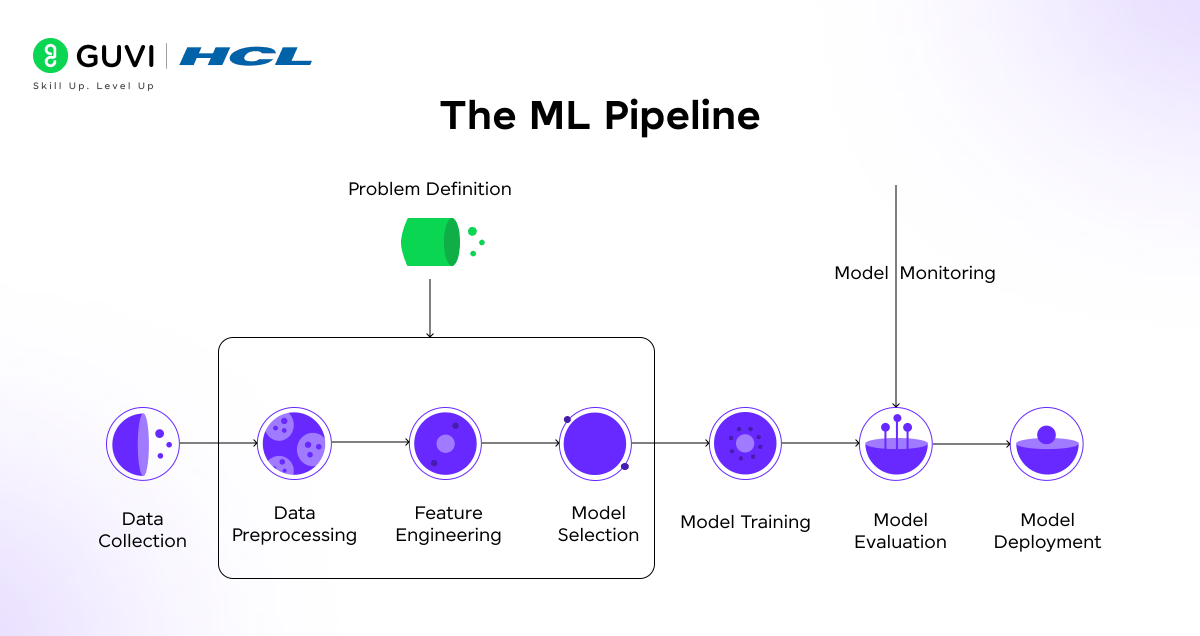
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)