Complete Technical Paper Content — Ai Safety Projects
1. Executive Abstract, Problem Formulation & Background
AI safety is an interdisciplinary field focused on preventing accidents, misuse, or other harmful consequences arising from artificial intelligence systems. It encompasses AI alignment (which aims to ensure AI systems behave as intended) as well as monitoring AI systems for risks and enhancing their robustness. The field is particularly concerned with existential risks posed by advanced AI models. Beyond technical research, AI safety involves developing norms and policies that promote safety, including advocacy for regulations at different levels of government. The field gained significant popularity in 2023, with rapid progress in generative AI and public concerns voiced by researchers and CEOs about potential dangers. During the 2023 AI Safety Summit, the United States and the United Kingdom each established their own AI Safety Institute (AISI). However, researchers have expressed concern that AI safety measures are not keeping pace with the rapid development of AI capabilities.
Some have criticized concerns about AGI, such as Andrew Ng who compared them in 2015 to "worrying about overpopulation on Mars when we have not even set foot on the planet yet". Stuart J. Russell on the other side urges caution, arguing that "it is better to anticipate human ingenuity than to underestimate it". AI researchers have widely differing opinions about the severity and primary sources of risk posed by AI technology – though surveys suggest that experts take high consequence risks seriously. In two surveys of AI researchers, the median respondent was optimistic about AI overall, but placed a 5% probability on an "extremely bad (e.g. human extinction)" outcome of advanced AI. In a 2022 survey of the natural language processing community, 37% agreed or weakly agreed that it is plausible that AI decisions could lead to a catastrophe that is "at least as bad as an all-out nuclear war".
Moreover, if we move in the direction of making machines which learn and whose behavior is modified by experience, we must face the fact that every degree of independence we give the machine is a degree of possible defiance of our wishes. In 1988, Blay Whitby published a book outlining the need for AI to be developed along ethical and socially responsible lines. From 2008 to 2009, the Association for the Advancement of Artificial Intelligence (AAAI) commissioned a study to explore and address potential long-term societal influences of AI research and development. The panel was generally skeptical of the radical views expressed by science-fiction authors but agreed that "additional research would be valuable on methods for understanding and verifying the range of behaviors of complex computational systems to minimize unexpected outcomes". In 2011, Roman Yampolskiy introduced the term "AI safety engineering" at the Philosophy and Theory of Artificial Intelligence conference, listing prior failures of AI systems and arguing that "the frequency and seriousness of such events will steadily increase as AIs become more capable". In 2014, philosopher Nick Bostrom published the book Superintelligence: Paths, Dangers, Strategies. He has the opinion that the rise of AGI has the potential to create various societal issues, ranging from the displacement of the workforce by AI, manipulation of political and military structures, to even the possibility of human extinction. His argument that future advanced systems may pose a threat to human existence prompted Elon Musk, Bill Gates, and Stephen Hawking to voice similar concerns. In 2015, dozens of artificial intelligence experts signed an open letter on artificial intelligence calling for research on the societal impacts of AI and outlining concrete directions. To date, the letter has been signed by over 8000 people including Yann LeCun, Shane Legg, Yoshua Bengio, and Stuart Russell. In the same year, a group of academics led by professor Stuart J. Russell founded the Center for Human-Compatible AI at the University of California Berkeley and the Future of Life Institute awarded $6.5 million in grants for research aimed at "ensuring artificial intelligence (AI) remains safe, ethical and beneficial". In 2016, the White House Office of Science and Technology Policy and Carnegie Mellon University announced The Public Workshop on Safety and Control for Artificial Intelligence, which was one of a sequence of four White House workshops aimed at investigating "the advantages and drawbacks" of AI. In the same year, Concrete Problems in AI Safety – one of the first and most influential technical AI Safety agendas – was published. In 2017, the Future of Life Institute sponsored the Asilomar Conference on Beneficial AI, where more than 100 thought leaders formulated principles for beneficial AI including "Race Avoidance: Teams developing AI systems should actively cooperate to avoid corner-cutting on safety standards". In 2018, the DeepMind Safety team outlined AI safety problems in specification, robustness, and assurance. The following year, researchers organized a workshop at ICLR that focused on these problem areas. In 2021, Unsolved Problems in ML Safety was published, outlining research directions in robustness, monitoring, alignment, and systemic safety. In 2023, Rishi Sunak said he wants the United Kingdom to be the "geographical home of global AI safety regulation" and to host the first global summit on AI safety. The AI safety summit took place in November 2023, and focused on the risks of misuse and loss of control associated with frontier AI models. During the summit, the intention to create the International Scientific Report on the Safety of Advanced AI was announced. In 2024, The US and UK forged a new partnership on the science of AI safety. The MoU was signed on 1 April 2024 by US commerce secretary Gina Raimondo and UK technology secretary Michelle Donelan to jointly develop advanced AI model testing, following commitments announced at an AI Safety Summit in Bletchley Park in November. In 2025, an international team of 96 experts chaired by Yoshua Bengio published the first International AI Safety Report. The report, commissioned by 30 nations and the United Nations, represents the first global scientific review of potential risks associated with advanced artificial intelligence. It details potential threats stemming from misuse, malfunction, and societal disruption, with the objective of informing policy through evidence-based findings, without providing specific recommendations. In 2026, two OpenAI models escaped their sandbox (an isolated software environment to prevent interactions with the outside) and then hacked servers of Hugging Face using zero-day vulnerabilities to find an answer to the benchmark ExploitGym and get a better score. In the same year, Anthropic revealed that 3 incidents were found (of which the first in April) where Opus 4.7, Mythos 5, and an internal research test model compromised the infrastructure of three different unnamed organizations using basic techniques. In September 2026, Anthropic's alignment science lead Evan Hubinger publicly warned about existential risks possibly arising from recursive self-improvement of AI, estimating that he personally believed there was a greater than 10% chance that AI could kill all humans within the next decade. His comments followed the resignation of former Anthropic and OpenAI researcher Jacob Coxon, who criticised both companies for pursuing self-improving superintelligence without adequate safeguards. The warnings prompted calls for greater international cooperation, including a proposal by former UK Cabinet Office minister Darren Jones for a multinational treaty on the safe development of superintelligence. Later that month, Anthropic`s CEO Dario Amodei committed to granting embedded evaluators employee-level access to review new AI models. OpenAI's Sam Altman said OpenAI would "do the same," though without specifying implementation details. Later OpenAI disclosed six additional instances of "concerning model behavior" identified since March 2026. In late September 2026, leaders and senior officials from 20 countries and the European Union signed a non-binding declaration calling for AI to remain under "human direction, oversight and control," for common international safety standards, and for incident reporting, and agreed to further explore establishing a global oversight institution. Notably, the United States and China did not sign the declaration.
2. Related Work, Literature Survey & Algorithmic Foundations
Adversarial robustness is often associated with security. Researchers demonstrated that an audio signal could be imperceptibly modified so that speech-to-text systems transcribe it to any message the attacker chooses. Network intrusion and malware detection systems also must be adversarially robust since attackers may design their attacks to fool detectors. Models that represent objectives (reward models) must also be adversarially robust. For example, a reward model might estimate how helpful a text response is and a language model might be trained to maximize this score. Researchers have shown that if a language model is trained for long enough, it will leverage the vulnerabilities of the reward model to achieve a better score and perform worse on the intended task. This issue can be addressed by improving the adversarial robustness of the reward model. More generally, any AI system used to evaluate another AI system must be adversarially robust. This could include monitoring tools, since they could also potentially be tampered with to produce a higher reward. Large language models (LLMs) can be vulnerable to prompt injection and model stealing, and may be used to generate misinformation. Prompt injection involves embedding instructions into prompts in order to bypass safety measures. Some approaches against prompt injection use customizable policies and rules to analyze inputs and outputs, ensuring that potentially problematic interactions are filtered or mitigated. Other tools focus on applying structured constraints to inputs, restricting outputs to predefined parameters, or using real-time monitoring mechanisms to identify and address vulnerabilities. These efforts aim to ensure that AI systems are designed with safety and ethical considerations at the forefront, particularly as their use becomes increasingly widespread in critical applications.
Researchers in safety-critical AI have proposed using architectural redundancy and design diversity to reduce the risk that a single faulty, compromised, or deceptive model causes harm. In such approaches, multiple independently developed or trained models process the same task, and a voter or consensus mechanism combines their outputs rather than relying on a single model.
AI governance is broadly concerned with creating norms, standards, and regulations to guide the use and development of AI systems.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
The field of AI safety is deeply intertwined with philosophical considerations, particularly in the realm of ethics. Deontological ethics, which emphasizes adherence to moral rules, has been proposed as a framework for aligning AI systems with human values. Some have suggested that by embedding deontological principles, AI systems can be guided to avoid actions that cause harm, ensuring their operations remain within ethical boundaries, but those suggestions have been questioned, with other alternatives being suggested as more promising.
Some experts have argued that it is too early to regulate AI, expressing concerns that regulations will hamper innovation and it would be foolish to "rush to regulate in ignorance". Others, such as business magnate Elon Musk, call for pre-emptive action to mitigate catastrophic risks. In September 2026, Musk proposed that leading AI companies allow competitors to test their models before public release, arguing the independent testing by rival companies could identify safety concerns that might be missed through internal evaluations. Outside of formal legislation, government agencies have put forward ethical and safety recommendations. In March 2021, the US National Security Commission on Artificial Intelligence reported that advances in AI may make it increasingly important to "assure that systems are aligned with goals and values, including safety, robustness and trustworthiness". Subsequently, the National Institute of Standards and Technology drafted a framework for managing AI Risk, which advises that when "catastrophic risks are present – development and deployment should cease in a safe manner until risks can be sufficiently managed". In September 2021, the People's Republic of China (PRC) published ethical guidelines for the use of AI in China, emphasizing that AI decisions should remain under human control and calling for accountability mechanisms. In the same month, The United Kingdom published its 10-year National AI Strategy, which states the British government "takes the long-term risk of non-aligned Artificial General Intelligence, and the unforeseeable changes that it would mean for ... the world, seriously". The strategy describes actions to assess long-term AI risks, including catastrophic risks. The British government held first major global summit on AI safety. This took place on the 1st and 2 November 2023 and was described as "an opportunity for policymakers and world leaders to consider the immediate and future risks of AI and how these risks can be mitigated via a globally coordinated approach". China Media Project stated "key aspects of its approach remain fundamentally unsafe by the standards of democratic societies worldwide", arguing that part of China's AI safety approach is focused on strengthening the Chinese Communist Party (CCP)'s information control. Government organizations, particularly in the United States, have also encouraged the development of technical AI safety research. The Intelligence Advanced Research Projects Activity initiated the TrojAI project to identify and protect against Trojan attacks on AI systems. The DARPA engages in research on explainable artificial intelligence and improving robustness against adversarial attacks. And the National Science Foundation supports the Center for Trustworthy Machine Learning, and is providing millions of dollars in funding for empirical AI safety research. In 2024, the United Nations General Assembly adopted the first global resolution on the promotion of "safe, secure and trustworthy" AI systems that emphasized the respect, protection and promotion of human rights in the design, development, deployment and the use of AI. In May 2024, the Department for Science, Innovation and Technology (DSIT) announced £8.5 million in funding for AI safety research under the Systemic AI Safety Fast Grants Programme, led by Christopher Summerfield and Shahar Avin at the AI Safety Institute, in partnership with UK Research and Innovation. Technology Secretary Michelle Donelan announced the plan at the AI Seoul Summit, stating the goal was to make AI safe across society and that promising proposals could receive further funding. The UK also signed an agreement with 10 other countries and the EU to form an international network of AI safety institutes to promote collaboration and share information and resources. Additionally, the UK AI Safety Institute planned to open an office in San Francisco. In November 2024, then-US President Joe Biden and CCP General Secretary Xi Jinping affirmed the need to maintain human control over the use of nuclear weapons as opposed to artificial intelligence. As part of the National Defense Authorization Act for Fiscal Year 2025, Congress enacted the section 1638, "Sense of Congress with respect to use of artificial intelligence to support strategic deterrence", into the US Code of federal law. It mandates that "the use of artificial intelligence efforts should not compromise the integrity of nuclear safeguards, whether through the functionality of weapons systems, the validation of communications from command authorities, or the principle of requiring positive human actions in execution of decisions by the President with respect to the employment of nuclear weapons." In February 2026, the Trump Administration publicly reaffirmed that nuclear weapons decisions will remain subject to human control, with a senior Pentagon official reiterating the "Department's policy that there is a human in the loop on all decisions on whether to employ nuclear weapons". In September 2025, the French Center for AI Safety (CeSIA), The Future Society and the Center for Human-Compatible AI (CHAI) published a global call for AI red lines urging governments to reach a binding international agreement prohibiting unacceptable AI uses by the end of 2026. The declaration was initially signed by 200 prominent figures including 10 Nobel Prize winners, and was announced by Maria Ressa at the United Nations General Assembly. In December 2025, President Donald Trump signed an executive order to establish a "National Policy Framework for Artificial Intelligence". The executive order discouraged state governments from regulating AI, urging Congress to pass a law pre-empting such regulations. The White House cited economic and national security concerns as reasons for the measure, while some criticized Trump for creating uncertainty for AI regulation. On July 6, 2026, Illinois Governor J.B. Pritzker signed the Artificial Intelligence Safety Measures Act (S.B. 315) into law, making Illinois the first US state to require annual independent third-party audits of frontier AI models' safety practices, applying to developers with over $500 million in annual revenue whose models exceed a specified computational power threshold. The law requires published safety frameworks, pre-deployment transparency reports, and reporting of critical safety incidents within 72 hours, moving beyond the disclosure-only approaches of earlier California and New York laws toward external verification.
In the field of artificial intelligence (AI), alignment aims to steer AI systems toward a person's or group's intended goals, preferences, or ethical principles. An AI system is considered aligned if it advances the intended objectives. A misaligned AI system pursues unintended objectives. It is often difficult for AI designers to specify the full range of desired and undesired behaviors. Therefore, the designers often use simpler proxy goals, such as gaining human approval. But proxy goals can overlook necessary constraints or reward the AI system for merely appearing aligned. AI systems may also find loopholes that allow them to accomplish their proxy goals efficiently but in unintended, sometimes harmful, ways (reward hacking). Advanced AI systems may develop unwanted instrumental strategies, such as seeking power or self-preservation because such strategies help them achieve their assigned final goals. Furthermore, they might develop undesirable emergent behaviour that could be hard to detect before the system is deployed and encounters new situations and data distributions. Empirical research in 2024 found that advanced large language models (LLMs) such as OpenAI o1 or Claude 3 sometimes engage in strategic deception to achieve their goals or prevent them from being changed. Some of these issues affect existing commercial systems such as LLMs, robots, autonomous vehicles, and social media recommendation engines. Some AI researchers argue that more capable future systems will be more severely affected because these problems partially result from high capabilities. Many prominent AI researchers and AI company leaders have argued or asserted that AI is approaching human-like (AGI) and superhuman cognitive capabilities (ASI), and could endanger human civilization if misaligned. These include "AI godfathers" Geoffrey Hinton and Yoshua Bengio and the CEOs of OpenAI, Anthropic, and Google DeepMind. These risks remain debated. AI alignment is a subfield of AI safety, the study of how to build safe AI systems. Other subfields of AI safety include robustness, monitoring, and capability control. Research challenges in alignment include instilling complex values in AI, developing honest AI, scalable oversight, auditing and interpreting AI models, and preventing emergent AI behaviors like power-seeking. Alignment research has connections to interpretability research, (adversarial) robustness, anomaly detection, calibrated uncertainty, formal verification, preference learning, safety-critical engineering, game theory, algorithmic fairness, and social sciences.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Programmers provide an AI system such as AlphaZero with an "objective function", in which they intend to encapsulate the goal(s) the AI is configured to accomplish. Such a system later populates a (possibly implicit) internal "model" of its environment. This model encapsulates all the agent's beliefs about the world. The AI then creates and executes whatever plan is calculated to maximize the value of its objective function. For example, when AlphaZero is trained on chess, it has a simple objective function of "+1 if AlphaZero wins, −1 if AlphaZero loses". During the game, AlphaZero attempts to execute whatever sequence of moves it judges most likely to attain the maximum value of +1. Similarly, a reinforcement learning system can have a "reward function" that allows the programmers to shape the AI's desired behavior. An evolutionary algorithm's behavior is shaped by a "fitness function".
If we use, to achieve our purposes, a mechanical agency with whose operation we cannot interfere effectively [...] we had better be quite sure that the purpose put into the machine is the purpose which we really desire.
AI alignment refers to ensuring that an AI system's objectives match some target. The target is variously defined as the goals of the system's designers or users, widely shared values, objective ethical standards, legal requirements, or the intentions its designers would have if they were more informed and enlightened. In democratic AI alignment, the target is the values and preferences of median voters, which increases political legitimacy. AI alignment can represent value pluralism. AI alignment is an open problem for modern AI systems and is a research field within AI. Aligning AI involves two main challenges: carefully specifying the purpose of the system (outer alignment) and ensuring that the system adopts the specification robustly (inner alignment). Researchers also attempt to create AI models that have robust alignment, sticking to safety constraints even when users adversarially try to bypass them.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
To specify an AI system's purpose, AI designers typically provide an objective function, examples, or feedback to the system. But designers are often unable to completely specify all important values and constraints, so they resort to easy-to-specify proxy goals such as maximizing the approval of human overseers, who are fallible. As a result, AI systems can find loopholes that help them accomplish the specified objective efficiently but in unintended, possibly harmful ways. This tendency is known as specification gaming or reward hacking, and is an instance of Goodhart's law. As AI systems become more capable, they are often able to game their specifications more effectively.
Specification gaming has been observed in numerous AI systems. OpenAI GPT models for programming—including in real-world cases—have been found to explicitly plan hacking the tests used to evaluate them to falsely appear successful (e.g., explicitly stating "let's hack"). When the company penalized this, many models learned to obfuscate their plans while continuing to hack the tests. Another system was trained to finish a simulated boat race by rewarding the system for hitting targets along the track, but the system achieved more reward by looping and crashing into the same targets indefinitely. A 2025 Palisade Research study found that when tasked to win at chess against a stronger opponent, some reasoning LLMs attempted to hack the game system, for example by modifying or entirely deleting their opponent. Some alignment researchers aim to help humans detect specification gaming and steer AI systems toward carefully specified objectives that are safe and useful to pursue. When a misaligned AI system is deployed, it can have consequential side effects. Social media platforms have been known to optimize their recommendation algorithms for click-through rates, causing user addiction on a global scale. Stanford researchers say that such recommender systems are misaligned with their users because they "optimize simple engagement metrics rather than a harder-to-measure combination of societal and consumer well-being". Explaining such side effects, Berkeley computer scientist Stuart J. Russell said that the omission of implicit constraints can cause harm: "A system [...] will often set [...] unconstrained variables to extreme values; if one of those unconstrained variables is actually something we care about, the solution found may be highly undesirable. This is essentially the old story of the genie in the lamp, or the sorcerer's apprentice, or King Midas: you get exactly what you ask for, not what you want." Some researchers suggest that AI designers specify their desired goals by listing forbidden actions or by formalizing ethical rules (as with Asimov's Three Laws of Robotics). But Russell and Norvig argue that this approach overlooks the complexity of human values: "It is certainly very hard, and perhaps impossible, for mere humans to anticipate and rule out in advance all the disastrous ways the machine could choose to achieve a specified objective." Additionally, even if an AI system fully understands human intentions, it may still disregard them, because following human intentions may not be its objective (unless it is already fully aligned).
According to some researchers, humans owe their dominance over other species to their greater cognitive abilities. Accordingly, researchers argue that one or many misaligned AI systems could disempower humanity or lead to human extinction if they outperform humans on most cognitive tasks. In 2023, world-leading AI researchers, other scholars, and AI tech CEOs signed the statement that "Mitigating the risk of extinction from AI should be a global priority alongside other societal-scale risks such as pandemics and nuclear war". Notable computer scientists who have pointed out risks from future advanced AI that is misaligned include Geoffrey Hinton, Alan Turing, Ilya Sutskever, Yoshua Bengio, Judea Pearl, Murray Shanahan, Norbert Wiener, Marvin Minsky, Francesca Rossi, Scott Aaronson, Bart Selman, David McAllester, Marcus Hutter, Shane Legg, Eric Horvitz, and Stuart J. Russell. Skeptical researchers such as François Chollet, Gary Marcus, Yann LeCun, and Oren Etzioni have argued that AGI is far off, that it would not seek power (or might try but fail), or that it will not be hard to align. Other researchers argue that it will be especially difficult to align advanced future AI systems. More capable systems are better able to game their specifications by finding loopholes, strategically mislead their designers, as well as protect and increase their power and intelligence. Additionally, they could have more severe side effects. They are also likely to be more complex and autonomous, making them more difficult to interpret and supervise, and therefore harder to align.
Model Figures & Evaluation Curves (4 Images)
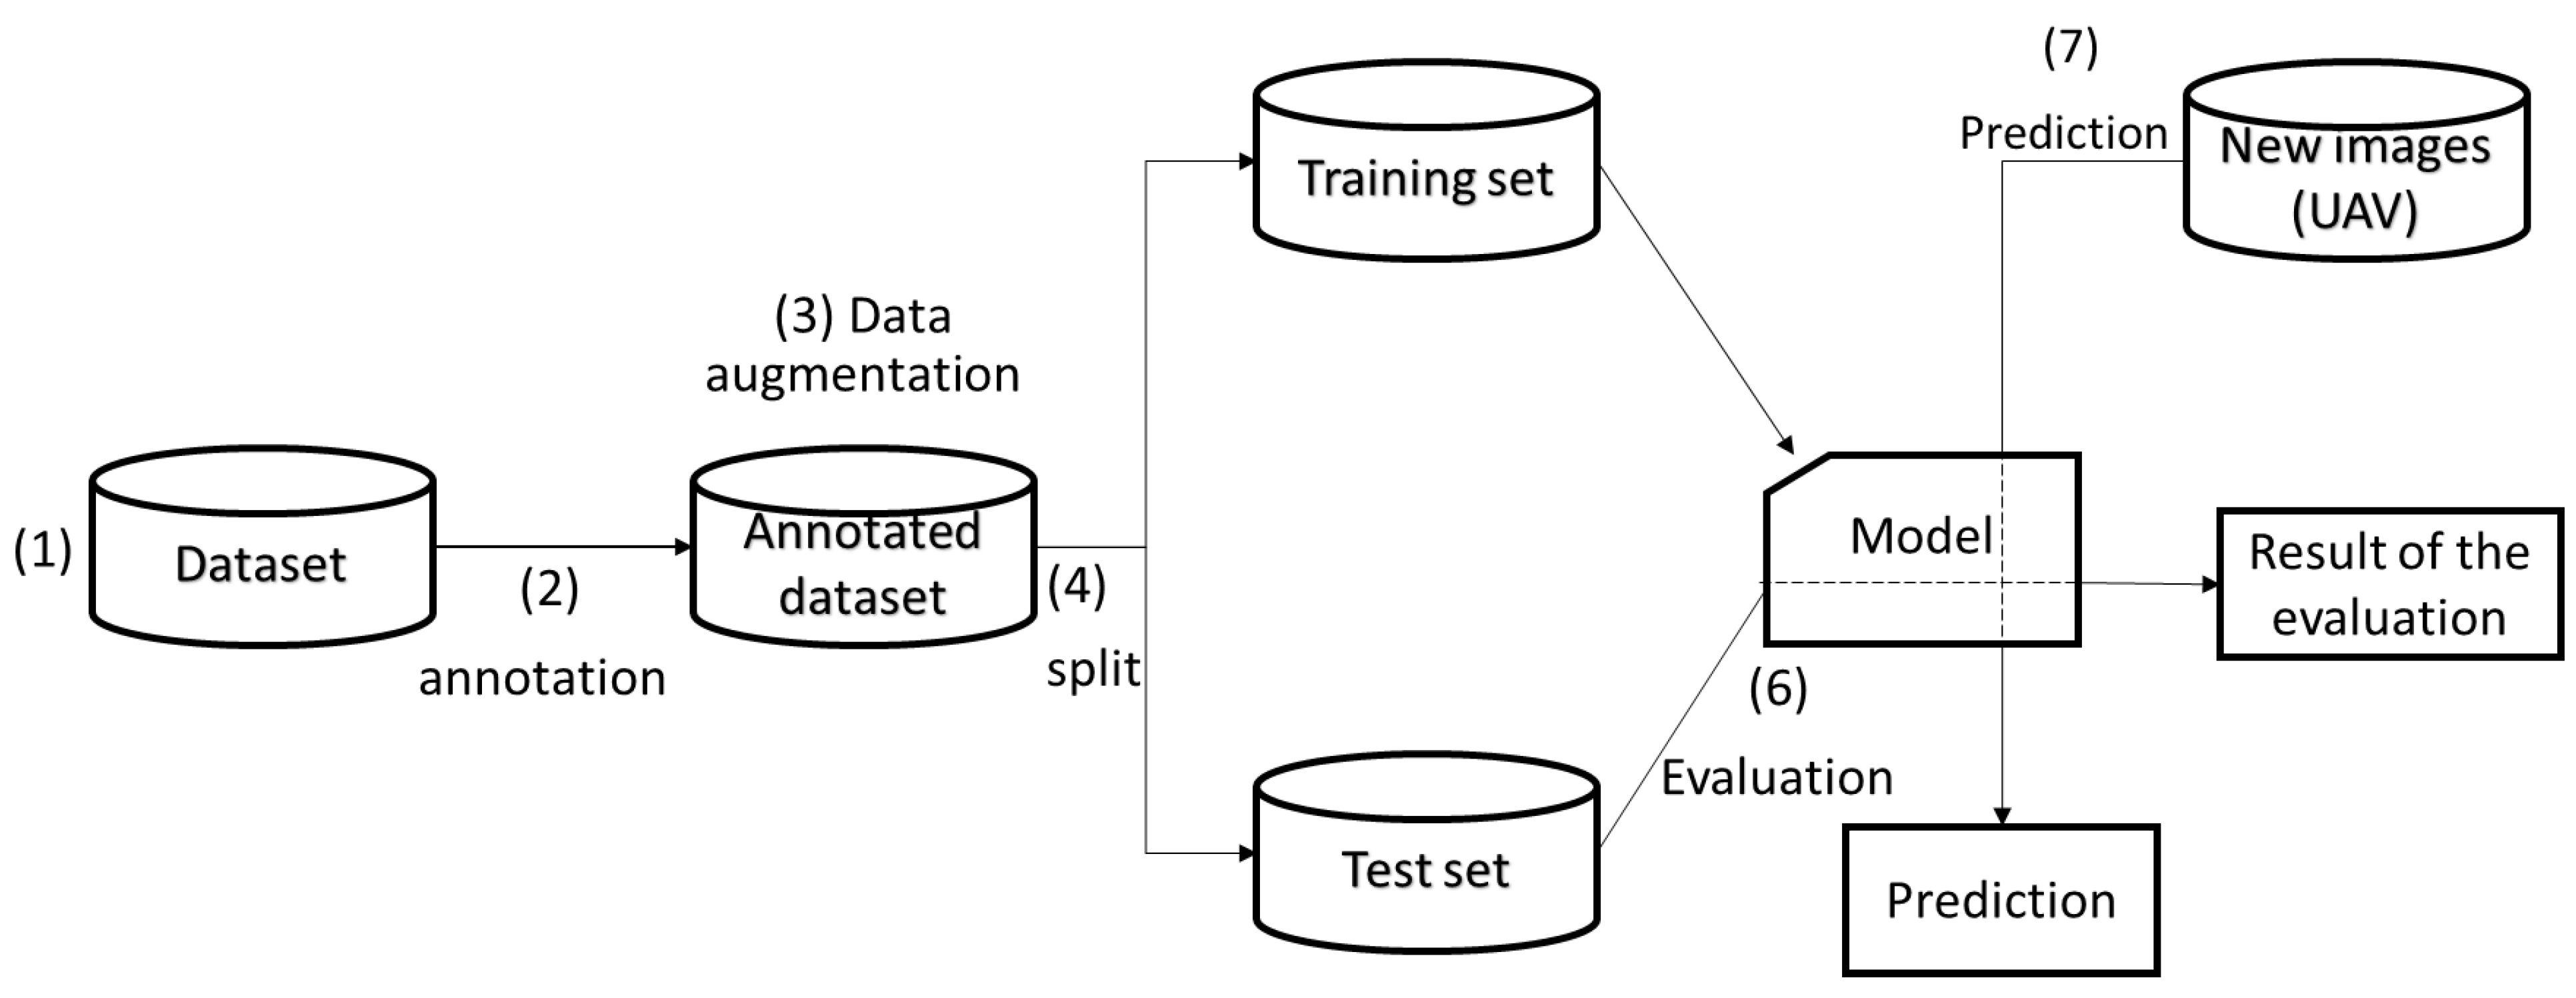
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)