Complete Technical Paper Content — Ai Sequential Recommendation
1. Executive Abstract, Problem Formulation & Background
A recommender system, also called a recommendation engine or content discovery platform is a type of information filtering system that aims to suggest items most relevant for some input or to a particular user. In the context of social media, search engines, and other online services, a recommender system for a given service might sometimes informally but erroneously be referred to as the service's "algorithm". The use of recommender systems is pervasive, with commonly recognised examples including the generation of playlists for video and music streaming services, product recommendations for e-commerce platforms, and topics and individual items posted on social media platforms and the open web. Online services employ machine learning or specialized deep learning recommendation models (DLRMs) that analyze user behavior and preferences to generate personalized content feeds for millions of users at any moment. The value of these systems becomes particularly evident in scenarios where users must select from a large number of options, such as products, media, or content. Suggestions are typically designed to shorten or work as a substitute for decision-making processes, including the selection of a product, musical selection, or online news source to read.
Last.fm creates a "station" of recommended songs by observing what bands and individual tracks the user has listened to on a regular basis and comparing those against the listening behavior of other users. Last.fm will play tracks that do not appear in the user's library, but are often played by other users with similar interests. As this approach leverages the behavior of users, it is an example of a collaborative filtering technique. Pandora uses the properties of a song or artist (a subset of the 450 attributes provided by the Music Genome Project) to seed a "station" that plays music with similar properties. User feedback is used to refine the station's results, deemphasizing certain attributes when a user "dislikes" a particular song and emphasizing other attributes when a user "likes" a song. This is an example of a content-based approach. Each type of system has its strengths and weaknesses. In the above example, Last.fm requires a large amount of information about a user to make accurate recommendations. This is an example of the cold start problem, and is common in collaborative filtering systems. Whereas Pandora needs very little information to start, it is far more limited in scope (for example, it can only make recommendations that are similar to the original seed).
and implemented at scale and worked through in technical reports and publications from 1994 onwards by Jussi Karlgren, then at SICS, and research groups led by Pattie Maes at MIT, Will Hill at Bellcore, and Paul Resnick, also at MIT, whose work with GroupLens was awarded the 2010 ACM Software Systems Award. Montaner provided the first overview of recommender systems from an intelligent agent perspective. Gediminas Adomavicius provided a new, alternate overview of recommender systems. Herlocker provides an additional overview of evaluation techniques for recommender systems, and Beel et al. discussed the problems of offline evaluations. Beel et al. have also provided literature surveys on available research paper recommender systems and existing challenges.
One approach to the design of recommender systems that has wide use is collaborative filtering. Collaborative filtering is based on the assumption that people who agreed in the past will agree in the future, and that they will like similar kinds of items as they liked in the past. The system generates recommendations using only information about rating profiles for different users or items. By locating peer users/items with a rating history similar to the current user or item, they generate recommendations using this neighborhood. The collaborative filtering approach does not rely on machine analyzable content and therefore it is capable of accurately recommending complex items such as movies without requiring an "understanding" of the item itself. Many algorithms have been used in measuring user similarity or item similarity in recommender systems. For example, the k-nearest neighbor (k-NN) approach and the Pearson Correlation as first implemented by Allen. Collaborative filtering approaches often suffer from three problems: cold start, scalability, and sparsity.
Cold start: For a new user or item, there is not enough data to make accurate recommendations. Note: one commonly implemented solution to this problem is the multi-armed bandit algorithm. Scalability: There are millions of users and products in many of the environments in which these systems make recommendations. Thus, a large amount of computation power is often necessary to calculate recommendations. Sparsity: The number of items sold on major e-commerce sites is extremely large. The most active users will only have rated a small subset of the overall database. Thus, even the most popular items have very few ratings. Social networking services have used collaborative filtering to recommend new friends, groups, and other social connections by examining the network of connections between a user and their friends.
A model of the user's preference. A history of the user's interaction with the recommender system. Basically, these methods use an item profile (i.e., a set of discrete attributes and features) characterizing the item within the system. To abstract the features of the items in the system, an item presentation algorithm is applied. A widely used algorithm is the tf–idf representation (also called vector space representation). The system creates a content-based profile of users based on a weighted vector of item features. The weights denote the importance of each feature to the user and can be computed from individually rated content vectors using a variety of techniques. Simple approaches use the average values of the rated item vector while other sophisticated methods use machine learning techniques such as Bayesian Classifiers, cluster analysis, decision trees, and artificial neural networks in order to estimate the probability that the user is going to like the item. Watch time can be used as a primary indicator of whether the user likes a post, and the posts can be clustered and associated in several ways via social graphs and techniques similar to the concept of embeddings in machine learning. Posts can be ranked with a dedicated model, and ranking and recommendation models can be used together in a ranking and recommendation system. Recommendation systems can have two towers: one with the user profile as an embedding and another for items or posts also as embeddings. Both types of embeddings can be generated from users and posts by specialized embedding models and then the differences between the two types of embeddings can be computed with cosine difference to match users to items. Then a ranking model can be used to show a feed that is diverse as it is scrolled that does not cluster together similar posts. A key issue with content-based filtering is whether the system can learn user preferences from users' actions regarding one content source and use them across other content types. When the system is limited to recommending content of the same type as the user is already using, the value from the recommendation system is significantly less than when other content types from other services can be recommended. For example, recommending news articles based on news browsing is useful. Still, it would be much more useful when music, videos, products, discussions, etc., from different services, can be recommended based on news browsing. To overcome this, most content-based recommender systems now use some form of the hybrid system. Content-based recommender systems can also include opinion-based recommender systems. In some cases, users are allowed to leave text reviews or feedback on the items. These user-generated texts are implicit data for the recommender system because they are potentially rich resources of both feature/aspects of the item and users' evaluation/sentiment to the item. Features extracted from the user-generated reviews are improved metadata of items, because as they also reflect aspects of the item like metadata, extracted features are widely concerned by the users. Sentiments extracted from the reviews can be seen as users' rating scores on the corresponding features. Popular approaches of opinion-based recommender system utilize various techniques including text mining, information retrieval, sentiment analysis (see also Multimodal sentiment analysis) and deep learning.
2. Related Work, Literature Survey & Algorithmic Foundations
Weighted: Combining the score of different recommendation components numerically. Switching: Choosing among recommendation components and applying the selected one. Mixed: Recommendations from different recommenders are presented together to give the recommendation. Cascade: Recommenders are given strict priority, with the lower priority ones breaking ties in the scoring of the higher ones. Meta-level: One recommendation technique is applied and produces some sort of model, which is then the input used by the next technique.
Mobile recommender systems make use of internet-accessing smartphones to offer personalized, context-sensitive recommendations. This is a particularly difficult area of research as mobile data is more complex than data that recommender systems often have to deal with. It is heterogeneous, noisy, requires spatial and temporal auto-correlation, and has validation and generality problems. There are three factors that could affect the mobile recommender systems and the accuracy of prediction results: the context, the recommendation method and privacy. Additionally, mobile recommender systems suffer from a transplantation problem – recommendations may not apply in all regions (for instance, it would be unwise to recommend a recipe in an area where all of the ingredients may not be available). One example of a mobile recommender system are the approaches taken by companies such as Uber and Lyft to generate driving routes for taxi drivers in a city. This system uses GPS data of the routes that taxi drivers take while working, which includes location (latitude and longitude), time stamps, and operational status (with or without passengers). It uses this data to recommend a list of pickup points along a route, with the goal of optimizing occupancy times and profits.
One of the events that energized research in recommender systems was the Netflix Prize. From 2006 to 2009, Netflix sponsored a competition, offering a grand prize of $1,000,000 to the team that could take an offered dataset of over 100 million movie ratings and return recommendations that were 10% more accurate than those offered by the company's existing recommender system. This competition energized the search for new and more accurate algorithms. On September 21, 2009, the grand prize of US$1,000,000 was given to the BellKor's Pragmatic Chaos team using tiebreaking rules. The most accurate algorithm in 2007 used an ensemble method of 107 different algorithmic approaches, blended into a single prediction. As stated by the winners, Bell et al.:
Predictive accuracy is substantially improved when blending multiple predictors. Our experience is that most efforts should be concentrated in deriving substantially different approaches, rather than refining a single technique. Consequently, our solution is an ensemble of many methods. Many benefits accrued to the web due to the Netflix project. Some teams have taken their technology and applied it to other markets. Some members from the team that finished second place founded Gravity R&D, a recommendation engine that's active in the RecSys community. 4-Tell, Inc. created a Netflix project–derived solution for ecommerce websites. A number of privacy issues arose around the dataset offered by Netflix for the Netflix Prize competition. Although the data sets were anonymized in order to preserve customer privacy, in 2007 two researchers from the University of Texas were able to identify individual users by matching the data sets with film ratings on the Internet Movie Database (IMDb). As a result, in December 2009, an anonymous Netflix user sued Netflix in Doe v. Netflix, alleging that Netflix had violated United States fair trade laws and the Video Privacy Protection Act by releasing the datasets. This, as well as concerns from the Federal Trade Commission, led to the cancellation of a second Netflix Prize competition in 2010.
Diversity – Users tend to be more satisfied with recommendations when there is a higher intra-list diversity, e.g. items from different artists. Recommender persistence – In some situations, it is more effective to re-show recommendations, or let users re-rate items, than showing new items. There are several reasons for this. Users may ignore items when they are shown for the first time, for instance, because they had no time to inspect the recommendations carefully. Privacy – Recommender systems usually have to deal with privacy concerns because users have to reveal sensitive information. Building user profiles using collaborative filtering can be problematic from a privacy point of view. Many European countries have a strong culture of data privacy, and every attempt to introduce any level of user profiling can result in a negative customer response. Much research has been conducted on ongoing privacy issues in this space. The Netflix Prize is particularly notable for the detailed personal information released in its dataset. Ramakrishnan et al. have conducted an extensive overview of the trade-offs between personalization and privacy and found that the combination of weak ties (an unexpected connection that provides serendipitous recommendations) and other data sources can be used to uncover identities of users in an anonymized dataset. User demographics – Beel et al. found that user demographics may influence how satisfied users are with recommendations. In their paper they show that elderly users tend to be more interested in recommendations than younger users. Robustness – When users can participate in the recommender system, the issue of fraud must be addressed. Serendipity – Serendipity is a measure of "how surprising the recommendations are". For instance, a recommender system that recommends milk to a customer in a grocery store might be perfectly accurate, but it is not a good recommendation because it is an obvious item for the customer to buy. "[Serendipity] serves two purposes: First, the chance that users lose interest because the choice set is too uniform decreases. Second, these items are needed for algorithms to learn and improve themselves". Trust – A recommender system is of little value for a user if the user does not trust the system. Trust can be built by a recommender system by explaining how it generates recommendations, and why it recommends an item. Labelling – User satisfaction with recommendations may be influenced by the labeling of the recommendations. For instance, in the cited study click-through rate (CTR) for recommendations labeled as "Sponsored" were lower (CTR=5.93%) than CTR for identical recommendations labeled as "Organic" (CTR=8.86%). Recommendations with no label performed best (CTR=9.87%) in that study.
Artificial intelligence (AI) applications in recommendation systems are the advanced methodologies that leverage AI technologies, to enhance the performance recommendation engines. The AI-based recommender can analyze complex data sets, learning from user behavior, preferences, and interactions to generate highly accurate and personalized content or product suggestions. The integration of AI in recommendation systems has marked a significant evolution from traditional recommendation methods. Traditional methods often relied on inflexible algorithms that could suggest items based on general user trends or apparent similarities in content. In comparison, AI-powered systems have the capability to detect patterns and subtle distinctions that may be overlooked by traditional methods. These systems can adapt to specific individual preferences, thereby offering recommendations that are more aligned with individual user needs. This approach marks a shift towards more personalized, user-centric suggestions. Recommendation systems widely adopt AI techniques such as machine learning, deep learning, and natural language processing. These advanced methods enhance system capabilities to predict user preferences and deliver personalized content more accurately. Each technique contributes uniquely. The following sections will introduce specific AI models utilized by a recommendation system by illustrating their theories and functionalities.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Data Representation: Create a n-dimensional space where each axis represents a user's trait (ratings, purchases, etc.). Represent the user as a point in that space. Statistical Distance: 'Distance' measures how far apart users are in this space. See statistical distance for computational details Identifying Neighbors: Based on the computed distances, find k nearest neighbors of the user to which we want to make recommendations Forming Predictive Recommendations: The system will analyze the similar preference of the k neighbors. The system will make recommendations based on that similarity
Time and Seasonality: what specify time and date or a season that a user interacts with the platform User Navigation Patterns: sequence of pages visited, time spent on different parts of a website, mouse movement, etc. External Social Trends: information from outer social media
User Tower: Encodes user-specific features, such as interaction history or demographic data. Item Tower: Encodes item-specific features, such as metadata or content embeddings. The outputs of the two towers are fixed-length embeddings that represent users and items in a shared vector space. A similarity metric, such as dot product or cosine similarity, is used to measure relevance between a user and an item. This model is highly efficient for large datasets as embeddings can be pre-computed for items, allowing rapid retrieval during inference. It is often used in conjunction with ranking models for end-to-end recommendation pipelines.
Artificial intelligence (AI) and its subfields have been used in applications throughout industry and academia. Machine learning has been used for various scientific and commercial purposes, including language translation, image recognition, decision-making, credit scoring, and e-commerce. Since the 2020s, massive advancements have been made in the field of generative AI (GenAI) as a result of the 2017 inception of Transformer Model architecture. GenAI has the ability to create text, images, voice, music, videos, and other forms of data from chat-based prompting.
In agriculture, AI has been proposed as a way for farmers to identify areas that need irrigation, fertilization, or pesticide treatments to increase yields, thereby improving efficiency. AI has been used to attempt to classify livestock pig call emotions, automate greenhouses, detect diseases and pests, and optimize irrigation.
A 2019 study found that generative AI increased productivity by 15% in contact centers. Another 2019 study found it increased productivity by up to 40% for writing tasks. An August 2025 review by MIT found that of surveyed companies, 95% did not report any improvement in revenue from the use of AI. In September 2025, a Harvard Business Review article described how increased use of AI does not automatically lead to increases in revenue or actual productivity. Referring to "AI generated work content that masquerades as good work, but lacks the substance to meaningfully advance a given task", the article coined the term workslop. Per studies done in collaboration with the Stanford Social Media Lab, workslop does not improve productivity and undermines trust and collaboration among colleagues. In telehealth, agentic AI is reportedly facilitating the creation of large business models (millions in annual profit) with 1–2 employees, such as MEDVi, which as of August 2025 only had 2 employees and ~$75M in annual profit for GLP-1 weight-loss telehealth services.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Research and development of quantum computers has been performed with machine learning algorithms. For example, there is a prototype, photonic, quantum memristive device for neuromorphic computers (NC)/artificial neural networks and NC-using quantum materials with some variety of potential neuromorphic computing-related applications. The use of quantum machine learning for quantum simulators has been proposed for solving physics and chemistry problems.
Artificial intelligence and machine learning are used in electronic design automation to assist with integrated circuit design, including floorplanning, placement, routing, functional verification, and optimization of power, performance, and chip area.
Time sharing Interactive interpreters Graphical user interfaces and the computer mouse Rapid application development environments The linked list data structure Automatic storage management Symbolic programming Functional programming Dynamic programming Object-oriented programming Optical character recognition Constraint satisfaction
AI programs have been used in hiring processes to screen resumes and rank candidates based on their qualifications, predict a candidate's likelihood of success in a given role, and automate repetitive communication tasks using chatbots. Studies on these programs have identified tendencies for gender bias, favoring male names and male-coded characteristics, as well as bias against disabled candidates and racial minorities.
AI underlies avatars (automated online assistants) on web pages. It can reduce operation and training costs. In 2016, Pypestream automated customer service for its mobile application to streamline communication with customers. A Google app analyzes language and converts speech into text. The platform can identify angry customers through their language and respond appropriately. Amazon uses a chatbot for customer service that can perform tasks like checking the status of an order, cancelling orders, offering refunds, and connecting the customer with a human representative.
In educational institutions, AI has been used to automate routine tasks such as attendance tracking, grading, and marking. AI tools have also been used to monitor student progress and analyze learning behaviors, with the goal of facilitating timely interventions for students facing academic challenges. As of 2025 and 2026, respectively, about 80% of high school students and nearly 60% of college students were also using AI. Some schools and universities proposed restrictions on students' usage due to issues with increased cheating, over-reliance on AI tools, and widening of digital inequities.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
The U.S. Department of Energy wrote in an April 2024 report that AI may have applications in modeling power grids, reviewing federal permits with large language models (LLMs), predicting levels of renewable energy production, and improving the planning process for electrical vehicle charging networks. Other studies have suggested that machine learning can be used for energy consumption prediction and scheduling (e.g., to help with renewable energy intermittency management).
The late 1980s and early 1990s saw expert systems used in technical and environmental domains. For example, researchers built a fishway design advisor to recommend fish passage structures under varying hydraulic and biological conditions using the VP-Expert shell. Transportation researchers applied the same shell to balance airport capacity with noise-mitigation plans. In agriculture, a potato insect expert system (PIES) supported pest management decisions for Colorado potato beetle. The U.S. Environmental Protection Agency's CORMIX system for modeling pollutant discharges combined rules with Fortran hydrodynamic models. Autonomous ships that monitor the ocean, AI-driven satellite data analysis, passive acoustics or remote sensing and other applications of environmental monitoring make use of machine learning. For example, "Global Plastic Watch" is an AI-based satellite-monitoring platform for analysis/tracking of plastic waste sites to help with the prevention of plastic pollution—primarily ocean pollution—by helping identify who mismanages plastic waste and where dumping into oceans occurs.
AI applications analyze media content such as movies, TV programs, advertisement videos, and user-generated content. The solutions often involve computer vision. Typical scenarios include the analysis of images using object recognition or facial recognition techniques, or the analysis of video for recognizing scenes, objects, or faces. AI-based media analysis can facilitate media search, the creation of descriptive keywords for content, content policy monitoring (such as verifying the suitability of content for a particular TV viewing time), speech to text for archival or other purposes, and the detection of logos, products, or celebrity faces for ad placement.
Motion interpolation Pixel-art scaling algorithms Image scaling Image restoration Photo colorization Film restoration and video upscaling Photo tagging Text-to-image models (such as DALL-E, Midjourney, and Stable Diffusion) Image to video Text to video (such as Make-A-Video from Meta, Imagen video and Phenaki from Google) Text to music with AI models (such as MusicLM) Text to speech (such as ElevenLabs and 15.ai) Motion capture
AI has been used to compose music of various genres. David Cope created an AI called Emily Howell that became well known in the field of algorithmic computer music. The algorithm behind Emily Howell is registered as a US patent. In 2012, AI Iamus created the first complete classical album. AIVA (Artificial Intelligence Virtual Artist), composes symphonic music, mainly classical music for film scores. It became the first virtual composer to be recognized by a musical professional association. Melomics creates computer-generated music for stress and pain relief. The Watson Beat uses reinforcement learning and deep belief networks to compose music on a simple seed input melody and a select style. The software was open sourced, and musicians such as Taryn Southern collaborated with the project. South Korean singer Hayeon's debut song, "Eyes on You", was composed using AI which was supervised by real composers, including NUVO.
Narrative Science sells computer-generated news and reports. It summarizes sporting events based on statistical data from a game. It also creates financial reports and real estate analyses. Automated Insights generates personalized recaps and previews for Yahoo Sports Fantasy Football. Yseop uses AI to turn structured data into natural language comments and recommendations. It writes financial reports, executive summaries, and personalized sales or marketing documents in multiple languages, including English, Spanish, French, and German. TALESPIN made up stories similar to the fables of Aesop. The program started with a set of characters who wanted to achieve certain goals. Mark Riedl and Vadim Bulitko asserted that the essence of storytelling was experience management, or "how to balance the need for a coherent story progression with user agency, which is often at odds". While AI storytelling focuses on story generation (character and plot), story communication also received attention. In 2002, researchers developed an architectural framework for narrative prose generation. They faithfully reproduced text variety and complexity on stories such as Little Red Riding Hood. In 2016, a Japanese AI co-wrote a short story and almost won a literary prize. South Korean company Hanteo Global uses a journalism bot to write articles. Literary authors are also exploring uses of AI. An example is David Jhave Johnston's work ReRites (2017–2019), where the poet created a daily rite of editing the poetic output of a neural network to create a series of performances and publications.
Model Figures & Evaluation Curves (4 Images)
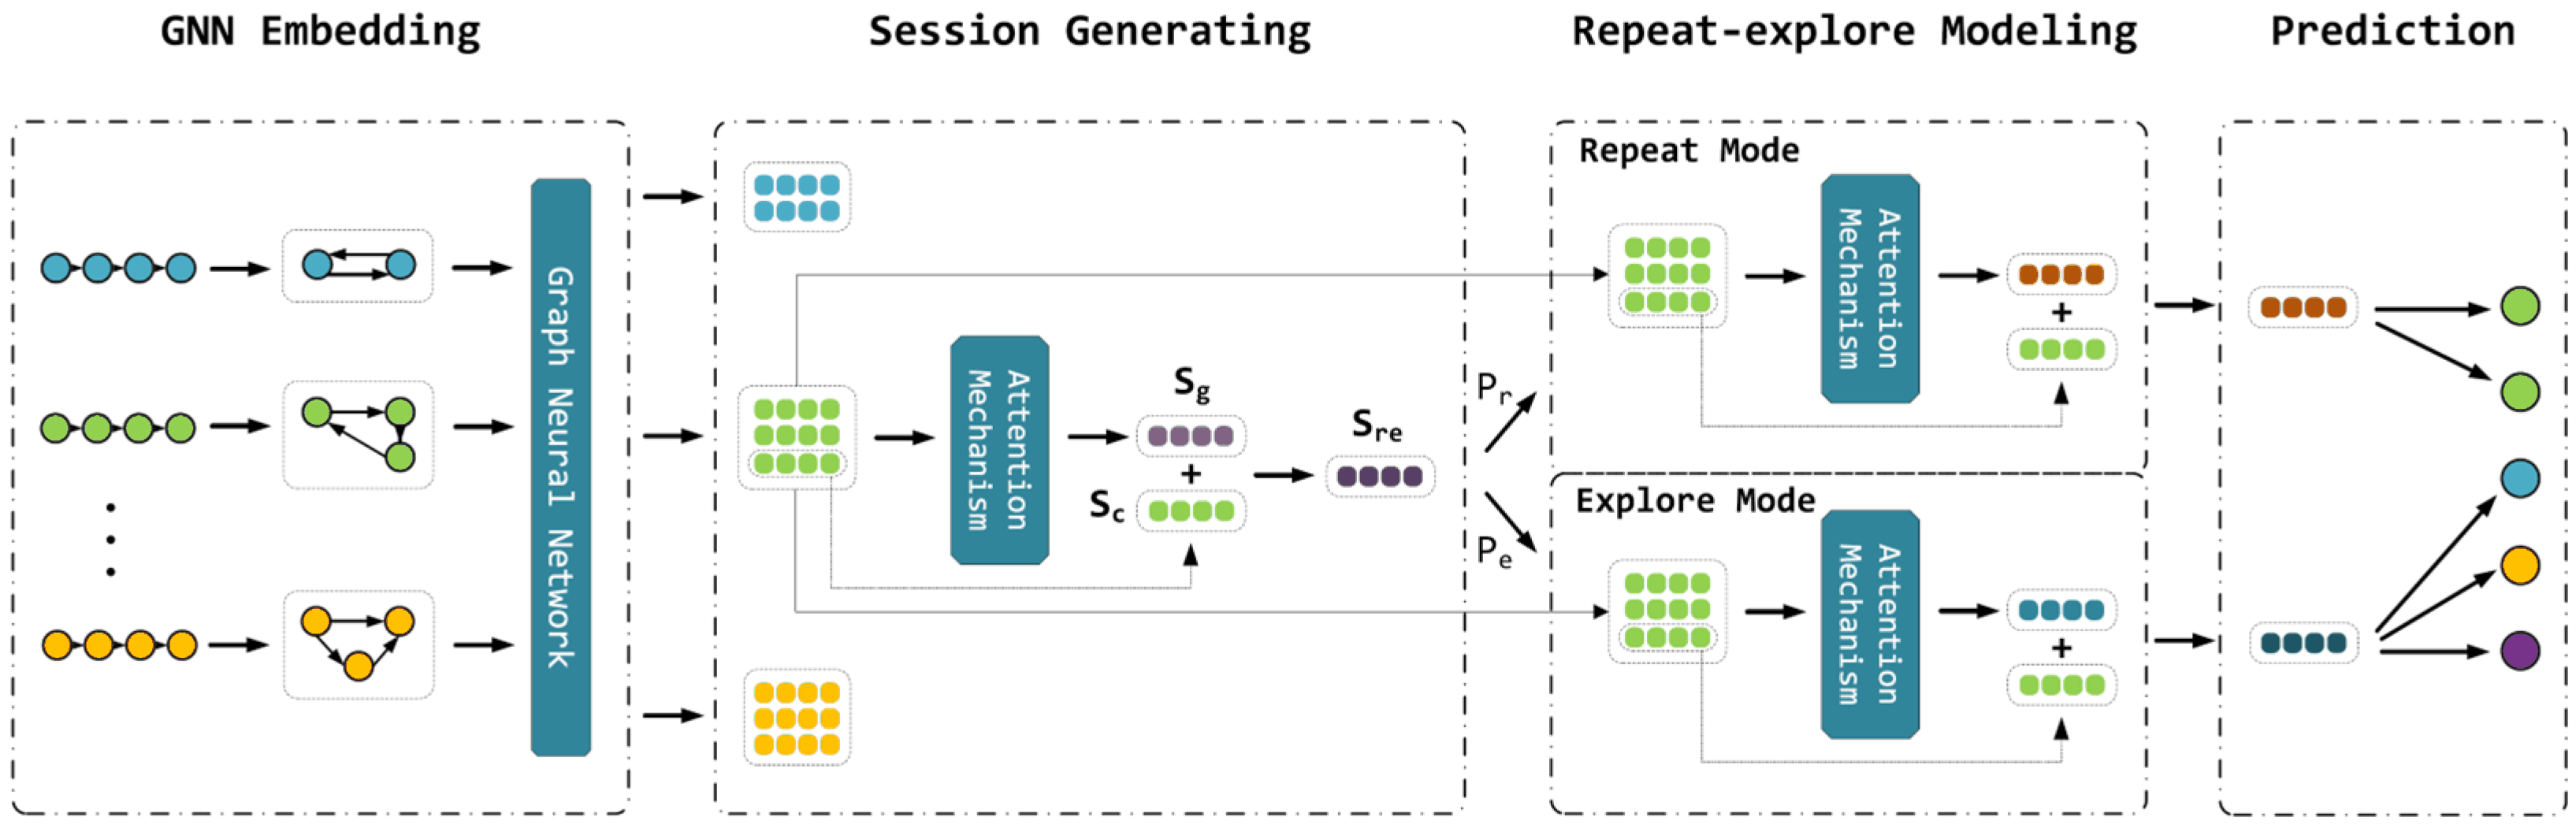
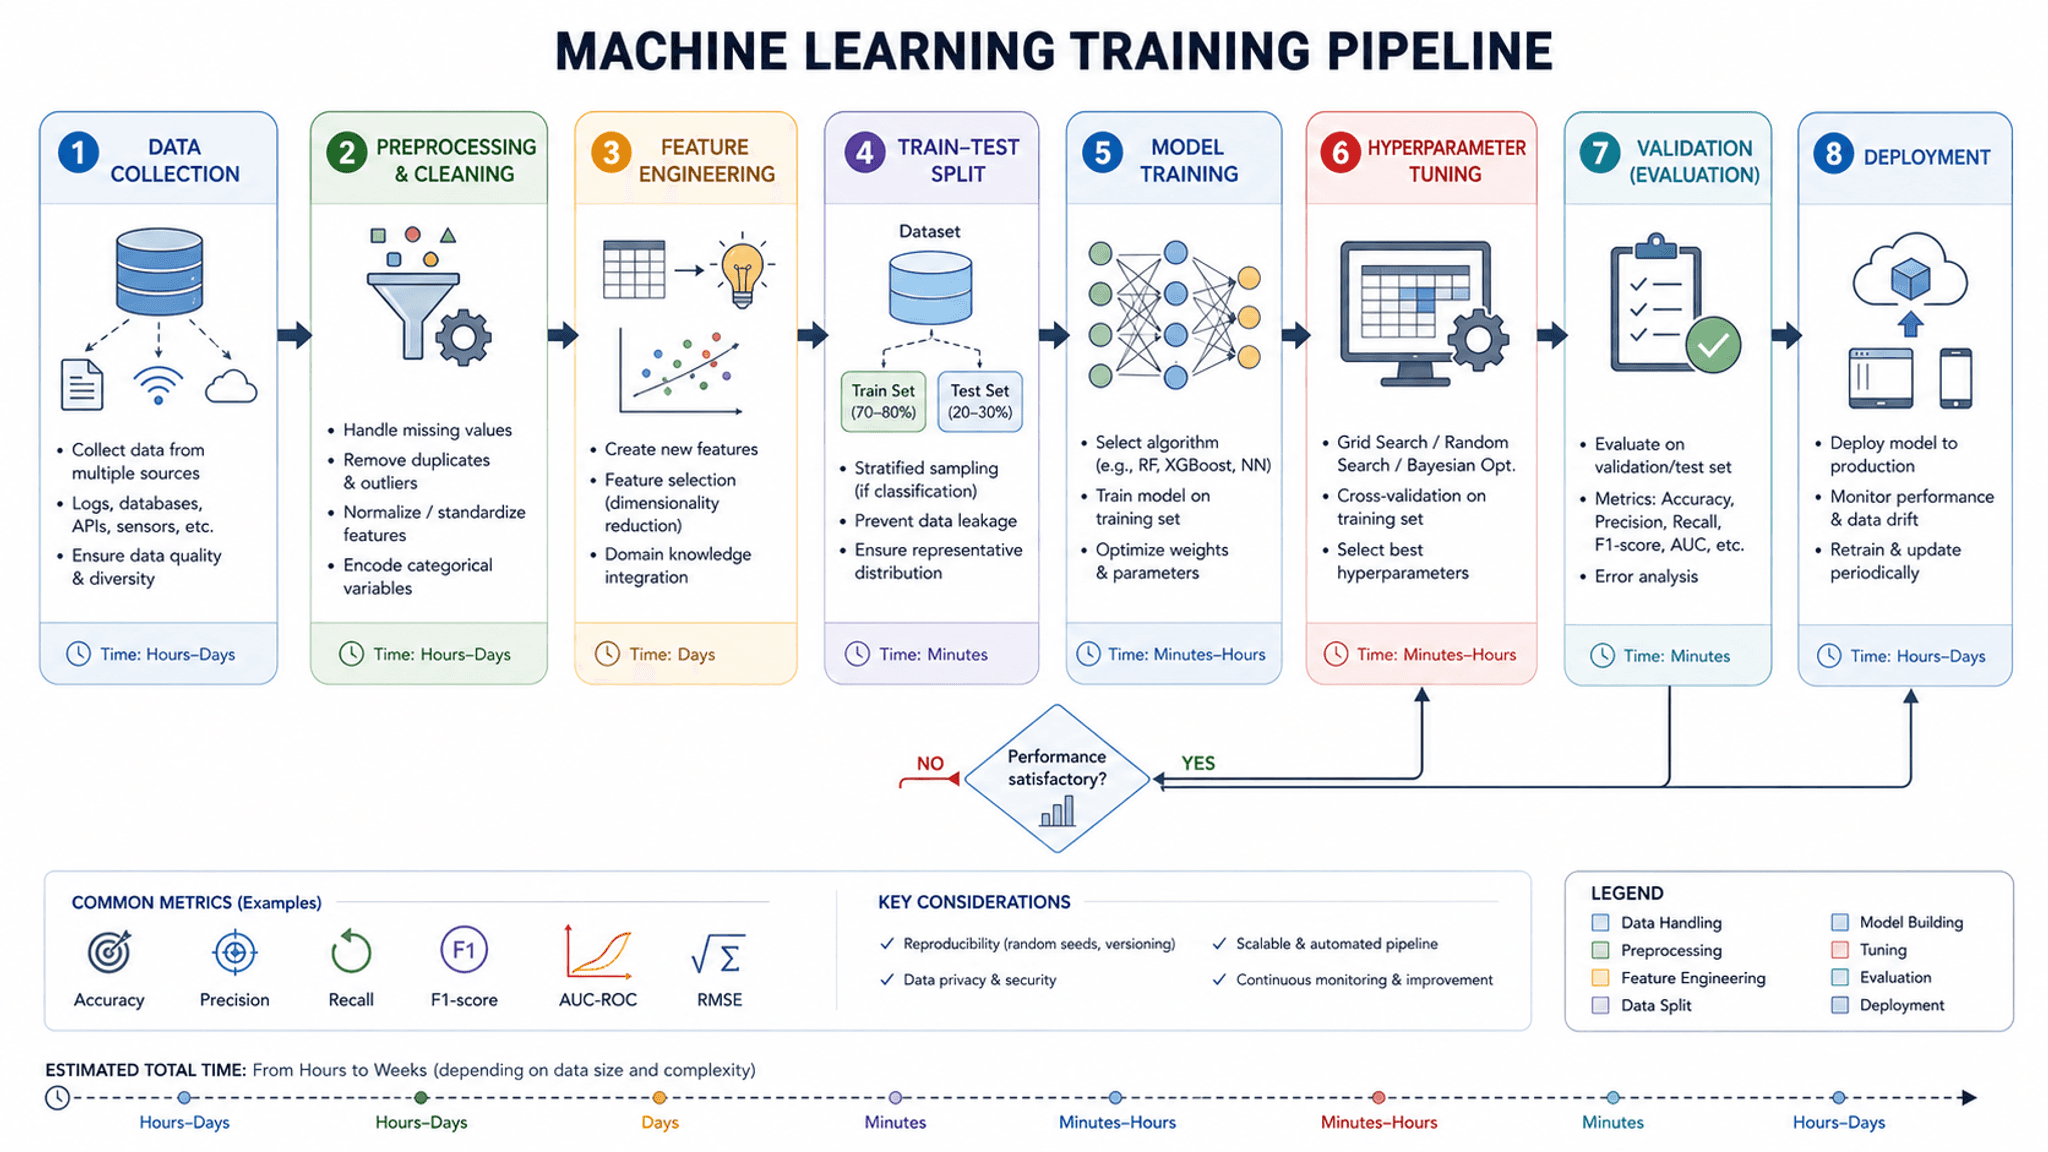
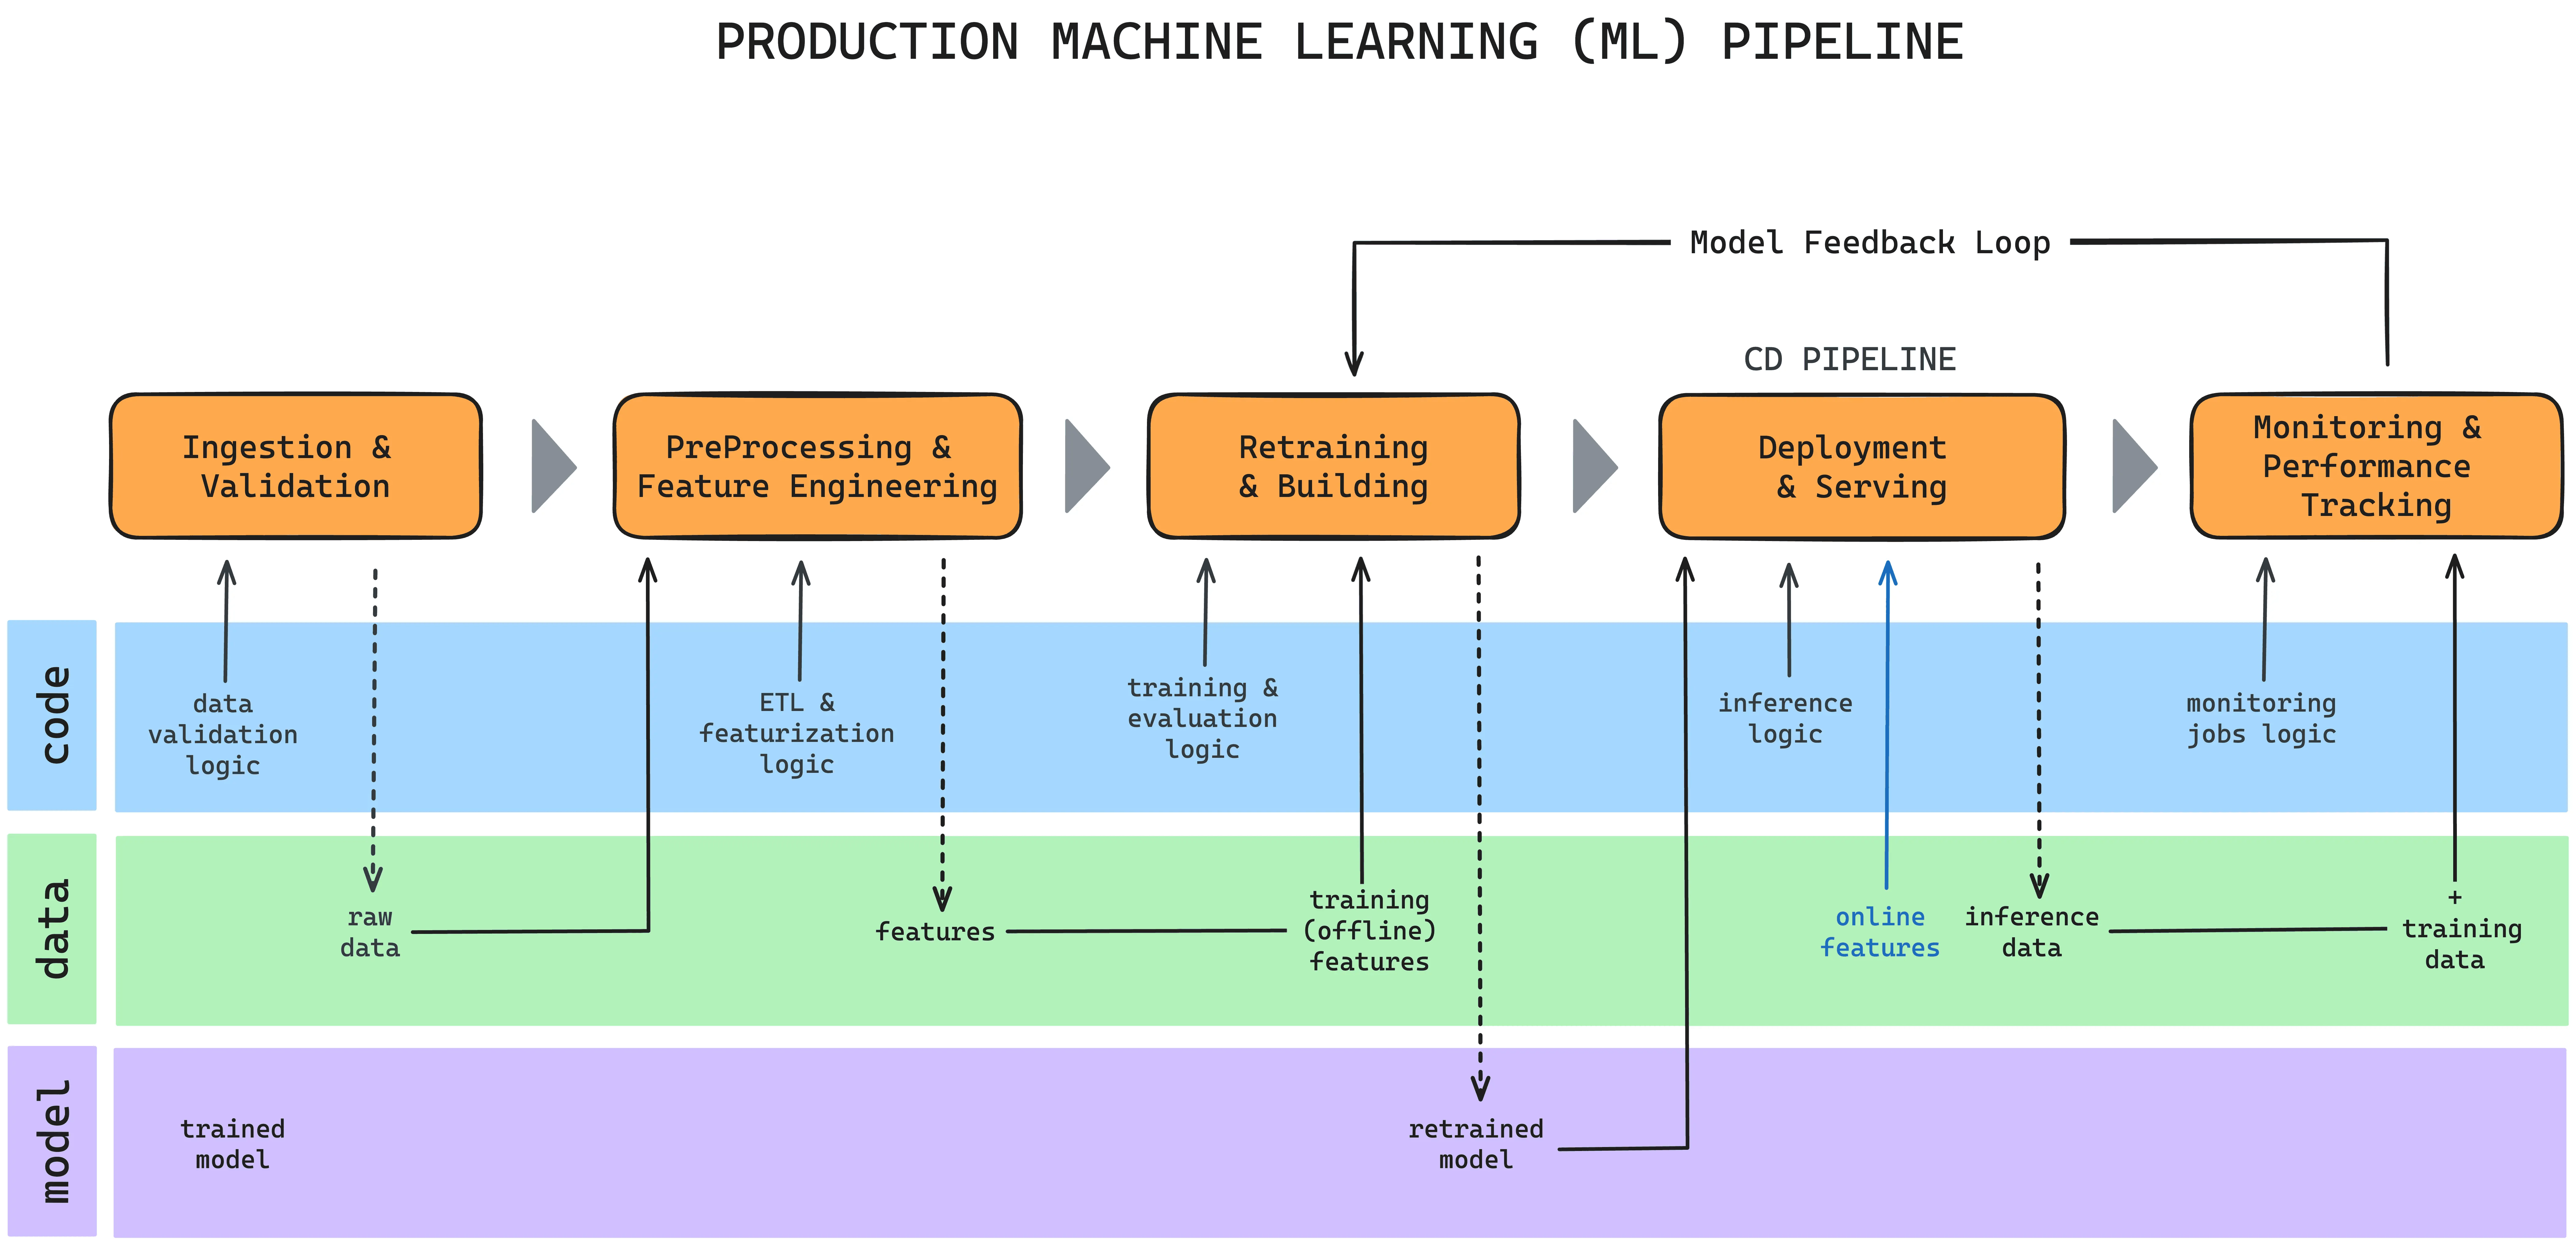
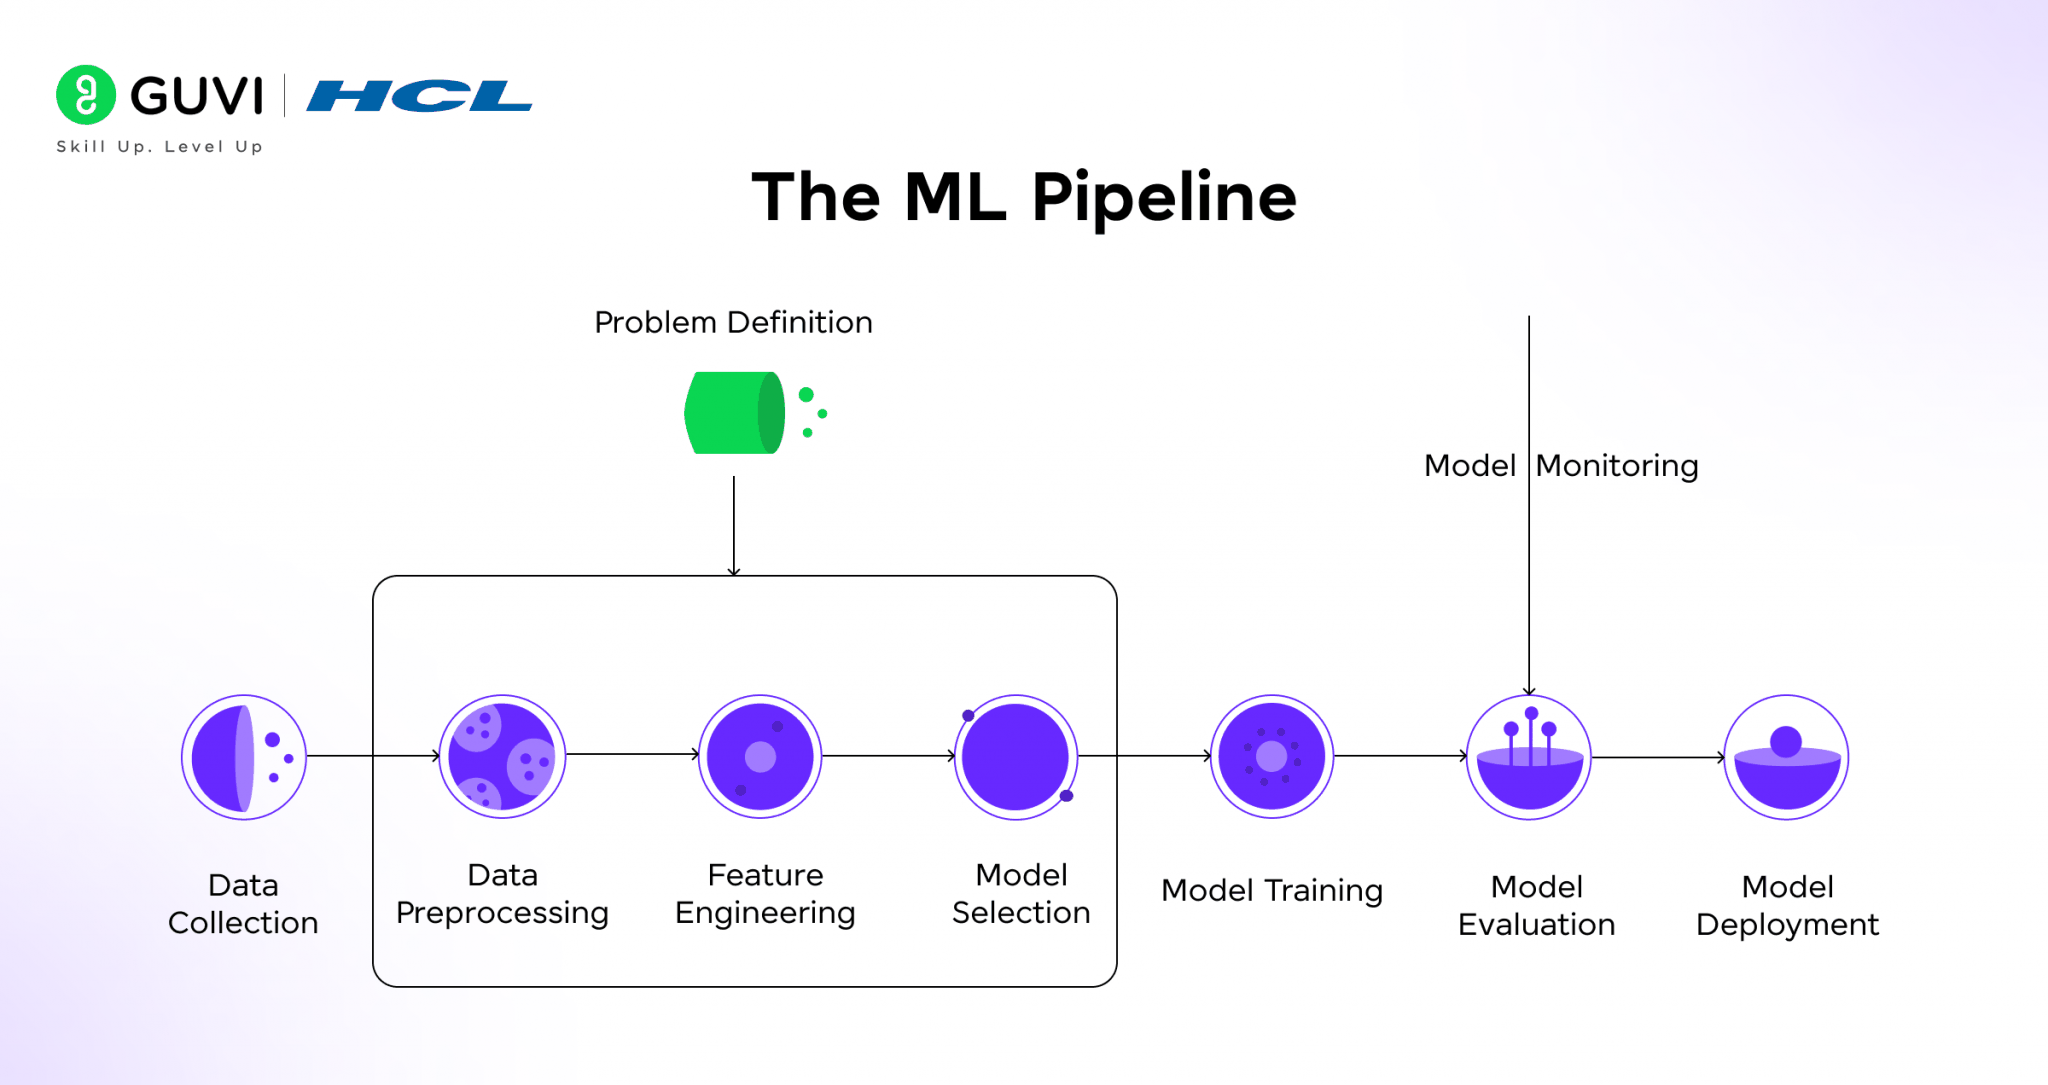
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)