Complete Technical Paper Content — Ai Streamlit Dashboard
1. Executive Abstract, Problem Formulation & Background
ai-driven-streamlit-dashboard An AI-driven modular Streamlit dashboard demonstrating prompt engineering, UI enhancement, and architecture-level refactoring. This project showcases how a simple AI-generated application can evolve into a maintainable, loosely coupled system using structured prompts and software architecture principles.
An AI-driven modular Streamlit dashboard demonstrating prompt engineering, UI enhancement, and architecture-level refactoring. This project showcases how a simple AI-generated application can evolve into a maintainable, loosely coupled system using structured prompts and software architecture principles.
An AI-driven modular Streamlit dashboard demonstrating prompt engineering, UI enhancement, and architecture-level refactoring. This project showcases how a simple AI-generated application can evolve into a maintainable, loosely coupled system using structured prompts and software architecture principles.
IntelliDecision AI A comprehensive machine learning platform for automated model selection, training, and prediction with an intuitive web interface. Overview IntelliDecision AI is a Streamlit-based application that simplifies the machine learning workflow by providing: Data Preprocessing - Automated cleaning and preparation Feature Engineering - Advanced feature extraction and transformation Model Selection - Intelligent algorithm selection for your data Model Training - Automated training with multiple algorithms (XGBoost, LightGBM, Neural Networks) Visualization - Interactive charts and insights Predictions - Real-time predictions on new data Features ✨ Key Capabilities: Multi-algorithm support (Scikit-learn, XGBoost, LightGBM, PyTorch) Interactive data exploration and visualization Automated preprocessing pipeline Model performance comparison SHAP-based model interpretability GPU support for deep learning Docker containerization Installation Local Setup # Clone the repository git clone https://github.com/gldheenadhayalan/IntelliDecision-AI.git cd IntelliDecision-AI # Create virtual environment python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate pip install --upgrade pip setuptools wheel # Install dependencies pip install -r requirements.txt GPU Installation (CUDA Support) Prerequisites: NVIDIA GPU with driver installed Option 1: Direct PyTorch Installation (Recommended) # For CUDA 12.1 (Default) pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121 --force-reinstall # For CUDA 11.8 pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118 --force-reinstall # Verify GPU is available python -c " import torch; print('GPU Available:', torch.cuda.is_available()); print('GPU:', torch.cuda.get_device_name(0) if torch.cuda.is_available() else 'None') " Option 2: Manual CUDA Installation On Windows: Download CUDA Toolkit 12.1 from NVIDIA Download cuDNN from NVIDIA Developer Install CUDA Toolkit (default path: C:\Program Files\NVIDIA GPU Computing Toolkit\CUDA\v12.1 ) Add CUDA to system PATH Verify: nvidia-smi in command prompt Install PyTorch as above On Linux (Ubuntu/Debian): # Install CUDA and cuDNN sudo apt-get install nvidia-cuda-toolkit nvidia-cudnn # Install PyTorch pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121 Verify Installation # Check PyTorch version and CUDA support python -c " import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA Available: {torch.cuda.is_available()}'); print(f'GPU: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else \" None \" }') " Note: If GPU is not detected, ensure NVIDIA drivers are installed and CUDA Toolkit is properly configured. Docker Setup # CPU-based docker-compose up -d # GPU-based docker-compose -f docker-compose.gpu.yml up -d Quick Start Run the Application streamlit run app.py The app will open at http://localhost:8501 Usage Steps Upload Data - CSV file upload in the web interface Explore - View statistics and visualizations Preprocess - Handle missing values and scaling Engineer Features - Create new features Train Models - Select and train algorithms Evaluate - Compare model performance Predict - Make predictions on new data Project Structure IntelliDecision-AI/ ├── app.py # Main Streamlit application ├── requirements.txt # Python dependencies ├── Dockerfile # Container setup ├── docker-compose.yml # Docker orchestration ├── src/ │ ├── preprocessing.py # Data cleaning & preparation │ ├── feature_engineering.py # Feature creation │ ├── model_training.py # Model training logic │ ├── model_selection.py # Algorithm selection │ ├── prediction_module.py # Inference pipeline │ ├── visualization.py # Plotting utilities │ └── pipeline.py # Unified pipeline ├── models/ # Saved trained models ├── prediction/ # Prediction utilities ├── artifacts/ # Generated artifacts └── datas/ # Sample datasets Requirements Python 3.8+ Streamlit 1.28.0+ Scikit-learn, XGBoost, LightGBM PyTorch (optional, for deep learning) Pandas, NumPy, Matplotlib, Seaborn Supported Models Regression : Linear Regression, Ridge, Lasso, ElasticNet, SVR, Random Forest, XGBoost, LightGBM, Neural Networks Classification : Logistic Regression, SVM, Random Forest, XGBoost, LightGBM, Neural Networks Clustering : K-Means, DBSCAN Dimensionality Reduction : PCA, t-SNE Docker Deployment # Build image docker build -t intellidecision-ai . # Run container docker run -p 8501:8501 intellidecision-ai Configuration Environment variables (optional): MODEL_PATH - Custom model save location DATA_PATH - Default data directory LOG_LEVEL - Logging verbosity Performance Tips Use GPU for large datasets (set up with GPU Docker image) Preprocess data to optimal sizes Use cross-validation for better model evaluation Enable SHAP for advanced interpretability Troubleshooting Port already in use: streamlit run app.py --server.port 8502 GPU not detected: python -c " import torch; print(torch.cuda.is_available()) " Support For issues and questions, please open a GitHub issue or contact the development team. Built with ❤️ for intelligent decision-making through machine learning
A comprehensive machine learning platform for automated model selection, training, and prediction with an intuitive web interface.
IntelliDecision AI is a Streamlit-based application that simplifies the machine learning workflow by providing:
# Clone the repository git clone https://github.com/gldheenadhayalan/IntelliDecision-AI.git cd IntelliDecision-AI # Create virtual environment python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate pip install --upgrade pip setuptools wheel # Install dependencies pip install -r requirements.txt
# For CUDA 12.1 (Default) pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121 --force-reinstall # For CUDA 11.8 pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu118 --force-reinstall # Verify GPU is available python -c " import torch; print('GPU Available:', torch.cuda.is_available()); print('GPU:', torch.cuda.get_device_name(0) if torch.cuda.is_available() else 'None') "
2. Related Work, Literature Survey & Algorithmic Foundations
# Install CUDA and cuDNN sudo apt-get install nvidia-cuda-toolkit nvidia-cudnn # Install PyTorch pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121
# Check PyTorch version and CUDA support python -c " import torch; print(f'PyTorch: {torch.__version__}'); print(f'CUDA Available: {torch.cuda.is_available()}'); print(f'GPU: {torch.cuda.get_device_name(0) if torch.cuda.is_available() else \" None \" }') "
Note: If GPU is not detected, ensure NVIDIA drivers are installed and CUDA Toolkit is properly configured.
# CPU-based docker-compose up -d # GPU-based docker-compose -f docker-compose.gpu.yml up -d
IntelliDecision-AI/ ├── app.py # Main Streamlit application ├── requirements.txt # Python dependencies ├── Dockerfile # Container setup ├── docker-compose.yml # Docker orchestration ├── src/ │ ├── preprocessing.py # Data cleaning & preparation │ ├── feature_engineering.py # Feature creation │ ├── model_training.py # Model training logic │ ├── model_selection.py # Algorithm selection │ ├── prediction_module.py # Inference pipeline │ ├── visualization.py # Plotting utilities │ └── pipeline.py # Unified pipeline ├── models/ # Saved trained models ├── prediction/ # Prediction utilities ├── artifacts/ # Generated artifacts └── datas/ # Sample datasets
# Build image docker build -t intellidecision-ai . # Run container docker run -p 8501:8501 intellidecision-ai
A comprehensive Streamlit-based dashboard for intelligent model selection, training, and prediction using Machine Learning (ML) and Deep Learning (DL) algorithms. This system empowers businesses to make data-driven decisions through automated model evaluation, performance visualization, and predictive analytics.
📊 Streamlit ML Dashboard Template A comprehensive machine learning dashboard template built with Streamlit, featuring data exploration, model training, predictions, and performance evaluation. 🎯 Features 📊 Data Exploration Interactive CSV file upload Statistical summaries and data profiling Missing value analysis Correlation matrices and heatmaps Interactive visualizations with Plotly 🧠 Model Training Support for classification and regression tasks Multiple algorithms: Logistic Regression Random Forest (Classifier/Regressor) Linear Regression Automated data preprocessing Feature selection capabilities Model persistence and saving 📈 Predictions Single instance predictions Batch predictions from CSV files Probability scores for classification Downloadable prediction results Real-time model loading 🧪 Model Evaluation Comprehensive performance metrics Interactive confusion matrices ROC curves and AUC scores Feature importance analysis Residual plots for regression Detailed classification reports 🚀 Quick Start Prerequisites Python 3.8+ pip package manager Installation Clone the repository git clone https://github.com/freewimoe/streamlit-ml-dashboard.git cd streamlit-ml-dashboard Install dependencies pip install -r requirements.txt Run the application streamlit run app/app.py Open your browser Navigate to http://localhost:8501 📊 Sample Data Included Try these sample datasets: Classification Example (Iris Dataset): Location: data/raw/sample_iris.csv Target: species Features: sepal_length, sepal_width, petal_length, petal_width Problem: Multi-class classification Regression Example (House Prices): Location: data/raw/sample_house_prices.csv Target: price Features: bedrooms, bathrooms, sqft, age Problem: Regression 📁 Project Structure streamlit-ml-dashboard/ ├── app/ │ ├── app.py # Main application entry point │ └── app_pages/ │ ├── __init__.py │ ├── 1_00_📘_Project_Summary.py │ ├── 1_01_🔎_EDA.py │ ├── 1_02_🧠_Train_Model.py │ ├── 1_03_📈_Predict.py │ └── 1_04_🧪_Model_Metrics.py ├── data/ │ ├── raw/ # Raw data files │ ├── processed/ # Processed data files │ └── interim/ # Intermediate data files ├── models/ │ └── versioned/ # Saved model files ├── notebooks/ # Jupyter notebooks for development ├── src/ # Source code utilities ├── tests/ # Unit tests ├── requirements.txt # Python dependencies ├── runtime.txt # Python runtime version ├── Procfile # Deployment configuration └── README.md # This file 📖 Usage Guide 1. Data Exploration Upload your CSV file in the EDA section Explore statistical summaries and visualizations Analyze missing values and correlations 2. Model Training Upload training data Select target variable and features Choose algorithm and parameters Train and save your model 3. Making Predictions Use single prediction for individual cases Upload CSV for batch predictions Download results with confidence scores 4. Model Evaluation Upload test data to evaluate performance View comprehensive metrics and visualizations Analyze feature importance and model behavior 🛠️ Technologies Used Streamlit : Web app framework Scikit-learn : Machine learning library Plotly : Interactive visualizations Pandas : Data manipulation NumPy : Numerical computing 🚀 Deployment Streamlit Cloud Push your code to GitHub Connect your repository to Streamlit Cloud Deploy with one click Heroku # Login to Heroku heroku login # Create new app heroku create your-app-name # Deploy git push heroku main 🤝 Contributing Fork the repository Create a feature branch ( git checkout -b feature/AmazingFeature ) Commit your changes ( git commit -m 'Add some AmazingFeature' ) Push to the branch ( git push origin feature/AmazingFeature ) Open a Pull Request 📝 License This project is licensed under the MIT License - see the LICENSE file for details. 🙏 Acknowledgments Streamlit team for the amazing framework Scikit-learn contributors for the ML tools Plotly for interactive visualizations ⭐ Star this repository if you find it helpful! ⭐
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
A comprehensive machine learning dashboard template built with Streamlit, featuring data exploration, model training, predictions, and performance evaluation.
git clone https://github.com/freewimoe/streamlit-ml-dashboard.git cd streamlit-ml-dashboard
streamlit-ml-dashboard/ ├── app/ │ ├── app.py # Main application entry point │ └── app_pages/ │ ├── __init__.py │ ├── 1_00_📘_Project_Summary.py │ ├── 1_01_🔎_EDA.py │ ├── 1_02_🧠_Train_Model.py │ ├── 1_03_📈_Predict.py │ └── 1_04_🧪_Model_Metrics.py ├── data/ │ ├── raw/ # Raw data files │ ├── processed/ # Processed data files │ └── interim/ # Intermediate data files ├── models/ │ └── versioned/ # Saved model files ├── notebooks/ # Jupyter notebooks for development ├── src/ # Source code utilities ├── tests/ # Unit tests ├── requirements.txt # Python dependencies ├── runtime.txt # Python runtime version ├── Procfile # Deployment configuration └── README.md # This file
# Login to Heroku heroku login # Create new app heroku create your-app-name # Deploy git push heroku main
Complete Machine Learning Dashboard Template with Streamlit - Features EDA, Model Training, Predictions & Metrics
AI & Machine Learning Projects Collection This repository contains multiple Machine Learning and Deep Learning projects built using Python, Streamlit, Scikit-learn, TensorFlow, Pandas, NumPy, and Matplotlib. The projects focus on real-world AI applications including classification, prediction, computer vision, and business analytics. The repository includes complete source code, datasets, trained models, preprocessing pipelines, and interactive Streamlit dashboards. Projects Included 1. Bengaluru Housing Price Prediction A Machine Learning web application that predicts house prices in Bengaluru based on property details such as area, number of bedrooms, and bathrooms. Features Data preprocessing and cleaning Area conversion handling Linear Regression model Interactive Streamlit interface Real-time house price prediction Data visualization dashboard Screenshots Technologies Used Python Pandas Scikit-learn Matplotlib Streamlit 2. Handwritten Digit Recognition using CNN A Deep Learning application that recognizes handwritten digits using a Convolutional Neural Network trained on the MNIST dataset. Features CNN-based digit classification Interactive drawing canvas Image upload support Real-time prediction Prediction confidence visualization Cached model loading TensorFlow/Keras implementation Screenshots Technologies Used Python TensorFlow Keras NumPy PIL Streamlit streamlit-drawable-canvas 3. Iris Flower Classification A Machine Learning classification project that predicts the species of an Iris flower based on sepal and petal measurements. Features Logistic Regression model Interactive sliders for input Prediction probability visualization Dataset viewer Model accuracy display Species information section Screenshots Technologies Used Python Scikit-learn Pandas NumPy Streamlit 4. Telecom Customer Churn Prediction Dashboard A professional Machine Learning dashboard that predicts whether a telecom customer is likely to churn based on customer behavior and service usage. Features Data preprocessing and encoding Random Forest Classification model Customer churn prediction Probability score calculation KPI dashboard Churn distribution visualization Interactive sidebar controls Model accuracy evaluation Screenshots Technologies Used Python Pandas NumPy Scikit-learn Streamlit Repository Structure ├── dataset/ │ ├── Bengaluru_House_Data.csv │ ├── Telco-Customer-Churn.csv │ ├── Housing_Price_Prediction/ │ ├── app.py │ ├── Digit_Recognition_CNN/ │ ├── app.py │ ├── mnist_model.h5 │ ├── Iris_Classification/ │ ├── app.py │ ├── Customer_Churn_Prediction/ │ ├── app.py │ ├── requirements.txt ├── README.md Installation Clone the repository: git clone https://github.com/your-username/your-repository-name.git Move into the project directory: cd your-repository-name Install dependencies: pip install -r requirements.txt Running Streamlit Applications Run any project using: streamlit run app.py Example: cd Iris_Classification streamlit run app.py Skills Demonstrated This repository demonstrates practical implementation of: Machine Learning Deep Learning Data Preprocessing Model Training Model Evaluation Classification Algorithms Regression Algorithms CNN Architecture Data Visualization Streamlit Deployment Interactive Dashboard Development Feature Engineering Predictive Analytics Libraries Used Streamlit Pandas NumPy Scikit-learn TensorFlow Matplotlib PIL streamlit-drawable-canvas 👨💻 Author Omkar Koli
This repository contains multiple Machine Learning and Deep Learning projects built using Python, Streamlit, Scikit-learn, TensorFlow, Pandas, NumPy, and Matplotlib. The projects focus on real-world AI applications including classification, prediction, computer vision, and business analytics.
The repository includes complete source code, datasets, trained models, preprocessing pipelines, and interactive Streamlit dashboards.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
A Machine Learning web application that predicts house prices in Bengaluru based on property details such as area, number of bedrooms, and bathrooms.
A Deep Learning application that recognizes handwritten digits using a Convolutional Neural Network trained on the MNIST dataset.
A Machine Learning classification project that predicts the species of an Iris flower based on sepal and petal measurements.
A professional Machine Learning dashboard that predicts whether a telecom customer is likely to churn based on customer behavior and service usage.
├── dataset/ │ ├── Bengaluru_House_Data.csv │ ├── Telco-Customer-Churn.csv │ ├── Housing_Price_Prediction/ │ ├── app.py │ ├── Digit_Recognition_CNN/ │ ├── app.py │ ├── mnist_model.h5 │ ├── Iris_Classification/ │ ├── app.py │ ├── Customer_Churn_Prediction/ │ ├── app.py │ ├── requirements.txt ├── README.md
AI & Machine Learning projects built with Python, Streamlit, TensorFlow, and Scikit-learn. Collection of AI, Deep Learning, and Data Science projects with interactive dashboards. Real-world Machine Learning and Deep Learning applications using Python and Streamlit. Machine Learning, CNN, and predictive analytics projects with deployment-ready inter
🧠 FlexiLearn AI Playground A No-Code Machine Learning & Deep Learning Platform Train and compare ML/DL models through an intuitive web interface—no coding required. Upload your data, choose a model, and get instant results with visualizations. The FlexiLearn AI interface: your personal ML/DL laboratory 🌟 Key Features Three Data Types : Tabular (CSV/Excel), Images (ZIP), Time Series Multiple Models : Classical ML (Scikit-learn), Deep Learning (PyTorch), RNN (Keras) Auto Preprocessing : One-click data preparation Custom Networks : Build your own neural architectures or use suggested templates Rich Visualizations : Confusion matrices, ROC curves, loss curves, forecasts Model Comparison : Track and compare all your training runs Export Models : Download trained models for deployment 🚀 Getting Started Prerequisites Python 3.8 or higher pip package manager Installation Clone or download this repository Navigate to the project directory : cd Streamlit_app_deep Create a virtual environment (recommended): # Windows python -m venv .venv .venv \S cripts \a ctivate # macOS/Linux python3 -m venv .venv source .venv/bin/activate Install dependencies : pip install -r requirements.txt Launch the application : # From the Streamlit_app_deep directory python -m streamlit run src/app.py Open your browser to the URL shown in the terminal (typically http://localhost:8501 ) Project Structure src/ ├── app.py # Main application ├── ui/ # User interface ├── models/ # Custom datasets ├── evaluation/ # Visualizations └── utils/ # Utilities 📚 User Guide Step 1: Choose Your Data Choose your data source from the sidebar Three Options: Upload Files Tabular: .csv , .xlsx (max 500MB) Images: .zip with folders per class Time Series: .csv , .xlsx with date column Classic Datasets Iris (Classification) California Housing (Regression) Built-in datasets for quick testing Generate Synthetic Time Series Auto-generated sales data Includes trend and seasonality Perfect for RNN experiments Synthetic data for forecasting practice Step 2: Preprocess Data Tabular Data: Select target column and click "Quick Process" Automatic handling of missing values Feature scaling and encoding 80/20 train-test split Data ready for training Image Data: Configure image size and train-test split Resize images (32x32 to 256x256) Automatic normalization Display sample images Time Series: View trends and seasonal patterns Visualize data over time Seasonal decomposition (Trend, Seasonality, Residual) Understand patterns before forecasting Step 3: Train Your Model Classical ML (Scikit-learn): Choose from Logistic Regression, Random Forest, SVM, KNN, or Decision Trees. Adjust parameters and click Train . Deep Learning (PyTorch): Suggested Mode : Pre-configured architectures for quick starts Custom Mode : Build your own network layer by layer Architecture Guide provides real-time tips for building your network For Tabular Data (ANNs): Build custom neural networks layer by layer Add Dense layers with neurons, activation functions (ReLU recommended), and dropout for regularization. Output layer is automatically configured. For Image Data (CNNs): Build CNNs with convolutional and pooling layers CNNs learn spatial patterns in images. Add Conv2d layers (filters, kernel size) and MaxPool2d layers for downsampling. The network automatically flattens and adds dense layers for classification. Training: Configure learning rate, epochs, and batch size Learning Rate : How fast the model learns (0.001 recommended) Epochs : Number of training passes (20-50 typical) Batch Size : Samples per update (32 recommended) Click Train and monitor the progress. Loss should decrease, accuracy should increase. Time Series (RNNs): RNNs handle sequential data with memory. Choose from Simple RNN, LSTM (recommended), or GRU. Suggested Mode: Pre-configured RNN with optimal settings Custom Mode: Control window size, layers, units, and training parameters. Training progress and forecast results Step 4: Evaluate Results Model Comparison Table: View all trained models with their metrics (Accuracy, MSE, R², etc.) Detailed Analysis: Classification: Confusion Matrix Precision, Recall, F1-Score ROC Curves with AUC Training curves (Deep Learning) Monitor training progress Regression: MSE, RMSE, MAE, R² Score Predictions vs Actual Forecasting (RNN): Loss curves over epochs Predictions timeline (train/test) Error metrics (RMSE, MAE, R²) Step 5: Export Models Download trained models: .pkl for Classical ML .pth for PyTorch .keras for RNN Load and Use: # Classical ML import pickle with open ( 'model.pkl' , 'rb' ) as f : model = pickle . load ( f ) predictions = model . predict ( new_data ) # PyTorch import torch model . load_state_dict ( torch . load ( 'model.pth' )) predictions = model ( new_data_tensor ) # RNN (Keras) from keras . models import load_model model = load_model ( 'rnn_model.keras' ) predictions = model . predict ( scaled_sequences ) 🔧 Troubleshooting Import errors : Activate virtual environment, run pip install -r requirements.txt Upload fails : Check .streamlit/config.toml for 500MB limit Slow training : Reduce batch size, image size, or epochs Overfitting : Add dropout, reduce complexity, get more data NaN loss : Lower learning rate to 0.0001 👨💻 Author Built By BELLMIR Yahya Happy Learning! 🚀
Train and compare ML/DL models through an intuitive web interface—no coding required. Upload your data, choose a model, and get instant results with visualizations.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
# Windows python -m venv .venv .venv \S cripts \a ctivate # macOS/Linux python3 -m venv .venv source .venv/bin/activate
src/ ├── app.py # Main application ├── ui/ # User interface ├── models/ # Custom datasets ├── evaluation/ # Visualizations └── utils/ # Utilities
Choose from Logistic Regression, Random Forest, SVM, KNN, or Decision Trees. Adjust parameters and click Train .
Add Dense layers with neurons, activation functions (ReLU recommended), and dropout for regularization. Output layer is automatically configured.
CNNs learn spatial patterns in images. Add Conv2d layers (filters, kernel size) and MaxPool2d layers for downsampling. The network automatically flattens and adds dense layers for classification.
RNNs handle sequential data with memory. Choose from Simple RNN, LSTM (recommended), or GRU.
# Classical ML import pickle with open ( 'model.pkl' , 'rb' ) as f : model = pickle . load ( f ) predictions = model . predict ( new_data ) # PyTorch import torch model . load_state_dict ( torch . load ( 'model.pth' )) predictions = model ( new_data_tensor ) # RNN (Keras) from keras . models import load_model model = load_model ( 'rnn_model.keras' ) predictions = model . predict ( scaled_sequences )
🧠 FlexiLearn AI: A no-code Streamlit platform for training, evaluating, and comparing classical ML (scikit-learn) and deep learning (PyTorch) models. Supports tabular data (CSV/Excel) and images (ZIP). Build custom ANNs/CNNs with an interactive architecture builder. Perfect for ML education and experimentation.
Model Figures & Evaluation Curves (4 Images)
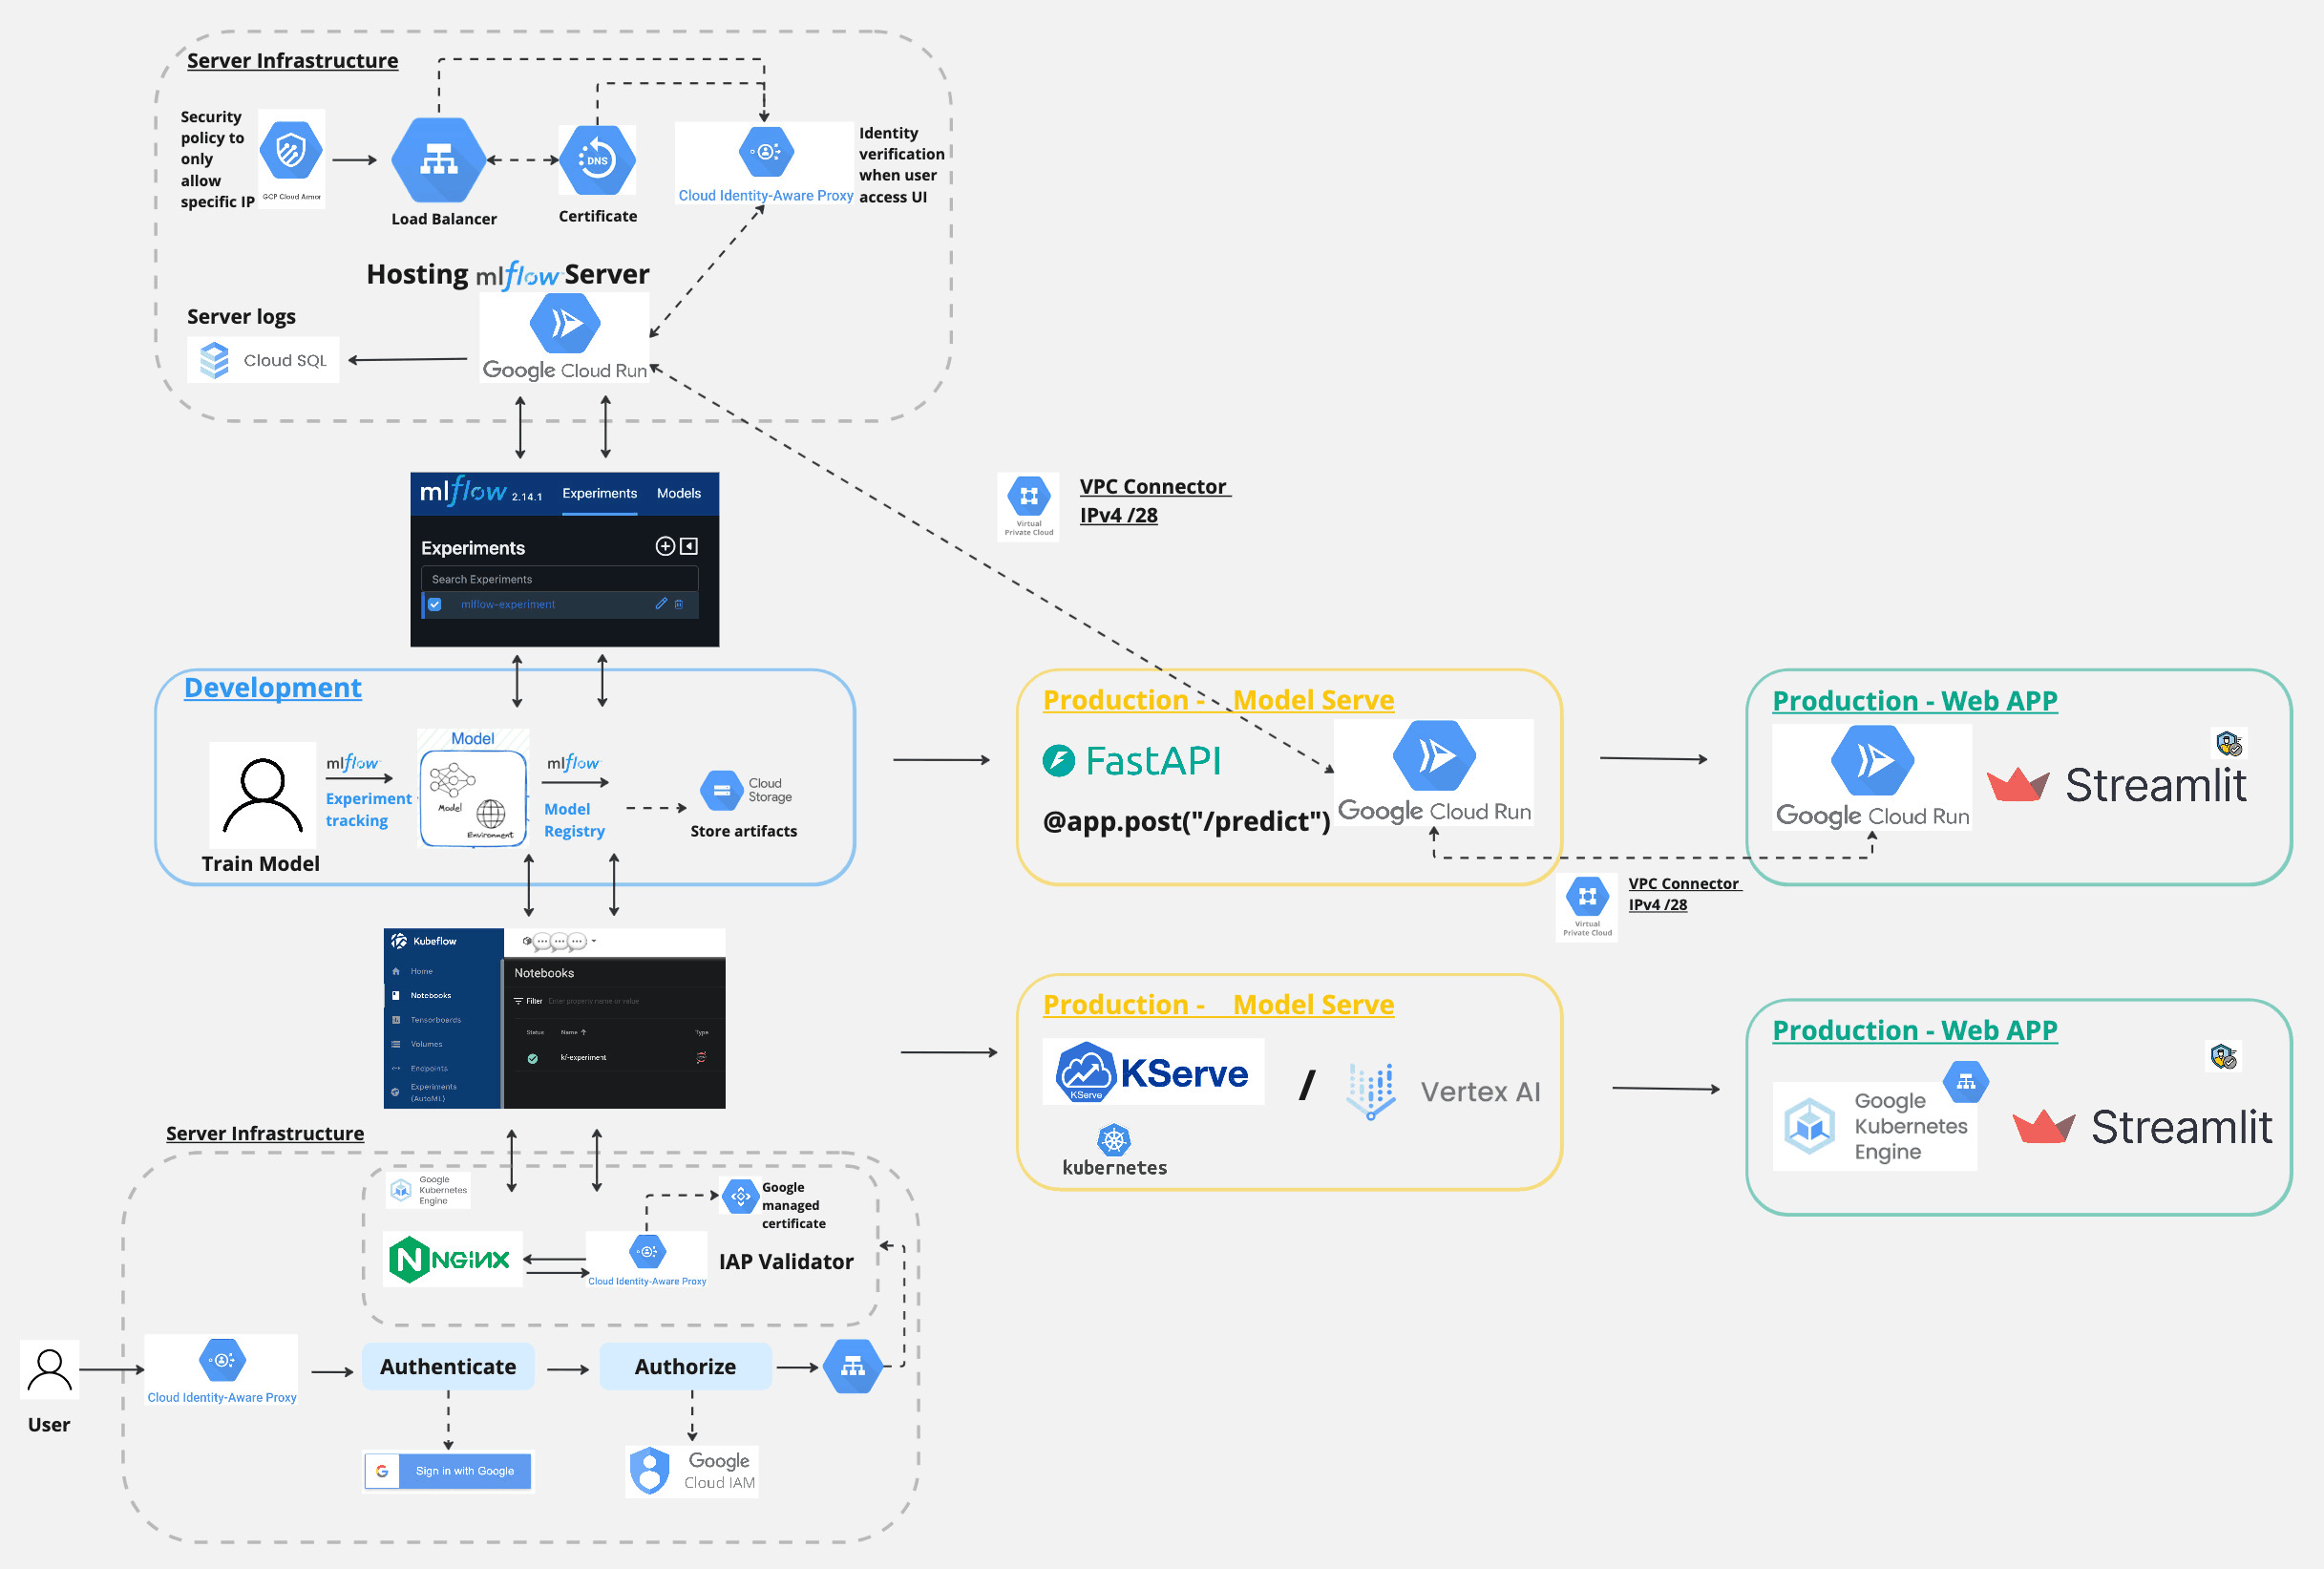
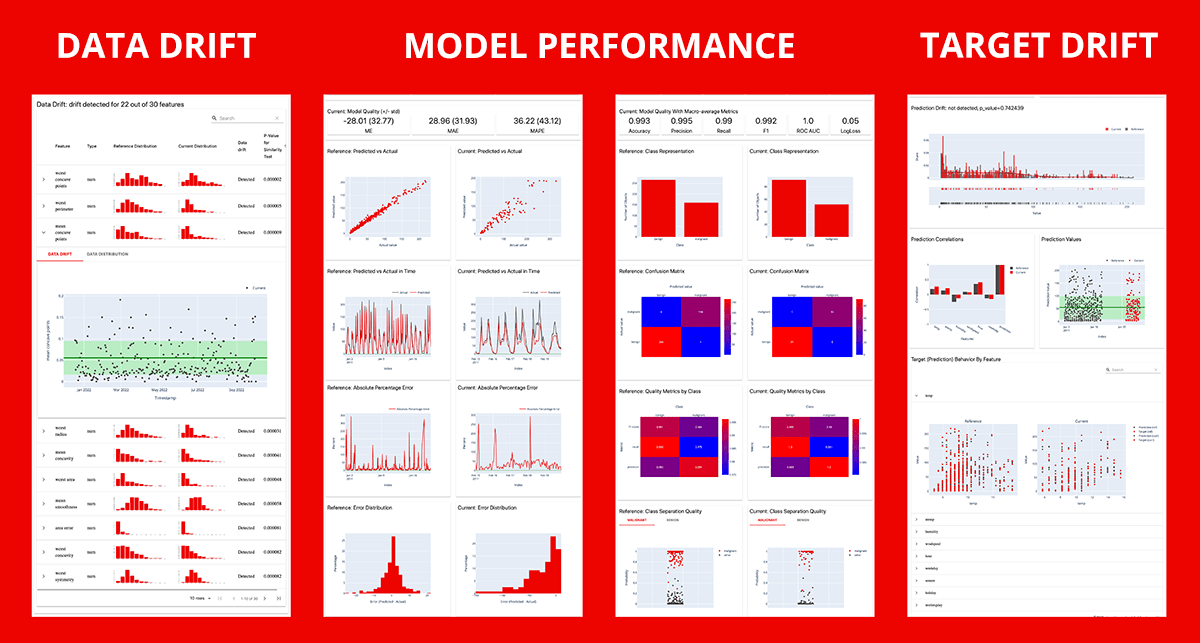
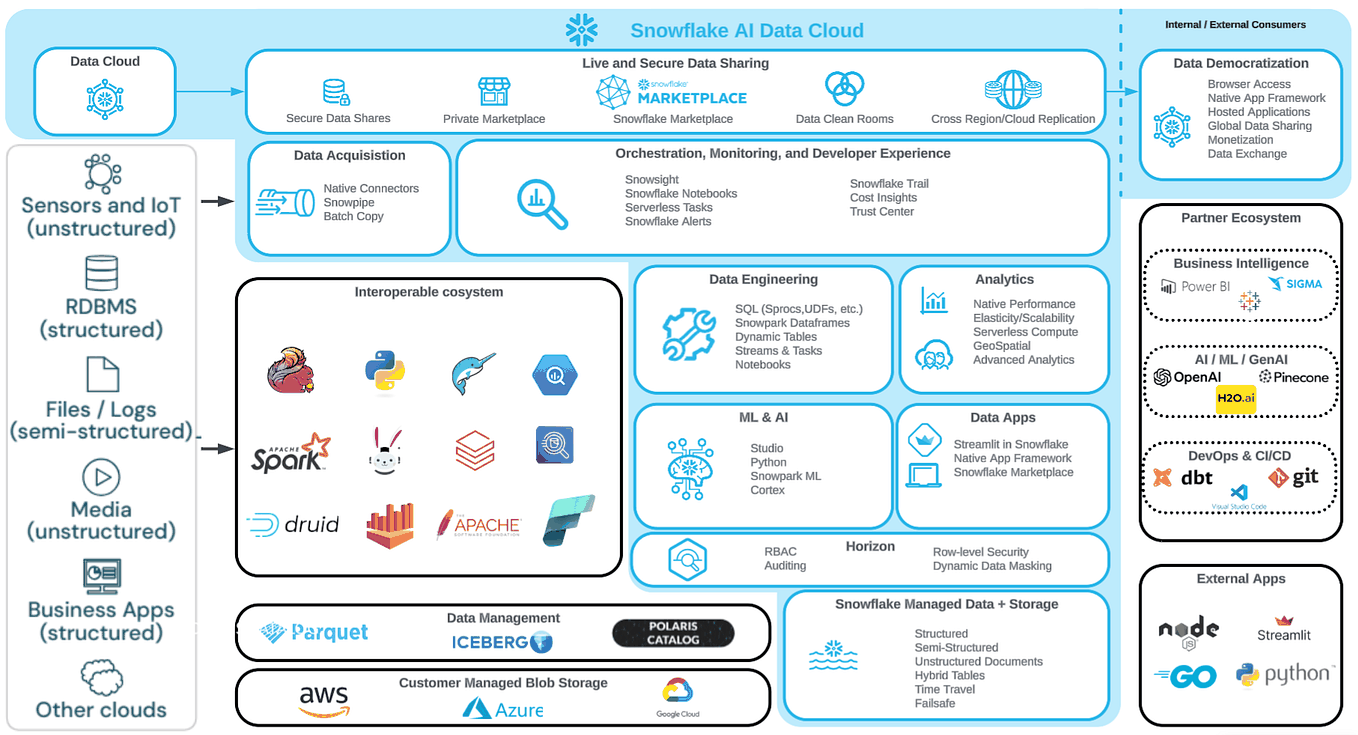
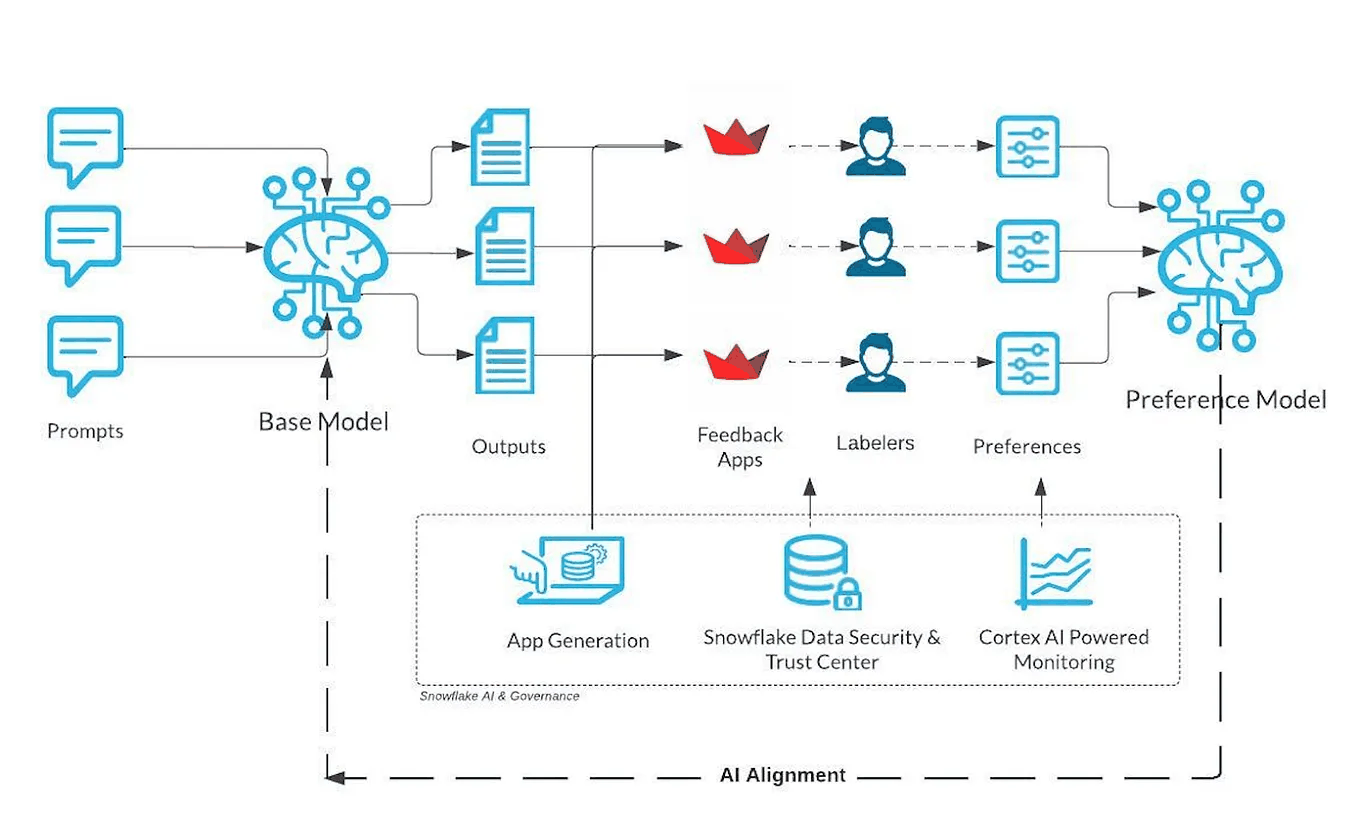
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)