Complete Technical Paper Content — Ai Translation Tools
1. Executive Abstract, Problem Formulation & Background
An AI agent, also known as agentic AI, is an artificial intelligence program that can make decisions, pursue goals, and take actions independently of human programmers. Agentic AI contrasts with tool-like AI use for narrow, specific tasks such as answering questions, as with chatbots in the non-agentic forms that were common since 2023, or with traditional machine learning algorithms. While there is no universally agreed-upon definition of an AI agent, common attributes of AI agents include goal-directed behavior, use of external tools, the ability to interact with and modify an external environment, and the ability to autonomously perform multi-step tasks. Their control flow is frequently driven by large language models (LLMs). Agent systems may also include memory components, planning logic, tool interfaces, and orchestration software for coordinating agent components.
The theoretical underpinnings for artificial agents emerged in the mid 20th century, with establishment of cybernetics and artificial intelligence. Oliver Selfridge's 1958 "Pandemonium: A Paradigm for Learning" paper was an important early theoretical contribution in establishing agent oriented architecture. Practical implementations of agents for real world applications began to become widespread in the 1990s, after the introduction of the belief–desire–intention software model (BDI), and agent-oriented programming. Harvard professor Milind Tambe notes that in the 1990s, the definition of an AI agent was not clear. Pure digital agents were deployed in computer infrastructure for purposes such as monitoring, while agents connected to real-world sensors and actuators were increasingly used in industrial control systems. Early artificial agents tended to have simple if then logic, which expanded over time into large decision tree models. By the early 2010s, products like Siri and Alexa were released, and were sometimes called AI agents, though they lacked the general purpose reasoning ability of later agents run by large language models (LLMs). The development of LLMs during the late 2010s and early 2020s introduced new approaches to AI agents. Models such as GPT-3 demonstrated the ability to generate and understand natural language at a much larger scale than many earlier language systems. Academics began to study LLM agents from 2018. Deployment of such agents began to accelerate in late 2023 after OpenAI's "function-calling" API was made available, and especially after Anthropic's late 2024 introduction of Model Context Protocol (MCP), a standardised way for LLM agents to gain contextual awareness, and to act on the world by calling various external tools. The term "agentic" only began to be used with any frequency in 2024, popularised in part by researcher Andrew Ng.
Ken Huang proposed an AI agent reference architecture that consists of seven interconnected layers, with each layer building on the functionality of the layers beneath it:
Layer 1: Foundation models – provide the datasets that power the agent. Layer 2: Data operations – manages the data infrastructure required for AI agent operations, including vector databases, data loaders, and RAG. Layer 3: Agent frameworks – software that manages the AI agents. Layer 4: Deployment and infrastructure – the technical foundation of the AI agents. Layer 5: Evaluation and observability – the safety and performance of AI agents. Layer 6: Security and compliance – a protective framework for safe operation and compliance with regulatory boundaries. At this layer, security and compliance features embedded into all the AI agent stack layers are integrated together. Layer 7: Agent ecosystem – represents the AI agents' interface with real-world applications and users.
An agent harness, or agent scaffold, is the software layer surrounding a large language model that enables it to function as an AI agent. It commonly manages prompts, context, tool use, memory, execution state, operational constraints, sandboxes, permissions, and the processing of results. The harness connects the model to internal and external computer hardware, software, data files, databases, web browsers, command-line interfaces, and application programming interfaces, while controlling how the agent accesses and uses these resources to complete multi-step tasks.
Prompt chaining: A sequence where the output of one step serves as the input for the next. Routing: Directing an input to a specialized downstream task or tool. Parallelization: The simultaneous execution of multiple tasks. Sequential processing: A fixed, linear progression of tasks through a predefined pipeline. Planner-critic: An iterative pattern where one agent generates a proposal and another evaluates it to provide feedback for refinement.
STRIDE: A Microsoft model that identifies threats across six categories: spoofing, tampering, repudiation, information disclosure, denial of service, and elevation of privilege. MITRE ATLAS: A knowledge base of adversary tactics and techniques for AI systems. OWASP GenAI Security Project: Provides guidance on vulnerabilities associated with generative AI and large language model integration, including guidelines specifically for agentic applications. MAESTRO: A framework from the Cloud Security Alliance for assessing risks in AI systems throughout their lifecycle.
The following outline is provided as an overview of, and topical guide to, machine learning: Machine learning (ML) is a subfield of artificial intelligence within computer science that evolved from the study of pattern recognition and computational learning theory. In 1959, Arthur Samuel defined machine learning as a "field of study that gives computers the ability to learn without being explicitly programmed". ML involves the study and construction of algorithms that can learn from and make predictions on data. These algorithms operate by building a model from a training set of example observations to make data-driven predictions or decisions expressed as outputs, rather than following strictly static program instructions.
Canonical correlation analysis (CCA) Factor analysis Feature extraction Feature selection Independent component analysis (ICA) Linear discriminant analysis (LDA) Multidimensional scaling (MDS) Non-negative matrix factorization (NMF) Partial least squares regression (PLSR) Principal component analysis (PCA) Principal component regression (PCR) Projection pursuit Sammon mapping t-distributed stochastic neighbor embedding (t-SNE)
2. Related Work, Literature Survey & Algorithmic Foundations
AdaBoost Boosting Bootstrap aggregating (also "bagging" or "bootstrapping") Ensemble averaging Gradient boosted decision tree (GBDT) Gradient boosting Random Forest Stacked Generalization
Q-learning State–action–reward–state–action (SARSA) Temporal difference learning (TD) Learning Automata
Averaged one-dependence estimators (AODE) Artificial neural network Case-based reasoning Gaussian process regression Gene expression programming Group method of data handling (GMDH) Inductive logic programming Instance-based learning Lazy learning Learning Automata Learning Vector Quantization Logistic Model Tree Minimum message length (decision trees, decision graphs, etc.) Nearest Neighbor Algorithm Analogical modeling Probably approximately correct learning (PAC) learning Ripple down rules, a knowledge acquisition methodology Symbolic machine learning algorithms Support vector machines Random Forests Ensembles of classifiers Bootstrap aggregating (bagging) Boosting (meta-algorithm) Ordinal classification Conditional Random Field ANOVA Quadratic classifiers k-nearest neighbor Boosting SPRINT Bayesian networks Naive Bayes Hidden Markov models Hierarchical hidden Markov model
Bayesian knowledge base Naive Bayes Gaussian Naive Bayes Multinomial Naive Bayes Averaged One-Dependence Estimators (AODE) Bayesian Belief Network (BBN) Bayesian Network (BN)
Decision tree Classification and regression tree (CART) Iterative Dichotomiser 3 (ID3) C4.5 algorithm C5.0 algorithm Chi-squared Automatic Interaction Detection (CHAID) Decision stump Conditional decision tree ID3 algorithm Random forest SLIQ
Fisher's linear discriminant Linear regression Logistic regression Multinomial logistic regression Naive Bayes classifier Perceptron Support vector machine
Expectation-maximization algorithm Vector Quantization Generative topographic map Information bottleneck method Association rule learning algorithms Apriori algorithm Eclat algorithm
Feedforward neural network Extreme learning machine Convolutional neural network Recurrent neural network Long short-term memory (LSTM) Logic learning machine Self-organizing map
BIRCH DBSCAN Expectation–maximization (EM) Fuzzy clustering Hierarchical clustering k-means clustering k-medians Mean-shift OPTICS algorithm
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Active learning Generative models Low-density separation Graph-based methods Co-training Transduction
Deep belief networks Deep Boltzmann machines Deep Convolutional neural networks Deep Recurrent neural networks Hierarchical temporal memory Generative Adversarial Network Style transfer Transformer Stacked Auto-Encoders
Data Science: Data to Insights from MIT (machine learning) Popular online course by Andrew Ng, at Coursera. It uses GNU Octave. The course is a free version of Stanford University's actual course taught by Ng, see.stanford.edu/Course/CS229 available for free]. mloss is an academic database of open-source machine learning software.
Machine-Translation-using-NLP-and-Deep-Learning This project implements a machine translation system that translates sentences from one language to another using advanced deep learning techniques, specifically focusing on Recurrent Neural Networks (RNNs), Long Short-Term Memory (LSTM) networks, Gated Recurrent Units (GRU), and the Attention Mechanism. The implementation is done in a Jupyter Notebook (machine_translation.ipynb), leveraging popular machine learning frameworks such as TensorFlow and Keras. Table of Contents Introduction Dataset Model Architecture Encoder-Decoder Architecture Recurrent Neural Networks (RNN) Long Short-Term Memory (LSTM) Gated Recurrent Unit (GRU) Attention Mechanism Project Structure Dependencies License Introduction Machine translation is a challenging task in Natural Language Processing (NLP) that involves automatically translating text from one language to another. In this project, we build a machine translation model that uses sequence-to-sequence learning (Seq2Seq) architecture with the attention mechanism to improve translation accuracy. The key components in this project include: Encoder-Decoder Architecture: A model that converts the source sentence into a fixed-length vector (encoder) and then converts this vector back into a target sentence (decoder). RNNs, GRUs, LSTMs: Recurrent neural networks that model the sequential nature of languages. Attention Mechanism: A mechanism that allows the decoder to focus on specific parts of the source sentence during translation. Model Architecture Encoder-Decoder Architecture The encoder-decoder architecture is commonly used in sequence-to-sequence tasks like machine translation. Here's how it works: The encoder processes the input sentence and generates a hidden representation or context vector, which summarizes the information of the entire input sequence. The decoder takes this context vector and generates the target sequence one word at a time. In this project, we use RNN-based architectures (LSTMs, GRUs) for both the encoder and the decoder to handle the sequential nature of text data. Dataset The dataset used in this project consists of paired Spanish and English sentences. The dataset was preprocessed to clean the text, remove punctuation, and tokenize the sentences for feeding into the model. Recurrent Neural Networks (RNN) Recurrent Neural Networks (RNNs) are a class of neural networks that are particularly suited for sequential data such as text. Unlike traditional feedforward neural networks, RNNs maintain a hidden state that can "remember" information from previous time steps, making them powerful for tasks like language modeling and machine translation. However, RNNs suffer from issues like the vanishing gradient problem, which makes it difficult for them to learn long-term dependencies in sequences. To address this, we use advanced variants of RNNs, namely LSTM and GRU. Long Short-Term Memory (LSTM) Long Short-Term Memory (LSTM) networks are a special type of RNN that can learn long-term dependencies more effectively by introducing a gating mechanism. The LSTM unit has three gates: Forget Gate: Decides which information should be thrown away or kept. Input Gate: Updates the cell state with new input information. Output Gate: Controls the output based on the cell state. LSTMs are ideal for handling the long-range dependencies in sequences that are crucial for machine translation tasks. Gated Recurrent Unit (GRU) Gated Recurrent Units (GRUs) are another variant of RNNs that aim to address the vanishing gradient problem. GRUs simplify the LSTM architecture by using only two gates: Update Gate: Decides how much of the previous information to retain. Reset Gate: Controls how much of the past information should be forgotten. GRUs are computationally more efficient than LSTMs while providing comparable performance, making them a popular choice for sequence-based tasks. Attention Mechanism The Attention Mechanism is an enhancement to the traditional encoder-decoder architecture. The problem with using only a fixed-length context vector (as in vanilla Seq2Seq models) is that it forces the model to condense all the information of the input sequence into a single vector. This leads to a loss of information, especially for long sequences. Attention helps the decoder "attend" to different parts of the input sequence at each step of the decoding process. This allows the model to focus on the most relevant parts of the input when predicting each word in the target sentence, which leads to better translation performance. In this project, we implement the attention mechanism to improve the quality of translations, especially for long sentences. Project Structure The project includes the following files: machine_translation.ipynb : This is the main Jupyter notebook that contains the code for preprocessing the dataset, defining the model, training the model, and evaluating it. requirements.txt : A file that contains the list of Python packages and dependencies required to run the project. .gitignore : A file to specify which files/folders to ignore when pushing the project to GitHub. dataset : The file spa.txt is the dataset used in this project. Key Steps in the Project Data Preprocessing : The source and target language sentences are tokenized and padded to ensure uniform length. We use libraries like nltk and TensorFlow for this step. Model Definition : We define an encoder-decoder architecture with attention using Keras's high-level APIs. The encoder processes the input sequence, and the decoder generates the output sequence, guided by the attention mechanism. Training : The model is trained using pairs of input (source language) and output (target language) sentences, with categorical cross-entropy as the loss function and Adam as the optimizer. Evaluation : The trained model is evaluated using BLEU scores, a popular metric for assessing the quality of machine translation systems. Prerequisites Python 3.x Jupyter Notebook Dependencies The project requires the following Python packages, listed in requirements.txt: tensorflow keras numpy pandas nltk matplotlib sklearn License GNU General Public License v3.0 Copyright (C) 2024 Vishweshwar Reddy Veerannagari Everyone is permitted to copy and distribute verbatim copies of this license document, but changing it is not allowed. Preamble The GNU General Public License is a free, copyleft license for software and other kinds of works. The licenses for most software and other practical works are designed to take away your freedom to share and change the works. By contrast, the GNU General Public License is intended to guarantee your freedom to share and change all versions of a program--to make sure it remains free software for all its users. We, the Free Software Foundation, use the GNU General Public License for most of our software; it applies also to any other work released this way by its authors. You can apply it to your programs, too.
This project implements a machine translation system that translates sentences from one language to another using advanced deep learning techniques, specifically focusing on Recurrent Neural Networks (RNNs), Long Short-Term Memory (LSTM) networks, Gated Recurrent Units (GRU), and the Attention Mechanism. The implementation is done in a Jupyter Notebook (machine_translation.ipynb), leveraging popular machine learning frameworks such as TensorFlow and Keras.
Machine translation is a challenging task in Natural Language Processing (NLP) that involves automatically translating text from one language to another. In this project, we build a machine translation model that uses sequence-to-sequence learning (Seq2Seq) architecture with the attention mechanism to improve translation accuracy.
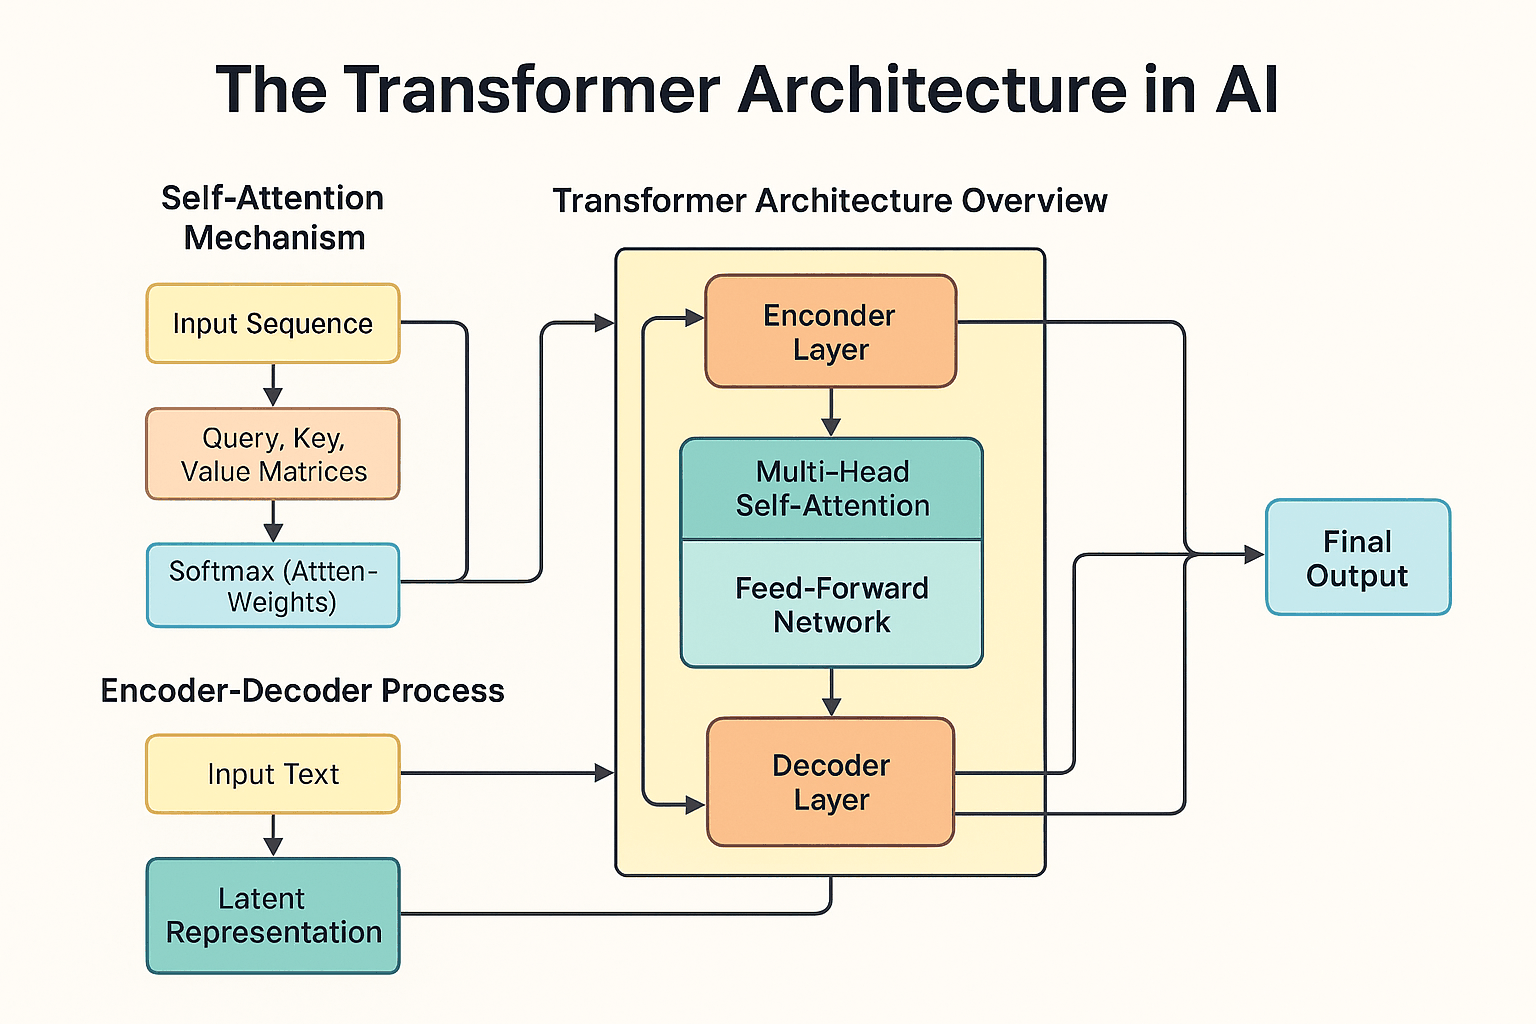
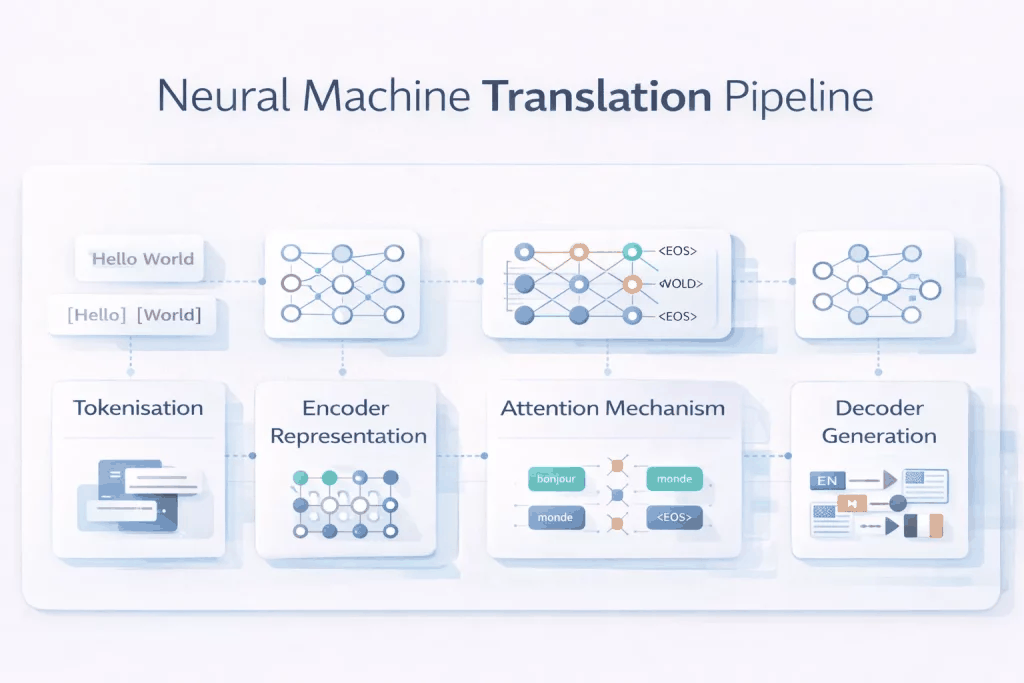
Encoder-Decoder Architecture: A model that converts the source sentence into a fixed-length vector (encoder) and then converts this vector back into a target sentence (decoder). RNNs, GRUs, LSTMs: Recurrent neural networks that model the sequential nature of languages. Attention Mechanism: A mechanism that allows the decoder to focus on specific parts of the source sentence during translation. Model Architecture Encoder-Decoder Architecture The encoder-decoder architecture is commonly used in sequence-to-sequence tasks like machine translation. Here's how it works:
The encoder processes the input sentence and generates a hidden representation or context vector, which summarizes the information of the entire input sequence. The decoder takes this context vector and generates the target sequence one word at a time. In this project, we use RNN-based architectures (LSTMs, GRUs) for both the encoder and the decoder to handle the sequential nature of text data.
The dataset used in this project consists of paired Spanish and English sentences. The dataset was preprocessed to clean the text, remove punctuation, and tokenize the sentences for feeding into the model.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Recurrent Neural Networks (RNNs) are a class of neural networks that are particularly suited for sequential data such as text. Unlike traditional feedforward neural networks, RNNs maintain a hidden state that can "remember" information from previous time steps, making them powerful for tasks like language modeling and machine translation.
However, RNNs suffer from issues like the vanishing gradient problem, which makes it difficult for them to learn long-term dependencies in sequences. To address this, we use advanced variants of RNNs, namely LSTM and GRU.
Long Short-Term Memory (LSTM) networks are a special type of RNN that can learn long-term dependencies more effectively by introducing a gating mechanism. The LSTM unit has three gates:
Forget Gate: Decides which information should be thrown away or kept. Input Gate: Updates the cell state with new input information. Output Gate: Controls the output based on the cell state. LSTMs are ideal for handling the long-range dependencies in sequences that are crucial for machine translation tasks.
Gated Recurrent Units (GRUs) are another variant of RNNs that aim to address the vanishing gradient problem. GRUs simplify the LSTM architecture by using only two gates:
Update Gate: Decides how much of the previous information to retain. Reset Gate: Controls how much of the past information should be forgotten. GRUs are computationally more efficient than LSTMs while providing comparable performance, making them a popular choice for sequence-based tasks.
The Attention Mechanism is an enhancement to the traditional encoder-decoder architecture. The problem with using only a fixed-length context vector (as in vanilla Seq2Seq models) is that it forces the model to condense all the information of the input sequence into a single vector. This leads to a loss of information, especially for long sequences.
Attention helps the decoder "attend" to different parts of the input sequence at each step of the decoding process. This allows the model to focus on the most relevant parts of the input when predicting each word in the target sentence, which leads to better translation performance.
In this project, we implement the attention mechanism to improve the quality of translations, especially for long sentences.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Everyone is permitted to copy and distribute verbatim copies of this license document, but changing it is not allowed.
The GNU General Public License is a free, copyleft license for software and other kinds of works.
The licenses for most software and other practical works are designed to take away your freedom to share and change the works. By contrast, the GNU General Public License is intended to guarantee your freedom to share and change all versions of a program--to make sure it remains free software for all its users. We, the Free Software Foundation, use the GNU General Public License for most of our software; it applies also to any other work released this way by its authors. You can apply it to your programs, too.
This project implements a machine translation system that translates sentences from one language to another using advanced deep learning techniques, specifically focusing on Recurrent Neural Networks (RNNs), Long Short-Term Memory (LSTM) networks, Gated Recurrent Units (GRU), and the Attention Mechanism.
Language-Translation-using-Deep-Learning This project demonstrates the implementation of a language translation system powered by deep learning techniques and TensorFlow. The primary objective is to build a neural machine translation model that can efficiently translate text from one language to another, making it a valuable tool for cross-lingual communication and content localization Project Description: This project is on machine translation for two "artificial" languages: an "Input Language" and an "Output Language". We want to build a model to translate the texts in the "Input Language" to texts in the "Output Language". For example, a text in the "Input Language" can be "a g b f a f a e a k a j c f b f c d a k a k c e b g a h a k b d b f b f b d c d " , and its translation to the "Output Language" is "b f c f b f c d a j e f g c e b g a k i j b d b f a k l m b f b d a h ed ee ef a k k eg a k h eh a e ei c d a f ej ek a g d el". As a training dataset, a list of 5,000 texts in the Input Language are here, and the corresponding list of 5,000 texts in the Output Language are here. (After downloading them, you can use pickle.load(open(path,'rb')) to open them. They are two lists of strings in Python.) Your task is to design and train a good model, which can take texts in the "Input language" as its input, translate them to the corresponding texts in the "Output Language" and output them. (Note: the final output of your code should not include extra tokens such as [start] or [end]. So if your model's output includes such extra tokens, you need to write a few more lines of code to remove them.) Your trained model will be evaluated using a testing set (which is shown below, and is similar to the above training set). Its performance will be measured by its "accuracy for words", defined as follows. Given a text, a word is a continuous sequence of letters separated by space in the text. (For example, the text "b f c ej ek d el" has 7 words: "b", "f", "c", "ej", "ek", "d" and "el".) "Accuracy" is defined as the fraction of words in the ground-truth text (in the Output Language) that are shown correctly in your model's output. (For example, if the ground-truth text is "b f c ej ek d el" and your model's output is "b c el", then your result has 1 correct word and 6 mistaken words (since the ground-truth text has 7 words in total). If your model's output is "b c el ej ek a b c d f g", then your result has 3 correct words and 4 mistaken words.)
This project demonstrates the implementation of a language translation system powered by deep learning techniques and TensorFlow. The primary objective is to build a neural machine translation model that can efficiently translate text from one language to another, making it a valuable tool for cross-lingual communication and content localization
Project Description: This project is on machine translation for two "artificial" languages: an "Input Language" and an "Output Language". We want to build a model to translate the texts in the "Input Language" to texts in the "Output Language". For example, a text in the "Input Language" can be "a g b f a f a e a k a j c f b f c d a k a k c e b g a h a k b d b f b f b d c d " , and its translation to the "Output Language" is "b f c f b f c d a j e f g c e b g a k i j b d b f a k l m b f b d a h ed ee ef a k k eg a k h eh a e ei c d a f ej ek a g d el".
As a training dataset, a list of 5,000 texts in the Input Language are here, and the corresponding list of 5,000 texts in the Output Language are here. (After downloading them, you can use pickle.load(open(path,'rb')) to open them. They are two lists of strings in Python.)
Your task is to design and train a good model, which can take texts in the "Input language" as its input, translate them to the corresponding texts in the "Output Language" and output them. (Note: the final output of your code should not include extra tokens such as [start] or [end]. So if your model's output includes such extra tokens, you need to write a few more lines of code to remove them.)
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)