Complete Technical Paper Content — Airflow Ml Pipelines
1. Executive Abstract, Problem Formulation & Background
This is a list of data science software and platforms used in data science, which includes programming languages, programming environments, machine learning frameworks, data engineering tools, statistical software, data analysis, plotting, MLOps systems, and more.
Apache Zeppelin Architect — Eclipse (software) CoCalc Dataiku Data Science Studio FreeMat GNU Octave Google Colab DataSpell Jupyter Notebook / JupyterLab Kaggle Notebooks MATLAB O-Matrix PyCharm RStudio SAS (software) and SAS Studio Spyder Visual Studio Code
Apache Airflow Apache Flink Apache Hadoop Apache Kafka Apache NiFi Apache Spark Dask Data build tool (dbt)
Apache Hadoop Cloudera Databricks Delta Lake Amazon S3 Google Cloud Storage Azure Data Lake
BentoML Data Version Control (DVC) Kubeflow MLflow Seldon Core Streamlit TensorFlow Serving Weights & Biases
Kaggle – platform for data science competitions, datasets, and notebooks. OpenML – collaborative platform for sharing datasets, algorithms, and experiments. University of California, Irvine Machine Learning Repository Zenodo – open-access repository supported by CERN and the EU.
Kaggle – online platform for data science education, competitions, datasets, and collaborative learning. KNIME – open-source data analytics platform used for teaching data science, machine learning, and workflow-based analysis. RapidMiner – used in academic research and education for data mining and machine learning. Statistics Online Computational Resource (SOCR) – online tools and instructional resources for statistics education. Tanagra (machine learning) – data mining software developed for research and teaching purposes. TinkerPlots – explore and analyze data through visual modeling.
Business intelligence software List of data science journals List of R software and tools Lists of mathematical software and List of open-source software for mathematics List of numerical-analysis software List of numerical analysis topics List of numerical libraries List of open-source data science software Common Crawl – nonprofit that crawls the web and freely provides its archives and datasets to the public under an MIT License
Dask is an open-source Python library for parallel computing. Dask scales Python code from multi-core local machines to large distributed clusters in the cloud. Dask provides a familiar user interface by mirroring the APIs of other libraries in the PyData ecosystem including: Pandas, scikit-learn and NumPy. It also exposes low-level APIs that help programmers run custom algorithms in parallel. Dask was created by Matthew Rocklin in December 2014 and has over 9.8k stars and 500 contributors on GitHub. Dask is used by retail, financial, governmental organizations, as well as life science and geophysical institutes. Walmart, Wayfair, JDA, GrubHub, General Motors, Nvidia, Harvard Medical School, Capital One and NASA are among the organizations that use Dask.
Big data collections (high level and low level) Dynamic task scheduling Dask's high-level parallel collections – DataFrames, Bags, and Arrays – operate in parallel on datasets that may not fit into memory. Dask's task scheduler executes task graphs in parallel. It can scale to thousand-node clusters. This powers the high-level collections as well as custom, user-defined workloads using low-level collections.
Local threads A threaded scheduler leverages Python's concurrent.futures.ThreadPoolExecuter to execute computations. It has a low memory footprint and does not require any setup. As all the computations occur in the same process, threaded schedulers incur minimal task overhead and no cost from transfer of data between tasks. Due to Python's Global Interpreter Lock, local threads provide parallelism only when the computation is primarily non-Python code, which is the case for Pandas DataFrame, Numpy arrays or other Python/C/C++ based projects. Local process A multiprocessing scheduler leverages Python's concurrent.futures.ProcessPoolExecutor to execute computations. Tasks and its dependencies are transferred from the main process to a local process, executed, and the results are transferred back to the main process. This allows bypassing of issues with Python's Global Interpretable Lock and provides parallelism for computation tasks with primarily Python code. However, transferring data between the main and local processes degrades performance, especially in cases when the size of data transferred is large. Single thread A single threaded scheduler executes computation with no parallelism. It is used for debugging purposes.
Walmart uses Dask for forecasting the demand for 500,000,000 store-item combinations. To provide in-demand items in sufficient quantities at all their outlets, they run large computations. Using RAPIDS and XGBoost, supported by Dask, they have reached 100x acceleration. Blue Yonder uses Dask to process terabytes of data on a daily basis. They can write Pandas-like code in Dask, which can then be pushed directly to production. This helps keep their feedback cycles short and waste low. Grubhub uses Dask alongside TensorFlow for pre-processing and ETL. Dask allows them to continue working in Python and get the functionalities needed.
2. Related Work, Literature Survey & Algorithmic Foundations
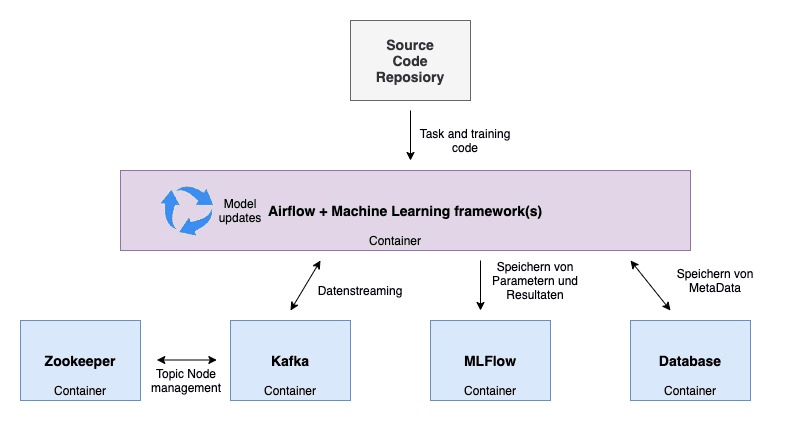
Airflow Example Pipeline for Machine Learning (Local Development) This repository provides an example Apache Airflow pipeline for local development of machine learning projects. The pipeline demonstrates how to fetch news articles from an open data source and apply a zero-shot classification NLP model to classify them into predefined categories. Overview In this example, we leverage Apache Airflow to automate the following steps: Data Loader: The pipeline retrieves news articles from an open data source and prepares them for further processing. Text Classification: We use a pre-trained NLP model for zero-shot classification to assign relevant categories to the news articles. This model can classify text into various categories without prior training on specific datasets. Results Aggregation: This task focuses on aggregating the classified news articles. The first and second tasks are executed in separate Docker-containers. By deploying the first two tasks in separate containers, we ensure efficient resource utilization and maintain modularity in the pipeline's execution environment. Usage To use this pipeline for local development, follow the steps below: Ensure that your Docker Engine has sufficient memory allocated, as running the pipeline may require more memory in certain cases. Сhange path to your local repo in dags/news_classifier.py . Replace "<path_to_your_airflow-ml_repo>/data" with your path. Before the first Airflow run, prepare the environment by executing the following steps: If you are working on Linux, specify the AIRFLOW_UID by running the command: echo -e " AIRFLOW_UID= $( id -u ) " > .env Perform the database migration and create the initial user account by running the command: docker compose up airflow-init The created user account will have the login airflow and the password airflow . Start Airflow and build custom images to run tasks in Docker-containers: docker compose up --build Access the Airflow web interface in your browser at http://localhost:8080 . Trigger the DAG financial_news to initiate the pipeline execution. When you are finished working and want to clean up your environment, run: docker compose down --volumes --rmi all
This repository provides an example Apache Airflow pipeline for local development of machine learning projects. The pipeline demonstrates how to fetch news articles from an open data source and apply a zero-shot classification NLP model to classify them into predefined categories.
Data Loader: The pipeline retrieves news articles from an open data source and prepares them for further processing.
Text Classification: We use a pre-trained NLP model for zero-shot classification to assign relevant categories to the news articles. This model can classify text into various categories without prior training on specific datasets.
The first and second tasks are executed in separate Docker-containers. By deploying the first two tasks in separate containers, we ensure efficient resource utilization and maintain modularity in the pipeline's execution environment.
Ensure that your Docker Engine has sufficient memory allocated, as running the pipeline may require more memory in certain cases.
Сhange path to your local repo in dags/news_classifier.py . Replace "<path_to_your_airflow-ml_repo>/data" with your path.
Before the first Airflow run, prepare the environment by executing the following steps:
Airflow ML Pipeline 🚀 End-to-end machine learning pipeline built with Apache Airflow for automated model training and prediction. 📌 Project Overview This project demonstrates how to build and automate an ML workflow using Apache Airflow. The pipeline: loads and prepares data trains a machine learning model saves the trained model performs predictions on new data organizes ML workflow using Airflow DAG 🏗️ Project Architecture Data ↓ Data preprocessing ↓ Model training ↓ Model serialization (.pkl) ↓ Prediction pipeline ↓ Airflow DAG orchestration 📸 Airflow Pipeline Demo Airflow DAG Prediction Results 🛠️ Technologies - Python 3.12 - Apache Airflow - Docker & Docker Compose - Scikit-learn - Pandas - Dill - PostgreSQL - Redis 📂 Project Structure airflow-ml-pipeline/ ├── dags/ │ └── hw_dag.py ├── modules/ │ ├── pipeline.py │ └── predict.py ├── data/ │ ├── test/ │ └── models/ ├── docker-compose.yml ├── requirements.txt ├── LICENSE └── README.md 🤖 Machine Learning The pipeline trains a machine learning model and stores it as a serialized file. Steps: 1. Data loading 2. Feature preprocessing 3. Model training 4. Model saving 5. Prediction generation ⚙️ Workflow Airflow DAG consists of tasks: 1. Model training 2. Saving trained model 3. Loading test data 4. Generating predictions 🚀 Running the project Clone repository: git clone https://github.com/lllda06/airflow-ml-pipeline.git Run Airflow environment: docker compose up -d Open Airflow UI: http://localhost:8080 📊 Results The pipeline successfully automates the ML lifecycle from training to prediction. 👩💻 Author Bahdanovich Lada
End-to-end machine learning pipeline built with Apache Airflow for automated model training and prediction.
This project demonstrates how to build and automate an ML workflow using Apache Airflow.
Data ↓ Data preprocessing ↓ Model training ↓ Model serialization (.pkl) ↓ Prediction pipeline ↓ Airflow DAG orchestration
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
- Python 3.12 - Apache Airflow - Docker & Docker Compose - Scikit-learn - Pandas - Dill - PostgreSQL - Redis
airflow-ml-pipeline/ ├── dags/ │ └── hw_dag.py ├── modules/ │ ├── pipeline.py │ └── predict.py ├── data/ │ ├── test/ │ └── models/ ├── docker-compose.yml ├── requirements.txt ├── LICENSE └── README.md
1. Data loading 2. Feature preprocessing 3. Model training 4. Model saving 5. Prediction generation
1. Model training 2. Saving trained model 3. Loading test data 4. Generating predictions
📊 Results The pipeline successfully automates the ML lifecycle from training to prediction.
Machine Learning pipeline orchestration using Apache Airflow, Docker, and Scikit-learn.
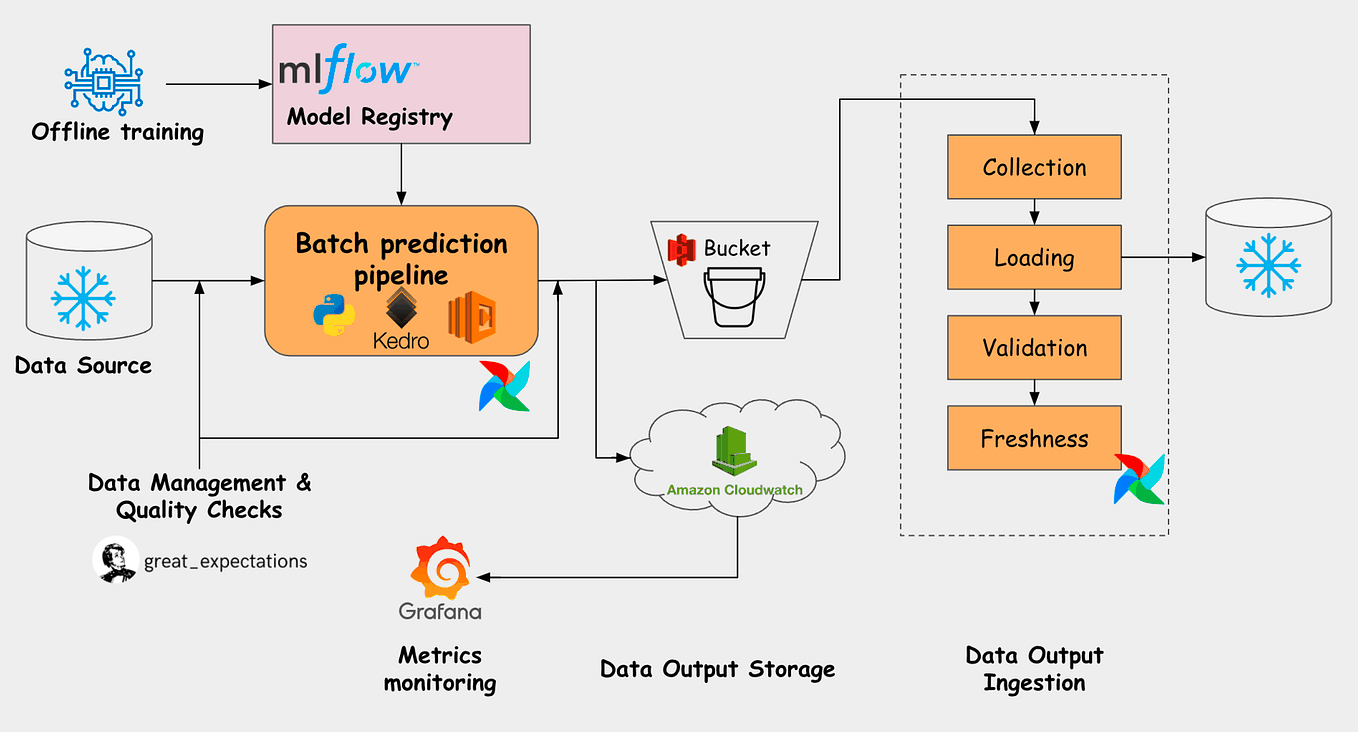
ML Pipeline Orchestration with Apache Airflow An end-to-end machine learning pipeline for customer churn prediction , orchestrated with Apache Airflow. The project demonstrates production-grade ML engineering practices including automated data ingestion, feature engineering, model training with hyperparameter tuning, evaluation with champion/challenger selection, and model deployment with a REST API. Architecture ┌─────────────┐ ┌──────────────────┐ ┌────────────────┐ ┌──────────────┐ ┌─────────────┐ │ Data │ │ Feature │ │ Model │ │ Model │ │ Model │ │ Ingestion │───▶│ Engineering │───▶│ Training │───▶│ Evaluation │───▶│ Deployment│ │ │ │ │ │ │ │ │ │ │ │ • Generate/ │ │ • Derived feats │ │ • Grid search │ │ • Metrics │ │ • Champion │ │ load data │ │ • Scaling │ │ • Cross-val │ │ • Thresholds │ │ promotion │ │ • Validate │ │ • Encoding │ │ • MLflow log │ │ • Selection │ │ • REST API │ └─────────────┘ └──────────────────┘ └────────────────┘ └──────────────┘ └─────────────┘ Orchestrated by Apache Airflow with a weekly retraining schedule and daily data quality monitoring. Tech Stack Component Technology Orchestration Apache Airflow 2.9 ML Framework scikit-learn, XGBoost Experiment Tracking MLflow Data Processing pandas, NumPy Model Serving Flask + Gunicorn Containerization Docker & Docker Compose Testing pytest Project Structure ├── dags/ │ ├── ml_pipeline_dag.py # Main pipeline DAG (weekly) │ └── data_quality_dag.py # Data quality monitoring DAG (daily) ├── src/ml_pipeline/ │ ├── config.py # Configuration management │ ├── data_ingestion.py # Data generation, loading, validation │ ├── feature_engineering.py # Feature transforms & preprocessing │ ├── training.py # Model training with hyperparameter tuning │ ├── evaluation.py # Metrics, champion selection │ ├── deployment.py # Model promotion & REST serving │ └── run_pipeline.py # Standalone runner (no Airflow needed) ├── tests/ # Unit tests for each module ├── config/pipeline_config.yaml # Pipeline configuration ├── docker/Dockerfile ├── docker-compose.yaml # Airflow + Postgres + MLflow stack └── Makefile Pipeline Details 1. Data Ingestion Generates a synthetic customer churn dataset (10K records) with realistic feature correlations. Includes schema validation, range checks, class balance verification, and duplicate detection. 2. Feature Engineering Derived features : charge-per-tenure ratio, tenure buckets, high-value flag, support intensity Preprocessing : StandardScaler for numerical, OneHotEncoder for categorical Outlier handling : z-score clipping with configurable threshold Fitted preprocessor is persisted for inference consistency 3. Model Training Trains three classifiers with grid search hyperparameter tuning and stratified k-fold cross-validation: Logistic Regression — interpretable baseline Random Forest — ensemble with feature importance XGBoost — gradient boosting for maximum performance All experiments are tracked in MLflow with parameters, metrics, and model artifacts. 4. Model Evaluation Computes accuracy, precision, recall, F1, and ROC-AUC on a held-out test set. Applies configurable minimum thresholds to filter candidates, then selects the champion by the best comparison metric. 5. Model Deployment Promotes the champion model to a versioned deployment directory with: Serialized model + preprocessor artifacts Metadata JSON with metrics, parameters, and timestamp Automatic archival of previous champion Flask REST API for real-time predictions Airflow DAGs ml_pipeline — Full training pipeline, runs weekly (Sunday 2 AM UTC). Uses BranchPythonOperator to skip deployment if no model meets thresholds. data_quality_check — Daily validation and drift monitoring. Quick Start Run Locally (without Docker) # Install dependencies pip install -e . pip install -r requirements.txt # Run the full pipeline python -m ml_pipeline.run_pipeline # Run tests pytest tests/ -v Run with Docker Compose # Start Airflow + Postgres + MLflow docker compose up -d --build # Access services: # Airflow UI: http://localhost:8080 (admin / admin) # MLflow UI: http://localhost:5000 # Optionally start the model serving API: docker compose --profile serving up -d model-server # Prediction API: http://localhost:8081 # Stop all services docker compose down -v API Usage # Health check curl http://localhost:8081/health # Single prediction curl -X POST http://localhost:8081/predict \ -H " Content-Type: application/json " \ -d ' { "tenure": 12, "contract_type": "month-to-month", "payment_method": "electronic_check", "internet_service": "fiber_optic", "monthly_charges": 79.99, "total_charges": 959.88, "num_support_tickets": 3, "avg_monthly_usage_gb": 45.2 } ' # Model info curl http://localhost:8081/model/info Configuration All pipeline parameters are defined in config/pipeline_config.yaml : Data generation and split ratios Feature lists and preprocessing methods Model hyperparameter search spaces Evaluation metrics and minimum thresholds Deployment paths Environment variables (see .env.example ) override config for Docker deployments. Testing # Full test suite with coverage make test # Quick run make test-quick
An end-to-end machine learning pipeline for customer churn prediction , orchestrated with Apache Airflow. The project demonstrates production-grade ML engineering practices including automated data ingestion, feature engineering, model training with hyperparameter tuning, evaluation with champion/challenger selection, and model deployment with a REST API.
┌─────────────┐ ┌──────────────────┐ ┌────────────────┐ ┌──────────────┐ ┌─────────────┐ │ Data │ │ Feature │ │ Model │ │ Model │ │ Model │ │ Ingestion │───▶│ Engineering │───▶│ Training │───▶│ Evaluation │───▶│ Deployment│ │ │ │ │ │ │ │ │ │ │ │ • Generate/ │ │ • Derived feats │ │ • Grid search │ │ • Metrics │ │ • Champion │ │ load data │ │ • Scaling │ │ • Cross-val │ │ • Thresholds │ │ promotion │ │ • Validate │ │ • Encoding │ │ • MLflow log │ │ • Selection │ │ • REST API │ └─────────────┘ └──────────────────┘ └────────────────┘ └──────────────┘ └─────────────┘
Orchestrated by Apache Airflow with a weekly retraining schedule and daily data quality monitoring.
├── dags/ │ ├── ml_pipeline_dag.py # Main pipeline DAG (weekly) │ └── data_quality_dag.py # Data quality monitoring DAG (daily) ├── src/ml_pipeline/ │ ├── config.py # Configuration management │ ├── data_ingestion.py # Data generation, loading, validation │ ├── feature_engineering.py # Feature transforms & preprocessing │ ├── training.py # Model training with hyperparameter tuning │ ├── evaluation.py # Metrics, champion selection │ ├── deployment.py # Model promotion & REST serving │ └── run_pipeline.py # Standalone runner (no Airflow needed) ├── tests/ # Unit tests for each module ├── config/pipeline_config.yaml # Pipeline configuration ├── docker/Dockerfile ├── docker-compose.yaml # Airflow + Postgres + MLflow stack └── Makefile
Generates a synthetic customer churn dataset (10K records) with realistic feature correlations. Includes schema validation, range checks, class balance verification, and duplicate detection.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Trains three classifiers with grid search hyperparameter tuning and stratified k-fold cross-validation:
Computes accuracy, precision, recall, F1, and ROC-AUC on a held-out test set. Applies configurable minimum thresholds to filter candidates, then selects the champion by the best comparison metric.
# Install dependencies pip install -e . pip install -r requirements.txt # Run the full pipeline python -m ml_pipeline.run_pipeline # Run tests pytest tests/ -v
# Start Airflow + Postgres + MLflow docker compose up -d --build # Access services: # Airflow UI: http://localhost:8080 (admin / admin) # MLflow UI: http://localhost:5000 # Optionally start the model serving API: docker compose --profile serving up -d model-server # Prediction API: http://localhost:8081 # Stop all services docker compose down -v
# Health check curl http://localhost:8081/health # Single prediction curl -X POST http://localhost:8081/predict \ -H " Content-Type: application/json " \ -d ' { "tenure": 12, "contract_type": "month-to-month", "payment_method": "electronic_check", "internet_service": "fiber_optic", "monthly_charges": 79.99, "total_charges": 959.88, "num_support_tickets": 3, "avg_monthly_usage_gb": 45.2 } ' # Model info curl http://localhost:8081/model/info
An end-to-end ML pipeline using Airflow for orchestration. Data ingestion, feature engineering, model training, evaluation, and deployment.
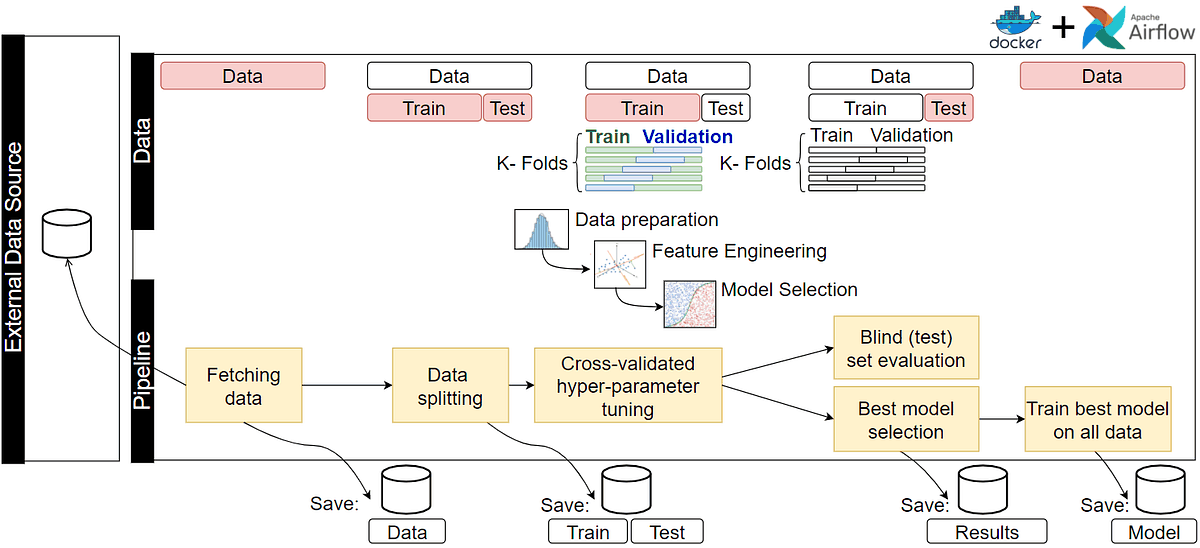
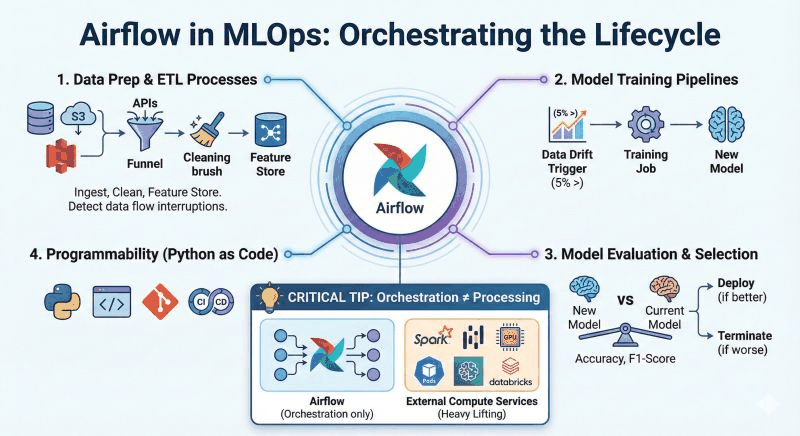
ML Pipeline with Apache Airflow Hands-on lab that orchestrates a five-task machine-learning workflow with Apache Airflow 2.10.4 , LocalExecutor , two PostgreSQL 13 databases, pandas , and scikit-learn , all managed by Docker Compose v2 . Figure: Conceptual ML lifecycle. This lab implements the core path through ingest, preprocess, train, evaluate, and simulated deploy. Project overview PostgreSQL source data ↓ ingest_data ↓ preprocess_data ↓ train_model ↓ evaluate_model ↓ deploy_model (quality gate + copy to production/) DAG ID: ml_pipeline UI: http://localhost:8081 Default login (fresh metadata volume): admin / admin Learning objectives Explain what Airflow orchestrates and what it does not do Separate Airflow metadata storage from ML source data and pipeline artifacts Build a custom Airflow image with compatible ML dependencies Run LocalExecutor with PostgreSQL metadata (no Redis/Celery) Trigger, monitor, and validate a five-task ML DAG Inspect CSV, model, metrics, and simulated deployment outputs What the project demonstrates Concern Implementation Orchestration Airflow DAG ml_pipeline Executor LocalExecutor Metadata DB Compose service postgres ML source DB Compose service ml-postgres Artifacts Bind mount ./data → /opt/airflow/data Model scikit-learn LinearRegression → model.pkl Quality gate MSE compared to MAX_MODEL_MSE Deployment Simulated copy to data/production/model.pkl Architecture diagram flowchart TB Browser["Browser :8081"] --> Web["airflow-webserver"] Scheduler["airflow-scheduler"] --> Executor["LocalExecutor"] Executor --> Tasks["ingest → preprocess → train → evaluate → deploy"] Web --> Meta[("postgres metadata")] Scheduler --> Meta Tasks --> ML[("ml-postgres source")] Tasks --> Data["/opt/airflow/data"] Data <--> Host["Host ./data"] Loading More detail: docs/architecture.md and docs/diagrams/ . Pipeline diagram ingest_data → preprocess_data → train_model → evaluate_model → deploy_model Figure: Five sequential PythonOperator tasks. Final lab task IDs are ingest_data , preprocess_data , train_model , evaluate_model , and deploy_model . Airflow service responsibilities Service Role airflow-webserver UI and API on host port 8081 airflow-scheduler Parses DAGs, schedules work, runs LocalExecutor processes airflow-init One-time DB migrate + admin user creation postgres Airflow metadata ml-postgres ML training rows ml-db-init One-time table create + seed Airflow metadata DB versus ML source DB Airflow metadata ML source Service postgres ml-postgres Database airflow ml_pipeline Volume postgres-db-volume ml-postgres-db-volume Contents Users, DAG runs, task states, XCom ml_training_data feature/target rows PostgreSQL files are not turned into CSV by Docker mounts. The ingest_data task queries the ML database and writes raw.csv . Named volumes versus bind mounts Named volumes persist database files inside Docker. Bind mounts expose ./dags , ./logs , ./config , ./plugins , and ./data on the host. Prerequisites Docker Desktop running (Windows) or Docker Engine + Compose v2 (Linux) At least 2 CPU cores, 4 GB RAM, 10 GB free disk Port 8081 free Git Bash recommended on Windows Windows Docker Desktop notes Keep AIRFLOW_UID=50000 from .env.example unless you have a specific reason to change it Use Git Bash for bash scripts/*.sh Do not use sudo Configure LF line endings for .sh files (see .gitattributes ) Bind-mounted artifacts appear under local ./data Git Bash may rewrite paths starting with / . Helper scripts set MSYS_NO_PATHCONV=1 for that reason. If you run raw docker compose exec commands with container paths, prefix with MSYS_NO_PATHCONV=1 or use //opt/... Linux notes cp .env.example .env sed -i " s/^AIRFLOW_UID=.*/AIRFLOW_UID= $( id -u ) / " .env chmod +x scripts/ * .sh Project structure ml-pipeline-with-apache-airflow/ ├── README.md ├── apache_airflow_ml_pipeline_one_stop_medium_guide.md ├── .env.example ├── .gitignore ├── .dockerignore ├── .gitattributes ├── Dockerfile ├── docker-compose.yaml ├── requirements.txt ├── dags/ │ ├── ml_pipeline_dag.py │ └── pipeline.py ├── sql/ │ └── init_ml_data.sql ├── scripts/ │ ├── bootstrap.sh │ ├── validate.sh │ ├── trigger_pipeline.sh │ ├── show_results.sh │ └── reset_lab.sh ├── data/ logs/ plugins/ config/ └── docs/ ├── architecture.md ├── troubleshooting.md ├── command-reference.md ├── diagrams/ └── images/ Quick start git clone < repository-url > cd ml-pipeline-with-apache-airflow cp .env.example .env docker compose config docker compose build --no-cache docker compose up airflow-init docker compose up ml-db-init docker compose up -d docker compose ps Or one helper script: bash scripts/bootstrap.sh Open: http://localhost:8081 Username: admin Password: admin Trigger: docker compose exec airflow-scheduler \ airflow dags trigger ml_pipeline Inspect: bash scripts/show_results.sh Manual setup / first-time initialization Copy .env.example → .env docker compose config docker compose build --no-cache (must end with successful pip check ) docker compose up airflow-init (exit code 0) docker compose up ml-db-init (exit code 0) docker compose up -d Wait until webserver and scheduler are healthy How to log in Open http://localhost:8081 Sign in with admin / admin on a fresh volume If login fails on an old volume, run airflow users list and reset the existing password How to trigger the DAG UI: open ml_pipeline → Trigger DAG CLI: bash scripts/trigger_pipeline.sh How to monitor tasks Grid / Graph views in the UI docker compose exec airflow-scheduler airflow dags list-runs -d ml_pipeline docker compose logs -f airflow-scheduler Figure: Airflow Details-style view for a five-task ML DAG (earlier lab screenshot; final task IDs use snake_case without gerunds). How to inspect source data docker compose exec ml-postgres \ psql -U mluser -d ml_pipeline \ -c " SELECT * FROM ml_training_data ORDER BY id; " Expected: 10 rows. How to inspect generated files After a successful run: data/raw.csv data/preprocessed.csv data/models/model.pkl data/metrics/evaluation.json data/production/model.pkl bash scripts/show_results.sh How to validate the stack bash scripts/validate.sh Checks Compose syntax, container health, Airflow version, Python packages, users, DAG discovery, import errors, ML row count, and artifact presence. Testing checklist (verify everything is correct) Use this sequence after bootstrap to confirm the lab works end-to-end. 1. Infrastructure health docker compose ps curl -s http://localhost:8081/health docker compose exec airflow-scheduler curl --fail http://localhost:8974/health Pass when: postgres , ml-postgres , airflow-webserver , and airflow-scheduler are running/healthy; both health endpoints respond successfully. 2. Airflow version and packages docker compose exec airflow-scheduler airflow version docker compose exec airflow-scheduler python -c " import pandas,sklearn; print(pandas.__version__, sklearn.__version__) " Pass when: version is 2.10.4 and packages print 2.1.4 and 1.5.2 . 3. Users and DAG discovery docker compose exec airflow-webserver airflow users list docker compose exec airflow-scheduler airflow dags list docker compose exec airflow-scheduler airflow dags list-import-errors Pass when: an admin user exists, ml_pipeline is listed, and there are no import errors. 4. ML source data docker compose exec ml-postgres \ psql -U mluser -d ml_pipeline \ -c " SELECT COUNT(*) FROM ml_training_data; " Pass when: count is 10 . 5. Pipeline execution bash scripts/trigger_pipeline.sh # wait until the run shows success in UI or: docker compose exec airflow-scheduler airflow dags list-runs -d ml_pipeline Pass when: the latest DAG run state is success and all five tasks are green. 6. Artifacts and deployment integrity bash scripts/show_results.sh test -f data/raw.csv test -f data/preprocessed.csv test -f data/models/model.pkl test -f data/metrics/evaluation.json test -f data/production/model.pkl sha256sum data/models/model.pkl data/production/model.pkl Pass when: all five artifacts exist and the two model checksums match. 7. Full validation script bash scripts/validate.sh Pass when: the script exits 0 and prints that validation finished successfully. Routine commands Action Command Start docker compose up -d Status docker compose ps Validate bash scripts/validate.sh Trigger bash scripts/trigger_pipeline.sh Results bash scripts/show_results.sh Stop (keep DBs) docker compose down Reset (delete volumes) bash scripts/reset_lab.sh Full index: docs/command-reference.md How to stop docker compose down Volumes are preserved. How to reset bash scripts/reset_lab.sh This is destructive: it deletes named volumes and clears generated data/ / logs/ files (keeps .gitkeep ). Troubleshooting summary Problem First check Build fails on pandas Use pinned pandas==2.1.4 Login fails airflow users list / reset password or reset volumes DAG missing airflow dags list-import-errors raw.csv missing DAG has not succeeded yet DB connection refused Use host ml-postgres , not localhost Script errors on Windows Run with bash and LF endings Details: docs/troubleshooting.md Security warning Lab credentials ( admin / admin , mluser / mlpassword ) and empty Fernet key are not production-safe. Do not expose this stack publicly. Do not commit .env . Production limitations This lab does not provide HA, TLS, secrets management, a model registry, object-storage artifacts, drift monitoring, or a live inference API. Deployment is a file copy behind an MSE gate. Possible evolution: managed Airflow, managed PostgreSQL, object storage, MLflow, Kubernetes inference, centralized logs, secret manager, CI/CD, canary deploy, and feature store. Medium training guide Deep theory + lab walkthrough: apache_airflow_ml_pipeline_one_stop_medium_guide.md Screenshot and image index See docs/images/README.md . Learning-use note Provided for education and local experimentation. Not a production Airflow or MLOps platform.
Hands-on lab that orchestrates a five-task machine-learning workflow with Apache Airflow 2.10.4 , LocalExecutor , two PostgreSQL 13 databases, pandas , and scikit-learn , all managed by Docker Compose v2 .
Figure: Conceptual ML lifecycle. This lab implements the core path through ingest, preprocess, train, evaluate, and simulated deploy.
PostgreSQL source data ↓ ingest_data ↓ preprocess_data ↓ train_model ↓ evaluate_model ↓ deploy_model (quality gate + copy to production/)
DAG ID: ml_pipeline UI: http://localhost:8081 Default login (fresh metadata volume): admin / admin
flowchart TB Browser["Browser :8081"] --> Web["airflow-webserver"] Scheduler["airflow-scheduler"] --> Executor["LocalExecutor"] Executor --> Tasks["ingest → preprocess → train → evaluate → deploy"] Web --> Meta[("postgres metadata")] Scheduler --> Meta Tasks --> ML[("ml-postgres source")] Tasks --> Data["/opt/airflow/data"] Data <--> Host["Host ./data"]
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Figure: Five sequential PythonOperator tasks. Final lab task IDs are ingest_data , preprocess_data , train_model , evaluate_model , and deploy_model .
PostgreSQL files are not turned into CSV by Docker mounts. The ingest_data task queries the ML database and writes raw.csv .
cp .env.example .env sed -i " s/^AIRFLOW_UID=.*/AIRFLOW_UID= $( id -u ) / " .env chmod +x scripts/ * .sh
ml-pipeline-with-apache-airflow/ ├── README.md ├── apache_airflow_ml_pipeline_one_stop_medium_guide.md ├── .env.example ├── .gitignore ├── .dockerignore ├── .gitattributes ├── Dockerfile ├── docker-compose.yaml ├── requirements.txt ├── dags/ │ ├── ml_pipeline_dag.py │ └── pipeline.py ├── sql/ │ └── init_ml_data.sql ├── scripts/ │ ├── bootstrap.sh │ ├── validate.sh │ ├── trigger_pipeline.sh │ ├── show_results.sh │ └── reset_lab.sh ├── data/ logs/ plugins/ config/ └── docs/ ├── architecture.md ├── troubleshooting.md ├── command-reference.md ├── diagrams/ └── images/
git clone < repository-url > cd ml-pipeline-with-apache-airflow cp .env.example .env docker compose config docker compose build --no-cache docker compose up airflow-init docker compose up ml-db-init docker compose up -d docker compose ps
Figure: Airflow Details-style view for a five-task ML DAG (earlier lab screenshot; final task IDs use snake_case without gerunds).
docker compose exec ml-postgres \ psql -U mluser -d ml_pipeline \ -c " SELECT * FROM ml_training_data ORDER BY id; "
data/raw.csv data/preprocessed.csv data/models/model.pkl data/metrics/evaluation.json data/production/model.pkl
Checks Compose syntax, container health, Airflow version, Python packages, users, DAG discovery, import errors, ML row count, and artifact presence.
docker compose ps curl -s http://localhost:8081/health docker compose exec airflow-scheduler curl --fail http://localhost:8974/health
Pass when: postgres , ml-postgres , airflow-webserver , and airflow-scheduler are running/healthy; both health endpoints respond successfully.
docker compose exec airflow-scheduler airflow version docker compose exec airflow-scheduler python -c " import pandas,sklearn; print(pandas.__version__, sklearn.__version__) "
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)