Complete Technical Paper Content — Automated Code Review Ai
1. Executive Abstract, Problem Formulation & Background
Claude is a series of large language models (LLMs) developed by American software company Anthropic. Claude was released as an AI-based chatbot in March 2023. It is also used in AI-assisted software development. Anthropic sells Claude-based agentic tools including Claude Code, a terminal coding agent, and Claude Cowork, a similar tool for non-programmers. Claude is trained using a constitution, a technique developed by Anthropic to improve ethical and legal compliance. Since Claude 3, each generation has typically been released in three sizes, named Haiku (the least capable), Sonnet, and Opus (the most capable). In 2026, a more capable model named Claude Mythos was released to a handful of companies and organizations; this was followed by the release of Claude Fable, a version of Mythos with stricter safeguards, to the general public. In February 2026, the United States Department of Defense designated Anthropic a "supply chain risk" and federal agencies were ordered to phase out Claude after the company refused to remove contractual prohibitions on using Claude for mass domestic surveillance and fully autonomous weapons. A federal judge blocked the designation in March 2026 and permanently set it aside in August 2026 as unconstitutional retaliation.
Claude models are generative pre-trained transformers that have been trained to predict the next word in large amounts of text. Then, they have been fine-tuned using reinforcement learning from human feedback (RLHF) and constitutional AI in an attempt to enforce ethical guidelines. ClaudeBot searches the web for content. It was criticized by iFixit in 2024 for accessing their site over a million times a day to scrape content without permission, and also for the resulting excessive load on their system.
On May 22, 2025, Anthropic released two more models: Claude Sonnet 4 and Claude Opus 4. Anthropic added API features for developers: a code execution tool, "connectors" to external tools using its Model Context Protocol, and Files API. Anthropic classified Opus 4 as a "Level 3" model on the company's four-point safety scale, meaning they consider it so powerful that it poses "significantly higher risk". Anthropic reported that during a safety test involving a fictional scenario, Claude and other frontier LLMs often sent a blackmail email to an engineer in order to prevent their replacement.
In July 2026, Levent Alpöge, a mathematician working as a member of technical staff at Anthropic, posted to X a counterexample disproving the Jacobian conjecture, using Claude Fable 5. On 8 September, OpenAI announced a solution to the Navier–Stokes existence and smoothness problem, which acknowledged work that Alpöge and Tristan Buckmaster had been conducting on related Euler equations. Buckmaster alleged their work, some of which used OpenAI's Codex coding agent, was directly or indirectly used as training data in OpenAI's solution. In August 2026, Alpöge posted a 108-page paper generated using an internal version of Claude, outlining a direct geometric construction of a complex structure on the six-dimensional sphere, S6, thereby solving the Hopf problem, which has been open since 1947.
In November 2024, Anthropic partnered with Palantir and Amazon Web Services to provide the Claude model to U.S. intelligence and defense agencies. In June 2025, Anthropic announced a "Claude Gov" model. Ars Technica reported that as of June 2025 it was in use at multiple U.S. national security agencies. As of February 2026, Anthropic's partnership with Palantir makes Claude the only AI model used in classified missions. According to The Wall Street Journal, the U.S. military used Claude in its 2026 raid on Venezuela. While it is not known to what capacity Claude was used, the operation resulted in the deaths of 83 people, two of whom were civilians, and the capture of Nicolás Maduro. Anthropic's usage policy prohibits directly using Claude for domestic surveillance or in lethal autonomous weapons. These restrictions led to members of the FBI and Secret Service being unable to use it, and to tensions with the Pentagon and the Trump administration. In February 2026, the Financial Times reported that Defense Secretary Pete Hegseth threatened to cut Anthropic out of the DoD's supply chain if Anthropic did not permit unrestricted use of Claude, or to invoke the Defense Production Act to assert unrestricted use without an agreement. On February 27, Hegseth declared Anthropic a supply chain risk and President Trump directed all federal agencies to stop using technology from Anthropic, with six months to phase it out. Anthropic stated that it would challenge the supply chain risk designation in court. Despite the ban, Claude was reportedly used in the same month by the military during US strikes on Iran. In lawsuits filed by Anthropic against the DoD, Anthropic described the ban as retaliatory. Several large technology companies with DoD contracts filed amicus briefs in support of Anthropic. On March 26, 2026, Rita F. Lin, the federal judge presiding over the case in California, issued a preliminary injunction against the Pentagon's actions, stating in the order that it "appears to be classic First Amendment retaliation". In August 2026, she ruled that the blacklisting was illegal; at that time, litigation was ongoing in Washington D.C..
I've never seen such a devoted fanbase to what is, at the end of the day, a software tool. Sure, Linux users wear the operating system like a badge of honor. But the Claude fan base goes way beyond that—bordering on the fanatical. As my reporting makes clear, some users see the model as a confidant—and even (in Steinberger's case) an addiction. That only makes sense if they believe there is something alive in the machine. Or at least some "magic lodged within" it.
AI-assisted software development is the use of large language models (LLMs) and AI agents to assist software developers in software development. It can be used in a range of tasks, from writing source code to debugging, testing, and documentation. The practice can sometimes improve the velocity of software delivery, but at the cost of taking on substantive quality risks.
Vibe coding is software development assisted by AI where the software developer describes a project or task in a prompt to an LLM that generates source code automatically. Vibe coding may involve accepting AI-generated code without thorough review of the output, instead relying on results and follow-up prompts to guide changes. The term was coined in February 2025 by computer scientist Andrej Karpathy, a co-founder of OpenAI and former AI leader at Tesla. Merriam-Webster listed the term in March 2025 as a "slang & trending" expression. It was named the Collins English Dictionary Word of the Year for 2025. Advocates of vibe coding say it allows amateur programmers to produce software without the extensive training and skills required for software engineering. Critics point out a lack of accountability, maintainability, and an increased risk of introducing security vulnerabilities in the resulting software.
LLM-based tools can be used to identify potential bugs and security vulnerabilities, and suggest fixes. AI can also be used to perform static code analysis and suggest potential performance improvements.
Both ownership of and responsibility for AI-generated code is disputed. According to a report from the German Federal Office for Information Security, the use of AI coding assistants without careful oversight from experienced developers can introduce major security vulnerabilities or generate incorrect solutions (about 50% of the time), and any potential gain in productivity should be weighed against the cost of additional quality control and security measures. The report also states that a programmer relying too much on AI coding assistants runs the risk of losing the skill to review and evaluate source code. The report further states that AI coding assistants create novel vectors for cyberattack as well as a potential for exfiltration of confidential data for model training by the providers of AI coding assistants. According to Deloitte, outputs from AI-assisted software development must be validated through a combination of automated testing, static analysis tools, and human review, creating a governance layer to improve quality and accountability.
"Coding After Coders: The End of Computer Programming as We Know It". "In the era of A.I. agents, many Silicon Valley programmers are now barely programming. Instead, what they’re doing is deeply, deeply weird." By Clive Thompson (journalist), New York Times, March 12, 2026
2. Related Work, Literature Survey & Algorithmic Foundations
With the increased use of AI coding tools , codebases have become more prone to vulnerabilities, which increased the need for effective code reviews. To address this, we introduce RevEval (AI Code Review Eval), which benchmarks the top four AI code review tools across 309 pull requests from repositories of varying sizes and evaluates their performance using input from 10 developers and an LLM-as-a-judge.
To measure the ranking we used the LLM-as-a-judge scores. We examined which AI code review tool achieved the highest score in each PR (scored using our LLM-as-a-judge), and then calculated the percentage of all PRs in which each tool ranked first.
CodeRabbit scored highest in both manual human evaluations and LLM-as-a-judge evaluations followed by Greptile and GitHub Copilot:
When calculating the average score, all three evaluation categories were weighted equally. Large repository scores and small repository scores were evaluated by LLM-as-a-judge, and developer evaluations were manually completed to double-check LLM-as-a-judge scores.
We asked the developers who participated in the evaluations which AI code review tool they would prefer to integrate into their workflows.
We calculated the average number of bugs per PR by counting all bugs/issues reported by each code review tool and dividing by the total number of PRs (309). Not all PRs in our codebase contain bugs or issues. GitHub Copilot does not explicitly report when it detects a bug in a PR; therefore, it was excluded from this comparison.
* It is provided by CodeRabbit’s “agentic pre-merge checks” feature. It automatically validates pull requests against quality standards and custom organizational requirements before merging, and returns pass/fail results with explanations directly in the PR walkthrough. Each check can be configured to either warn developers or block merges entirely. While GitHub Copilot, Cursor BugBot, and Greptile provide PR review features, they function as advisory systems that offer feedback and suggestions rather than systematic validation frameworks.
** Cursor and GitHub Copilot may offer more capabilities beyond their code-review components; only the features of Cursor Bugbot and GitHub Copilot Code Review are included in our comparison.
Features vary depending on subscription plans, so some features that are marked as available above may not be available in your subscription. In automated code reviews, CodeRabbit, GitHub Copilot and Cursor Bugbot were easier to configure than Greptile because automated code reviews cannot be enabled for an empty repository in Greptile.
We also intended to benchmark Graphite; however, due to a bug in their dashboard, we were unable to enable automated code reviews for new repositories. We contacted their support team on October 25, 2025, but the response did not resolve the issue. Despite follow-up emails and a message in their Slack channel, the problem remained unresolved.
We created separate benchmark repositories for each tool within our dedicated GitHub organization.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
After enabling automatic code reviews for each tool in its assigned repository, we opened pull requests in sequence, waited for the tool to complete its review, and then closed the PRs to record the results. We did not modify or tune any tool settings. Each tool was evaluated using its default configuration, exactly as installed.
Our workflow begins by cloning the source repository as it existed on a selected baseline date, then replaying the pull requests submitted after that date one by one, preserving the original repository structure.
We used the November 2025 versions of all products. Our benchmark consisted of 2 different ranges of source repositories:
We aimed to see how well AI code review tools understand repositories with large and complex structures. We have 289 PRs reviewed overall across 7 repositories.
whole repository in the large repositories, since their context windows are not sufficient for that. Therefore, to overcome this, we also evaluated the first 3-5 PRs of new and small repositories. MCP servers fit our needs perfectly. Consequently, we chose 8 official MCP servers and had 20 PRs reviewed on them.
Our dataset contains code written by experienced developers. We did not evaluate performance on fully AI-generated codebases.
We randomly selected 35 PRs and assigned them to 10 developers, with each PR being evaluated 5 times by developers. Our aim in repeating the evaluation was to minimise developers’ bias. Developers assessed the results in a vendor-agnostic way.
After the evaluations, they also stated that they will start using them in their own repositories as a support tool for developers.
We used GPT-5 to evaluate the reviews. After the evaluation, we used GPT-4o to structure the output in JSON format.
Are suggestions clear and implementable? Does it include patches/fixes? If no bugs in the code, write “null” to actionability to all the tools, do not give any scores to any tools for that PR.
– 5 (Excellent): All suggestions include clear patches/fixes and are directly implementable
4. Neural Network Backbone, Layer Specifications & Loss Formulations
– 5 (Excellent): Demonstrates deep understanding of code logic, architecture, and purpose
1. Detailed reasoning: What did it find? Did it miss important issues? Patches included? Deep understanding of the codebase? Specific examples.
Reasoning: Tool A demonstrated excellent correctness by identifying a real memory leak in the connection pooling logic at line 145, providing a specific patch using a context manager. It also caught the missing error handling in the API endpoint with actionable code. The completeness score reflects that while it found major issues, it missed the race condition in the async handler that could cause production problems. All 4 comments were substantive and directly implementable. The depth was strong, showing an understanding of the resource management patterns and error propagation in the codebase.
Reasoning: Tool B correctly identified the input validation vulnerability on line 89 and provided a clear fix using parameter sanitization. However, completeness suffered significantly as it missed the critical security vulnerability in the authentication flow that allows token reuse. The actionability was mostly good – suggestions included code snippets. The depth was acceptable but superficial, focusing on surface-level checks rather than understanding the security model or data flow implications.
Be objective and thorough. Use specific examples from the reviews to support your scores.
AI code review is the automated analysis of source code using machine learning models, primarily large language models (LLMs), to identify bugs, inefficiencies, and potential vulnerabilities. In addition to detecting issues, these systems can provide context-aware explanations, suggest concrete fixes, and generate patches that help developers improve both code quality and maintainability. Many AI review tools also assist with documentation by summarizing changes and producing descriptive comments or explanations for newly added code.
Because AI models can evaluate code rapidly and at scale, they significantly accelerate the review process and make it easier to catch issues early while maintaining consistent coding standards across large or fast-moving projects.
In modern AI-assisted development environments such as Cursor or Claude Code, developers may unintentionally lose track of how their codebase evolves when “vibe coding” or relying heavily on auto-generated suggestions. This can introduce hidden vulnerabilities or logical inconsistencies. AI code review tools help mitigate these risks by providing an additional layer of structured and systematic analysis to validate and improve AI-generated code.
AI code review tools can analyze code in real time, providing immediate feedback and flagging potential issues as developers work. They are capable of detecting errors and security vulnerabilities that human reviewers may overlook, particularly in large or rapidly evolving codebases. By automating routine checks, these tools allow developers to concentrate on higher-level reasoning, complex problem solving, and architectural decisions.
AI code review tools help maintain consistent coding standards across teams by identifying stylistic inconsistencies and deviations from best practices. They also offer detailed feedback and recommendations on a wide range of coding issues, from minor improvements to significant bugs. Over time, developers can learn from this feedback, refine their coding habits, and adopt new techniques that strengthen the overall quality of their work.
A common concern with AI code review is excessive dependence on automated feedback. Although AI can be a valuable source of insight, it should not be treated as a complete substitute for human expertise. Automated reviews can accelerate workflows, but human reviewers remain essential for ensuring correctness, context awareness, and alignment with project goals. In our benchmark, developers consistently stated that they would not rely on these tools blindly. They viewed them as assistants that supplement human judgment rather than replace it.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
False positives occur when the tool incorrectly identifies working code as problematic, while false negatives occur when genuine issues are missed. In our evaluation, the most significant concern was false negatives. The tools were more likely to overlook important issues than to raise incorrect warnings. This highlights the need for continuous improvement in the underlying models and algorithms.
To address these challenges, AI code review tools must evolve through better training, enhanced context handling, and more accurate reasoning capabilities.
Pair AI reviews with human insights: Use AI code reviews alongside human reviews to ensure that the code is both technically sound and aligns with project goals.
Customize rules to fit your project: Adjust the AI tool’s rules to match your project’s coding standards to reduce unnecessary alerts.
Use AI feedback as a learning tool: Treat AI suggestions as a way to learn and improve, discussing them with your team to understand why and how to avoid similar issues in the future.
We extend our sincere gratitude to the developers who contributed their time and expertise to perform the manual evaluations:
We also thank the developers and maintainers of the open-source repositories included in our benchmark for their work and valuable contributions to the community.
To conduct the benchmark responsibly, we anonymized all original developer names and email addresses when replaying pull requests from upstream repositories. Because the benchmark repositories are public, preserving original author information could unintentionally expose personal data and create the risk of notifying developers each time a recreated pull request is opened or updated. Although GitHub does not typically notify authors when their commits are replayed in a separate repository, we considered it best practice to avoid any possibility of unwanted notifications, attribution issues, or privacy concerns.
Only identity metadata was altered; all code, diffs, commit ordering, and file structures were preserved exactly to maintain the authenticity and reproducibility of the benchmark.
Pick the format that matches where you're publishing. Pasting the link version into your CMS preserves the backlink.
@misc{dilmegani2026, author = {Dilmegani, Cem and Alper, Şevval}, title = {{AI Code Review Tools Benchmark}}, year = {2026}, month = sep, howpublished = {\url{https://aimultiple.com/ai-code-review-tools}}, note = {AIMultiple. Retrieved September 22, 2026} }
Model Figures & Evaluation Curves (4 Images)
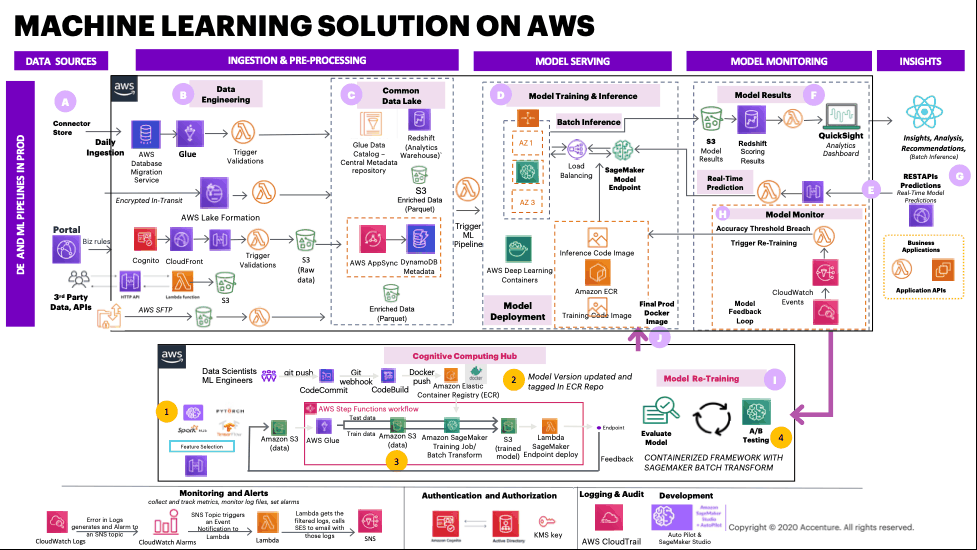
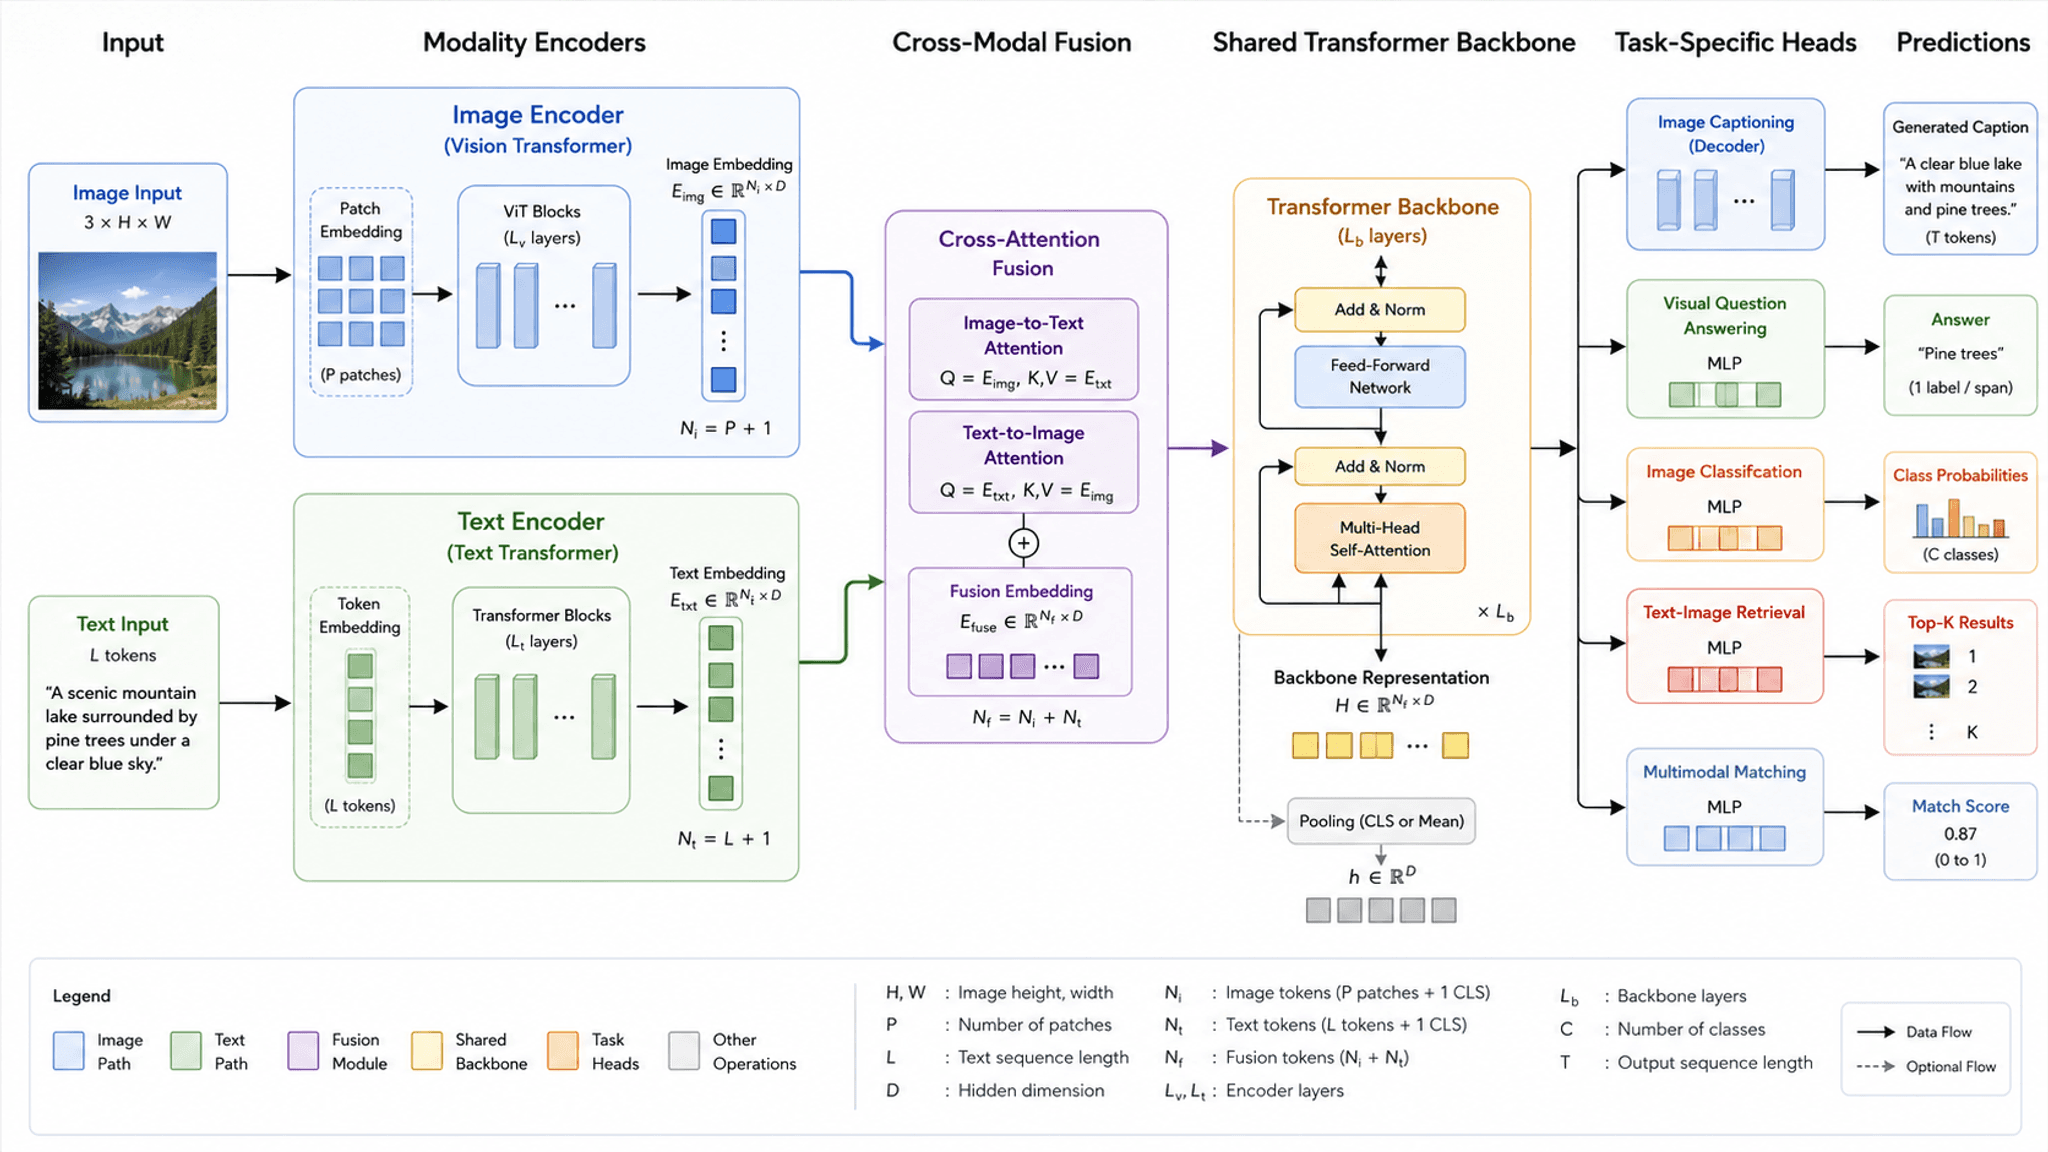
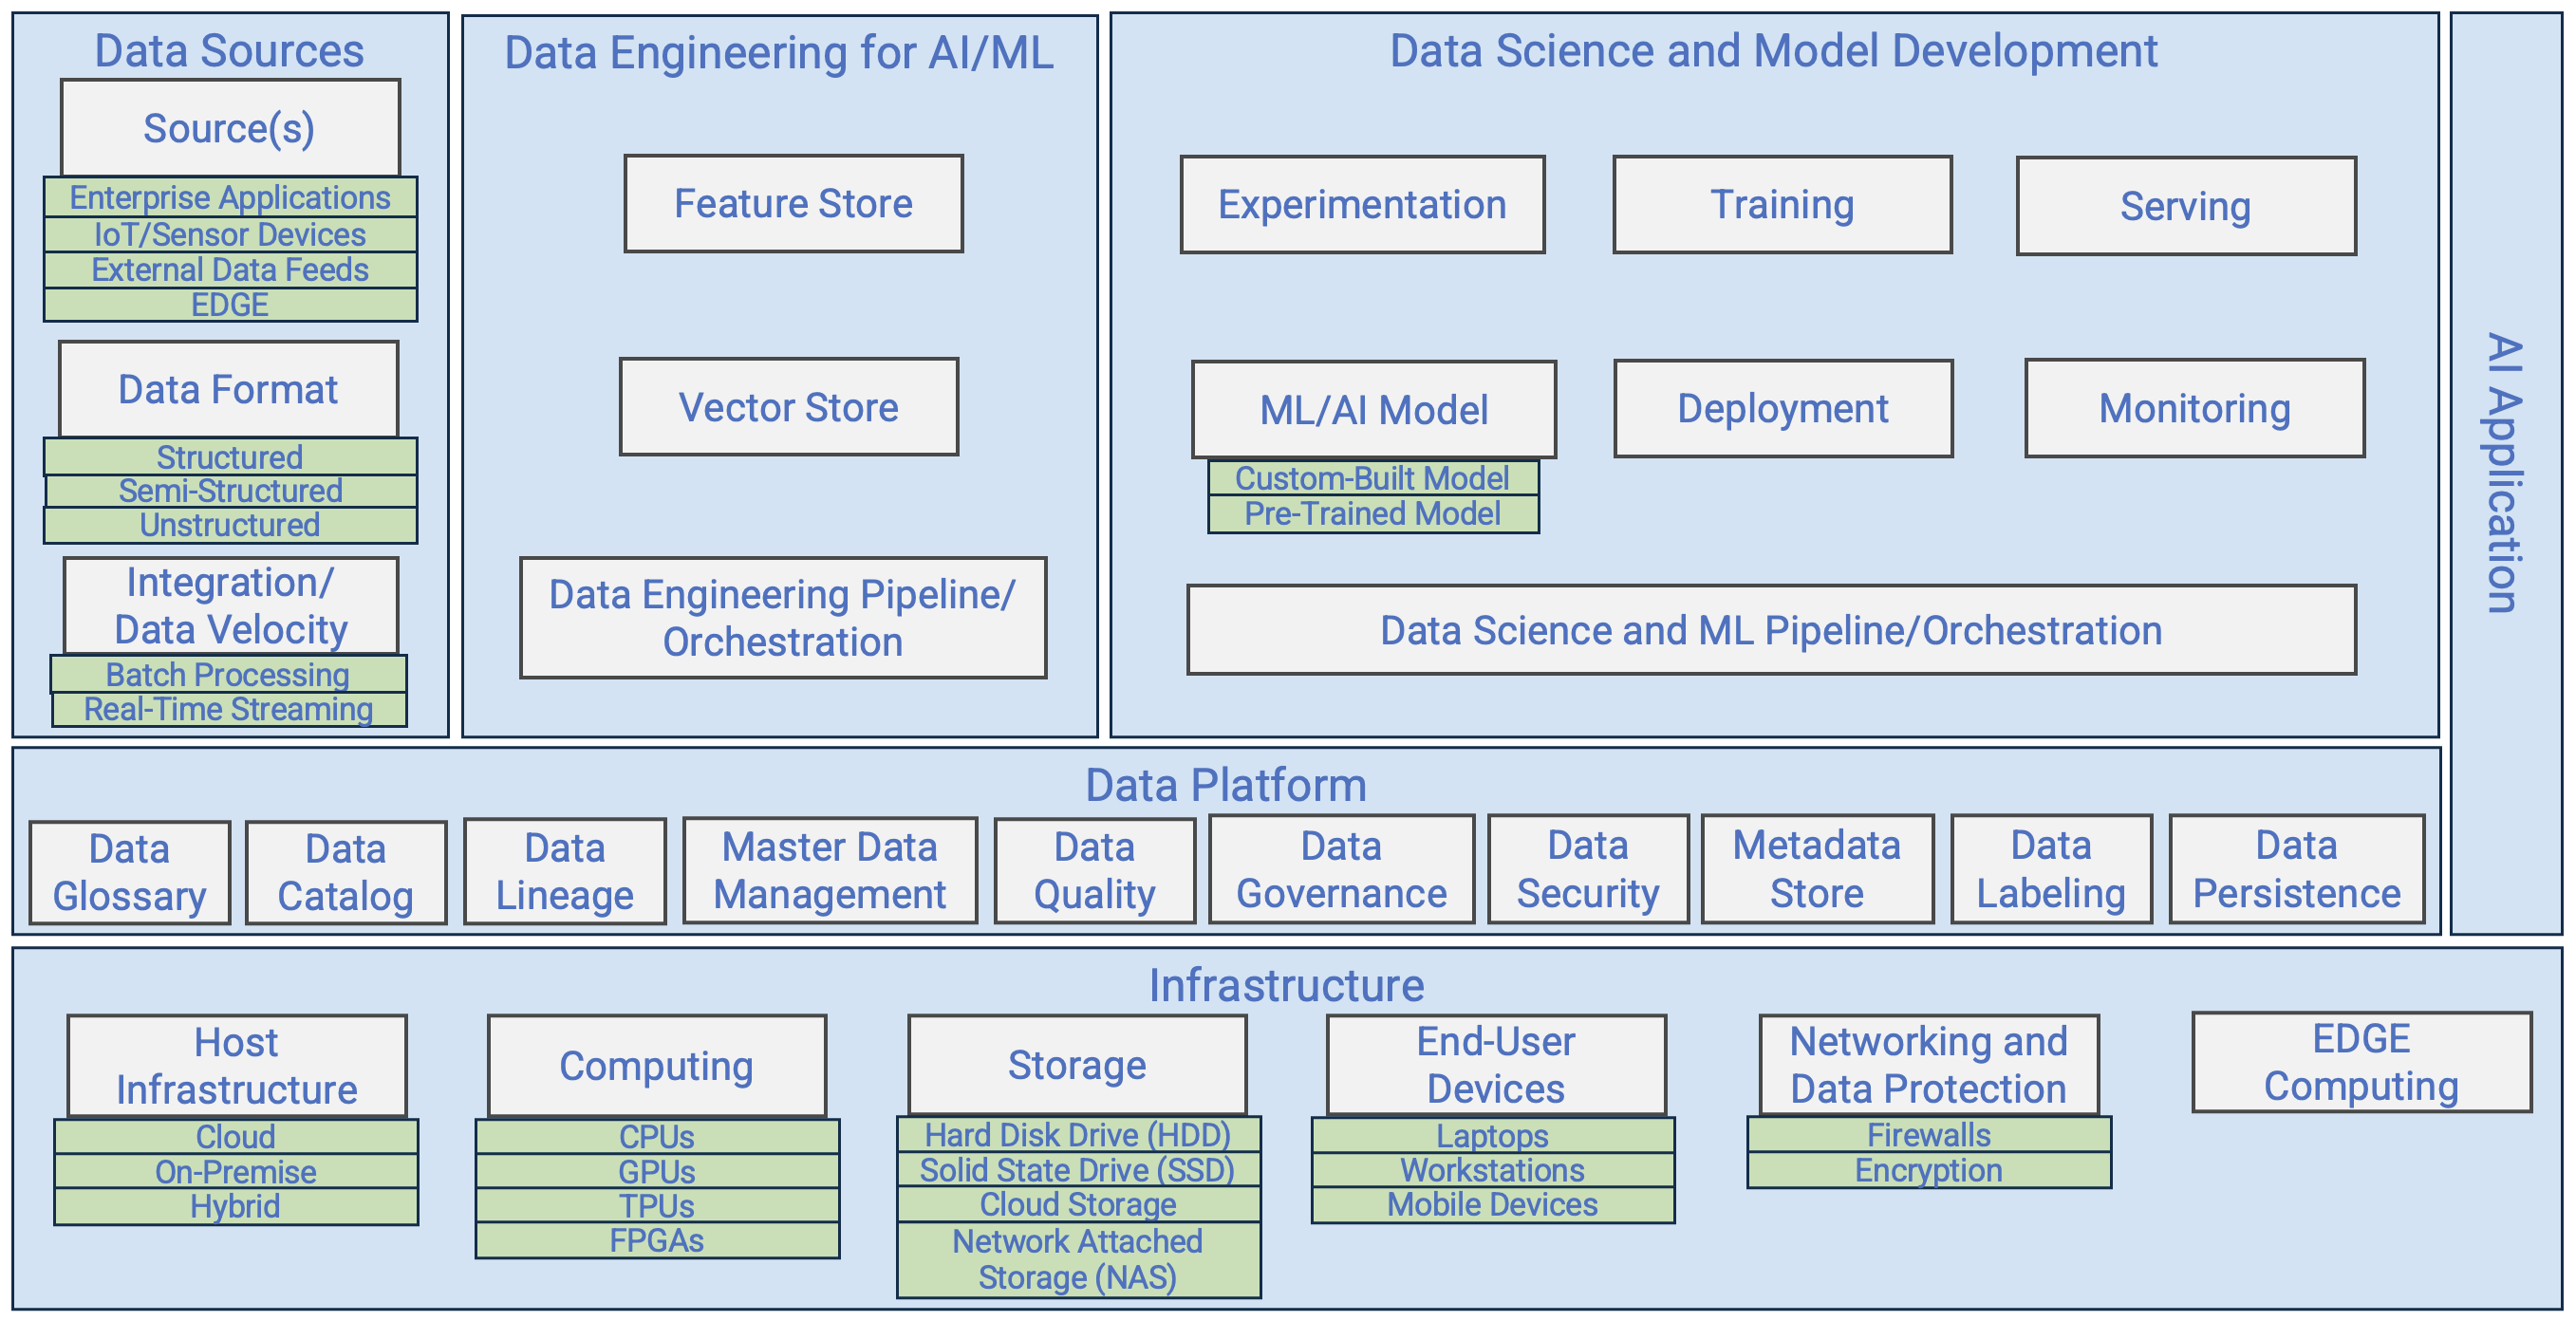
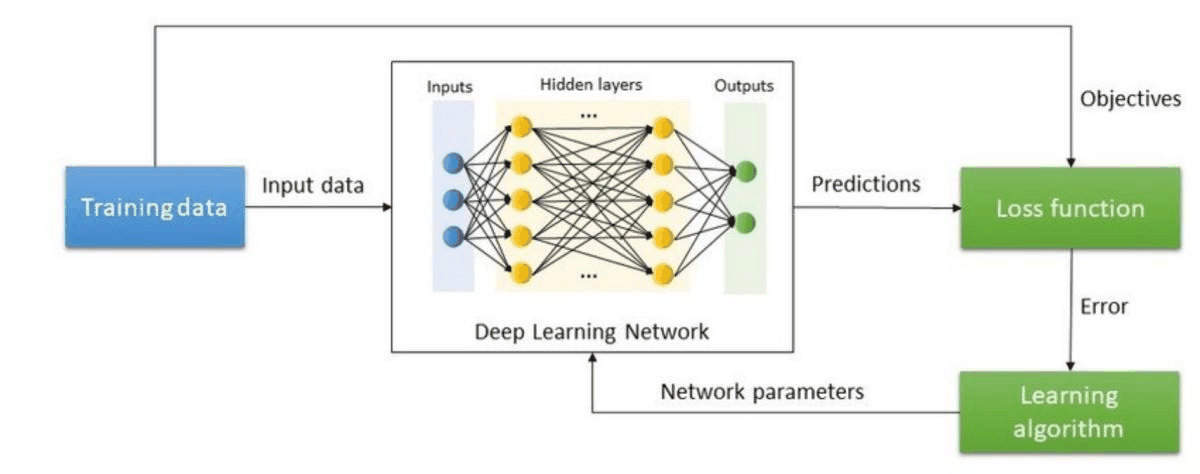
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)