Complete Technical Paper Content — Bert Projects
1. Executive Abstract, Problem Formulation & Background
The following outline is provided as an overview of, and topical guide to, deep learning: Deep learning is a subfield of machine learning and artificial intelligence based on artificial neural networks with multiple processing layers. It emphasizes representation learning and is widely used in areas such as computer vision, natural language processing, speech recognition, recommender systems, robotics, and generative artificial intelligence.
Artificial neuron Activation function Rectified linear unit Sigmoid function Softmax function Embedding Convolution Pooling layer Attention Batch normalization Layer normalization Residual connections
Automatic speech recognition Music information retrieval Speaker recognition Speech synthesis
Backpropagation Conjugate gradient method Generalized Hebbian algorithm Gradient descent Levenberg–Marquardt algorithm Perceptron Quasi-Newton method Wake-sleep algorithm
IEEE Transactions on Neural Networks and Learning Systems Neural Networks Neural Computation
Artificial intelligence Artificial neural network Generative artificial intelligence Glossary of artificial intelligence Lists of open-source artificial intelligence software Machine learning Neural network software Outline of artificial intelligence Outline of computer vision Outline of machine learning Outline of robotics
Artificial intelligence and machine learning techniques are used in video games for a wide variety of applications such as non-player character (NPC) control, procedural content generation (PCG) and deep learning-based content generation. Machine learning is a subset of artificial intelligence that uses historical data to build predictive and analytical models. This is in sharp contrast to traditional methods of artificial intelligence such as search trees and expert systems. Information on machine learning techniques in the field of games is mostly known to public through research projects as most gaming companies choose not to publish specific information about their intellectual property. The most publicly known application of machine learning in games is likely the use of deep learning agents that compete with professional human players in complex strategy games. There has been a significant application of machine learning on games such as Atari/ALE, Doom, Minecraft, StarCraft, and car racing. Other games that did not originally exists as video games, such as chess and Go have also been affected by the machine learning.
The 3D printer available in InZOI (available in early access), a life simulation game developed by InZOI Studio and published by Krafton. Given a 2D image file provided by the user, the 3D printer generates the corresponding 3D object, which the user can then place in the game or use to decorate its avatar. The terrain generation solution implemented in Prologue: Go Wayback! (early access: to be announced, with play tests undergoing in early 2025), a survival game developed by PlayerUnknown Productions. The approach allows to generate a new game map every time the game is launched.
Advances in machine learning models that process language have been rapid in the last few years. This progress has left the research lab and is beginning to power some leading digital products. A great example is the announcement that BERT models are now a significant force behind Google Search. Google believes that this move ( advances in natural language understanding applied to search) represents “the biggest jump in the past five years and one of the biggest in the history of search.” Let’s understand what is BERT? So , in this Article you will get to know about the BERT Implementation Guide and Why we need it, how does it work and either various things you will get to know in this Guide.
BERT stands for Bidirectional Encoder Representations from Transformers . Its design involves pre-training deep bidirectional representations from the unlabeled text, conditioning on both the left and right contexts. We can enhance the pre-trained BERT model for different NLP tasks by adding just one additional output layer.
Proper language representation is the ability of machines to grasp the general language. Context-free models like word2Vec or Glove generate a single word embedding representation for each word in the vocabulary. For example, the term “crane” would have the exact representation in “crane in the sky” and in “crane to lift heavy objects.” Contextual models represent each word based on the other words in the sentence. So BERT is a contextual model which captures these relationships bidirectionally.
BERT builds upon recent work and clever ideas in pre-training contextual representations, including Semi-supervised Sequence Learning, Generative Pre-Training , ELMo, the OpenAI Transformer, ULMFit, and the Transformer. Although these models are all unidirectional or shallowly bidirectional, BERT is fully bidirectional.
We may train the BERT models on our data for a specific purpose, such as sentiment analysis or question answering, to provide advanced predictions, or we can use them to extract high-quality language features from our text data. The next question that comes to mind is, “What’s going on behind it?” Let’s move on to understand this.
A language model(One-Directional Approach) will complete this sentence by saying that the words:
Most respondents (80%) will choose pair, while 20% will select cart right. Both are legitimate, but which should I take into consideration? Select the appropriate word to fill in the blank using the various techniques.
Now BERT comes into the picture, a bi-directionally trained language model. This means we have a more profound sense of language context than single-direction language models.
BERT, or Bidirectional Encoder Representations from Transformers, stands as a pivotal milestone in natural language processing (NLP). Introduced by Google AI in 2018, BERT revolutionized NLP by its ability to capture contextual information bidirectionally. Unlike its predecessors, which read text in one direction, BERT comprehends words in sentences by considering both their left and right context. This capability greatly enhances its understanding of nuances in language, making it highly effective in various NLP tasks.
2. Related Work, Literature Survey & Algorithmic Foundations
BERT’s architecture, based on the Transformer model, involves training on massive text corpora, resulting in a versatile and context-aware language model. Its applications span a wide range of NLP tasks, including sentiment analysis, text classification, question answering, and language understanding. Researchers and developers frequently fine-tune BERT for specific tasks, further leveraging its pre-trained capabilities to achieve state-of-the-art results across various domains. In essence, BERT has become a cornerstone tool in modern NLP, significantly advancing the accuracy and sophistication of language understanding and generation systems.
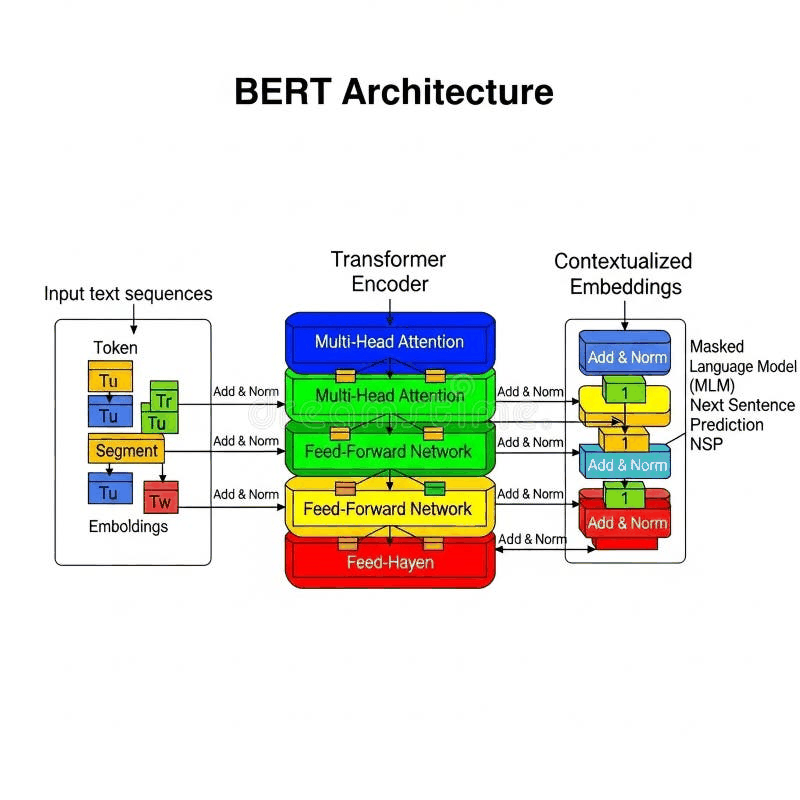
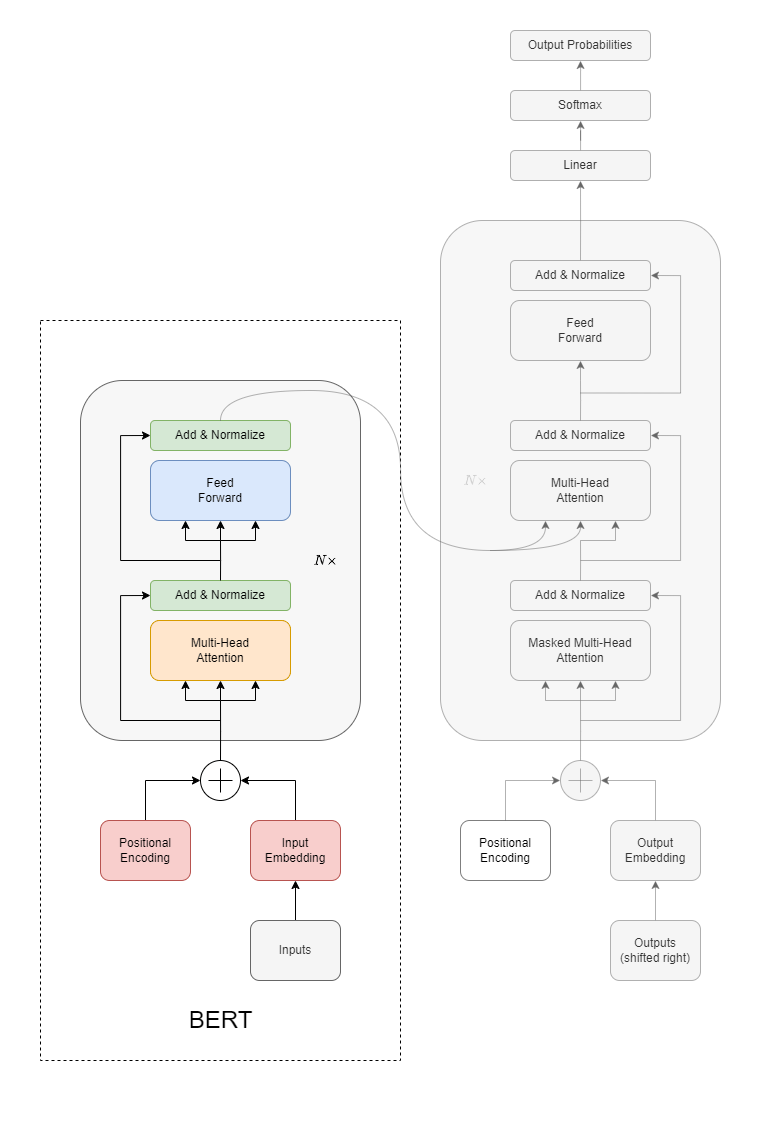
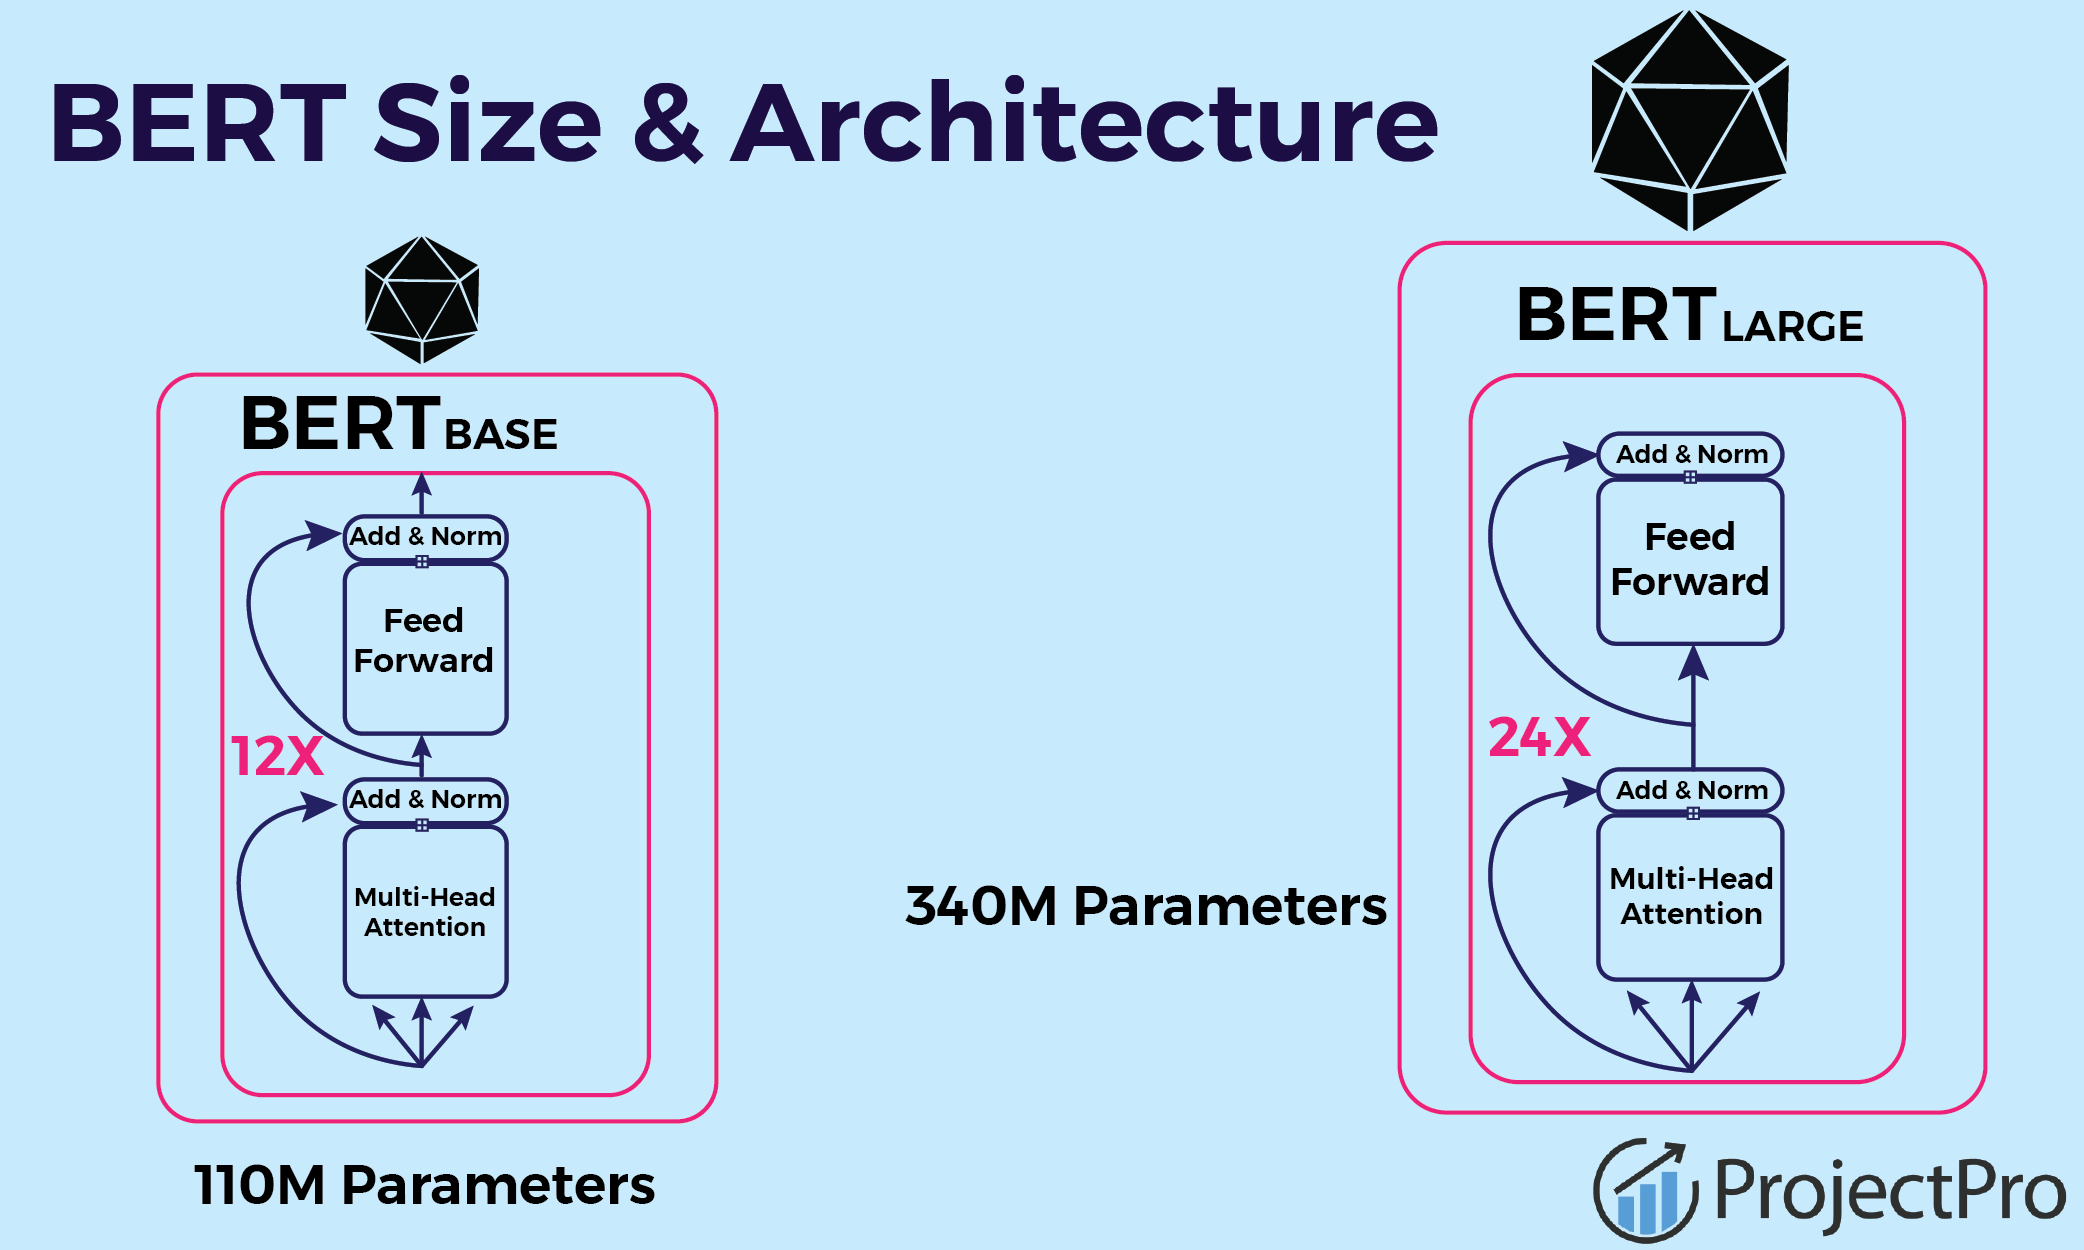
BERT (Bidirectional Encoder Representations from Transformers) is a transformer-based language model architecture. It consists of multiple layers of self-attention and feed-forward neural networks. BERT utilizes a bidirectional approach to capture contextual information from preceding and following words in a sentence. There are four types of pre-trained versions of BERT depending on the scale of the model architecture:
As per your requirement, you can select BERT’s pre-trained weights. For example, we will move forward with base models if we don’t have access to Google TPU. And then, the choice of “cased” vs. “uncased” depends on whether letter casing will be helpful for the task at hand. Let’s Dive into it.
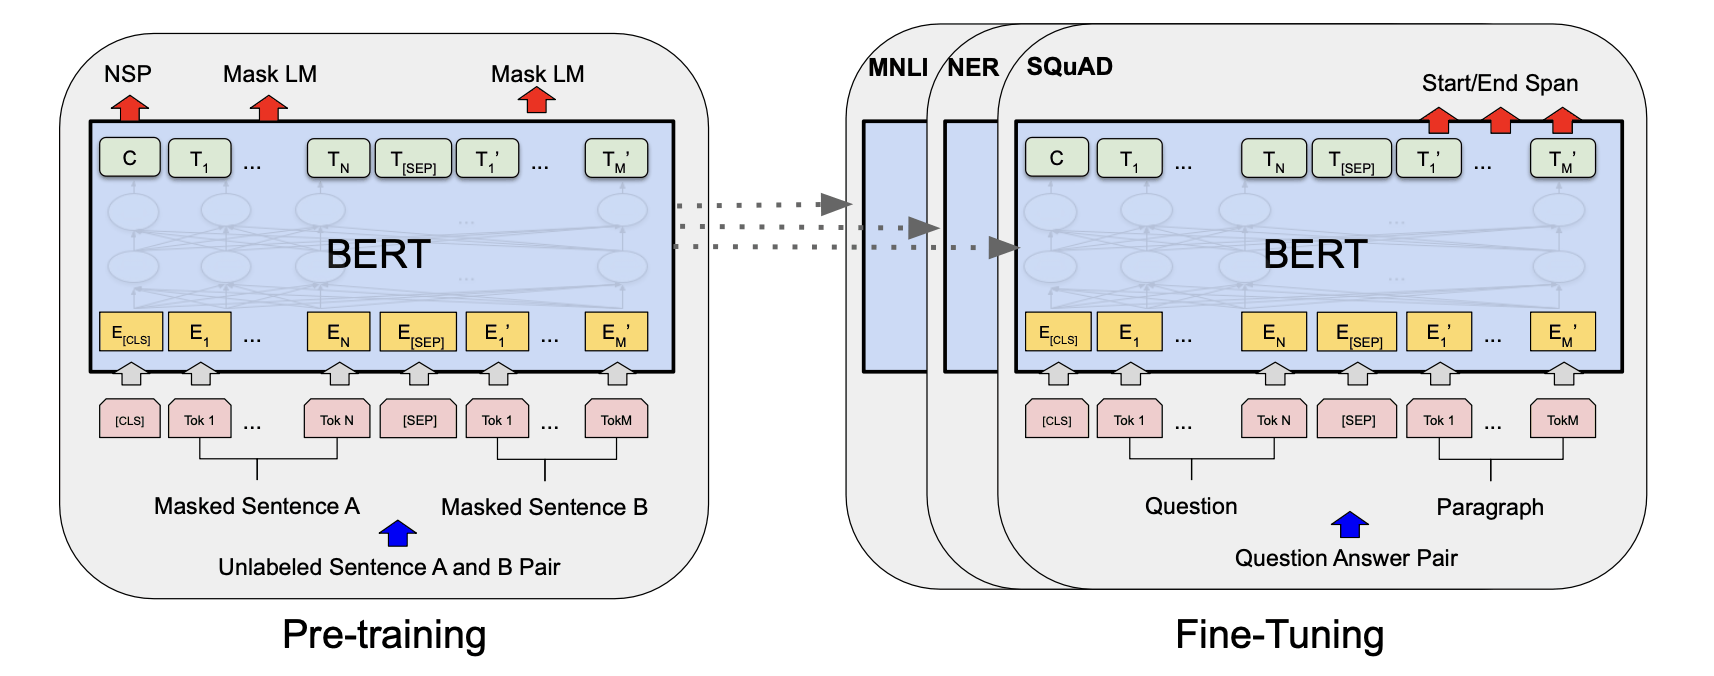
BERT works by leveraging the power of unsupervised pre-training followed by supervised fine-tuning . This section will convert two areas: text preprocessing and pre-training tasks.
A fundamental Transformer consists of an encoder for reading text input and a decoder for producing a task prediction. There is only a need for the encoder element of BERT because its goal is to create a language representation model. The input to the BERT encoder is a stream of tokens first converted into vectors. Then the neural network processes them.
Add the token, segmentation, and position embeddings together to form the input representation for BERT.
Predicting the next word from a string of words is the job of language modeling. In masked language modeling , some input tokens are randomly masked, and only those masked tokens are predicted rather than the token that comes after it.
The following sentence prediction task assesses whether the second sentence in a pair genuinely follows the first sentence. A binary classification problem exists.
Constructing this work from any monolingual corpus is easy. Recognizing the connection between two sentences is beneficial as it is necessary for various downstream tasks like Question and Answering and Natural Language Inference .
BERT is a powerful language model architecture that can be used for a wide variety of natural language processing (NLP) tasks, including:
Implementing BERT (Bidirectional Encoder Representations from Transformers) involves utilizing pre-trained BERT models and fine-tuning them on the specific task. This includes tokenizing the text data, encoding sequences, defining the model architecture, training the model, and evaluating its performance. BERT’s implementation offers powerful language modeling capabilities, allowing for influential natural language processing tasks such as text classification and sentiment analysis . Here’s a list of steps for implementing BERT:
The objective is to create a system that can classify SMS messages as spam or non-spam. This system aims to improve user experience and prevent potential security threats by accurately identifying and filtering out spam messages. The task involves developing a model distinguishing between spam and legitimate texts, enabling prompt detection and action against unwanted messages.
We have several SMS messages, which is the problem. The majority of these emails are authentic. However, some of them are spam. Our goal is to create a system that can instantly determine whether or not a text is spam. Dataset Link:- ()
Imports the necessary libraries and datasets for the task at hand. It prepares the environment by loading the required dependencies and makes the dataset available for further processing and analysis.
import numpy as np import pandas as pd import torch import torch.nn as nn from sklearn.model_selection import train_test_split from sklearn.metrics import classification_report import transformers from transformers import AutoModel, BertTokenizerFast # specify GPU device = torch.device("cuda")
The dataset consists of two columns – “label” and “text.” The column “text” contains the message body, and the “label” is a binary variable where 1 means spam and 0 represents the message that is not spam.
We divide the dataset into three parts based on the given parameters using a library like scikit-learn’s train_test_split function.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
The resulting sets, namely train_text, val_text, and test_text, are accompanied by their respective labels: train_labels, val_labels, and test_labels. These sets can be utilized for training, validating, and testing the machine learning model.
Evaluating model performance on hypothetical data makes it possible to assess models and avoid overfitting properly.
# split train dataset into train, validation and test sets train_text, temp_text, train_labels, temp_labels = train_test_split(df['text'], df['label'], random_state=2018, test_size=0.3, stratify=df['label']) val_text, test_text, val_labels, test_labels = train_test_split(temp_text, temp_labels, random_state=2018, test_size=0.5, stratify=temp_labels)
The BERT-base pre-trained model is imported using the AutoModel.from_pretrained() function from the Hugging Face Transformers library. This allows users to access the BERT architecture and its pre-trained weights for powerful language processing tasks.
The BERT tokenizer is also loaded using the BertTokenizerFast.from_pretrained() function. The tokenizer is responsible for converting input text into tokens that BERT understands. The ‘Bert-base-uncased’ tokenizer is specifically designed for handling lowercase text and is aligned with the ‘Bert-base-uncased’ pre-trained model.
# import BERT-base pretrained model bert = AutoModel.from_pretrained('bert-base-uncased') # Load the BERT tokenizer tokenizer = BertTokenizerFast.from_pretrained('bert-base-uncased')
# get length of all the messages in the train set seq_len = [len(i.split()) for i in train_text] pd.Series(seq_len).hist(bins = 30)
We initialize the vocabulary with all the individual characters in the language and then iteratively update it with the most frequent/likely combinations of the existing words.
We utilize the BERT tokenizer to tokenize and encode the sequences in the training, validation, and test sets. By employing the tokenizer.batch_encode_plus() function, the text sequences are transformed into numerical tokens.
For uniformity in sequence length, a maximum length of 25 is established for each set. When the pad_to_max_length=True parameter is set, the sequences are padded or truncated accordingly. Sequences longer than the specified maximum length are truncated when the truncation=True parameter is enabled.
# tokenize and encode sequences in the training set tokens_train = tokenizer.batch_encode_plus( train_text.tolist(), max_length = 25, pad_to_max_length=True, truncation=True ) # tokenize and encode sequences in the validation set tokens_val = tokenizer.batch_encode_plus( val_text.tolist(), max_length = 25, pad_to_max_length=True, truncation=True ) # tokenize and encode sequences in the test set tokens_test = tokenizer.batch_encode_plus( test_text.tolist(), max_length = 25, pad_to_max_length=True, truncation=True )
To convert the tokenized sequences and corresponding labels into tensors using PyTorch. The “torch. tensor()” function creates tensors from the tokenized sequences and labels.
For each set (training, validation, and test), the tokenized input sequences are converted to tensors using “torch. tensor(tokens_train[‘input_ids’])”. Similarly, the attention masks are converted to tensors using a “torch. tensor(tokens_train[‘attention_mask’])”. Convert the labels to tensors utilizing a torch.tensor(train_labels.tolist()).
Converting the data to tensors allows for efficient computation and compatibility with PyTorch models, enabling further processing and training using BERT or other models in the PyTorch ecosystem.
train_seq = torch.tensor(tokens_train[‘input_ids’]) train_mask = torch.tensor(tokens_train[‘attention_mask’]) train_y = torch.tensor(train_labels.tolist())
val_seq = torch.tensor(tokens_val[‘input_ids’]) val_mask = torch.tensor(tokens_val[‘attention_mask’]) val_y = torch.tensor(val_labels.tolist())
test_seq = torch.tensor(tokens_test[‘input_ids’]) test_mask = torch.tensor(tokens_test[‘attention_mask’]) test_y = torch.tensor(test_labels.tolist())
4. Neural Network Backbone, Layer Specifications & Loss Formulations
The creation of data loaders using PyTorch’s TensorDataset, DataLoader , RandomSampler, and SequentialSampler classes. The TensorDataset class wraps the input sequences, attention masks, and labels into a single dataset object.
We use the RandomSampler to randomly sample the training set, ensuring diverse data representation during training. Conversely, we employ the SequentialSampler for the validation set to sequentially test the data.
To facilitate efficient iteration and batching of the data during training and validation, we employ the DataLoader. This tool enables the creation of iterators over the datasets with a designated batch size, streamlining the process.
from torch.utils.data import TensorDataset, DataLoader, RandomSampler, SequentialSampler #define a batch size batch_size = 32 # wrap tensors train_data = TensorDataset(train_seq, train_mask, train_y) # sampler for sampling the data during training train_sampler = RandomSampler(train_data) # dataLoader for train set train_dataloader = DataLoader(train_data, sampler=train_sampler, batch_size=batch_size) # wrap tensors val_data = TensorDataset(val_seq, val_mask, val_y) # sampler for sampling the data during training val_sampler = SequentialSampler(val_data) # dataLoader for validation set val_dataloader = DataLoader(val_data, sampler = val_sampler, batch_size=batch_size)
The BERT_Arch class extends the nn.Module class and initializes the BERT model as a parameter. By setting the parameters of the BERT model not to require gradients (param.requires_grad = False), we ensure that only the parameters of the added layers are trained during the training process. This technique allows us to leverage the pre-trained BERT model for transfer learning and adapt it to a specific task.
# freeze all the parameters for param in bert.parameters(): param.requires_grad = False
The architecture consists of a dropout layer, a ReLU activation function, two dense layers (with 768 and 512 units, respectively), and a softmax activation function. The forward method takes sentence IDs and masks as inputs, passes them through the BERT model to obtain the output from the classification token (cls_hs), and then applies the defined layers and activations to produce the final classification probabilities.
class BERT_Arch(nn.Module): def __init__(self, bert): super(BERT_Arch, self).__init__() self.bert = bert # dropout layer self.dropout = nn.Dropout(0.1) # relu activation function self.relu = nn.ReLU() # dense layer 1 self.fc1 = nn.Linear(768,512) # dense layer 2 (Output layer) self.fc2 = nn.Linear(512,2) #softmax activation function self.softmax = nn.LogSoftmax(dim=1) #define the forward pass def forward(self, sent_id, mask): #pass the inputs to the model _, cls_hs = self.bert(sent_id, attention_mask=mask, return_dict=False) x = self.fc1(cls_hs) x = self.relu(x) x = self.dropout(x) # output layer x = self.fc2(x) # apply softmax activation x = self.softmax(x) return x
To initialize an instance of the BERT_Arch class with the BERT model as an argument, we pass the pre-trained BERT model to the defined architecture, BERT_Arch. This establishes the BERT model as the backbone of the custom architecture.
The model is moved to the GPU by calling the to() method and specifying the desired device (device) to leverage GPU acceleration. This allows for faster computations during training and inference by utilizing the parallel processing capabilities of the GPU.
# pass the pre-trained BERT to our define architecture model = BERT_Arch(bert) # push the model to GPU model = model.to(device)
The AdamW optimizer from the Hugging Face import the Transformers library. AdamW is a variant of the Adam optimizer that includes weight decay regularization.
The optimizer is then defined by passing the model parameters (model. parameters()) and the learning rate (lr) of 1e-5 to the AdamW optimizer constructor. This optimizer will update the model parameters during training, optimizing the model’s performance on the task at hand.
The compute_class_weight function from the sklearn.utils.class_weight module is used to compute the class weights with multiple parameters for the training labels.
#compute the class weights class_weights = compute_class_weight(‘balanced’, np.unique(train_labels), train_labels)
To convert the class weights to a tensor, move it to the GPU and defines the loss function with weighted class weights. The number of training epochs is set to 10.
# converting list of class weights to a tensor weights= torch.tensor(class_weights,dtype=torch.float) # push to GPU weights = weights.to(device) # define the loss function cross_entropy = nn.NLLLoss(weight=weights) # number of training epochs epochs = 10
5. Training Protocol, Convergence Behavior & Experimental Evaluation
A training function that iterates over batches of data performs forward and backward passes, updates model parameters and computes the training loss. The function also stores the model predictions and returns the average loss and predictions.
# function to train the model def train(): model.train() total_loss, total_accuracy = 0, 0 # empty list to save model predictions total_preds=[] # iterate over batches for step,batch in enumerate(train_dataloader): # progress update after every 50 batches. if step % 50 == 0 and not step == 0: print(' Batch {:>5,} of {:>5,}.'.format(step, len(train_dataloader))) # push the batch to gpu batch = [r.to(device) for r in batch] sent_id, mask, labels = batch # clear previously calculated gradients model.zero_grad() # get model predictions for the current batch preds = model(sent_id, mask) # compute the loss between actual and predicted values loss = cross_entropy(preds, labels) # add on to the total loss total_loss = total_loss + loss.item() # backward pass to calculate the gradients loss.backward() # clip the the gradients to 1.0. It helps in preventing the exploding gradient problem torch.nn.utils.clip_grad_norm_(model.parameters(), 1.0) # update parameters optimizer.step() # model predictions are stored on GPU. So, push it to CPU preds=preds.detach().cpu().numpy() # append the model predictions total_preds.append(preds) # compute the training loss of the epoch avg_loss = total_loss / len(train_dataloader) # predictions are in the form of (no. of batches, size of batch, no. of classes). # reshape the predictions in form of (number of samples, no. of classes) total_preds = np.concatenate(total_preds, axis=0) #returns the loss and predictions return avg_loss, total_preds
An evaluation function that evaluates the model on the validation data. It computes the validation loss, stores the model predictions, and returns the average loss and predictions. The function deactivates dropout layers and performs forward passes without gradient computation using torch.no_grad().
# function for evaluating the model def evaluate(): print("\nEvaluating...") # deactivate dropout layers model.eval() total_loss, total_accuracy = 0, 0 # empty list to save the model predictions total_preds = [] # iterate over batches for step,batch in enumerate(val_dataloader): # Progress update every 50 batches. if step % 50 == 0 and not step == 0: # Calculate elapsed time in minutes. elapsed = format_time(time.time() - t0) # Report progress. print(' Batch {:>5,} of {:>5,}.'.format(step, len(val_dataloader))) # push the batch to gpu batch = [t.to(device) for t in batch] sent_id, mask, labels = batch # deactivate autograd with torch.no_grad(): # model predictions preds = model(sent_id, mask) # compute the validation loss between actual and predicted values loss = cross_entropy(preds,labels) total_loss = total_loss + loss.item() preds = preds.detach().cpu().numpy() total_preds.append(preds) # compute the validation loss of the epoch avg_loss = total_loss / len(val_dataloader) # reshape the predictions in form of (number of samples, no. of classes) total_preds = np.concatenate(total_preds, axis=0) return avg_loss, total_preds
To train the model for the specified number of epochs. It tracks the best validation loss, saves the model weights if the current validation loss is better, and appends the training and validation losses to their respective lists. The training and validation losses are printed for each epoch.
# set initial loss to infinite best_valid_loss = float('inf') #defining epochs epochs = 1 # empty lists to store training and validation loss of each epoch train_losses=[] valid_losses=[] #for each epoch for epoch in range(epochs): print('\n Epoch {:} / {:}'.format(epoch + 1, epochs)) #train model train_loss, _ = train() #evaluate model valid_loss, _ = evaluate() #save the best model if valid_loss < best_valid_loss: best_valid_loss = valid_loss torch.save(model.state_dict(), 'saved_weights.pt') # append training and validation loss train_losses.append(train_loss) valid_losses.append(valid_loss) print(f'\nTraining Loss: {train_loss:.3f}') print(f'Validation Loss: {valid_loss:.3f}')
To load the best model weights from the saved file ‘saved_weights.pt’ using torch.load() and set them in the model using model.load_state_dict().
#load weights of best model path = 'saved_weights.pt' model.load_state_dict(torch.load(path))
To make predictions on the test data using the trained model and converts the predictions to NumPy arrays. We compute classification metrics, including precision, recall, and F1-score, to evaluate the model’s performance using the classification_report function from scikit-learn’s metrics module.
# get predictions for test data with torch.no_grad(): preds = model(test_seq.to(device), test_mask.to(device)) preds = preds.detach().cpu().numpy() # model's performance preds = np.argmax(preds, axis = 1) print(classification_report(test_y, preds))
In conclusion, BERT is undoubtedly a breakthrough in using Machine Learning for Natural Language Processing. The fact that it’s approachable and allows fast fine-tuning will likely enable a wide range of practical applications in the future. This step-by-step BERT implementation tutorial empowers users to build powerful language models that can accurately understand and generate natural language.
A: Google developed BERT (Bidirectional Encoder Representations from Transformers), a transformer-based neural network architecture. It captures the bidirectional context of words, enabling understanding and generation of natural language.
A: Traditional language models, such as word2vec or GloVe, generate fixed-size word embeddings. In contrast, BERT generates contextualized word embeddings by considering the entire sentence context, allowing it to capture more nuanced meaning and context in language.
A: Yes, fine-tuning BERT enables its application in various tasks, such as sequence labeling, text generation, text summarization, and document classification, among others. It has a wide range of applications beyond just text classification.
A: BERT captures contextual information, allowing it to understand the meaning of words in different contexts. It handles polysemy (words with multiple meanings) and captures complex linguistic patterns, improving performance on various NLP tasks compared to traditional word embeddings.
BERT stands for Bidirectional Encoder Representations from Transformers. It is a type of language model that can understand the meaning of text by considering the context of the words around it. BERT is trained on a massive dataset of text and code, and it can be used for a variety of tasks, such as answering questions, summarizing text, and translating languages.
Hi, I am Kajal Kumari. have completed my Master’s from IIT(ISM) Dhanbad in Computer Science & Engineering. As of now, I am working as Machine Learning Engineer in Hyderabad. hope that you have enjoyed the article. If you like it, share it with your friends also. Please feel free to comment if you have any thoughts that can improve my article writing.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)