Complete Technical Paper Content — Churn Prediction Machine Learning
1. Executive Abstract, Problem Formulation & Background
Churn rate (also known as attrition rate, customer turnover, or customer defection) is a metric that measures the proportion of individuals (e.g. employees), customers, or items that leave a defined group during a specified period of time. In business and economics, it is commonly used to assess customer retention and the stability of recurring-revenue models, particularly in subscription-based or contractual services. Churn rate is widely applied in industries with contractual customer bases, such as telecommunications, subscription media services, software-as-a-service (SaaS), and utilities. It is a key input in customer lifetime value (CLV) modeling and is often used to evaluate marketing effectiveness and long-term revenue sustainability. The term originates from the analogy of agitation in a butter churn, reflecting continuous customer movement in and out of a service base.
Churn = L T ∗ 100 = Customers lost Total customers during time period ∗ 100 {\displaystyle {\text{Churn}}={\frac {L}{T}}*100={\frac {\text{Customers lost}}{\text{Total customers during time period}}}*100}
For example, if your company lost 50 customers in month, while having a total of 500 customers at the start of the month, the total churn rate is 10% (50/500*100 = 10%). An alternative calculation for churn is to divide by the number of customers acquired during the same time period, rather than total number of customers.
Churn rate, when applied to a customer base, is the proportion of contractual customers or subscribers who leave a supplier during a given period. It may indicate customer dissatisfaction, cheaper and/or better offers from the competition, more successful sales and/or marketing by the competition, or reasons having to do with the customer life cycle. Churn is closely related to the concept of average customer life time. For example, an annual churn rate of 25 percent implies an average customer life of four years. An annual churn rate of 33 percent implies an average customer life of three years. The churn rate can be minimized by creating barriers which discourage customers to change suppliers (contractual binding periods, use of proprietary technology, value-added services, unique business models, etc.), or through retention activities such as loyalty programs. It is possible to overstate the churn rate, as when a consumer drops the service but then restarts it within the same year. Thus, a clear distinction needs to be made between "gross churn", the total number of absolute disconnections, and "net churn", the overall loss of subscribers or members. The difference between the two measures is the number of new subscribers or members that have joined during the same period. Suppliers may find that if they offer a loss-leader "introductory special", it can lead to a higher churn rate and subscriber abuse, as some subscribers will sign on, let the service lapse, then sign on again to take continuous advantage of current specials. When talking about subscribers or customers, sometimes the expression "survival rate" is used to mean 1 minus the churn rate. For example, for a group of subscribers, an annual churn rate of 25 percent is the same as an annual survival rate of 75 percent. Both imply a customer lifetime of four years because a customer lifetime can be calculated as the inverse of that customer's predicted churn rate. For a group or segment of customers, their customer life (or tenure) is the inverse of their aggregate churn rate. Gompertz distribution models of distribution of customer life times can therefore also predict a distribution of churn rates. For companies with a fast-growing customer base (e.g., digital media companies in a BCG-matrix problem child or star phase), confusion can arise between the statistical analyses associated with what percentage of the whole customer base churns in a given year – What percentage of the base of subscribers in all of 2010 churned out? – versus a particular customer cohort's churn rate. For example: Taking those customers who subscribed in given month, say January 2010 – How many had churned out by January 2011? Examining churn for a fast-growing aggregated customer base will understate the true churn rate compared to cohort based approach to the calculation. The cohort based approach will also allow you to calculate the survival rate and the average customer life, whereas the aggregate approach can not calculate these two metrics. In recent years, using AI and machine-learning as a means to calculate customer churn has become increasingly common for large retailers and service providers. The phrase "rotational churn" is used to describe the phenomenon where a customer churns and immediately rejoins. This is common in prepaid mobile phone services, where existing customers may take up a new subscription from their current provider in order to avail of special offers only available to new customers. In most circumstances churn is seen as indicating that customers are dissatisfied with a service. However, in some industries whose services delivers on a promise, churn is considered as a positive signal, such as the health care services, weight loss services and online dating platforms. Some researchers have disputed the simple assumption that just dissatisfaction would lead customers to churn, and called for a more nuanced approach.
In finance and mathematics, predictive modelling is the use of statistics to predict outcomes. Most often the event one wants to predict is in the future, but predictive modelling can be applied to any type of unknown event, regardless of when it occurred. For example, predictive models are often used to detect crimes and identify suspects, after the crime has taken place. The output of predictive models can come in multiple forms, such as an estimated probability of a certain event occurring (e.g. Binary regression), or a scalar response variable (e.g. Linear regression). The usage of predictive modelling in business decision making is often referred to as predictive analytics. Predictive modelling is often contrasted with causal modelling. In the former, one may be entirely satisfied to make use of indicators of, or proxies for, the outcome of interest. In the latter, one seeks to determine true cause-and-effect relationships. This distinction has given rise to a burgeoning literature in the fields of research methods and statistics and to the common statement that "correlation does not imply causation". Depending on definitional boundaries, predictive modelling is synonymous with, or largely overlapping with, the field of machine learning, as it is more commonly referred to in academic or research and development contexts. This growing field has been made more accessible through increases in computing power and new data architectures that allow for more efficient model training techniques (see Attention Is All You Need). As the power and complexity of predictive modelling continue to grow, fairness in predictive models has become a growing field of study, particularly given the applications of predictive modelling within areas such as healthcare, insurance, and lending.
Predictive modelling gives lead generators a head start by forecasting data-driven outcomes for each potential campaign. This method saves time and exposes potential blind spots to help client make smarter decisions.
Telecom Customer Churn Prediction Using a Two-Phase Hybrid Architecture 📌 Project Overview This project presents a two-phase hybrid architecture for predicting customer churn in the telecommunications domain. The proposed approach combines traditional machine learning models with advanced deep learning models to improve customer churn prediction. The project involves large-scale data preprocessing, feature selection, class-imbalance handling, machine learning-based initial prediction, and a second-phase deep learning architecture for refined churn prediction. 🎯 Objectives Predict customer churn using machine learning and deep learning techniques. Perform preprocessing and feature engineering on a large-scale telecom churn dataset. Handle class imbalance using SMOTE. Develop an initial churn prediction phase using multiple machine learning models. Use the predictions generated in Phase 1 as additional information for Phase 2. Develop ANN and BiLSTM-based models for advanced churn prediction. Compare the performance of different models. Apply SHAP-based model interpretation. Perform hyperparameter optimization for selected models. 🏗️ Proposed Architecture The project follows a two-phase hybrid learning architecture. Telecom Customer Dataset │ ▼ Data Preprocessing │ ▼ Feature Engineering │ ▼ Feature Selection │ ▼ ┌──────────────────────────┐ │ PHASE 1 │ │ Machine Learning │ │ │ │ LR / DT / RF / XGBoost │ │ CatBoost / Other Models │ └────────────┬─────────────┘ │ ▼ Initial Churn Predictions │ ▼ Original Features + Predictions │ ▼ ┌──────────────────────────┐ │ PHASE 2 │ │ Deep Learning │ │ │ │ ANN / BiLSTM │ └────────────┬─────────────┘ │ ▼ Final Churn Prediction 🔬 Methodology The project consists of the following major stages: 1. Data Preprocessing The dataset is processed to prepare it for machine learning and deep learning models. The preprocessing pipeline includes handling data quality issues and preparing the features for subsequent modelling stages. 2. Feature Selection Feature selection techniques are applied to identify relevant features and reduce unnecessary dimensionality. 3. Handling Class Imbalance SMOTE (Synthetic Minority Over-sampling Technique) is used to address class imbalance in the churn prediction problem. 4. Phase 1 — Machine Learning Multiple machine learning algorithms are investigated for initial churn prediction. The project includes models such as: Logistic Regression Decision Tree Random Forest XGBoost CatBoost The Phase 1 models generate initial churn predictions/probabilities that are subsequently used in the second phase. 5. Phase 2 — Deep Learning The processed features are combined with information generated from Phase 1 and used for advanced prediction. The project explores: Artificial Neural Network (ANN) Bidirectional LSTM (BiLSTM) Hybrid deep learning architecture 6. Model Interpretation SHAP (SHapley Additive exPlanations) is used to investigate feature importance and model interpretability. 7. Hyperparameter Optimization Hyperparameter optimization is performed for selected models using Optuna. 🛠️ Technologies Used Programming Language Python Machine Learning Scikit-learn XGBoost CatBoost Deep Learning TensorFlow / Keras Data Processing Pandas NumPy Data Visualization Matplotlib Seaborn Imbalanced Learning Imbalanced-learn / SMOTE Explainable AI SHAP Hyperparameter Optimization Optuna Experiment Tracking MLflow 📂 Repository Structure telecom-churn-prediction/ │ ├── README.md ├── requirements.txt ├── .gitignore │ ├── notebooks/ │ └── Telecom_Churn_FeatureSelection.ipynb │ ├── dataset/ │ └── README.md │ ├── results/ │ └── README.md │ ├── report/ │ └── Final_Project_Report.pdf │ └── research-paper/ └── Published_Paper.pdf Some files and directories will be added or updated as the project repository is further organized. 📊 Dataset The project uses a large-scale telecom customer churn dataset. The dataset itself is currently not included in this repository. Dataset availability and redistribution will depend on the original dataset source and its licensing conditions. 🚀 Project Status Final Year Academic Project The repository is being organized to document the source code, methodology, experiments, results, project report, and associated research publication. 📄 Documentation The complete project report will be added to the report/ directory. The associated research publication will be added to the research-paper/ directory subject to the applicable publication and copyright policies. 👨💻 Authors Rudra Prasad Sahu B.Tech — Computer Science & Engineering Final Year Project 📌 Note This repository is intended for academic and educational purposes and documents the implementation and research work carried out as part of the final-year project.
This project presents a two-phase hybrid architecture for predicting customer churn in the telecommunications domain.
The proposed approach combines traditional machine learning models with advanced deep learning models to improve customer churn prediction.
The project involves large-scale data preprocessing, feature selection, class-imbalance handling, machine learning-based initial prediction, and a second-phase deep learning architecture for refined churn prediction.
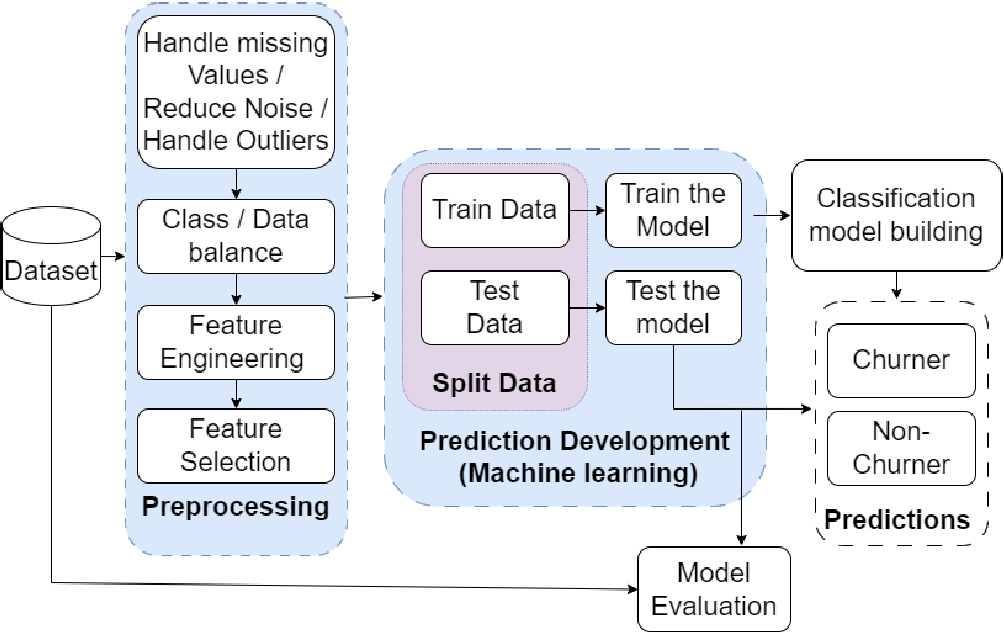
Telecom Customer Dataset │ ▼ Data Preprocessing │ ▼ Feature Engineering │ ▼ Feature Selection │ ▼ ┌──────────────────────────┐ │ PHASE 1 │ │ Machine Learning │ │ │ │ LR / DT / RF / XGBoost │ │ CatBoost / Other Models │ └────────────┬─────────────┘ │ ▼ Initial Churn Predictions │ ▼ Original Features + Predictions │ ▼ ┌──────────────────────────┐ │ PHASE 2 │ │ Deep Learning │ │ │ │ ANN / BiLSTM │ └────────────┬─────────────┘ │ ▼ Final Churn Prediction
2. Related Work, Literature Survey & Algorithmic Foundations
The preprocessing pipeline includes handling data quality issues and preparing the features for subsequent modelling stages.
Feature selection techniques are applied to identify relevant features and reduce unnecessary dimensionality.
SMOTE (Synthetic Minority Over-sampling Technique) is used to address class imbalance in the churn prediction problem.
The Phase 1 models generate initial churn predictions/probabilities that are subsequently used in the second phase.
The processed features are combined with information generated from Phase 1 and used for advanced prediction.
SHAP (SHapley Additive exPlanations) is used to investigate feature importance and model interpretability.
telecom-churn-prediction/ │ ├── README.md ├── requirements.txt ├── .gitignore │ ├── notebooks/ │ └── Telecom_Churn_FeatureSelection.ipynb │ ├── dataset/ │ └── README.md │ ├── results/ │ └── README.md │ ├── report/ │ └── Final_Project_Report.pdf │ └── research-paper/ └── Published_Paper.pdf
Some files and directories will be added or updated as the project repository is further organized.
The dataset itself is currently not included in this repository. Dataset availability and redistribution will depend on the original dataset source and its licensing conditions.
The repository is being organized to document the source code, methodology, experiments, results, project report, and associated research publication.
The associated research publication will be added to the research-paper/ directory subject to the applicable publication and copyright policies.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
This repository is intended for academic and educational purposes and documents the implementation and research work carried out as part of the final-year project.
Telecom Customer Churn Prediction using a Two-Phase Hybrid Machine Learning and Deep Learning Architecture
🔥 Customer Churn Prediction with Deep Learning Predict • Analyze • Visualize • Learn A hands-on deep learning project for predicting customer churn using TensorFlow/Keras , with a complete workflow covering data preprocessing, exploratory data analysis, feature engineering, neural-network modeling, evaluation, and visualization. 📌 Overview Customer churn is one of the most important business problems in subscription-based industries. The goal of this project is to build a neural-network model that learns patterns in historical customer data and predicts whether a customer is likely to leave a service. This repository is designed as both a practical machine-learning project and a deep-learning learning exercise . It focuses on understanding the end-to-end pipeline rather than treating the model as a black box. 🎯 Main Objective Build a binary classification model that predicts whether a customer will churn based on demographic, account, and banking-related features. 🧠 What This Project Covers Raw Customer Data ↓ Data Loading ↓ Exploratory Data Analysis ↓ Data Cleaning & Preprocessing ↓ Encoding Categorical Features ↓ Feature Scaling ↓ Train / Test Split ↓ Neural Network Design ↓ Model Training ↓ Validation & Evaluation ↓ Visualization ↓ Churn Prediction ✨ Key Learning Areas 📊 Exploratory Data Analysis (EDA) 🧹 Data preprocessing and transformation 🔤 Categorical feature encoding ⚖️ Feature scaling 🧠 Artificial Neural Networks (ANN) 🔥 TensorFlow / Keras model building 📈 Training and validation analysis 🎯 Binary classification 📋 Model evaluation 📉 Loss and accuracy visualization 🔍 Interpreting customer churn patterns 🗂️ Repository Structure customer-churn-deep-learning/ │ ├── 📄 Churn_Modelling.csv # Customer churn dataset ├── 📓 Model.ipynb # Complete analysis and deep learning workflow └── 📘 README.md # Project documentation The repository currently contains the original customer churn dataset , the main Jupyter notebook , and this project documentation. fileciteturn1file0L2-L2 📊 Dataset The project uses the Churn_Modelling.csv dataset stored directly in the repository. The dataset contains customer-level information commonly used for churn classification, including a mixture of numerical, categorical, demographic, and account-related attributes. Typical churn modeling inputs in this dataset include fields such as: Feature Group Examples Customer identity Row number, customer ID, surname Geography Country / geography Demographics Gender, age Account profile Credit score, tenure, balance Product usage Number of products, active membership Banking / relationship Estimated salary, card status Target Customer churn / exit indicator Note: The notebook is the source of truth for the exact preprocessing steps, selected features, model architecture, training configuration, and evaluation output. 🧪 Project Workflow 1. Data Loading The dataset is loaded into a Pandas DataFrame for inspection and analysis. 2. Exploratory Data Analysis The notebook explores the dataset using statistics and visualizations to understand: Class distribution Numerical feature distributions Categorical feature patterns Relationships between customer attributes and churn Potential outliers and unusual values 3. Data Preprocessing The workflow prepares the raw data for neural-network training by handling categorical data, selecting useful features, and transforming the input matrix into a model-ready numerical representation. 4. Feature Scaling Numerical inputs are normalized/scaled so that features with very different ranges do not dominate the training process. 5. Train/Test Split The prepared data is divided into training and testing subsets so the model can be trained on one portion and evaluated on unseen samples. 6. Neural Network Modeling A feed-forward neural network is trained for binary classification using TensorFlow/Keras. Conceptually: Input Features ↓ Dense Layer ↓ Activation ↓ Dense Layer ↓ Activation ↓ Output Layer ↓ Churn Probability 7. Model Training The model learns from the training data over multiple epochs while monitoring loss and classification performance. 8. Evaluation The notebook evaluates the trained model on unseen data and visualizes training behavior to understand model performance and potential overfitting. 9. Prediction The final model can be used to estimate the probability that an individual customer belongs to the churn class. 📈 Visualizations The project emphasizes visual understanding of both the data and the model-training process. Depending on the notebook execution, visualizations may include: Customer churn distribution Feature distributions Categorical feature comparisons Correlation analysis Training vs. validation accuracy Training vs. validation loss Prediction/evaluation plots These plots help turn model output into something interpretable instead of relying on a single accuracy number. 🛠️ Tech Stack Tool Purpose 🐍 Python Core programming language 🐼 Pandas Data loading and manipulation 🔢 NumPy Numerical operations 📊 Matplotlib Data visualization 🎨 Seaborn Statistical visualization 🤖 TensorFlow Deep learning framework 🧠 Keras Neural network API 📓 Jupyter Notebook Interactive development and experimentation 🚀 Getting Started 1. Clone the repository git clone https://github.com/Maganpreet-Singh/customer-churn-deep-learning.git cd customer-churn-deep-learning 2. Create a virtual environment Windows python -m venv .venv .venv \S cripts \a ctivate macOS / Linux python3 -m venv .venv source .venv/bin/activate 3. Install dependencies pip install numpy pandas matplotlib seaborn scikit-learn tensorflow jupyter 4. Launch Jupyter Notebook jupyter notebook Then open: Model.ipynb 5. Run the notebook Execute the cells from top to bottom so that preprocessing, training, evaluation, and visualization happen in the intended order. 💡 Why Deep Learning for Churn? Traditional machine-learning algorithms can perform very well on structured tabular data, and they should absolutely be considered during a serious modeling process. This project uses an artificial neural network primarily to build practical understanding of deep learning for binary classification. The project is especially useful for learning how a neural network connects: Data → Preprocessing → Features → Network → Training → Evaluation → Prediction That pipeline is the real skill. The model is just one component of it. 🔍 Model Evaluation For a churn classification problem, accuracy alone is not enough. A stronger evaluation strategy can include: Accuracy — overall proportion of correct predictions Precision — how many predicted churners actually churned Recall — how many actual churners were successfully identified F1-score — balance between precision and recall Confusion Matrix — detailed breakdown of classification errors ROC-AUC — ranking quality across classification thresholds The exact metrics and values should be taken from the executed notebook rather than hard-coded here, so the README stays aligned with the current experiment. 📚 Learning Outcomes After completing this project, you should have practical exposure to: Preparing real-world tabular data for deep learning Encoding categorical variables for neural networks Scaling numerical features Designing a basic ANN with Keras Training a TensorFlow model Monitoring model performance across epochs Evaluating binary classification results Communicating results through visualizations Structuring a reproducible Jupyter-based ML project 🔮 Future Improvements This project can be extended significantly as your deep-learning skills grow. Model Improvements Compare ANN performance with Logistic Regression, Random Forest, XGBoost, and other tabular models Experiment with deeper or wider network architectures Tune batch size, learning rate, optimizer, and number of epochs Add dropout and other regularization techniques Introduce early stopping and learning-rate scheduling Evaluation Improvements Add a confusion matrix heatmap Add precision, recall, F1-score, and ROC-AUC Plot ROC and Precision-Recall curves Perform cross-validation with suitable classical baselines Project Engineering Add requirements.txt Add a dedicated training script Add saved model artifacts Add a prediction script or API Add experiment tracking Add CI checks with GitHub Actions Add a polished results section with reproducible metrics 🧩 Example Prediction Concept A deployed version of this project could accept customer information and return a churn probability: Customer Data ↓ Preprocessing Pipeline ↓ Trained Neural Network ↓ Probability of Churn ↓ Business Retention Decision A production system could then use this probability to prioritize retention campaigns, identify high-risk customer segments, and support customer-success teams. ⚠️ Important Notes This repository is primarily a learning and portfolio project . The model's actual performance depends on the current notebook code, preprocessing pipeline, random seeds, training configuration, and execution environment. Re-run the notebook to reproduce the latest visualizations and metrics. Do not treat model predictions as business truth without validating the model on appropriate production data. 🤝 Contributing Contributions, suggestions, and improvements are welcome. A good contribution could include: Better feature engineering Improved evaluation metrics Model comparison experiments Hyperparameter tuning Cleaner visualizations Deployment improvements Documentation enhancements Contribution flow git fork git clone < your-fork > git checkout -b feature/improvement git commit -m " Add improvement " git push origin feature/improvement Then open a pull request. ⭐ Support the Project If this project helped you learn something about TensorFlow, neural networks, or customer churn prediction , consider giving the repository a ⭐ on GitHub. 👨💻 Author Maganpreet Singh GitHub: @Maganpreet-Singh 🚀 Keep Learning. Keep Building. Keep Shipping. Made with 🧠 + Python + TensorFlow
A hands-on deep learning project for predicting customer churn using TensorFlow/Keras , with a complete workflow covering data preprocessing, exploratory data analysis, feature engineering, neural-network modeling, evaluation, and visualization.
Customer churn is one of the most important business problems in subscription-based industries. The goal of this project is to build a neural-network model that learns patterns in historical customer data and predicts whether a customer is likely to leave a service.
This repository is designed as both a practical machine-learning project and a deep-learning learning exercise . It focuses on understanding the end-to-end pipeline rather than treating the model as a black box.
Build a binary classification model that predicts whether a customer will churn based on demographic, account, and banking-related features.
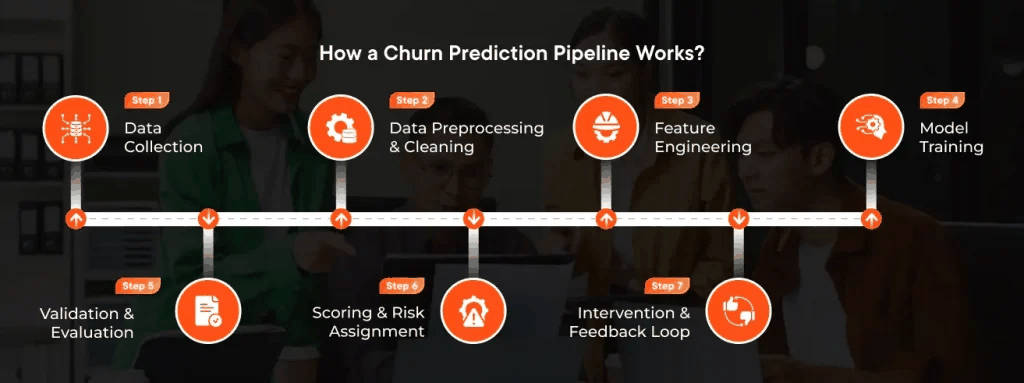
Raw Customer Data ↓ Data Loading ↓ Exploratory Data Analysis ↓ Data Cleaning & Preprocessing ↓ Encoding Categorical Features ↓ Feature Scaling ↓ Train / Test Split ↓ Neural Network Design ↓ Model Training ↓ Validation & Evaluation ↓ Visualization ↓ Churn Prediction
customer-churn-deep-learning/ │ ├── 📄 Churn_Modelling.csv # Customer churn dataset ├── 📓 Model.ipynb # Complete analysis and deep learning workflow └── 📘 README.md # Project documentation
The repository currently contains the original customer churn dataset , the main Jupyter notebook , and this project documentation. fileciteturn1file0L2-L2
The project uses the Churn_Modelling.csv dataset stored directly in the repository. The dataset contains customer-level information commonly used for churn classification, including a mixture of numerical, categorical, demographic, and account-related attributes.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Note: The notebook is the source of truth for the exact preprocessing steps, selected features, model architecture, training configuration, and evaluation output.
The workflow prepares the raw data for neural-network training by handling categorical data, selecting useful features, and transforming the input matrix into a model-ready numerical representation.
Numerical inputs are normalized/scaled so that features with very different ranges do not dominate the training process.
The prepared data is divided into training and testing subsets so the model can be trained on one portion and evaluated on unseen samples.
A feed-forward neural network is trained for binary classification using TensorFlow/Keras.
Input Features ↓ Dense Layer ↓ Activation ↓ Dense Layer ↓ Activation ↓ Output Layer ↓ Churn Probability
The model learns from the training data over multiple epochs while monitoring loss and classification performance.
The notebook evaluates the trained model on unseen data and visualizes training behavior to understand model performance and potential overfitting.
The final model can be used to estimate the probability that an individual customer belongs to the churn class.
The project emphasizes visual understanding of both the data and the model-training process.
These plots help turn model output into something interpretable instead of relying on a single accuracy number.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
git clone https://github.com/Maganpreet-Singh/customer-churn-deep-learning.git cd customer-churn-deep-learning
Execute the cells from top to bottom so that preprocessing, training, evaluation, and visualization happen in the intended order.
Traditional machine-learning algorithms can perform very well on structured tabular data, and they should absolutely be considered during a serious modeling process. This project uses an artificial neural network primarily to build practical understanding of deep learning for binary classification.
For a churn classification problem, accuracy alone is not enough. A stronger evaluation strategy can include:
The exact metrics and values should be taken from the executed notebook rather than hard-coded here, so the README stays aligned with the current experiment.
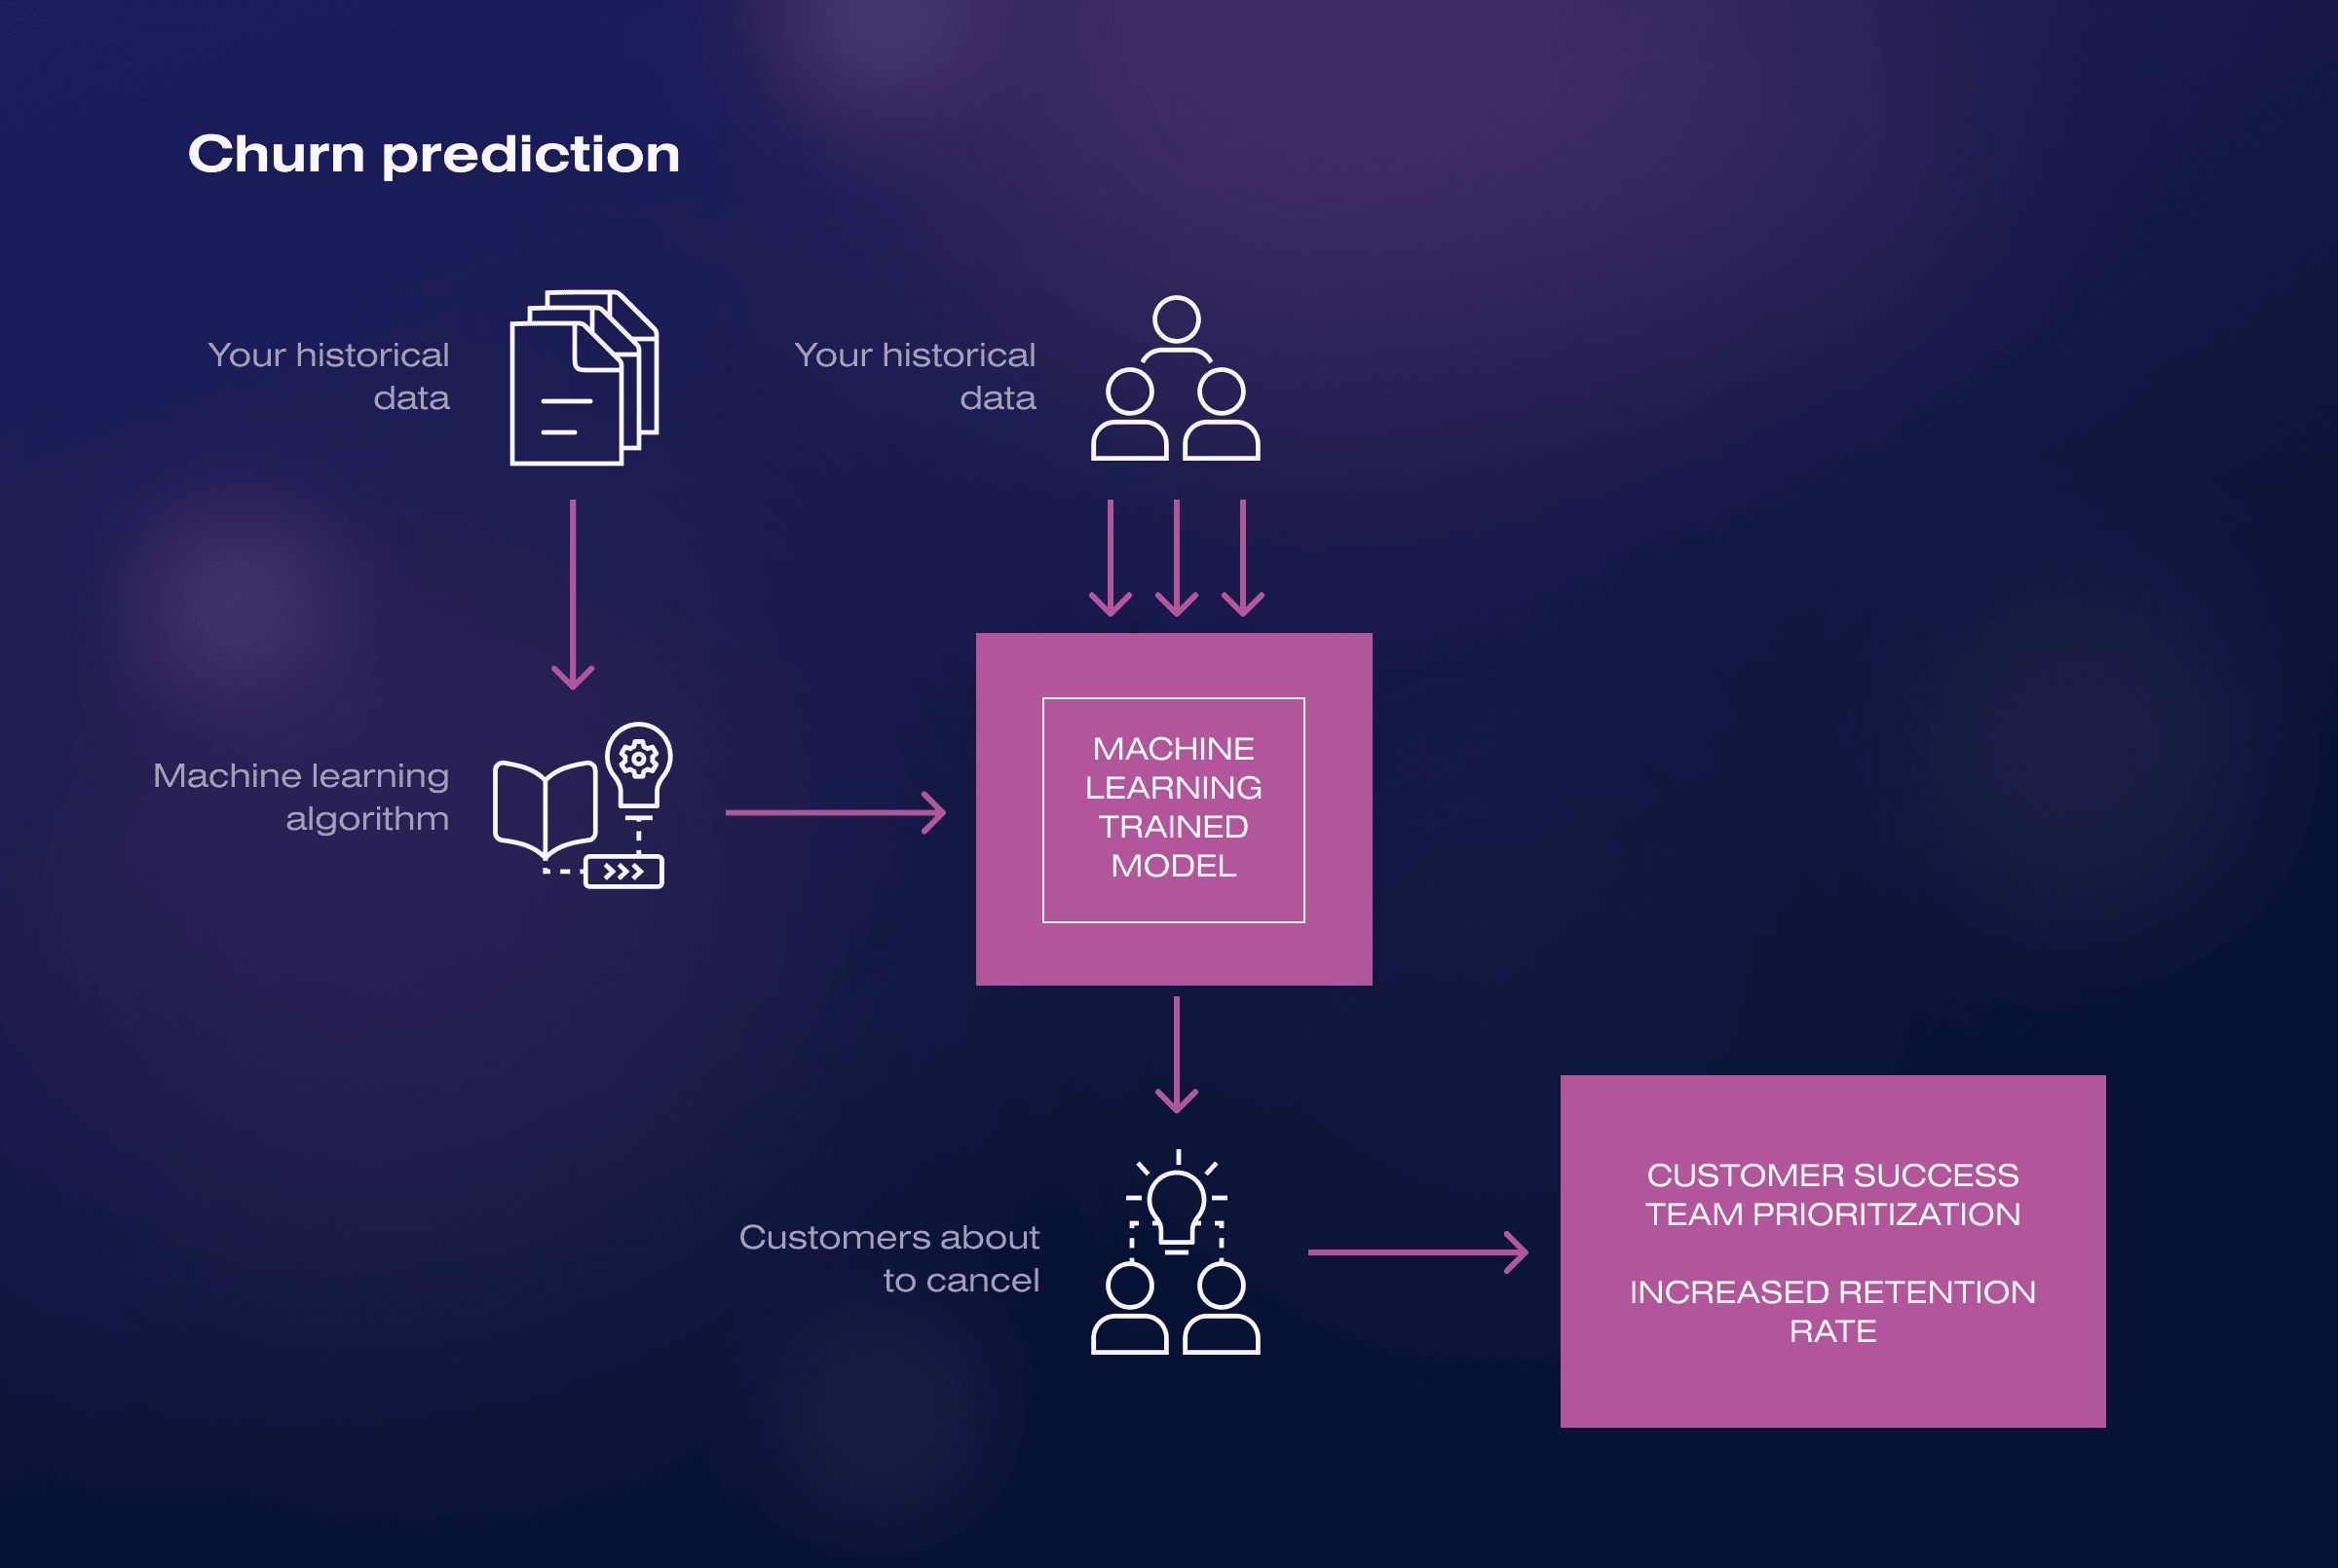
A deployed version of this project could accept customer information and return a churn probability:
Customer Data ↓ Preprocessing Pipeline ↓ Trained Neural Network ↓ Probability of Churn ↓ Business Retention Decision
A production system could then use this probability to prioritize retention campaigns, identify high-risk customer segments, and support customer-success teams.
git fork git clone < your-fork > git checkout -b feature/improvement git commit -m " Add improvement " git push origin feature/improvement
If this project helped you learn something about TensorFlow, neural networks, or customer churn prediction , consider giving the repository a ⭐ on GitHub.
Customer Churn Prediction using TensorFlow and Deep Learning with data preprocessing, exploratory data analysis, feature engineering, model training, evaluation, and visualization.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)