Complete Technical Paper Content — Code Completion Ai
1. Executive Abstract, Problem Formulation & Background
Code completion is an autocompletion feature in many integrated development environments (IDEs) that speeds up the process of coding applications by fixing common mistakes and suggesting lines of code. This usually happens through popups while typing, querying parameters of functions, and query hints related to syntax errors. Code completion and related tools serve as documentation and disambiguation for variable names, functions, and methods, using static analysis. The feature appears in many programming environments. Implementations include IntelliSense in Visual Studio and Visual Studio Code. The term was originally popularized as "picklist" and some implementations still refer to it as such.
IntelliSense is Microsoft's implementation of code completion, best known in Visual Studio. It was first introduced as a feature of a mainstream Microsoft product in 1996 building on many already invented concepts of code completion and syntax checking, with the Visual Basic 5.0 Control Creation Edition, which was essentially a publicly available prototype for Visual Basic 5.0. Initially, Visual Basic IDE was the primary "test bed" for the technology, but IntelliSense was incorporated into Visual FoxPro and Visual C++ in the Visual Studio 97 timeframe (one revision after first seen in Visual Basic). Because it was based on the introspection capabilities of COM, the Visual Basic versions of IntelliSense were always more robust and complete than the 5.0 and 6.0 (97 and 98 in the Visual Studio naming sequence) versions of Visual C++, which did not have the benefit of being entirely based on COM. These shortcomings, such as a lack of template support, criticized by many VC++ developers, have been largely corrected in the .NET product lines. IntelliSense entered a new phase of development with the unified Visual Studio.NET environment first released in 2001, augmented by the more powerful introspection and code documentation capabilities provided by the .NET framework. IntelliSense is now supported by the Visual Studio editors for C++, C#, J#, Visual Basic, XML, HTML and XSLT among others. As of Visual Studio 2005, IntelliSense is activated by default when the user begins to type, instead of requiring marker characters (though this behavior can be turned off). The IDE has the capability of inferring a greater amount of context based on what the developer is typing, to the point that basic language constructs such as for and while are also included in the choice list. In 2017 Microsoft announced IntelliCode, which uses machine learning to infer exactly which language or library feature is likely to be intended at every keystroke. Initially available as an extension for C# only, it is expected to be built in to future releases of Visual Studio. Visual Studio 2022 includes artificial-intelligence features, such as GitHub Copilot, which can automatically suggest entire lines of code based on surrounding context. Other Microsoft products that incorporate IntelliSense include Expression Web, FrontPage 2003, Small Basic, the Visual Basic for Applications IDEs in the Microsoft Office products, Visual Studio Code and many others. SQL Server 2008 Management Studio has autocomplete for the SQL syntax.
as soon as the user types the period after foo, IntelliSense automatically lists all the available member functions (i.e. bar() and foo_bar()) and all the available member attributes (private and protected members can be identified by a padlock picture beside their names). The user can then select one by using the arrow keys and hitting a completion character when the correct member function is highlighted. When available, IntelliSense displays a short description of the member function as given in the source code documentation. IntelliSense goes further by indicating the required parameters in another pop-up window as the user fills in the parameters. As the user types a variable name, the feature also makes suggestions to complete the variable as they are typed. IntelliSense continues to show parameters, highlighting the pertinent one, as the user types. The user can "force" IntelliSense to show its pop-up list without context by using Ctrl+J or Ctrl+Space. In Visual Studio this displays the entire application domain object model available to the developer.
In the field of artificial intelligence (AI), a hallucination or artificial hallucination (also called bullshitting, confabulation, delusion, or mirage) is a response generated by AI that contains false or misleading information presented as fact. These terms draw a loose analogy with human psychology, where a hallucination typically involves false percepts. Chatbots powered by large language models (LLMs), like ChatGPT, may embed plausible-sounding random falsehoods within their generated content, such as fabricated citations. Detecting and mitigating errors and hallucinations pose significant challenges for practical deployment and reliability of LLMs in high-stakes scenarios, such as chip design, supply chain logistics, and medical diagnostics. Some software engineers and statisticians have criticized the specific term "AI hallucination" for unreasonably anthropomorphizing computers. Symbolic artificial intelligence models generally do not produce hallucinations, unlike large language models.
Uses, definitions and characterizations of the term hallucination in the context of LLMs include:
"a tendency to invent facts in moments of uncertainty" (OpenAI, May 2023) "a model's logical mistakes" (OpenAI, May 2023) "fabricating information entirely, but behaving as if spouting facts" (CNBC, May 2023) "making up information" (The Verge, February 2023) "misleading and/or nonsensical factual errors" (Algorithm Watch and AI Forensics, December 2023) "probability distributions" (in scientific contexts) In July 2024, a White House report on fostering public trust in AI research mentioned hallucinations only in the context of reducing them. Notably, when acknowledging David Baker's Nobel Prize-winning work with AI-generated proteins, the Nobel committee avoided it entirely, instead referring to "imaginative protein creation". Hicks, Humphries, and Slater, in their article in Ethics and Information Technology, argue that the output of LLMs is bullshit under Harry Frankfurt's definition, and that the models are "in an important way indifferent to the truth of their outputs", with true statements only accidentally true, and false ones accidentally false. Some researchers also call the uncritical use of AI botshit. The term mirage has been proposed as an alternative to the use of hallucination, framing false or misleading responses as predictable results of LLM data processing created by both AI training datasets and the rules engineered into the LLM rather than a mental breaking from reality. This shift in language aims to increase AI literacy by using terminology that avoids anthropomorphic implications that LLMs have conscious minds with their own intent, shows that untrue outputs come from patterns in training data, and indicates that outputs are novel syntheses of training data requiring critical human judgment.
Other examples involve baiting ChatGPT with a false premise to see if it embellishes upon the premise. When asked about "Harold Coward's idea of dynamic canonicity", ChatGPT fabricated that Coward wrote a book titled Dynamic Canonicity: A Model for Biblical and Theological Interpretation, arguing that religious principles are actually in a constant state of change. When pressed, ChatGPT continued to insist that the book was real. Asked for proof that dinosaurs built a civilization, ChatGPT claimed there were fossil remains of dinosaur tools and stated, "Some species of dinosaurs even developed primitive forms of art, such as engravings on stones". When prompted that "Scientists have recently discovered churros, the delicious fried-dough pastries ... (are) ideal tools for home surgery", ChatGPT claimed that a "study published in the journal Science" found that the dough is pliable enough to form into surgical instruments that can get into hard-to-reach places, and that the flavor has a calming effect on patients. By 2023, analysts considered frequent hallucination to be a major problem in LLM technology, with a Google executive identifying hallucination reduction as a "fundamental" task for ChatGPT competitor Google Gemini. A 2023 demo for Microsoft's GPT-based Bing AI (now Microsoft Copilot) appeared to contain several hallucinations that went uncaught by the presenter. In June 2023, Mark Walters, a gun rights activist and radio personality, sued OpenAI in a Georgia state court after ChatGPT mischaracterized a legal complaint in a manner alleged to be defamatory against Walters. The complaint in question was brought in May 2023 by the Second Amendment Foundation against Washington attorney general Robert W. Ferguson for allegedly violating their freedom of speech, whereas the ChatGPT-generated summary bore no resemblance and claimed that Walters was accused of embezzlement and fraud while holding a Second Amendment Foundation office post that he never held in real life. According to AI legal expert Eugene Volokh, OpenAI is likely not shielded against this claim by Section 230, because OpenAI likely "materially contributed" to the creation of the defamatory content. In May 2025, Judge Tracie Cason of Gwinnett County Superior Court ruled in favor of OpenAI, stating that the plaintiff had not shown he was defamed, as Walters failed to show that OpenAI's statements about him were negligent or made with "actual malice". In February 2024, Canadian airline Air Canada was ordered by the Civil Resolution Tribunal in Moffatt v. Air Canada to pay damages to a customer and honor a bereavement fare policy that was hallucinated by a support chatbot, which incorrectly stated that customers could retroactively request a bereavement discount within 90 days of the date the ticket was issued (the actual policy does not allow the fare to be requested after the flight is booked). The Tribunal rejected Air Canada's defense that the chatbot was a "separate legal entity that is responsible for its own actions". In October 2025, several hallucinations, including non-existent academic sources and a fake quote from a federal court judgement were discovered in an A$440,000 report written by Deloitte and submitted to the Australian government in July. The company later submitted a revised report with these errors removed, and will issue a partial refund to the government. The following month, in November 2025, The Independent, a news publication in Newfoundland and Labrador, Canada, discovered that Deloitte's CA$1.6 million Health Human Resources Plan for the Government of Newfoundland and Labrador commissioned in May 2025 contained at least four false citations to non-existent research papers.
2. Related Work, Literature Survey & Algorithmic Foundations
In reality, such textures and outlines would not be represented by single nodes, but rather by associated weight patterns of multiple nodes.
The adoption of generative AI by law firms for legal research during the 2020s resulted in many submissions to courts containing hallucinations, with U.S. judges nationwide sanctioning or reprimanding lawyers. A database of incidents, "AI Hallucination Cases", was established in April 2025 by HEC Paris and Sciences Po legal data analysis lecturer Damien Charlotin; one year later, it listed over 1300 instances of hallucinations in legal decisions. In May 2023, it was discovered that Stephen Schwartz had submitted six fake case precedents generated by ChatGPT in his brief to the Southern District of New York on Mata v. Avianca, Inc., a personal injury case against the airline Avianca. Schwartz said that he had never previously used ChatGPT, that he did not recognize the possibility that ChatGPT's output could have been fabricated, and that ChatGPT continued to assert the authenticity of the precedents after their nonexistence was discovered. In response, Brantley Starr of the Northern District of Texas banned the submission of AI-generated case filings that have not been reviewed by a human, noting that:
Generative AI platforms in their current states are prone to hallucinations and bias. On hallucinations, they make stuff up—even quotes and citations. Another issue is reliability or bias. While attorneys swear an oath to set aside their personal prejudices, biases, and beliefs to faithfully uphold the law and represent their clients, generative artificial intelligence is the product of programming devised by humans who did not have to swear such an oath. As such, these systems hold no allegiance to any client, the rule of law, or the laws and Constitution of the United States (or, as addressed above, the truth). Unbound by any sense of duty, honor, or justice, such programs act according to computer code rather than conviction, based on programming rather than principle. On 23 June 2023, judge P. Kevin Castel dismissed the Mata case and issued a $5,000 fine to Schwartz and another lawyer—who had both continued to stand by the fictitious precedents despite Schwartz's previous claims—for bad faith conduct. Castel characterized numerous errors and inconsistencies in the opinion summaries, describing one of the cited opinions as "gibberish" and "[bordering] on nonsensical". In May 2025, high-profile pro se plaintiff Ashley Gjøvik, who has a Juris Doctor from Santa Clara University School of Law, was admonished in U.S. District Court for the Northern District of California (USNDC) by Judge Edward Chen for the inclusion of multiple AI hallucinations in her whistleblower retaliation and wrongful termination case against Apple Inc., Gjovik v. Apple Inc., warning that future instances would result in Gjøvik being held in contempt of court and her pro se privileges revoked. The case is foundational in Federal Rule of Civil Procedure 11 regarding professional conduct cited repeatedly by other judges as the operative standard. It has also been discussed by the American Bar Association in updating the model professional rules and cited in its opinion regarding the use of generative AI. In September 2025, USNDC Magistrate Judge Peter Kang sanctioned Webb Law attorney Katherine Cervantes for her submission of July 21 that included an AI hallucination which she stated had been obtained from Westlaw AI, the Thomson Reuters' artificial intelligence tool. On April 28, 2026, Judge Kang sanctioned and fined Webb Law Group managing partner Lenden Webb for insufficient supervision of Cervantes—a junior lawyer incorporating AI for the first time—therefore allowing the legal submission that included an AI hallucinated citation of July 21, 2025. On 18 March 2026, Clayton County, Georgia, Assistant District Attorney Deborah Leslie appeared before the Supreme Court of Georgia to deliver oral arguments regarding an order to deny an appeal for a murder conviction, which a Clayton County Superior Court judge used in denying the defendant's motion. During the session, Chief Justice Nels S. D. Peterson noted at least five fictitious citations within the filing, as well as five others that did not support the proposition for which they were cited. On 30 March 2026, Leslie admitted in an affidavit to not verifying AI-generated "expanded legal research" used to prepare the order, which District Attorney Tasha Mosley corroborated in a written apology to Peterson. On 5 May, the Supreme Court vacated the lower court's ruling and ordered for a new order with legitimate citations to be written. Leslie was also suspended from practicing before the Supreme Court for six months and was ordered to take additional education for ethics and proper use of artificial intelligence. In April 2026, Sullivan & Cromwell submitted an apology to the U.S. Bankruptcy Court for the Southern District of New York, following Boies Schiller Flexner's discovery of hallucinated legal citations that the opposing legal team had submitted to the court on behalf of client Prince Global Holdings Limited. On 28 April 2026, U.S. Magistrate Judge Robert T. Numbers formally reprimanded former assistant U.S. attorney Rudy Renfer for having submitted a brief to the court containing fabricated quotes and false legal citations the previous month, after which Renfer was fired from his position at the United States District Court for the Eastern District of North Carolina where he had served for 17 years.
Code Completion with StarCoder A Python implementation of an AI-powered code completion system using the StarCoder base model with LoRA fine-tuning. This project provides a lightweight yet powerful code completion capability that can be trained on custom datasets. Features Fill-in-the-Middle (FIM) Capability : Handles both prefix-suffix code completion and middle-context completion LoRA Fine-tuning : Efficient parameter-efficient fine-tuning using Low-Rank Adaptation Modular Architecture : Clean separation between settings, model components, and training logic Customizable Training : Easily adjust hyperparameters through the settings file Apple Silicon Support : Optimized for running on Apple MPS devices / Note-Since currenlty huggingface does'nt support MLX backend out of the box, hence training runs on mlx backend is slow when compare to cuda device. Requirements Python 3.8+ PyTorch 2.0+ Transformers 4.30+ PEFT (Parameter-Efficient Fine-Tuning) Datasets Accelerate BitsAndBytes (for quantization) 🛠 Installation # Clone the repository git clone https://github.com/deep-learner-ConfigurableAI/code-completion.git cd code-completion # Create a virtual environment python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate # Install dependencies pip install torch transformers datasets accelerate bitsandbytes peft tqdm Project Structure code-completion/ ├── LICENSE ├── README.md ├── src/ │ ├── main.py # Entry point for the application │ ├── settings.py # Configuration settings │ ├── model.py # Core model implementation │ └── runner.py # Training and inference logic Configuration All model and training configurations are centralized in src/settings.py . Key parameters include: Model checkpoint ( MODEL ) Training dataset ( DATASET ) Sequence length ( SEQ_LENGTH ) Training parameters (batch size, learning rate, etc.) LoRA configuration (rank, alpha, target modules) FIM transformation settings Usage Training To train the model on your dataset: Update the settings.py file with your desired configuration Uncomment the train_model() line in main.py Run the following command: cd src python main.py Snapshot of Trainig Run: TrainOutput(global_step=1000, training_loss=0.7857105331420898, metrics={'train_runtime': 626.5932, 'train_samples_per_second': 12.767, 'train_steps_per_second': 1.596, 'train_tokens_per_second': 25841.328, 'total_flos': 9.961198190592e+16, 'train_loss': 0.7857105331420898, 'epoch': 0.8176614881439084}) Inference To use the model for code completion: Ensure you have a trained model or use the provided checkpoint Uncomment the code_completion_demo() line in main.py Run: cd src python main.py Custom Inference You can also use the model programmatically: from model import load_model_tokenizer , get_code_completion from runner import load_model_for_inference # Load model model , tokenizer = load_model_for_inference () # Example code completion prefix = "def calculate_total(items):" suffix = " return total" completed_code = get_code_completion ( model , tokenizer , prefix , suffix ) print ( completed_code ) How It Works Fill-in-the-Middle (FIM) : The model is trained to predict missing code in the middle of two context pieces (prefix and suffix). LoRA Fine-tuning : Instead of fine-tuning all parameters, we use LoRA to efficiently adapt the pre-trained StarCoder model. Dataset Processing : The training process formats the dataset into fixed-length chunks with FIM transformations applied. Constant Length Dataset : For efficient training, we process examples into a constant length format. Performance The model's performance depends on: The quality and size of the training dataset The hyperparameters used (especially LoRA rank and learning rate) The number of training steps Contributing Contributions are welcome! Please feel free to submit a Pull Request. License This project is licensed under the MIT License - see the LICENSE file for details. Acknowledgments BigCode Project for the StarCoder base model Hugging Face for their excellent Transformers library PEFT for the efficient fine-tuning implementation
A Python implementation of an AI-powered code completion system using the StarCoder base model with LoRA fine-tuning. This project provides a lightweight yet powerful code completion capability that can be trained on custom datasets.
# Clone the repository git clone https://github.com/deep-learner-ConfigurableAI/code-completion.git cd code-completion # Create a virtual environment python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate # Install dependencies pip install torch transformers datasets accelerate bitsandbytes peft tqdm
code-completion/ ├── LICENSE ├── README.md ├── src/ │ ├── main.py # Entry point for the application │ ├── settings.py # Configuration settings │ ├── model.py # Core model implementation │ └── runner.py # Training and inference logic
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
All model and training configurations are centralized in src/settings.py . Key parameters include:
Snapshot of Trainig Run: TrainOutput(global_step=1000, training_loss=0.7857105331420898, metrics={'train_runtime': 626.5932, 'train_samples_per_second': 12.767, 'train_steps_per_second': 1.596, 'train_tokens_per_second': 25841.328, 'total_flos': 9.961198190592e+16, 'train_loss': 0.7857105331420898, 'epoch': 0.8176614881439084})
from model import load_model_tokenizer , get_code_completion from runner import load_model_for_inference # Load model model , tokenizer = load_model_for_inference () # Example code completion prefix = "def calculate_total(items):" suffix = " return total" completed_code = get_code_completion ( model , tokenizer , prefix , suffix ) print ( completed_code )
Fill-in-the-Middle (FIM) : The model is trained to predict missing code in the middle of two context pieces (prefix and suffix).
LoRA Fine-tuning : Instead of fine-tuning all parameters, we use LoRA to efficiently adapt the pre-trained StarCoder model.
Dataset Processing : The training process formats the dataset into fixed-length chunks with FIM transformations applied.
Constant Length Dataset : For efficient training, we process examples into a constant length format.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
AI-powered Code Autocompletion This project demonstrates the implementation of an AI-powered code autocompletion model using the Salesforce CodeGen model with parameter-efficient fine-tuning techniques. Project Overview Code autocompletion tools have revolutionized software development by predicting and suggesting code as developers type. The growing insurgence of GitHub Copilot and Cursor Tab, a code autocomplete project was simply a must-try for me. This project aims to fine-tune a pre-trained Large Language Model (LLM) to complete Python code snippets based on function signatures, docstrings and the function itself. The model is trained on Python functions from the Code_Search_Net dataset. Features Uses the Salesforce/codegen-350M-mono model as a base model (from huggingface ) Implements Parameter-Efficient Fine-Tuning (PEFT) with Low-Rank Adaptation (LoRA) to reduce trainable parameters Training and evaluation pipeline for code completion Demo App Demo App Technical Implementation The project includes: Data preparation from the Code_Search_Net dataset Tokenization optimized for code Parameter-Efficient Fine-Tuning with LoRA Training and evaluation pipeline Example generation and testing Getting Started Prerequisites Python 3.8+ PyTorch Transformers Datasets PEFT library All project libraries and package requirements are listed in the requirements.txt file. To install the requirements, check below "Install dependencies". Running the Project Clone the repository: git clone https://github.com/yourusername/ai-code-autocompletion.git cd ai-code-autocompletion Install dependencies: pip install -r requirements.txt or in conda environments (recommended): conda install -r requirements.txt Open and run the Jupyter notebook: jupyter notebook notebooks/ai_code_autocompletion.ipynb Follow the steps in the notebook to train and evaluate the model. To train the model locally: # Set environment variables export MODEL_PATH= " models/newly-trained model " # The trained model will be saved to this path export WANDB_API_KEY= " your-wandb-api-key " # Optional for metrics tracking # Run the training script python src/training/train.py \ --model_name= " Salesforce/codegen-350M-mono " \ --output_dir= $MODEL_PATH \ --num_epochs=3 \ --batch_size=8 \ --learning_rate=5e-4 Also it is possible to train the model on Google Colab by simply uploading the notebooks/Model_training.ipynb notebook to Google Colab and hitting Run. Usage Example After training, you can use the model to complete code snippets: # Example code completion function_prefix = "def process_image(image_path): \n # Load and preprocess image \n import numpy as np \n img = " completion = generate_completion ( model , tokenizer , function_prefix ) print ( f"Completion: { completion } " ) Demo Application A web-based demo application is available to showcase the code completion model's capabilities: Simple web interface built with Streamlit Syntax highlighting for Python code Adjustable parameters (temperature, max tokens) Running the Demo # Make sure to install the required libraries (included in the requirements.txt) pip install streamlit pygments # Run the demo app (from the root directory) streamlit run src/app/demo.py Then open your browser at the URL displayed in the terminal (by default: http://localhost:8501 ) to interact with the demo. Metrics Tracking The Codegen-350M-mono model makes use of Weights & Biases for metrics tracking. (You will need an account to get an API key). Training Metrics Evaluation Metrics GPU Performance Metrics Challenges and Limitations Context Window Limitations: The model can only see a limited amount of context (often just the current function), making it difficult to understand the broader codebase. Computational Efficiency: Code suggestions must appear nearly instantaneously to be useful, requiring more (GPU) power and model optimization for low latency. Conclusion This project demonstrates the feasibility of fine-tuning a code autocompletion model using modern techniques such as PEFT and LoRA. The Salesforce CodeGen model shows promising results for not only Python code completion tasks and can easily be extended and trained with other programming languages. Remarks The ai_code_completions.ipynb notebook in notebooks/ was my original submission for my end semester project for the Deep Learning and AI course I took (Winter 2025). I decided to expand the idea into this fully-flegded project you see now using industry best practices for model development and test. This is the first of its kind for me. If you're reading this, it really means a lot to me.
This project demonstrates the implementation of an AI-powered code autocompletion model using the Salesforce CodeGen model with parameter-efficient fine-tuning techniques.
Code autocompletion tools have revolutionized software development by predicting and suggesting code as developers type. The growing insurgence of GitHub Copilot and Cursor Tab, a code autocomplete project was simply a must-try for me. This project aims to fine-tune a pre-trained Large Language Model (LLM) to complete Python code snippets based on function signatures, docstrings and the function itself. The model is trained on Python functions from the Code_Search_Net dataset.
All project libraries and package requirements are listed in the requirements.txt file. To install the requirements, check below "Install dependencies".
git clone https://github.com/yourusername/ai-code-autocompletion.git cd ai-code-autocompletion
# Set environment variables export MODEL_PATH= " models/newly-trained model " # The trained model will be saved to this path export WANDB_API_KEY= " your-wandb-api-key " # Optional for metrics tracking # Run the training script python src/training/train.py \ --model_name= " Salesforce/codegen-350M-mono " \ --output_dir= $MODEL_PATH \ --num_epochs=3 \ --batch_size=8 \ --learning_rate=5e-4
Also it is possible to train the model on Google Colab by simply uploading the notebooks/Model_training.ipynb notebook to Google Colab and hitting Run.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
# Example code completion function_prefix = "def process_image(image_path): \n # Load and preprocess image \n import numpy as np \n img = " completion = generate_completion ( model , tokenizer , function_prefix ) print ( f"Completion: { completion } " )
A web-based demo application is available to showcase the code completion model's capabilities:
# Make sure to install the required libraries (included in the requirements.txt) pip install streamlit pygments # Run the demo app (from the root directory) streamlit run src/app/demo.py
Then open your browser at the URL displayed in the terminal (by default: http://localhost:8501 ) to interact with the demo.
The Codegen-350M-mono model makes use of Weights & Biases for metrics tracking. (You will need an account to get an API key).
This project demonstrates the feasibility of fine-tuning a code autocompletion model using modern techniques such as PEFT and LoRA. The Salesforce CodeGen model shows promising results for not only Python code completion tasks and can easily be extended and trained with other programming languages.
The ai_code_completions.ipynb notebook in notebooks/ was my original submission for my end semester project for the Deep Learning and AI course I took (Winter 2025). I decided to expand the idea into this fully-flegded project you see now using industry best practices for model development and test. This is the first of its kind for me. If you're reading this, it really means a lot to me.
Model Figures & Evaluation Curves (4 Images)
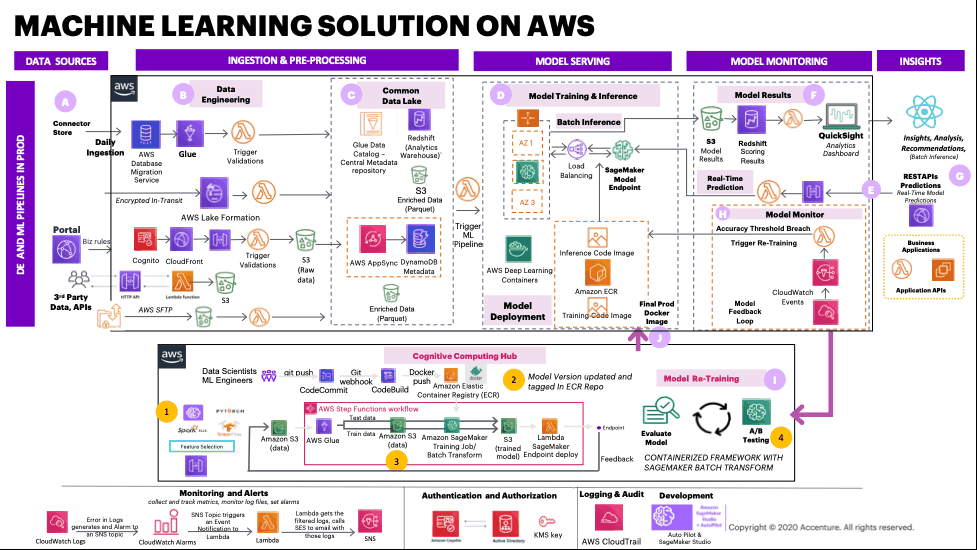
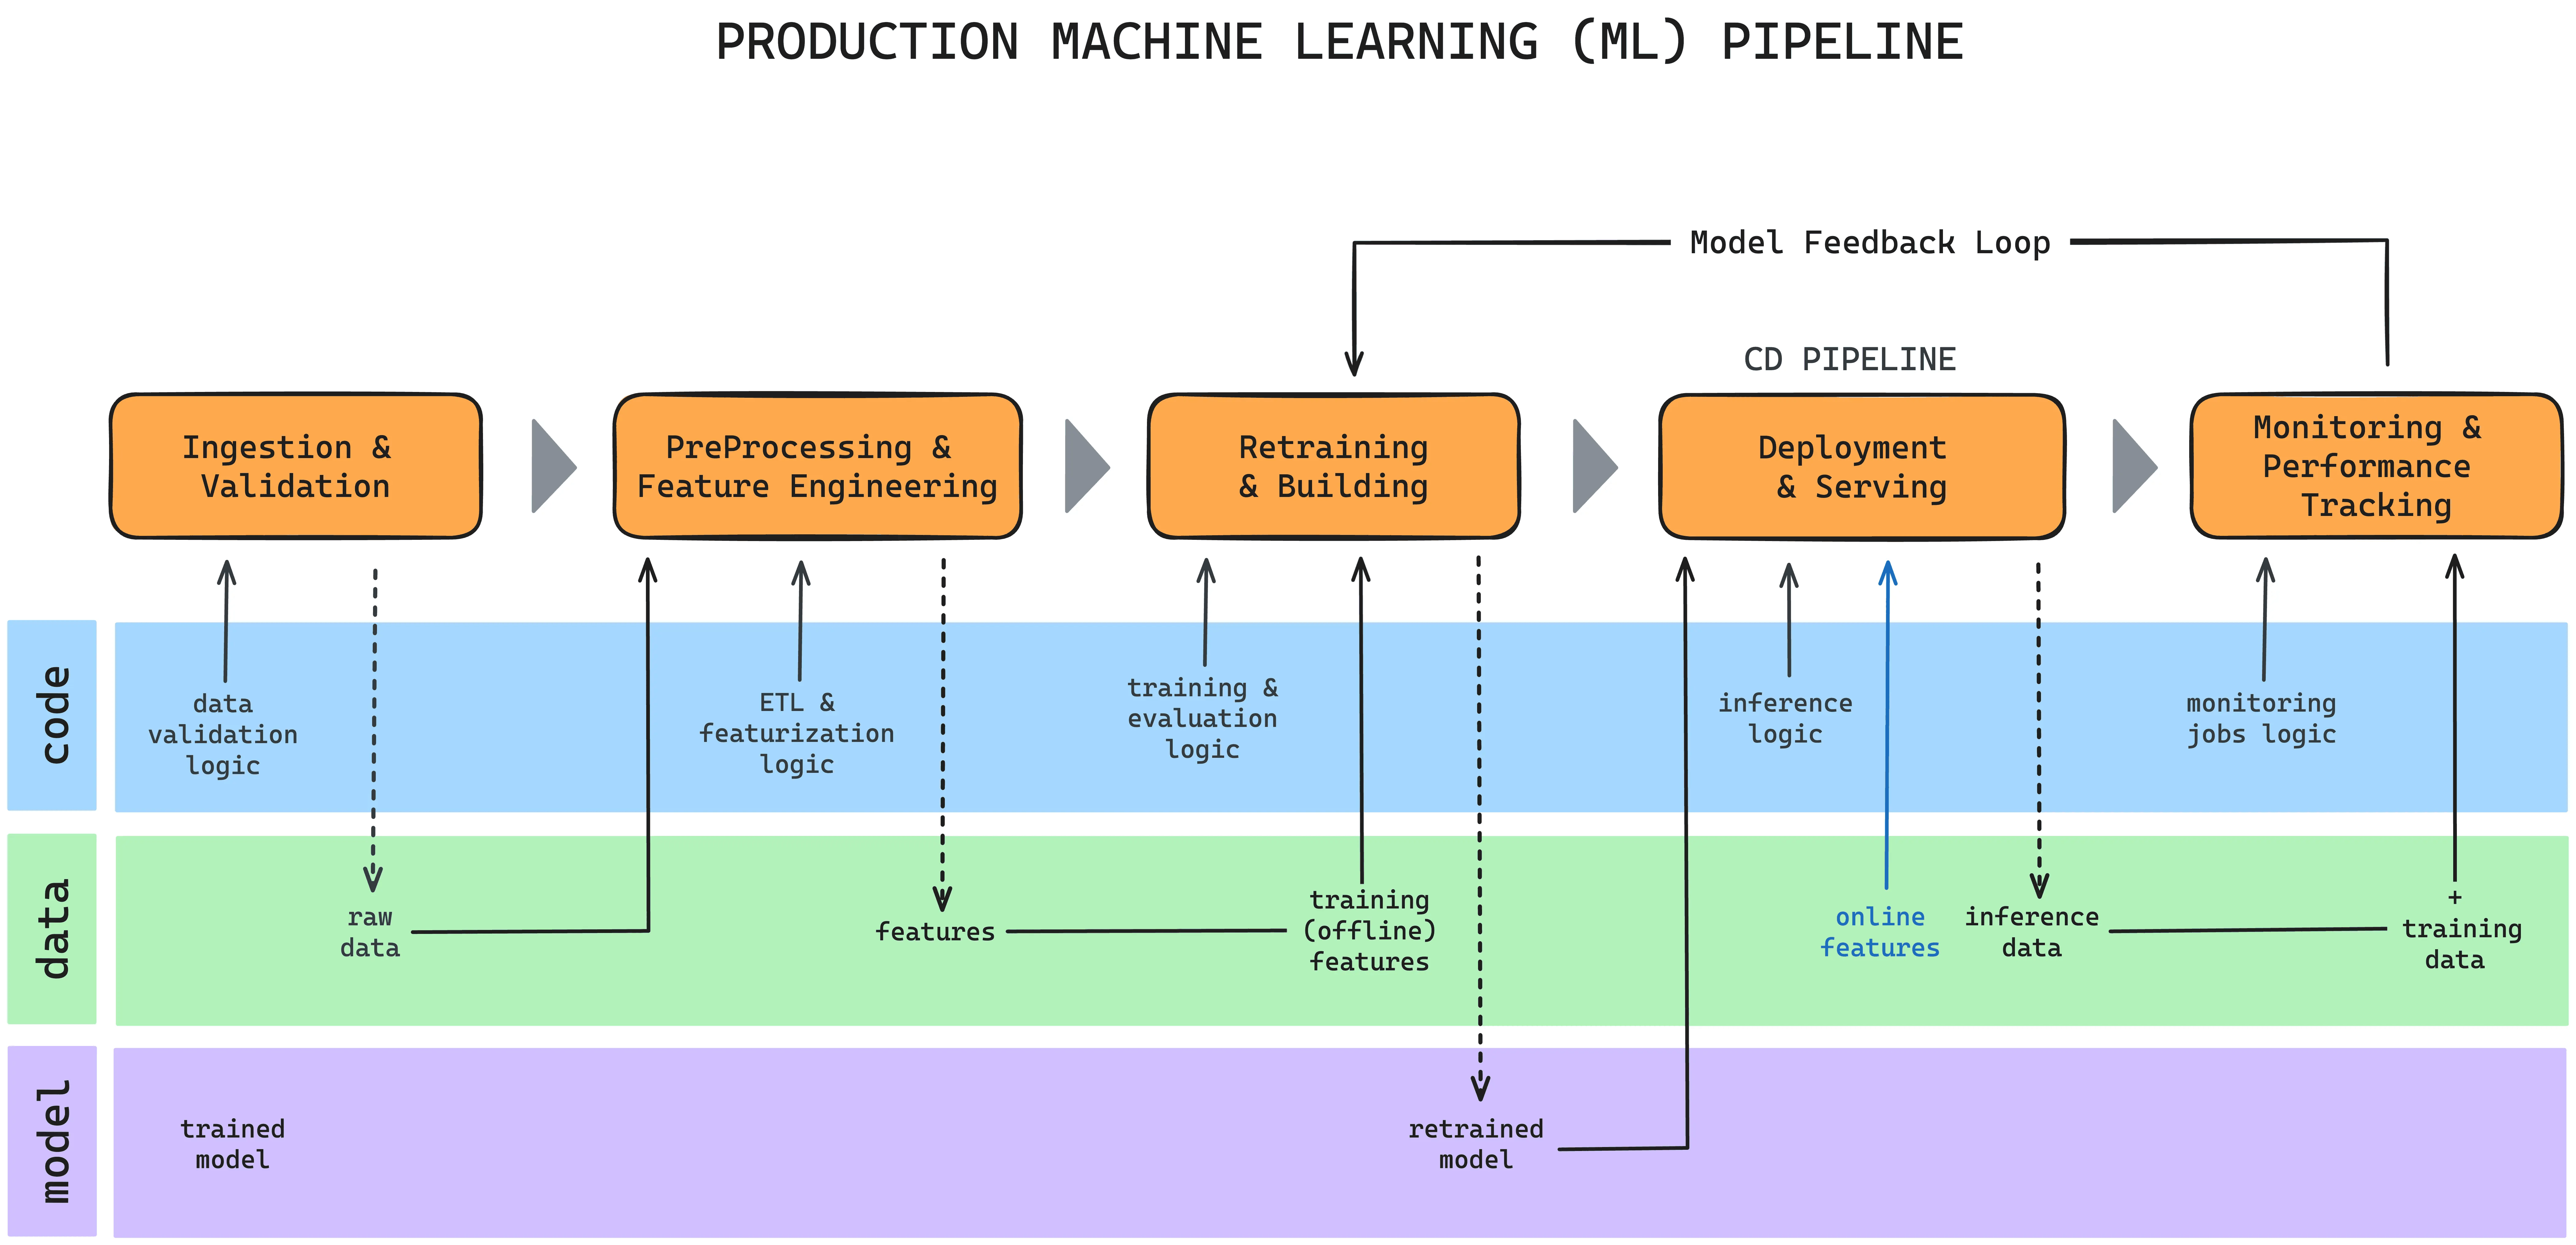
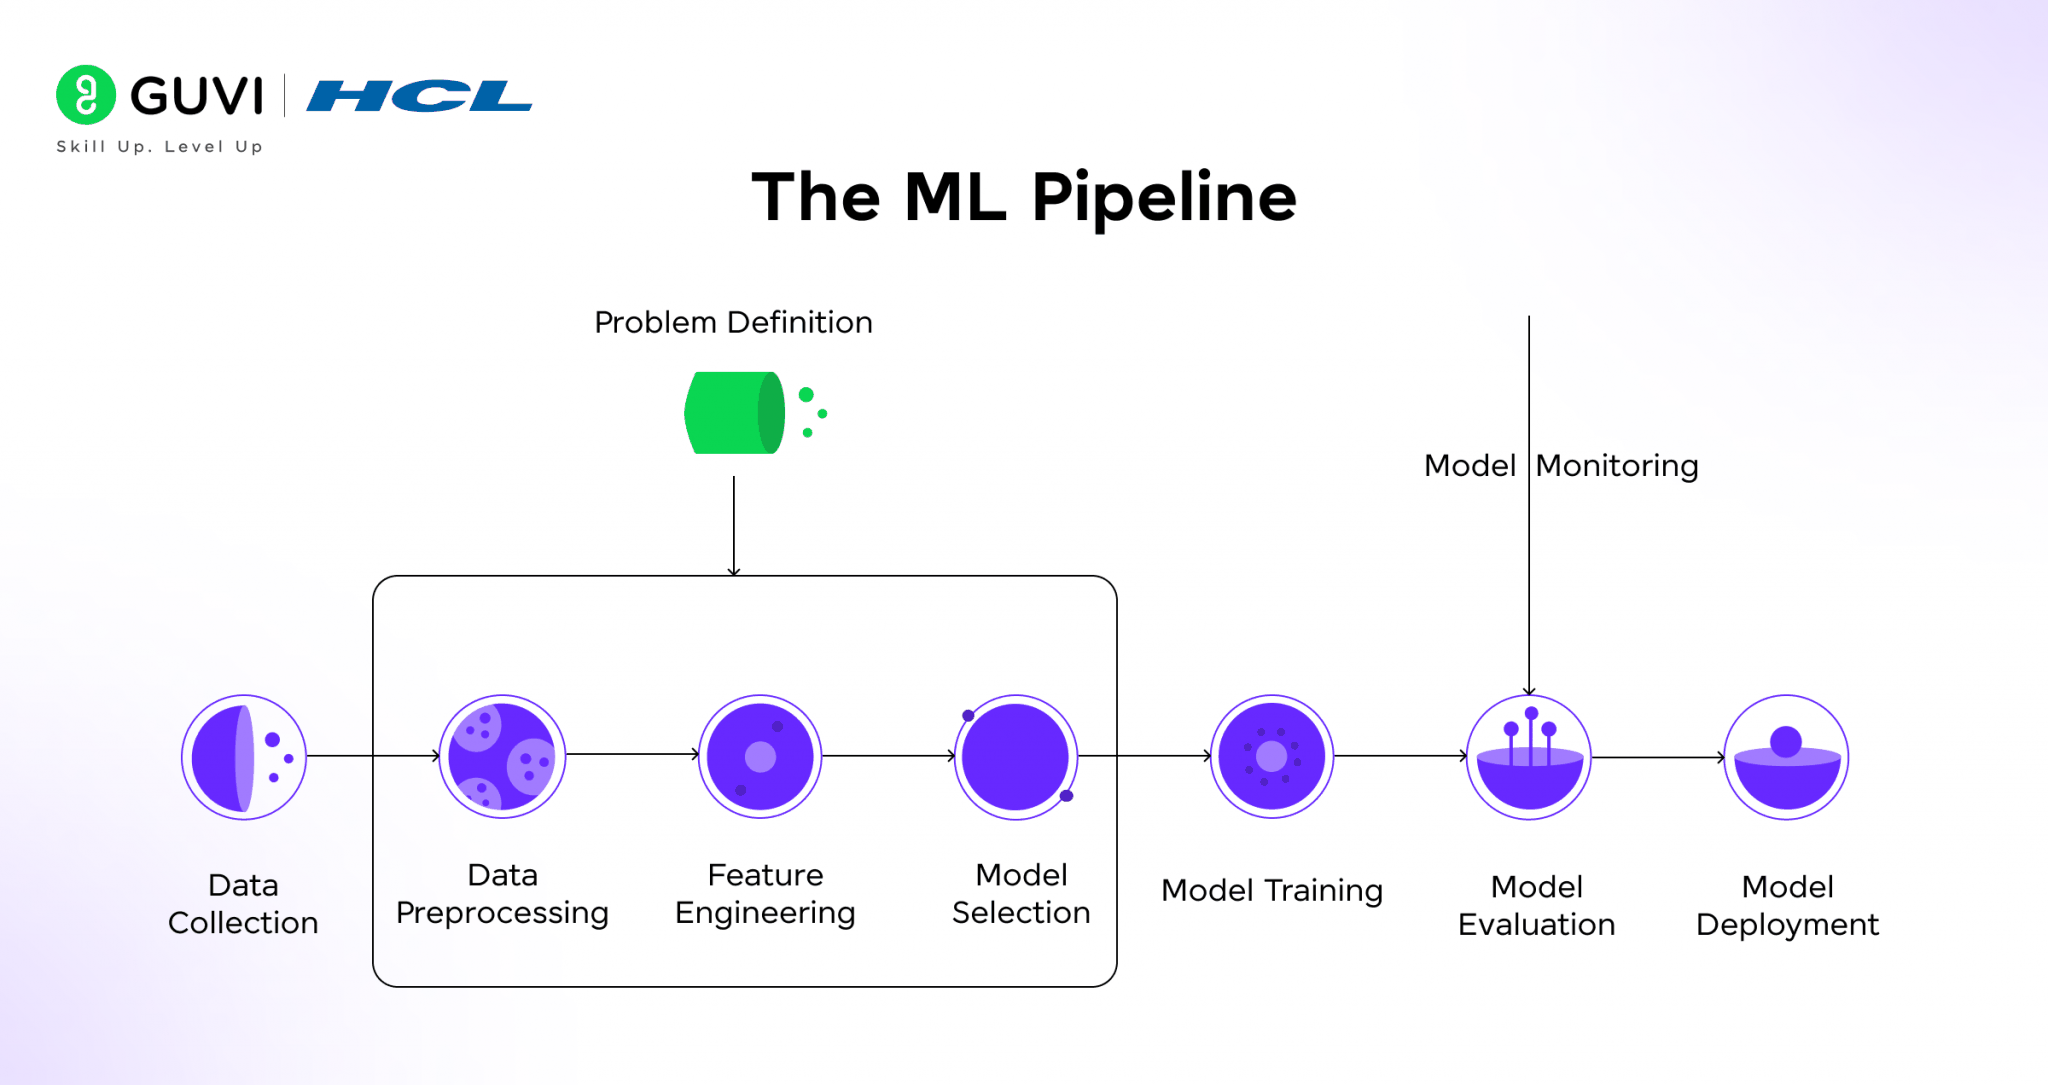
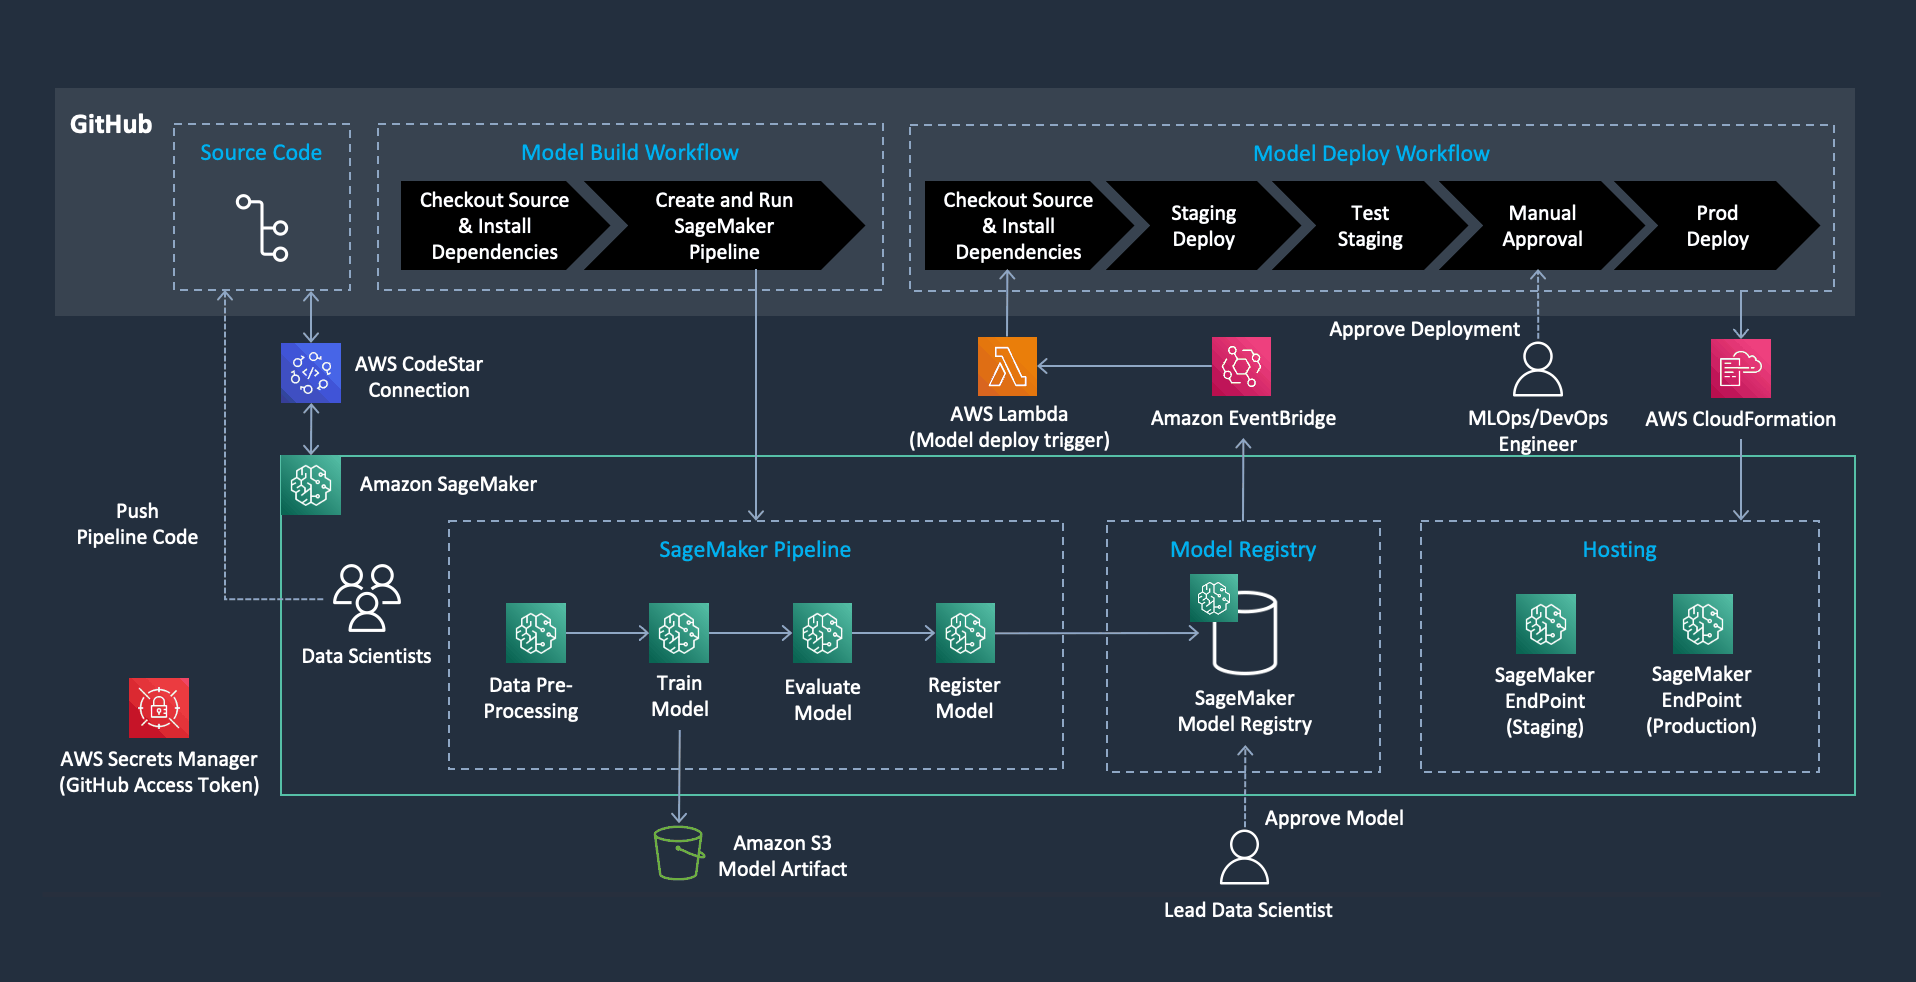
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)