Complete Technical Paper Content — Contract Analysis Nlp
1. Executive Abstract, Problem Formulation & Background
These datasets are used in machine learning (ML) research and have been cited in peer-reviewed academic journals. Datasets are an integral part of the field of machine learning. Major advances in this field can result from advances in learning algorithms (such as deep learning), computer hardware, and, less intuitively, the availability of high-quality training datasets. High-quality labeled training datasets for supervised and semi-supervised machine-learning algorithms are usually difficult and expensive to produce because of the large amount of time needed to label the data. Although they do not need to be labeled, high-quality unlabeled datasets for unsupervised learning can also be difficult and costly to produce. Many organizations, including governments, publish and share their datasets, often using common metadata formats (such as Croissant). The datasets are classified, based on the licenses, into two groups: open data and non-open data. The datasets from various governmental-bodies are presented in List of open government data sites. The datasets are ported on open data portals. They are made available for searching, depositing and accessing through interfaces like Open API. The datasets are made available as various sorted types and subtypes.
The data portal is classified based on its type of license. The open source license based data portals are known as open data portals which are used by many government organizations and academic institutions.
The data portal sometimes lists a wide variety of subtypes of datasets pertaining to many machine learning applications.
The data portals which are suitable for a specific subtype of machine learning application are listed in the subsequent sections.
2. Related Work, Literature Survey & Algorithmic Foundations
**RTP set** – 35,087 stationary-point geometries (reactant, transition state and product) drawn from 11,961 elementary reactions, each labeled with density-functional energies, atomic forces and full Hessian matrices at the ωB97X-D/6-31G(d) level. **IRC set** – 34,248 structures along 600 minimum-energy reaction paths, used to test extrapolation beyond trained stationary points. **NMS set** – 62,527 off-equilibrium geometries generated by normal-mode sampling to probe model robustness under thermal perturbations. The collection underpins the study Does Hessian Data Improve the Performance of Machine Learning Potentials? and was used to train and benchmark the machine-learning interatomic potentials reported therein. The dataset itself is distributed under a CC licence via Figshare.
OpenML: Web platform with Python, R, Java, and other APIs for downloading hundreds of machine learning datasets, evaluating algorithms on datasets, and benchmarking algorithm performance against dozens of other algorithms. PMLB: A large, curated repository of benchmark datasets for evaluating supervised machine learning algorithms. Provides classification and regression datasets in a standardized format that are accessible through a Python API. Metatext NLP: https://metatext.io/datasets web repository maintained by community, containing nearly 1000 benchmark datasets, and counting. Provides many tasks from classification to QA, and various languages from English, Portuguese to Arabic. Appen: Off The Shelf and Open Source Datasets hosted and maintained by the company. These biological, image, physical, question answering, signal, sound, text, and video resources number over 250 and can be applied to over 25 different use cases.
Document AI, also known as Document Intelligence, refers to a field of technology that employs machine learning (ML) techniques, such as natural language processing (NLP). These techniques are used to develop computer models capable of analyzing documents in a manner akin to human review. Through NLP, computer systems are able to understand relationships and contextual nuances in document contents, which facilitates the extraction of information and insights. Additionally, this technology enables the categorization and organization of the documents themselves. The applications of Document AI extend to processing and parsing a variety of semi-structured documents, such as forms, tables, receipts, invoices, tax forms, contracts, loan agreements, and financial reports.
A business letter contains information in for the form of text, as well as other types of information, such as the position of the text. For instance, a typical letter contains two addresses before the body of the text. The address at the very top (sometimes aligned to the right) is the sender address. This is normally followed by the date of the letter, with the place of writing. After this, the receiver address is listed. The distinction between the sender address and the receiver address is conveyed solely by the position of the address on the page, i.e. there is no textual indication like Sender: in front of the addresses.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Contract Analysis System using NLP 🚀 Overview The Contract Analysis System is an AI-powered application that analyzes legal contract text and automatically extracts important information using Natural Language Processing (NLP). The system identifies key entities such as organization names, persons, dates, and monetary values, and also detects important clauses like payment, termination, confidentiality, and governing law. This helps reduce manual effort and improves efficiency in legal document analysis. 🎯 Features 📌 Extract key entities (Organization, Person, Date, Money) 📑 Identify important clauses (Payment, Termination, etc.) 🧠 NLP-based text processing using spaCy 📊 Structured output with tables 🌐 Interactive web interface using Streamlit ⚡ Fast and simple contract analysis 🛠️ Tech Stack Python Streamlit (UI) spaCy (NLP - Named Entity Recognition) Pandas (Data handling) ⚙️ Installation Clone the repository: git clone https://github.com/your-username/contract-analysis-system.git cd contract-analysis-system Install dependencies: pip install -r requirements.txt Install spaCy model: python -m spacy download en_core_web_sm ▶️ Run the Application python -m streamlit run app.py Then open in browser: http://localhost:8501 🔮 Future Enhancements 📄 PDF & image upload (OCR integration) 🤖 Transformer models for better accuracy 📊 Clause confidence scores 📥 Downloadable reports (CSV/PDF) 💬 Chatbot to query contract data
The Contract Analysis System is an AI-powered application that analyzes legal contract text and automatically extracts important information using Natural Language Processing (NLP).
The system identifies key entities such as organization names, persons, dates, and monetary values, and also detects important clauses like payment, termination, confidentiality, and governing law.
🎯 Features 📌 Extract key entities (Organization, Person, Date, Money) 📑 Identify important clauses (Payment, Termination, etc.) 🧠 NLP-based text processing using spaCy 📊 Structured output with tables 🌐 Interactive web interface using Streamlit ⚡ Fast and simple contract analysis
4. Neural Network Backbone, Layer Specifications & Loss Formulations
🛠️ Tech Stack Python Streamlit (UI) spaCy (NLP - Named Entity Recognition) Pandas (Data handling)
⚙️ Installation Clone the repository: git clone https://github.com/your-username/contract-analysis-system.git cd contract-analysis-system Install dependencies: pip install -r requirements.txt Install spaCy model: python -m spacy download en_core_web_sm
🔮 Future Enhancements 📄 PDF & image upload (OCR integration) 🤖 Transformer models for better accuracy 📊 Clause confidence scores 📥 Downloadable reports (CSV/PDF) 💬 Chatbot to query contract data
An interactive NLP-based contract analysis system that extracts entities and classifies clauses from legal documents, improving automation and reducing manual effort.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Contract-Analysis-System NLP based Contract Analysis System using Legal-BERT ⚖️ Contract Analysis System An NLP-powered Contract Analysis System inspired by JPMorgan's legal document processing pipeline . Automatically classifies contract clauses, extracts obligor names and identifies maturity dates using Legal-BERT fine-tuned on LEDGAR dataset . 📸 Screenshots 🖥️ Gradio Web Interface 📊 Sample Output 📌 Table of Contents Overview Features Dataset Model Project Structure Installation How to Run Results Technologies Used Team 📖 Overview JPMorgan developed an NLP pipeline to process legal documents, using OCR for text extraction followed by transformer models to classify clauses like obligor names and maturity dates. This project replicates that system by: Training Legal-BERT on the LEDGAR dataset (60,000+ labeled contract provisions) Implementing NER using SpaCy to extract obligor names and maturity dates Adding OCR support using pytesseract for scanned PDFs and images Deploying an interactive Gradio web demo for real-time contract analysis ✨ Features Feature Description 📌 Clause Classification 60+ clause types — Termination, Payment, Governing Law 👤 Obligor Name Extraction Identifies persons and organizations as obligors 📅 Maturity Date Detection Extracts contract expiry and maturity dates 📁 PDF / Image Upload OCR-based text extraction from scanned contracts 📝 Text Input Paste contract text directly for instant analysis 📊 Document Statistics Word count, sentence count and contract preview 🌐 Gradio Web Demo Interactive web interface for real-time analysis 📦 Dataset LEDGAR Dataset (via LexGLUE Benchmark) Property Details Source SEC filings Size 60,000+ labeled contract provisions Labels 60+ clause types Publisher Stanford Law School from datasets import load_dataset dataset = load_dataset ( "lex_glue" , "ledgar" , trust_remote_code = True ) 🤖 Model Architecture Contract Text (Input) ↓ OCR Extraction (pytesseract) ↓ Tokenization (Legal-BERT) ↓ Fine-tuned Model ↓ ┌─────────────────────────┐ │ │ Clause Named Entity Classification Recognition (60+ types) (SpaCy NER) │ │ Clause Type Obligor Names + Confidence + Maturity Dates └─────────────────────────┘ ↓ Gradio Demo (Output) 📁 Project Structure Contract-Analysis-System/ │ ├── Contract_Analysis_System.ipynb ← Main Colab notebook ├── README.md ← Project documentation ├── requirements.txt ← Dependencies ├── sample_contract.pdf ← Sample contract for testing ├── demo(1).png ← Gradio UI screenshot ├── image(4).png ← Sample output screenshot ⚙️ Installation pip install -r requirements.txt python -m spacy download en_core_web_sm apt-get install tesseract-ocr apt-get install poppler-utils 🚀 How to Run Google Colab (Recommended) Open Contract_Analysis_System.ipynb in Google Colab Go to Runtime → Change runtime type → T4 GPU Run all cells from Cell 1 to Cell 17 Cell 17 launches Gradio demo with public link 📊 Results Metric Score Accuracy ~78% F1 Score (Weighted) ~76% Training Samples 2000 Test Samples 300 🛠️ Technologies Used Technology Purpose Legal-BERT Transformer model for legal text LEDGAR Dataset 60,000+ labeled contract provisions HuggingFace Transformers Model loading and fine-tuning SpaCy Named Entity Recognition pytesseract OCR for PDF/Image extraction Gradio Interactive web demo Google Colab Training with free GPU 📄 License MIT License
An NLP-powered Contract Analysis System inspired by JPMorgan's legal document processing pipeline . Automatically classifies contract clauses, extracts obligor names and identifies maturity dates using Legal-BERT fine-tuned on LEDGAR dataset .
JPMorgan developed an NLP pipeline to process legal documents, using OCR for text extraction followed by transformer models to classify clauses like obligor names and maturity dates. This project replicates that system by:
from datasets import load_dataset dataset = load_dataset ( "lex_glue" , "ledgar" , trust_remote_code = True )
Model Figures & Evaluation Curves (4 Images)
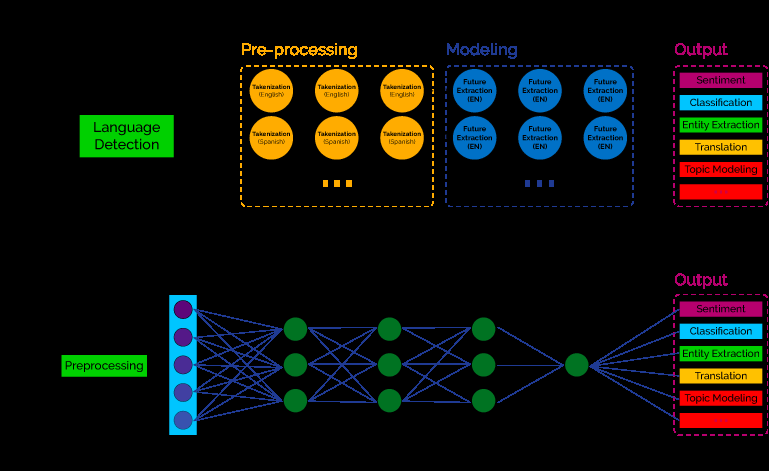
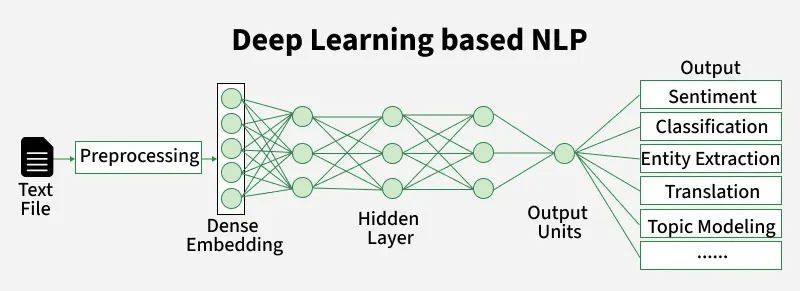
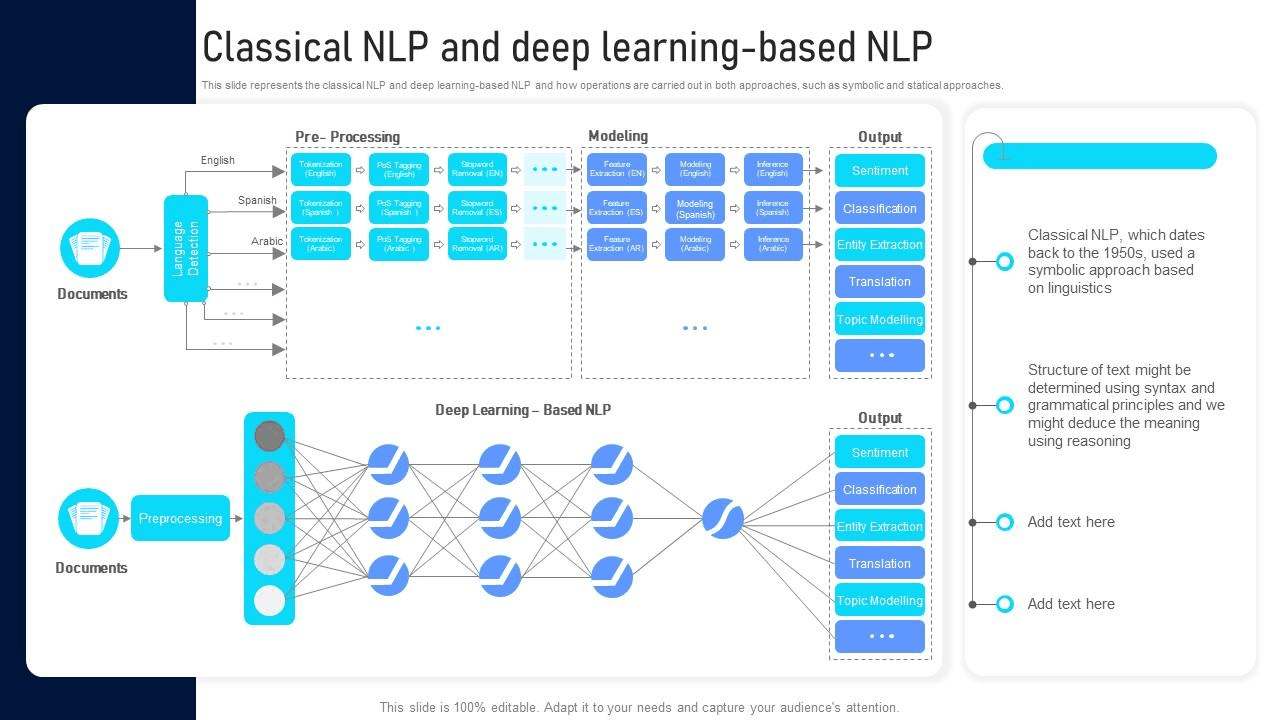
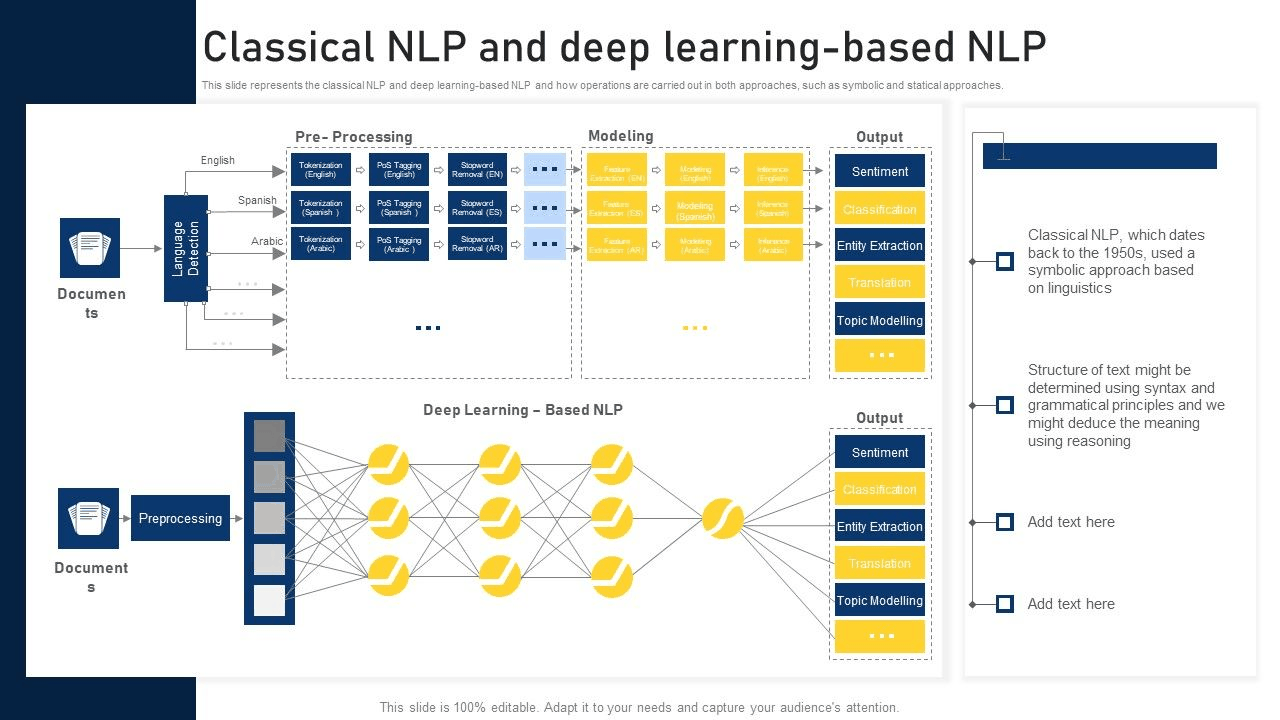
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)