Complete Technical Paper Content — Distilbert Projects
1. Executive Abstract, Problem Formulation & Background
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
2. Related Work, Literature Survey & Algorithmic Foundations
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs .
4. Neural Network Backbone, Layer Specifications & Loss Formulations
TinyBERT: Distilling BERT for Natural Language Understanding Xiaoqi Jiao Thanks: Authors contribute equally. Thanks: This work is done when Xiaoqi Jiao is an intern at Huawei Noah’s Ark Lab. Affiliation: Key Laboratory of Information Storage System, Huazhong University ofScience and Technology, Wuhan National Laboratory for Optoelectronics Yichun Yin Thanks: Corresponding authors. Lifeng Shang Xin Jiang Affiliation: Huawei Noah’s Ark Lab Xiao Chen Affiliation: Huawei Noah’s Ark Lab Linlin Li Affiliation: Huawei Technologies Co., Ltd. {jiaoxiaoqi,wangfang}@hust.edu.cn{yinyichun,shang.lifeng,jiang.xin}@huawei.com{chen.xiao2,lynn.lilinlin,qun.liu}@huawei.com Fang Wang Qun Liu Affiliation: Huawei Noah’s Ark Lab Abstract Language model pre-training, such as BERT, has significantly improved the performances of many natural language processing tasks. However, pre-trained language models are usually computationally expensive, so it is difficult to efficiently execute them on resource-restricted devices. To accelerate inference and reduce model size while maintaining accuracy, we first propose a novel Transformer distillation method that is specially designed for knowledge distillation (KD) of the Transformer-based models. By leveraging this new KD method, the plenty of knowledge encoded in a large “teacher” BERT can be effectively transferred to a small “student” TinyBERT. Then, we introduce a new two-stage learning framework for TinyBERT, which performs Transformer distillation at both the pre-training and task-specific learning stages. This framework ensures that TinyBERT can capture the general-domain as well as the task-specific knowledge in BERT. TinyBERT 4 1 1 1 The code and models are publicly available at https://github.com/huawei-noah/Pretrained-Language-Model/tree/master/TinyBERT with 4 layers is empirically effective and achieves more than 96.8% the performance of its teacher BERT BASE on GLUE benchmark, while being 7.5x smaller and 9.4x faster on inference. TinyBERT 4 is also significantly better than 4-layer state-of-the-art baselines on BERT distillation, with only ∼ \sim 28% parameters and ∼ \sim 31% inference time of them. Moreover, TinyBERT 6 with 6 layers performs on-par with its teacher BERT BASE . 1 Introduction Pre-training language models then fine-tuning on downstream tasks has become a new paradigm for natural language processing (NLP). Pre-trained language models (PLMs), such as BERT Devlin et al. 2019 , XLNet Yang et al. 2019 , RoBERTa Liu et al. 2019 , ALBERT Lan et al. 2020 , T5 Raffel et al. 2019 and ELECTRA Clark et al. 2020 , have achieved great success in many NLP tasks (e.g., the GLUE benchmark Wang et al. 2018 and the challenging multi-hop reasoning task Ding et al. 2019 ). However, PLMs usually have a large number of parameters and take long inference time, which are difficult to be deployed on edge devices such as mobile phones. Recent studies Kovaleva et al. 2019 ; Michel et al. 2019 ; Voita et al. 2019 demonstrate that there is redundancy in PLMs. Therefore, it is crucial and feasible to reduce the computational overhead and model storage of PLMs while retaining their performances. There have been many model compression techniques Han et al. 2016 proposed to accelerate deep model inference and reduce model size while maintaining accuracy. The most commonly used techniques include quantization Gong et al. 2014 , weights pruning Han et al. 2015 , and knowledge distillation (KD) Romero et al. 2014 . In this paper, we focus on knowledge distillation, an idea originated from Hinton et al. 2015 , in a teacher-student framework. KD aims to transfer the knowledge embedded in a large teacher network to a small student network where the student network is trained to reproduce the behaviors of the teacher network. Based on the framework, we propose a novel distillation method specifically for the Transformer-based models Vaswani et al. 2017 , and use BERT as an example to investigate the method for large-scale PLMs. KD has been extensively studied in NLP Kim and Rush 2016 ; Hu et al. 2018 as well as for pre-trained language models Sanh et al. 2019 ; Sun et al. 2019 ; Sun et al. 2020 ; Wang et al. 2020 . The pre-training-then-fine-tuning paradigm firstly pre-trains BERT on a large-scale unsupervised text corpus, then fine-tunes it on task-specific dataset, which greatly increases the difficulty of BERT distillation. Therefore, it is required to design an effective KD strategy for both training stages. To build a competitive TinyBERT, we firstly propose a new Transformer distillation method to distill the knowledge embedded in teacher BERT. Specifically, we design three types of loss functions to fit different representations from BERT layers: 1) the output of the embedding layer; 2) the hidden states and attention matrices derived from the Transformer layer; 3) the logits output by the prediction layer. The attention based fitting is inspired by the recent findings Clark et al. 2019 that the attention weights learned by BERT can capture substantial linguistic knowledge, and it thus encourages the linguistic knowledge can be well transferred from teacher BERT to student TinyBERT. Then, we propose a novel two-stage learning framework including the general distillation and the task-specific distillation , as illustrated in Figure 1 . At general distillation stage, the original BERT without fine-tuning acts as the teacher model. The student TinyBERT mimics the teacher’s behavior through the proposed Transformer distillation on general-domain corpus. After that, we obtain a general TinyBERT that is used as the initialization of student model for the further distillation. At the task-specific distillation stage, we first do the data augmentation, then perform the distillation on the augmented dataset using the fine-tuned BERT as the teacher model. It should be pointed out that both the two stages are essential to improve the performance and generalization capability of TinyBERT. Figure 1: The illustration of TinyBERT learning. The main contributions of this work are as follows: 1) We propose a new Transformer distillation method to encourage that the linguistic knowledge encoded in teacher BERT can be adequately transferred to TinyBERT; 2) We propose a novel two-stage learning framework with performing the proposed Transformer distillation at both the pre-training and fine-tuning stages, which ensures that TinyBERT can absorb both the general-domain and task-specific knowledge of the teacher BERT. 3) We show in the experiments that our TinyBERT 4 can achieve more than 96.8% the performance of teacher BERT BASE on GLUE tasks, while having much fewer parameters ( ∼ \sim 13.3%) and less inference time ( ∼ \sim 10.6%), and significantly outperforms other state-of-the-art baselines with 4 layers on BERT distillation; 4) We also show that a 6-layer TinyBERT 6 can perform on-par with the teacher BERT BASE on GLUE. 2 Preliminaries In this section, we describe the formulation of Transformer Vaswani et al. 2017 and Knowledge Distillation Hinton et al. 2015 . Our proposed Transformer distillation is a specially designed KD method for Transformer-based models. 2.1 Transformer Layer Most of the recent pre-trained language models (e.g., BERT, XLNet and RoBERTa) are built with Transformer layers, which can capture long-term dependencies between input tokens by self-attention mechanism. Specifically, a standard Transformer layer includes two main sub-layers: multi-head attention (MHA) and fully connected feed-forward network (FFN). Multi-Head Attention (MHA) . The calculation of attention function depends on the three components of queries, keys and values, denoted as matrices 𝑸 \bm{Q} , 𝑲 \bm{K} and 𝑽 \bm{V} respectively. The attention function can be formulated as follows: 𝑨 \displaystyle\!\!\bm{A}\! = 𝑸 𝑲 T d k , \displaystyle=\!\frac{\bm{Q}\bm{K}^{T}}{\sqrt{d_{k}}}, (1) Attention ( 𝑸 , 𝑲 , 𝑽 ) \displaystyle\!\!\texttt{Attention}(\bm{Q},\bm{K},\bm{V})\! = softmax ( 𝑨 ) 𝑽 , \displaystyle=\!\texttt{softmax}(\bm{A})\bm{V}, (2) where d k d_{k} is the dimension of keys and acts as a scaling factor, 𝑨 \bm{A} is the attention matrix calculated from the compatibility of 𝑸 \bm{Q} and 𝑲 \bm{K} by dot-product operation. The final function output is calculated as a weighted sum of values 𝑽 \bm{V} , and the weight is computed by applying softmax() operation on the each column of matrix 𝑨 \bm{A} . According to Clark et al. Clark et al. 2019 , the attention matrices in BERT can capture substantial linguistic knowledge, and thus play an essential role in our proposed distillation method. Multi-head attention is defined by concatenating the attention heads from different representation subspaces as follows: MHA ( 𝑸 , 𝑲 , 𝑽 ) \displaystyle\texttt{MHA}(\bm{Q},\bm{K},\bm{V})\! = Concat ( h 1 , … , h k ) 𝑾 , \displaystyle=\!\texttt{Concat}({\rm h}_{1},\ldots,{\rm h}_{k})\bm{W}, (3) where k k is the number of attention heads, and h i {\rm h}_{i} denotes the i i -th attention head, which is calculated by the Attention ( ) \texttt{Attention}() function with inputs from different representation subspaces. The matrix 𝑾 \bm{W} acts as a linear transformation. Position-wise Feed-Forward Network (FFN) . Transformer layer also contains a fully connected feed-forward network, which is formulated as follows: FFN ( x ) = max ( 0 , x 𝑾 1 + b 1 ) 𝑾 2 + b 2 . \displaystyle\texttt{FFN}(x)=\max(0,x\bm{W}_{1}+b_{1})\bm{W}_{2}+b_{2}. (4) We can see that the FFN contains two linear transformations and one ReLU activation. 2.2 Knowledge Distillation KD aims to transfer the knowledge of a large teacher network T T to a small student network S S . The student network is trained to mimic the behaviors of teacher networks. Let f T f^{T} and f S f^{S} represent the behavior functions of teacher and student networks, respectively. The behavior function targets at transforming network inputs to some informative representations, and it can be defined as the output of any layer in the network. In the context of Transformer distillation, the output of MHA layer or FFN layer, or some intermediate representations (such as the attention matrix 𝑨 \bm{A} ) can be used as behavior function. Formally, KD can be modeled as minimizing the following objective function: ℒ KD = ∑ x ∈ 𝒳 L ( f S ( x ) , f T ( x ) ) , \displaystyle\mathcal{L}_{\text{KD}}=\sum_{x\in\mathcal{X}}L\big(f^{S}(x),f^{T}(x)\big), (5) where L ( ⋅ ) L(\cdot) is a loss function that evaluates the difference between teacher and student networks, x x is the text input and 𝒳 \mathcal{X} denotes the training dataset. Thus the key research problem becomes how to define effective behavior functions and loss functions. Different from previous KD methods, we also need to consider how to perform KD at the pre-training stage of BERT in addition to the task-specific training stage. Figure 2: The details of Transformer-layer distillation consisting of Attn loss (attention based distillation) and Hidn loss (hidden states based distillation). 3 Method In this section, we propose a novel distillation method for Transformer-based models, and present a two-stage learning framework for our model distilled from BERT, which is called TinyBERT. 3.1 Transformer Distillation The proposed Transformer distillation is a specially designed KD method for Transformer networks. In this work, both the student and teacher networks are built with Transformer layers. For a clear illustration, we formulate the problem before introducing our method. Problem Formulation . Assuming that the student model has M M Transformer layers and teacher model has N N Transformer layers, we start with choosing M M out of N N layers from the teacher model for the Transformer-layer distillation . Then a function n = g ( m ) n=g(m) is defined as the mapping function between indices from student layers to teacher layers, which means that the m m -th layer of student model learns the information from the g ( m ) g(m) -th layer of teacher model. To be precise, we set 0 to be the index of embedding layer and M + 1 M+1 to be the index of prediction layer, and the corresponding layer mappings are defined as 0 = g ( 0 ) 0=g(0) and N + 1 = g ( M + 1 ) N+1=g(M+1) respectively. The effect of the choice of different mapping functions on the performances is studied in the experiment section. Formally, the student can acquire knowledge from the teacher by minimizing the following objective: ℒ model = ∑ x ∈ 𝒳 ∑ m = 0 M + 1 λ m ℒ layer ( f m S ( x ) , f g ( m ) T ( x ) ) , \displaystyle\!\!\!\mathcal{L}_{\text{model}}\!=\!\sum_{x\in\mathcal{X}}\sum^{M+1}_{m=0}\!\lambda_{m}\mathcal{L}_{\text{layer}}(f^{S}_{m}(x),f^{T}_{g(m)}(x)), (6) where ℒ layer \mathcal{L}_{\text{layer}} refers to the loss function of a given model layer (e.g., Transformer layer or embedding layer), f m ( x ) f_{m}(x) denotes the behavior function induced from the m m -th layers and λ m \lambda_{m} is the hyper-parameter that represents the importance of the m m -th layer’s distillation. Transformer-layer Distillation . The proposed Transformer-layer distillation includes the attention based distillation and hidden states based distillation , which is shown in Figure 2 . The attention based distillation is motivated by the recent findings that attention weights learned by BERT can capture rich linguistic knowledge Clark et al. 2019 . This kind of linguistic knowledge includes the syntax and coreference information, which is essential for natural language understanding. Thus we propose the attention based distillation to encourage that the linguistic knowledge can be transferred from teacher (BERT) to student (TinyBERT). Specifically, the student learns to fit the matrices of multi-head attention in the teacher network, and the objective is defined as: ℒ attn = 1 h ∑ i = 1 h MSE ( 𝑨 i S , 𝑨 i T ) , \displaystyle\mathcal{L}_{\text{attn}}=\frac{1}{h}\sum\nolimits^{h}_{i=1}\texttt{MSE}(\bm{A}_{i}^{S},\bm{A}_{i}^{T}), (7) where h h is the number of attention heads, 𝑨 i ∈ ℝ l × l \bm{A}_{i}\in\mathbb{R}^{l\times l} refers to the attention matrix corresponding to the i i -th head of teacher or student, l l is the input text length, and MSE() means the mean squared error loss function. In this work, the (unnormalized) attention matrix 𝑨 i \bm{A}_{i} is used as the fitting target instead of its softmax output softmax ( 𝑨 i ) \texttt{softmax}(\bm{A}_{i}) , since our experiments show that the former setting has a faster convergence rate and better performances. In addition to the attention based distillation, we also distill the knowledge from the output of Transformer layer, and the objective is as follows: ℒ hidn = MSE ( 𝑯 S 𝑾 h , 𝑯 T ) , \displaystyle\mathcal{L}_{\text{hidn}}=\texttt{MSE}(\bm{H}^{S}\bm{W}_{h},\bm{H}^{T}), (8) where the matrices 𝑯 S ∈ ℝ l × d ′ \bm{H}^{S}\in\mathbb{R}^{l\times d^{\prime}} and 𝑯 T ∈ ℝ l × d \bm{H}^{T}\in\mathbb{R}^{l\times d} refer to the hidden states of student and teacher networks respectively, which are calculated by Equation 4 . The scalar values d d and d ′ d^{\prime} denote the hidden sizes of teacher and student models, and d ′ d^{\prime} is often smaller than d d to obtain a smaller student network. The matrix 𝑾 h ∈ ℝ d ′ × d \bm{W}_{h}\in\mathbb{R}^{d^{\prime}\times d} is a learnable linear transformation, which transforms the hidden states of student network into the same space as the teacher network’s states. Embedding-layer Distillation . Similar to the hidden states based distillation, we also perform embedding-layer distillation and the objective is: ℒ embd = MSE ( 𝑬 S 𝑾 e , 𝑬 T ) , \displaystyle\mathcal{L}_{\text{embd}}=\texttt{MSE}(\bm{E}^{S}\bm{W}_{e},\bm{E}^{T}), (9) where the matrices 𝑬 S \bm{E}^{S} and 𝑯 T \bm{H}^{T} refer to the embeddings of student and teacher networks, respectively. In this paper, they have the same shape as the hidden state matrices. The matrix 𝑾 e \bm{W}_{e} is a linear transformation playing a similar role as 𝑾 h \bm{W}_{h} . Prediction-layer Distillation . In addition to imitating the behaviors of intermediate layers, we also use the knowledge distillation to fit the predictions of teacher model as in Hinton et al. 2015 . Specifically, we penalize the soft cross-entropy loss between the student network’s logits against the teacher’s logits: ℒ pred = CE ( 𝒛 T / t , 𝒛 S / t ) , \displaystyle\mathcal{L}_{\text{pred}}=\texttt{CE}(\bm{z}^{T}/t,\bm{z}^{S}/t), (10) where 𝒛 S {\bm{z}}^{S} and 𝒛 T {\bm{z}}^{T} are the logits vectors predicted by the student and teacher respectively, CE means the cross entropy loss, and t t means the temperature value. In our experiment, we find that t = 1 t=1 performs well. Using the above distillation objectives (i.e. Equations 7 , 8 , 9 and 10 ), we can unify the distillation loss of the corresponding layers between the teacher and the student network: ℒ layer = { ℒ embd , m = 0 ℒ hidn + ℒ attn , M ≥ m > 0 ℒ pred , m = M + 1 \displaystyle\mathcal{L}_{\text{layer}}\!\!=\!\!\begin{cases}\!\mathcal{L}_{\text{embd}},\!\!\!\!\!&m\!=\!0\\ \!\mathcal{L}_{\text{hidn}}\!+\!\mathcal{L}_{\text{attn}},\!\!\!\!\!&M\!\geq\!\!m\!>\!0\\ \!\mathcal{L}_{\text{pred}},\!\!\!\!\!&m\!=\!M+1\end{cases} (11) 3.2 TinyBERT Learning The application of BERT usually consists of two learning stages: the pre-training and fine-tuning. The plenty of knowledge learned by BERT in the pre-training stage is of great importance and should be transferred to the compressed model. Therefore, we propose a novel two-stage learning framework including the general distillation and the task-specific distillation , as illustrated in Figure 1 . General distillation helps TinyBERT learn the rich knowledge embedded in pre-trained BERT, which plays an important role in improving the generalization capability of TinyBERT. The task-specific distillation further teaches TinyBERT the knowledge from the fine-tuned BERT. With the two-step distillation, we can substantially reduce the gap between teacher and student models. General Distillation . We use the original BERT without fine-tuning as the teacher and a large-scale text corpus as the training data. By performing the Transformer distillation 2 2 2 In the general distillation, we do not perform prediction-layer distillation as Equation 10 . Our motivation is to make the TinyBERT primarily learn the intermediate structures of BERT at pre-training stage. From our preliminary experiments, we also found that conducting prediction-layer distillation at pre-training stage does not bring extra improvements on downstream tasks, when the Transformer-layer distillation (Attn and Hidn distillation) and Embedding-layer distillation have already been performed. on the text from general domain, we obtain a general TinyBERT that can be fine-tuned for downstream tasks. However, due to the significant reductions of the hidden/embedding size and the layer number, general TinyBERT performs generally worse than BERT. Task-specific Distillation . Previous studies show that the complex models, such as fine-tuned BERTs, suffer from over-parametrization for domain-specific tasks Kovaleva et al. 2019 . Thus, it is possible for smaller models to achieve comparable performances to the BERTs. To this end, we propose to produce competitive fine-tuned TinyBERTs through the task-specific distillation. In the task-specific distillation, we re-perform the proposed Transformer distillation on an augmented task-specific dataset. Specifically, the fine-tuned BERT is used as the teacher and a data augmentation method is proposed to expand the task-specific training set. Training with more task-related examples, the generalization ability of the student model can be further improved. Algorithm 1 Data Augmentation Procedure for Task-specific Distillation Input : 𝐱 \mathbf{x} is a sequence of words Params : p t p_{t} : the threshold probability N a N_{a} : the number of samples augmented per example K K : the size of candidate set Output : D ′ {D^{\prime}} : the augmented data 1: n ← 0 ; D ′ ← [ ] n\leftarrow 0\ ;\ \ D^{\prime}\leftarrow[\ ] 2: while n < N a n<N_{a} do 3: 𝐱 m ← 𝐱 \mathbf{x}_{m}\leftarrow\mathbf{x} 4: for i ← i\leftarrow 1 to len ( 𝐱 ) (\mathbf{x}) do 5: if 𝐱 [ i ] \mathbf{x}[i] is a single-piece word then 6: Replace 𝐱 m [ i ] \mathbf{x}_{m}[i] with [MASK] 7: C ← K C\leftarrow K most probable words of BERT ( 𝐱 m ) [ i ] \texttt{BERT}(\mathbf{x}_{m})[i] 8: else 9: C ← K C\leftarrow K most similar words of 𝐱 [ i ] \mathbf{x}[i] from GloVe 10: end if 11: Sample p ∼ p\sim Uniform(0, 1) 12: if p ≤ p t p\leq p_{t} then 13: Replace 𝐱 m [ i ] \mathbf{x}_{m}[i] with a word in C C randomly 14: end if 15: end for 16: Append 𝐱 m \mathbf{x}_{m} to D ′ {D^{\prime}} 17: n ← n + 1 n\leftarrow n+1 18: end while 19: return D ′ D^{\prime} Data Augmentation . We combine a pre-trained language model BERT and GloVe Pennington et al. 2014 word embeddings to do word-level replacement for data augmentation. Specifically, we use the language model to predict word replacements for single-piece words Wu et al. 2019 , and use the word embeddings to retrieve the most similar words as word replacements for multiple-pieces words 3 3 3 A word is tokenized into multiple word-pieces by the tokenizer of BERT. . Some hyper-parameters are defined to control the replacement ratio of a sentence and the amount of augmented dataset. More details of the data augmentation procedure are shown in Algorithm 1 . We set p t p_{t} = 0.4, N a N_{a} = 20, K K = 15 for all our experiments. The above two learning stages are complementary to each other: the general distillation provides a good initialization for the task-specific distillation, while the task-specific distillation on the augmented data further improves TinyBERT by focusing on learning the task-specific knowledge. Although there is a significant reduction of model size, with the data augmentation and by performing the proposed Transformer distillation method at both the pre-training and fine-tuning stages, TinyBERT can achieve competitive performances in various NLP tasks. 4 Experiments System #Params #FLOPs Speedup MNLI-(m/mm) QQP QNLI SST-2 CoLA STS-B MRPC RTE Avg BERT BASE (Teacher) 109M 22.5B 1.0x 83.9/83.4 71.1 90.9 93.4 52.8 85.2 87.5 67.0 79.5 BERT TINY 14.5M 1.2B 9.4x 75.4/74.9 66.5 84.8 87.6 19.5 77.1 83.2 62.6 70.2 BERT SMALL 29.2M 3.4B 5.7x 77.6/77.0 68.1 86.4 89.7 27.8 77.0 83.4 61.8 72.1 BERT 4 -PKD 52.2M 7.6B 3.0x 79.9/79.3 70.2 85.1 89.4 24.8 79.8 82.6 62.3 72.6 DistilBERT 4 52.2M 7.6B 3.0x 78.9/78.0 68.5 85.2 91.4 32.8 76.1 82.4 54.1 71.9 MobileBERT TINY † {}_{\rm TINY}\dagger 15.1M 3.1B - 81.5/81.6 68.9 89.5 91.7 46.7 80.1 87.9 65.1 77.0 TinyBERT 4 (ours) 14.5M 1.2B 9.4x 82.5 / 81.8 71.3 87.7 92.6 44.1 80.4 86.4 66.6 77.0 BERT 6 -PKD 67.0M 11.3B 2.0x 81.5/81.0 70.7 89.0 92.0 - - 85.0 65.5 - PD 67.0M 11.3B 2.0x 82.8/82.2 70.4 88.9 91.8 - - 86.8 65.3 - DistilBERT 6 67.0M 11.3B 2.0x 82.6/81.3 70.1 88.9 92.5 49.0 81.3 86.9 58.4 76.8 TinyBERT 6 (ours) 67.0M 11.3B 2.0x 84.6 / 83.2 71.6 90.4 93.1 51.1 83.7 87.3 70.0 79.4 Table 1: Results are evaluated on the test set of GLUE official benchmark. The best results for each group of student models are in-bold. The architecture of TinyBERT 4 and BERT TINY is ( M M =4, d d =312, d i d_{i} =1200), BERT SMALL is ( M M =4, d d =512, d i d_{i} =2048), BERT 4 -PKD and DistilBERT 4 is ( M M =4, d d =768, d i d_{i} =3072) and the architecture of BERT 6 -PKD, DistilBERT 6 and TinyBERT 6 is ( M M =6, d d =768, d i d_{i} =3072). All models are learned in a single-task manner. The inference speedup is evaluated on a single NVIDIA K80 GPU. † \dagger denotes that the comparison between MobileBERT TINY and TinyBERT 4 may not be fair since the former has 24 layers and is task-agnosticly distilled from IB-BERT LARGE while the later is a 4-layers model task-specifically distilled from BERT BASE . In this section, we evaluate the effectiveness and efficiency of TinyBERT on a variety of tasks with different model settings. 4.1 Datasets We evaluate TinyBERT on the General Language Understanding Evaluation (GLUE) Wang et al. 2018 benchmark, which consists of 2 single-sentence tasks: CoLA Warstadt et al. 2019 , SST-2 Socher et al. 2013 , 3 sentence similarity tasks: MRPC Dolan and Brockett 2005 , STS-B Cer et al. 2017 , QQP Chen et al. 2018 , and 4 natural language inference tasks: MNLI Williams et al. 2018 , QNLI Rajpurkar et al. 2016 , RTE Bentivogli et al. 2009 and WNLI Levesque et al. 2012 . The metrics for these tasks can be found in the GLUE paper Wang et al. 2018 . 4.2 TinyBERT Settings We instantiate a tiny student model (the number of layers M M =4, the hidden size d ′ d^{\prime} =312, the feed-forward/filter size d i ′ d^{\prime}_{i} =1200 and the head number h h =12) that has a total of 14.5M parameters. This model is referred to as TinyBERT 4 . The original BERT BASE ( N N =12, d d =768, d i d_{i} =3072 and h h =12) is used as the teacher model that contains 109M parameters. We use g ( m ) = 3 × m g(m)=3\times m as the layer mapping function, so TinyBERT 4 learns from every 3 layers of BERT BASE . The learning weight λ \lambda of each layer is set to 1. Besides, for a direct comparisons with baselines, we also instantiate a TinyBERT 6 ( M M =6, d ′ d^{\prime} =768, d i ′ d^{\prime}_{i} =3072 and h h =12) with the same architecture as BERT 6 -PKD Sun et al. 2019 and DistilBERT 6 Sanh et al. 2019 . TinyBERT learning includes the general distillation and the task-specific distillation. For the general distillation, we set the maximum sequence length to 128 and use English Wikipedia (2,500M words) as the text corpus and perform the intermediate layer distillation for 3 epochs with the supervision from a pre-trained BERT BASE and keep other hyper-parameters the same as BERT pre-training Devlin et al. 2019 . For the task-specific distillation, under the supervision of a fine-tuned BERT, we firstly perform intermediate layer distillation on the augmented data for 20 epochs 4 4 4 For large datasets MNLI, QQP, and QNLI, we only perform 10 epochs of the intermediate layer distillation , and for the challenging task CoLA, we perform 50 epochs at this step. with batch size 32 and learning rate 5e-5, and then perform prediction layer distillation on the augmented data 5 5 5 For regression task STS-B, the original train set is better. for 3 epochs with choosing the batch size from {16, 32} and learning rate from {1e-5, 2e-5, 3e-5} on dev set. At task-specific distillation, the maximum sequence length is set to 64 for single-sentence tasks, and 128 for sequence pair tasks. 4.3 Baselines We compare TinyBERT with BERT TINY , BERT SMALL 6 6 6 https://github.com/google-research/bert Turc et al. 2019 and several state-of-the-art KD baselines including BERT-PKD Sun et al. 2019 , PD Turc et al. 2019 , DistilBERT Sanh et al. 2019 and MobileBERT Sun et al. 2020 . BERT TINY means directly pretraining a small BERT, which has the same model architecture as TinyBERT 4 . When training BERT TINY , we follow the same learning strategy as described in the original BERT Devlin et al. 2019 . To make a fair comparison, we use the released code to train a 4-layer BERT 4 -PKD 7 7 7 https://github.com/intersun/PKD-for-BERT-Model-Compression and a 4-layer DistilBERT 4 8 8 8 https://github.com/huggingface/transformers/tree/master/examples/distillation and fine-tuning these 4-layer baselines with suggested hyper-paramters. For 6-layer baselines, we use the reported numbers or evaluate the results on the test set of GLUE with released models. 4.4 Experimental Results on GLUE We submitted our model predictions to the official GLUE evaluation server to obtain results on the test set 9 9 9 https://gluebenchmark.com , as summarized in Table 1 . The experiment results from the 4-layer student models demonstrate that: 1) There is a large performance gap between BERT TINY (or BERT SMALL ) and BERT BASE due to the dramatic reduction in model size. 2) TinyBERT 4 is consistently better than BERT TINY on all the GLUE tasks and obtains a large improvement of 6.8% on average. This indicates that the proposed KD learning framework can effectively improve the performances of small models on a variety of downstream tasks. 3) TinyBERT 4 significantly outperforms the 4-layer state-of-the-art KD baselines (i.e., BERT 4 -PKD and DistilBERT 4 ) by a margin of at least 4.4%, with ∼ \sim 28% parameters and 3.1x inference speedup. 4) Compared with the teacher BERT BASE , TinyBERT 4 is 7.5x smaller and 9.4x faster in the model efficiency, while maintaining competitive performances. 5) For the challenging CoLA dataset (the task of predicting linguistic acceptability judgments), all the 4-layer distilled models have big performance gaps compared to the teacher model, while TinyBERT 4 achieves a significant improvement over the 4-layer baselines. 6) We also compare TinyBERT with the 24-layer MobileBERT TINY , which is distilled from 24-layer IB-BERT LARGE . The results show that TinyBERT 4 achieves the same average score as the 24-layer model with only 38.7% FLOPs. 7) When we increase the capacity of our model to TinyBERT 6 , its performance can be further elevated and outperforms the baselines of the same architecture by a margin of 2.6% on average and achieves comparable results with the teacher. 8) Compared with the other two-stage baseline PD, which first pre-trains a small BERT, then performs distillation on a specific task with this small model, TinyBERT initialize the student in task-specific stage via general distillation. We analyze these two initialization methods in Appendix C . In addition, BERT-PKD and DistilBERT initialize their student models with some layers of a pre-trained BERT, which makes the student models have to keep the same size settings of Transformer layer (or embedding layer) as their teacher. In our two-stage distillation framework, TinyBERT is initialized through general distillation, making it more flexible in choosing model configuration. More Comparisons. We demonstrate the effectiveness of TinyBERT by including more baselines such as Poor Man’s BERT Sajjad et al. 2020 , BERT-of-Theseus Xu et al. 2020 and MiniLM Wang et al. 2020 , some of which only report results on the GLUE dev set. In addition, we evaluate TinyBERT on SQuAD v1.1 and v2.0. Due to the space limit, we present our results in the Appendix A and B . 4.5 Ablation Studies In this section, we conduct ablation studies to investigate the contributions of : a) different procedures of the proposed two-stage TinyBERT learning framework in Figure 1 , and b) different distillation objectives in Equation 11 . 4.5.1 Effects of Learning Procedure The proposed two-stage TinyBERT learning framework consists of three key procedures: GD (General Distillation), TD (Task-specific Distillation) and DA (Data Augmentation). The performances of removing each individual learning procedure are analyzed and presented in Table 2 . The results indicate that all of the three procedures are crucial for the proposed method. The TD and DA has comparable effects in all the four tasks. We note that the task-specific procedures (TD and DA) are more helpful than the pre-training procedure (GD) on all of the tasks. Another interesting observation is that GD contribute more on CoLA than on MNLI and MRPC. We conjecture that the ability of linguistic generalization Warstadt et al. 2019 learned by GD plays an important role in the task of linguistic acceptability judgments. System MNLI-m MNLI-mm MRPC CoLA Avg TinyBERT 4 82.8 82.9 85.8 50.8 75.6 w/o GD 82.5 82.6 84.1 40.8 72.5 w/o TD 80.6 81.2 83.8 28.5 68.5 w/o DA 80.5 81.0 82.4 29.8 68.4 Table 2: Ablation studies of different procedures (i.e., TD, GD, and DA) of the two-stage learning framework. The variants are validated on the dev set. System MNLI-m MNLI-mm MRPC CoLA Avg TinyBERT 4 82.8 82.9 85.8 50.8 75.6 w/o Embd 82.3 82.3 85.0 46.7 74.1 w/o Pred 80.5 81.0 84.3 48.2 73.5 w/o Trm 71.7 72.3 70.1 11.2 56.3 w/o Attn 79.9 80.7 82.3 41.1 71.0 w/o Hidn 81.7 82.1 84.1 43.7 72.9 Table 3: Ablation studies of different distillation objectives in the TinyBERT learning. The variants are validated on the dev set. 4.5.2 Effects of Distillation Objective We investigate the effects of distillation objectives on the TinyBERT learning. Several baselines are proposed including the learning without the Transformer-layer distillation (w/o Trm), the embedding-layer distillation (w/o Emb) or the prediction-layer distillation (w/o Pred) 10 10 10 The prediction-layer distillation performs soft cross-entropy as Equation 10 on the augmented data. “w/o Pred” means performing standard cross-entropy against the ground-truth of original train set. respectively. The results are illustrated in Table 3 and show that all the proposed distillation objectives are useful. The performance w/o Trm 11 11 11 Under “w/o Trm” setting, we actually 1) conduct embedding-layer distillation at the pre-training stage; 2) perform embedding-layer and prediction-layer distillation at fine-tuning stage. drops significantly from 75.6 to 56.3. The reason for the significant drop lies in the initialization of student model. At the pre-training stage, obtaining a good initialization is crucial for the distillation of transformer-based models, while there is no supervision signal from upper layers to update the parameters of transformer layers at this stage under the w/o Trm setting. Furthermore, we study the contributions of attention (Attn) and hidden states (Hidn) in the Transformer-layer distillation. We can find the attention based distillation has a greater impact than hidden states based distillation. Meanwhile, these two kinds of knowledge distillation are complementary to each other, which makes them the most important distillation techniques for Transformer-based model in our experiments. 4.6 Effects of Mapping Function We also investigate the effects of different mapping functions n = g ( m ) n=g(m) on the TinyBERT learning. Our original TinyBERT as described in section 4.2 uses the uniform strategy, and we compare with two typical baselines including top-strategy ( g ( m ) = m + N − M ; 0 < m ≤ M ) \left(g(m)=m+N-M;0<m\leq M\right) and bottom-strategy ( g ( m ) = m ; 0 < m ≤ M ) \left(g(m)=m;0<m\leq M\right) . The comparison results are presented in Table 4 . We find that the top-strategy performs better than the bottom-strategy on MNLI, while being worse on MRPC and CoLA, which confirms the observations that different tasks depend on the knowledge from different BERT layers. The uniform strategy covers the knowledge from bottom to top layers of BERT BASE , and it achieves better performances than the other two baselines in all the tasks. Adaptively choosing layers for a specific task is a challenging problem and we leave it as future work. System MNLI-m MNLI-mm MRPC CoLA Avg Uniform 82.8 82.9 85.8 50.8 75.6 Top 81.7 82.3 83.6 35.9 70.9 Bottom 80.6 81.3 84.6 38.5 71.3 Table 4: Results (dev) of different mapping strategies for TinyBERT 4 . 5 Related Work Pre-trained Language Models Compression Generally, pre-trained language models (PLMs) can be compressed by low-rank approximation Ma et al. 2019 ; Lan et al. 2020 , weight sharing Dehghani et al. 2019 ; Lan et al. 2020 , knowledge distillation Tang et al. 2019 ; Sanh et al. 2019 ; Turc et al. 2019 ; Sun et al. 2020 ; Liu et al. 2020 ; Wang et al. 2020 , pruning Cui et al. 2019 ; McCarley 2019 ; F. et al. 2020 ; Elbayad et al. 2020 ; Gordon et al. 2020 ; Hou et al. 2020 or quantization Shen et al. 2019 ; Zafrir et al. 2019 . In this paper, our focus is on knowledge distillation. Knowledge Distillation for PLMs There have been some works trying to distill pre-trained language models (PLMs) into smaller models. BiLSTM SOFT {}_{\hbox{SOFT}} Tang et al. 2019 distills task-specific knowledge from BERT into a single-layer BiLSTM. BERT-PKD Sun et al. 2019 extracts knowledges not only from the last layer of the teacher, but also from intermediate layers at fine-tuning stage. DistilBERT Sanh et al. 2019 performs distillation at pre-training stage on large-scale corpus. Concurrent works, MobileBERT Sun et al. 2020 distills a BERT LARGE augmented with bottleneck structures into a 24-layer slimmed version by progressive knowledge transfer at pre-training stage. MiniLM Wang et al. 2020 conducts deep self-attention distillation also at pre-training stage. By contrast, we propose a new two-stage learning framework to distill knowledge from BERT at both pre-training and fine-tuning stages by a novel transformer distillation method. Pretraining Lite PLMs Other related works aim at directly pretraining lite PLMs. Turc et al. 2019 pre-trained 24 miniature BERT models and show that pre-training remains important in the context of smaller architectures, and fine-tuning pre-trained compact models can be competitive. ALBERT Lan et al. 2020 incorporates embedding factorization and cross-layer parameter sharing to reduce model parameters. Since ALBERT does not reduce hidden size or layers of transformer block, it still has large amount of computations. Another concurrent work, ELECTRA Clark et al. 2020 proposes a sample-efficient task called replaced token detection to accelerate pre-training, and it also presents a 12-layer ELECTRA small that has comparable performance with TinyBERT 4 . Different from these small PLMs, TinyBERT 4 is a 4-layer model which can achieve more speedup. 6 Conclusion and Future Work In this paper, we introduced a new method for Transformer-based distillation, and further proposed a two-stage framework for TinyBERT. Extensive experiments show that TinyBERT achieves competitive performances meanwhile significantly reducing the model size and inference time of BERT BASE , which provides an effective way to deploy BERT-based NLP models on edge devices. In future work, we would study how to effectively transfer the knowledge from wider and deeper teachers (e.g., BERT LARGE ) to student TinyBERT. Combining distillation with quantization/pruning would be another promising direction to further compress the pre-trained language models. Acknowledgements This work is supported in part by NSFC NO.61832020, No.61821003, 61772216, National Science and Technology Major Project No.2017ZX01032-101, Fundamental Research Funds for the Central Universities. References Bentivogli et al. (2009) L. Bentivogli, P. Clark, I. Dagan, and D. Giampiccolo. 2009. The fifth pascal recognizing textual entailment challenge. Cer et al. (2017) D. Cer, M. Diab, E. Agirre, I. Lopez-Gazpio, and L. Specia. 2017. Semeval-2017 task 1: Semantic textual similarity multilingual and crosslingual focused evaluation. In Proceedings of the 11th International Workshop on Semantic Evaluation . Chen et al. (2018) Z. Chen, H. Zhang, X. Zhang, and L. Zhao. 2018. Quora question pairs. Clark et al. (2019) K. Clark, U. Khandelwal, O. Levy, and C. D. Manning. 2019. What does bert look at? an analysis of bert’s attention. In Proceedings of the 2019 ACL Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP . Clark et al. (2020) K. Clark, M. Luong, Q. V. Le, and C. D. Manning. 2020. Electra: Pre-training text encoders as discriminators rather than generators. In ICLR . Cui et al. (2019) B. Cui, Y. Li, M. Chen, and Z. Zhang. 2019. Fine-tune bert with sparse self-attention mechanism. In EMNLP . Dehghani et al. (2019) M. Dehghani, S. Gouws, O. Vinyals, J. Uszkoreit, and L. Kaiser. 2019. Universal transformers. In ICLR . Devlin et al. (2019) J. Devlin, M. Chang, K. Lee, and K. Toutanova. 2019. Bert: Pre-training of deep bidirectional transformers for language understanding. In NAACL . Ding et al. (2019) M. Ding, C. Zhou, Q. Chen, H. Yang, and J. Tang. 2019. Cognitive graph for multi-hop reading comprehension at scale. In ACL . Dolan and Brockett (2005) W. B. Dolan and C. Brockett. 2005. Automatically constructing a corpus of sentential paraphrases. In Proceedings of the Third International Workshop on Paraphrasing . Elbayad et al. (2020) M. Elbayad, J. Gu, E. Grave, and M. Auli. 2020. Depth-adaptive transformer. In ICLR . F. et al. (2020) Angela F., Edouard G., and Armand J. 2020. Reducing transformer depth on demand with structured dropout. In ICLR . Gong et al. (2014) Y. Gong, L. Liu, M. Yang, and L. Bourdev. 2014. Compressing deep convolutional networks using vector quantization. arXiv preprint arXiv:1412.6115 . Gordon et al. (2020) M. A. Gordon, K. Duh, and N. Andrews. 2020. Compressing bert: Studying the effects of weight pruning on transfer learning. arXiv preprint arXiv:2002.08307 . Han et al. (2016) S. Han, Mao H., and Dally W. J. 2016. Deep compression: Compressing deep neural network with pruning, trained quantization and huffman coding. In ICLR . Han et al. (2015) S Han, J. Pool, J. Tran, and W. Dally. 2015. Learning both weights and connections for efficient neural network. In NIPS . Hinton et al. (2015) G. Hinton, O. Vinyals, and J. Dean. 2015. Distilling the knowledge in a neural network. arXiv preprint arXiv:1503.02531 . Hou et al. (2020) L. Hou, L. Shang, X. Jiang, and Q. Liu. 2020. Dynabert: Dynamic bert with adaptive width and depth. arXiv preprint arXiv:2004.04037 . Hu et al. (2018) M. Hu, Y. Peng, F. Wei, Z. Huang, D. Li, N. Yang, and M. Zhou. 2018. Attention-guided answer distillation for machine reading comprehension. In EMNLP . Kim and Rush (2016) Y. Kim and A. M. Rush. 2016. Sequence-level knowledge distillation. In EMNLP . Kovaleva et al. (2019) O. Kovaleva, A. Romanov, A. Rogers, and A. Rumshisky. 2019. Revealing the dark secrets of bert. In EMNLP . Lan et al. (2020) Z. Lan, M. Chen, S. Goodman, K. Gimpel, P. Sharma, and R. Soricut. 2020. Albert: A lite bert for self-supervised learning of language representations. In ICLR . Levesque et al. (2012) Hector Levesque, Ernest Davis, and Leora Morgenstern. 2012. The winograd schema challenge. In Thirteenth International Conference on the Principles of Knowledge Representation and Reasoning . Liu et al. (2020) W. Liu, P. Zhou, Z. Zhao, Z. Wang, H. Deng, and Q. Ju. 2020. Fastbert: a self-distilling bert with adaptive inference time. arXiv preprint arXiv:2004.02178 . Liu et al. (2019) Y. Liu, M. Ott, N. Goyal, J. Du, M. Joshi, D. Chen, O. Levy, M. Lewis, L. Zettlemoyer, and V. Stoyanov. 2019. Roberta: A robustly optimized bert pretraining approach. arXiv preprint arXiv:1907.11692 . Ma et al. (2019) X. Ma, P. Zhang, S. Zhang, N. Duan, Y. Hou, M. Zhou, and D. Song. 2019. A tensorized transformer for language modeling. In NIPS . McCarley (2019) J. S. McCarley. 2019. Pruning a bert-based question answering model. arXiv preprint arXiv:1910.06360 . Michel et al. (2019) P. Michel, O. Levy, and G. Neubig. 2019. Are sixteen heads really better than one? In NIPS . Pennington et al. (2014) J. Pennington, R. Socher, and C. D. Manning. 2014. Glove: Global vectors for word representation. In EMNLP . Raffel et al. (2019) C. Raffel, N. Shazeer, A. Roberts, K. Lee, S. Narang, M. Matena, Y. Zhou, W. Li, and P. J. Liu. 2019. Exploring the limits of transfer learning with a unified text-to-text transformer. arXiv preprint arXiv:1910.10683 . Rajpurkar et al. (2018) P. Rajpurkar, R. Jia, and P. Liang. 2018. Know what you don’t know: Unanswerable questions for squad. In ACL . Rajpurkar et al. (2016) P. Rajpurkar, J. Zhang, K. Lopyrev, and P. Liang. 2016. Squad: 100,000+ questions for machine comprehension of text. In EMNLP . Romero et al. (2014) A. Romero, N. Ballas, S. E. Kahou, A. Chassang, C. Gatta, and Y. Bengio. 2014. Fitnets: Hints for thin deep nets. arXiv preprint arXiv:1412.6550 . Sajjad et al. (2020) H. Sajjad, F. Dalvi, N. Durrani, and P. Nakov. 2020. Poor man’s bert: Smaller and faster transformer models. arXiv preprint arXiv:2004.03844 . Sanh et al. (2019) V. Sanh, L. Debut, J. Chaumond, and T. Wolf. 2019. Distilbert, a distilled version of bert: smaller, faster, cheaper and lighter. arXiv preprint arXiv:1910.01108 . Shen et al. (2019) S. Shen, Z. Dong, J. Ye, L. Ma, Z. Yao, A. Gholami, M. W. Mahoney, and K. Keutzer. 2019. Q-bert: Hessian based ultra low precision quantization of bert. arXiv preprint arXiv:1909.05840 . Socher et al. (2013) R. Socher, A. Perelygin, J. Wu, J. Chuang, C. D. Manning, A. Y. Ng, and C. Potts. 2013. Recursive deep models for semantic compositionality over a sentiment treebank. In EMNLP . Sun et al. (2019) S. Sun, Y. Cheng, Z. Gan, and J. Liu. 2019. Patient knowledge distillation for bert model compression. In EMNLP . Sun et al. (2020) Z. Sun, H. Yu, X. Song, R. Liu, Y. Yang, and D. Zhou. 2020. Mobilebert: a compact task-agnostic bert for resource-limited devices. arXiv preprint arXiv:2004.02984 . Tang et al. (2019) R. Tang, Y. Lu, L. Liu, L. Mou, O. Vechtomova, and J. Lin. 2019. Distilling task-specific knowledge from bert into simple neural networks. arXiv preprint arXiv:1903.12136 . Turc et al. (2019) I. Turc, M. Chang, K. Lee, and K. Toutanova. 2019. Well-read students learn better: The impact of student initialization on knowledge distillation. arXiv preprint arXiv:1908.08962 . Vaswani et al. (2017) A. Vaswani, N. Shazeer, N. Parmar, J. Uszkoreit, L. Jones, A. N. Gomez, Ł. Kaiser, and I. Polosukhin. 2017. Attention is all you need. In NIPS . Voita et al. (2019) E. Voita, D. Talbot, F. Moiseev, R. Sennrich, and I. Titov. 2019. Analyzing multi-head self-attention: Specialized heads do the heavy lifting, the rest can be pruned. In ACL . Wang et al. (2018) A. Wang, A. Singh, J. Michael, F. Hill, O. Levy, and S. Bowman. 2018. Glue: A multi-task benchmark and analysis platform for natural language understanding. In Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP . Wang et al. (2020) W. Wang, F. Wei, L. Dong, H. Bao, N. Yang, and M. Zhou. 2020. Minilm: Deep self-attention distillation for task-agnostic compression of pre-trained transformers. arXiv preprint arXiv:2002.10957 . Warstadt et al. (2019) A. Warstadt, A. Singh, and S. R. Bowman. 2019. Neural network acceptability judgments. TACL . Williams et al. (2018) A. Williams, N. Nangia, and S. Bowman. 2018. A broad-coverage challenge corpus for sentence understanding through inference. In NAACL . Wu et al. (2019) X. Wu, S. Lv, L. Zang, J. Han, and S. Hu. 2019. Conditional bert contextual augmentation. In International Conference on Computational Science . Xu et al. (2020) C. Xu, W. Zhou, T. Ge, F. Wei, and M. Zhou. 2020. Bert-of-theseus: Compressing bert by progressive module replacing. arXiv preprint arXiv:2002.02925 . Yang et al. (2019) Z. Yang, Z. Dai, Y. Yang, J. Carbonell, R. R. Salakhutdinov, and Q. V. Le. 2019. Xlnet: Generalized autoregressive pretraining for language understanding. In NIPS . Zafrir et al. (2019) O. Zafrir, G. Boudoukh, P. Izsak, and M. Wasserblat. 2019. Q8bert: Quantized 8bit bert. arXiv preprint arXiv:1910.06188 . Appendix Appendix A More Comparisons on GLUE System CoLA MNLI-m MNLI-mm MRPC QNLI QQP RTE SST-2 STS-B (8.5k) (393k) (393k) (3.7k) (105k) (364k) (2.5k) (67k) (5.7k) Mcc Acc Acc F1/Acc Acc F1/Acc Acc Acc Pear/Spea Same Student Architecture ( M M =6; d ′ d^{\prime} =768; d i ′ d^{\prime}_{i} =3072) DistilBERT 6 51.3 82.2 - 87.5/- 89.2 -/88.5 59.9 92.7 -/86.9 Poor Man’s BERT 6 - 81.1 - -/80.2 87.6 -/90.4 65.0 90.3 -/88.5 BERT-of-Theseus 51.1 82.3 - 89.0/- 89.5 -/89.6 68.2 91.5 -/88.7 MiniLM 6 49.2 84.0 - 88.4/- 91.0 -/91.0 71.5 92.0 - TinyBERT 6 54.0 84.5 84.5 90.6/86.3 91.1 88.0/91.1 73.4 93.0 90.1/89.6 Table 5: Comparisons between TinyBERT with other baselines on the dev set of GLUE tasks. Mcc refers to Matthews correlation and Pear/Spea refer to Pearson/Spearman. Since some prior works on BERT compression only evaluate their models on the GLUE dev set, for an easy and direct comparison, we here compare our TinyBERT 6 with the reported results from these prior works. All the compared methods have the same model architecture as TinyBERT 6 (i.e. M M =6, d ′ d^{\prime} =768, d i ′ d^{\prime}_{i} =3072). The direct comparison results are shown in Table 5 . We can see the TinyBERT 6 outperforms all the baselines under the same settings of architecture and evaluation methods. The effectiveness of TinyBERT is further confirmed. Appendix B Results on SQuAD v1.1 and v2.0 We also demonstrate the effectiveness of TinyBERT on the question answering (QA) tasks: SQuAD v1.1 ( Rajpurkar et al. 2016 ) and SQuAD v2.0 ( Rajpurkar et al. 2018 ) . Following the learning procedure in the previous work ( Devlin et al. 2019 ) , we treat these two tasks as the problem of sequence labeling which predicts the possibility of each token as the start or end of answer span. One small difference from the GLUE tasks is that we perform the prediction-layer distillation on the original training dataset instead of the augmented dataset, which can bring better performances. The results show that TinyBERT consistently outperforms both the 4-layer and 6-layer baselines, which indicates that the proposed framework also works for the tasks of token-level labeling. Compared with sequence-level GLUE tasks, the question answering tasks depend on more subtle knowledge to infer the correct answer, which increases the difficulty of knowledge distillation. We leave how to build a better QA-TinyBERT as future work. System SQuAD 1.1 SQuAD 2.0 EM F1 EM F1 BERT BASE (Teacher) 80.7 88.4 74.5 77.7 4-layer student models BERT 4 -PKD 70.1 79.5 60.8 64.6 DistilBERT 4 71.8 81.2 60.6 64.1 MiniLM 4 - - - 69.7 TinyBERT 4 72.7 82.1 68.2 71.8 6-layer student models BERT 6 -PKD 77.1 85.3 66.3 69.8 DistilBERT 6 78.1 86.2 66.0 69.5 MiniLM 6 - - - 76.4 TinyBERT 6 79.7 87.5 74.7 77.7 Table 6: Results (dev) of baselines and TinyBERT on question answering tasks. The architecture of MiniLM 4 is ( M M =4, d d =384, d i d_{i} =1536) which is wider than TinyBERT 4 , and the architecture of MiniLM 6 is the same as TinyBERT 6 ( M M =6, d d =768, d i d_{i} =3072) Appendix C Initializing TinyBERT with BERT TINY In the proposed two-stage learning framework, to make TinyBERT effectively work for different downstream tasks, we propose the General Distillation (GD) to capture the general domain knowledge, through which the TinyBERT learns the knowledge from intermediate layers of teacher BERT at the pre-training stage. After that, a general TinyBERT is obtained and used as the initialization of student model for Task-specific Distillation (TD) on downstream tasks. System MNLI-m MNLI-mm MRPC CoLA Avg (392k) (392k) (3.5k) (8.5k) BERT TINY 75.9 76.9 83.2 19.5 63.9 BERT TINY (+TD) 79.2 79.7 82.9 12.4 63.6 TinyBERT (GD) 76.6 77.2 82.0 8.7 61.1 TinyBERT (GD+TD) 80.5 81.0 82.4 29.8 68.4 Table 7: Results of different methods at pre-training stage. TD and GD refers to Task-specific Distillation (without data augmentation) and General Distillation, respectively. The results are evaluated on dev set. In our preliminary experiments, we have also tried to initialize TinyBERT with the directly pre-trained BERT TINY , and then conduct the TD on downstream tasks. We denote this compression method as BERT TINY (+TD). The results in Table 7 show that BERT TINY (+TD) performs even worse than BERT TINY on MRPC and CoLA tasks. We conjecture that if without imitating the BERT BASE ’s behaviors at the pre-training stage, BERT TINY will derive mismatched distributions in intermediate representations (e.g., attention matrices and hidden states) with the BERT BASE model. The following task-specific distillation under the supervision of fine-tuned BERT BASE will further disturb the learned distribution/knowledge of BERT TINY , finally leading to poor performances on some less-data tasks. For the intensive-data task (e.g. MNLI), TD has enough training data to make BERT TINY acquire the task-specific knowledge very well, although the pre-trained distributions have already been disturbed. From the results of Table 7 , we find that GD can effectively transfer the knowledge from the teacher BERT to the student TinyBERT and achieve comparable results with BERT TINY (61.1 vs. 63.9), even without performing the MLM and NSP tasks. Furthermore, the task-specific distillation boosts the performances of TinyBERT by continuing on learning the task-specific knowledge from fine-tuned teacher BERT BASE . Appendix D GLUE Details The GLUE datasets are described as follows: MNLI. Multi-Genre Natural Language Inference is a large-scale, crowd-sourced entailment classification task ( Williams et al. 2018 ) . Given a pair of ⟨ p r e m i s e , h y p o t h e s i s ⟩ \langle premise,hypothesis\rangle , the goal is to predict whether the h y p o t h e s i s hypothesis is an entailment, contradiction, or neutral with respect to the p r e m i s e premise . QQP. Quora Question Pairs is a collection of question pairs from the website Quora. The task is to determine whether two questions are semantically equivalent ( Chen et al. 2018 ) . QNLI. Question Natural Language Inference is a version of the Stanford Question Answering Dataset which has been converted to a binary sentence pair classification task by Wang et al. 2018 . Given a pair ⟨ q u e s t i o n , c o n t e x t ⟩ \langle question,context\rangle . The task is to determine whether the c o n t e x t context contains the answer to the q u e s t i o n question . SST-2. The Stanford Sentiment Treebank is a binary single-sentence classification task, where the goal is to predict the sentiment of movie reviews Socher et al. 2013 . CoLA. The Corpus of Linguistic Acceptability is a task to predict whether an English sentence is a grammatically correct one ( Warstadt et al. 2019 ) . STS-B. The Semantic Textual Similarity Benchmark is a collection of sentence pairs drawn from news headlines and many other domains ( Cer et al. 2017 ) . The task aims to evaluate how similar two pieces of texts are by a score from 1 to 5. MRPC. Microsoft Research Paraphrase Corpus is a paraphrase identification dataset where systems aim to identify if two sentences are paraphrases of each other Dolan and Brockett 2005 . RTE. Recognizing Textual Entailment is a binary entailment task with a small training dataset ( Bentivogli et al. 2009 ) .
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Improving QA Efficiency with DistilBERT: Fine-Tuning and Inference on mobile Intel CPUs Ngeyen Yinkfu Email: nyinkfu@andrew.cmu.edu Affiliation: Carnegie Mellon University Africa Affiliation: Kigali, Rwanda Abstract This study presents an efficient transformer-based question-answering (QA) model optimized for deployment on a 13th Gen Intel i7-1355U CPU, using the Stanford Question Answering Dataset (SQuAD) v1.1. Leveraging exploratory data analysis, data augmentation, and fine-tuning of a DistilBERT architecture, the model achieves a validation F1 score of 0.6536 with an average inference time of 0.1208 seconds per question. Compared to a rule-based baseline (F1: 0.3124) and full BERT-based models, our approach offers a favorable trade-off between accuracy and computational efficiency. This makes it well-suited for real-time applications on resource-constrained systems. The study includes systematic evaluation of data augmentation strategies and hyperparameter configurations, providing practical insights into optimizing transformer models for CPU-based inference. 1 Introduction Question answering (QA) systems have become a cornerstone of natural language processing (NLP), enabling machines to extract precise answers from textual contexts. The Stanford Question Answering Dataset (SQuAD) v1.1 ( Rajpurkar et al., 2016 ) is a widely adopted benchmark for evaluating QA models, comprising over 87,000 training examples of context-question-answer triples. While transformer-based models like BERT ( Devlin et al., 2019 ) have achieved state-of-the-art performance on SQuAD, their computational complexity often demands GPU acceleration, limiting deployment on resource-constrained devices like mid-range CPUs. This study addresses the challenge of developing a transformer-based QA model optimized for inference on a 13th Gen Intel i7-1355U CPU, a 10-core processor with a 5.0 GHz turbo frequency. We focus on DistilBERT ( Sanh et al., 2020 ) , a lightweight transformer, to balance performance—measured by F1 score and accuracy—with inference speed. Our contributions include: • Comprehensive exploratory data analysis (EDA) of SQuAD v1.1 to inform modeling decisions. • Data augmentation strategies to enhance model robustness to low-overlap question-context pairs. • Fine-tuning and optimization of DistilBERT, achieving a validation F1 score of 0.6536 and an average inference time of 0.1208 seconds per question. • Comparative evaluation against a rule-based baseline and BERT-based configurations, highlighting efficiency trade-offs. This paper details the dataset, methodology, results, and implications for deploying QA systems in resource-constrained environments. 2 Related Work The advent of transformer-based architectures has significantly advanced question-answering (QA) systems, particularly on benchmarks like SQuAD v1.1 ( Rajpurkar et al., 2016 ) . Below, we discuss key QA models, their architectures, performance, and optimization strategies, situating our work within this landscape. 2.1 Transformer-Based QA Models The introduction of BERT ( Devlin et al., 2019 ) marked a breakthrough in QA, achieving an F1 score of 88.5 on SQuAD v1.1 through bidirectional pre-training on large corpora. BERT’s 12-layer (BERT-Base) architecture with 110 million parameters leverages self-attention to capture contextual relationships, making it highly effective for span-based QA tasks. However, its computational complexity poses challenges for deployment on resource-constrained devices. Subsequent models have built on BERT’s foundation. RoBERTa ( Liu et al., 2019 ) enhances BERT by optimizing pre-training with larger datasets and longer training, achieving an F1 score of 91.5 on SQuAD v1.1. ALBERT ( Lan et al., 2020 ) reduces parameters through factorized embeddings and cross-layer parameter sharing, reaching an F1 score of 90.9 with lower memory demands. XLNet ( Yang et al., 2020 ) integrates autoregressive pre-training, outperforming BERT with an F1 score of 89.9 by modeling permutations of input sequences. T5 ( Raffel et al., 2023 ) frames QA as a text-to-text task, achieving competitive performance (F1: 90) by treating all NLP tasks as sequence generation. ELECTRA ( Clark et al., 2020 ) introduces a discriminative pre-training objective, where a smaller model detects replaced tokens, yielding an F1 score of 90.8 with improved efficiency over BERT. While these models achieve high performance, their large parameter counts (e.g., RoBERTa: 125M, T5: up to 11B) and computational requirements make them less practical for CPU-based inference, motivating our focus on lightweight models like DistilBERT ( Sanh et al., 2020 ) . DistilBERT, with 66 million parameters, is a distilled version of BERT, retaining 97% of its performance (F1: 85 on SQuAD) while reducing inference time, as demonstrated in Wolf et al. (2020) . MobileBERT ( Sun et al., 2020 ) further optimizes for mobile devices, achieving an F1 score of 84.3 with 25 million parameters, but its applicability to standard CPUs remains underexplored. 2.2 Optimization for Efficiency To address computational constraints, several optimization techniques have been proposed. Knowledge distillation, as used in DistilBERT ( Sanh et al., 2020 ) , transfers knowledge from a larger model (e.g., BERT) to a smaller one, reducing parameters while preserving performance. Quantization, explored by Shen et al. (2021) , compresses model weights to lower precision (e.g., 8-bit integers), reducing inference time on CPUs. Pruning techniques, such as those in Michel et al. (2019) , remove redundant attention heads or layers, further enhancing efficiency. For example, Zafrir et al. (2019) applied 8-bit quantization to BERT, achieving near-original performance with faster inference. However, these studies primarily target edge devices or GPUs, with limited focus on mid-range CPUs like the Intel i7-1355U. 2.3 Data Augmentation in QA Data augmentation enhances QA model robustness, particularly for low-overlap question-context pairs. Yang et al. (2019) employed synonym replacement and back-translation, increasing SQuAD training data diversity and improving generalization. Similarly, Wei and Zou (2019) proposed easy data augmentation (EDA) techniques, including synonym substitution and random insertion, which improved performance on smaller datasets. These strategies align with our approach of using WordNet-based paraphrasing to augment questions and contexts, addressing the moderate overlap (mean: 0.52) observed in SQuAD. 2.4 Positioning Our Work Our study builds on these advancements by fine-tuning DistilBERT for SQuAD v1.1, emphasizing CPU inference on a mid-range processor. Unlike high-parameter models (e.g., RoBERTa, T5), we prioritize efficiency, achieving a competitive F1 score (0.6536) with an inference time of 0.1208 seconds per question. Compared to Shen et al. (2021) and Michel et al. (2019) , our work focuses on standard CPU hardware, and our augmentation strategies extend Yang et al. (2019) by combining question and context paraphrasing. This positions our work as a practical solution for real-time QA in resource-constrained environments, addressing a gap in deploying transformer-based QA models on CPUs. 3 Dataset Description The SQuAD v1.1 dataset ( Rajpurkar et al., 2016 ) contains 87,599 training examples and 10,570 validation examples, each comprising a Wikipedia-sourced context, a question, and an answer span. Its diversity and scale make it a standard benchmark for QA tasks. 4 Exploratory Data Analysis We conducted exploratory data analysis (EDA) on SQuAD v1.1’s training split to guide model design. Key statistics include: • Training Set Size : 87,599 examples; Validation Set Size : 10,570 examples. • Question Length : Mean of 10.06 words, standard deviation of 4.32, maximum of 40 words. • Context Length : Mean of 119.76 words, standard deviation of 52.14, maximum of 653 words. • Answer Length : Mean of 3.16 words, standard deviation of 2.87, maximum of 43 words. • Question-Context Overlap : Mean proportion of 0.52, standard deviation of 0.19. Visualizations (Figures 1 , 2 , 3 ) reveal right-skewed distributions for question and context lengths, short answer spans (81% between 1–5 words), near-uniform answer positions, and moderate question-context overlap (62% between 0.4–0.7). These findings informed a maximum sequence length of 384 tokens, data augmentation for low-overlap examples, and the choice of a transformer architecture to handle diverse answer positions. Figure 1: Histogram of question lengths (left) with a mode around 8–10 words, and context lengths (right) with a mode around 100–120 words. Figure 2: Histogram of answer lengths (left) showing most answers are 1–5 words, and answer start positions (right) indicating a near-uniform distribution. Figure 3: Histogram of question-context word overlap (left) peaking at 0.5–0.6, and scatter plot of context vs. answer length (right), showing no correlation (Pearson correlation coefficient ≈ \approx 0.03). 4.1 Implications for Modeling The EDA justified a 384-token sequence length, data augmentation for robustness, and a transformer architecture to capture context-wide dependencies. The prevalence of factoid questions guided augmentation strategies focusing on paraphrasing. 5 Data Augmentation Techniques To enhance model robustness, we applied: • Question Paraphrasing : Using NLTK’s WordNet, we replaced question words (e.g., ”what” with ”which thing”) and rephrased structures, doubling the training set for Model 1 to 20,000 examples. • Context Paraphrasing : For Model 2, we augmented contexts with synonym substitutions (e.g., ”said” with ”stated”), increasing the training set to 45,000 examples while preserving answer spans. These strategies addressed low question-context overlap, ensuring semantic equivalence via WordNet. 6 Model Architecture We primarily used DistilBERT ( Sanh et al., 2020 ) , with BERT ( Devlin et al., 2019 ) for comparison. DistilBERT features 6 transformer layers, 12 attention heads, a hidden size of 768, and no token-type embeddings, with a linear layer for span prediction. It has 66 million parameters versus BERT’s 110 million, enabling faster inference (0.12 vs. 0.30 seconds per question) on the target CPU. DistilBERT’s lower validation loss (1.9240 vs. 22.6069 for BERT) and competitive F1 score (0.6536) justified its selection. 7 Baseline Evaluation A rule-based baseline, selecting answer spans via maximum word overlap, achieved an F1 score of 0.3124 and accuracy of 0.2567 on the validation set, highlighting the limitations of keyword matching given moderate question-context overlap. 8 Methodology We trained four models on SQuAD v1.1 subsets using a Tesla P100 GPU: • Model 1 (DistilBERT-Base) : 20,000 examples, 5 epochs, early stopping (patience: 3). • Model 2 (DistilBERT-Warm-Up) : 45,000 examples, 5 epochs, 500 warm-up steps. • Model 3 (DistilBERT-Frozen) : 10,000 examples, 24 epochs, frozen embeddings and 4 layers. • Model 4 (BERT-Frozen) : 10,000 examples, 5 epochs, frozen embeddings and 4 layers. Preprocessing used DistilBERT/BERT tokenizers, mapping answers to token indices. We used the Adam optimizer with polynomial decay, gradient clipping (norm: 1.0), and TensorFlow datasets with batching and shuffling. Evaluation metrics included validation loss, accuracy, and F1 score, computed as the harmonic mean of precision and recall for answer span predictions. 9 Training Dynamics and Hyperparameter Analysis Hyperparameter configurations are shown in Table 1 . Training times were 50–70 minutes per epoch at batch size 8, and 26 minutes at batch size 32 on the Tesla P100. Table 1: Hyperparameter Configurations Model Learning Rate Batch Size Warm-Up Steps Label Smoothing Epochs Model 1 (DistilBERT-Base) 3e-5 8 0 0.1 5 Model 2 (DistilBERT-Warm-Up) 2e-5 8 500 0.05 5 Model 3 (DistilBERT-Frozen) 3e-5 32 0 0.0 24 Model 4 (BERT-Frozen) 3e-5 16 0 0.0 5 Alt Config Model 2: Model 2 (Trial 1) 5e-5 8 500 0.05 3 (stopped) Model 2 (Trial 2) 2e-5 16 500 0.05 4 (stopped) Model 2 (Trial 3) 2e-5 8 1000 0.05 5 Lower learning rates (2e-5) and warm-up steps (500) improved stability, while label smoothing (0.05) enhanced F1 scores. Larger batch sizes or extended epochs led to memory issues or overfitting. 10 Results Table 2 summarizes model performance. Model 2 achieved the best results (F1: 0.6536, accuracy: 0.5040, loss: 1.9240), benefiting from warm-up and augmentation. All models outperformed the baseline, confirming transformer efficacy. Table 2: Model Performance on Validation Set Model Val Loss Val Accuracy Val F1 Score Epochs Run Baseline (Keyword Matching) N/A 0.2567 0.3124 N/A Model 1 (DistilBERT-Base) 2.3024 0.4945 0.6437 5 Model 2 (DistilBERT-Warm-Up) 1.9240 0.5040 0.6536 5 Model 3 (DistilBERT-Frozen) 95.0318 0.3613 N/A 24 Model 4 (BERT-Frozen) 22.6069 0.5302 N/A 5 10.1 Discussion Model 2’s superior performance reflects the effectiveness of warm-up and extensive augmentation, aligning with findings from Yang et al. (2019) . While our F1 score (0.6536) is lower than state-of-the-art models like RoBERTa (F1: 90+), it is competitive for a CPU-optimized model with limited training data. Model 3’s poor performance indicates that freezing layers hinders learning, while Model 4’s higher loss suggests BERT’s complexity is less suited for small datasets. Limitations include the dataset size constraint and lack of quantization, which could further reduce inference time. 11 Inference on Intel i7-1355U Model 2’s inference on the target CPU averaged 0.1208 seconds per question across five validation examples (e.g., predicting “denver broncos” for “Which NFL team represented the AFC at Super Bowl 50?”). BERT’s inference time (0.30 seconds) underscores DistilBERT’s efficiency for real-time applications. 12 Conclusion This study presents an efficient DistilBERT-based QA model for SQuAD v1.1, achieving an F1 score of 0.6536 and an inference time of 0.1208 seconds on a 13th Gen Intel i7-1355U CPU. Through EDA, data augmentation, and hyperparameter optimization, we demonstrate a practical solution for resource-constrained environments. Future work could explore quantization, pruning, or larger datasets to enhance performance while maintaining efficiency. Appendix A Code Listings A.1 Data Preprocessing and Augmentation Listing 1: Data Preprocessing and Augmentation ⬇ 1 from transformers import DistilBertTokenizer 2 from nltk . corpus import wordnet 3 import tensorflow as tf 4 5 tokenizer = DistilBertTokenizer . from_pretrained ( ’distilbert-base-uncased’ ) 6 7 def paraphrase_question ( question ): 8 words = question . split () 9 new_words = [] 10 for word in words : 11 syns = wordnet . synsets ( word ) 12 if syns and word in [ ’what’ , ’who’ ]: 13 new_word = syns [0]. lemmas ()[0]. name () if syns [0]. lemmas () else word 14 new_words . append ( new_word ) 15 else : 16 new_words . append ( word ) 17 return ’ ␣ ’ . join ( new_words ) 18 19 def preprocess_data ( examples , max_length =384): 20 inputs = tokenizer ( 21 examples [ ’question’ ], examples [ ’context’ ], 22 max_length = max_length , truncation = True , padding = ’max_length’ , 23 return_tensors = ’tf’ 24 ) 25 start_positions = tf . constant ([ example [ ’answer_start’ ] for example in examples ]) 26 end_positions = tf . constant ([ example [ ’answer_end’ ] for example in examples ]) 27 return inputs , start_positions , end_positions A.2 Model Training (Model 2) Listing 2: Training Code for Model 2 ⬇ 1 from transformers import TFDistilBertForQuestionAnswering , create_optimizer 2 import tensorflow as tf 3 4 model = TFDistilBertForQuestionAnswering . from_pretrained ( ’distilbert-base-uncased’ ) 5 num_train_steps = 45000 // 8 * 5 6 optimizer , lr_schedule = create_optimizer ( 7 init_lr =2 e -5, num_train_steps = num_train_steps , num_warmup_steps =500 8 ) 9 10 model . compile ( 11 optimizer = optimizer , 12 loss = tf . keras . losses . SparseCategoricalCrossentropy ( from_logits = True , label_smoothing =0.05), 13 metrics =[ ’accuracy’ ] 14 ) 15 16 train_dataset = tf . data . Dataset . from_tensor_slices (( inputs , { ’start_positions’ : start_positions , ’end_positions’ : end_positions })) 17 train_dataset = train_dataset . shuffle (1000). batch (8) 18 model . fit ( train_dataset , epochs =5, callbacks =[ tf . keras . callbacks . EarlyStopping ( patience =3)]) A.3 Inference Implementation Listing 3: Inference Code for Model 2 ⬇ 1 import tensorflow as tf 2 from transformers import AutoTokenizer , TFDistilBertForQuestionAnswering 3 import time 4 5 model_path = "best_distilbert_model" 6 tokenizer = AutoTokenizer . from_pretrained ( "distilbert-base-uncased" ) 7 loaded_model = TFDistilBertForQuestionAnswering . from_pretrained ( "distilbert-base-uncased" ) 8 try : 9 loaded_model . load_weights ( model_path ) 10 except Exception as e : 11 print ( f "Warning: ␣ Could ␣ not ␣ load ␣ weights ␣ from ␣ {model_path}. ␣ Error: ␣ {e}" ) 12 13 def predict_answer_distilbert ( question , context , model , tokenizer ): 14 inputs = tokenizer ( question , context , max_length =512, truncation = "only_second" , padding = "max_length" , return_tensors = "tf" ) 15 outputs = model ( inputs ) 16 start_logits = outputs . start_logits [0] 17 end_logits = outputs . end_logits [0] 18 start_pred = tf . argmax ( start_logits ). numpy () 19 end_pred = tf . argmax ( end_logits ). numpy () 20 input_ids = inputs [ "input_ids" ]. numpy ()[0] 21 sep_idx = -1 22 for i , id in enumerate ( input_ids ): 23 if id == tokenizer . sep_token_id : 24 sep_idx = i 25 break 26 if sep_idx != -1 and start_pred <= end_pred and start_pred > 0 and end_pred < sep_idx : 27 answer_tokens = input_ids [ start_pred : end_pred +1] 28 answer = tokenizer . decode ( answer_tokens , skip_special_tokens = True ) 29 return answer 30 else : 31 return "No ␣ answer ␣ found" References Clark et al. [2020] Kevin Clark, Minh-Thang Luong, Quoc V. Le, and Christopher D. Manning. Electra: Pre-training text encoders as discriminators rather than generators, 2020. URL https://arxiv.org/abs/2003.10555 . Devlin et al. [2019] Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. Bert: Pre-training of deep bidirectional transformers for language understanding, 2019. URL https://arxiv.org/abs/1810.04805 . Lan et al. [2020] Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, and Radu Soricut. Albert: A lite bert for self-supervised learning of language representations, 2020. URL https://arxiv.org/abs/1909.11942 . Liu et al. [2019] Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, and Veselin Stoyanov. Roberta: A robustly optimized bert pretraining approach, 2019. URL https://arxiv.org/abs/1907.11692 . Michel et al. [2019] Paul Michel, Omer Levy, and Graham Neubig. Are sixteen heads really better than one?, 2019. URL https://arxiv.org/abs/1905.10650 . Raffel et al. [2023] Colin Raffel, Noam Shazeer, Adam Roberts, Katherine Lee, Sharan Narang, Michael Matena, Yanqi Zhou, Wei Li, and Peter J. Liu. Exploring the limits of transfer learning with a unified text-to-text transformer, 2023. URL https://arxiv.org/abs/1910.10683 . Rajpurkar et al. [2016] Pranav Rajpurkar, Jian Zhang, Konstantin Lopyrev, and Percy Liang. Squad: 100,000+ questions for machine comprehension of text, 2016. URL https://arxiv.org/abs/1606.05250 . Sanh et al. [2020] Victor Sanh, Lysandre Debut, Julien Chaumond, and Thomas Wolf. Distilbert, a distilled version of bert: smaller, faster, cheaper and lighter, 2020. URL https://arxiv.org/abs/1910.01108 . Shen et al. [2021] Siqi Shen, Zhequan Dong, Jianda Ye, Linjian Ma, Zhe Yao, Amir Gholami, Michael W. Mahoney, and Kurt Keutzer. Q-bert: Hessian based ultra low precision quantization of bert. arXiv preprint arXiv:1909.05840 , 2021. Sun et al. [2020] Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou. Mobilebert: a compact task-agnostic bert for resource-limited devices, 2020. URL https://arxiv.org/abs/2004.02984 . Wei and Zou [2019] Jason Wei and Kai Zou. Eda: Easy data augmentation techniques for boosting performance on text classification tasks, 2019. URL https://arxiv.org/abs/1901.11196 . Wolf et al. [2020] Thomas Wolf, Lysandre Debut, Victor Sanh, Julien Chaumond, Clement Delangue, Anthony Moi, Pierric Cistac, Tim Rault, Rémi Louf, Morgan Funtowicz, Joe Davison, Sam Shleifer, Patrick von Platen, Clara Ma, Yacine Jernite, Julien Plu, Canwen Xu, Teven Le Scao, Sylvain Gugger, Mariama Drame, Quentin Lhoest, and Alexander M. Rush. Huggingface’s transformers: State-of-the-art natural language processing, 2020. URL https://arxiv.org/abs/1910.03771 . Yang et al. [2019] Wei Yang, Yuqing Xie, Aileen Lin, Xingyu Li, Luchen Tan, Kun Xiong, Ming Li, and Jimmy Lin. End-to-end open-domain question answering with. In Proceedings of the 2019 Conference of the North . Association for Computational Linguistics, 2019. doi: 10.18653/v1/n19-4013 . URL http://dx.doi.org/10.18653/v1/N19-4013 . Yang et al. [2020] Zhilin Yang, Zihang Dai, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, and Quoc V. Le. Xlnet: Generalized autoregressive pretraining for language understanding, 2020. URL https://arxiv.org/abs/1906.08237 . Zafrir et al. [2019] Ofir Zafrir, Guy Boudoukh, Peter Izsak, and Moshe Wasserblat. Q8bert: Quantized 8bit bert. In 2019 Fifth Workshop on Energy Efficient Machine Learning and Cognitive Computing - NeurIPS Edition (EMC2-NIPS) , page 36–39. IEEE, December 2019. doi: 10.1109/emc2-nips53020.2019.00016 . URL http://dx.doi.org/10.1109/EMC2-NIPS53020.2019.00016 .
Model Figures & Evaluation Curves (4 Images)
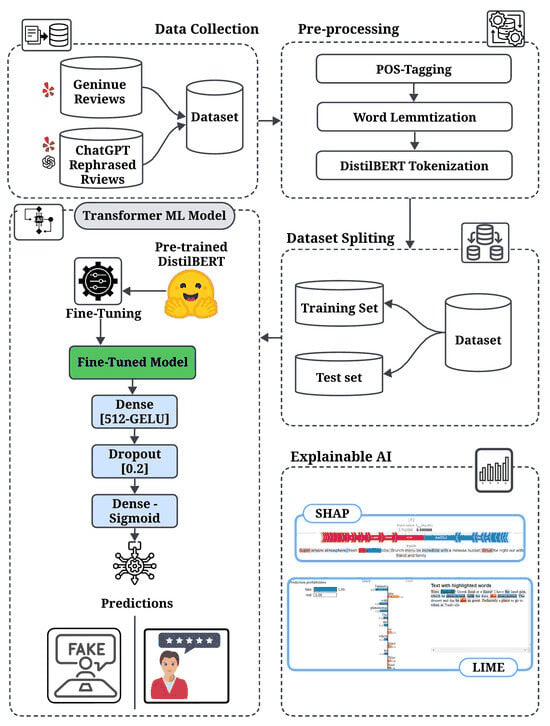
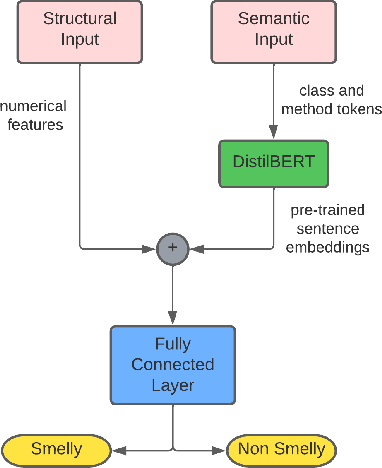
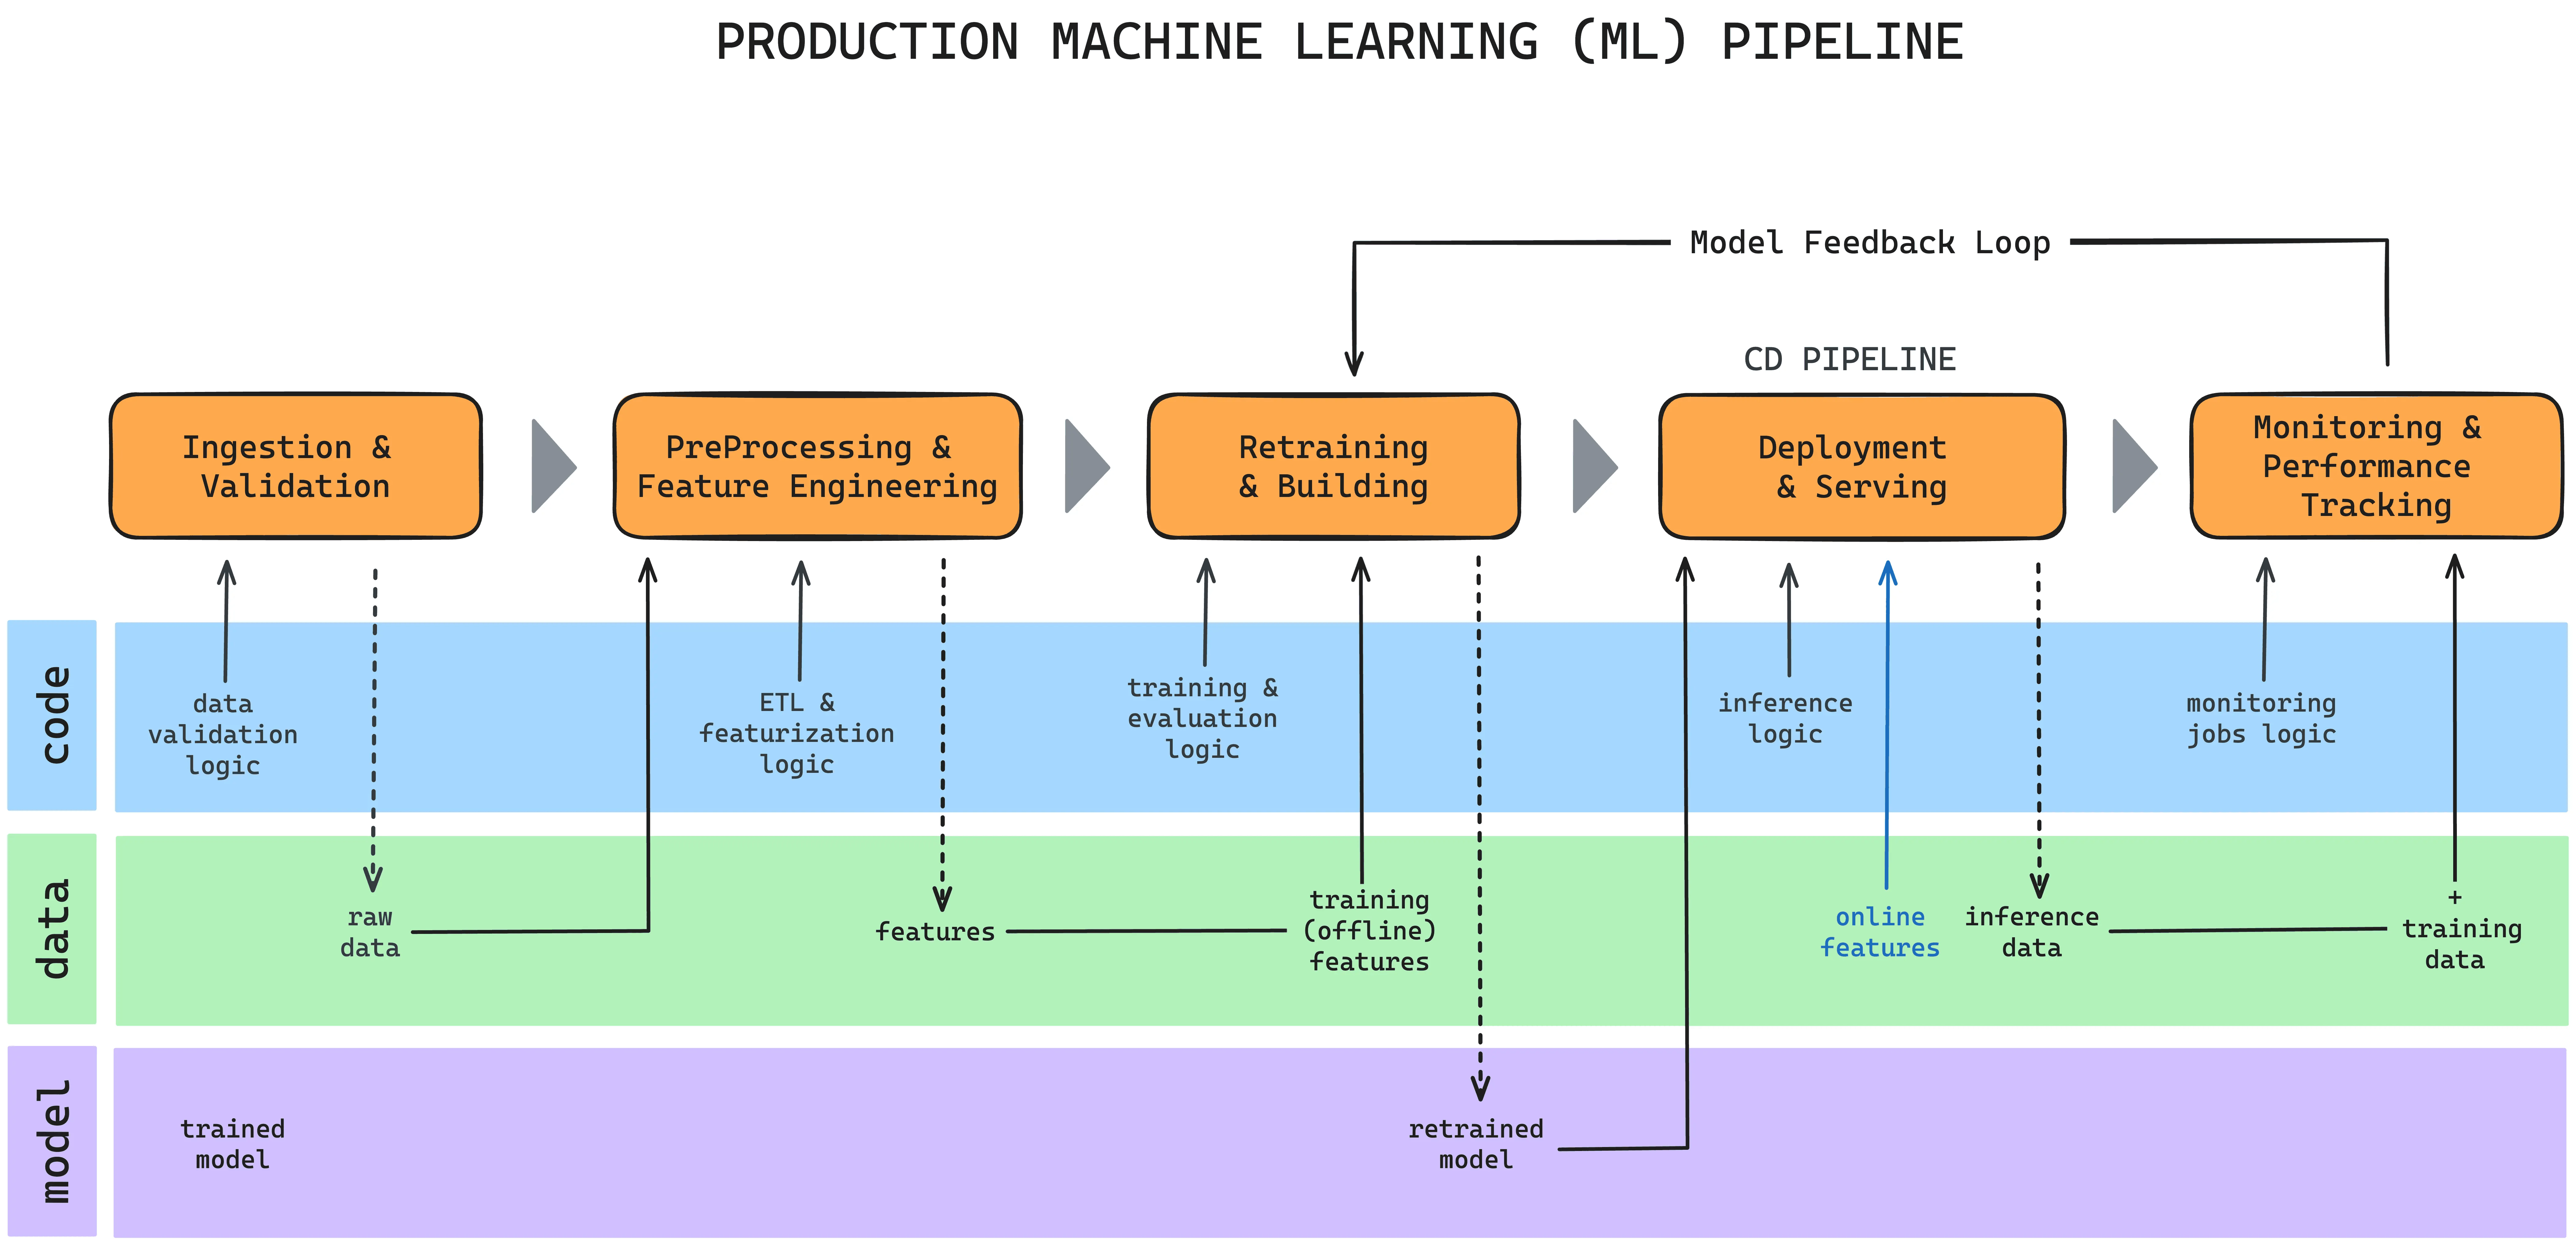
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)