Complete Technical Paper Content — Efficientnet Projects
1. Executive Abstract, Problem Formulation & Background
Google Brain was a deep learning artificial intelligence research team that served as the sole AI branch of Google before being incorporated under the newer umbrella of Google AI, a research division at Google dedicated to artificial intelligence. Formed in 2011, it combined open-ended machine learning research with information systems and large-scale computing resources. It created tools such as TensorFlow, which allow neural networks to be used by the public, and multiple internal AI research projects, and aimed to create research opportunities in machine learning and natural language processing. It was merged into former Google sister company DeepMind to form Google DeepMind in April 2023.
Word2vec learns word embeddings from the contexts in which words occur. It uses two model architectures, [[Bag-of-words model |continuous bag of words]] and skip-gram, which learn vector representations by predicting words from their surrounding context or vice versa. It was released as open-source software in 2013 and subsequently gained widespread adoption in research and industry.
TensorFlow is an open source software library powered by Google Brain that allows anyone to utilize machine learning by providing the tools to train one's own neural network. The tool has been used to develop software using deep learning models that farmers use to reduce the amount of manual labor required to sort their yield, by training it with a data set of human-sorted images.
Google Brain announced in 2022 that it created two different types of text-to-image models called Imagen and Parti that compete with OpenAI's DALL-E. Later in 2022, the project was extended to text-to-video. Imagen development was transferred to Google Deepmind after the merger with Deepmind.
In December 2020, AI ethicist Timnit Gebru left Google. While the exact nature of her quitting or being fired is disputed, the cause of the departure was her refusal to retract a paper entitled "On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?" and a related ultimatum she made, setting conditions to be met otherwise she would leave. This paper explored potential risks of the growth of AI such as Google Brain, including environmental impact, biases in training data, and the ability to deceive the public. The request to retract the paper was made by Megan Kacholia, vice president of Google Brain. As of April 2021, nearly 7000 current or former Google employees and industry supporters have signed an open letter accusing Google of "research censorship" and condemning Gebru's treatment at the company. In February 2021, Google fired one of the leaders of the company's AI ethics team, Margaret Mitchell. The company's statement alleged that Mitchell had broken company policy by using automated tools to find support for Gebru. In the same month, engineers outside the ethics team began to quit, citing the termination of Gebru as their reason for leaving. In April 2021, Google Brain co-founder Samy Bengio announced his resignation from the company. Despite being Gebru's manager, Bengio was not notified before her termination, and he posted online in support of both her and Mitchell. While Bengio's announcement focused on personal growth as his reason for leaving, anonymous sources indicated to Reuters that the turmoil within the AI ethics team played a role in his considerations.
In March 2022, Google fired AI researcher Satrajit Chatterjee after he questioned the findings of a paper published in Nature by Google AI, claiming that their AI techniques (in particular reinforcement learning) for the placement problem for integrated circuits were superior to prior methods. However, this claim is contested because claimed results, especially fast chip design, were not properly supported by specific empirical data and found inconsistent with subsequent published research. The paper didn't report run times of prior and proposed methods on specific inputs, lacked head-to-head comparisons to sufficiently advanced implementations of prior methods, and was difficult to replicate due to proprietary training and test data. At least one initially favorable commentary had been retracted upon further review, and the paper was reportedly under investigation by Nature editors. In a lawsuit contesting his firing, Chatterjee claimed the Nature paper overhyped Google's technology. Google moved to dismiss, but the court ruled that Chatterjee had "adequately supported his claim that Google terminated him in retaliation for refusing to participate in an act that would violate state or federal law." Nature published an addendum in September 2024, where the Google engineers clarified their methodology, and announced that they had open-sourced a software repository to reproduce the methods (but not the proprietary data of their examples) described in their paper. However, this did not quell the controversy over whether the proposed techniques are in fact an advance over other existing methods. In particular, Google did not show comparative results on publicly available benchmarks, the standard in the field and evidence long requested by experts.
2. Related Work, Literature Survey & Algorithmic Foundations
DeepMind Technologies Limited, trading as Google DeepMind or simply DeepMind, is a British-American artificial intelligence (AI) research laboratory which is a subsidiary of Alphabet Inc. Founded in the UK in 2010, it was acquired by Google in 2014, and merged with Google AI's Google Brain division to become Google DeepMind in April 2023. The company is headquartered in London, with research centres in the United States, Canada, France, Germany, and Switzerland. In 2014, DeepMind introduced neural Turing machines (neural networks that can access external memory like a conventional Turing machine). The company has created many neural network models trained with reinforcement learning to play video games and board games. It made headlines in 2016 after its AlphaGo program beat Lee Sedol, a Go world champion, in a five-game match, which was later featured in the documentary AlphaGo. A more general program, AlphaZero, beat the most powerful programs playing go, chess and shogi (Japanese chess) after a few days of play against itself using reinforcement learning. DeepMind has since trained models for game-playing (MuZero, AlphaStar), for mathematics (AlphaGeometry, FunSearch), and for algorithm discovery (AlphaEvolve, AlphaDev, AlphaTensor). In 2020, DeepMind made significant advances in the problem of protein folding with AlphaFold, which achieved state of the art records on benchmark tests for protein folding prediction. In July 2022, it was announced that over 200 million predicted protein structures, representing virtually all known proteins, would be released on the AlphaFold database. Google DeepMind has become responsible for the development of two large language model families: the proprietary Gemini and open-weight Gemma, as well as other generative AI models, such as Imagen (text-to-image), Veo (text-to-video), and Lyria (text-to-music).
Major venture capital firms Horizons Ventures and Founders Fund invested in the company, as well as entrepreneurs Scott Banister, Peter Thiel, and Elon Musk. Jaan Tallinn was an early investor and an adviser to the company. DeepMind needed a well-funded backer to pay its employees, provide compute resources and further expand. It was courted by Facebook, Musk, Google and some others. On 26 January 2014, Google confirmed its acquisition of DeepMind for a price reportedly ranging between $400 million and $650 million. The company was afterwards renamed Google DeepMind and kept that name for about two years. In 2014, DeepMind received the "Company of the Year" award from Cambridge Computer Laboratory. Looking for opportunities to benefit society, DeepMind started a pilot program with the NHS to modernize its information systems which were often still using plain paper and fax machines. In September 2015, DeepMind and the Royal Free NHS Trust signed their initial information sharing agreement to co-develop a clinical task management app, Streams. After Google's acquisition the company established an artificial intelligence ethics board. The ethics board for AI research was a mystery, with both Google and DeepMind declining to reveal who sat on the board. DeepMind opened a new unit called DeepMind Ethics and Society and focused on the ethical and societal questions raised by artificial intelligence featuring prominent philosopher Nick Bostrom as advisor. In October 2017, DeepMind launched a new research team to investigate AI ethics. In December 2019, co-founder Suleyman announced he would be leaving DeepMind to join the parent company Google, working in a policy role. In April 2023, DeepMind merged with Google AI's Google Brain division to form Google DeepMind, as part of the company's continued efforts to accelerate work on AI in response to OpenAI's release of ChatGPT to the general public. This marked the end of a years-long struggle from DeepMind executives to secure greater autonomy from Google. In the summer of 2026, DeepMind moved into Google's Platform 37 building in King's Cross Central.
In October 2015, a computer Go program called AlphaGo, developed by DeepMind, beat the European Go champion Fan Hui, a 2 dan (out of 9 dan possible) professional, five to zero. This was the first time an artificial intelligence (AI) defeated a professional Go player. Previously, computers were only known to have played Go at "amateur" level. Go is considered much more difficult for computers to win compared to other games like chess, due to the much larger number of possibilities, making it prohibitively difficult for traditional AI methods such as brute-force. In March 2016 it beat Lee Sedol, a 9-dan professional player, with a score of 4 to 1 in a five-game match. In the 2017 Future of Go Summit, AlphaGo won a three-game match with Ke Jie, who had been the world's highest-ranked player for two years. In 2017, an improved version, AlphaGo Zero, defeated AlphaGo in a hundred out of a hundred games. Later that year, AlphaZero, a modified version of AlphaGo Zero, gained superhuman abilities at chess and shogi. In 2019, DeepMind released a new model named MuZero that mastered the domains of Go, chess, shogi, and Atari 2600 games without human data, domain knowledge, or known rules. AlphaGo technology was developed based on deep reinforcement learning, making it different from the AI technologies then on the market. The data fed into the AlphaGo algorithm consisted of various moves based on historical tournament data. The number of moves was increased gradually until over 30 million of them were processed. The aim was to have the system mimic the human player, as represented by the input data, and eventually become better. It played against itself and learned from the outcomes; thus, it learned to improve itself over the time and increased its winning rate as a result. AlphaGo used two deep neural networks: a policy network to evaluate move probabilities and a value network to assess positions. The policy network trained via supervised learning, and was subsequently refined by policy-gradient reinforcement learning. The value network learned to predict winners of games played by the policy network against itself. After training, these networks employed a lookahead Monte Carlo tree search, using the policy network to identify candidate high-probability moves, while the value network (in conjunction with Monte Carlo rollouts using a fast rollout policy) evaluated tree positions. In contrast, AlphaGo Zero was trained without being fed data of human-played games. Instead it generated its own data, playing millions of games against itself. It used a single neural network, rather than separate policy and value networks. Its simplified tree search relied upon this neural network to evaluate positions and sample moves. A new reinforcement learning algorithm incorporated lookahead search inside the training loop. AlphaGo Zero employed around 15 people and millions in computing resources. Ultimately, it needed much less computing power than AlphaGo, running on four specialized AI processors (Google TPUs), instead of AlphaGo's 48. It also required less training time, being able to beat its predecessor after just three days, compared with months required for the original AlphaGo. Similarly, AlphaZero also learned via self-play. Researchers applied MuZero to solve the real world challenge of video compression with a set number of bits with respect to Internet traffic on sites such as YouTube, Twitch, and Google Meet. The goal of MuZero is to optimally compress the video so the quality of the video is maintained with a reduction in data. The final result using MuZero was a 6.28% average reduction in bitrate.
In 2016, Hassabis discussed the game StarCraft as a future challenge, since it requires strategic thinking and handling imperfect information. In January 2019, DeepMind introduced AlphaStar, a program playing the real-time strategy game StarCraft II. AlphaStar used reinforcement learning based on replays from human players, and then played against itself to enhance its skills. At the time of the presentation, AlphaStar had knowledge equivalent to 200 years of playing time. It won 10 consecutive matches against two professional players, although it had the unfair advantage of being able to see the entire field, unlike a human player who has to move the camera manually. A preliminary version in which that advantage was fixed lost a subsequent match. In July 2019, AlphaStar began playing against random humans on the public 1v1 European multiplayer ladder. Unlike the first iteration of AlphaStar, which played only Protoss v. Protoss, this one played as all of the game's races, and had earlier unfair advantages fixed. By October 2019, AlphaStar had reached Grandmaster level on the StarCraft II ladder on all three StarCraft races, becoming the first AI to reach the top league of a widely popular esport without any game restrictions.
In 2016, DeepMind turned its artificial intelligence to protein folding, a long-standing problem in molecular biology. In December 2018, DeepMind's AlphaFold won the 13th Critical Assessment of Techniques for Protein Structure Prediction (CASP) by successfully predicting the most accurate structure for 25 out of 43 proteins. "This is a lighthouse project, our first major investment in terms of people and resources into a fundamental, very important, real-world scientific problem," Hassabis said to The Guardian. In 2020, in the 14th CASP, AlphaFold's predictions achieved an accuracy score regarded as comparable with lab techniques. Andriy Kryshtafovych, one of the panel of scientific adjudicators, described the achievement as "truly remarkable", and said the problem of predicting how proteins fold had been "largely solved". In July 2021, the open-source RoseTTAFold and AlphaFold2 were released to allow scientists to run their own versions of the tools. A week later DeepMind announced that AlphaFold had completed its prediction of nearly all human proteins as well as the entire proteomes of 20 other widely studied organisms. The structures were released on the AlphaFold Protein Structure Database. In July 2022, it was announced that the predictions of over 200 million proteins, representing virtually all known proteins, would be released on the AlphaFold database. The most recent update, AlphaFold3, was released in May 2024, predicting the interactions of proteins with DNA, RNA, and various other molecules. In a particular benchmark test on the problem of DNA interactions, AlphaFold3's attained an accuracy of 65%, significantly improving the previous state of the art of 28%. In October 2024, Hassabis and John Jumper received half of the 2024 Nobel Prize in Chemistry jointly for protein structure prediction, citing AlphaFold2 achievement.
Gemini is a multimodal large language model which was released on 6 December 2023. It is the successor of Google's LaMDA and PaLM 2 language models and sought to challenge OpenAI's GPT-4. Gemini comes in 3 sizes: Nano, Pro, and Ultra. Gemini is also the name of the chatbot that integrates Google Gemini and which was previously called Google Bard. On 12 December 2024, Google released Gemini 2.0 Flash, the first model in the Gemini 2.0 series. It notably features expanded multimodality, with the ability to also generate images and audio, and is part of Google's broader plans to integrate advanced AI into autonomous agents. On 25 March 2025, Google released Gemini 2.5, a reasoning model that stops to "think" before giving a response. Google announced that all future models will also have reasoning ability. On 30 March 2025, Google released Gemini 2.5 to all free users. On 18 November 2025, Google released Gemini 3 Pro, a reasoning model which is fully multimodal. It was fully integrated with Google Search and AI Mode the same day.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Gemma is a collection of open-weight large language models. The first ones were released on 21 February 2024 and are available in two distinct sizes: a 7 billion parameter model optimized for GPU and TPU usage, and a 2 billion parameter model designed for CPU and on-device applications. Gemma models were trained on up to 6 trillion tokens of text, employing similar architectures, datasets, and training methodologies as the Gemini model set. In June 2024, Google started releasing Gemma 2 models. In December 2024, Google introduced PaliGemma 2, an upgraded vision-language model. In February 2025, they launched PaliGemma 2 Mix, a version fine-tuned for multiple tasks. It is available in 3B, 10B, and 28B parameters with 224px and 448px resolutions. In March 2025, Google released Gemma 3, calling it the most capable model that can be run on a single GPU. It has four available sizes: 1B, 4B, 12B, and 27B. In March 2025, Google introduced TxGemma, an open-source model designed to improve the efficiency of therapeutics development. In April 2025, Google introduced DolphinGemma, a research artificial intelligence model designed to hopefully decode dolphin communication. They want to train a foundation model that can learn the structure of dolphin vocalizations and generate novel dolphin-like sound sequences.
In 2024, Google Deepmind published the results of an experiment where they trained two large language models to help identify and present areas of overlap among a few thousand group members they had recruited online using techniques like sortition to get a representative sample of participants. The project is named in honor of Jürgen Habermas. In one experiment, the participants rated the summaries by the AI higher than the human moderator 56% of the time.
In May 2024, a multimodal video generation model called Veo was announced at Google I/O 2024. Google claimed that it could generate 1080p videos beyond a minute long. In December 2024, Google released Veo 2, available via VideoFX. It supports 4K video generation, and has an improved understanding of physics. In April 2025, Google announced that Veo 2 became available for advanced users on Gemini App. In May 2025, Google released Veo 3, which not only generates videos but also creates synchronized audio — including dialogue, sound effects, and ambient noise — to match the visuals. Google also announced Flow, a video-creation tool powered by Veo and Imagen.
Google DeepMind developed Lyria, a text-to-music model. As of August 2025, it is available on Vertex AI and the Gemini API. On February 18, 2026, DeepMind released Lyria 3. On March 25, 2026, DeepMind released Lyria 3 Pro which allows users to create longer tracks with more structural awareness.
In March 2024, DeepMind introduced "Genie" (Generative Interactive Environments), an AI model that can generate game-like, action-controllable virtual worlds based on textual descriptions, images, or sketches. Built as an autoregressive latent diffusion model, Genie enables frame-by-frame interactivity without requiring labelled action data for training. Its successor, Genie 2, released in December 2024, expanded these capabilities to generate diverse and interactive 3D environments. Genie 3 was released in August 2025, with higher-resolution world generations and multiple minutes of visual consistency. On January 29, 2026, DeepMind released Project Genie to AI Ultra subscribers.
AlphaGeometry is a neuro-symbolic AI that was able to solve 25 out of 30 geometry problems of the International Mathematical Olympiad, a performance comparable to that of a gold medalist. Traditional geometry programs are symbolic engines that rely exclusively on human-coded rules to generate rigorous proofs, which makes them lack flexibility in unusual situations. AlphaGeometry combines such a symbolic engine with a specialized large language model trained on synthetic data of geometrical proofs. When the symbolic engine doesn't manage to find a formal and rigorous proof on its own, it solicits the large language model, which suggests a geometrical construct to move forward. However, it is unclear how applicable this method is to other domains of mathematics or reasoning, because symbolic engines rely on domain-specific rules and because of the need for synthetic data.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
In June 2023, Deepmind announced that AlphaDev, which searches for improved computer science algorithms using reinforcement learning, discovered a more efficient way of coding a sorting algorithm and a hashing algorithm. The new sorting algorithm was 70% faster for shorter sequences and 1.7% faster for sequences exceeding 250,000 elements, and the new hashing algorithm was 30% faster in some cases. The sorting algorithm was accepted into the C++ Standard Library sorting algorithms, and was the first change to those algorithms in more than a decade and the first update to involve an algorithm discovered using AI. The hashing algorithm was released to an opensource library. Google estimates that these two algorithms are used trillions of times every day.
In May 2025, Google DeepMind unveiled AlphaEvolve, an evolutionary coding agent using LLMs like Gemini to design optimized algorithms. AlphaEvolve begins each optimization process with an initial algorithm and metrics to evaluate the quality of a solution. At each step, it uses the LLM to generate variations of the algorithms or combine them, and selects the best candidates for further iterations. AlphaEvolve has made several algorithmic discoveries, including in matrix multiplication. According to Google, when tested on 50 open mathematical problems, AlphaEvolve was able to match the efficiency of state-of-the-art algorithms in 75% of cases, and discovered improved solutions 20% of the time, such as with the kissing number in 11 dimensions. It also developed a new heuristic for data centre scheduling, recovering on average 0.7% of Google's worldwide compute resources.
AlphaChip is a reinforcement learning-based neural architecture that guides the task of chip placement. DeepMind claimed that the technique reduced the time needed to create chip layouts from weeks to hours. According to the company, its chip designs were used in every Tensor Processing Unit (TPU) iteration since 2020. Multiple independent researchers remained unconvinced, citing a lack of direct public benchmarks and independent proof of its claimed superiority over existing commercial chip design tools. The TPU chips were co-designed with Broadcom. Communications of the ACM noted that despite substantial publicity, DeepMind had not provided the comparative benchmarks long requested by experts, leaving some scepticism in the field. Similarly, New Scientist reported that while Google claims AlphaChip has produced “superhuman” chip layouts now used in production, external specialists called for transparent performance data to substantiate these assertions and enable fair comparisons with current state-of-the-art methods.
At the University of Cambridge, held by Neil Lawrence, in the Department of Computer Science and Technology, At the University of Oxford, held by Michael Bronstein, in the Department of Computer Science, and At the University College London, held by Marc Deisenroth, in the Department of Computer Science.
Mathematical Formulation 1.1: Loss Objectives and Optimization Dynamics for Efficientnet Projects. The training protocol of efficientnet projects minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
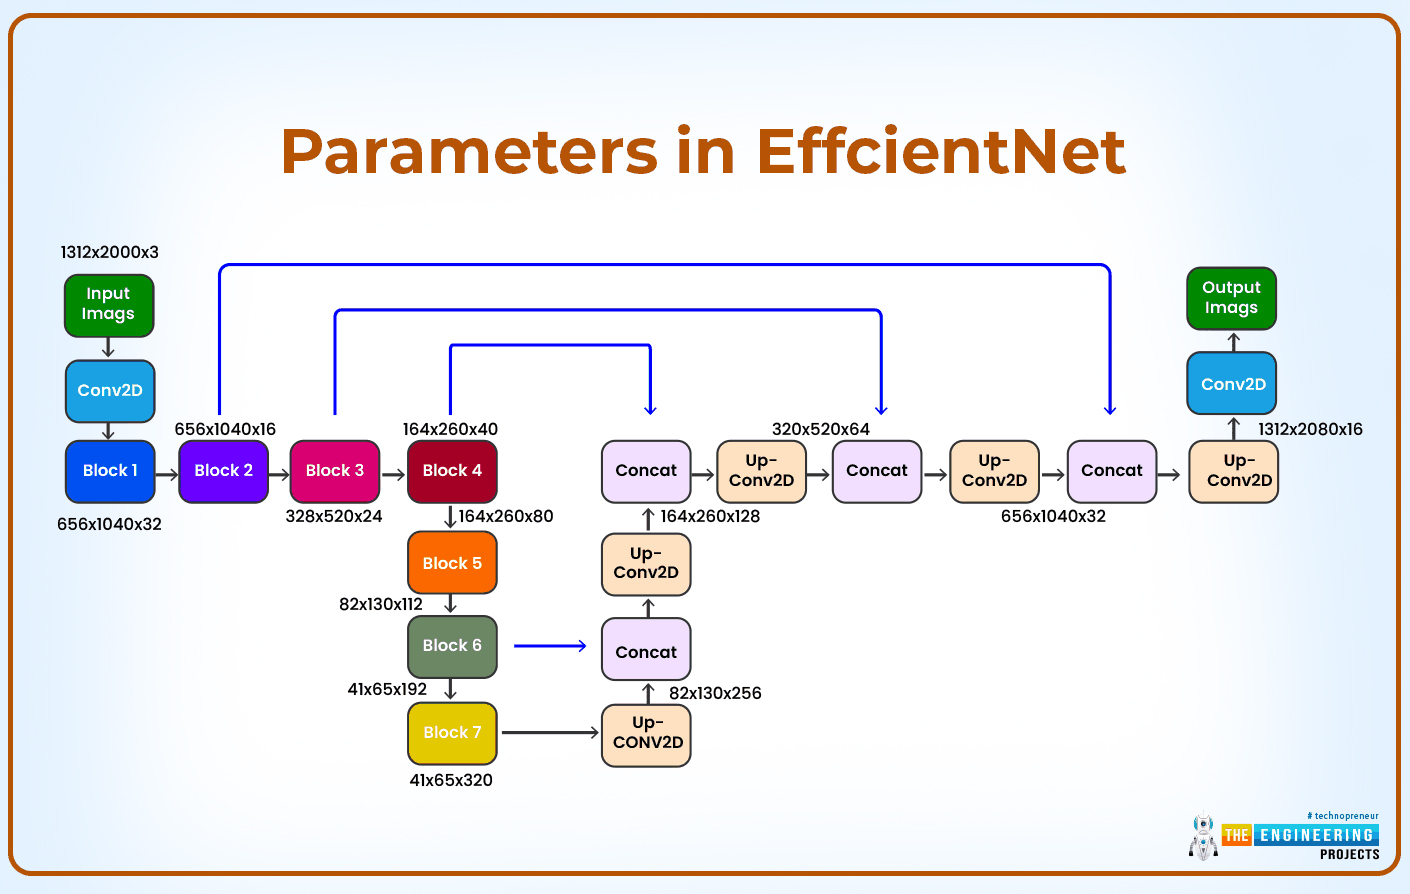
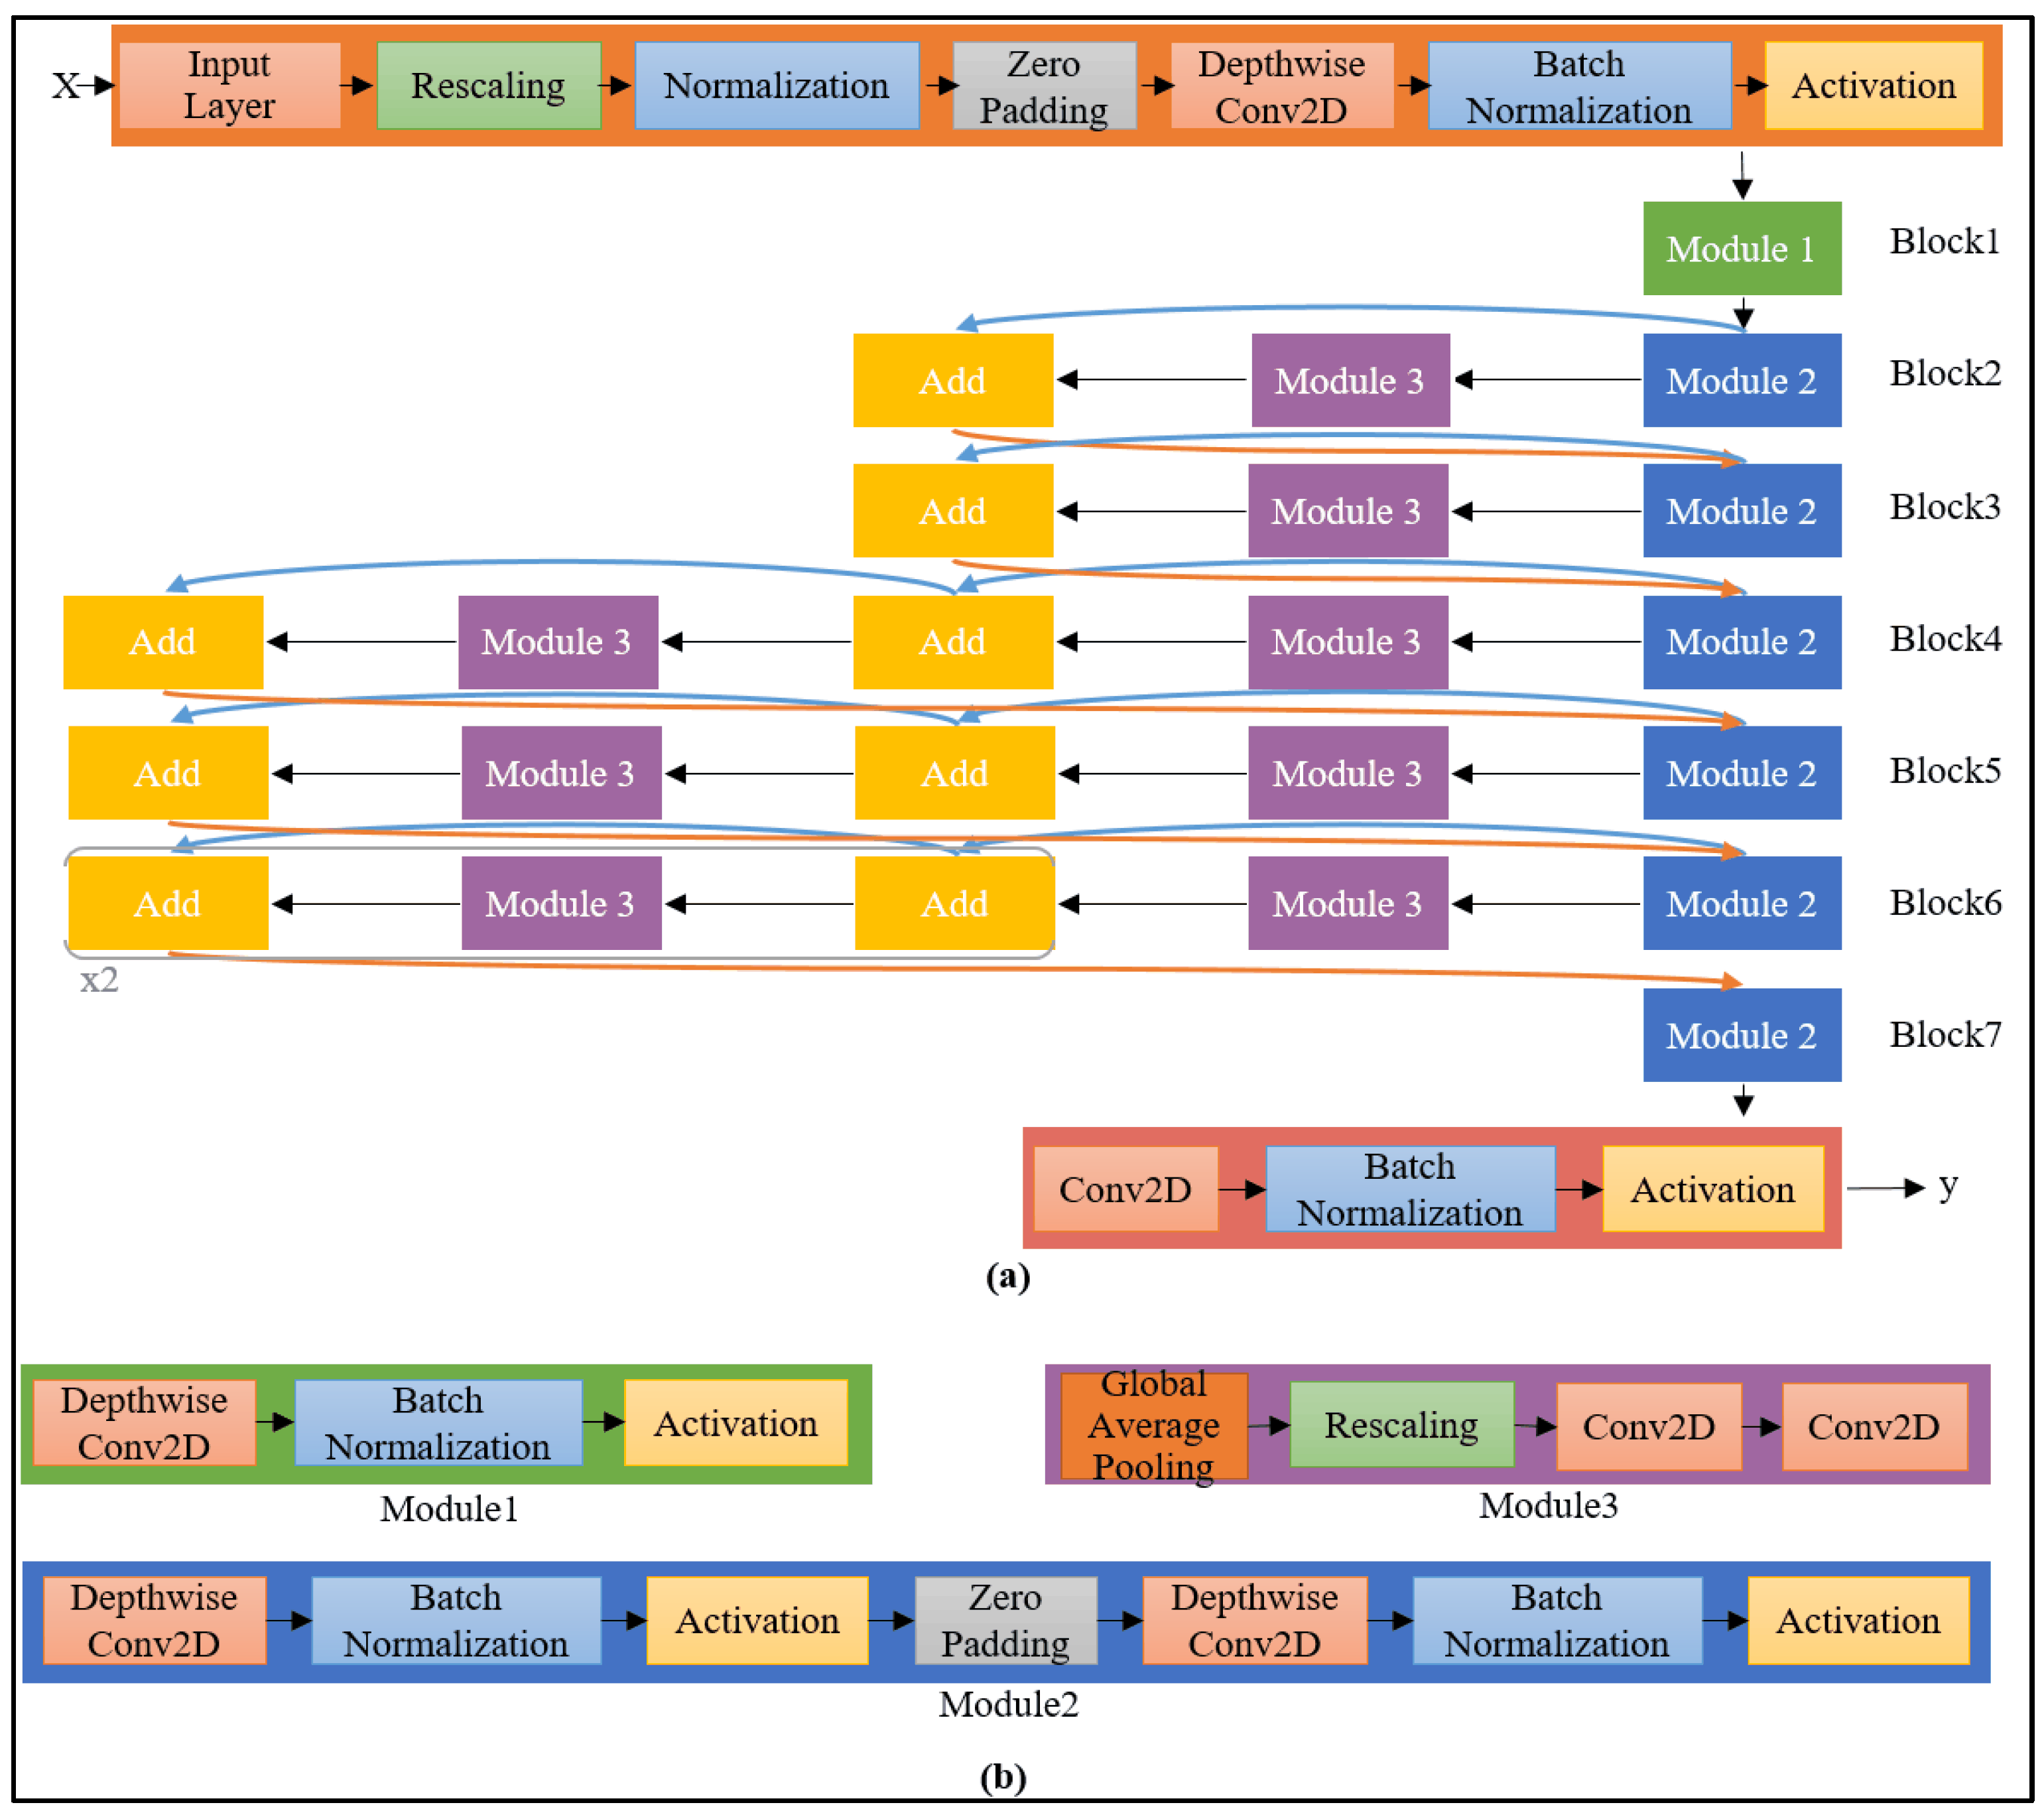
Architecture Specification 1.2: Feature Extraction and Layer Formulations for Efficientnet Projects. The primary computational backbone for Efficientnet Projects incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Data Pipeline 1.3: Stochastic Augmentation and Normalization Protocols for Efficientnet Projects. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 1.4: TensorRT Acceleration and Edge Quantization for Efficientnet Projects. Production deployment of Efficientnet Projects focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Mathematical Formulation 2.1: Loss Objectives and Optimization Dynamics for Efficientnet Projects. The training protocol of efficientnet projects minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
Architecture Specification 2.2: Feature Extraction and Layer Formulations for Efficientnet Projects. The primary computational backbone for Efficientnet Projects incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 2.3: Stochastic Augmentation and Normalization Protocols for Efficientnet Projects. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 2.4: TensorRT Acceleration and Edge Quantization for Efficientnet Projects. Production deployment of Efficientnet Projects focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Model Figures & Evaluation Curves (4 Images)
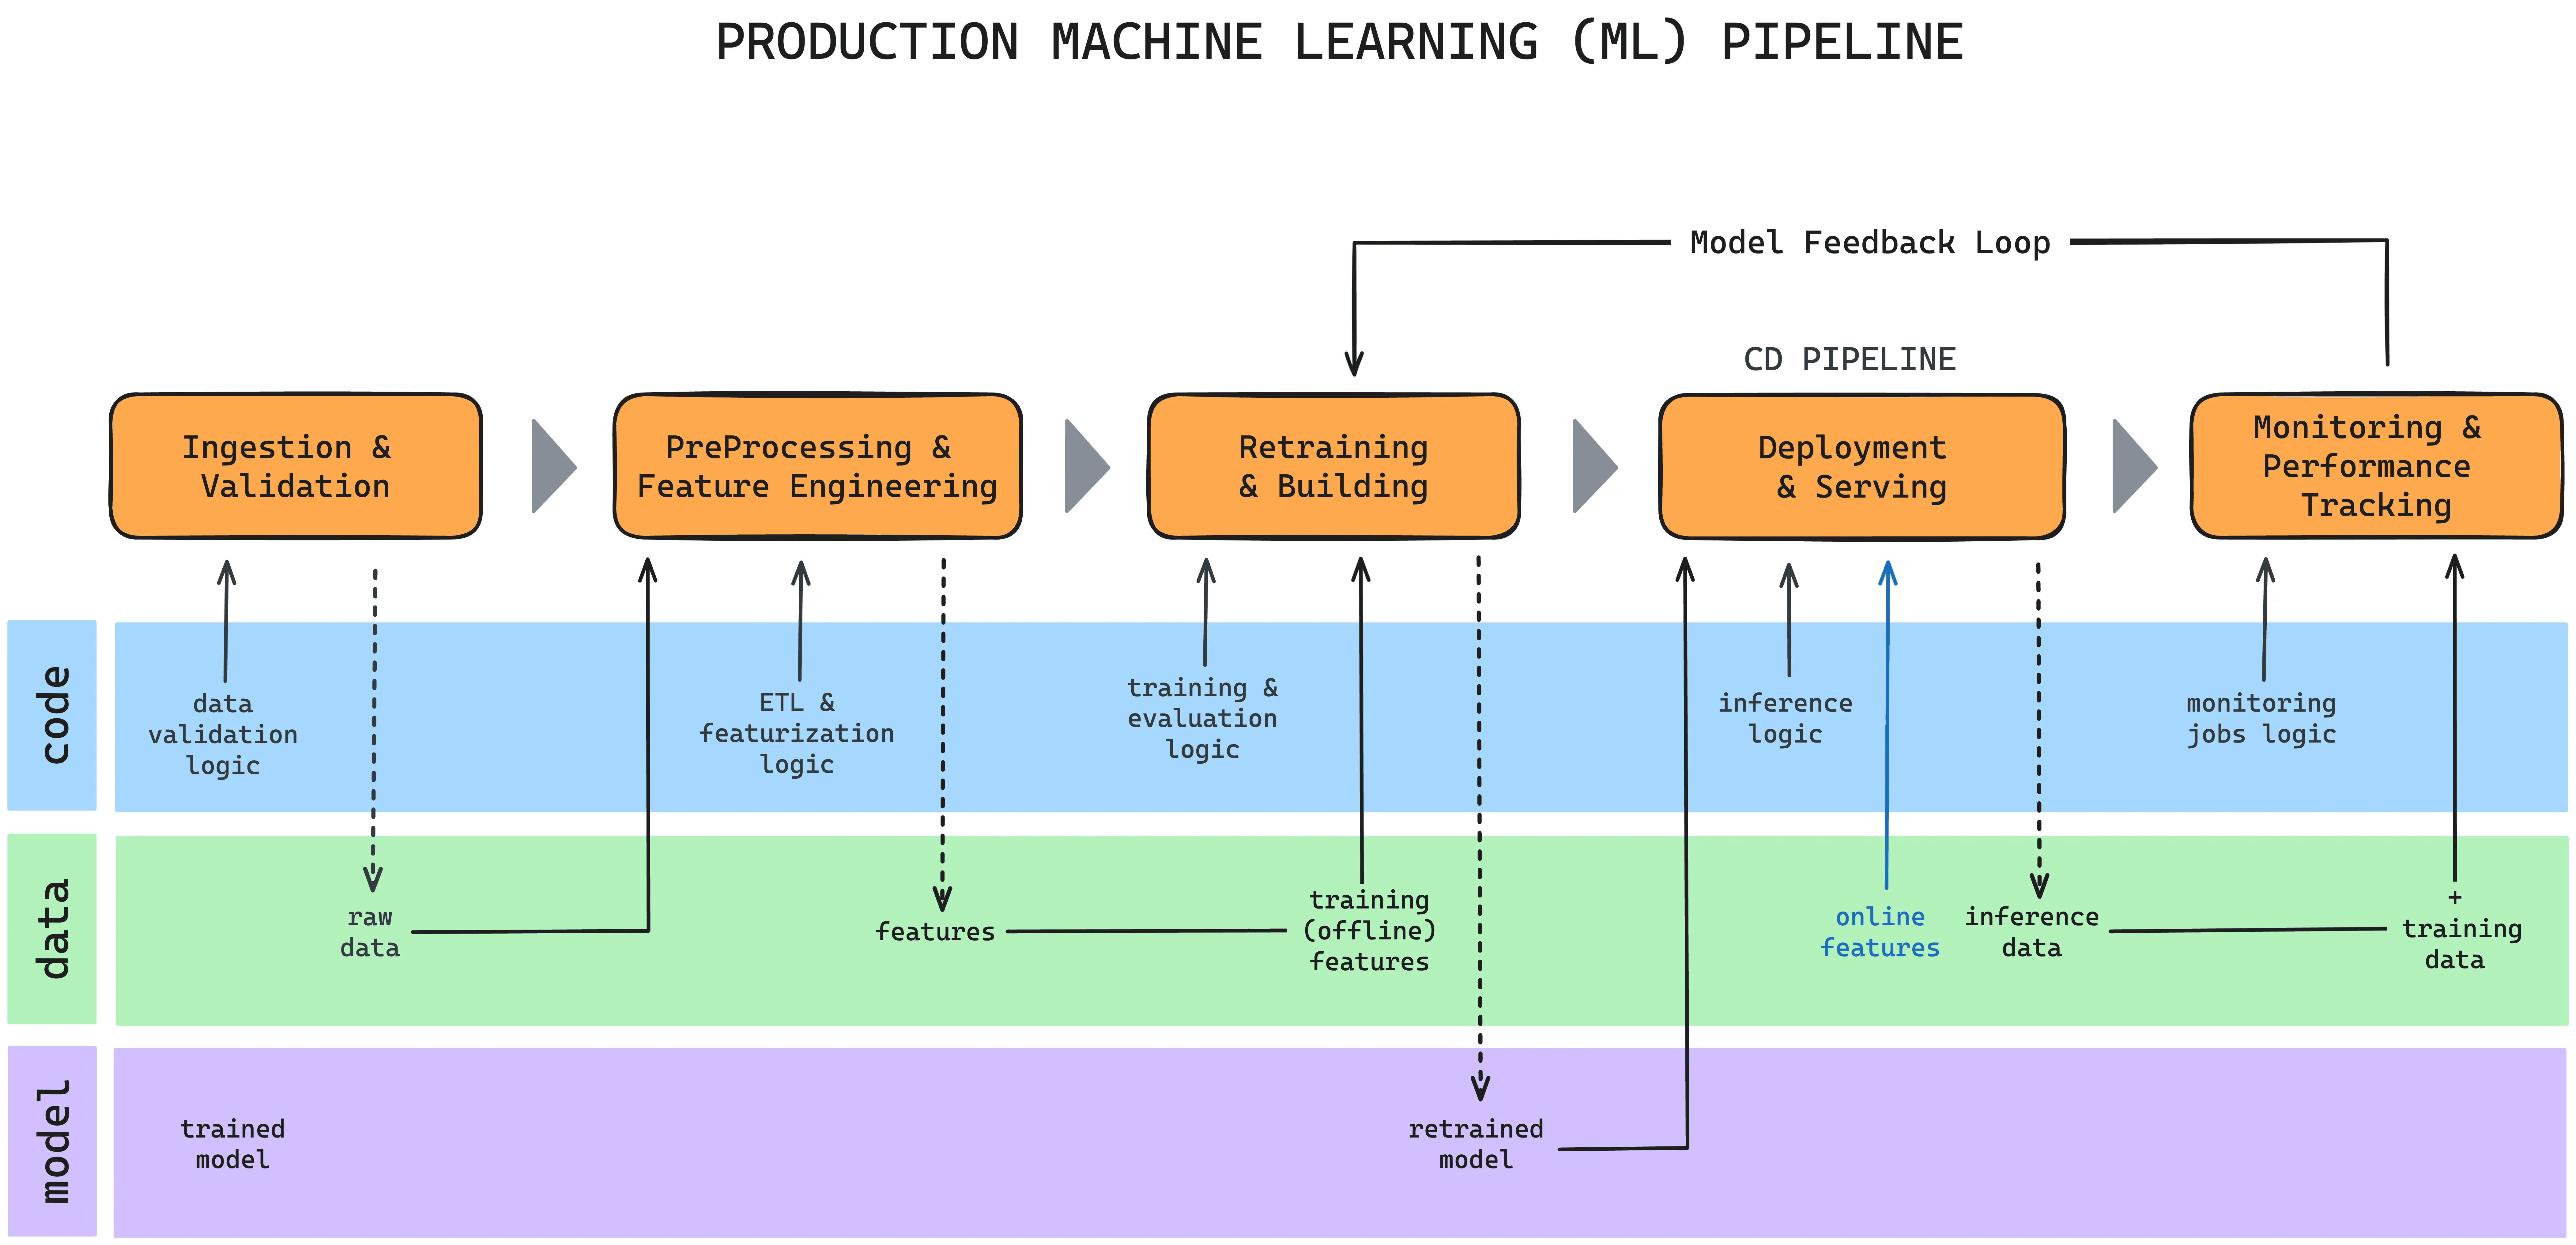
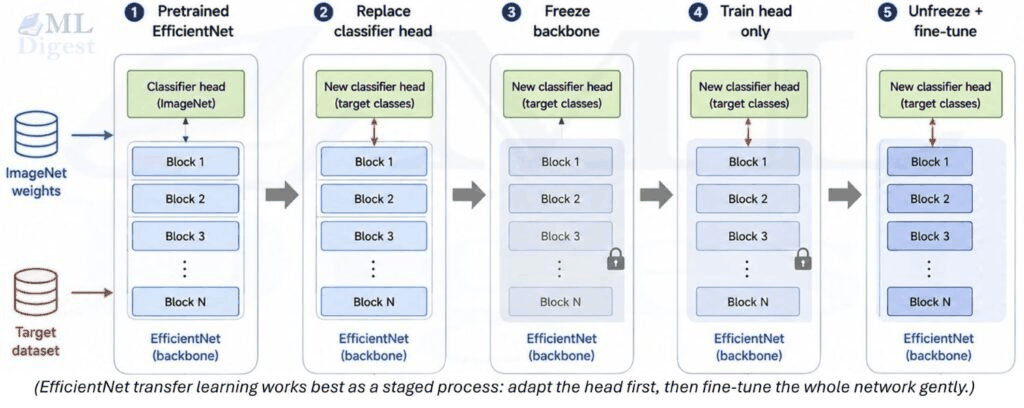
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)