Complete Technical Paper Content — Falcon Llm Projects
1. Executive Abstract, Problem Formulation & Background
A large language model (LLM) is a type of machine learning model designed for natural language processing tasks such as language generation. LLMs are language models with many parameters, and are trained with self-supervised learning on a vast amount of text.
The GGUF (GGML Universal File) file format is a binary file format that stores both tensors and metadata in a single file and is designed for fast saving and loading of model data. It was introduced in August 2023 by the llama.cpp project to better maintain backward compatibility as support was added for other model architectures. It superseded previous formats used by the project such as GGML and is typically produced by converting models developed with a different machine-learning library such as PyTorch. GGUF has become the standard format for distributing quantized large language models for local inference and is natively supported by tools such as llama.cpp, Ollama, LM Studio, GPT4All, Jan, and koboldcpp. As of 2026, tens of thousands of GGUF checkpoints are hosted on Hugging Face, which provides first-class integration, including a metadata viewer, an inference endpoint service, and a JavaScript parser library.
Self-contained — a single file holds the tensors, the tokenizer and all metadata needed to load and run the model, eliminating the need for accompanying configuration files. Memory-mappable — tensor data are aligned (by default to a 32-byte boundary) so that weights can be accessed directly through pointers without loading the entire file into RAM, allowing models larger than available memory to be served through operating-system paging. Extensible — the key–value metadata block lets new fields be added without breaking compatibility with older readers. GGUF supports 2-bit to 8-bit quantized integer types, common floating-point data formats such as float32, float16 and bfloat16, and 1.58-bit quantization. Several "K-quant" variants (such as Q4_K, Q5_K and Q6_K) use a block-based scheme with separate scale and minimum values per super-block, generally giving better quality at a given bit-width than the simpler legacy quantizations such as Q4_0 and Q8_0. GGUF contains the information necessary for running a GPT-like language model such as the tokenizer vocabulary, context length, tensor info and other attributes.
Prior to version 3, files were implicitly little-endian; version 3 permits big-endian storage but does not include a flag indicating endianness, so it must be inferred from context.
Falcon-LLM Helper scripts and examples for exploring the Falcon LLM models Overview of the model and use-cases: https://www.youtube.com/watch?v=-IV1NTGy6Mg Files: api_server.py - Run locally or in cloud. Should fully set up a proper web server if you intend to host on a public IP, this is using the basic flask demo web server. api_client.py - Make requests to the server. Makes R&D a lot easier if you can load and access the model separately, even if everything is on the same machine, so you're not re-loading the model every single time you make a change to your script. You can also use a notebook, but, depending on the complexity of your project, this might not be good enough. Falcon-40B-demo.ipynb - a short notebook example of loading Falcon 40B with options for various datatypes (4, 8, and 16bit). setup.sh - a quick shell script for setup of requirements that I used for Lambda H100 machines. ( chmod +x setup.sh & ./setup.sh
2. Related Work, Literature Survey & Algorithmic Foundations
Flock: Configurable ML Pipeline for Domain-Specific LLMs Flock is a versatile and configurable Machine Learning (ML) pipeline designed to build Language Model Models (LLMs) for domain-specific tasks. It offers support for popular LLM architectures such as wizardlm, bloom, falcon, and llama. The project also features a deep document mining system capable of extracting data from both text and images. Features Configurable ML pipeline for domain-specific Language Model Models (LLMs). Supports multiple LLM architectures: wizardlm, bloom, falcon, and llama. Deep document mining system for data extraction from text and images. Developed using Python, pdfMiner, langChain, and streamLit technologies. Installation Clone the repository: git clone https://github.com/yourusername/flock.git cd flock Install the required dependencies: pip install -r requirements.txt Run the Flock application: python app.py Usage Choose an LLM architecture: wizardlm, bloom, falcon, or llama. Configure the pipeline settings according to your domain-specific task. Prepare your text and image data for training and evaluation. Run the pipeline using the provided scripts. Evaluate the trained LLM and fine-tune as necessary. Action Plan Phase 1: Setup and Data Collection Set up the project repository with a basic directory structure. Create a virtual environment and install necessary dependencies. Implement data collection mechanisms for text and image data. Preprocess and clean the collected data for further processing. Phase 2: LLM Architecture Integration Integrate support for wizardlm architecture. Integrate support for bloom architecture. Integrate support for falcon architecture. Integrate support for llama architecture. Phase 3: Deep Document Mining System Implement a data extraction system for text documents. Implement a data extraction system for image documents. Develop mechanisms to combine text and image data for comprehensive analysis. Phase 4: Configuration and Pipeline Development Create a configuration interface for setting pipeline parameters. Develop the ML pipeline to train and evaluate LLMs based on selected architectures. Implement mechanisms for fine-tuning LLMs using domain-specific data. Phase 5: User Interface and Visualization Build a user-friendly interface using streamLit for interacting with the pipeline. Implement visualization tools to display training progress and evaluation metrics. Phase 6: Testing and Optimization Test the pipeline with sample domain-specific tasks and datasets. Optimize the pipeline for performance and efficiency. Identify and resolve any bugs or issues. Phase 7: Documentation and Deployment Write comprehensive documentation for setting up, using, and extending the pipeline. Prepare the repository for deployment, including proper version control and packaging. Contribution Contributions are welcome! If you'd like to contribute to Flock, please follow the guidelines in the CONTRIBUTING.md file. License This project is licensed under the MIT License .
Flock is a versatile and configurable Machine Learning (ML) pipeline designed to build Language Model Models (LLMs) for domain-specific tasks. It offers support for popular LLM architectures such as wizardlm, bloom, falcon, and llama. The project also features a deep document mining system capable of extracting data from both text and images.
Contributions are welcome! If you'd like to contribute to Flock, please follow the guidelines in the CONTRIBUTING.md file.
Craft custom Language Model Models (LLMs) effortlessly using Flock. Build LLMs for specific domains like a pro, supported by wizardlm, bloom, falcon, and llama. Extract insights from text and images seamlessly. Powered by Python, pdfMiner, langChain, and streamLit. Unlock domain-specific intelligence with Flock! 🚀
datasets tiiuae/falcon-refinedweb language en de es fr inference false 🚀 Falcon-40B Falcon-40B is a 40B parameters causal decoder-only model built by TII and trained on 1,000B tokens of RefinedWeb enhanced with curated corpora. It is made available under the TII Falcon LLM License . Paper coming soon 😊. Why use Falcon-40B? It is the best open-source model currently available. Falcon-40B outperforms LLaMA , StableLM , RedPajama , MPT , etc. See the OpenLLM Leaderboard . It features an architecture optimized for inference , with FlashAttention ( Dao et al., 2022 ) and multiquery ( Shazeer et al., 2019 ). It is made available under a license allowing commercial use , see the details of the TII Falcon LLM License below. ⚠️ This is a raw, pretrained model, which should be further finetuned for most usecases. If you are looking for a version better suited to taking generic instructions in a chat format, we recommend taking a look at Falcon-40B-Instruct . 💸 Looking for a smaller, less expensive model? Falcon-7B is Falcon-40B's small brother! from transformers import AutoTokenizer , AutoModelForCausalLM import transformers import torch model = "tiiuae/falcon-40b" tokenizer = AutoTokenizer . from_pretrained ( model ) pipeline = transformers . pipeline ( "text-generation" , model = model , tokenizer = tokenizer , torch_dtype = torch . bfloat16 , trust_remote_code = True , device_map = "auto" , ) sequences = pipeline ( "Girafatron is obsessed with giraffes, the most glorious animal on the face of this Earth. Giraftron believes all other animals are irrelevant when compared to the glorious majesty of the giraffe. \n Daniel: Hello, Girafatron! \n Girafatron:" , max_length = 200 , do_sample = True , top_k = 10 , num_return_sequences = 1 , eos_token_id = tokenizer . eos_token_id , ) for seq in sequences : print ( f"Result: { seq [ 'generated_text' ] } " ) 💥 Falcon LLMs require PyTorch 2.0 for use with transformers ! Model Card for Falcon-40B Model Details Model Description Developed by: https://www.tii.ae ; Model type: Causal decoder-only; Language(s) (NLP): English, German, Spanish, French (and limited capabilities in Italian, Portuguese, Polish, Dutch, Romanian, Czech, Swedish); License: TII Falcon LLM License . Model Source Paper: coming soon . Uses Direct Use Research on large language models; as a foundation for further specialization and finetuning for specific usecases (e.g., summarization, text generation, chatbot, etc.) Out-of-Scope Use Production use without adequate assessment of risks and mitigation; any use cases which may be considered irresponsible or harmful. Bias, Risks, and Limitations Falcon-40B is trained mostly on English, German, Spanish, French, with limited capabilities also in in Italian, Portuguese, Polish, Dutch, Romanian, Czech, Swedish. It will not generalize appropriately to other languages. Furthermore, as it is trained on a large-scale corpora representative of the web, it will carry the stereotypes and biases commonly encountered online. Recommendations We recommend users of Falcon-40B to consider finetuning it for the specific set of tasks of interest, and for guardrails and appropriate precautions to be taken for any production use. How to Get Started with the Model from transformers import AutoTokenizer , AutoModelForCausalLM import transformers import torch model = "tiiuae/falcon-40b" tokenizer = AutoTokenizer . from_pretrained ( model ) pipeline = transformers . pipeline ( "text-generation" , model = model , tokenizer = tokenizer , torch_dtype = torch . bfloat16 , trust_remote_code = True , device_map = "auto" , ) sequences = pipeline ( "Girafatron is obsessed with giraffes, the most glorious animal on the face of this Earth. Giraftron believes all other animals are irrelevant when compared to the glorious majesty of the giraffe. \n Daniel: Hello, Girafatron! \n Girafatron:" , max_length = 200 , do_sample = True , top_k = 10 , num_return_sequences = 1 , eos_token_id = tokenizer . eos_token_id , ) for seq in sequences : print ( f"Result: { seq [ 'generated_text' ] } " ) Training Details Training Data Falcon-40B was trained on 1,000B tokens of RefinedWeb , a high-quality filtered and deduplicated web dataset which we enhanced with curated corpora. Significant components from our curated copora were inspired by The Pile ( Gao et al., 2020 ). Data source Fraction Tokens Sources RefinedWeb-English 75% 750B massive web crawl RefinedWeb-Europe 7% 70B European massive zeb crawl Books 6% 60B Conversations 5% 50B Reddit, StackOverflow, HackerNews Code 5% 50B Technical 2% 20B arXiv, PubMed, UPSTO, etc. RefinedWeb-Europe is made of the following languages: Language Fraction of multilingual data Tokens German 26% 18B Spanish 24% 17B French 23% 16B Italian 7% 5B Portuguese 4% 3B Polish 4% 3B Dutch 4% 3B Romanian 3% 2B Czech 3% 2B Swedish 2% 1B The data was tokenized with the Falcon- 7B / 40B tokenizer. Training Procedure Falcon-40B was trained on 384 A100 40GB GPUs, using a 3D parallelism strategy (TP=8, PP=4, DP=12) combined with ZeRO. Training Hyperparameters Hyperparameter Value Comment Precision bfloat16 Optimizer AdamW Learning rate 1.85e-4 4B tokens warm-up, cosine decay to 1.85e-5 Weight decay 1e-1 Z-loss 1e-4 Batch size 1152 100B tokens ramp-up Speeds, Sizes, Times Training started in December 2022 and took two months. Evaluation Paper coming soon. See the OpenLLM Leaderboard for early results. Technical Specifications Model Architecture and Objective Falcon-40B is a causal decoder-only model trained on a causal language modeling task (i.e., predict the next token). The architecture is broadly adapted from the GPT-3 paper ( Brown et al., 2020 ), with the following differences: Positionnal embeddings: rotary ( Su et al., 2021 ); Attention: multiquery ( Shazeer et al., 2019 ) and FlashAttention ( Dao et al., 2022 ); Decoder-block: parallel attention/MLP with a two layer norms. For multiquery, we are using an internal variant which uses independent key and values per tensor parallel degree. Hyperparameter Value Comment Layers 60 d_model 8192 head_dim 64 Reduced to optimise for FlashAttention Vocabulary 65024 Sequence length 2048 Compute Infrastructure Hardware Falcon-40B was trained on AWS SageMaker, on 384 A100 40GB GPUs in P4d instances. Software Falcon-40B was trained a custom distributed training codebase, Gigatron. It uses a 3D parallelism approach combined with ZeRO and high-performance Triton kernels (FlashAttention, etc.) Citation Paper coming soon 😊. License Falcon-40B is made available under the TII Falcon LLM License . Broadly speaking, You can freely use our models for research and/or personal purpose; You are allowed to share and build derivatives of these models, but you are required to give attribution and to share-alike with the same license; For commercial use, you are exempt from royalties payment if the attributable revenues are inferior to $1M/year, otherwise you should enter in a commercial agreement with TII. Contact falconllm@tii.ae
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Falcon-40B is a 40B parameters causal decoder-only model built by TII and trained on 1,000B tokens of RefinedWeb enhanced with curated corpora. It is made available under the TII Falcon LLM License .
⚠️ This is a raw, pretrained model, which should be further finetuned for most usecases. If you are looking for a version better suited to taking generic instructions in a chat format, we recommend taking a look at Falcon-40B-Instruct .
💸 Looking for a smaller, less expensive model? Falcon-7B is Falcon-40B's small brother!
from transformers import AutoTokenizer , AutoModelForCausalLM import transformers import torch model = "tiiuae/falcon-40b" tokenizer = AutoTokenizer . from_pretrained ( model ) pipeline = transformers . pipeline ( "text-generation" , model = model , tokenizer = tokenizer , torch_dtype = torch . bfloat16 , trust_remote_code = True , device_map = "auto" , ) sequences = pipeline ( "Girafatron is obsessed with giraffes, the most glorious animal on the face of this Earth. Giraftron believes all other animals are irrelevant when compared to the glorious majesty of the giraffe. \n Daniel: Hello, Girafatron! \n Girafatron:" , max_length = 200 , do_sample = True , top_k = 10 , num_return_sequences = 1 , eos_token_id = tokenizer . eos_token_id , ) for seq in sequences : print ( f"Result: { seq [ 'generated_text' ] } " )
Research on large language models; as a foundation for further specialization and finetuning for specific usecases (e.g., summarization, text generation, chatbot, etc.)
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Production use without adequate assessment of risks and mitigation; any use cases which may be considered irresponsible or harmful.
Falcon-40B is trained mostly on English, German, Spanish, French, with limited capabilities also in in Italian, Portuguese, Polish, Dutch, Romanian, Czech, Swedish. It will not generalize appropriately to other languages. Furthermore, as it is trained on a large-scale corpora representative of the web, it will carry the stereotypes and biases commonly encountered online.
We recommend users of Falcon-40B to consider finetuning it for the specific set of tasks of interest, and for guardrails and appropriate precautions to be taken for any production use.
from transformers import AutoTokenizer , AutoModelForCausalLM import transformers import torch model = "tiiuae/falcon-40b" tokenizer = AutoTokenizer . from_pretrained ( model ) pipeline = transformers . pipeline ( "text-generation" , model = model , tokenizer = tokenizer , torch_dtype = torch . bfloat16 , trust_remote_code = True , device_map = "auto" , ) sequences = pipeline ( "Girafatron is obsessed with giraffes, the most glorious animal on the face of this Earth. Giraftron believes all other animals are irrelevant when compared to the glorious majesty of the giraffe. \n Daniel: Hello, Girafatron! \n Girafatron:" , max_length = 200 , do_sample = True , top_k = 10 , num_return_sequences = 1 , eos_token_id = tokenizer . eos_token_id , ) for seq in sequences : print ( f"Result: { seq [ 'generated_text' ] } " )
Falcon-40B was trained on 1,000B tokens of RefinedWeb , a high-quality filtered and deduplicated web dataset which we enhanced with curated corpora. Significant components from our curated copora were inspired by The Pile ( Gao et al., 2020 ).
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Falcon-40B was trained on 384 A100 40GB GPUs, using a 3D parallelism strategy (TP=8, PP=4, DP=12) combined with ZeRO.
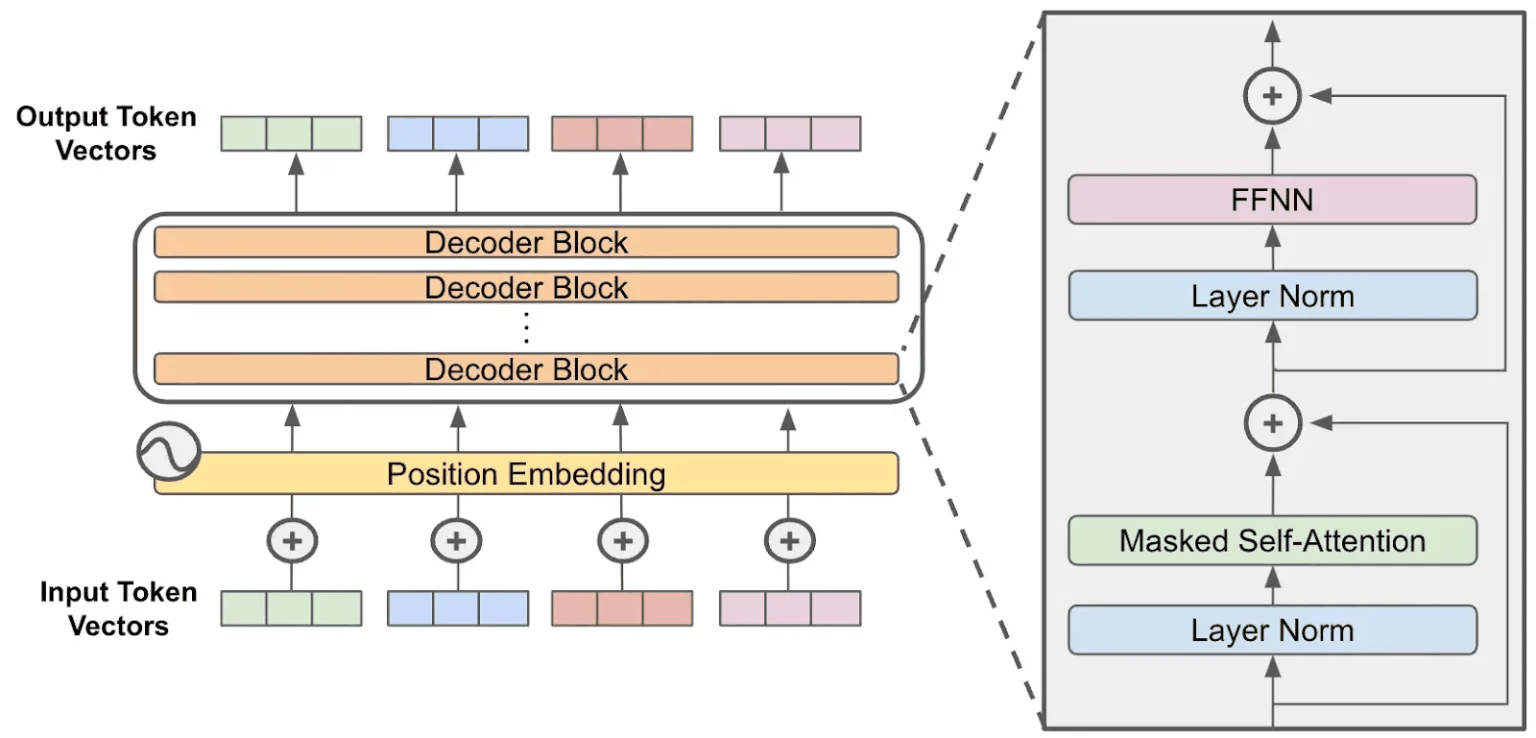
Falcon-40B is a causal decoder-only model trained on a causal language modeling task (i.e., predict the next token).
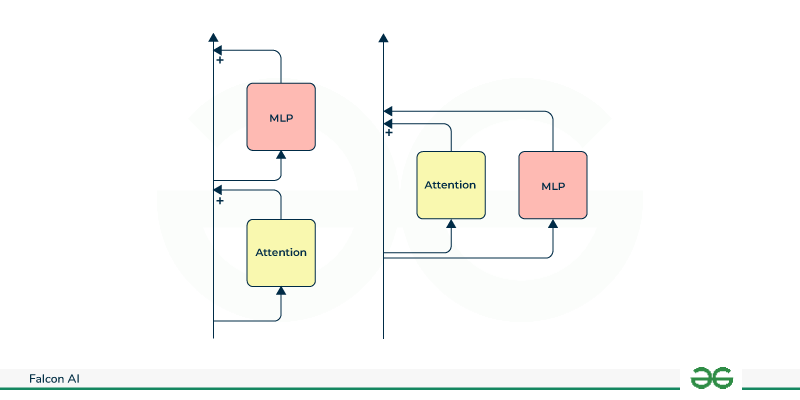
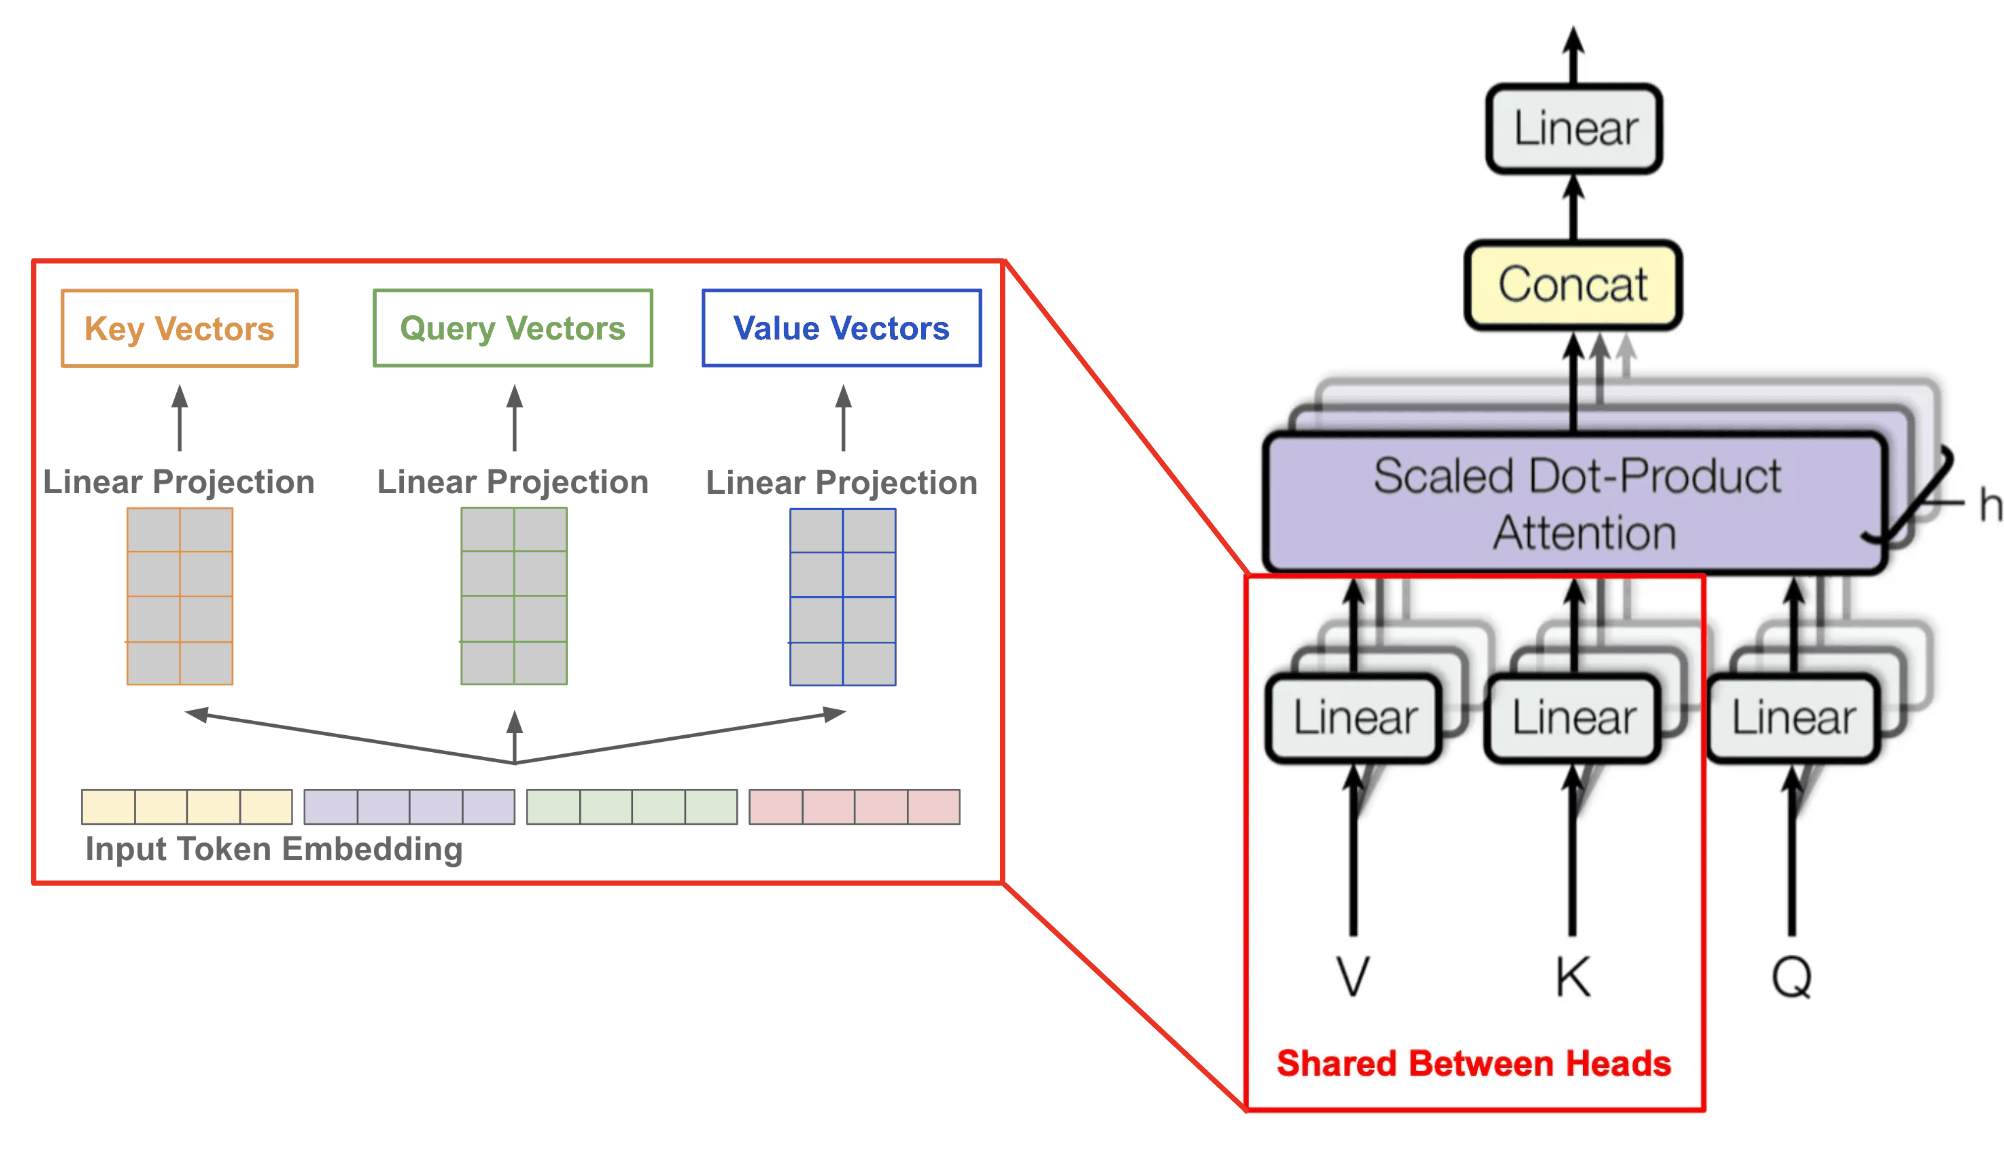
The architecture is broadly adapted from the GPT-3 paper ( Brown et al., 2020 ), with the following differences:
For multiquery, we are using an internal variant which uses independent key and values per tensor parallel degree.
Falcon-40B was trained a custom distributed training codebase, Gigatron. It uses a 3D parallelism approach combined with ZeRO and high-performance Triton kernels (FlashAttention, etc.)
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)