Complete Technical Paper Content — Few Shot Learning Projects
1. Executive Abstract, Problem Formulation & Background
Easy Few-Shot Learning Ready-to-use code and tutorial notebooks to boost your way into few-shot image classification. This repository is made for you if: you're new to few-shot learning and want to learn; or you're looking for reliable, clear and easily usable code that you can use for your projects. Don't get lost in large repositories with hundreds of methods and no explanation on how to use them. Here, we want each line of code to be covered by a tutorial. What's in there? Notebooks: learn and practice You want to learn few-shot learning and don't know where to start? Start with our tutorials. Notebook Description Colab First steps into few-shot image classification Basically Few-Shot Learning 101, in less than 15min. Example of episodic training Use it as a starting point if you want to design a script for episodic training using EasyFSL. Example of classical training Use it as a starting point if you want to design a script for classical training using EasyFSL. Test with pre-extracted embeddings Most few-shot methods use a frozen backbone at test-time. With EasyFSL, you can extract all embeddings for your dataset once and for all, and then perform inference directly on embeddings. Code that you can use and understand State-Of-The-Art Few-Shot Learning methods: With 11 built-in methods, EasyFSL is the most comprehensive open-source Few-Shot Learning library! Prototypical Networks SimpleShot Matching Networks Relation Networks FEAT Fine-Tune BD-CSPN LaplacianShot Transductive Information Maximization PT-MAP Transductive Fine-Tuning We also provide a FewShotClassifier class to quickstart your implementation of any few-shot classification algorithm, as well as commonly used architectures . See the benchmarks section below for more details on the methods. Tools for data loading: Data loading in FSL is a bit different from standard classification because we sample batches of instances in the shape of few-shot classification tasks. No sweat! In EasyFSL you have: TaskSampler : an extension of the standard PyTorch Sampler object, to sample batches in the shape of few-shot classification tasks FewShotDataset : an abstract class to standardize the interface of any dataset you'd like to use EasySet : a ready-to-use FewShotDataset object to handle datasets of images with a class-wise directory split WrapFewShotDataset : a wrapper to transform any dataset into a FewShotDataset object FeaturesDataset : a dataset to handle pre-extracted features SupportSetFolder : a dataset to handle support sets stored in a directory Scripts to reproduce our benchmarks: scripts/predict_embeddings.py to extract all embeddings from a dataset with a given pre-trained backbone scripts/benchmark_methods.py to evaluate a method on a test dataset using pre-extracted embeddings. And also: some utilities that I felt I often used in my research, so I'm sharing with you. Datasets to test your model There are enough datasets used in Few-Shot Learning for anyone to get lost in them. They're all here, explicited, downloadable and easy-to-use, in EasyFSL. CU-Birds We provide a make download-cub recipe to download and extract the dataset, along with the standard (train / val / test) split along classes. Once you've downloaded the dataset, you can instantiate the Dataset objects in your code with this super complicated process: from easyfsl . datasets import CUB train_set = CUB ( split = "train" , training = True ) test_set = CUB ( split = "test" , training = False ) tieredImageNet To use it, you need the ILSVRC2015 dataset. Once you have downloaded and extracted the dataset, ensure that its localisation on disk is consistent with the class paths specified in the specification files . Then: from easyfsl . datasets import TieredImageNet train_set = TieredImageNet ( split = "train" , training = True ) test_set = TieredImageNet ( split = "test" , training = False ) miniImageNet Same as tieredImageNet, we provide the specification files , but you need the ILSVRC2015 dataset. Once you have it: from easyfsl . datasets import MiniImageNet train_set = MiniImageNet ( root = "where/imagenet/is" , split = "train" , training = True ) test_set = MiniImageNet ( root = "where/imagenet/is" , split = "test" , training = False ) Since miniImageNet is relatively small, you can also load it on RAM directly at instantiation simply by adding load_on_ram=True to the constructor. It takes a few minutes but it can make your training significantly faster! Danish Fungi I've recently started using it as a Few-Shot Learning benchmarks, and I can tell you it's a great playing field. To use it, first download the data: # Download the original dataset (/!\ 110GB) wget http://ptak.felk.cvut.cz/plants/DanishFungiDataset/DF20-train_val.tar.gz # Or alternatively the images reduced to 300px (6.5Gb) wget http://ptak.felk.cvut.cz/plants/DanishFungiDataset/DF20-300px.tar.gz # And finally download the metadata (83Mb) to data/fungi/ wget https://public-sicara.s3.eu-central-1.amazonaws.com/easy-fsl/DF20_metadata.csv -O data/fungi/DF20_metadata.csv And then instantiate the dataset with the same process as always: from easyfsl . datasets import DanishFungi dataset = DanishFungi ( root = "where/fungi/is" ) Note that I didn't specify a train and test set because the CSV I gave you describes the whole dataset. I recommend to use it to test models with weights trained on an other dataset (like ImageNet). But if you want to propose a train/val/test split along classes, you're welcome to contribute! QuickStart Install the package: pip install easyfsl or simply fork the repository. Download your data . Design your training and evaluation scripts. You can use our example notebooks for episodic training or classical training . Contribute This project is very open to contributions! You can help in various ways: raise issues resolve issues already opened tackle new features from the roadmap fix typos, improve code quality Benchmarks We used EasyFSL to benchmark a dozen methods. Inference times are computed over 1000 tasks using pre-extracted features. They are only indicative. Note that the inference time for fine-tuning methods highly depends on the number of fine-tuning steps. All methods hyperparameters are defined in this JSON file . They were selected on miniImageNet validation set. The procedure can be reproduced with make hyperparameter-search . We decided to use miniImageNet's hyperparameters for all benchmarks in order to highlight the adaptability of the different methods. Note that all methods use L2 normalization of features, except for FEAT as it harms its performance. There are no results for Mathing and Relation Networks as the trained weights for their additional modules are unavailable. miniImageNet & tieredImageNet All methods use the same backbone: a custom ResNet12 using the trained parameters provided by the authors from FEAT (download: miniImageNet , tieredImageNet ). Best inductive and best transductive results for each column are shown in bold. Method Ind / Trans mini Imagenet 1-shot mini Imagenet 5-shot tiered Imagenet 1-shot tiered Imagenet 5-shot Time ProtoNet Inductive 63.6 80.4 60.2 77.4 6s SimpleShot Inductive 63.6 80.5 60.2 77.4 6s MatchingNet Inductive - - - - - RelationNet Inductive - - - - - Finetune Inductive 63.3 80.5 59.8 77.5 1mn33s FEAT Inductive 64.7 80.1 61.3 76.2 3s BD-CSPN Transductive 69.8 82.2 66.3 79.1 7s LaplacianShot Transductive 69.8 82.3 66.2 79.2 9s PT-MAP Transductive 76.1 84.2 71.7 80.7 39mn40s TIM Transductive 74.3 84.2 70.7 80.7 3mn05s Transductive Finetuning Transductive 63.0 80.6 59.1 77.5 30s To reproduce: Download the mini ImageNet and tieredImageNet weights for ResNet12 and save them under data/models/feat_resnet12_mini_imagenet.pth (resp. tiered ). Extract all embeddings from the test sets of all datasets with make extract-all-features-with-resnet12 . Run the evaluation scripts with make benchmark-mini-imagenet (resp. tiered ).
Ready-to-use code and tutorial notebooks to boost your way into few-shot image classification. This repository is made for you if:
Don't get lost in large repositories with hundreds of methods and no explanation on how to use them. Here, we want each line of code to be covered by a tutorial.
You want to learn few-shot learning and don't know where to start? Start with our tutorials.
With 11 built-in methods, EasyFSL is the most comprehensive open-source Few-Shot Learning library!
We also provide a FewShotClassifier class to quickstart your implementation of any few-shot classification algorithm, as well as commonly used architectures .
Data loading in FSL is a bit different from standard classification because we sample batches of instances in the shape of few-shot classification tasks. No sweat! In EasyFSL you have:
And also: some utilities that I felt I often used in my research, so I'm sharing with you.
There are enough datasets used in Few-Shot Learning for anyone to get lost in them. They're all here, explicited, downloadable and easy-to-use, in EasyFSL.
We provide a make download-cub recipe to download and extract the dataset, along with the standard (train / val / test) split along classes. Once you've downloaded the dataset, you can instantiate the Dataset objects in your code with this super complicated process:
from easyfsl . datasets import CUB train_set = CUB ( split = "train" , training = True ) test_set = CUB ( split = "test" , training = False )
To use it, you need the ILSVRC2015 dataset. Once you have downloaded and extracted the dataset, ensure that its localisation on disk is consistent with the class paths specified in the specification files . Then:
from easyfsl . datasets import TieredImageNet train_set = TieredImageNet ( split = "train" , training = True ) test_set = TieredImageNet ( split = "test" , training = False )
Same as tieredImageNet, we provide the specification files , but you need the ILSVRC2015 dataset. Once you have it:
from easyfsl . datasets import MiniImageNet train_set = MiniImageNet ( root = "where/imagenet/is" , split = "train" , training = True ) test_set = MiniImageNet ( root = "where/imagenet/is" , split = "test" , training = False )
Since miniImageNet is relatively small, you can also load it on RAM directly at instantiation simply by adding load_on_ram=True to the constructor. It takes a few minutes but it can make your training significantly faster!
I've recently started using it as a Few-Shot Learning benchmarks, and I can tell you it's a great playing field. To use it, first download the data:
# Download the original dataset (/!\ 110GB) wget http://ptak.felk.cvut.cz/plants/DanishFungiDataset/DF20-train_val.tar.gz # Or alternatively the images reduced to 300px (6.5Gb) wget http://ptak.felk.cvut.cz/plants/DanishFungiDataset/DF20-300px.tar.gz # And finally download the metadata (83Mb) to data/fungi/ wget https://public-sicara.s3.eu-central-1.amazonaws.com/easy-fsl/DF20_metadata.csv -O data/fungi/DF20_metadata.csv
from easyfsl . datasets import DanishFungi dataset = DanishFungi ( root = "where/fungi/is" )
Note that I didn't specify a train and test set because the CSV I gave you describes the whole dataset. I recommend to use it to test models with weights trained on an other dataset (like ImageNet). But if you want to propose a train/val/test split along classes, you're welcome to contribute!
Design your training and evaluation scripts. You can use our example notebooks for episodic training or classical training .
We used EasyFSL to benchmark a dozen methods. Inference times are computed over 1000 tasks using pre-extracted features. They are only indicative. Note that the inference time for fine-tuning methods highly depends on the number of fine-tuning steps.
2. Related Work, Literature Survey & Algorithmic Foundations
All methods hyperparameters are defined in this JSON file . They were selected on miniImageNet validation set. The procedure can be reproduced with make hyperparameter-search . We decided to use miniImageNet's hyperparameters for all benchmarks in order to highlight the adaptability of the different methods. Note that all methods use L2 normalization of features, except for FEAT as it harms its performance.
There are no results for Mathing and Relation Networks as the trained weights for their additional modules are unavailable.
All methods use the same backbone: a custom ResNet12 using the trained parameters provided by the authors from FEAT (download: miniImageNet , tieredImageNet ).
Ready-to-use code and tutorial notebooks to boost your way into few-shot learning for image classification.
Few-Shot-and-Zero-Shot-Learning-Techniques Introduction This repository is dedicated to exploring and implementing few-shot and zero-shot learning approaches, two advanced machine learning techniques that handle the challenges of limited labeled data. Few-shot learning: A method where models learn to make predictions with only a few labeled examples. This is especially helpful when gathering large, unusable, or expensive datasets. Zero-shot learning: This method allows models to perform tasks without seeing examples of the task or class. Instead, the model generalizes knowledge from similar tasks or semantic relationships, enabling it to recognize and act on unseen categories. This repository aims to provide implementations, tutorials, and insights into leveraging these methods for real-world applications. By using meta-learning, transfer learning, and large pre-trained models, we strive to develop strong solutions for scenarios with limited data. Features Implementations of state-of-the-art few-shot and zero-shot learning algorithms. Preprocessing pipelines for data preparation and feature extraction. Ready-to-use scripts for model training, evaluation, and hyperparameter tuning. For example, notebooks apply these techniques to real-world tasks. Performance comparisons between traditional machine learning models and few-shot/zero-shot models. Getting Started Follow these steps to get started with the repository: Prerequisites Before running the code, ensure you have the following installed: Python 3.8 or later PyTorch or TensorFlow (depending on the model you plan to use) Additional libraries as listed in the requirements.txt file Installation Clone the repository: bash git clone https://github.com/MohammadMaftoun/Few-Shot-and-Zero-Shot-Learning-Techniques.git cd few-shot-zero-shot-learning Install dependencies: bash pip install -r requirements.txt Set up environment (optional but recommended): Use virtual environments to isolate dependencies: bash python -m venv venv source venv/bin/activate # for Unix/Mac venv\Scripts\activate # for Windows Usage Training a Few-Shot Model To train a few-shot learning model on your dataset: bash python train_few_shot.py --dataset --model Example: bash python train_few_shot.py --dataset miniImageNet --model ProtoNet Zero-Shot Learning Example For a zero-shot learning task, use the following command: bash python zero_shot.py --model --task Example: bash python zero_shot.py --model CLIP --task image-classification Datasets You can use various open-source datasets to experiment with few-shot and zero-shot learning. Below are some popular datasets included in this repository: MiniImageNet: A benchmark dataset for few-shot classification. CIFAR-FS: A few-shot learning variant of CIFAR-100. Omniglot: For evaluating the performance of few-shot learning models. Custom Datasets: Instructions on how to add your datasets are provided. Model Architectures This repository implements and experiments with several few-shot and zero-shot learning models, including: ProtoNet (Prototypical Networks for Few-Shot Learning) RelationNet (Relation Networks for Few-Shot Learning) MAML (Model-Agnostic Meta-Learning) CLIP (Contrastive Language-Image Pretraining for Zero-Shot Learning) GPT-3 (Zero-shot language understanding) Results and Benchmarks We provide a detailed comparison of few-shot and zero-shot learning techniques on various datasets. The repository includes: Performance metrics such as accuracy, precision, recall, and F1-score. Analysis of how each model generalizes to new, unseen tasks. Hyperparameter tuning strategies and their impact on model performance. Contributing Contributions are welcome! If you would like to improve this repository, please follow the steps below: Fork the repository. Create a new branch (git checkout -b feature-branch). Commit your changes (git commit -am 'Add new feature'). Push the branch (git push origin feature branch). Open a pull request. GitHub Repository Address Find the repository here: https://github.com/MohammadMaftoun/Few-Shot-and-Zero-Shot-Learning-Techniques
This repository is dedicated to exploring and implementing few-shot and zero-shot learning approaches, two advanced machine learning techniques that handle the challenges of limited labeled data.
Few-shot learning: A method where models learn to make predictions with only a few labeled examples. This is especially helpful when gathering large, unusable, or expensive datasets. Zero-shot learning: This method allows models to perform tasks without seeing examples of the task or class. Instead, the model generalizes knowledge from similar tasks or semantic relationships, enabling it to recognize and act on unseen categories.
This repository aims to provide implementations, tutorials, and insights into leveraging these methods for real-world applications. By using meta-learning, transfer learning, and large pre-trained models, we strive to develop strong solutions for scenarios with limited data.
Implementations of state-of-the-art few-shot and zero-shot learning algorithms. Preprocessing pipelines for data preparation and feature extraction. Ready-to-use scripts for model training, evaluation, and hyperparameter tuning. For example, notebooks apply these techniques to real-world tasks. Performance comparisons between traditional machine learning models and few-shot/zero-shot models.
Python 3.8 or later PyTorch or TensorFlow (depending on the model you plan to use) Additional libraries as listed in the requirements.txt file
git clone https://github.com/MohammadMaftoun/Few-Shot-and-Zero-Shot-Learning-Techniques.git cd few-shot-zero-shot-learning
python -m venv venv source venv/bin/activate # for Unix/Mac venv\Scripts\activate # for Windows
You can use various open-source datasets to experiment with few-shot and zero-shot learning. Below are some popular datasets included in this repository:
MiniImageNet: A benchmark dataset for few-shot classification. CIFAR-FS: A few-shot learning variant of CIFAR-100. Omniglot: For evaluating the performance of few-shot learning models. Custom Datasets: Instructions on how to add your datasets are provided.
This repository implements and experiments with several few-shot and zero-shot learning models, including:
ProtoNet (Prototypical Networks for Few-Shot Learning) RelationNet (Relation Networks for Few-Shot Learning) MAML (Model-Agnostic Meta-Learning) CLIP (Contrastive Language-Image Pretraining for Zero-Shot Learning) GPT-3 (Zero-shot language understanding)
We provide a detailed comparison of few-shot and zero-shot learning techniques on various datasets. The repository includes:
Performance metrics such as accuracy, precision, recall, and F1-score. Analysis of how each model generalizes to new, unseen tasks. Hyperparameter tuning strategies and their impact on model performance.
Contributions are welcome! If you would like to improve this repository, please follow the steps below:
Fork the repository. Create a new branch (git checkout -b feature-branch). Commit your changes (git commit -am 'Add new feature'). Push the branch (git push origin feature branch). Open a pull request.
Find the repository here: https://github.com/MohammadMaftoun/Few-Shot-and-Zero-Shot-Learning-Techniques
This repository is dedicated to exploring and implementing few-shot and zero-shot learning techniques.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
After running pilots with several annotation providers, Label Your Data delivered the strongest results by a clear margin, standing out on turnaround time, annotation quality, and the responsiveness of their feedback loops.
Public datasets don’t fit custom use cases, and collecting thousands of labeled examples per class isn’t realistic for most ML teams.
Few shot learning (FSL) trains machine learning models to classify from minimal examples by learning patterns across many small tasks rather than memorizing one large dataset.
This guide explains metric-based, optimization-based, and transfer learning approaches with real performance benchmarks and when to use each method.
Few-shot learning AI trains models to generalize from 1-10 labeled examples per class by extracting transferable representations across related tasks.
For example, instead of showing a model thousands of dog images and thousands of cat images until it learns to distinguish them, FSL meta-trains on hundreds of small classification tasks, teaching the model how to learn classification or image recognition patterns in general.
Common benchmarks include 5-way 1-shot (5 classes, 1 example each) and 5-way 5-shot (5 classes, 5 examples each).
One shot vs few shot learning differs in K value: one-shot uses K=1 (single example per class), while few-shot typically uses K=5-10 examples per class for improved accuracy.
Episode-based training simulates test conditions by sampling random N-way K-shot tasks during training. Each iteration picks N random classes and K examples per class. The model sees thousands of these small tasks, learning the general pattern of how to solve them rather than memorizing specific classes.
Meta-train and meta-test classes are completely separate. Training uses 64 ImageNet categories, testing uses 20 different categories ( standard miniImageNet split ). This tests real generalization, not memorization.
Custom use cases rarely fit public datasets. You need classification for proprietary products, specialized defect types, or domain-specific categories.
Collecting and labeling thousands of examples per class can take months and require a significant data annotation budget.
Few-shot learning becomes necessary for inherently rare events where examples don’t exist at scale. Or privacy-constrained scenarios where data can't be shared or pooled. And constantly evolving categories where waiting months for new data isn't viable.
Also, while data annotation pricing for thousands of examples per class can be substantial, FSL reduces volume requirements significantly. Yet, this makes expert data annotation providers practical and cost-effective for specialized domains.
According to Parnami & Lee's survey of few-shot learning techniques and approaches, these methods achieve 68-81% accuracy on standard benchmarks with just 5 examples per class.
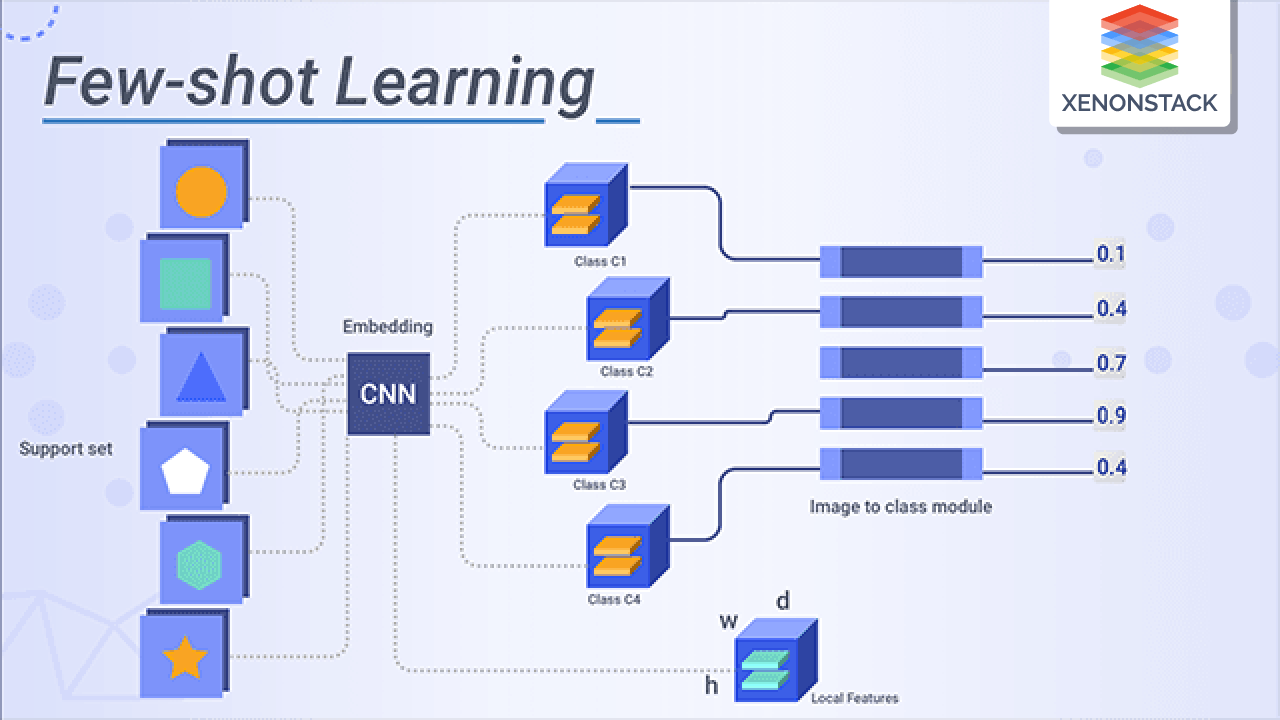
Metric-based approaches learn an embedding space where similar examples cluster together, then classify queries by measuring distance to support set examples. No gradient updates happen at test time, making inference fast.
Prototypical networks compute a prototype for each class by averaging support set embeddings, then classify queries by Euclidean distance to prototypes. This achieved 68.2% on miniImageNet 5-way 5-shot.
TADAM improves on this by making embeddings task-specific. Bird classification needs texture features, car classification needs shape features. TADAM uses task embeddings to modulate which features matter, achieving 76.7% on miniImageNet 5-way 5-shot.
SimpleShot showed something surprising: using a pre-trained ResNet with L2 normalization and nearest centroid classification achieves 81.5% on the same benchmark without any meta-training.
If you have a good pre-trained encoder for your domain, this baseline often works better than complex meta-learning.
Optimization-based methods learn initialization parameters that enable rapid fine-tuning to new tasks via a few gradient steps. You continue training on the support set rather than freezing the model.
MAML finds model parameters that adapt quickly when fine-tuned on new tasks. It uses two nested optimization loops:
4. Neural Network Backbone, Layer Specifications & Loss Formulations
MAML achieved 63.1% on miniImageNet 5-way 5-shot. The method works across vision, NLP, and robotics, but requires gradient computation at test time, making inference slower than metric-based approaches.
LEO addresses MAML’s limitation with deep networks. Fine-tuning millions of parameters from 5 examples causes overfitting. LEO optimizes in a low-dimensional latent space instead, then decodes to full parameters, achieving 77.6% on miniImageNet 5-way 5-shot.
Meta-transfer learning combines pre-training with meta-learning. Pre-train a deep network on base classes, freeze most layers as a feature extractor, then meta-learn only the final classifier.
This balances sophistication with simplicity, making it practical for production systems.
Recent research we mentioned earlier showed simple transfer learning can match complex meta-learning on standard benchmarks. The approach looks like this:
This works because ImageNet features already capture texture, shape, and color patterns. Transfer learning succeeds when you have pre-trained models for similar domains and test classes resemble training classes visually.
However, it fails with large domain shifts or when no suitable pre-trained model exists.
The machine learning algorithm you choose depends on whether you have pre-trained models available, can tolerate slow inference, and need maximum accuracy versus simplicity.
Start with SimpleShot if you have a pre-trained model. Move to TADAM for metric-based meta-learning if transfer learning underperforms. Use LEO only when you need maximum accuracy with deep networks and can tolerate implementation complexity.
Few shot learning image classification is widely used in manufacturing quality assurance for rare defect detection where new defect types emerge faster than you can collect thousands of examples.
Medical imaging applies FSL when rare diseases have limited confirmed cases. Satellite monitoring uses FSL for time-sensitive detection of events like oil spills where labeled data are sparse but detection speed matters.
Retail companies classify new product arrivals weekly without retraining entire catalog classifiers, handling long-tail SKUs that appear infrequently.
Chatbot platforms use FSL to add new intents from few example utterances without full retraining. Text classification achieves results comparable to fine-tuning on thousands of examples by using sentence transformers with contrastive learning on fewer than 10 examples per class.
Recommendation systems handle cold-start items where user interaction data is naturally limited. Robotics enables learning new manipulation tasks from single demonstrations by meta-learning across related tasks.
FSL models trained on natural images drop significantly in accuracy when tested on completely different domains like medical scans or satellite imagery . Meta-learning learns domain-specific patterns, so what works for natural images doesn't transfer to specialized domains without domain-specific pre-training.
Training on 5-way 5-shot but testing on 10-way 1-shot causes accuracy drops. Models overfit to specific N and K values during meta-training. If you know test conditions (always 3 defect types, always 10 examples), train on exactly that. If conditions vary, train on diverse task configurations.
With thousands of examples, label noise averages out. With 5 examples, a single mislabeled support example significantly degrades accuracy.
For specialized domains, crowdsourced annotation introduces too much noise for FSL to handle effectively. Medical imaging, satellite analysis, and manufacturing QA need trained annotation teams like Label Your Data who understand subtle inter-class boundaries.
As an alternative option, using data annotation tools with quality control workflows helps catch errors early as well.
Which 5 examples you annotate directly impacts performance. Diversity matters more than redundancy.
Bad support set: 5 similar poses, same background, same lighting. Model learns background patterns instead of class features.
Good support set: Different poses, backgrounds, lighting conditions. Forces model to extract invariant features.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Beyond selecting existing examples strategically, synthetic data generation can complement few-shot learning by augmenting limited support sets.
But keep in mind that synthetic examples work best when combined with real annotated data rather than replacing it entirely.
Few-shot learning reduces annotation volume but increases quality requirements. The smaller the support set, the more each annotation error impacts your model performance.
Multi-annotator consensus workflows where 3 annotators label the same support examples and only unanimous agreements are kept costs more but proves worthwhile because support set quality determines FSL success.
Pre-annotation with foundation models like CLIP can generate candidate labels ranked by confidence, allowing human reviewers to verify rather than label from scratch, significantly reducing annotation time when the foundation model has reasonable zero-shot performance on your domain.
Working with a data-compliant data annotation company experienced in computer vision ensures annotators understand all these subtle inter-class boundaries.
Computer vision specialization in satellite imagery, 3D LiDAR , medical imaging, and manufacturing QA requires annotators who understand domain-specific patterns.
Generic crowdsourced workers miss subtle inter-class boundaries that matter for classification accuracy.
Experienced teams delivering high-quality data annotation services , such as Label Your Data, can identify diverse, representative support examples rather than just labeling provided data.
For specialized domains, strategic sample selection combined with high-quality annotation often matters more than the meta-learning algorithm choice.
Our team at Label Your Data provides expert annotation for computer vision optimized for few-shot learning AI workflows. You can rest assured that our annotators understand meta-learning requirements for satellite image annotation, 3D LiDAR object detection, and specialized computer vision domains where support set quality determines production success.
Standard machine learning datasets for FSL benchmarking include miniImageNet, Omniglot, and tieredImageNet.
miniImageNet is the standard benchmark with 100 ImageNet classes split into 64 train, 16 validation, 20 test classes. Most papers report results here. Use this to validate your implementation before moving to custom data.
Omniglot contains handwritten characters from 50 alphabets, serving as an easier benchmark for validating implementations.
tieredImageNet provides hierarchical class structure ensuring train and test classes are semantically distant, making it harder than miniImageNet and better for testing generalization.
If baseline accuracy is high, transfer learning might suffice. If it’s moderate, FSL will help significantly. If it's very low, classes may not be separable from these features.
Validate on miniImageNet before training on custom data. If your implementation doesn't reach published benchmarks on miniImageNet, it won't work on custom data.
Collect strategically with 5-10 carefully selected examples per class for support sets and 20-50 examples per class for validation. Also, use active learning loops:
Plus, monitor meta-overfitting by tracking accuracy on both meta-train and meta-validation classes. If train accuracy increases while validation plateaus, reduce learning rate, use more meta-training classes, or add regularization.
Move to metric-based meta-learning (Prototypical Networks, TADAM) if transfer learning underperforms and you need fast inference. Use optimization-based methods (MAML, LEO) only when maximizing accuracy with deep networks justifies implementation complexity.
FSL reduces annotation volume significantly but increases quality requirements. With 5 examples, each label matters. Strategic sample selection, multi-annotator consensus, and expert annotation for specialized domains become necessary rather than optional.
For production computer vision in various domains, our dedicated teams at Label Your Data provide expert annotation support optimized for few-shot learning.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)