Complete Technical Paper Content — Gpt Projects
1. Executive Abstract, Problem Formulation & Background
Generative Pre-trained Transformer 3 (GPT-3) was a large language model released by OpenAI in 2020 as part of the company's GPT series of models. Like its predecessor, GPT-2, it is a decoder-only transformer model of deep neural network, which supersedes recurrence and convolution-based architectures with a technique known as "attention". This attention mechanism allows the model to focus selectively on segments of input text it predicts to be most relevant. GPT-3 has 175 billion parameters, each with 16-bit precision, requiring 350GB of storage since each parameter occupies 2 bytes. It has a context window size of 2,048 tokens, and has demonstrated strong "zero-shot" and "few-shot" learning abilities on many tasks. On September 22, 2020, Microsoft announced that it had licensed GPT-3 exclusively. Others can still receive output from its public API, but only Microsoft has access to the underlying model.
On May 28, 2020, an arXiv preprint by a group of 31 engineers and researchers at OpenAI described the achievement and development of GPT-3, a third-generation "state-of-the-art language model". The team increased the capacity of GPT-3 by over two orders of magnitude from that of its predecessor, GPT-2, making GPT-3 the largest non-sparse language model at that time. Because GPT-3 is structurally similar to its predecessors, its greater accuracy is attributed to its increased capacity and greater number of parameters. GPT-3's capacity is ten times larger than that of Microsoft's Turing NLG, the next largest NLP model known at the time. Lambdalabs estimated a hypothetical cost of around $4.6 million US dollars and 355 years to train GPT-3 on a single GPU in 2020, with lower actual training time by using more GPUs in parallel. Sixty percent of the weighted pre-training dataset for GPT-3 comes from a filtered version of Common Crawl consisting of 410 billion byte-pair-encoded tokens. Fuzzy deduplication used Apache Spark's MinHashLSH. Other sources are 19 billion tokens from WebText2 representing 22% of the weighted total, 12 billion tokens from Books1 representing 8%, 55 billion tokens from Books2 representing 8%, and 3 billion tokens from Wikipedia representing 3%. GPT-3 was trained on hundreds of billions of words and is also capable of coding in CSS, JSX, and Python, among others.
Since GPT-3's training data was all-encompassing, it does not require further training for distinct language tasks. The training data contains occasional toxic language and GPT-3 occasionally generates toxic language as a result of mimicking its training data. A study from the University of Washington found that GPT-3 produced toxic language at a toxicity level comparable to the similar natural language processing models of GPT-2 and CTRL. OpenAI has implemented several strategies to limit the amount of toxic language generated by GPT-3. As a result, GPT-3 produced less toxic language compared to its predecessor model, GPT-1, although it produced both more generations and a higher toxicity of toxic language compared to CTRL Wiki, a language model trained entirely on Wikipedia data. On June 11, 2020, OpenAI announced that users could request access to its user-friendly GPT-3 API—a "machine learning toolset"—to help OpenAI "explore the strengths and limits" of this new technology. The invitation described how this API had a general-purpose "text in, text out" interface that can complete almost "any English language task", instead of the usual single use-case. According to one user, who had access to a private early release of the OpenAI GPT-3 API, GPT-3 was "eerily good" at writing "amazingly coherent text" with only a few simple prompts. In an initial experiment 80 US subjects were asked to judge if short ~200 word articles were written by humans or GPT-3. The participants judged correctly 52% of the time, doing only slightly better than random guessing. On November 18, 2021, OpenAI announced that enough safeguards had been implemented that access to its API would be unrestricted. OpenAI provided developers with a content moderation tool that helps them abide by OpenAI's content policy. On January 27, 2022, OpenAI announced that its newest GPT-3 language models (collectively referred to as InstructGPT) were now the default language model used on their API. According to OpenAI, InstructGPT produced content that was better aligned to user intentions by following instructions better, generating fewer made-up facts, and producing somewhat less toxic content. Because GPT-3 can "generate news articles which human evaluators have difficulty distinguishing from articles written by humans," GPT-3 has the "potential to advance both the beneficial and harmful applications of language models." In their May 28, 2020 paper, the researchers described in detail the potential "harmful effects of GPT-3" which include "misinformation, spam, phishing, abuse of legal and governmental processes, fraudulent academic essay writing and social engineering pretexting". The authors draw attention to these dangers to call for research on risk mitigation. GPT-3 is capable of performing zero-shot and few-shot learning (including one-shot). In June 2022, Almira Osmanovic Thunström wrote that GPT-3 was the primary author on an article on itself, that they had submitted it for publication, and that it had been pre-published while waiting for completion of its review.
Half of the models are accessible through the API, namely GPT-3-medium, GPT-3-xl, GPT-3-6.7B and GPT-3-175b, which are referred to as ada, babbage, curie and davinci respectively. While the size of the API models was not originally disclosed by OpenAI, EleutherAI announced the mapping between model sizes and API names in May 2021. These model sizes were later confirmed by OpenAI, but the sizes of subsequent models have not been disclosed.
GPT Image is a series of image generation and editing models developed by OpenAI. A text-to-image variant of the GPT family, it uses deep learning methodologies to generate digital images from natural language descriptions or images precisely. As the successor to DALL-E, GPT Image is native to ChatGPT as ChatGPT Images and available through the API. Upon release in March 2025, GPT Image went viral on social media, particularly for its capability of generating images in the style of Studio Ghibli. GPT Image is also available with Microsoft Copilot and Apple Intelligence as well.
The first model of GPT Image was revealed by OpenAI as the "GPT-4o image generation" in a blog post on March 25, 2025, developed based on the GPT-4o model to generate images. It was initially made available to only paid users, with the rollout to free users delayed due to high demands. The use of the feature was subsequently limited, with Sam Altman saying that the GPUs were "melting" from the level of use. OpenAI later said that over 130 million users around the world had created more than 700 million images in the first week. The model was named as GPT Image 1 (gpt-image-1) and introduced to the API on April 23. A cost-efficient version was released as GPT Image 1 Mini (gpt-image-1-mini) on October 6, also OpenAI DevDay 2025, with the cost in the API 80% less expensive than GPT Image 1. A new model named GPT Image 1.5 (gpt-image-1.5) was introduced on December 16, which was rolled out globally as the "ChatGPT Images" to all users and immediately made available via the API. OpenAI claimed that the new model can make precise edits while keeping details intact, and generates images up to four times faster. Image inputs and outputs in the API are 20% cheaper in GPT Image 1.5 as compared to GPT Image 1. In April 2026, OpenAI released GPT Image 2 (gpt-image-2) which introduced a reasoning model into their generation. GPT Image 2.5 was released on September 8, 2026. The model introduced a Sketch feature that allows users to turn their drawings into an AI image, and the latency of the image generation decreased by 50%. Two versions were released on the API, one called Flare (gpt-image-2.5/flare), designed to be quicker while maintaining some quality and Sunburst (gpt-image-2.5/sunburst) is designed to be more detailed at the expense of taking more time.
Upon the launch of GPT Image 1 in March 2025, photographs recreated in the style of Studio Ghibli films went viral. Sam Altman acknowledged the trend by changing his Twitter profile picture into a Studio Ghibli-inspired one. In response to the trend, many commentators referred to Ghibli director Hayao Miyazaki's previous negative comments on AI art. Some creative professionals, including animator Alex Hirsch, criticized Altman for profiting from Studio Ghibli's work. North American distributor GKids indirectly commented on the trend, alluding to "a time when technology tries to replicate humanity" in a press release for the re-release of the 1997 Studio Ghibli film Princess Mononoke. The White House's official Twitter account posted a Ghibli-style image mocking the arrest by immigration authorities of Virginia Basora-Gonzalez, a migrant from the Dominican Republic, which shows her crying as an immigration officer places her in handcuffs.
ChatGPT Images 2.0 OpenAI image models - including GPT Image 1, 1.5 and 2 4o ImageGen - the official custom GPT for GPT Image 1
2. Related Work, Literature Survey & Algorithmic Foundations
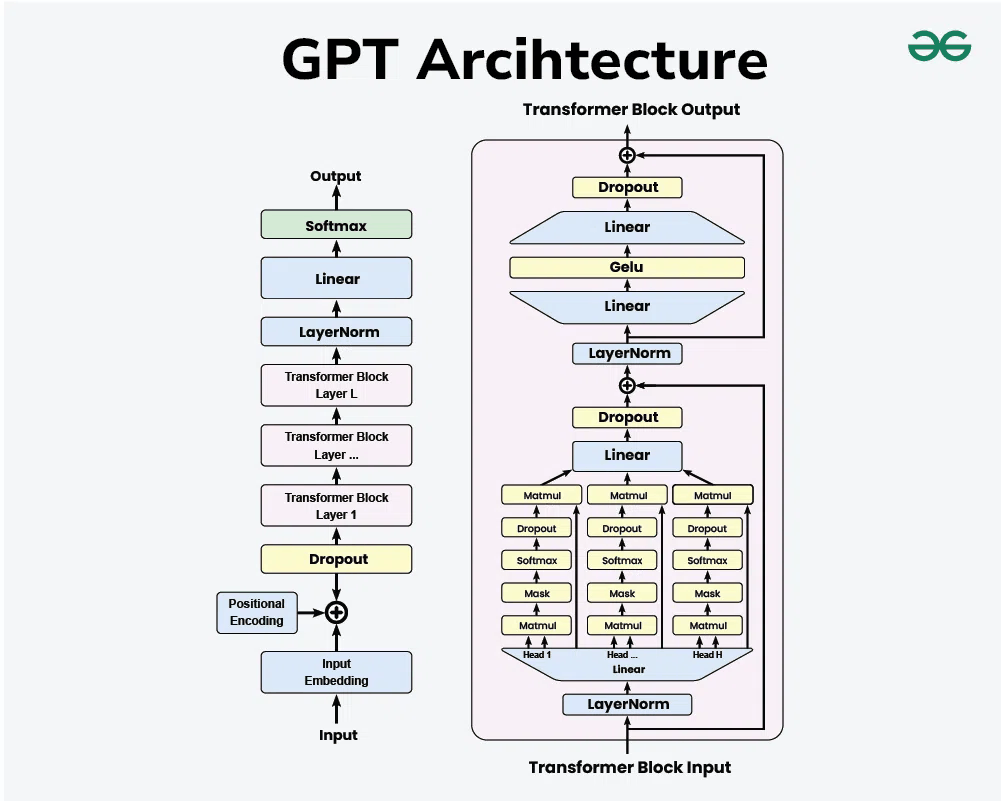
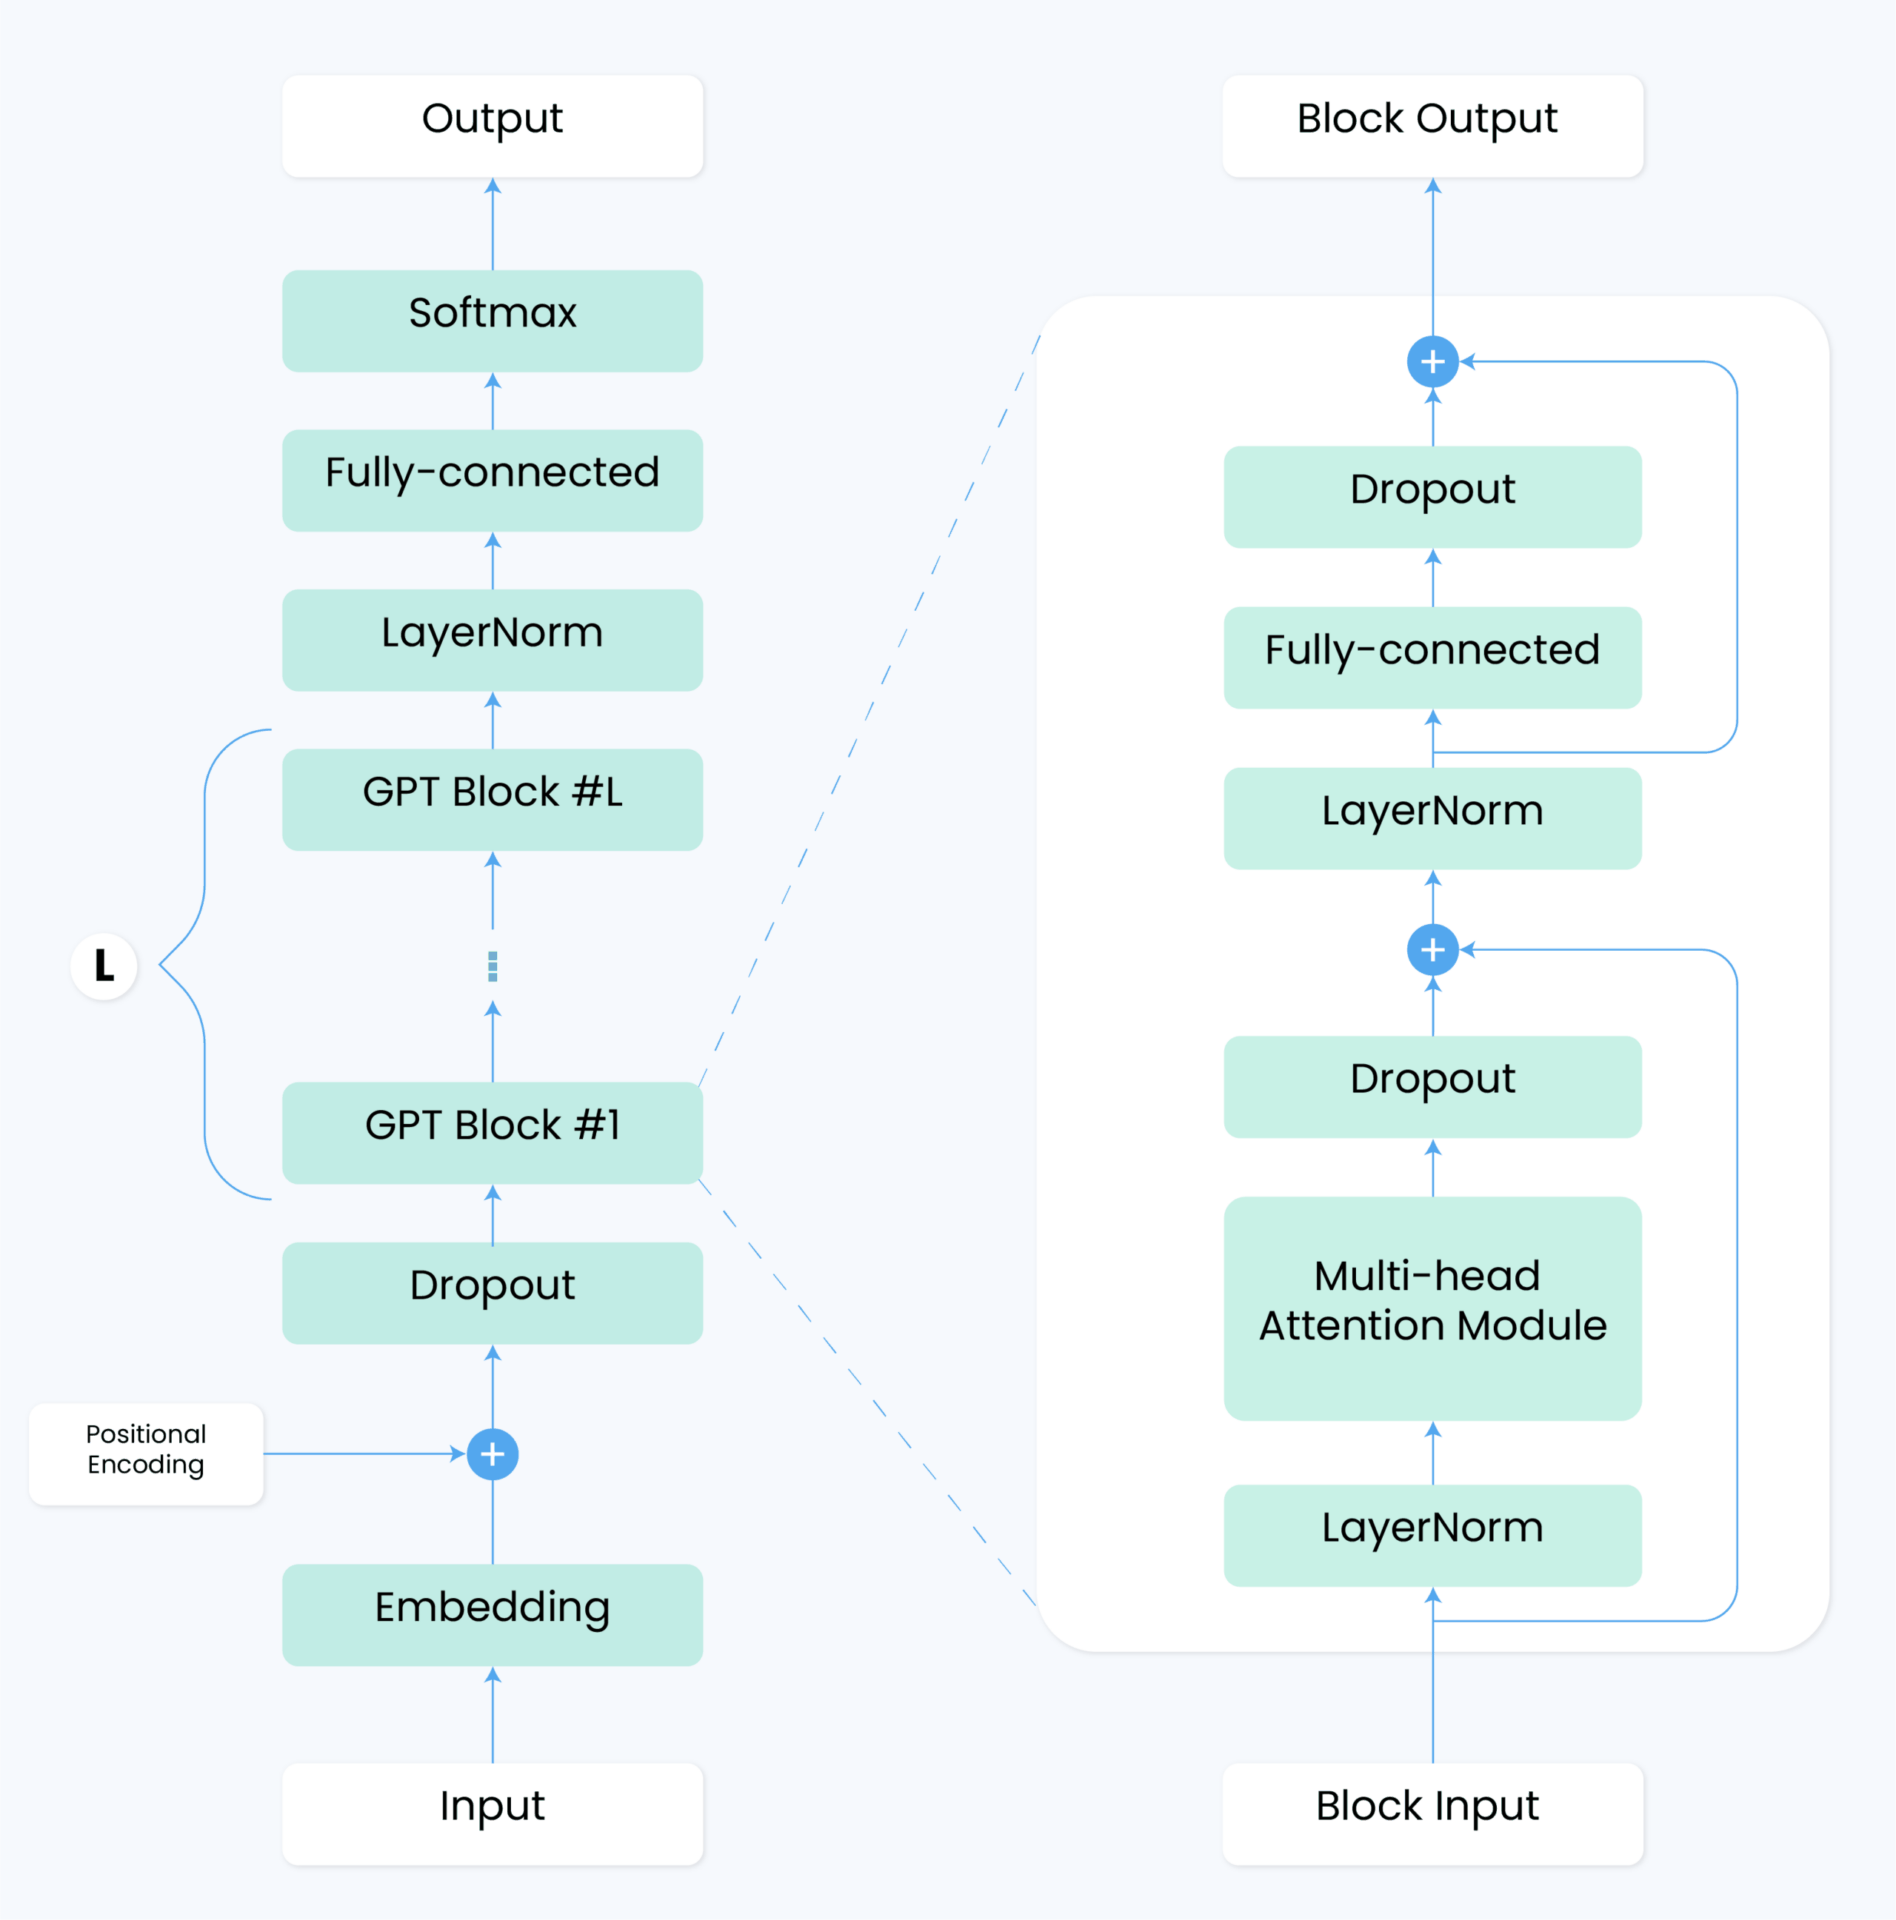
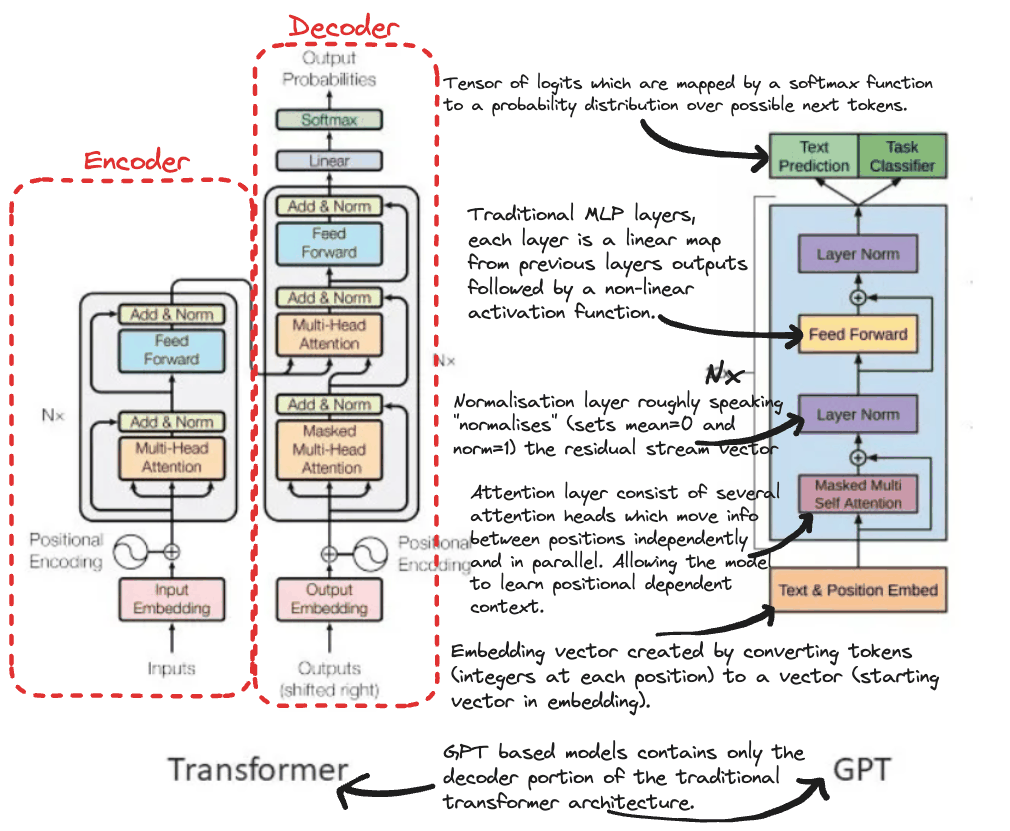
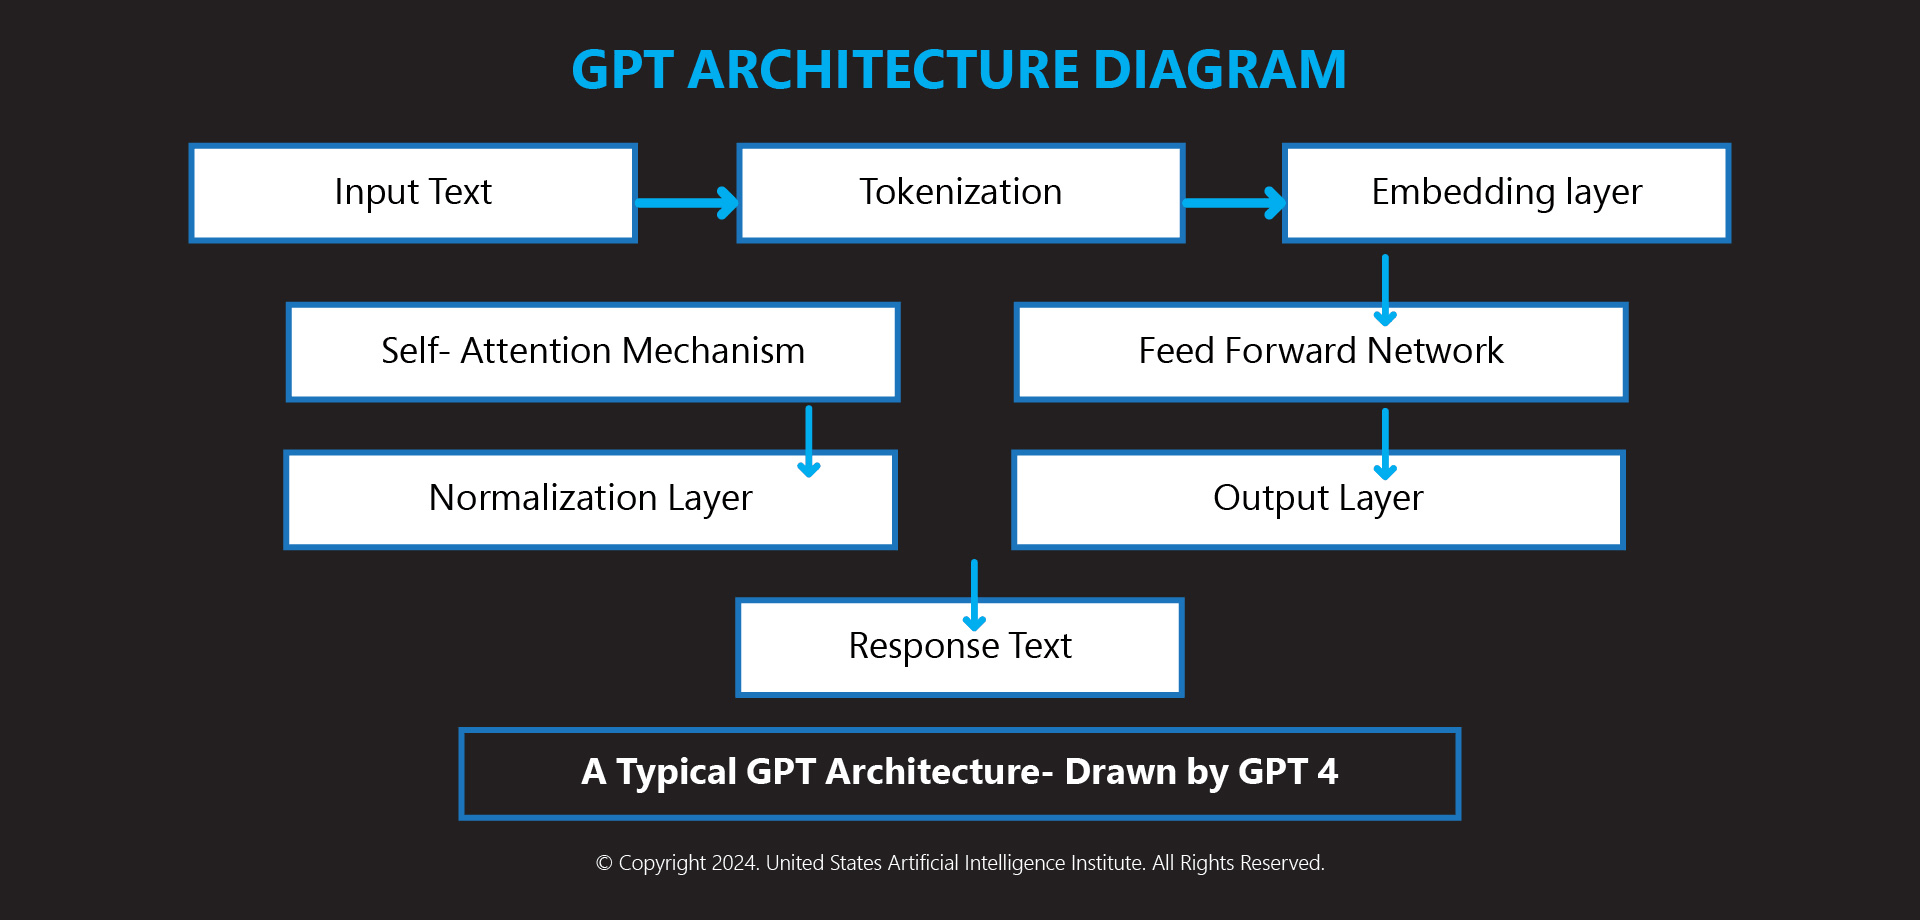
🤖 GPT Series Deep Learning Models Explanation 🎯 Introduction This repository aims to provide a comprehensive and intuitive explanation of the deep learning model architecture underlying OpenAI's GPT series of language models, including GPT-4, GPT-3, GPT-2, and the original GPT. Based on the Transformer model, these architectures are complex, and understanding them can be quite challenging. Here, we break down the process into its constituent parts using a sentence example "The dog bit the man". 🚀 GPT Series and Transformer Architecture The GPT series of models, including GPT-4, GPT-3, GPT-2, and the original GPT, are based on the Transformer architecture and follow a similar design philosophy. The main differences among these models lie in the scale (number of model parameters) and training data. Let's take a closer look at the steps involved in the Transformer architecture. 🧩 Transformer Architecture: A Closer Look The Transformer architecture is the backbone of the GPT models and represents a significant breakthrough in Natural Language Processing. It addresses the limitations of sequential processing in recurrent neural networks by enabling parallelization and capturing dependencies regardless of their distance in the input sequence. Here, we dive into the steps involved in this innovative architecture: Embedding Layer : the initial step in the Transformer architecture is the transformation of each word into a unique vector representation. This allows the model to process the input text numerically: "The" --> [⚫] "dog" --> [🐶] "bit" --> [🦷] "the" --> [⚫] "man" --> [👨] Positional Encoding : to preserve the sequence information intrinsic to language, position information is added to each word vector: "The (1)" --> [⚫1️⃣] "dog (2)" --> [🐶2️⃣] "bit (3)" --> [🦷3️⃣] "the (4)" --> [⚫4️⃣] "man (5)" --> [👨5️⃣] Multi-Head Attention : this step involves determining the dependencies between each word and the others in the sentence. The connections (—) between words represent these dependencies, with the thickness of the connection indicating the degree of dependency: "The (1)" —— "dog (2)" ——— "bit (3)" —— "the (4)" —— "man (5)" Feedforward Network : the feedforward network can be visualized as a funnel (🔽) that processes and refines the information from each word: "The (1)" ——🔽—— "dog (2)" ——🔽—— "bit (3)" ——🔽—— "the (4)" ——🔽—— "man (5)" Layer Normalization and Residual Connection : balancing the information from each word is achieved through mechanisms similar to sliders (🔲🔳): "The (1)" ——🚫🔲🔳—— "dog (2)" ——🔽🔲🔳—— "bit (3)" ——🔽🔲🔳—— "the (4)" ——🔽🔲🔳—— "man (5)" Output Layer : the culmination of the process is the output layer, where the model predicts the next word in the sentence based on the learned information. For example, given the sentence "The dog bit the man," the model might suggest the word "injured" (🩹): "The dog bit the man" ——> "injured (🩹)" This detailed examination of the Transformer architecture sheds light on the intricate processes that empower the GPT series to generate contextually relevant and creative text. 📊 GPT Model Parameters One of the significant differences between each GPT model is the number of parameters: 🎈 GPT (Original): 117M parameters 🎈🎈 GPT-2: 1.5B parameters 🎈🎈🎈 GPT-3: 175B parameters 🎈🎈🎈🎈 GPT-4: 100T (trillion) parameters These models' increasing complexity correlates with their ability to understand and generate increasingly nuanced text. 📚 Why this Repository? Understanding the Transformer architecture and deep learning models like the GPT series can be a complex process. This repository's goal is to distill these complexities into more comprehensible units, thereby allowing enthusiasts, students, and even seasoned developers to get a clear understanding of how these models function. 📖 Further Reading We encourage interested readers to delve deeper into the fascinating world of language models. To that end, here are a few resources: Attention is All You Need - The original Transformer paper by Vaswani et al. The Illustrated Transformer - A highly recommended blog post with clear explanations and helpful diagrams. OpenAI's GPT-2 Paper - This paper provides further insights into the use of Transformer architecture in language models. Thank you for visiting this repository! Feel free to contribute and expand on this basic explanation.
This repository aims to provide a comprehensive and intuitive explanation of the deep learning model architecture underlying OpenAI's GPT series of language models, including GPT-4, GPT-3, GPT-2, and the original GPT. Based on the Transformer model, these architectures are complex, and understanding them can be quite challenging. Here, we break down the process into its constituent parts using a sentence example "The dog bit the man".
The GPT series of models, including GPT-4, GPT-3, GPT-2, and the original GPT, are based on the Transformer architecture and follow a similar design philosophy. The main differences among these models lie in the scale (number of model parameters) and training data. Let's take a closer look at the steps involved in the Transformer architecture.
The Transformer architecture is the backbone of the GPT models and represents a significant breakthrough in Natural Language Processing. It addresses the limitations of sequential processing in recurrent neural networks by enabling parallelization and capturing dependencies regardless of their distance in the input sequence. Here, we dive into the steps involved in this innovative architecture:
Embedding Layer : the initial step in the Transformer architecture is the transformation of each word into a unique vector representation. This allows the model to process the input text numerically:
Positional Encoding : to preserve the sequence information intrinsic to language, position information is added to each word vector:
Multi-Head Attention : this step involves determining the dependencies between each word and the others in the sentence. The connections (—) between words represent these dependencies, with the thickness of the connection indicating the degree of dependency:
Feedforward Network : the feedforward network can be visualized as a funnel (🔽) that processes and refines the information from each word:
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Layer Normalization and Residual Connection : balancing the information from each word is achieved through mechanisms similar to sliders (🔲🔳):
Output Layer : the culmination of the process is the output layer, where the model predicts the next word in the sentence based on the learned information. For example, given the sentence "The dog bit the man," the model might suggest the word "injured" (🩹):
This detailed examination of the Transformer architecture sheds light on the intricate processes that empower the GPT series to generate contextually relevant and creative text.
One of the significant differences between each GPT model is the number of parameters:
These models' increasing complexity correlates with their ability to understand and generate increasingly nuanced text.
Understanding the Transformer architecture and deep learning models like the GPT series can be a complex process. This repository's goal is to distill these complexities into more comprehensible units, thereby allowing enthusiasts, students, and even seasoned developers to get a clear understanding of how these models function.
We encourage interested readers to delve deeper into the fascinating world of language models. To that end, here are a few resources:
Thank you for visiting this repository! Feel free to contribute and expand on this basic explanation.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
This repository provides a comprehensive and intuitive explanation of the architecture of OpenAI's GPT (Generative Pretrained Transformer) models.
Implementation of GPT Architecture This Repository inspired by the LLMs-from-scratch repository, designed to understanding and implement a GPT-2-like large language model (LLM) from the ground up. This repository provides a complete implementation of a GPT-2 model (355M parameters) with a conversational chatbot interface built using Streamlit. It includes scripts and Jupyter notebooks for model training, fine-tuning, and data processing, making it an educational resource for learning about LLMs. The goal of this project is to provide a hands-on, code-centric approach to building and interacting with a GPT-2 model, from architecture implementation to deployment as a chatbot. Table of Contents Overview Project Structure Installation Usage Running the Chatbot Training the Model Fine-Tuning the Model Testing and Notebooks Datasets FAQ Contributing License Contact Overview This project implements a GPT-2 model from scratch, including the transformer architecture, attention mechanism, finetuning for classification and instruction and training pipeline. The model is fine-tuned for text generation and integrated into a Streamlit-based chatbot interface ( app.py ) that allows users to interact with the model via a conversational UI. The repository includes: A custom GPT-2 achitecture implementation ( src/gpt.py ) with multi-head attention ( src/utils/attention_mechanism.py ). Scripts for data loading, training, and fine-tuning ( src/utils/ , src/training/ , src/finetuning/ ). Datasets for raw text, classification, and instruction-based tasks ( data/ ). Jupyter notebooks for testing ( notebooks/ ). A pre-trained model checkpoint ( models/gpt2-medium355M-sft-standalone.pth , not included in the repo). This project is heavily inspired by the LLMs-from-scratch repository by Sebastian Raschka, adapted to include a user-friendly chatbot interface and custom datasets. Project Structure GPT/ ├── app.py ├── data/ │ ├── raw/ │ │ └── pride_and_prejudice.txt │ ├── classification/ │ │ ├── test.csv │ │ ├── train.csv │ │ └── validation.csv │ └── instruction/ │ ├── instruction-data-with-response-standalone.json │ └── instruction-data.json ├── src/ │ ├── gpt.py │ ├── training/ │ │ ├── load_weights.ipynb │ │ └── train.ipynb │ ├── finetuning/ │ │ ├── instruction.py │ │ └── classification.py │ └── utils/ │ ├── attention_mechanism.py │ ├── data_loader.py │ ├── dataset_classification.py │ ├── gpt_download.py │ ├── train.py ├── models/ │ ├── classification_model.pth │ ├── classification_train_metrics.json │ ├── gpt2-medium355M-sft-standalone.pth │ ├── model_and_optimizer.pth │ └── model.pth ├── notebooks/ │ ├── test_instruction.ipynb │ └── test_train.ipynb └── README.md Installation To set up the project, follow these steps. We recommend using a virtual environment or Conda for dependency management. Prerequisites Python 3.8 or higher A CUDA-compatible GPU (optional but recommended for faster training/inference) Git (for cloning the repository) Steps Clone the Repository : git clone https://github.com/your-username/GPT.git cd GPT Set Up a Conda Environment (recommended): conda create -n GPT python=3.8 conda activate GPT Alternatively, use a Python virtual environment: python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate Install Dependencies : Create a requirements.txt file with the following content: streamlit>=1.10.0 torch>=1.10.0 tiktoken pandas numpy jupyter Install the dependencies: pip install -r requirements.txt For GPU support, install the appropriate PyTorch version: pip install torch --index-url https://download.pytorch.org/whl/cu118 Obtain the Model Checkpoint : The gpt2-medium355M-sft-standalone.pth file is required for the chatbot and is not included in the repository due to its size. Download the model (if available) and place it in models/ . Alternatively, check src/utils/gpt_download.py for downloading instructions or train your own model using src/training/train.ipynb . Verify Setup : Confirm datasets are in data/ and the model checkpoint is in models/ . Usage This repository offers multiple ways to interact with the GPT-2 model, from running the chatbot to training and fine-tuning. Running the Chatbot The primary interface is a Streamlit-based chatbot ( app.py ) that lets you interact with the fine-tuned GPT-2 model. Start the Streamlit app: cd GPT streamlit run app.py Open your browser at http://localhost:8501 . Type a prompt in the chat input field and press Enter to receive a response from the model. Example : Prompt : "What is the plural form of 'mouse'?" Response : (A 35-token response generated by the model, displayed in the chat interface) Training the Model To train the GPT-2 model from scratch or continue training: Open src/training/train.ipynb in Jupyter Notebook: jupyter notebook src/training/train.ipynb Follow the notebook’s instructions to load data (e.g., data/raw/pride_and_prejudice.txt ), configure hyperparameters, and train the model. Save the trained checkpoint to models/ . Alternatively, use src/utils/train.py for command-line training (check the script for usage). Fine-Tuning the Model To fine-tune the model on specific tasks: For instruction-based fine-tuning, use src/finetuning/instruction.py : python src/finetuning/instruction.py Requires data/instruction/instruction-data.json or instruction-data-with-response-standalone.json . For classification tasks, use src/finetuning/classification.py : python src/finetuning/classification.py Uses data/classification/train.csv , test.csv , and validation.csv . Check the scripts for configuration details and adjust hyperparameters as needed. Testing and Notebooks Explore the model and data using the provided notebooks: notebooks/test_instruction.ipynb : Test instruction-based generation. notebooks/test_train.ipynb : Experiment with training configurations. Run the notebooks: jupyter notebook notebooks/ Datasets The data/ directory contains datasets for various tasks: Raw Text ( data/raw/pride_and_prejudice.txt ): Used for pre-training the model on a large text corpus (e.g., Pride and Prejudice ). Classification ( data/classification/ ): CSV files ( train.csv , test.csv , validation.csv ) for classification tasks, such as sentiment analysis or text categorization. Instruction ( data/instruction/ ): JSON files ( instruction-data.json , instruction-data-with-response-standalone.json ) for instruction-based fine-tuning, containing prompts and responses. You can add your own datasets to these directories, following the same format. FAQ Q: Why is the model checkpoint not included in the repository? A: The gpt2-medium355M-sft-standalone.pth file is large and not included to keep the repository lightweight. Download it separately or train your own model using src/training/train.ipynb . Q: I get a ModuleNotFoundError when running app.py . A: Verify that src/gpt.py and src/utils/train.py use relative imports (e.g., from .utils.attention_mechanism import MultiHeadAttention ). Run the app from the GPT/ directory. Q: How can I improve response time? A: Use a CUDA-compatible GPU for faster inference. Alternatively, reduce max_new_tokens in app.py (default: 35) for quicker responses. Q: Can I use my own dataset? A: Yes! Place raw text files in data/raw/ , CSVs in data/classification/ , or JSONs in data/instruction/ , and update the training or fine-tuning scripts accordingly. Contributing Contributions are welcome! To contribute: Fork the repository. Create a feature branch ( git checkout -b feature/your-feature ). Commit your changes ( git commit -m "Add your feature" ). Push to the branch ( git push origin feature/your-feature ). Open a pull request.
This Repository inspired by the LLMs-from-scratch repository, designed to understanding and implement a GPT-2-like large language model (LLM) from the ground up. This repository provides a complete implementation of a GPT-2 model (355M parameters) with a conversational chatbot interface built using Streamlit. It includes scripts and Jupyter notebooks for model training, fine-tuning, and data processing, making it an educational resource for learning about LLMs.
The goal of this project is to provide a hands-on, code-centric approach to building and interacting with a GPT-2 model, from architecture implementation to deployment as a chatbot.
This project implements a GPT-2 model from scratch, including the transformer architecture, attention mechanism, finetuning for classification and instruction and training pipeline. The model is fine-tuned for text generation and integrated into a Streamlit-based chatbot interface ( app.py ) that allows users to interact with the model via a conversational UI. The repository includes:
This project is heavily inspired by the LLMs-from-scratch repository by Sebastian Raschka, adapted to include a user-friendly chatbot interface and custom datasets.
GPT/ ├── app.py ├── data/ │ ├── raw/ │ │ └── pride_and_prejudice.txt │ ├── classification/ │ │ ├── test.csv │ │ ├── train.csv │ │ └── validation.csv │ └── instruction/ │ ├── instruction-data-with-response-standalone.json │ └── instruction-data.json ├── src/ │ ├── gpt.py │ ├── training/ │ │ ├── load_weights.ipynb │ │ └── train.ipynb │ ├── finetuning/ │ │ ├── instruction.py │ │ └── classification.py │ └── utils/ │ ├── attention_mechanism.py │ ├── data_loader.py │ ├── dataset_classification.py │ ├── gpt_download.py │ ├── train.py ├── models/ │ ├── classification_model.pth │ ├── classification_train_metrics.json │ ├── gpt2-medium355M-sft-standalone.pth │ ├── model_and_optimizer.pth │ └── model.pth ├── notebooks/ │ ├── test_instruction.ipynb │ └── test_train.ipynb └── README.md
To set up the project, follow these steps. We recommend using a virtual environment or Conda for dependency management.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
This repository offers multiple ways to interact with the GPT-2 model, from running the chatbot to training and fine-tuning.
The primary interface is a Streamlit-based chatbot ( app.py ) that lets you interact with the fine-tuned GPT-2 model.
Type a prompt in the chat input field and press Enter to receive a response from the model.
Alternatively, use src/utils/train.py for command-line training (check the script for usage).
Q: Why is the model checkpoint not included in the repository? A: The gpt2-medium355M-sft-standalone.pth file is large and not included to keep the repository lightweight. Download it separately or train your own model using src/training/train.ipynb .
Q: I get a ModuleNotFoundError when running app.py . A: Verify that src/gpt.py and src/utils/train.py use relative imports (e.g., from .utils.attention_mechanism import MultiHeadAttention ). Run the app from the GPT/ directory.
Q: How can I improve response time? A: Use a CUDA-compatible GPU for faster inference. Alternatively, reduce max_new_tokens in app.py (default: 35) for quicker responses.
Q: Can I use my own dataset? A: Yes! Place raw text files in data/raw/ , CSVs in data/classification/ , or JSONs in data/instruction/ , and update the training or fine-tuning scripts accordingly.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)