Complete Technical Paper Content — Gpt3 Applications
1. Executive Abstract, Problem Formulation & Background
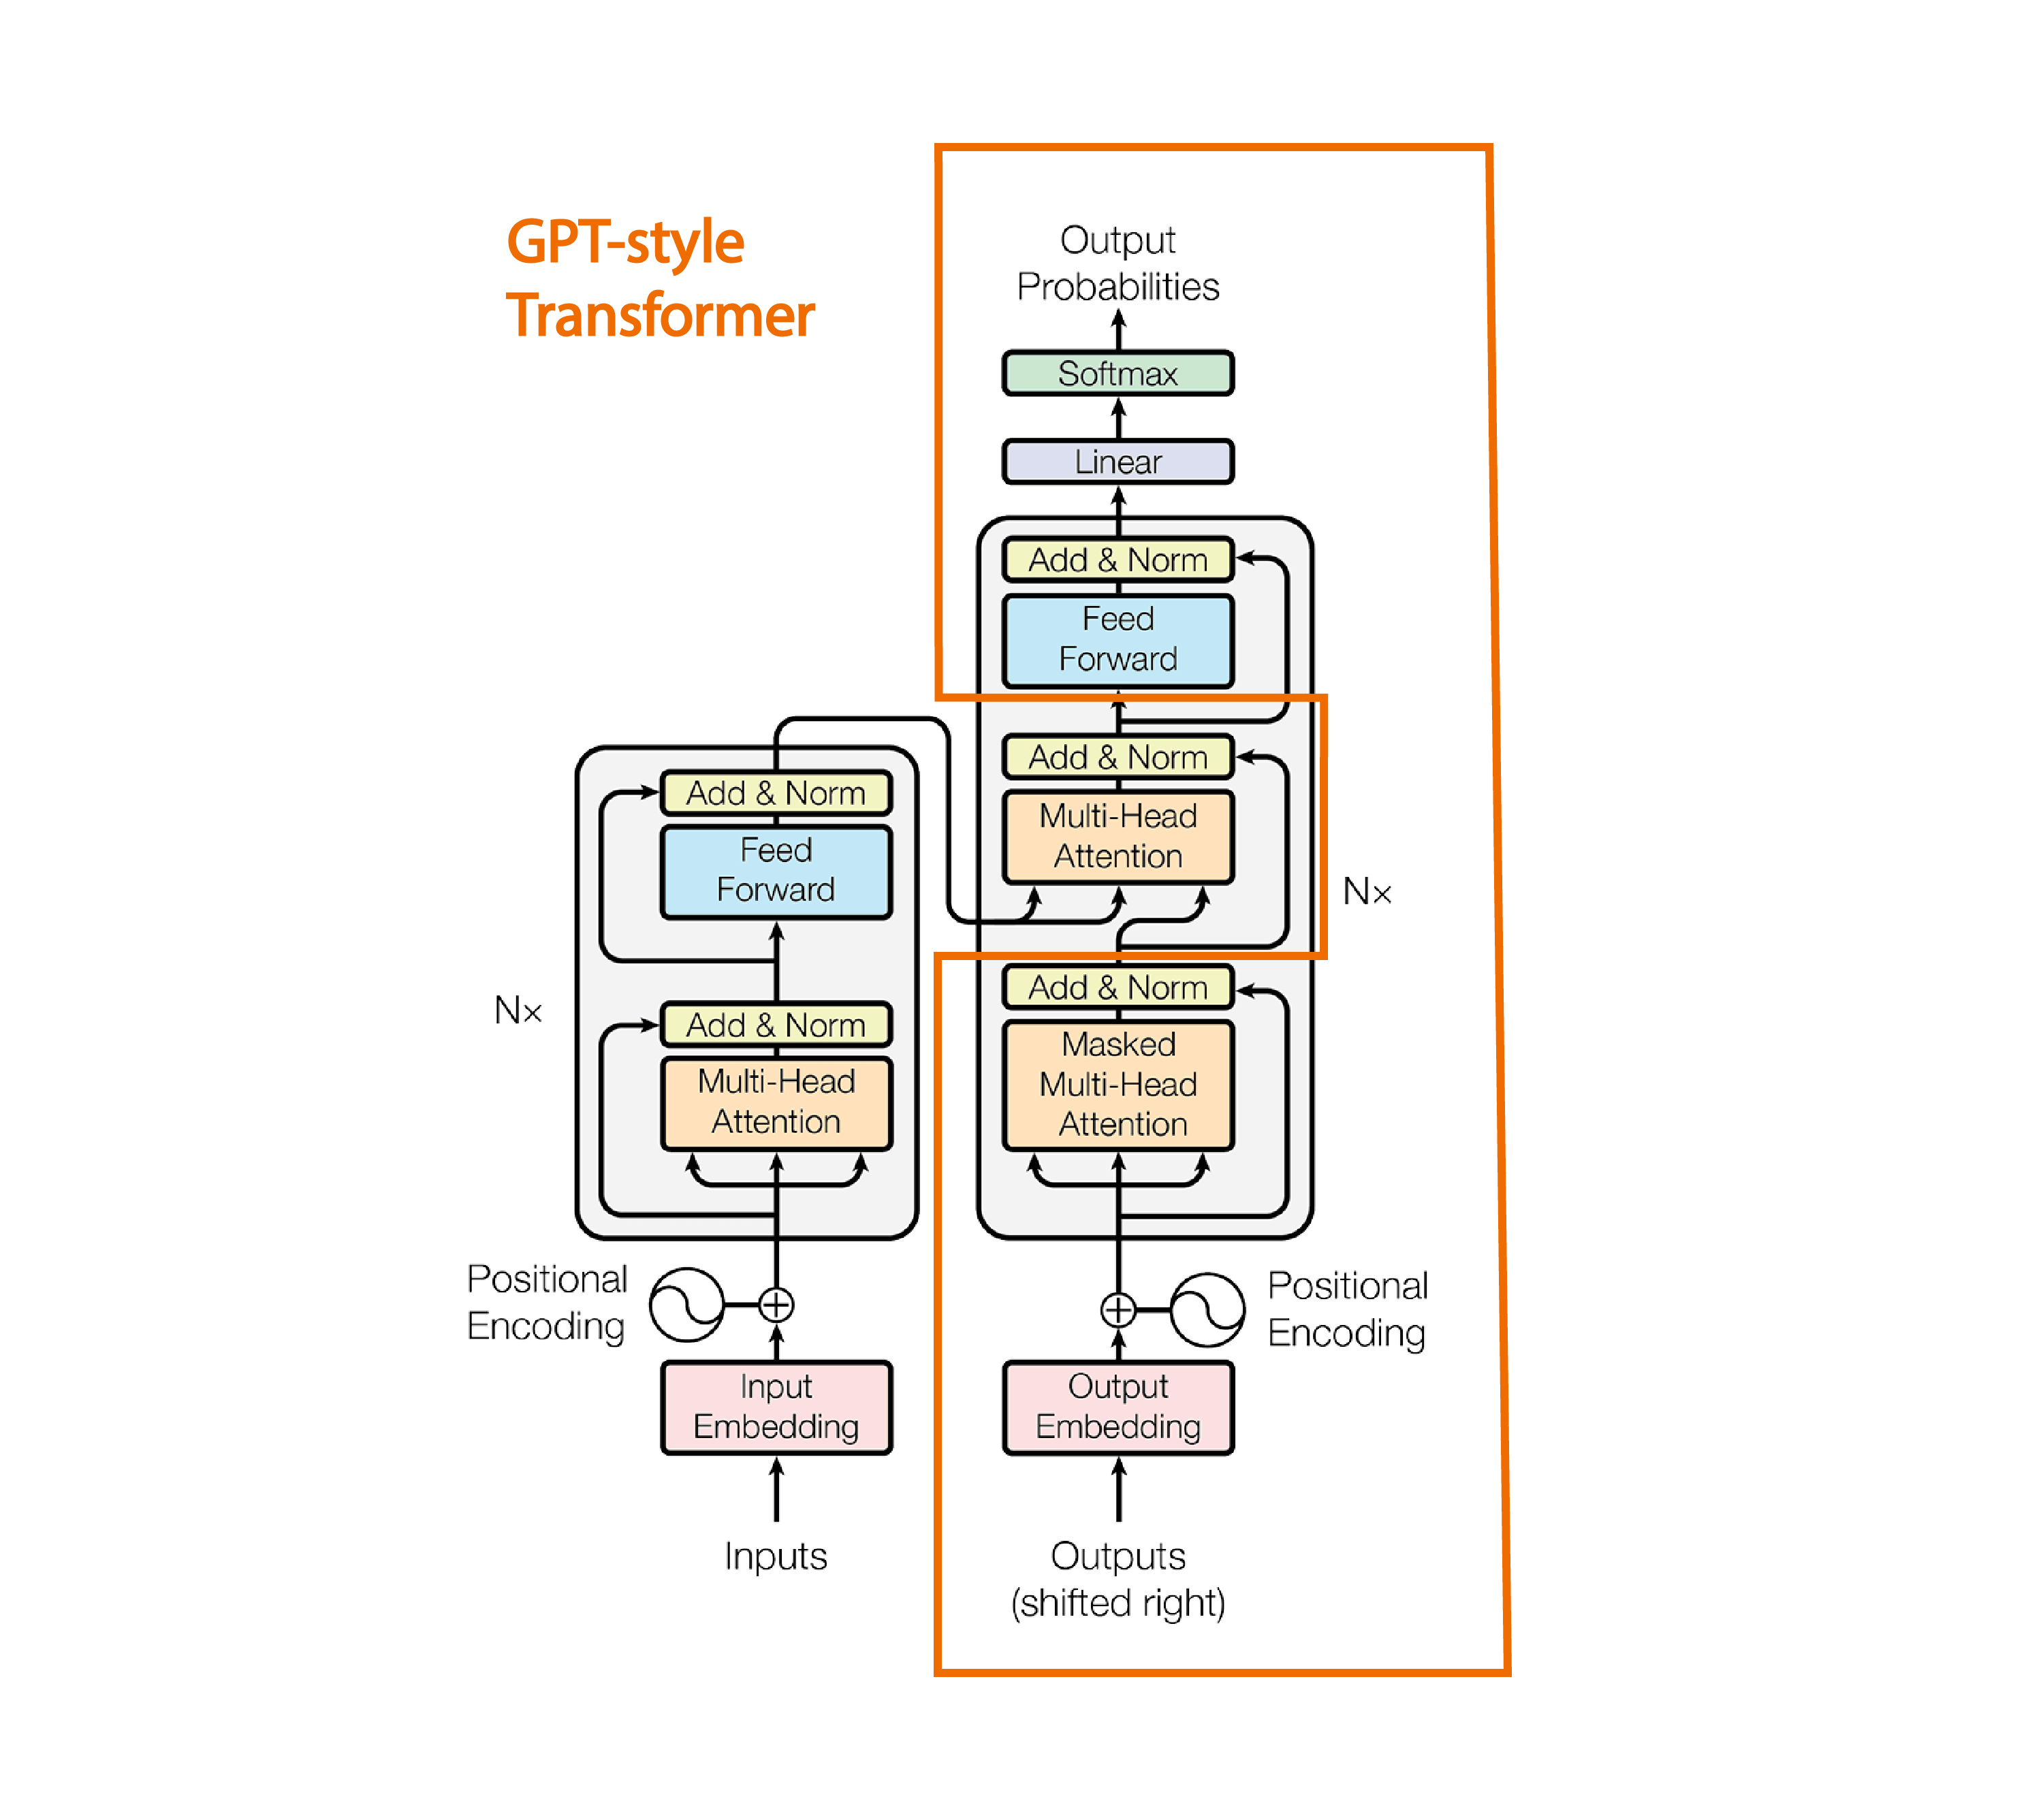
Generative Pre-trained Transformer 3 (GPT-3) was a large language model released by OpenAI in 2020 as part of the company's GPT series of models. Like its predecessor, GPT-2, it is a decoder-only transformer model of deep neural network, which supersedes recurrence and convolution-based architectures with a technique known as "attention". This attention mechanism allows the model to focus selectively on segments of input text it predicts to be most relevant. GPT-3 has 175 billion parameters, each with 16-bit precision, requiring 350GB of storage since each parameter occupies 2 bytes. It has a context window size of 2,048 tokens, and has demonstrated strong "zero-shot" and "few-shot" learning abilities on many tasks. On September 22, 2020, Microsoft announced that it had licensed GPT-3 exclusively. Others can still receive output from its public API, but only Microsoft has access to the underlying model.
On May 28, 2020, an arXiv preprint by a group of 31 engineers and researchers at OpenAI described the achievement and development of GPT-3, a third-generation "state-of-the-art language model". The team increased the capacity of GPT-3 by over two orders of magnitude from that of its predecessor, GPT-2, making GPT-3 the largest non-sparse language model at that time. Because GPT-3 is structurally similar to its predecessors, its greater accuracy is attributed to its increased capacity and greater number of parameters. GPT-3's capacity is ten times larger than that of Microsoft's Turing NLG, the next largest NLP model known at the time. Lambdalabs estimated a hypothetical cost of around $4.6 million US dollars and 355 years to train GPT-3 on a single GPU in 2020, with lower actual training time by using more GPUs in parallel. Sixty percent of the weighted pre-training dataset for GPT-3 comes from a filtered version of Common Crawl consisting of 410 billion byte-pair-encoded tokens. Fuzzy deduplication used Apache Spark's MinHashLSH. Other sources are 19 billion tokens from WebText2 representing 22% of the weighted total, 12 billion tokens from Books1 representing 8%, 55 billion tokens from Books2 representing 8%, and 3 billion tokens from Wikipedia representing 3%. GPT-3 was trained on hundreds of billions of words and is also capable of coding in CSS, JSX, and Python, among others.
Since GPT-3's training data was all-encompassing, it does not require further training for distinct language tasks. The training data contains occasional toxic language and GPT-3 occasionally generates toxic language as a result of mimicking its training data. A study from the University of Washington found that GPT-3 produced toxic language at a toxicity level comparable to the similar natural language processing models of GPT-2 and CTRL. OpenAI has implemented several strategies to limit the amount of toxic language generated by GPT-3. As a result, GPT-3 produced less toxic language compared to its predecessor model, GPT-1, although it produced both more generations and a higher toxicity of toxic language compared to CTRL Wiki, a language model trained entirely on Wikipedia data. On June 11, 2020, OpenAI announced that users could request access to its user-friendly GPT-3 API—a "machine learning toolset"—to help OpenAI "explore the strengths and limits" of this new technology. The invitation described how this API had a general-purpose "text in, text out" interface that can complete almost "any English language task", instead of the usual single use-case. According to one user, who had access to a private early release of the OpenAI GPT-3 API, GPT-3 was "eerily good" at writing "amazingly coherent text" with only a few simple prompts. In an initial experiment 80 US subjects were asked to judge if short ~200 word articles were written by humans or GPT-3. The participants judged correctly 52% of the time, doing only slightly better than random guessing. On November 18, 2021, OpenAI announced that enough safeguards had been implemented that access to its API would be unrestricted. OpenAI provided developers with a content moderation tool that helps them abide by OpenAI's content policy. On January 27, 2022, OpenAI announced that its newest GPT-3 language models (collectively referred to as InstructGPT) were now the default language model used on their API. According to OpenAI, InstructGPT produced content that was better aligned to user intentions by following instructions better, generating fewer made-up facts, and producing somewhat less toxic content. Because GPT-3 can "generate news articles which human evaluators have difficulty distinguishing from articles written by humans," GPT-3 has the "potential to advance both the beneficial and harmful applications of language models." In their May 28, 2020 paper, the researchers described in detail the potential "harmful effects of GPT-3" which include "misinformation, spam, phishing, abuse of legal and governmental processes, fraudulent academic essay writing and social engineering pretexting". The authors draw attention to these dangers to call for research on risk mitigation. GPT-3 is capable of performing zero-shot and few-shot learning (including one-shot). In June 2022, Almira Osmanovic Thunström wrote that GPT-3 was the primary author on an article on itself, that they had submitted it for publication, and that it had been pre-published while waiting for completion of its review.
Half of the models are accessible through the API, namely GPT-3-medium, GPT-3-xl, GPT-3-6.7B and GPT-3-175b, which are referred to as ada, babbage, curie and davinci respectively. While the size of the API models was not originally disclosed by OpenAI, EleutherAI announced the mapping between model sizes and API names in May 2021. These model sizes were later confirmed by OpenAI, but the sizes of subsequent models have not been disclosed.
AI anthropomorphism is the attribution of human-like feelings, mental states, and behavioral characteristics to artificial intelligence systems. Factors related to the user of the AI – such as culture, age, education, gender, and personality traits – are also important determinants of the strength of anthropomorphic effects. Since the earliest days of AI development, humans have interpreted machine outputs through anthropomorphic frameworks, but the recent emergence of generative AI has amplified these tendencies. Terms such as learning, understanding, reasoning, thinking, hallucinating and planning are frequently used in AI research to describe capabilities of AI systems, without necessarily implying consciousness, sentience, human-like cognition, or understanding in a stronger philosophical sense. In research and engineering, there is a distinction between anthropomorphism and anthropomorphic design. The former is an innate human tendency toward non-human entities. The latter is the scientific community or commercial effort to “design anthropomorphism”. Such a design can involve the manipulation of cues, including AI appearance, behaviour and language. Contemporary AI systems today can generate extremely human-like outputs and are often designed specifically to do so, meaning that their anthropomorphic effects can be especially powerful. In some cases, anthropomorphism is accompanied with explicit beliefs that AI systems are capable of empathy, goodwill, understanding, or consciousness.
Anthropomorphic portrayals of AI are common in film, literature, and other interactive media. These depictions often emphasize human-like qualities of AI in ways that shape public perceptions.
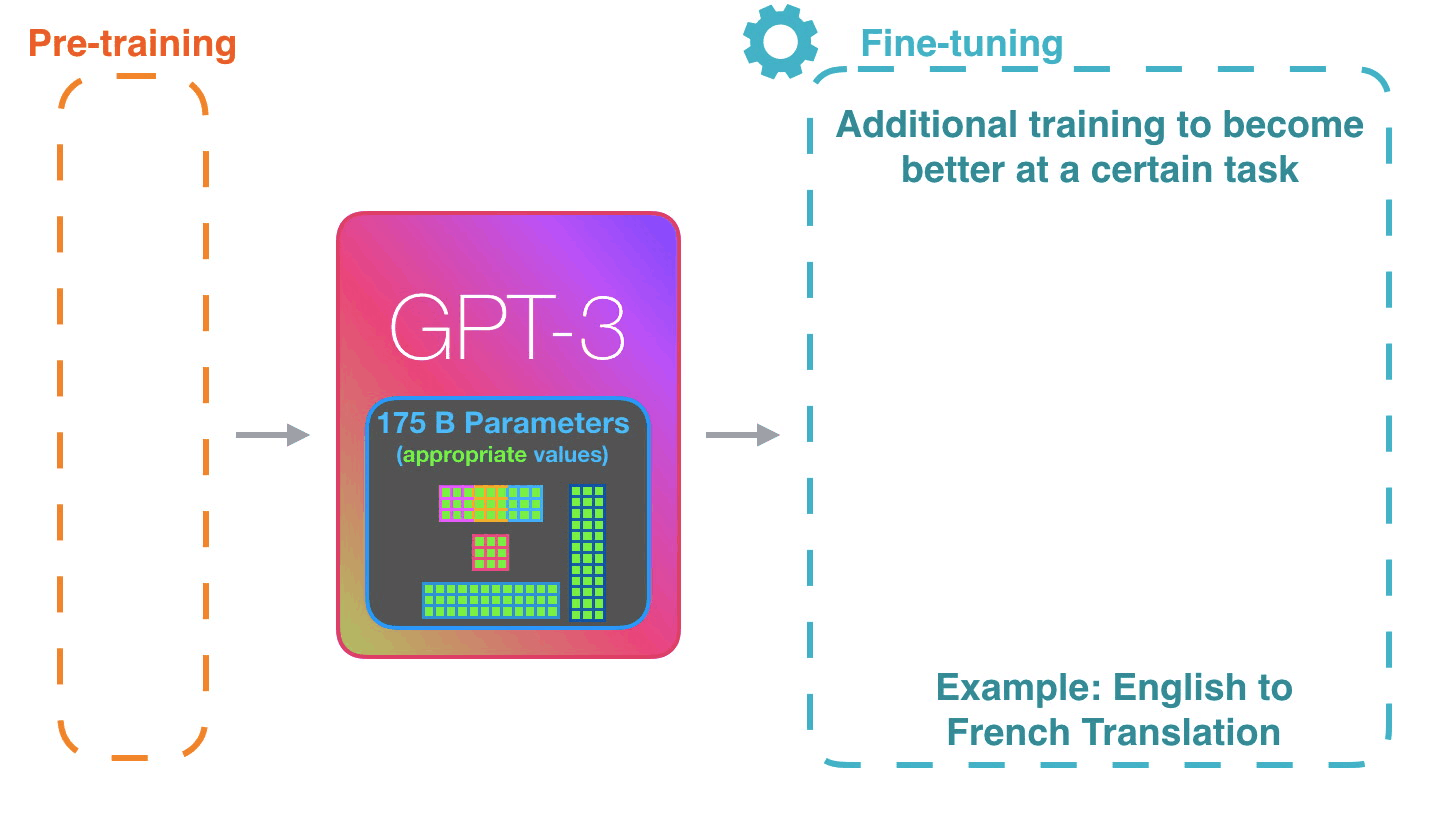
Fine-Tuning GPT-3 Using the OpenAI API and Python A tutorial on fine-tuning the GPT-3 model using OpenAI API and Python, covering steps from API setup to model validation. Overview This repository contains a tutorial on fine-tuning the GPT-3 model using the OpenAI API and Python. The process involves using a pre-trained GPT-3 model and training it further on a custom dataset to adapt it to specific use cases or domains. The tutorial covers all necessary steps, from obtaining API credentials to preparing data, training the model, and validating its performance. Prerequisites Before starting, ensure you have the following: Basic understanding of Python programming. Familiarity with machine learning and natural language processing. OpenAI API credentials. Dataset Preparation Prepare your dataset for fine-tuning. Ensure that your data is in the correct format and structure suitable for training. The dataset should be relevant to your specific use case or domain. Fine-Tuning Process 1. Get API Credentials: Obtain your OpenAI API key from the OpenAI website. 2. Prepare Data: Format your data according to the requirements for fine-tuning. This includes cleaning and structuring the data appropriately. 3. Train the Model: Use the provided notebook fine-tuning-gpt3-python_notebook.ipynb to walk through the training process. The notebook covers: 4. Setting up the OpenAI API client. Uploading your dataset. Initiating the fine-tuning process. 5. Validate the Model: After training, validate the model using test data to ensure it performs well on your specific tasks. Model Validation The validation step involves testing the fine-tuned model on a separate dataset to evaluate its performance. The notebook includes steps to perform validation and interpret the results. Usage To use the fine-tuned GPT-3 model, follow the instructions in the notebook to generate predictions on new data. The notebook demonstrates how to: Make API calls to the fine-tuned model. Process the responses. Integrate the model into your applications. Results Document the results of your fine-tuning process here. Include any metrics or performance improvements observed during validation. Contributing Contributions are welcome! Please fork the repository and use a feature branch. Pull requests are reviewed on a regular basis.
A tutorial on fine-tuning the GPT-3 model using OpenAI API and Python, covering steps from API setup to model validation.
This repository contains a tutorial on fine-tuning the GPT-3 model using the OpenAI API and Python. The process involves using a pre-trained GPT-3 model and training it further on a custom dataset to adapt it to specific use cases or domains. The tutorial covers all necessary steps, from obtaining API credentials to preparing data, training the model, and validating its performance.
2. Related Work, Literature Survey & Algorithmic Foundations
Prepare your dataset for fine-tuning. Ensure that your data is in the correct format and structure suitable for training. The dataset should be relevant to your specific use case or domain.
Format your data according to the requirements for fine-tuning. This includes cleaning and structuring the data appropriately.
Use the provided notebook fine-tuning-gpt3-python_notebook.ipynb to walk through the training process. The notebook covers:
After training, validate the model using test data to ensure it performs well on your specific tasks.
The validation step involves testing the fine-tuned model on a separate dataset to evaluate its performance. The notebook includes steps to perform validation and interpret the results.
To use the fine-tuned GPT-3 model, follow the instructions in the notebook to generate predictions on new data. The notebook demonstrates how to:
Document the results of your fine-tuning process here. Include any metrics or performance improvements observed during validation.
Contributions are welcome! Please fork the repository and use a feature branch. Pull requests are reviewed on a regular basis.
A DataCamp tutorial on fine-tuning the GPT-3 model using OpenAI API and Python, covering steps from API setup to model validation.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
In this tutorial, we will build our own fine-tuned GPT-3 model with provided training and validation dataset. It's doing text-summarization. 1. Getting OpenAI API key Go to https://platform.openai.com/account/api-keys and log in. Generate new secret key and keep it safely. 2. Checking the prepared training and validation data. It should include a number of pairs of prompt and completion. {"prompt": "Summarize the following text:Our new business production totaled $389 million of direct PVP exceeded by $75 million -- the direct PVP we produced in every year but once since 2010.\n....", "completion": "Turning to our fourth quarter 2020 results, adjusted operating income was $56 million or $0.69 per share compared with $87 million or $0.90 per share in the fourth quarter of 2019."} {"prompt": "Summarize the following text:Overall, restaurant traffic has largely stabilized at about 5% below pre-pandemic levels led by the continued solid performance at quick service restaurants.\nDemand in U.S. retail channels also remained solid with overall category volumes in the quarter still up 15% to 20% from pre-pandemic levels....", "completion": "Specifically in the quarter, sales increased 13% to $984 million, with volume up 11% and price mix up 2%.\nDiluted earnings per share in the first quarter was $0.20, down from $0.61 in the prior year, while adjusted EBITDA including joint ventures was $123 million, down from $202 million."} ........................ 3. Let's get started First, we need to install the OpenAI library: !pip install --upgrade openai import os import openai os.environ["OPENAI_API_KEY"] = 'YOUR_API_KEY' We will pass GPT-3 model as parameters. Such as ada, curie, or davinci !openai api fine_tunes.create -t "prepared_train.jsonl" -v "prepared_val.jsonl" -m ada It takes time to put fine-tune job in queue and train a model. Let's wait and check the status !openai api fine_tunes.follow -i ft-3Wnb4hOrXU1FuQGDRfyvNWlz After the fine-tuned model is created, wee can test our function. We will use the following prompt: Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance. Use command line !openai api completions.create -m ada:ft-tpisoftware-2023-03-01-00-10-20 -p "Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance." Or python code openai.api_key = os.getenv("OPENAI_API_KEY") openai.Completion.create( model="ada:ft-tpisoftware-2023-03-01-00-10-20", prompt="Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance.", max_tokens=256, temperature=0 ) Sample result: <OpenAIObject text_completion id=cmpl-6p4x0eQuRB83JEWs19ssaSS5g7TKC at 0x1011ea4a0> JSON: { "choices": [ { "finish_reason": "length", "index": 0, "logprobs": null, "text": "\nWe have been in the business of providing our customers with the best quality products and services for over 40 years." } ], "created": 1677631778, "id": "cmpl-6p4x0eQuRB83JEWs19ssaSS5g7TKC", "model": "ada:ft-tpisoftware-2023-03-01-00-10-20", "object": "text_completion", "usage": { "completion_tokens": 256, "prompt_tokens": 17, "total_tokens": 273 } } 4. Reference https://chuangtc.com/projects/fine-tune-GPT3.php Github OpenAI For further actions, you may consider blocking this person and/or reporting abuse
In this tutorial, we will build our own fine-tuned GPT-3 model with provided training and validation dataset. It's doing text-summarization.
Go to https://platform.openai.com/account/api-keys and log in. Generate new secret key and keep it safely.
{"prompt": "Summarize the following text:Our new business production totaled $389 million of direct PVP exceeded by $75 million -- the direct PVP we produced in every year but once since 2010.\n....", "completion": "Turning to our fourth quarter 2020 results, adjusted operating income was $56 million or $0.69 per share compared with $87 million or $0.90 per share in the fourth quarter of 2019."} {"prompt": "Summarize the following text:Overall, restaurant traffic has largely stabilized at about 5% below pre-pandemic levels led by the continued solid performance at quick service restaurants.\nDemand in U.S. retail channels also remained solid with overall category volumes in the quarter still up 15% to 20% from pre-pandemic levels....", "completion": "Specifically in the quarter, sales increased 13% to $984 million, with volume up 11% and price mix up 2%.\nDiluted earnings per share in the first quarter was $0.20, down from $0.61 in the prior year, while adjusted EBITDA including joint ventures was $123 million, down from $202 million."} ........................
!pip install --upgrade openai import os import openai os.environ["OPENAI_API_KEY"] = 'YOUR_API_KEY'
!openai api fine_tunes.create -t "prepared_train.jsonl" -v "prepared_val.jsonl" -m ada
It takes time to put fine-tune job in queue and train a model. Let's wait and check the status
After the fine-tuned model is created, wee can test our function. We will use the following prompt:
Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
!openai api completions.create -m ada:ft-tpisoftware-2023-03-01-00-10-20 -p "Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance."
openai.api_key = os.getenv("OPENAI_API_KEY") openai.Completion.create( model="ada:ft-tpisoftware-2023-03-01-00-10-20", prompt="Summarize the following text:During the first quarter, we maintained a very safe environment with an RIR of 0.64, which is in line with our full year 2020 performance.", max_tokens=256, temperature=0 )
<OpenAIObject text_completion id=cmpl-6p4x0eQuRB83JEWs19ssaSS5g7TKC at 0x1011ea4a0> JSON: { "choices": [ { "finish_reason": "length", "index": 0, "logprobs": null, "text": "\nWe have been in the business of providing our customers with the best quality products and services for over 40 years." } ], "created": 1677631778, "id": "cmpl-6p4x0eQuRB83JEWs19ssaSS5g7TKC", "model": "ada:ft-tpisoftware-2023-03-01-00-10-20", "object": "text_completion", "usage": { "completion_tokens": 256, "prompt_tokens": 17, "total_tokens": 273 } }
GPT3 Welcome to the GPT3 repository! This project is an attempt to recreate the architecture and approach from the original OpenAI GPT-3 paper. The repository includes scripts for training, fine-tuning, and inference of a GPT-3-like model using PyTorch and the Hugging Face Transformers library. This repository contains the v2 rewrite of my GPT-3-style research project: custom architecture, foundation training, benchmark evaluation, and a new SFT workflow. If you want the old "stable" code snapshot, use the v1-stable tag/release archive. v1 architecture models: GPT3-dev-125m, GPT3-dev, GPT3-dev-125m-0612, GPT3-dev-125m-1202, GPT3-dev-125m-0104, GPT3-dev-350m-2805 The most stable transformers version for all models (so far) is transformers==4.52.4 What Changed In v2 I finally came up with a semi-working strided attention implementation, so the architecture matches (as GPTs told me) the original GPT-3 paper (with sparse+dense attention blocks). Replaced multiple legacy training scripts with a single train.py pipeline. Reworked model implementation in modeling_gpt3dev.py for newer transformers compatibility. Upgraded evaluation in eval.py with CLI flags for HellaSwag, LAMBADA, and MMLU tasks. Added a new full SFT workflow in sft.py with multi-dataset loading, filtering, and chat-template training. Removed old scripts ( train-17m.py , train-125m.py , fine-tune-SFT.py , inference.py , etc.) to keep the repo focused. Repository Layout train.py : Foundation-model training (streaming FineWeb, periodic validation/checkpointing, W&B logging). modeling_gpt3dev.py : Custom GPT-3-like architecture ( GPT3DevConfig , sparse+dense attention blocks, HF auto-registration). eval.py : Benchmark runner for HellaSwag / LAMBADA / MMLU. sft.py : v2 supervised fine-tuning workflow with Harmony-style chat formatting and dataset filtering. arch_demonstrator.py : Build/save architecture-only checkpoint for experiments. Install git clone https://github.com/krll-corp/GPT3.git cd GPT3 python3 -m venv .venv source .venv/bin/activate pip install -U pip pip install -r requirements.txt Optional: Login for experiment tracking: wandb login Quickstart 1) Train Foundation Model (v2) python3 train.py \ --acc 128 \ --log-steps 1 \ --eval-steps 500 \ --ckpt-steps 100 \ --hf-save-steps 1000 Useful flags: --resume : Resume from ./emergency_ckpt_jetson_gpt3_v2 . --skip-val : Disable validation. --skip-gen : Disable periodic generation previews. --opt-state-on-cpu : Move optimizer state to CPU (lower VRAM, slower). --total-tokens and --warmup-tokens : Token-based run length control. By default, the script trains a ~125M model ( 12 layers , 768 hidden , context block 512 ) on streaming FineWeb. 2) Evaluate A Checkpoint python3 eval.py \ --model k050506koch/GPT3-dev-125m-1202 \ --run-hellaswag \ --run-lambada \ --run-mmlu \ --mmlu-tasks abstract_algebra anatomy \ --batch-size 2 \ --block-size 128 You can pass either a local checkpoint path or a Hugging Face repo id. 3) Run SFT Workflow python3 sft.py Current defaults in sft.py : Loads base model/tokenizer from ./gpt3-small-jetson-v2 . Adds Harmony-style special tokens and chat template. Builds a filtered multi-dataset instruction corpus. Saves SFT outputs to ./gpt3-small-jetson-v2-sft . If your base checkpoint path is different, edit it near the top of sft.py . 4) Minimal Inference Run a minimal local generation test with an inline Python snippet: python3 - << ' PY ' import torch from eval import load_model_and_tokenizer model, tokenizer = load_model_and_tokenizer( "k050506koch/GPT3-dev-125m", torch.device("cuda" if torch.cuda.is_available() else "cpu"), ) inputs = tokenizer("He is a doctor. His main goal is", return_tensors="pt").to(model.device) with torch.no_grad(): output = model.generate(**inputs, max_length=50, do_sample=False, pad_token_id=tokenizer.pad_token_id, eos_token_id=tokenizer.eos_token_id) print(tokenizer.decode(output[0], skip_special_tokens=True)) PY Pretrained Checkpoints Public checkpoints (all of them use v1 architecture): k050506koch/GPT3-dev (17M) k050506koch/GPT3-dev-125m k050506koch/GPT3-dev-125m-0612 k050506koch/GPT3-dev-125m-1202 When you use the shared eval.py loader, the local modeling_gpt3dev registration handles these checkpoints without requiring trust_remote_code . Notes And Caveats This is an actively evolving v2 codebase, so errors / inconsistencies may occur, but I will be happy if you open an error or create a PR. train.py is tuned for memory-constrained CUDA setups (i use Nvidia Jetson Orin Nano Super, it has 8GB of unified memory. “And in those days many a clever programmer derived an immense intellectual satisfaction from the cunning tricks by which he contrived to squeeze the impossible into the constraints of his equipment.” ). sft.py currently has hardcoded paths/settings intended for local experimentation; adjust before large runs. requirements.txt is pinned to my working environment and includes more than strictly minimal runtime dependencies. License MIT because it's true open-source. See LICENSE . Acknowledgements Thanks OpenAI, HuggingFace and Pytorch for making this project possible! OpenAI GPT-3 paper Hugging Face Transformers PyTorch
Welcome to the GPT3 repository! This project is an attempt to recreate the architecture and approach from the original OpenAI GPT-3 paper. The repository includes scripts for training, fine-tuning, and inference of a GPT-3-like model using PyTorch and the Hugging Face Transformers library.
This repository contains the v2 rewrite of my GPT-3-style research project: custom architecture, foundation training, benchmark evaluation, and a new SFT workflow.
v1 architecture models: GPT3-dev-125m, GPT3-dev, GPT3-dev-125m-0612, GPT3-dev-125m-1202, GPT3-dev-125m-0104, GPT3-dev-350m-2805
git clone https://github.com/krll-corp/GPT3.git cd GPT3 python3 -m venv .venv source .venv/bin/activate pip install -U pip pip install -r requirements.txt
python3 train.py \ --acc 128 \ --log-steps 1 \ --eval-steps 500 \ --ckpt-steps 100 \ --hf-save-steps 1000
5. Training Protocol, Convergence Behavior & Experimental Evaluation
By default, the script trains a ~125M model ( 12 layers , 768 hidden , context block 512 ) on streaming FineWeb.
python3 eval.py \ --model k050506koch/GPT3-dev-125m-1202 \ --run-hellaswag \ --run-lambada \ --run-mmlu \ --mmlu-tasks abstract_algebra anatomy \ --batch-size 2 \ --block-size 128
python3 - << ' PY ' import torch from eval import load_model_and_tokenizer model, tokenizer = load_model_and_tokenizer( "k050506koch/GPT3-dev-125m", torch.device("cuda" if torch.cuda.is_available() else "cpu"), ) inputs = tokenizer("He is a doctor. His main goal is", return_tensors="pt").to(model.device) with torch.no_grad(): output = model.generate(**inputs, max_length=50, do_sample=False, pad_token_id=tokenizer.pad_token_id, eos_token_id=tokenizer.eos_token_id) print(tokenizer.decode(output[0], skip_special_tokens=True)) PY
When you use the shared eval.py loader, the local modeling_gpt3dev registration handles these checkpoints without requiring trust_remote_code .
“And in those days many a clever programmer derived an immense intellectual satisfaction from the cunning tricks by which he contrived to squeeze the impossible into the constraints of his equipment.” ).
Mathematical Formulation 1.1: Loss Objectives and Optimization Dynamics for Gpt3 Applications. The training protocol of gpt3 applications minimizes an empirical risk objective defined across high-dimensional parameter space Theta in R^d. Categorical predictions are governed by Cross-Entropy Loss: L_CE = -sum(y_i * log(p_i)). To tackle class imbalance, the network incorporates Focal Loss: L_Focal = -alpha_t * (1 - p_t)^gamma * log(p_t), where gamma modulates the gradient penalty on hard misclassified instances. For spatial tasks, Dice Loss balances continuous spatial overlap: L_Dice = 1 - (2 * sum(y * y_hat) + eps) / (sum(y) + sum(y_hat) + eps). Stochastic optimization utilizes AdamW with decoupled weight decay, maintaining stable moment estimations m_t and v_t across variable learning rate schedules.
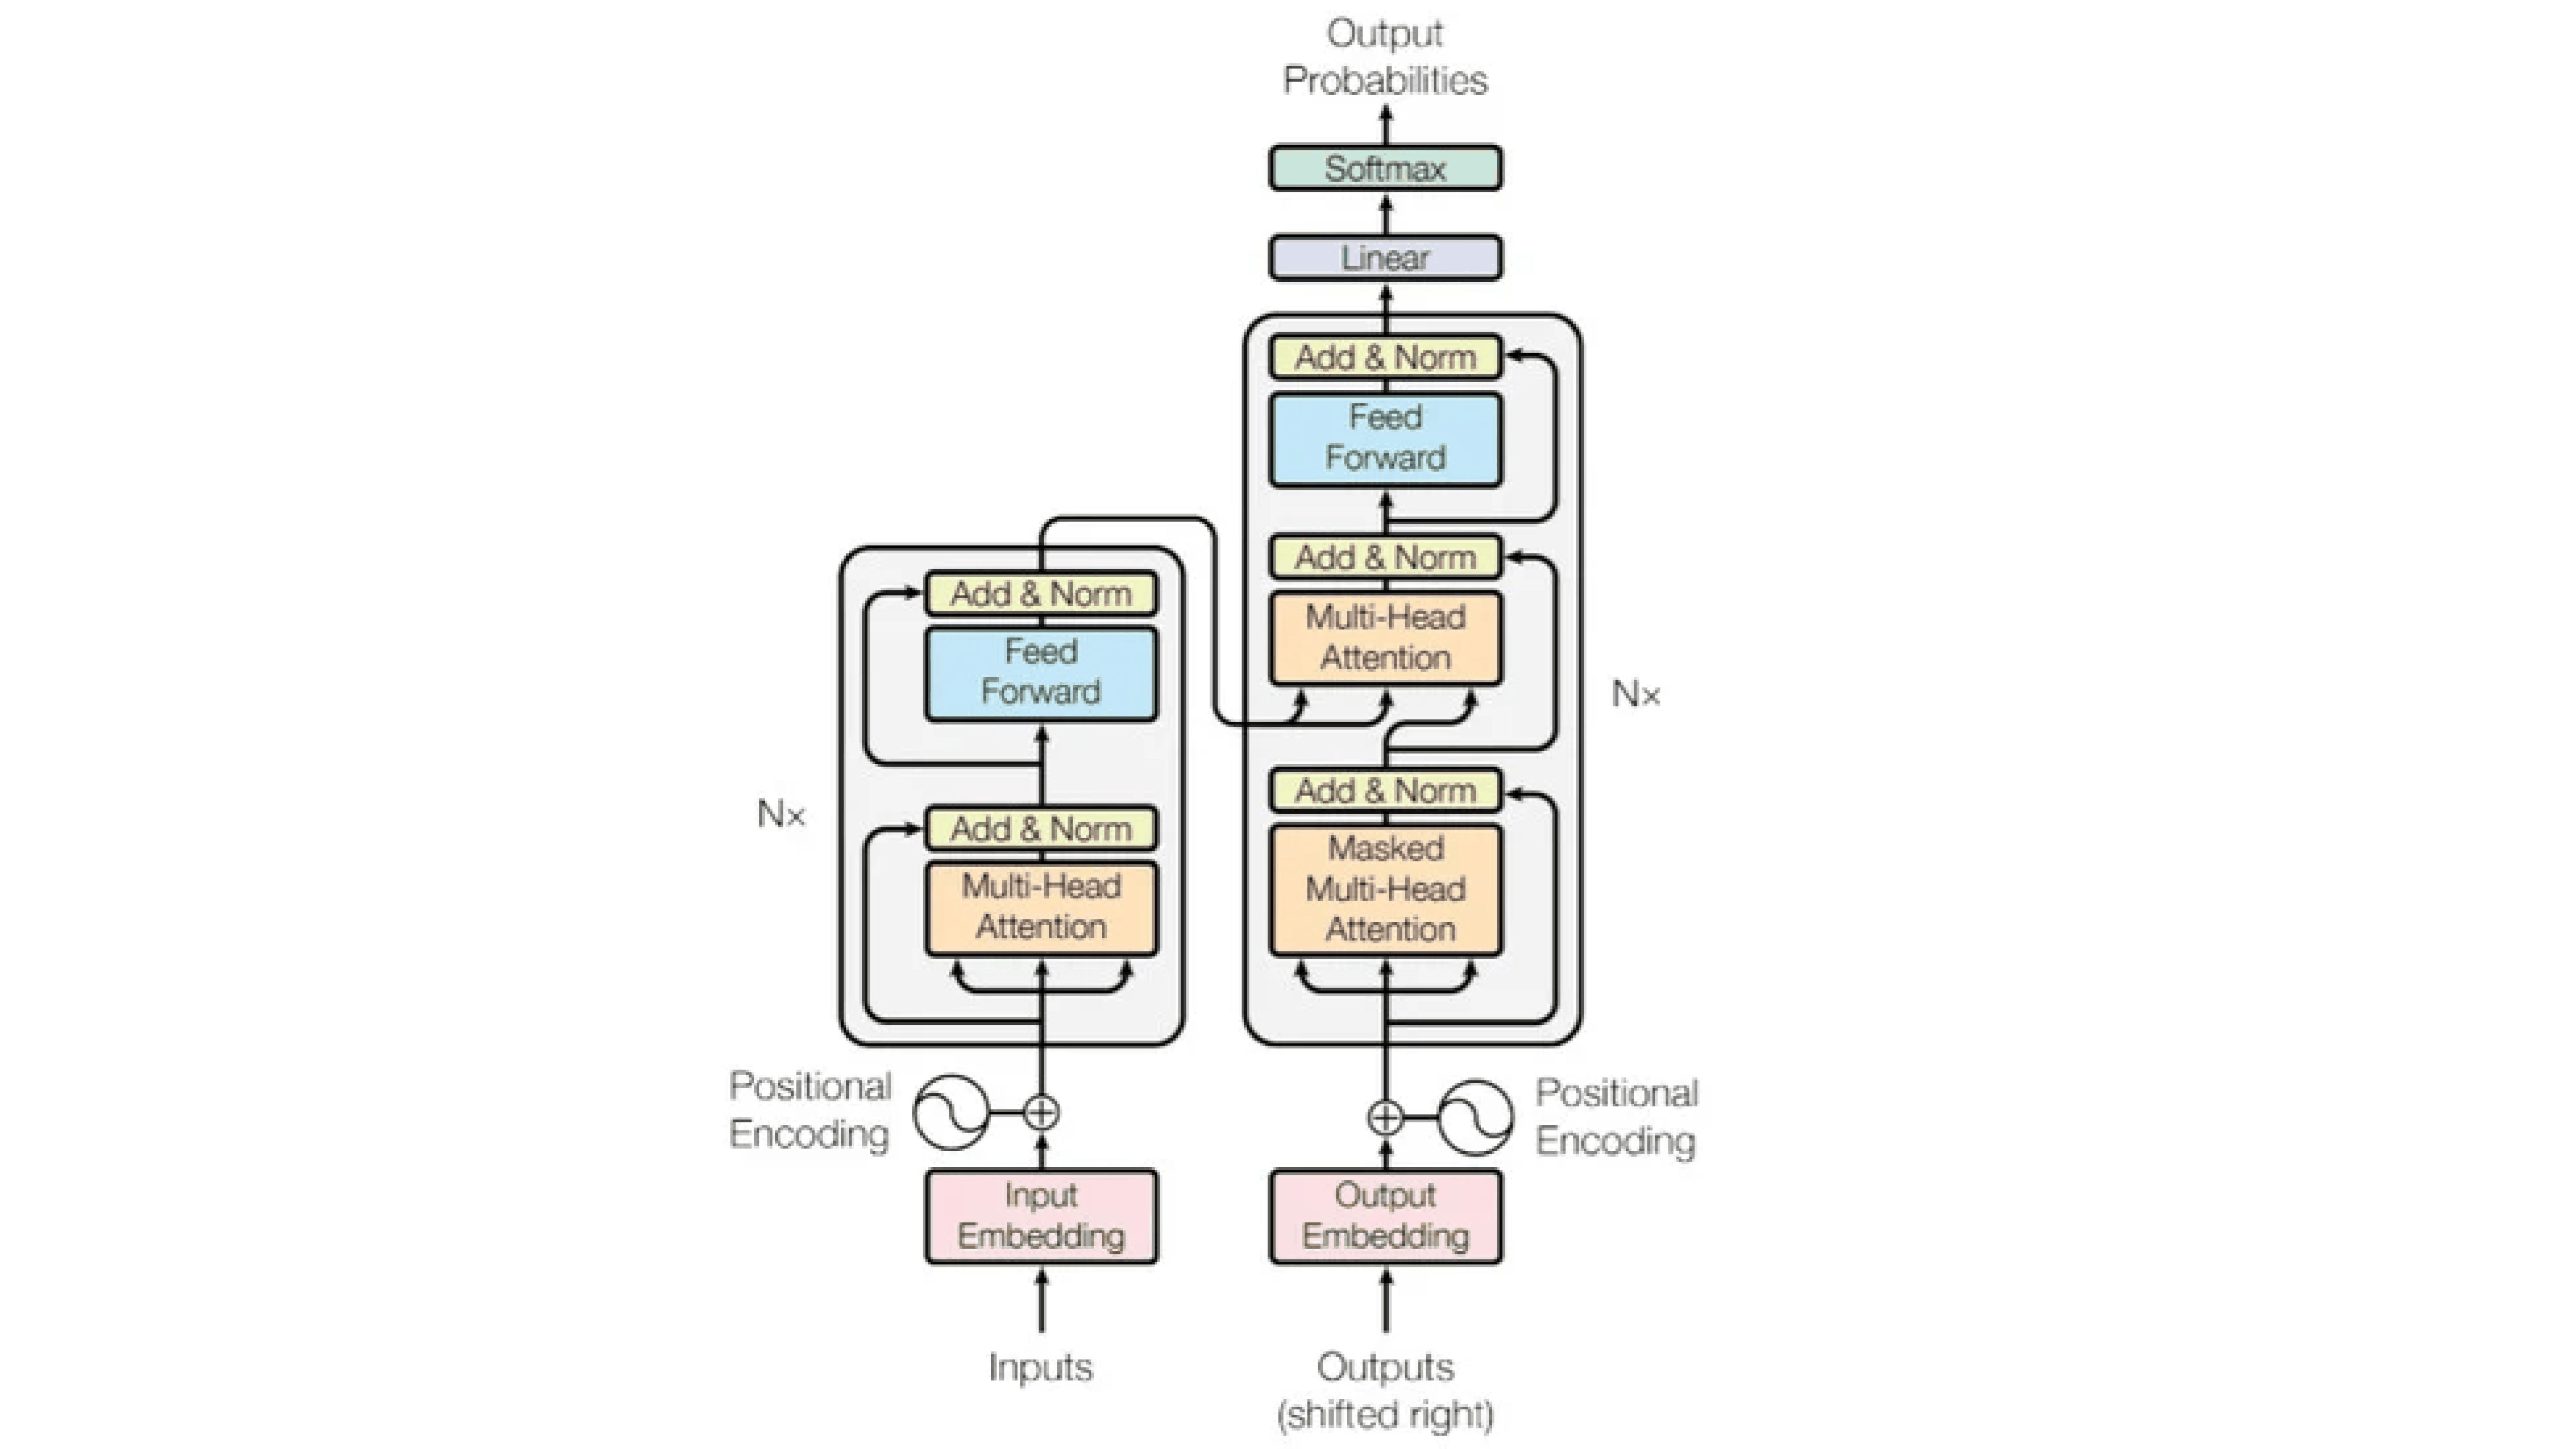
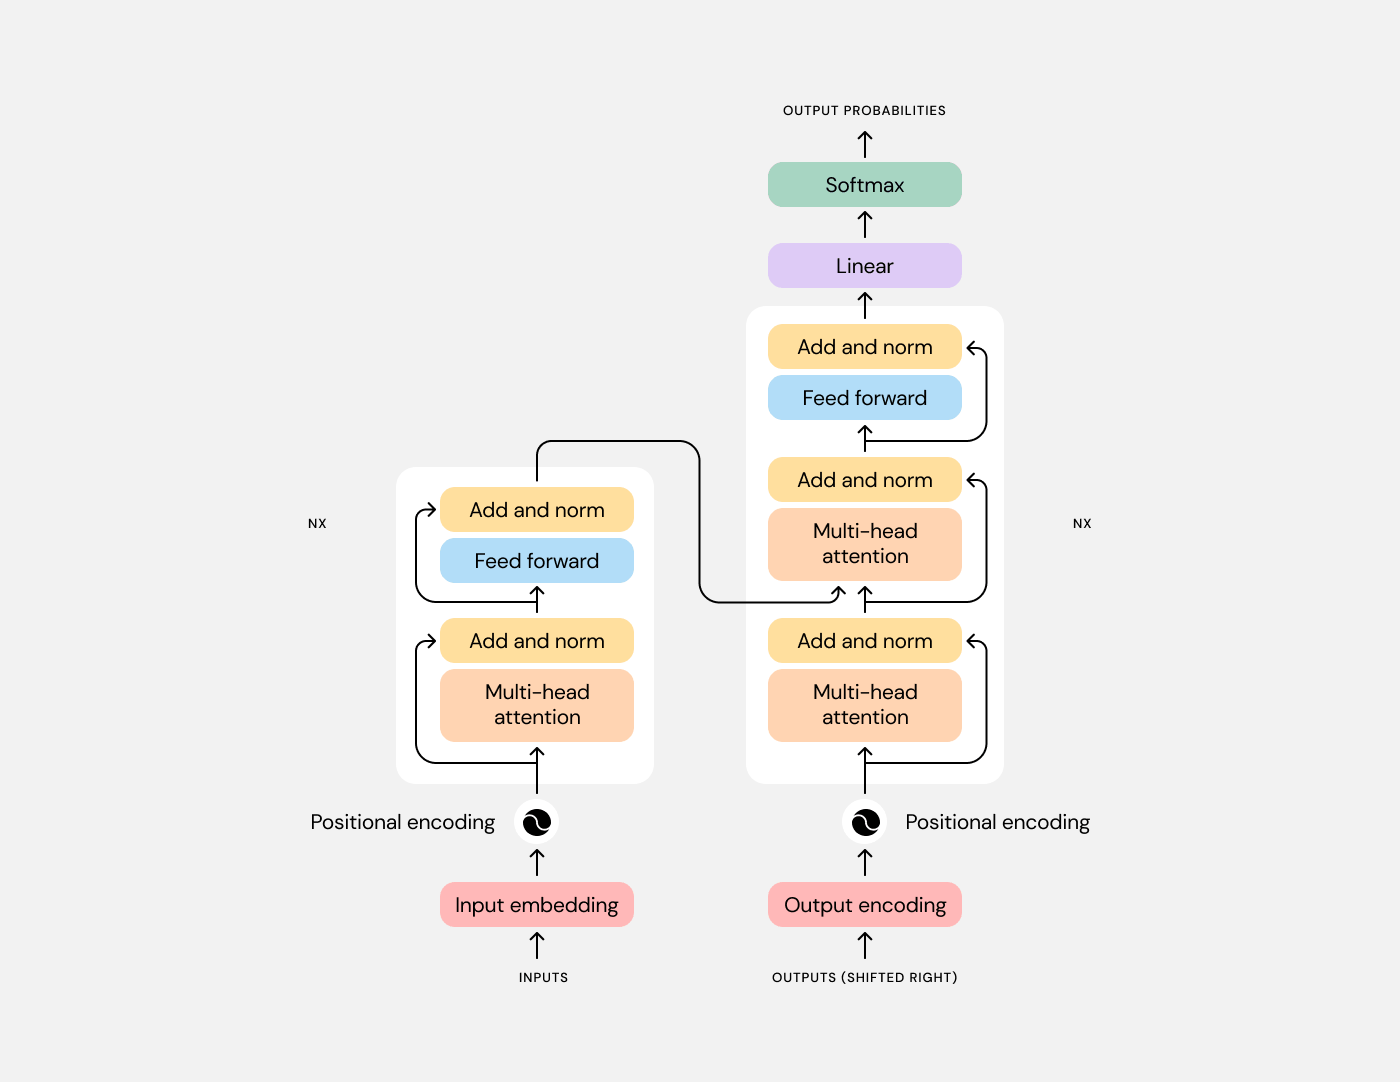
Architecture Specification 1.2: Feature Extraction and Layer Formulations for Gpt3 Applications. The primary computational backbone for Gpt3 Applications incorporates hierarchical deep neural layers designed for multi-scale representation extraction. Input tensors X in R^(B x C x H x W) pass through initial stem convolutions with Batch Normalization and GELU non-linearities. Residual identity skip connections, expressed as F(X) + X, prevent vanishing gradient degradation across deep topologies. Multi-head self-attention mechanisms compute Query, Key, and Value projections: Attention(Q, K, V) = softmax((Q * K^T) / sqrt(d_k)) * V, capturing non-local contextual dependencies across spatial and temporal sequences.
Data Pipeline 1.3: Stochastic Augmentation and Normalization Protocols for Gpt3 Applications. To prevent overfitting and maximize generalization on unseen testing distributions, input datasets undergo rigorous preprocessing. Images and sequences are standardized using z-score normalization: x_norm = (x - mu) / sigma. Stochastic augmentations include random horizontal flips, affine rotations (-15 deg to +15 deg), CutMix, and Mixup: X_tilde = lambda * X_i + (1 - lambda) * X_j, smoothing decision boundaries and reducing model overconfidence.
Deployment Optimization 1.4: TensorRT Acceleration and Edge Quantization for Gpt3 Applications. Production deployment of Gpt3 Applications focuses on minimizing memory footprints and sub-20ms inference latencies. Trained models are exported to ONNX and compiled via NVIDIA TensorRT. Post-Training Quantization (PTQ) maps FP32 weights into low-bit INT8 representations: q = round(r / S) + Z, achieving high-throughput execution across embedded edge platforms like NVIDIA Jetson without accuracy loss.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)