Complete Technical Paper Content — Handwriting Recognition Ai
1. Executive Abstract, Problem Formulation & Background
Handwriting recognition (HWR), also known as handwritten text recognition (HTR), is the ability of a computer to receive and interpret intelligible handwritten input from sources such as paper documents, photographs, touch-screens and other devices. The image of the written text may be sensed "off line" from a piece of paper by optical scanning (optical character recognition) or intelligent word recognition. Alternatively, the movements of the pen tip may be sensed "on line", for example by a pen-based computer screen surface, a generally easier task as there are more clues available. A handwriting recognition system handles formatting, performs correct segmentation into characters, and finds the most possible words.
a pen or stylus for the user to write with a touch sensitive surface, which may be integrated with, or adjacent to, an output display. a software application which interprets the movements of the stylus across the writing surface, translating the resulting strokes into digital text. The process of online handwriting recognition can be broken down into a few general steps:
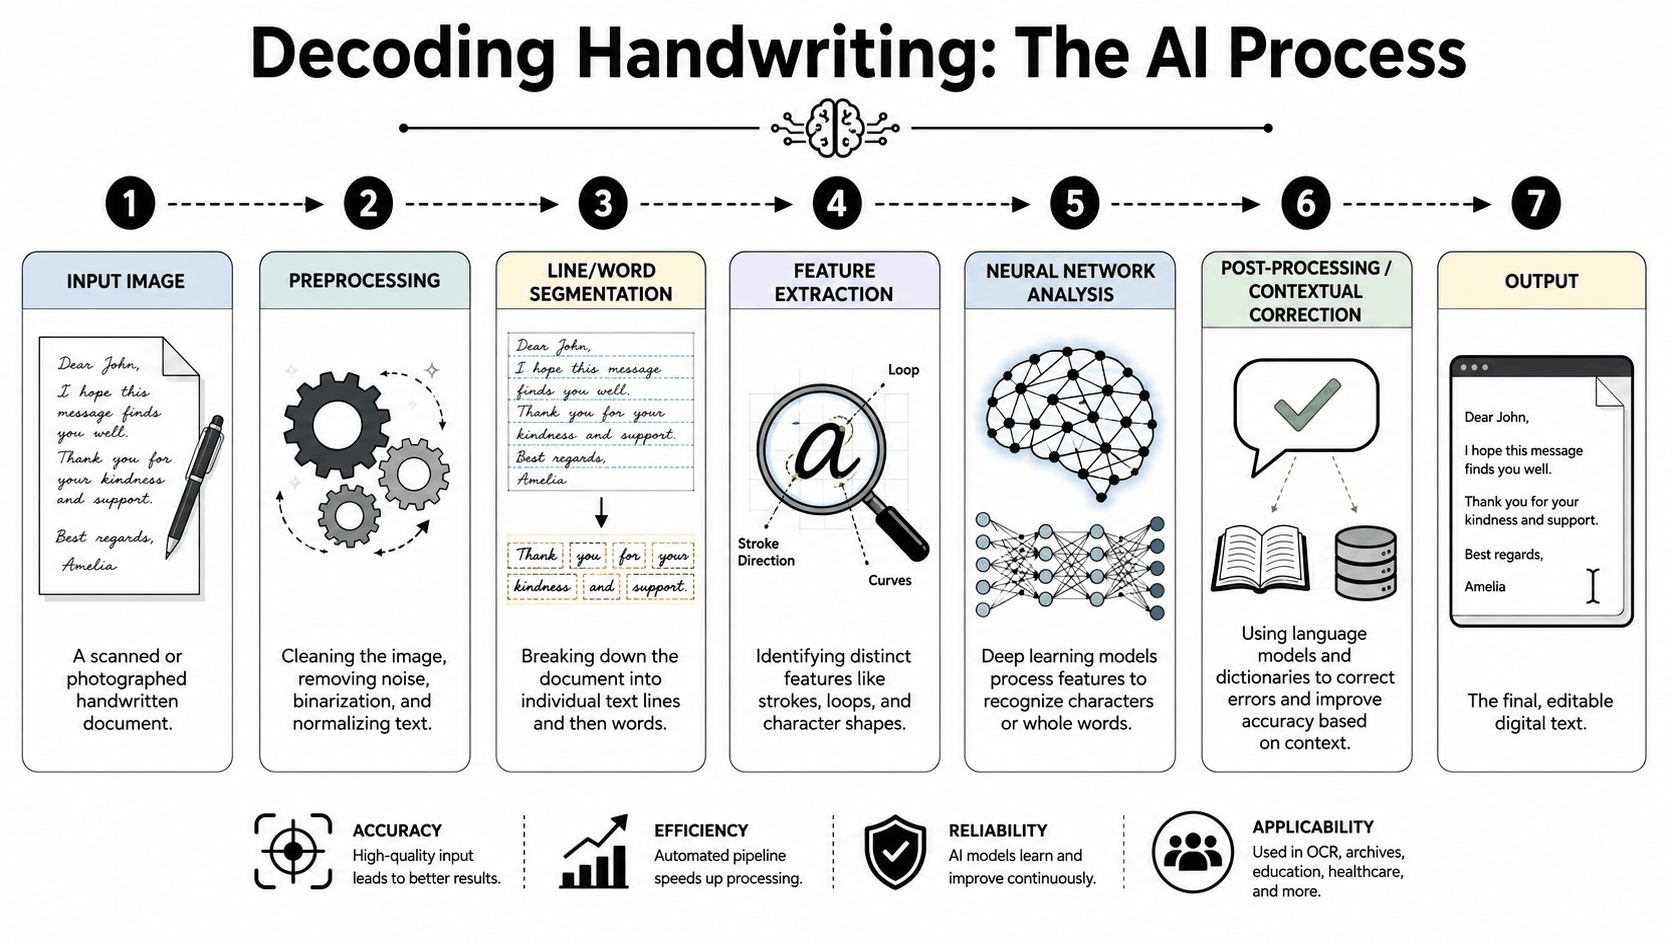
preprocessing, feature extraction and classification The purpose of preprocessing is to discard irrelevant information in the input data, that can negatively affect the recognition. This concerns speed and accuracy. Preprocessing usually consists of binarization, normalization, sampling, smoothing and denoising. The second step is feature extraction. Out of the two- or higher-dimensional vector field received from the preprocessing algorithms, higher-dimensional data is extracted. The purpose of this step is to highlight important information for the recognition model. This data may include information like pen pressure, velocity or the changes of writing direction. The last big step is classification. In this step, various models are used to map the extracted features to different classes and thus identifying the characters or words the features represent.
Handwriting recognition has an active community of academics studying it. The biggest conferences for handwriting recognition are the International Conference on Frontiers in Handwriting Recognition (ICFHR), held in even-numbered years, and the International Conference on Document Analysis and Recognition (ICDAR), held in odd-numbered years. Both of these conferences are endorsed by the IEEE and IAPR. In 2021, the ICDAR proceedings will be published by LNCS, Springer. Active areas of research include:
Online recognition Offline recognition Signature verification Postal address interpretation Bank-Check processing Writer recognition
Pattern recognition is the task of assigning a class to an observation based on patterns extracted from data. While similar, pattern recognition (PR) is not to be confused with pattern machines (PM) which may possess PR capabilities but their primary function is to distinguish and create emergent patterns. PR has applications in statistical data analysis, signal processing, image analysis, information retrieval, bioinformatics, data compression, computer graphics and machine learning. Pattern recognition has its origins in statistics and engineering; some modern approaches to pattern recognition include the use of machine learning, due to the increased availability of big data and a new abundance of processing power. Pattern recognition systems are commonly trained from labeled "training" data. When no labeled data are available, other algorithms can be used to discover previously unknown patterns. KDD and data mining have a larger focus on unsupervised methods and stronger connection to business use. Pattern recognition focuses more on the signal and also takes acquisition and signal processing into consideration. It originated in engineering, and the term is popular in the context of computer vision: a leading computer vision conference is named Conference on Computer Vision and Pattern Recognition. In machine learning, pattern recognition is the assignment of a label to a given input value. In statistics, discriminant analysis was introduced for this same purpose in 1936. An example of pattern recognition is classification, which attempts to assign each input value to one of a given set of classes (for example, determine whether a given email is "spam"). Pattern recognition is a more general problem that encompasses other types of output as well. Other examples are regression, which assigns a real-valued output to each input; sequence labeling, which assigns a class to each member of a sequence of values (for example, part of speech tagging, which assigns a part of speech to each word in an input sentence); and parsing, which assigns a parse tree to an input sentence, describing the syntactic structure of the sentence. Pattern recognition algorithms generally aim to provide a reasonable answer for all possible inputs and to perform "most likely" matching of the inputs, taking into account their statistical variation. This is opposed to pattern matching algorithms, which look for exact matches in the input with pre-existing patterns. A common example of a pattern-matching algorithm is regular expression matching, which looks for patterns of a given sort in textual data and is included in the search capabilities of many text editors and word processors.
The field of pattern recognition is concerned with the automatic discovery of regularities in data through the use of computer algorithms and with the use of these regularities to take actions such as classifying the data into different categories. Pattern recognition is generally categorized according to the type of learning procedure used to generate the output value. Supervised learning assumes that a set of training data (the training set) has been provided, consisting of a set of instances that have been properly labeled by hand with the correct output. A learning procedure then generates a model that attempts to meet two sometimes conflicting objectives: Perform as well as possible on the training data, and generalize as well as possible to new data (usually, this means being as simple as possible, for some technical definition of "simple", in accordance with Occam's Razor, discussed below). Unsupervised learning, on the other hand, assumes training data that has not been hand-labeled, and attempts to find inherent patterns in the data that can then be used to determine the correct output value for new data instances. A combination of the two that has been explored is semi-supervised learning, which uses a combination of labeled and unlabeled data (typically a small set of labeled data combined with a large amount of unlabeled data). In cases of unsupervised learning, there may be no training data at all. Sometimes different terms are used to describe the corresponding supervised and unsupervised learning procedures for the same type of output. The unsupervised equivalent of classification is normally known as clustering, based on the common perception of the task as involving no training data to speak of, and of grouping the input data into clusters based on some inherent similarity measure (e.g. the distance between instances, considered as vectors in a multi-dimensional vector space), rather than assigning each input instance into one of a set of pre-defined classes. In some fields, the terminology is different. In community ecology, the term classification is used to refer to what is commonly known as "clustering". The piece of input data for which an output value is generated is formally termed an instance. The instance is formally described by a vector of features, which together constitute a description of all known characteristics of the instance. These feature vectors can be seen as defining points in an appropriate multidimensional space, and methods for manipulating vectors in vector spaces can be correspondingly applied to them, such as computing the dot product or the angle between two vectors. Features typically are either categorical (also known as nominal, i.e., consisting of one of a set of unordered items, such as a gender of "male" or "female", or a blood type of "A", "B", "AB" or "O"), ordinal (consisting of one of a set of ordered items, e.g., "large", "medium" or "small"), integer-valued (e.g., a count of the number of occurrences of a particular word in an email) or real-valued (e.g., a measurement of blood pressure). Often, categorical and ordinal data are grouped together, and this is also the case for integer-valued and real-valued data. Many algorithms work only in terms of categorical data and require that real-valued or integer-valued data be discretized into groups (e.g., less than 5, between 5 and 10, or greater than 10).
Many common pattern recognition algorithms are probabilistic in nature, in that they use statistical inference to find the best label for a given instance. Unlike other algorithms, which simply output a "best" label, often probabilistic algorithms also output a probability of the instance being described by the given label. In addition, many probabilistic algorithms output a list of the N-best labels with associated probabilities, for some value of N, instead of simply a single best label. When the number of possible labels is fairly small (e.g., in the case of classification), N may be set so that the probability of all possible labels is output. Probabilistic algorithms have many advantages over non-probabilistic algorithms:
They output a confidence value associated with their choice. (Note that some other algorithms may also output confidence values, but in general, only for probabilistic algorithms is this value mathematically grounded in probability theory. Non-probabilistic confidence values can in general not be given any specific meaning, and only used to compare against other confidence values output by the same algorithm.) Correspondingly, they can abstain when the confidence of choosing any particular output is too low. Because of the probabilities output, probabilistic pattern-recognition algorithms can be more effectively incorporated into larger machine-learning tasks, in a way that partially or completely avoids the problem of error propagation.
Techniques to transform the raw feature vectors (feature extraction) are sometimes used prior to application of the pattern-matching algorithm. Feature extraction algorithms attempt to reduce a large-dimensionality feature vector into a smaller-dimensionality vector that is easier to work with and encodes less redundancy, using mathematical techniques such as principal components analysis (PCA). The distinction between feature selection and feature extraction is that the resulting features after feature extraction has taken place are of a different sort than the original features and may not easily be interpretable, while the features left after feature selection are simply a subset of the original features.
p ( l a b e l | x , θ ) = f ( x ; θ ) {\displaystyle p({\rm {label}}|{\boldsymbol {x}},{\boldsymbol {\theta }})=f\left({\boldsymbol {x}};{\boldsymbol {\theta }}\right)}
where the feature vector input is x {\displaystyle {\boldsymbol {x}}} , and the function f is typically parameterized by some parameters θ {\displaystyle {\boldsymbol {\theta }}} . In a discriminative approach to the problem, f is estimated directly. In a generative approach, however, the inverse probability p ( x | l a b e l ) {\displaystyle p({{\boldsymbol {x}}|{\rm {label}}})} is instead estimated and combined with the prior probability p ( l a b e l | θ ) {\displaystyle p({\rm {label}}|{\boldsymbol {\theta }})} using Bayes' rule, as follows:
2. Related Work, Literature Survey & Algorithmic Foundations
p ( l a b e l | x , θ ) = p ( x | l a b e l , θ ) p ( l a b e l | θ ) ∑ L ∈ all labels p ( x | L ) p ( L | θ ) . {\displaystyle p({\rm {label}}|{\boldsymbol {x}},{\boldsymbol {\theta }})={\frac {p({{\boldsymbol {x}}|{\rm {label,{\boldsymbol {\theta }}}}})p({\rm {label|{\boldsymbol {\theta }}}})}{\sum _{L\in {\text{all labels}}}p({\boldsymbol {x}}|L)p(L|{\boldsymbol {\theta }})}}.}
When the labels are continuously distributed (e.g., in regression analysis), the denominator involves integration rather than summation:
p ( l a b e l | x , θ ) = p ( x | l a b e l , θ ) p ( l a b e l | θ ) ∫ L ∈ all labels p ( x | L ) p ( L | θ ) d L . {\displaystyle p({\rm {label}}|{\boldsymbol {x}},{\boldsymbol {\theta }})={\frac {p({{\boldsymbol {x}}|{\rm {label,{\boldsymbol {\theta }}}}})p({\rm {label|{\boldsymbol {\theta }}}})}{\int _{L\in {\text{all labels}}}p({\boldsymbol {x}}|L)p(L|{\boldsymbol {\theta }})\operatorname {d} L}}.}
The value of θ {\displaystyle {\boldsymbol {\theta }}} is typically learned using maximum a posteriori (MAP) estimation. This finds the best value that simultaneously meets two conflicting objects: To perform as well as possible on the training data (smallest error-rate) and to find the simplest possible model. Essentially, this combines maximum likelihood estimation with a regularization procedure that favors simpler models over more complex models. In a Bayesian context, the regularization procedure can be viewed as placing a prior probability p ( θ ) {\displaystyle p({\boldsymbol {\theta }})} on different values of θ {\displaystyle {\boldsymbol {\theta }}} . Mathematically:
θ ∗ = arg max θ p ( θ | D ) {\displaystyle {\boldsymbol {\theta }}^{*}=\arg \max _{\boldsymbol {\theta }}p({\boldsymbol {\theta }}|\mathbf {D} )}
where θ ∗ {\displaystyle {\boldsymbol {\theta }}^{*}} is a point estimate (such as the MAP estimate) used for θ {\displaystyle {\boldsymbol {\theta }}} in point-estimate evaluation, and p ( θ | D ) {\displaystyle p({\boldsymbol {\theta }}|\mathbf {D} )} , the posterior probability of θ {\displaystyle {\boldsymbol {\theta }}} , is given by Bayes' theorem:
p ( θ | D ) = [ ∏ i = 1 n p ( y i | x i , θ ) ] p ( θ ) p ( D ) ∝ [ ∏ i = 1 n p ( y i | x i , θ ) ] p ( θ ) , {\displaystyle p({\boldsymbol {\theta }}|\mathbf {D} )={\frac {\left[\prod _{i=1}^{n}p(y_{i}|{\boldsymbol {x}}_{i},{\boldsymbol {\theta }})\right]p({\boldsymbol {\theta }})}{p(\mathbf {D} )}}\propto \left[\prod _{i=1}^{n}p(y_{i}|{\boldsymbol {x}}_{i},{\boldsymbol {\theta }})\right]p({\boldsymbol {\theta }}),}
where D = { ( x i , y i ) } i = 1 n {\displaystyle \mathbf {D} =\{({\boldsymbol {x}}_{i},y_{i})\}_{i=1}^{n}} represents the training dataset, and
p ( D ) = ∫ [ ∏ i = 1 n p ( y i | x i , θ ) ] p ( θ ) d θ {\displaystyle p(\mathbf {D} )=\int \left[\prod _{i=1}^{n}p(y_{i}|{\boldsymbol {x}}_{i},{\boldsymbol {\theta }})\right]p({\boldsymbol {\theta }})\,d{\boldsymbol {\theta }}}
is the marginal likelihood (or Bayesian evidence). In the full Bayesian approach, instead of selecting a single parameter vector θ ∗ {\displaystyle {\boldsymbol {\theta }}^{*}} , the probability of a label y ∗ {\displaystyle y^{*}} for a new query instance x ∗ {\displaystyle {\boldsymbol {x}}^{*}} given the dataset D {\displaystyle \mathbf {D} } is computed by integrating over all possible values of θ {\displaystyle {\boldsymbol {\theta }}} , weighted according to the posterior probability:
p ( y ∗ | x ∗ , D ) = ∫ p ( y ∗ | x ∗ , θ ) p ( θ | D ) d θ = 1 p ( D ) ∫ p ( y ∗ | x ∗ , θ ) [ ∏ i = 1 n p ( y i | x i , θ ) ] p ( θ ) d θ . {\displaystyle p(y^{*}|{\boldsymbol {x}}^{*},\mathbf {D} )=\int p(y^{*}|{\boldsymbol {x}}^{*},{\boldsymbol {\theta }})p({\boldsymbol {\theta }}|\mathbf {D} )\operatorname {d} {\boldsymbol {\theta }}={\frac {1}{p(\mathbf {D} )}}\int p(y^{*}|{\boldsymbol {x}}^{*},{\boldsymbol {\theta }})\left[\prod _{i=1}^{n}p(y_{i}|{\boldsymbol {x}}_{i},{\boldsymbol {\theta }})\right]p({\boldsymbol {\theta }})\operatorname {d} {\boldsymbol {\theta }}.}
Within medical science, pattern recognition is the basis for computer-aided diagnosis (CAD) systems. CAD describes a procedure that supports the doctor's interpretations and findings. Other typical applications of pattern recognition techniques are automatic speech recognition, speaker identification, classification of text into several categories (e.g., spam or non-spam email messages), the automatic recognition of handwriting on postal envelopes, automatic recognition of images of human faces, or handwriting image extraction from medical forms. The last two examples form the subtopic image analysis of pattern recognition that deals with digital images as input to pattern recognition systems. Optical character recognition is an example of the application of a pattern classifier. The method of signing one's name was captured with stylus and overlay starting in 1990. The strokes, speed, relative min, relative max, acceleration and pressure is used to uniquely identify and confirm identity. Banks were first offered this technology, but were content to collect from the FDIC for any bank fraud and did not want to inconvenience customers. Pattern recognition has many real-world applications in image processing. Some examples include:
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
identification and authentication: e.g., license plate recognition, fingerprint analysis, face detection/verification, and voice-based authentication. medical diagnosis: e.g., screening for cervical cancer (Papnet), breast tumors or heart sounds; defense: various navigation and guidance systems, target recognition systems, shape recognition technology etc. mobility: advanced driver assistance systems, autonomous vehicle technology, etc. In psychology, pattern recognition is used to make sense of and identify objects, and is closely related to perception. This explains how the sensory inputs humans receive are made meaningful. Pattern recognition can be thought of in two different ways. The first concerns template matching and the second concerns feature detection. A template is a pattern used to produce items of the same proportions. The template-matching hypothesis suggests that incoming stimuli are compared with templates in the long-term memory. If there is a match, the stimulus is identified. Feature detection models, such as the Pandemonium system for classifying letters (Selfridge, 1959), suggest that the stimuli are broken down into their component parts for identification. One observation is a capital E having three horizontal lines and one vertical line.
Linear discriminant analysis Quadratic discriminant analysis Maximum entropy classifier (aka logistic regression, multinomial logistic regression): Note that logistic regression is an algorithm for classification, despite its name. (The name comes from the fact that logistic regression uses an extension of a linear regression model to model the probability of an input being in a particular class.) Nonparametric:
Decision trees, decision lists Kernel estimation and K-nearest-neighbor algorithms Naive Bayes classifier Neural networks (multi-layer perceptrons) Perceptrons Support vector machines Gene expression programming
Categorical mixture models Hierarchical clustering (agglomerative or divisive) K-means clustering Correlation clustering Kernel principal component analysis (Kernel PCA)
Boosting (meta-algorithm) Bootstrap aggregating ("bagging") Ensemble averaging Mixture of experts, hierarchical mixture of experts
Gaussian process regression (kriging) Linear regression and extensions Independent component analysis (ICA) Principal components analysis (PCA)
OCR tools achieve over 99% accuracy on typed text in high-quality images. However, handwriting remains challenging due to variations in style, spacing, and irregularities. We introduce a cursive handwriting recognition benchmark with 100 handwriting samples written by our team to prevent overfitting.
In this benchmark, GPT-5, Gemini 3 Pro Preview, and olmOCR-2-7B-1025-FP8 are the top-performing models, achieving the highest semantic similarity scores and the most consistent interpretation of cursive text across all samples.
Across 100 cursive handwriting samples written by 10 writers, Gemini 3 Pro Preview achieved a perfect score, while Deepseek OCR recorded 79%.
For this benchmark, 10 writers handwrote 10 paragraphs each in cursive, resulting in a dataset of 100 cursive handwriting samples. Writers were not asked to write neatly. Natural letter connectivity, stroke variability, spacing distortion, and line fluidity were intentionally preserved to reflect realistic cursive complexity.
All samples were evaluated using our unified OCR assessment pipeline, based on cosine similarity for fair comparison.
Handwriting recognition, also known as handwriting OCR or cursive OCR, is a subfield of OCR technology that translates handwritten letters to corresponding digital text or commands in real time. To perform this task, these systems benefit from pattern matching to identify various styles of handwritten letters. Wikipedia defines handwriting recognition as:
4. Neural Network Backbone, Layer Specifications & Loss Formulations
The ability of a computer to receive and interpret intelligible handwritten input from sources such as paper documents, photographs, touch-screens, and other devices.
LLM handwriting recognition abilities are also highly developed, in our benchmark, gemini-3-pro is 100% accurate.
By handwriting, we refer to texts written in manuscript and cursive form. Texts in manuscript style are easier to recognize as the characters are written separately as block letters. However, cursive handwriting involves joined characters as they are written.
This aspect necessitates handwriting recognition tools to perceive each separate character correctly and identify them accurately. Below are examples of manuscript and cursive writing.
Handwriting recognition tools can also identify handwriting on digital screens. This kind of handwriting can be tracked as it is written. The software can leverage your dynamic motion to provide more accurate results. Below is an example of digital handwriting recognition, provided by Microsoft Azure Ink Recognizer API.
Even though traditional OCR tools have been in the market since the 70s, there are still not many tools that can handle handwriting recognition. As everyone has their own style of writing, traditional OCR tools cannot perceive everyone’s handwriting.
Besides computer vision technology, highly complex deep learning algorithms are required to identify all these variations successfully. Below is a list of challenges that handwriting recognition tools frequently encounter:
Modern HTR tools combine computer vision with deep learning to overcome these challenges. These approaches go beyond traditional OCR, which has been around since the 1970s but still struggles with handwriting. Today, progress is being made through:
There are a variety of factors to consider while designing documents. The most important one is the data to be captured from documents. As there are different ways to represent the same type of data, you need to consider the speed, accuracy, and user-friendliness of each option while constructing your document. 2 , 3 , 4
Segmentation is the process of breaking down the image into smaller, more manageable components, such as text lines, words, and individual characters. To ensure that, businesses can use segmentation methods, which you can see below.
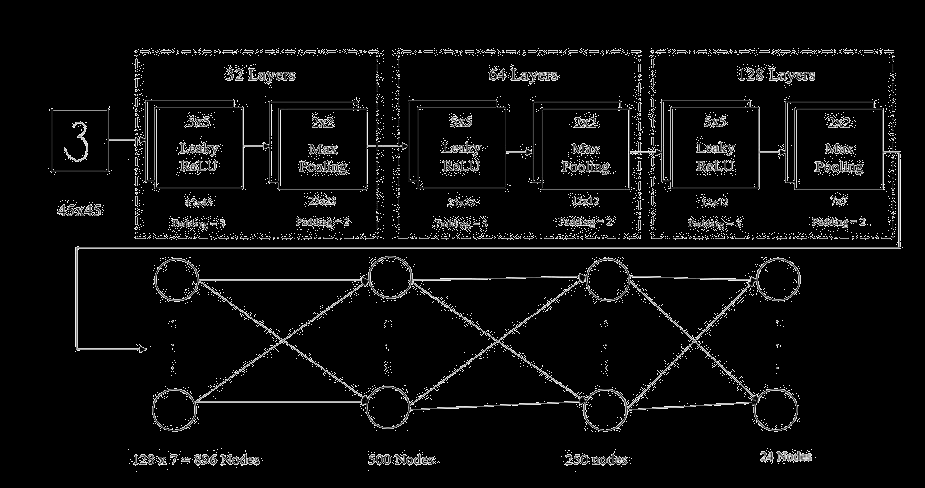
As handwriting recognition capability highly depends on neural networks, advances in these algorithms profoundly affect the performance of handwriting recognition tools. Thus, active research on handwriting recognition is based on neural network algorithms.
Google is also using language processing algorithms to improve handwriting recognition performance. For example, if the tool needs to decide between “i” and “l,” it can analyze the whole word and decide on the suitable character to provide accurate results.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
OCR software usually has several handwriting recognition engines integrated into the software. These engines work synchronously to generate the most accurate character representation corresponding to the input.
As handwriting recognition is a subfield of OCR, the criteria for choosing the proper handwriting recognition are similar to those of OCR tools. While selecting a handwriting recognition vendor, you should consider the following factors:
In addition to these, procurement best practices such as ensuring minimum Total Cost of Ownership (TCO), flexibility, data security best practices, and avoiding vendor lock-in are essential.
Below you can find a short list of handwriting vendors. You should also keep in mind that these vendors can also provide OCR services for your business.
Use a cursive reader or handwriting recognition software to help decipher illegible handwriting Straighten and flatten paper notes to prevent skewing or distortion, and get as high-quality scanned documents as possible Use optical character recognition (OCR) software to convert scanned images or photographs of handwritten text. Export converted digital text to PDF files or other formats for sharing or storage
Look for features such as character recognition, digital ink, and block letters support
If you want to read more about handwriting recognition tools, these articles can also interest you:
Pick the format that matches where you're publishing. Pasting the link version into your CMS preserves the backlink.
@misc{dilmegani2026, author = {Dilmegani, Cem and Arslan, Ezgi}, title = {{Handwriting Recognition Benchmark with 14 LLMs & OCRs}}, year = {2026}, month = aug, howpublished = {\url{https://aimultiple.com/handwriting-recognition}}, note = {AIMultiple. Retrieved August 25, 2026} }
Results and timestamps of 14 data points. Download the summary data shown in this article's charts and tables as a ZIP file containing one CSV file.
Your email address will not be published. All fields are required. Comments are left in their original language.
Hi Cem, your article is very clear and practical. Thank you for sharing your knowledge! It will be very useful for me.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)