Complete Technical Paper Content — Homomorphic Encryption Ml
1. Executive Abstract, Problem Formulation & Background
Lattice-based cryptography is the generic term for constructions of cryptographic primitives that involve lattices, either in the construction itself or in the security proof. Lattice-based constructions support important standards of post-quantum cryptography. Unlike more widely used and known public-key schemes such as the RSA, Diffie-Hellman or elliptic-curve cryptosystems—which could, theoretically, be defeated using Shor's algorithm on a quantum computer—some lattice-based constructions appear to be resistant to attack by both classical and quantum computers. Furthermore, many lattice-based constructions are considered to be secure under the assumption that certain well-studied computational lattice problems cannot be solved efficiently. In 2024 NIST announced the Module-Lattice-Based Digital Signature Standard for post-quantum cryptography.
L = { ∑ a i b i : a i ∈ Z } . {\displaystyle L={\Big \{}\sum a_{i}\mathbf {b} _{i}:a_{i}\in \mathbb {Z} {\Big \}}.}
For example, Z n {\displaystyle \mathbb {Z} ^{n}} is a lattice, generated by the standard basis for R n {\displaystyle \mathbb {R} ^{n}} . Crucially, the basis for a lattice is not unique. For example, the vectors ( 3 , 1 , 4 ) {\displaystyle (3,1,4)} , ( 1 , 5 , 9 ) {\displaystyle (1,5,9)} , and ( 2 , − 1 , 0 ) {\displaystyle (2,-1,0)} form an alternative basis for Z 3 {\displaystyle \mathbb {Z} ^{3}} . The most important lattice-based computational problem is the shortest vector problem (SVP or sometimes GapSVP), which asks for an approximate minimal Euclidean length of a non-zero lattice vector. This problem is thought to be hard to solve efficiently, even with approximation factors that are polynomial in n {\displaystyle n} , and even with a quantum computer. Many (though not all) lattice-based cryptographic constructions are known to be secure if SVP is in fact hard in this regime.
GGH encryption scheme, which is based in the closest vector problem (CVP). In 1999, Nguyen published a critical flaw in the scheme's design. NTRUEncrypt.
CRYSTALS-Kyber, which is built upon module learning with errors (module-LWE). Kyber was selected for standardization by the NIST in 2023. In August 2023, NIST published FIPS 203 (Initial Public Draft), and started referring to their Kyber version as Module-Lattice-based Key Encapsulation Mechanism (ML-KEM). FrodoKEM, a scheme based on the learning with errors (LWE) problem. FrodoKEM joined the standardization call conducted by the National Institute of Standards and Technology (NIST), and lived up to the 3rd round of the process. It was then discarded due to low performance reasons. In October, 2022, the Twitter account associated to cryptologist Daniel J. Bernstein posted security issues in frodokem640. NewHope is based on the ring learning with errors (RLWE) problem. NTRU Prime. Peikert's work, which is based on the ring learning with errors (RLWE) problem. Saber, which is based on the module learning with rounding (module-LWR) problem.
CRYSTALS-Dilithium, which is built upon module learning with errors (module-LWE) and module short integer solution (module-SIS). Dilithium was selected for standardization by the NIST. According to a message from Ray Perlner, writing on behalf of the NIST PQC team, the NIST module-LWE signing standard is to be based on version 3.1 of the Dilithium specification. Falcon, which is built upon short integer solution (SIS) over NTRU. Falcon was selected for standardization by the NIST. GGH signature scheme. Güneysu, Lyubashevsky, and Pöppelmann's work, which is based on ring learning with errors (RLWE). MITAKA, a variant of Falcon. NTRUSign. qTESLA, which is based on ring learning with errors (RLWE). The qTESLA scheme joined the standardization call conducted by the National Institute of Standards and Technology (NIST).
Flux is an open-source machine-learning software library and ecosystem written in Julia. Its current stable release is v0.16.5 . It has a layer-stacking-based interface for simpler models, and has a strong support on interoperability with other Julia packages instead of a monolithic design. For example, GPU support is implemented transparently by CuArrays.jl. This is in contrast to some other machine learning frameworks which are implemented in other languages with Julia bindings, such as TensorFlow.jl (the unofficial wrapper, now deprecated), and thus are more limited by the functionality present in the underlying implementation, which is often in C or C++. Flux joined NumFOCUS as an affiliated project in December of 2021. Flux's focus on interoperability has enabled, for example, support for Neural Differential Equations, by fusing Flux.jl and DifferentialEquations.jl into DiffEqFlux.jl. Flux supports recurrent and convolutional networks. It is also capable of differentiable programming through its source-to-source automatic differentiation package, Zygote.jl. Julia is a popular language in machine-learning and Flux.jl is its most highly regarded machine-learning repository (Lux.jl is another more recent, that shares a lot of code with Flux.jl). A demonstration compiling Julia code to run in Google's tensor processing unit (TPU) received praise from Google Brain AI lead Jeff Dean. Flux has been used as a framework to build neural networks that work with homomorphic encrypted data without ever decrypting it. This kind of application is envisioned to be central for privacy to future API using machine-learning models. Flux.jl is an intermediate representation for running high level programs on CUDA hardware. It was the predecessor to CUDAnative.jl which is also a GPU programming language.
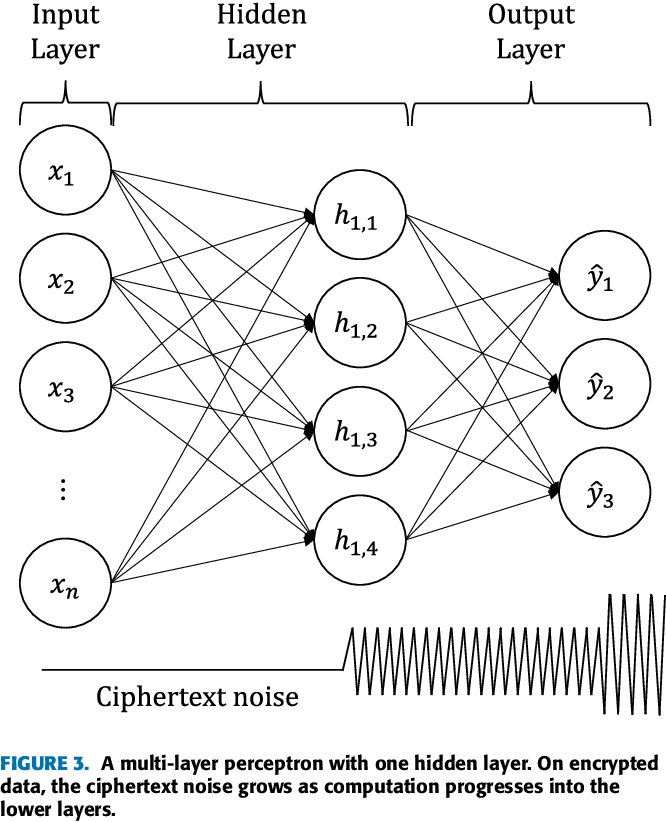
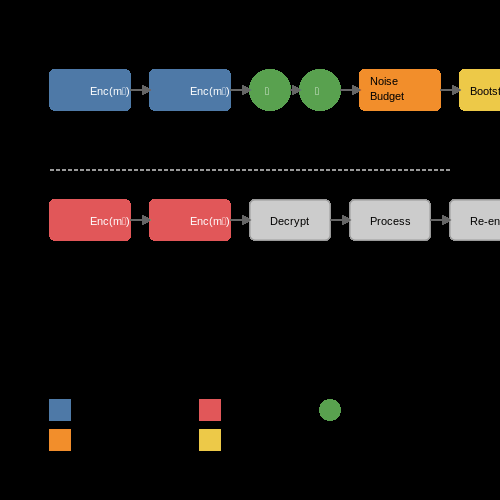
CryptoDL How to install These steps assume your are running Ubuntu. First step Clone this repository Install Dependency Packages CryptoDL/dependencies/ contains scripts and information to install and build the required dependencies. Run config_system.sh as root to install the depencies that are availabe via the package manager. After that run install_dependencies.sh from CryptoDL/dependencies/ directory. This downloads and builds dependcies not only availalbe from source or that require specific configuration. Building CryptoDL To build CrptoDL simply run make in the CryptoDL/Debug directory. This builds a static library libkalypso.a which other projects can link against. To make linking easier CryptoDL/dependencies/versions.sh creates varialbes that you can use in your build scripts. An example build script can looks like this. All you need to is set the CRYPTODL_DIR variable to where you coloned the repository. $(shell $(CRYPTODL_DIR)/dependencies/versions.sh) -include $(CRYPTODL_DIR)/dependencies/makefile.versions g++ -std=c++17 -Wall $(INCLUDE_DIRS) $(DEP_INCLUDES) -c example.cpp g++ -std=c++17 -o "example" example.o $(CRYPTODL_DIR)/Debug/libkalypso.a $(DEP_LIBS) $(DEP_RPATH) What is this repository for? This project aims to provide Deep Learning with a privacy preserving computation backend. The privacy preserving computation is based on homomorphic encryption (HE). Homomorphic encryption allows for computation on encrypted data, get an encrypted result without the need to decrypt the data for any of the computation. These properties come with a number of restrictions and things to look out for. We aim to provide a library that provides privacy preserving deep learning for people with a deep learning background without needing to dig into HE, aswell as the abiltity to easily integrate different HE libraries as computation backends. What is supported at the moment? Deep Learning So far we support the following types of layers: 2D Convolutional Fully Connected Fully Connected Recurrent Layer We support a number of activation functions: Linear Square ReLU ( not useable with the HE backend ) Polynomials We only support inference. Training is not supported and needs to be done with other tools/frameworks. As of now there is no automated way of importing pretrained models. The current suggested workflow is: Train model using keras Use provided tools to extract weights Define model in C++ and import weights Models that are supposed to used with our code may only use these layers and activation functions. HE Backend Currently we only support HELib library as a computational backend (other than plaintext). Limitations HE places a number of constraints and limitations on the type of computation that can be performed. This is supposed to be a list of the main points to be aware off. It is not meant to be comprehenisve. No Division Division of ciphertexts is not supported No comparison There is no comparison between ciphertext, e.g. no max, min, etc. This means we can not use ReLU, MaxPooling, etc. Limited number of computations Every computation performed on a ciphertext adds some additional noise to the ciphertext. If the noise exceeds some threshold we can not decrypt it correctly anymore. Therefore we can not run an arbitrary number of computations Limited support of Activation functions, Layers Due the constraints mentioned above we can not use every activation function or layer that we normally can. We suggest using poynomials as activation functions. Contribution guidelines TBD Who do I talk to? Contact: rpodschwadt1@student.gsu.edu
CryptoDL/dependencies/ contains scripts and information to install and build the required dependencies.
Run config_system.sh as root to install the depencies that are availabe via the package manager.
from CryptoDL/dependencies/ directory. This downloads and builds dependcies not only availalbe from source or that require specific configuration.
2. Related Work, Literature Survey & Algorithmic Foundations
in the CryptoDL/Debug directory. This builds a static library libkalypso.a which other projects can link against.
To make linking easier CryptoDL/dependencies/versions.sh creates varialbes that you can use in your build scripts.
An example build script can looks like this. All you need to is set the CRYPTODL_DIR variable to where you coloned the repository.
$(shell $(CRYPTODL_DIR)/dependencies/versions.sh) -include $(CRYPTODL_DIR)/dependencies/makefile.versions g++ -std=c++17 -Wall $(INCLUDE_DIRS) $(DEP_INCLUDES) -c example.cpp g++ -std=c++17 -o "example" example.o $(CRYPTODL_DIR)/Debug/libkalypso.a $(DEP_LIBS) $(DEP_RPATH)
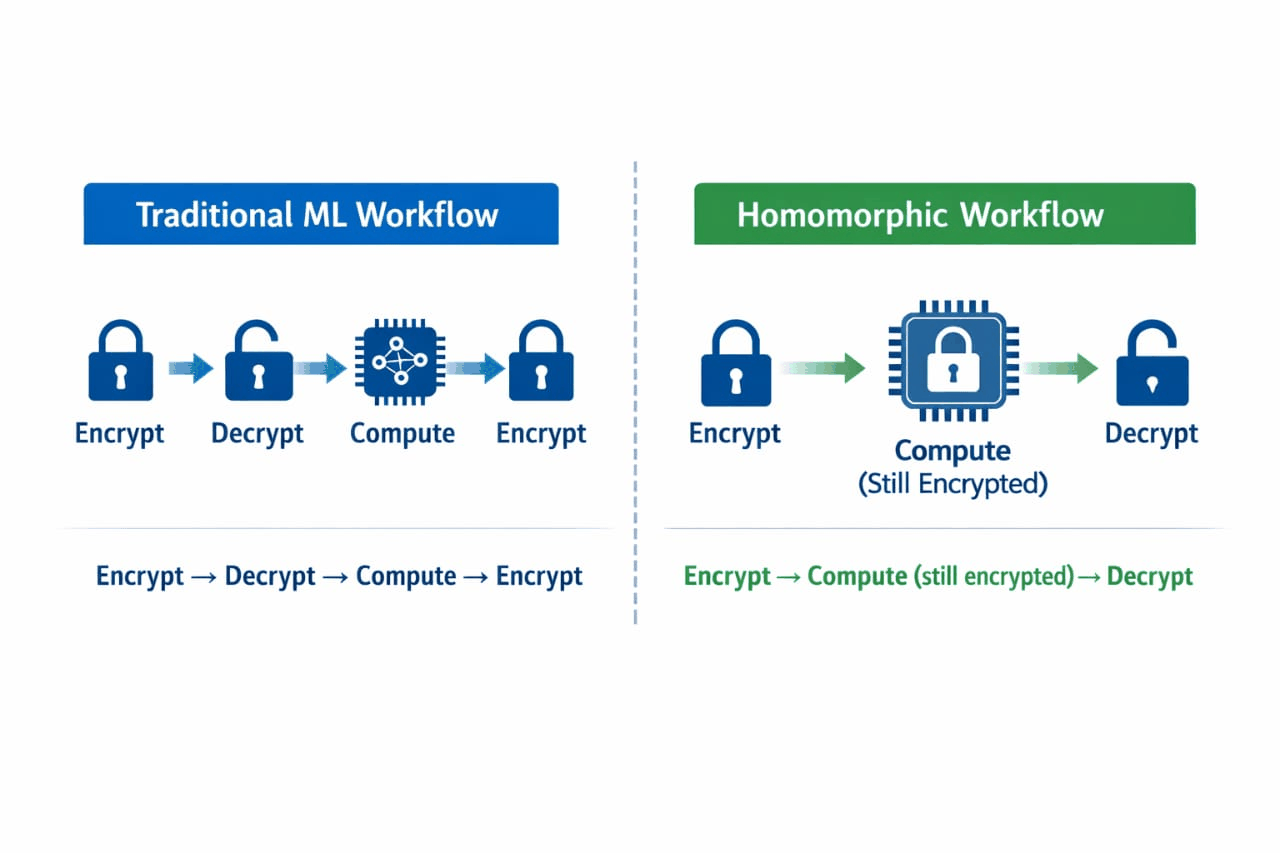
This project aims to provide Deep Learning with a privacy preserving computation backend. The privacy preserving computation is based on homomorphic encryption (HE). Homomorphic encryption allows for computation on encrypted data, get an encrypted result without the need to decrypt the data for any of the computation. These properties come with a number of restrictions and things to look out for. We aim to provide a library that provides privacy preserving deep learning for people with a deep learning background without needing to dig into HE, aswell as the abiltity to easily integrate different HE libraries as computation backends.
We only support inference. Training is not supported and needs to be done with other tools/frameworks. As of now there is no automated way of importing pretrained models. The current suggested workflow is:
Currently we only support HELib library as a computational backend (other than plaintext).
HE places a number of constraints and limitations on the type of computation that can be performed. This is supposed to be a list of the main points to be aware off. It is not meant to be comprehenisve.
Zama Concrete ML: Simplifying Homomorphic Encryption for Python Machine Learning Zama creates open-source tools that bring Fully Homomorphic Encryption (FHE) to blockchain and AI developers. FHE is a cryptographic technique that enables computations on encrypted data without needing to decrypt it or access the private key. This approach is invaluable in industries requiring strong privacy protections—such as healthcare, finance, advertising, and defense. FHE not only ensures trust when outsourcing machine learning tasks to the cloud, but also facilitates collaborative analytics between multiple parties, all while keeping the data secure and private throughout the entire process. Concrete ML: a user-friendly Python Package with classical APIs To simplify the adoption of FHE, which involves a complex and resource-intensive technological stack, we developed tools that streamline the integration of FHE into applications. Since Python is the de facto standard for building machine learning (ML) applications, it was an obvious choice to create an open-source FHE library in Python. The library features APIs that closely resemble those of familiar ML libraries, making it accessible to machine learning practitioners. For classical machine learning models, we drew inspiration from the API of scikit-learn , the leading ML library that supports a wide range of models, including linear models, decision trees, and random forests. from concrete . ml . sklearn import LogisticRegression model = LogisticRegression ( n_bits = 12 ) model . fit ( X_train , y_train ) model . predict ( X_test ) model . compile ( X_train ) model . predict ( X_test , fhe = "simulate" ) model . predict ( X_test , fhe = "execute" ) from concrete . ml . sklearn import XGBClassifier model = XGBClassifier ( n_bits = 8 ) model . fit ( X_train , y_train ) model . predict ( X_test ) model . compile ( X_train ) model . predict ( X_test , fhe = "simulate" ) model . predict ( X_test , fhe = "execute" ) For deep learning models, we decided to support PyTorch through the intermediary of ONNX, the open standard for machine learning interoperability. import torch import torch . nn as nn import torch . nn . functional as F from concrete . ml . torch . compile import compile_torch_model class SimpleNet ( nn . Module ): def __init__ ( self ): super (). __init__ () self . fc1 = nn . Linear ( 784 , 30 ) self . fc2 = nn . Linear ( 30 , 30 ) self . fc3 = nn . Linear ( 30 , 2 ) def forward ( self , x ): x = F . relu ( self . fc1 ( x )) x = F . relu ( self . fc2 ( x )) x = self . fc3 ( x ) return x model = SimpleNet () input_data = torch . randn ( 100 , 784 ) quantized_fhe_module = compile_torch_model ( model , input_data , n_bits = 8 ) Finally, for DataFrames, Concrete ML took inspiration from pandas . from concrete . ml . pandas import ClientEngine from io import StringIO import pandas data_left = """index,total_bill,tip,sex,smoker 1,12.54,2.5,Male,No 2,11.17,1.5,Female,No 3,20.29,2.75,Female,No """ # Load your pandas DataFrame df = pandas . read_csv ( StringIO ( data_left )) # Obtain client object client = ClientEngine ( keys_path = "my_keys" ) # Encrypt the DataFrame df_encrypted = client . encrypt_from_pandas ( df ) # Decrypt the DataFrame to produce a pandas DataFrame df_decrypted = client . decrypt_to_pandas ( df_encrypted ) Building with Concrete ML Both our ML framework and FHE compiler are open-source. Recently, external developers have used our libraries to build exciting FHE applications, such as an encrypted version of Shazam where songs are encrypted before matching to a database, and an encrypted DNA ancestry analysis solution that keeps the DNA encrypted throughout the entire process. Both our ML framework and FHE compiler are open-source. Recently, external developers have used our libraries to build exciting FHE applications, such as an encrypted version of Shazam where songs are encrypted before matching to a database, and an encrypted DNA ancestry analysis solution that keeps the DNA encrypted throughout the entire process. Ready to start building with FHE? Read the Concrete ML documentation Explore the comprehensive tutorials and demos About the authors Andrei Stoian, PhD, is head of the machine learning team at Zama. His main responsibility in this role is to oversee the development of Concrete ML, Zama's privacy preserving machine learning toolkit based on fully homomorphic encryption. In the past, Andrei worked on machine learning tools and algorithms for video analytics and satellite image processing on embedded systems. Andrei has co-authored more than 20 papers about machine learning applications and holds several patents. Benoit Chevallier-Mames is serving as VP of Cloud & Machine Learning at Zama. He has spent 20+ years between cryptographic research and secure implementations in a wide range of domains such as side-channel security, provable security, whitebox cryptography, and fully homomorphic encryption. Benoit has co-written 15+ peer-reviewed papers and is the co-author of 50+ patents. He holds a PhD from Ecole Normale Superieure / Paris University and a master's degree from CentraleSupelec.
Zama creates open-source tools that bring Fully Homomorphic Encryption (FHE) to blockchain and AI developers. FHE is a cryptographic technique that enables computations on encrypted data without needing to decrypt it or access the private key. This approach is invaluable in industries requiring strong privacy protections—such as healthcare, finance, advertising, and defense. FHE not only ensures trust when outsourcing machine learning tasks to the cloud, but also facilitates collaborative analytics between multiple parties, all while keeping the data secure and private throughout the entire process.
To simplify the adoption of FHE, which involves a complex and resource-intensive technological stack, we developed tools that streamline the integration of FHE into applications. Since Python is the de facto standard for building machine learning (ML) applications, it was an obvious choice to create an open-source FHE library in Python. The library features APIs that closely resemble those of familiar ML libraries, making it accessible to machine learning practitioners.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
For classical machine learning models, we drew inspiration from the API of scikit-learn , the leading ML library that supports a wide range of models, including linear models, decision trees, and random forests.
from concrete . ml . sklearn import LogisticRegression model = LogisticRegression ( n_bits = 12 ) model . fit ( X_train , y_train ) model . predict ( X_test ) model . compile ( X_train ) model . predict ( X_test , fhe = "simulate" ) model . predict ( X_test , fhe = "execute" )
from concrete . ml . sklearn import XGBClassifier model = XGBClassifier ( n_bits = 8 ) model . fit ( X_train , y_train ) model . predict ( X_test ) model . compile ( X_train ) model . predict ( X_test , fhe = "simulate" ) model . predict ( X_test , fhe = "execute" )
For deep learning models, we decided to support PyTorch through the intermediary of ONNX, the open standard for machine learning interoperability.
import torch import torch . nn as nn import torch . nn . functional as F from concrete . ml . torch . compile import compile_torch_model class SimpleNet ( nn . Module ): def __init__ ( self ): super (). __init__ () self . fc1 = nn . Linear ( 784 , 30 ) self . fc2 = nn . Linear ( 30 , 30 ) self . fc3 = nn . Linear ( 30 , 2 ) def forward ( self , x ): x = F . relu ( self . fc1 ( x )) x = F . relu ( self . fc2 ( x )) x = self . fc3 ( x ) return x model = SimpleNet () input_data = torch . randn ( 100 , 784 ) quantized_fhe_module = compile_torch_model ( model , input_data , n_bits = 8 )
from concrete . ml . pandas import ClientEngine from io import StringIO import pandas data_left = """index,total_bill,tip,sex,smoker 1,12.54,2.5,Male,No 2,11.17,1.5,Female,No 3,20.29,2.75,Female,No """ # Load your pandas DataFrame df = pandas . read_csv ( StringIO ( data_left )) # Obtain client object client = ClientEngine ( keys_path = "my_keys" ) # Encrypt the DataFrame df_encrypted = client . encrypt_from_pandas ( df ) # Decrypt the DataFrame to produce a pandas DataFrame df_decrypted = client . decrypt_to_pandas ( df_encrypted )
Both our ML framework and FHE compiler are open-source. Recently, external developers have used our libraries to build exciting FHE applications, such as an encrypted version of Shazam where songs are encrypted before matching to a database, and an encrypted DNA ancestry analysis solution that keeps the DNA encrypted throughout the entire process.
Both our ML framework and FHE compiler are open-source. Recently, external developers have used our libraries to build exciting FHE applications, such as an encrypted version of Shazam where songs are encrypted before matching to a database, and an encrypted DNA ancestry analysis solution that keeps the DNA encrypted throughout the entire process.
Andrei Stoian, PhD, is head of the machine learning team at Zama. His main responsibility in this role is to oversee the development of Concrete ML, Zama's privacy preserving machine learning toolkit based on fully homomorphic encryption. In the past, Andrei worked on machine learning tools and algorithms for video analytics and satellite image processing on embedded systems. Andrei has co-authored more than 20 papers about machine learning applications and holds several patents.
Benoit Chevallier-Mames is serving as VP of Cloud & Machine Learning at Zama. He has spent 20+ years between cryptographic research and secure implementations in a wide range of domains such as side-channel security, provable security, whitebox cryptography, and fully homomorphic encryption. Benoit has co-written 15+ peer-reviewed papers and is the co-author of 50+ patents. He holds a PhD from Ecole Normale Superieure / Paris University and a master's degree from CentraleSupelec.
Homomorphic Encryption in Machine Learning (HEML) Research Background This repository contains the implementation of the research paper accepted at the SNPD-2025 Conference (International Conference on Software, Networking, and Parallel/Distributed Computing). The study explores the integration of Homomorphic Encryption (HE) into Machine Learning (ML) workflows to enable secure computation on encrypted data without compromising model accuracy or efficiency. By leveraging TenSEAL , the project demonstrates how encrypted tensors can be used for training and inference, providing a strong foundation for privacy-preserving AI in sensitive domains such as healthcare, finance, and federated learning. https://www.researchgate.net/publication/395399493_Privacy-Preserving_Machine_Learning_for_Mental_Health_Prediction_Using_Homomorphic_Encryption?_tp=eyJjb250ZXh0Ijp7InBhZ2UiOiJwcm9maWxlIiwicHJldmlvdXNQYWdlIjpudWxsLCJwb3NpdGlvbiI6InBhZ2VDb250ZW50In19 Introduction This project investigates the application of Homomorphic Encryption (HE) within the domain of Machine Learning (ML) to enhance privacy-preserving capabilities. The implementation and evaluation focus on TenSEAL , which enables secure tensor operations and seamless integration of encryption in ML pipelines. Project Objective The main goal is to ensure that data remains encrypted throughout the entire computation process in machine learning models, providing robust privacy and end-to-end security in sensitive use cases. Features Implementation of HE Schemes – Multiple homomorphic encryption schemes implemented using TenSEAL for integration with ML algorithms. Performance Evaluation – Benchmarks model accuracy, training time, and encryption overhead under encrypted computation. Privacy Analysis – Evaluates privacy guarantees and performance trade-offs for each encryption scheme. Application Demonstration – Real-world demonstration of HE applied to privacy-sensitive ML scenarios. Technologies Used Python – Core programming language for encryption and ML model development. TenSEAL – For homomorphic encryption over tensors. TensorFlow / PyTorch – For training and evaluating machine learning models. Installation Clone the repository and install dependencies: git clone https://github.com/your-repository/homomorphic-encryption-ml.git cd homomorphic-encryption-ml pip install -r requirements.txt
4. Neural Network Backbone, Layer Specifications & Loss Formulations
This repository contains the implementation of the research paper accepted at the SNPD-2025 Conference (International Conference on Software, Networking, and Parallel/Distributed Computing).
The study explores the integration of Homomorphic Encryption (HE) into Machine Learning (ML) workflows to enable secure computation on encrypted data without compromising model accuracy or efficiency. By leveraging TenSEAL , the project demonstrates how encrypted tensors can be used for training and inference, providing a strong foundation for privacy-preserving AI in sensitive domains such as healthcare, finance, and federated learning.
https://www.researchgate.net/publication/395399493_Privacy-Preserving_Machine_Learning_for_Mental_Health_Prediction_Using_Homomorphic_Encryption?_tp=eyJjb250ZXh0Ijp7InBhZ2UiOiJwcm9maWxlIiwicHJldmlvdXNQYWdlIjpudWxsLCJwb3NpdGlvbiI6InBhZ2VDb250ZW50In19
This project investigates the application of Homomorphic Encryption (HE) within the domain of Machine Learning (ML) to enhance privacy-preserving capabilities. The implementation and evaluation focus on TenSEAL , which enables secure tensor operations and seamless integration of encryption in ML pipelines.
The main goal is to ensure that data remains encrypted throughout the entire computation process in machine learning models, providing robust privacy and end-to-end security in sensitive use cases.
git clone https://github.com/your-repository/homomorphic-encryption-ml.git cd homomorphic-encryption-ml pip install -r requirements.txt
Homomorphic Encryption in Machine Learning (HEML) — Implementation of the research paper accepted at SNPD-2025. This project integrates Homomorphic Encryption (HE) with Machine Learning using TenSEAL to enable privacy-preserving model training and inference on encrypted data, ensuring end-to-end data confidentiality without sacrificing accuracy.
Concrete ML is a Privacy-Preserving Machine Learning (PPML) open-source set of tools built on top of Concrete by Zama .
It simplifies the use of fully homomorphic encryption (FHE) for data scientists so that they can automatically turn machine learning models into their homomorphic equivalents, and use them without knowledge of cryptography.
Concrete ML is designed with ease of use in mind. Data scientists can use models with APIs that are close to the frameworks they already know well, while additional options to those models allow them to run inference or training on encrypted data with FHE. The Concrete ML model classes are similar to those in scikit-learn and it is also possible to convert PyTorch models to FHE.
By leveraging FHE, Concrete ML can unlock a myriad of new use cases for machine learning, such as enabling secure and private data collaboration, protecting sensitive data while still allowing for analysis, and facilitating machine learning on data-sets that are subject to strict data privacy regulations, for instance
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Note: Concrete ML only supports Python 3.8 , 3.9 , 3.10 , 3.11 and 3.12 . Concrete ML can be installed on Kaggle ( see this question on the community for more details ) and on Google Colab.
To install with Docker, pull the concrete-ml image as follows: docker pull zamafhe/concrete-ml:latest
Here is a simple example which is very close to scikit-learn for a logistic regression :
from sklearn . datasets import make_classification from sklearn . model_selection import train_test_split from concrete . ml . sklearn import LogisticRegression # Lets create a synthetic data-set x , y = make_classification ( n_samples = 100 , class_sep = 2 , n_features = 30 , random_state = 42 ) # Split the data-set into a train and test set X_train , X_test , y_train , y_test = train_test_split ( x , y , test_size = 0.2 , random_state = 42 ) # Now we train in the clear and quantize the weights model = LogisticRegression ( n_bits = 8 ) model . fit ( X_train , y_train ) # We can simulate the predictions in the clear y_pred_clear = model . predict ( X_test ) # We then compile on a representative set model . compile ( X_train ) # Finally we run the inference on encrypted inputs ! y_pred_fhe = model . predict ( X_test , fhe = "execute" ) print ( "In clear :" , y_pred_clear ) print ( "In FHE :" , y_pred_fhe ) print ( f"Similarity: { int (( y_pred_fhe == y_pred_clear ). mean () * 100 ) } %" ) # Output: # In clear : [0 0 0 0 1 0 1 0 1 1 0 0 1 0 0 1 1 1 0 0] # In FHE : [0 0 0 0 1 0 1 0 1 1 0 0 1 0 0 1 1 1 0 0] # Similarity: 100%
It is also possible to call encryption, model prediction, and decryption functions separately as follows. Executing these steps separately is equivalent to calling predict_proba on the model instance.
# Predict probability for a single example y_proba_fhe = model . predict_proba ( X_test [[ 0 ]], fhe = "execute" ) # Quantize an original float input q_input = model . quantize_input ( X_test [[ 0 ]]) # Encrypt the input q_input_enc = model . fhe_circuit . encrypt ( q_input ) # Execute the linear product in FHE q_y_enc = model . fhe_circuit . run ( q_input_enc ) # Decrypt the result (integer) q_y = model . fhe_circuit . decrypt ( q_y_enc ) # De-quantize and post-process the result y0 = model . post_processing ( model . dequantize_output ( q_y )) print ( "Probability with `predict_proba`: " , y_proba_fhe ) print ( "Probability with encrypt/run/decrypt calls: " , y0 )
Concrete ML built-in models have APIs that are almost identical to their scikit-learn counterparts. It is also possible to convert PyTorch networks to FHE with the Concrete ML conversion APIs. Please refer to the linear models , tree-based models and neural networks documentation for more examples, showing the scikit-learn-like API of the built-in models.
If you have built awesome projects using Concrete ML, please let us know and we will be happy to showcase them here!
Full, comprehensive documentation is available here: https://docs.zama.ai/concrete-ml .
@Misc{ConcreteML, title={Concrete {ML}: a Privacy-Preserving Machine Learning Library using Fully Homomorphic Encryption for Data Scientists}, author={Zama}, year={2022}, note={\url{https://github.com/zama-ai/concrete-ml}}, }
This software is distributed under the BSD-3-Clause-Clear license. Read this for more details.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)