Complete Technical Paper Content — Hyperparameter Tuning Ai
1. Executive Abstract, Problem Formulation & Background
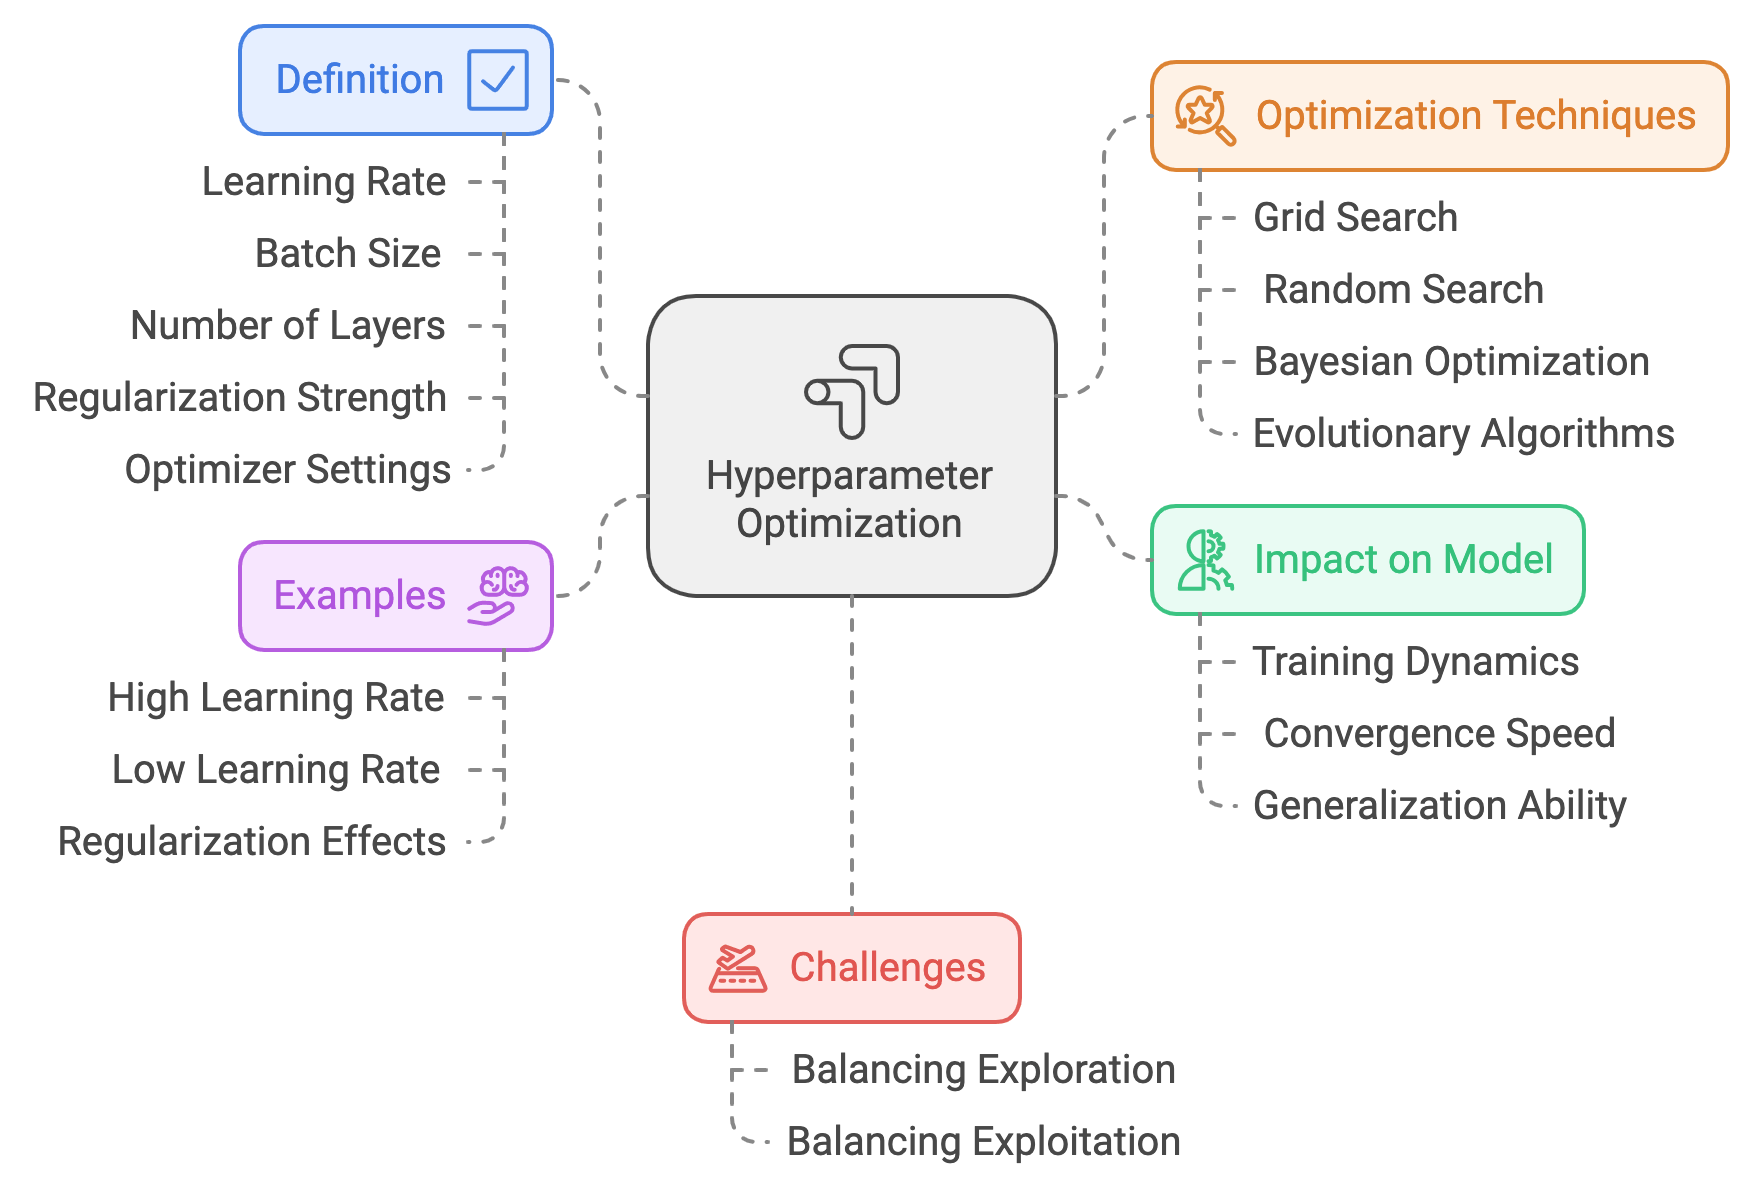
In machine learning, a hyperparameter is a parameter that can be set in order to define any configurable part of a model's learning process. Hyperparameters can be classified as either model hyperparameters (such as the topology and size of a neural network) or algorithm hyperparameters (such as the learning rate and the batch size of an optimizer). These are named hyperparameters in contrast to parameters, which are characteristics that the model learns from the data. Hyperparameters are not required by every model or algorithm. Some simple algorithms such as ordinary least squares regression require none. However, the LASSO algorithm, for example, adds a regularization hyperparameter to ordinary least squares which must be set before training. Even models and algorithms without a strict requirement to define hyperparameters may not produce meaningful results if these are not carefully chosen. However, optimal values for hyperparameters are not always easy to predict. Some hyperparameters may have no meaningful effect, or one important variable may be conditional upon the value of another. Often a separate process of hyperparameter tuning is needed to find a suitable combination for the data and task. As well as improving model performance, hyperparameters can be used by researchers to introduce robustness and reproducibility into their work, especially if it uses models that incorporate random number generation.
Hyperparameter optimization finds a tuple of hyperparameters that yields an optimal model which minimizes a predefined loss function on given test data. The objective function takes a tuple of hyperparameters and returns the associated loss. Typically these methods are not gradient based, and instead apply concepts from derivative-free optimization or black box optimization.
2. Related Work, Literature Survey & Algorithmic Foundations
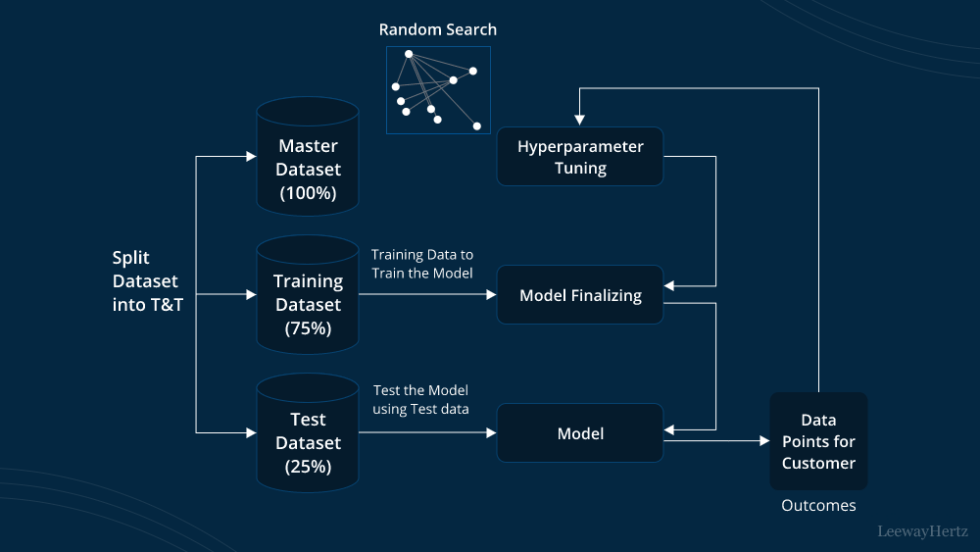
In machine learning, hyperparameter optimization or tuning is the problem of choosing a set of optimal hyperparameters for a learning algorithm. A hyperparameter is a parameter whose value is used to control the learning process, which must be configured before the process starts. Hyperparameter optimization determines the set of hyperparameters that yields an optimal model which minimizes a predefined loss function on a given data set. The objective function takes a set of hyperparameters and returns the associated loss. Cross-validation is often used to estimate this generalization performance, and therefore choose the set of values for hyperparameters that maximize it.
C ∈ { 10 , 100 , 1000 } {\displaystyle C\in \{10,100,1000\}}
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
γ ∈ { 0.1 , 0.2 , 0.5 , 1.0 } {\displaystyle \gamma \in \{0.1,0.2,0.5,1.0\}}
Grid search then trains an SVM with each pair (C, γ) in the Cartesian product of these two sets and evaluates their performance on a held-out validation set (or by internal cross-validation on the training set, in which case multiple SVMs are trained per pair). Finally, the grid search algorithm outputs the settings that achieved the highest score in the validation procedure. Grid search suffers from the curse of dimensionality, but is often embarrassingly parallel because the hyperparameter settings it evaluates are typically independent of each other.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Bayesian optimization is a global optimization method for noisy black-box functions. Applied to hyperparameter optimization, Bayesian optimization builds a probabilistic model of the function mapping from hyperparameter values to the objective evaluated on a validation set. By iteratively evaluating a promising hyperparameter configuration based on the current model, and then updating it, Bayesian optimization aims to gather observations revealing as much information as possible about this function and, in particular, the location of the optimum. It tries to balance exploration (hyperparameters for which the outcome is most uncertain) and exploitation (hyperparameters expected close to the optimum). In practice, Bayesian optimization has been shown to obtain better results in fewer evaluations compared to grid search and random search, due to the ability to reason about the quality of experiments before they are run.
Evolutionary optimization is a methodology for the global optimization of noisy black-box functions. In hyperparameter optimization, evolutionary optimization uses evolutionary algorithms to search the space of hyperparameters for a given algorithm. Evolutionary hyperparameter optimization follows a process inspired by the biological concept of evolution:
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Create an initial population of random solutions (i.e., randomly generate tuples of hyperparameters, typically 100+) Evaluate the hyperparameter tuples and acquire their fitness function (e.g., 10-fold cross-validation accuracy of the machine learning algorithm with those hyperparameters) Rank the hyperparameter tuples by their relative fitness Replace the worst-performing hyperparameter tuples with new ones generated via crossover and mutation Repeat steps 2-4 until satisfactory algorithm performance is reached or is no longer improving. Evolutionary optimization has been used in hyperparameter optimization for statistical machine learning algorithms, automated machine learning, typical neural network and deep neural network architecture search, as well as training of the weights in deep neural networks.
A class of early stopping-based hyperparameter optimization algorithms is purpose-built for large search spaces of continuous and discrete hyperparameters, particularly when the computational cost to evaluate the performance of a set of hyperparameters is high. Irace implements the iterated racing algorithm, that focuses the search around the most promising configurations, using statistical tests to discard the ones that perform poorly. Another early stopping hyperparameter optimization algorithm is successive halving (SHA), which begins as a random search but periodically prunes low-performing models, thereby focusing computational resources on more promising models. Asynchronous successive halving (ASHA) further improves upon SHA's resource utilization profile by removing the need to synchronously evaluate and prune low-performing models. Hyperband is a higher level early stopping-based algorithm that invokes SHA or ASHA multiple times with varying levels of pruning aggressiveness, in order to be more widely applicable and with fewer required inputs.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)