Complete Technical Paper Content — Image To Image Translation
1. Executive Abstract, Problem Formulation & Background
GPT Image is a series of image generation and editing models developed by OpenAI. A text-to-image variant of the GPT family, it uses deep learning methodologies to generate digital images from natural language descriptions or images precisely. As the successor to DALL-E, GPT Image is native to ChatGPT as ChatGPT Images and available through the API. Upon release in March 2025, GPT Image went viral on social media, particularly for its capability of generating images in the style of Studio Ghibli. GPT Image is also available with Microsoft Copilot and Apple Intelligence as well.
The first model of GPT Image was revealed by OpenAI as the "GPT-4o image generation" in a blog post on March 25, 2025, developed based on the GPT-4o model to generate images. It was initially made available to only paid users, with the rollout to free users delayed due to high demands. The use of the feature was subsequently limited, with Sam Altman saying that the GPUs were "melting" from the level of use. OpenAI later said that over 130 million users around the world had created more than 700 million images in the first week. The model was named as GPT Image 1 (gpt-image-1) and introduced to the API on April 23. A cost-efficient version was released as GPT Image 1 Mini (gpt-image-1-mini) on October 6, also OpenAI DevDay 2025, with the cost in the API 80% less expensive than GPT Image 1. A new model named GPT Image 1.5 (gpt-image-1.5) was introduced on December 16, which was rolled out globally as the "ChatGPT Images" to all users and immediately made available via the API. OpenAI claimed that the new model can make precise edits while keeping details intact, and generates images up to four times faster. Image inputs and outputs in the API are 20% cheaper in GPT Image 1.5 as compared to GPT Image 1. In April 2026, OpenAI released GPT Image 2 (gpt-image-2) which introduced a reasoning model into their generation. GPT Image 2.5 was released on September 8, 2026. The model introduced a Sketch feature that allows users to turn their drawings into an AI image, and the latency of the image generation decreased by 50%. Two versions were released on the API, one called Flare (gpt-image-2.5/flare), designed to be quicker while maintaining some quality and Sunburst (gpt-image-2.5/sunburst) is designed to be more detailed at the expense of taking more time.
Upon the launch of GPT Image 1 in March 2025, photographs recreated in the style of Studio Ghibli films went viral. Sam Altman acknowledged the trend by changing his Twitter profile picture into a Studio Ghibli-inspired one. In response to the trend, many commentators referred to Ghibli director Hayao Miyazaki's previous negative comments on AI art. Some creative professionals, including animator Alex Hirsch, criticized Altman for profiting from Studio Ghibli's work. North American distributor GKids indirectly commented on the trend, alluding to "a time when technology tries to replicate humanity" in a press release for the re-release of the 1997 Studio Ghibli film Princess Mononoke. The White House's official Twitter account posted a Ghibli-style image mocking the arrest by immigration authorities of Virginia Basora-Gonzalez, a migrant from the Dominican Republic, which shows her crying as an immigration officer places her in handcuffs.
ChatGPT Images 2.0 OpenAI image models - including GPT Image 1, 1.5 and 2 4o ImageGen - the official custom GPT for GPT Image 1
A text-to-image (T2I or TTI) model is a machine learning model which takes an input natural language prompt and produces an image matching that description. Text-to-image models gradually began to be developed in the mid-2010s during the beginnings of the AI boom, as a result of advances in deep neural networks. In 2022, the output of state-of-the-art text-to-image models—such as OpenAI's DALL-E 2, Google Brain's Imagen, Stability AI's Stable Diffusion, Midjourney, and Runway's Gen-4—began to be considered to approach the quality of real photographs and human-drawn art. Text-to-image models are generally latent diffusion models, which perform the diffusion process in a compressed latent space rather than directly in pixel space. An autoencoder (often a variational autoencoder) is used to convert between pixel space and this latent representation. These systems typically use a pretrained language or vision–language model to convert the input prompt into a text embedding, and a diffusion-based generative image model that produces images conditioned on that embedding. The most effective models have generally been trained on massive amounts of image and text data scraped from the web.
The first modern text-to-image model, alignDRAW, was introduced in 2015 by researchers from the University of Toronto. alignDRAW extended the previously introduced DRAW architecture (which used a recurrent variational autoencoder with an attention mechanism) to be conditioned on text sequences. Images generated by alignDRAW were in small resolution (32×32 pixels, attained from resizing) and were considered to be 'low in diversity'. The model was able to generalize to objects not represented in the training data (such as a red school bus) and appropriately handled novel prompts such as "a stop sign is flying in blue skies", exhibiting output that it was not merely "memorizing" data from the training set. In 2016, Reed, Akata, Yan et al. became the first to use generative adversarial networks for the text-to-image task. With models trained on narrow, domain-specific datasets, they were able to generate "visually plausible" images of birds and flowers from text captions like "an all black bird with a distinct thick, rounded bill". A model trained on the more diverse COCO (Common Objects in Context) dataset produced images which were "from a distance... encouraging", but which lacked coherence in their details. Later systems include VQGAN-CLIP, XMC-GAN, and GauGAN2.
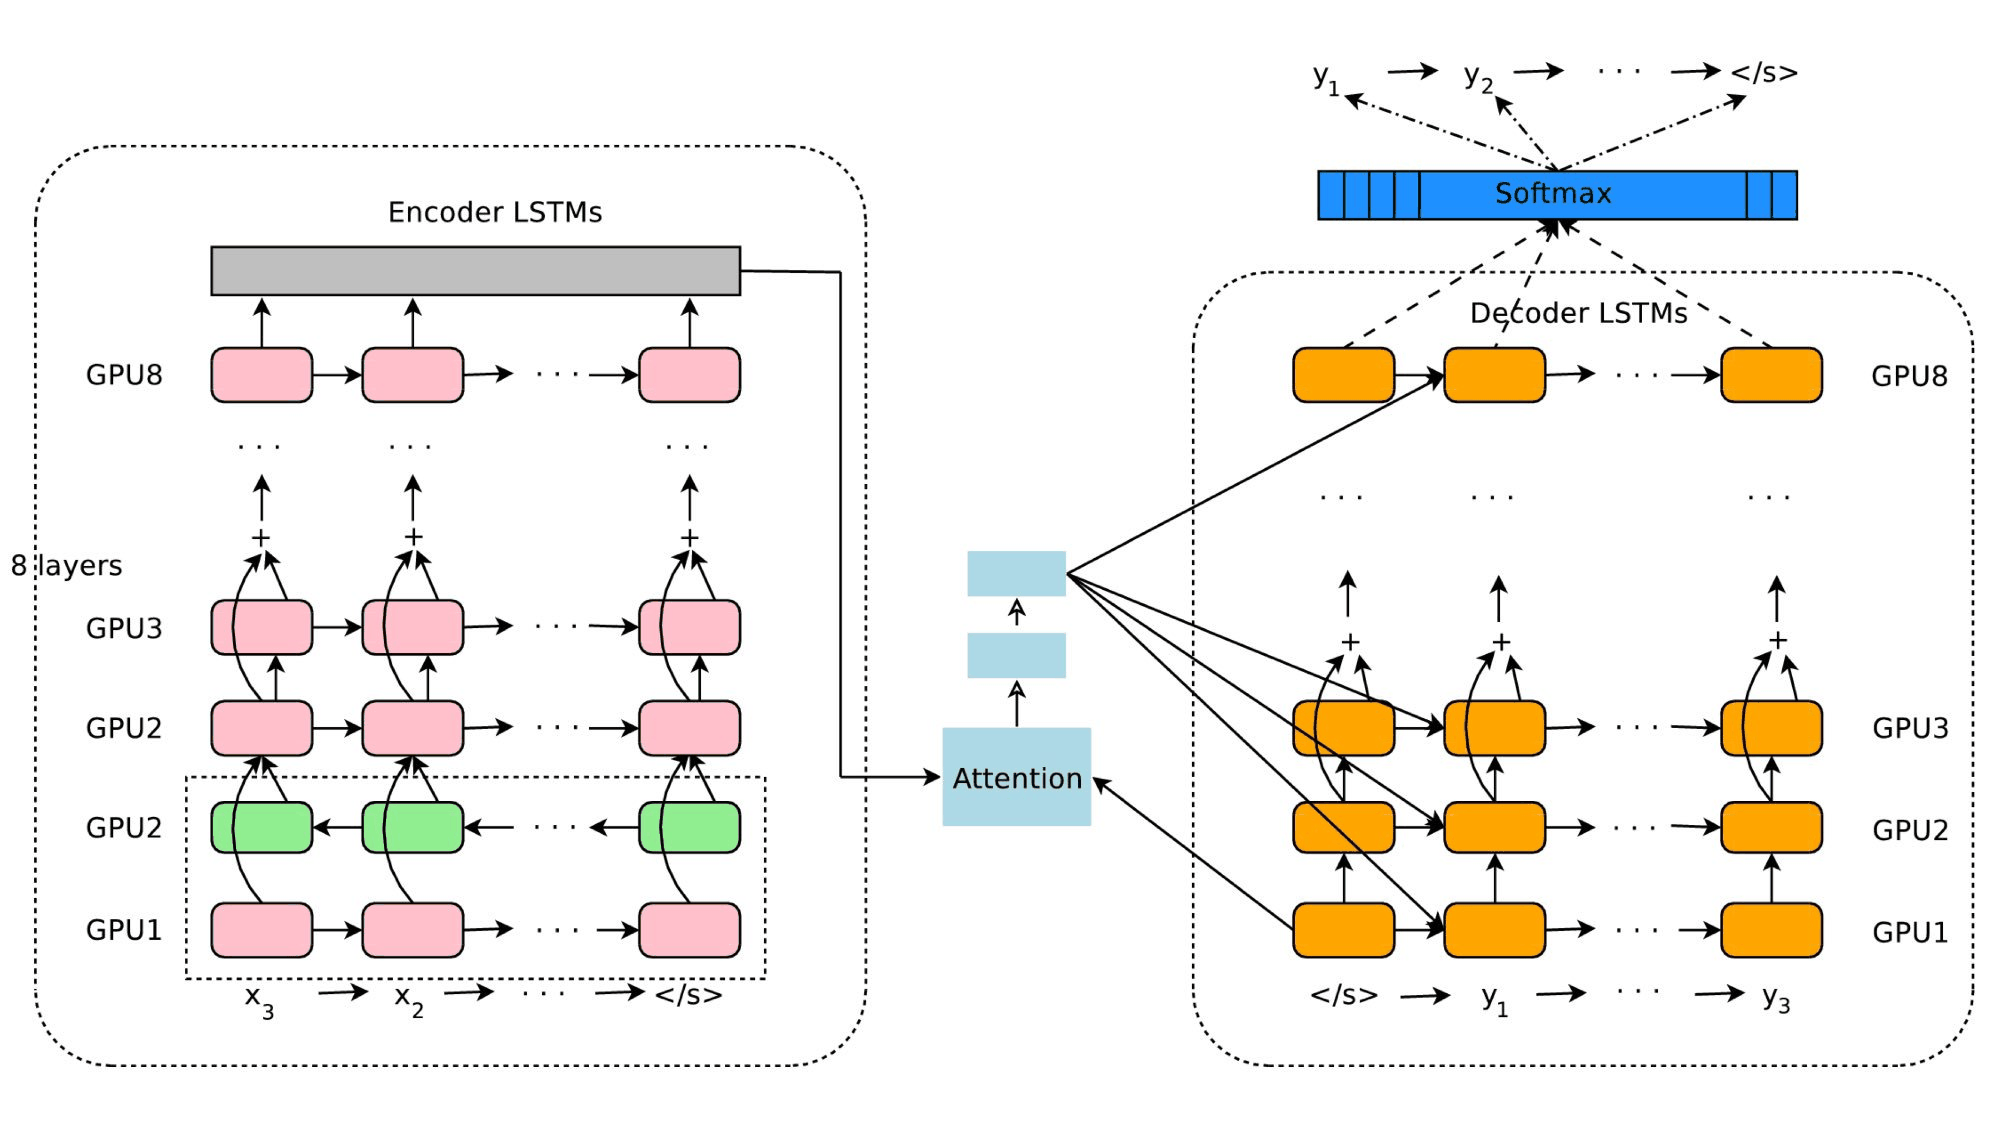
Text-to-image models have been built using a variety of architectures. The text encoding step may be performed with a recurrent neural network such as a long short-term memory (LSTM) network, though transformer models have since become a more popular option. For the image generation step, conditional generative adversarial networks (GANs) was once widely used in early days. Since 2020, diffusion models have become the popular option. Rather than directly training a model to output a high-resolution image conditioned on a text embedding, a popular technique is to train a model to generate low-resolution images or latent space, and use one or more auxiliary deep learning models to upscale or decode it, filling in finer details. Text-to-image models are trained on large datasets of (text, image) pairs, often scraped from the web. With their 2022 Imagen model, Google Brain reported positive results from using a large language model trained separately on a text-only corpus (with its weights subsequently frozen), a departure from the theretofore standard approach.
Training a text-to-image model requires a dataset of images paired with text captions. One dataset commonly used for this purpose is the COCO dataset. Released by Microsoft in 2014, COCO consists of around 123,000 images depicting a diversity of objects with five captions per image, generated by human annotators. Originally, the main focus of COCO was on the recognition of objects and scenes in images. Oxford-120 Flowers and CUB-200 Birds are smaller datasets of around 10,000 images each, restricted to flowers and birds, respectively. It is considered less difficult to train a high-quality text-to-image model with these datasets because of their narrow range of subject matter. One of the largest open datasets for training text-to-image models is LAION-5B, containing more than 5 billion image-text pairs. This dataset was created using web scraping and automatic filtering based on similarity to high-quality artwork and professional photographs. Because of this, however, it also contains controversial content, which has led to discussions about the ethics of its use. Some modern AI platforms not only generate images from text but also create synthetic datasets to improve model training and fine-tuning. These datasets help avoid copyright issues and expand the diversity of training data.
🖼️ Image-to-Image Translation with CGAN Translate images from one visual domain to another using a Conditional Generative Adversarial Network (cGAN). This project implements Image-to-Image Translation with a Conditional Generative Adversarial Network (cGAN) based on the pix2pix architecture introduced by Isola et al. It is designed for paired image-to-image translation . Unlike a traditional GAN that generates images from random noise, this model learns a mapping between corresponding input and target images: Input Image ↓ Conditional GAN ↓ Translated Image Examples include: Satellite Image → Map Building Photo → Segmentation Map Sketch → Realistic Photo Day Image → Night Image The implementation contains the complete training pipeline, including dataset loading, augmentation, U-Net generator, PatchGAN discriminator, adversarial training, L1 reconstruction loss, checkpointing, and image translation. ✨ What is Image-to-Image Translation with cGAN? A Conditional Generative Adversarial Network (cGAN) can generate an output image based on a given input condition. This project uses the pix2pix approach for paired image-to-image translation. The model learns from pairs of corresponding images: Input Image → Target Image For example: Satellite Photo → Geographic Map During training, the generator learns to produce an image that: Looks realistic. Matches the structure of the target image. Preserves important information from the input image. 🧠 How Does a cGAN Work? A standard GAN contains two main components: Generator — creates generated images. Discriminator — determines whether an image is real or generated. A Conditional GAN additionally provides an input condition to guide the generation process. Instead of: Random Noise ↓ Generator ↓ Image this project uses: Input Image ↓ Generator ↓ Generated Image The discriminator receives both the input image and the target/generated image. ┌───────────────┐ Input Image ───► │ Generator │ ───► Generated Image └───────────────┘ │ ▼ ┌─────────────┐ Input Image ─────► │ Discriminator│ Target Image ────► │ │ ───► Real / Fake └─────────────┘ The two networks learn together. Generator The generator tries to: Fool the discriminator. Produce realistic outputs. Stay close to the expected target. Discriminator The discriminator tries to distinguish between: Real Pair: (Input Image, Target Image) Fake Pair: (Input Image, Generated Image) As training progresses, both networks improve. 🏗️ Architecture The project uses two major neural network components: Component Architecture Purpose 🎨 Generator U-Net Converts input images into translated images 🔍 Discriminator PatchGAN Determines whether local image patches look realistic 📉 Reconstruction L1 Loss Keeps generated image close to target ⚔️ Adversarial Training cGAN Loss Encourages realistic outputs 🎨 Generator — U-Net The generator uses a U-Net encoder-decoder architecture . Input Image ↓ Encoder ↓ Feature Representation ↓ Decoder ↓ Output Image The important feature of U-Net is its skip connections . Encoder ───────────────► Decoder │ │ ├───────────────────────┤ ├───────────────────────┤ └───────────────────────┘ Skip connections allow low-level spatial information to bypass the bottleneck and reach the decoder. This helps preserve: Edges Shapes Fine details Spatial structure Without skip connections, the generator can lose important information during encoding. 🔍 Discriminator — PatchGAN The discriminator uses PatchGAN rather than classifying the entire image as a single unit. Instead of asking: Is this entire image real or fake? PatchGAN evaluates local regions: ┌────┬────┬────┐ │ P1 │ P2 │ P3 │ ├────┼────┼────┤ │ P4 │ P5 │ P6 │ ├────┼────┼────┤ │ P7 │ P8 │ P9 │ └────┴────┴────┘ Each patch receives a real/fake prediction. This encourages the generator to produce realistic: Textures Edges Local patterns Fine details The implementation follows the 70×70 PatchGAN design described in the original pix2pix work. 📉 Loss Functions The generator is trained using two main objectives: Generator Loss = Adversarial Loss + λ × L1 Loss The implementation uses: λ = 100 ⚔️ Adversarial Loss The adversarial component encourages the generator to create images that the discriminator considers realistic. Generated Image ↓ Discriminator ↓ Should look REAL Without adversarial loss, the generated images may become overly smooth. 📐 L1 Reconstruction Loss The L1 loss directly compares the generated image with the target image. L1 Loss = |Target Image - Generated Image| It encourages the output to remain structurally similar to the target. This is particularly important for paired image translation. 🎯 Why Combine Both? Adversarial loss and L1 loss solve different problems. Adversarial Loss ↓ Realistic appearance + L1 Loss ↓ Correct structure and content ↓ Better translated image Adversarial loss makes the image look realistic, while L1 loss helps ensure that it corresponds correctly to the target. 🔄 Training Pipeline The complete training process can be summarized as: Paired Dataset ↓ Load Input + Target ↓ Data Augmentation ↓ Normalization ↓ U-Net Generator ↓ Generated Image ↓ PatchGAN Discriminator ↓ Calculate Losses ↓ Backpropagation ↓ Update Generator ↓ Update Discriminator ↓ Save Checkpoint ↓ Generate Sample ↓ Repeat 🧹 Data Preprocessing The dataset pipeline supports common preprocessing operations: Random jitter Random cropping Random horizontal flipping Image resizing Normalization These transformations help the model generalize better and provide additional variation during training. 📦 Dataset Format The model expects paired images . A training example contains: [ Input Image | Target Image ] For example: ┌──────────────────┬──────────────────┐ │ Satellite │ Map │ │ Image │ │ └──────────────────┴──────────────────┘ The dataset can be organized as: dataset/ ├── train/ │ ├── image_001.jpg │ ├── image_002.jpg │ └── image_003.jpg │ └── val/ ├── image_001.jpg ├── image_002.jpg └── image_003.jpg Each image should contain the input and target side-by-side. 🗂️ Project Structure image-to-image-translation-cgan/ │ ├── src/ │ ├── dataset.py │ ├── models.py │ ├── losses.py │ ├── train.py │ ├── translate.py │ └── utils.py │ ├── examples/ │ └── my_input.jpg │ ├── outputs/ │ └── training_samples/ │ ├── checkpoints/ │ ├── requirements.txt └── README.md File Overview File Purpose dataset.py Dataset loading, augmentation, preprocessing models.py U-Net Generator and PatchGAN Discriminator losses.py Generator and Discriminator losses train.py Training loop and checkpoint management translate.py Translation using a trained generator utils.py Image saving and visualization utilities examples/ Test images outputs/ Generated samples checkpoints/ Saved model weights 🛠️ Technologies Used Python TensorFlow NumPy Pillow Deep Learning Generative Adversarial Networks Conditional GANs Convolutional Neural Networks U-Net PatchGAN Computer Vision ⚙️ Installation Windows — PowerShell git clone https: // github.com / < your - username > / image - to - image - translation - cgan.git cd image - to - image - translation - cgan python - m venv .venv .venv\Scripts\Activate.ps1 pip install - r requirements.txt macOS / Linux git clone https://github.com/ < your-username > /image-to-image-translation-cgan.git cd image-to-image-translation-cgan python3 -m venv .venv source .venv/bin/activate pip install -r requirements.txt 🚀 Usage 1. Train on the Maps Dataset The project supports the maps dataset by default. python src\train.py -- dataset maps -- epochs 40 The dataset is downloaded automatically on the first run. 2. Train on Your Own Dataset For a custom paired dataset: python src\train.py -- data - dir path\to\your\dataset -- epochs 40 Expected structure: dataset/ ├── train/ │ ├── train_001.jpg │ ├── train_002.jpg │ └── ... │ └── val/ ├── val_001.jpg ├── val_002.jpg └── ... 🎛️ Training Parameters Parameter Default Description --epochs 40 Number of training epochs --batch-size 1 Training batch size --lr 2e-4 Learning rate for Adam optimizers --checkpoint-every 5 Save checkpoint every N epochs Batch Size The implementation uses: batch-size = 1 which is consistent with the original pix2pix setup. Learning Rate The default learning rate is: 2e-4 for both the generator and discriminator optimizers. 💾 Checkpoints Training checkpoints are saved inside: checkpoints/ For example: checkpoints/ ├── epoch_005/ ├── epoch_010/ ├── epoch_015/ └── ... Checkpoints allow training to be resumed and provide saved versions of the trained model. 🖼️ Training Samples After each epoch, the training process generates a sample comparison containing: Input + Ground Truth + Prediction Conceptually: ┌──────────────┬──────────────┬──────────────┐ │ Input │ Ground Truth │ Prediction │ └──────────────┴──────────────┴──────────────┘ These samples are stored in: outputs/training_samples/ This makes it possible to monitor how the generator improves throughout training. 🔮 Translate a New Image Once a trained checkpoint is available, a new image can be translated using: python src\translate.py -- input examples\my_input.jpg -- output outputs\translated.png The trained generator processes the input image and produces the translated result. ⏱️ Training Performance The model is trained from scratch , so training is significantly more computationally expensive than using a pretrained model. Approximate experience: CPU ↓ Long training time GPU ↓ Much faster training The exact training time depends on: GPU/CPU hardware Image resolution Dataset size Number of epochs Batch size For experimentation, training for fewer epochs can be useful to verify that the pipeline works correctly before starting a full run. 🔬 What This Project Demonstrates This implementation provides practical experience with: Conditional GANs GAN training Generator vs Discriminator optimization U-Net architecture Skip connections PatchGAN Adversarial loss L1 reconstruction loss Paired image datasets Data augmentation Image normalization Checkpointing Image-to-image translation Computer Vision Deep Learning 💡 Key Learning Image-to-image translation with cGANs demonstrates how GANs can be conditioned on an existing image instead of generating an image from random noise. The central idea is: Input Image ↓ Conditional Information ↓ Generator ↓ Translated Image ↓ Discriminator ↓ Realistic + Correct Output The project also demonstrates why combining different objectives is useful: Adversarial Loss ↓ Realistic appearance L1 Loss ↓ Correct correspondence ↓ High-quality image translation ⚠️ Limitations The current implementation has several limitations: Requires paired training data. Training from scratch can be computationally expensive. GAN training can be unstable. Results depend heavily on dataset quality. A model trained for one translation task may not generalize to another domain. High-resolution image translation requires significantly more computational resources. 🔮 Future Improvements Possible extensions include: Add GPU/mixed-precision training Add training resume functionality Add TensorBoard training visualization Add validation metrics Add side-by-side result visualization Support unpaired image translation Implement CycleGAN Add a Streamlit interface Add a Flask API Support higher-resolution images Add experiment tracking Compare different GAN architectures Add video-to-video translation 📚 References TensorFlow — pix2pix Tutorial Isola, Zhu, Zhou & Efros — Image-to-Image Translation with Conditional Adversarial Networks Conditional Generative Adversarial Network — GeeksforGeeks cGAN: How to Gain Control Over GAN Outputs ⭐ Conclusion This project implements Image-to-Image Translation with a Conditional Generative Adversarial Network (cGAN) for paired image-to-image translation. It combines a U-Net Generator , PatchGAN Discriminator , adversarial loss , and L1 reconstruction loss to learn mappings between visual domains. The project provides both a practical implementation and a deeper understanding of how GANs can learn structured transformations such as: Satellite Image → Map Sketch → Photo Photo → Segmentation Overall, the project demonstrates how conditional generative models can learn meaningful visual transformations from paired examples . 👩💻 Author Usha S. Reddy If you found this project useful, consider giving the repository a ⭐.
Translate images from one visual domain to another using a Conditional Generative Adversarial Network (cGAN).
This project implements Image-to-Image Translation with a Conditional Generative Adversarial Network (cGAN) based on the pix2pix architecture introduced by Isola et al. It is designed for paired image-to-image translation .
2. Related Work, Literature Survey & Algorithmic Foundations
Unlike a traditional GAN that generates images from random noise, this model learns a mapping between corresponding input and target images:
Satellite Image → Map Building Photo → Segmentation Map Sketch → Realistic Photo Day Image → Night Image
The implementation contains the complete training pipeline, including dataset loading, augmentation, U-Net generator, PatchGAN discriminator, adversarial training, L1 reconstruction loss, checkpointing, and image translation.
A Conditional Generative Adversarial Network (cGAN) can generate an output image based on a given input condition.
A Conditional GAN additionally provides an input condition to guide the generation process.
┌───────────────┐ Input Image ───► │ Generator │ ───► Generated Image └───────────────┘ │ ▼ ┌─────────────┐ Input Image ─────► │ Discriminator│ Target Image ────► │ │ ───► Real / Fake └─────────────┘
Input Image ↓ Encoder ↓ Feature Representation ↓ Decoder ↓ Output Image
Encoder ───────────────► Decoder │ │ ├───────────────────────┤ ├───────────────────────┤ └───────────────────────┘
Skip connections allow low-level spatial information to bypass the bottleneck and reach the decoder.
Without skip connections, the generator can lose important information during encoding.
The discriminator uses PatchGAN rather than classifying the entire image as a single unit.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
┌────┬────┬────┐ │ P1 │ P2 │ P3 │ ├────┼────┼────┤ │ P4 │ P5 │ P6 │ ├────┼────┼────┤ │ P7 │ P8 │ P9 │ └────┴────┴────┘
The implementation follows the 70×70 PatchGAN design described in the original pix2pix work.
The adversarial component encourages the generator to create images that the discriminator considers realistic.
Adversarial Loss ↓ Realistic appearance + L1 Loss ↓ Correct structure and content ↓ Better translated image
Adversarial loss makes the image look realistic, while L1 loss helps ensure that it corresponds correctly to the target.
Paired Dataset ↓ Load Input + Target ↓ Data Augmentation ↓ Normalization ↓ U-Net Generator ↓ Generated Image ↓ PatchGAN Discriminator ↓ Calculate Losses ↓ Backpropagation ↓ Update Generator ↓ Update Discriminator ↓ Save Checkpoint ↓ Generate Sample ↓ Repeat
These transformations help the model generalize better and provide additional variation during training.
┌──────────────────┬──────────────────┐ │ Satellite │ Map │ │ Image │ │ └──────────────────┴──────────────────┘
dataset/ ├── train/ │ ├── image_001.jpg │ ├── image_002.jpg │ └── image_003.jpg │ └── val/ ├── image_001.jpg ├── image_002.jpg └── image_003.jpg
image-to-image-translation-cgan/ │ ├── src/ │ ├── dataset.py │ ├── models.py │ ├── losses.py │ ├── train.py │ ├── translate.py │ └── utils.py │ ├── examples/ │ └── my_input.jpg │ ├── outputs/ │ └── training_samples/ │ ├── checkpoints/ │ ├── requirements.txt └── README.md
git clone https: // github.com / < your - username > / image - to - image - translation - cgan.git cd image - to - image - translation - cgan python - m venv .venv .venv\Scripts\Activate.ps1 pip install - r requirements.txt
4. Neural Network Backbone, Layer Specifications & Loss Formulations
git clone https://github.com/ < your-username > /image-to-image-translation-cgan.git cd image-to-image-translation-cgan python3 -m venv .venv source .venv/bin/activate pip install -r requirements.txt
dataset/ ├── train/ │ ├── train_001.jpg │ ├── train_002.jpg │ └── ... │ └── val/ ├── val_001.jpg ├── val_002.jpg └── ...
Checkpoints allow training to be resumed and provide saved versions of the trained model.
┌──────────────┬──────────────┬──────────────┐ │ Input │ Ground Truth │ Prediction │ └──────────────┴──────────────┴──────────────┘
python src\translate.py -- input examples\my_input.jpg -- output outputs\translated.png
The model is trained from scratch , so training is significantly more computationally expensive than using a pretrained model.
For experimentation, training for fewer epochs can be useful to verify that the pipeline works correctly before starting a full run.
Image-to-image translation with cGANs demonstrates how GANs can be conditioned on an existing image instead of generating an image from random noise.
Input Image ↓ Conditional Information ↓ Generator ↓ Translated Image ↓ Discriminator ↓ Realistic + Correct Output
Adversarial Loss ↓ Realistic appearance L1 Loss ↓ Correct correspondence ↓ High-quality image translation
This project implements Image-to-Image Translation with a Conditional Generative Adversarial Network (cGAN) for paired image-to-image translation.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
It combines a U-Net Generator , PatchGAN Discriminator , adversarial loss , and L1 reconstruction loss to learn mappings between visual domains.
The project provides both a practical implementation and a deeper understanding of how GANs can learn structured transformations such as:
Overall, the project demonstrates how conditional generative models can learn meaningful visual transformations from paired examples .
A Conditional GAN (cGAN) project for paired image-to-image translation. Uses a U-Net Generator and PatchGAN discriminator to generate realistic translated images. Built with Python and TensorFlow for practical Deep Learning and Computer Vision applications.
Image-to-Image Translation with cGAN This repository contains code and resources for performing Image-to-Image Translation using Conditional Generative Adversarial Networks (cGANs). The goal of this project is to translate images from one domain to another (e.g., turning black-and-white images into color, or transforming sketches into realistic images). Table of Contents Introduction Features Requirements Dataset Usage Training Testing Results Directory Structure Acknowledgments Introduction Image-to-Image Translation is a field in computer vision where the task is to transform an image from one domain into a corresponding image in another domain. This can be achieved by using Conditional Generative Adversarial Networks (cGANs), which are a variant of GANs that condition on some input data to generate the output. In this project, we implement cGANs using a deep learning framework to perform image translation tasks. The network is trained to learn the mapping from input images to output images using paired or unpaired image datasets. Features Implement cGANs for image-to-image translation. Customizable architecture and training parameters. Supports various image translation tasks (e.g., colorization, style transfer). Save and load trained models for future use. Visualize results during and after training. Requirements Python 3.x TensorFlow or PyTorch NumPy Matplotlib OpenCV argparse To install the required dependencies, you can run: pip install -r requirements.txt Dataset To train the cGAN, you'll need a dataset of paired images (i.e., input-output pairs) or unpaired images depending on the task. For paired datasets, the input and output images should be aligned and stored in corresponding directories. Example datasets: Cityscapes Edges2Shoes Maps Usage Training To train the cGAN model on your dataset, run the following command: python train.py --dataset_name < DATASET_NAME > --epochs < NUM_EPOCHS > --batch_size < BATCH_SIZE > --learning_rate < LEARNING_RATE > Parameters: dataset_name : Name of the dataset folder. epochs : Number of epochs to train. batch_size : Size of the mini-batches. learning_rate : Learning rate for the optimizer. Testing After training, you can test the model on unseen images using: python test.py --model_path < MODEL_PATH > --input_image < INPUT_IMAGE_PATH > --output_image < OUTPUT_IMAGE_PATH > Parameters: model_path : Path to the saved model. input_image : Path to the input image for translation. output_image : Path to save the translated output image. Results During training, results will be saved in the output directory, including: Generated images at different epochs. Loss curves. Model checkpoints. After training, you can evaluate the model's performance on test data. Directory Structure ├── datasets │ └── <dataset_name> │ ├── train │ └── test ├── models │ ├── generator.h5 │ └── discriminator.h5 ├── output │ ├── images │ ├── losses │ └── models ├── train.py ├── test.py └── README.md Acknowledgments This project is inspired by the work of Pix2Pix and CycleGAN . Special thanks to the open-source community for providing valuable datasets and resources.
This repository contains code and resources for performing Image-to-Image Translation using Conditional Generative Adversarial Networks (cGANs). The goal of this project is to translate images from one domain to another (e.g., turning black-and-white images into color, or transforming sketches into realistic images).
Image-to-Image Translation is a field in computer vision where the task is to transform an image from one domain into a corresponding image in another domain. This can be achieved by using Conditional Generative Adversarial Networks (cGANs), which are a variant of GANs that condition on some input data to generate the output.
In this project, we implement cGANs using a deep learning framework to perform image translation tasks. The network is trained to learn the mapping from input images to output images using paired or unpaired image datasets.
To train the cGAN, you'll need a dataset of paired images (i.e., input-output pairs) or unpaired images depending on the task.
For paired datasets, the input and output images should be aligned and stored in corresponding directories.
python train.py --dataset_name < DATASET_NAME > --epochs < NUM_EPOCHS > --batch_size < BATCH_SIZE > --learning_rate < LEARNING_RATE >
Model Figures & Evaluation Curves (4 Images)
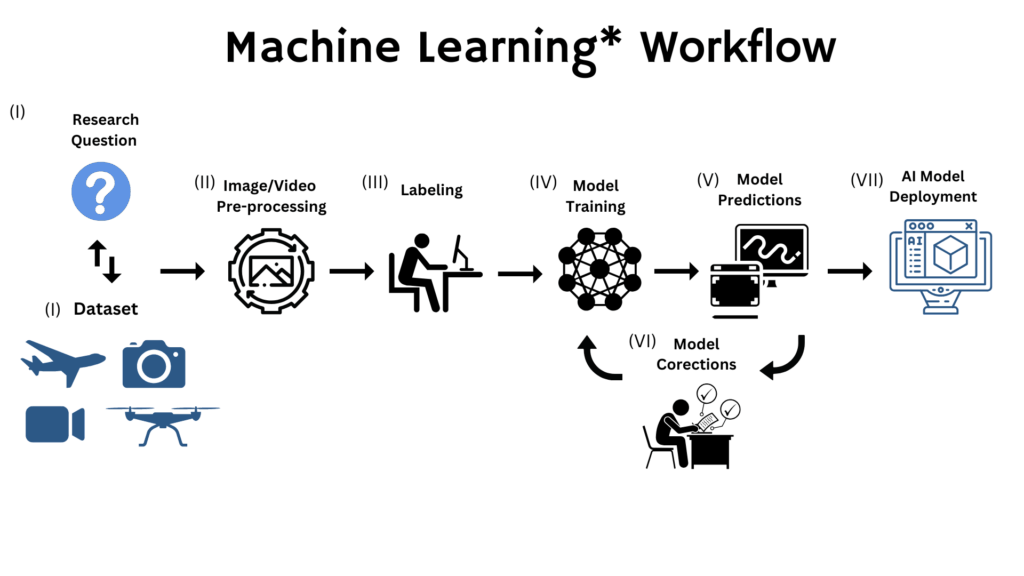
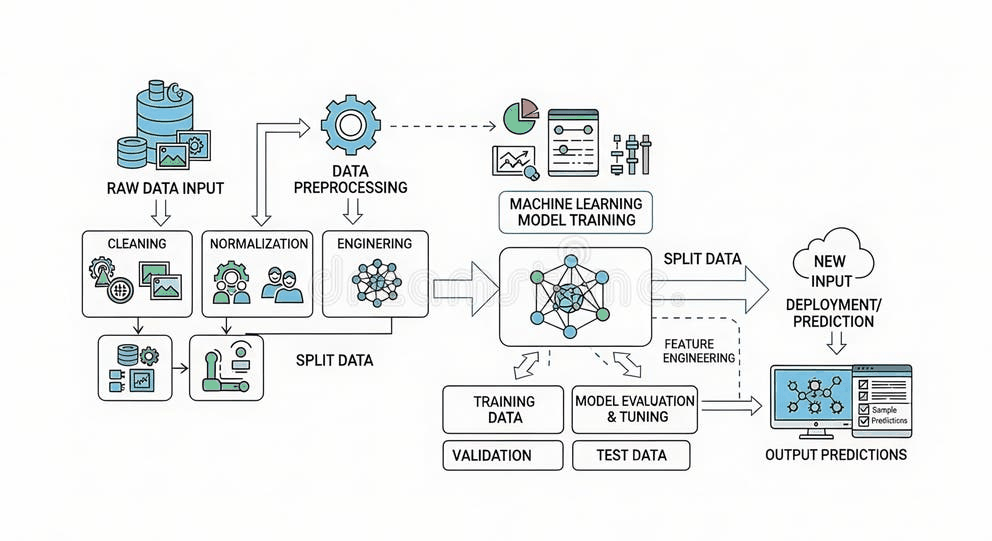
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)