Complete Technical Paper Content — Information Retrieval Ai
1. Executive Abstract, Problem Formulation & Background
Multimodal learning is a type of deep learning that integrates and processes multiple types of data, referred to as modalities, such as text, audio, images, or video. This integration allows for a more holistic understanding of complex data, improving model performance in tasks like visual question answering, cross-modal retrieval, text-to-image generation, aesthetic ranking, and image captioning. Multimodal learning was proposed in 2011 at the beginning of the deep learning period. Large multimodal models, such as Google Gemini and GPT-4o, have become increasingly popular since 2023, enabling increased versatility and a broader understanding of real-world phenomena.
Models such as CLIP (Contrastive Language–Image Pretraining) learn joint representations of images and text by optimizing contrastive objectives, allowing the model to match images with their corresponding textual descriptions.
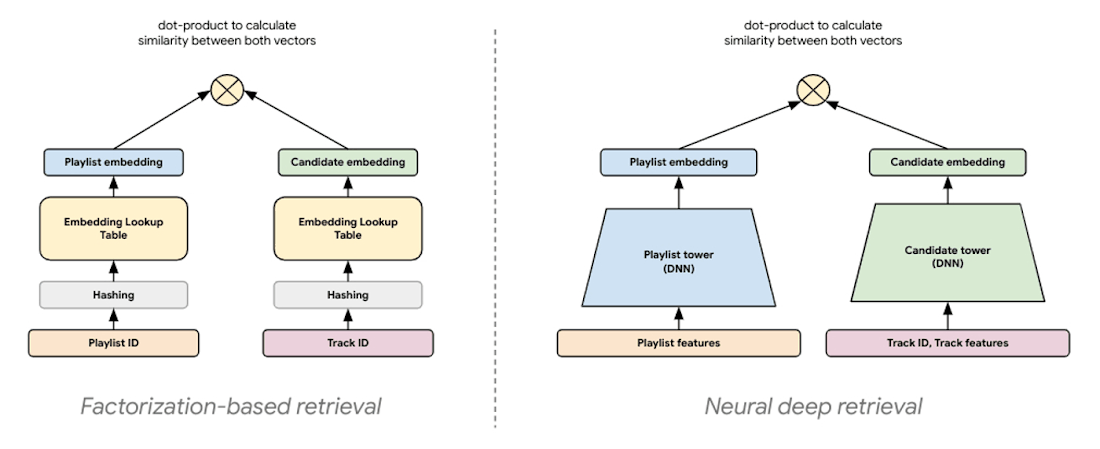
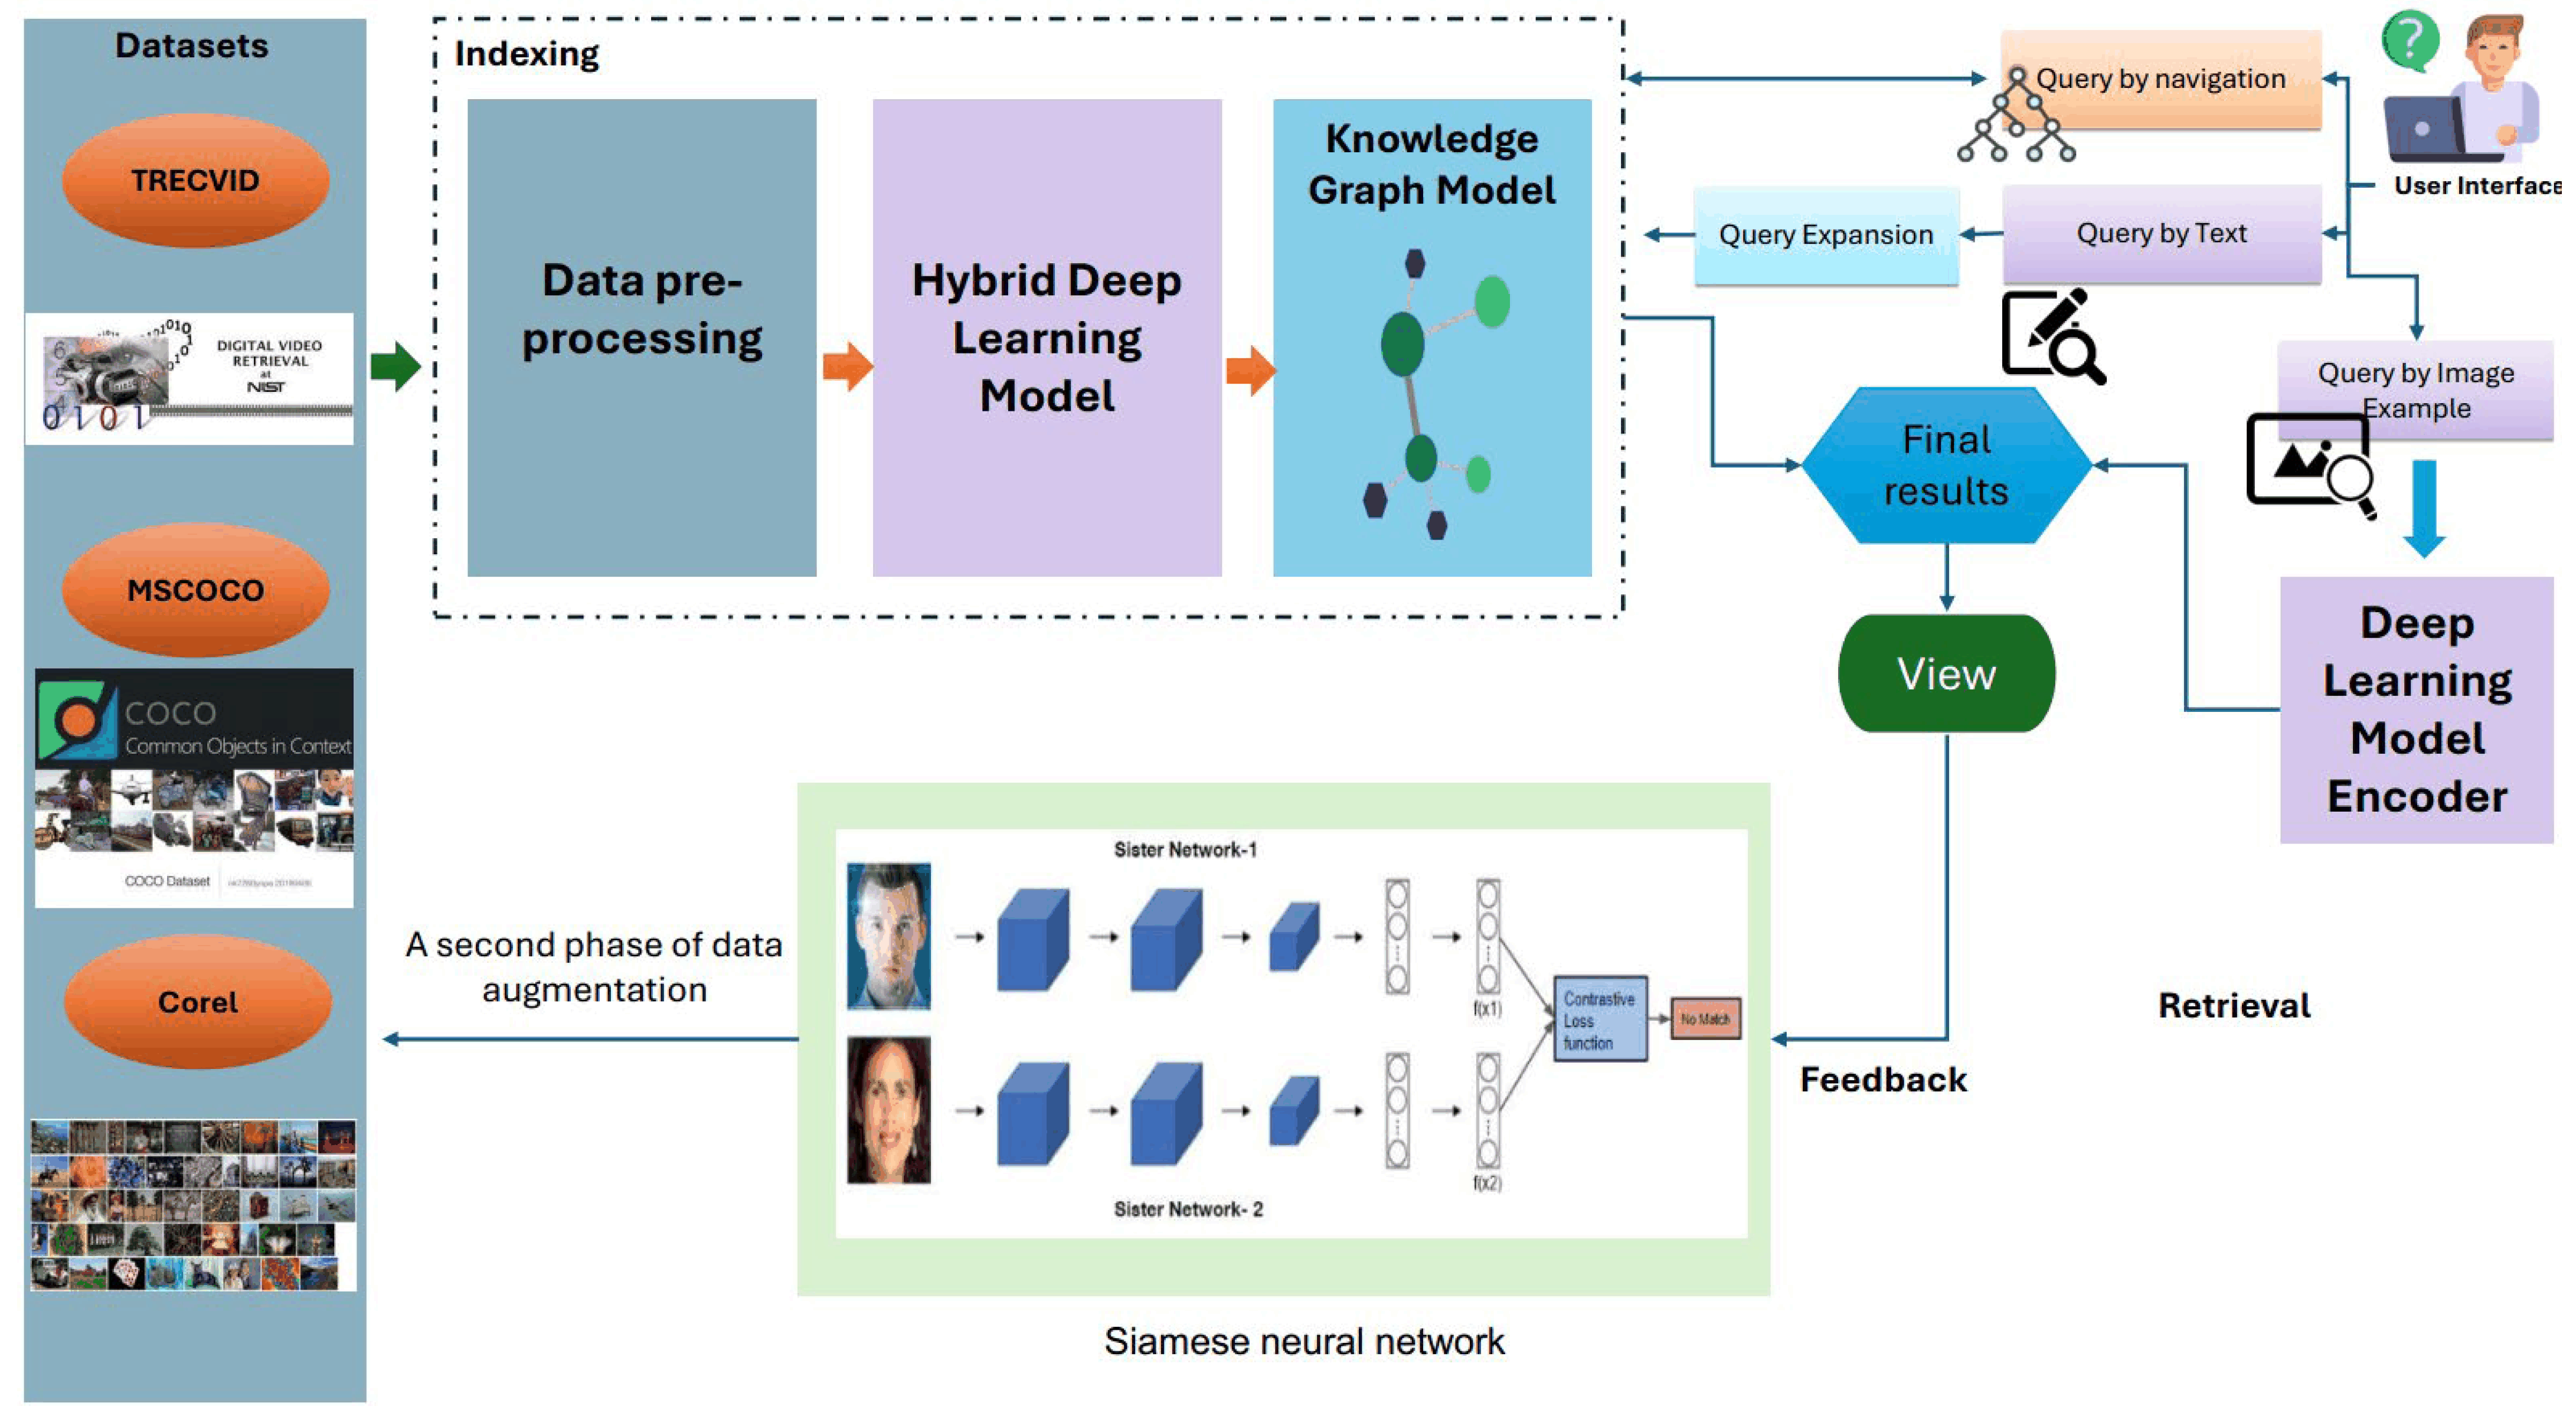
Cross-modal retrieval: cross-modal retrieval allows users to search for data across different modalities (e.g., retrieving images based on text descriptions), improving multimedia search engines and content recommendation systems. Classification and missing data retrieval: multimodal Deep Boltzmann Machines outperform traditional models like support vector machines and latent Dirichlet allocation in classification tasks and can predict missing data in multimodal datasets, such as images and text. Healthcare diagnostics: multimodal models integrate medical imaging, genomic data, and patient records to improve diagnostic accuracy and early disease detection, especially in cancer screening. Content generation: models like DALL·E generate images from textual descriptions, benefiting creative industries, while cross-modal retrieval enables dynamic multimedia searches. Robotics and human-computer interaction: multimodal learning improves interaction in robotics and AI by integrating sensory inputs like speech, vision, and touch, aiding autonomous systems and human-computer interaction. Emotion recognition: combining visual, audio, and text data, multimodal systems enhance sentiment analysis and emotion recognition, applied in customer service, social media, and marketing. Code search: multimodal representations combining source code structure (e.g., abstract syntax trees) with natural language descriptions improve retrieval of relevant code snippets for a given query. Source code has also been rendered as a two-dimensional pixel image, for instance by converting a method's control-flow graph into a black-and-white image processed with a convolutional neural network to search for malwares.
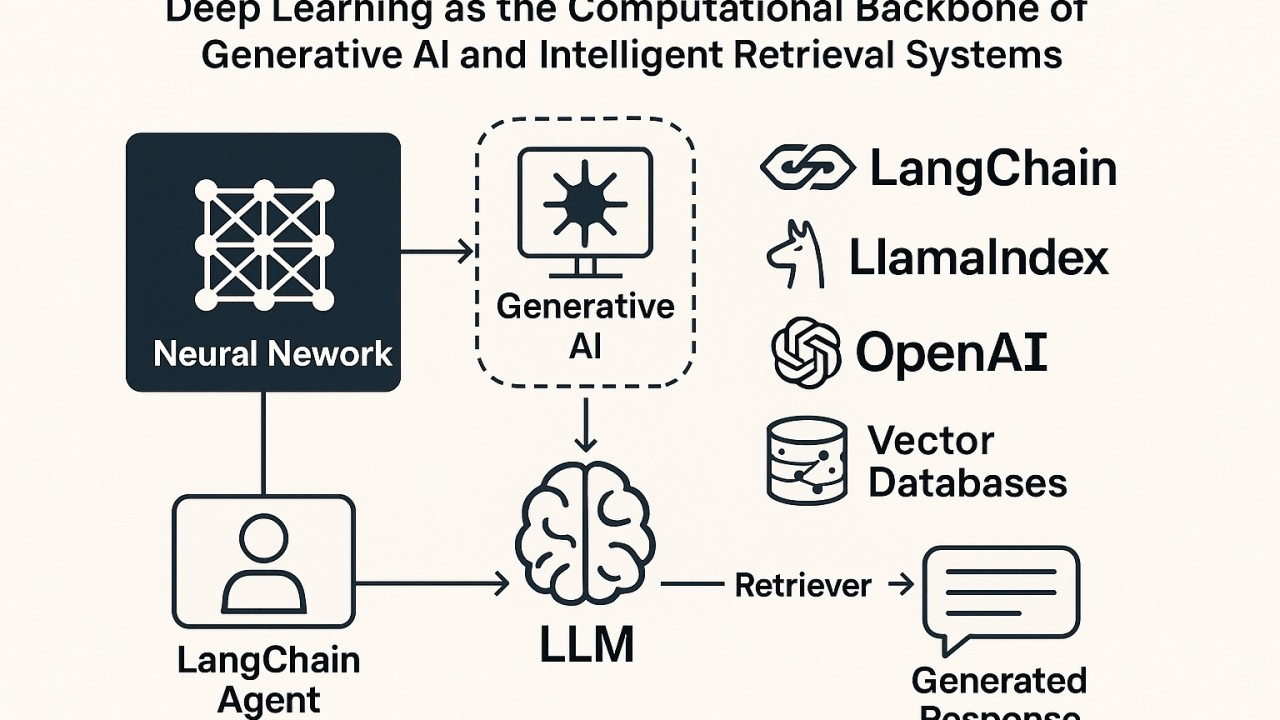
An AI agent, also known as agentic AI, is an artificial intelligence program that can make decisions, pursue goals, and take actions independently of human programmers. Agentic AI contrasts with tool-like AI use for narrow, specific tasks such as answering questions, as with chatbots in the non-agentic forms that were common since 2023, or with traditional machine learning algorithms. While there is no universally agreed-upon definition of an AI agent, common attributes of AI agents include goal-directed behavior, use of external tools, the ability to interact with and modify an external environment, and the ability to autonomously perform multi-step tasks. Their control flow is frequently driven by large language models (LLMs). Agent systems may also include memory components, planning logic, tool interfaces, and orchestration software for coordinating agent components.
The theoretical underpinnings for artificial agents emerged in the mid 20th century, with establishment of cybernetics and artificial intelligence. Oliver Selfridge's 1958 "Pandemonium: A Paradigm for Learning" paper was an important early theoretical contribution in establishing agent oriented architecture. Practical implementations of agents for real world applications began to become widespread in the 1990s, after the introduction of the belief–desire–intention software model (BDI), and agent-oriented programming. Harvard professor Milind Tambe notes that in the 1990s, the definition of an AI agent was not clear. Pure digital agents were deployed in computer infrastructure for purposes such as monitoring, while agents connected to real-world sensors and actuators were increasingly used in industrial control systems. Early artificial agents tended to have simple if then logic, which expanded over time into large decision tree models. By the early 2010s, products like Siri and Alexa were released, and were sometimes called AI agents, though they lacked the general purpose reasoning ability of later agents run by large language models (LLMs). The development of LLMs during the late 2010s and early 2020s introduced new approaches to AI agents. Models such as GPT-3 demonstrated the ability to generate and understand natural language at a much larger scale than many earlier language systems. Academics began to study LLM agents from 2018. Deployment of such agents began to accelerate in late 2023 after OpenAI's "function-calling" API was made available, and especially after Anthropic's late 2024 introduction of Model Context Protocol (MCP), a standardised way for LLM agents to gain contextual awareness, and to act on the world by calling various external tools. The term "agentic" only began to be used with any frequency in 2024, popularised in part by researcher Andrew Ng.
Ken Huang proposed an AI agent reference architecture that consists of seven interconnected layers, with each layer building on the functionality of the layers beneath it:
Layer 1: Foundation models – provide the datasets that power the agent. Layer 2: Data operations – manages the data infrastructure required for AI agent operations, including vector databases, data loaders, and RAG. Layer 3: Agent frameworks – software that manages the AI agents. Layer 4: Deployment and infrastructure – the technical foundation of the AI agents. Layer 5: Evaluation and observability – the safety and performance of AI agents. Layer 6: Security and compliance – a protective framework for safe operation and compliance with regulatory boundaries. At this layer, security and compliance features embedded into all the AI agent stack layers are integrated together. Layer 7: Agent ecosystem – represents the AI agents' interface with real-world applications and users.
An agent harness, or agent scaffold, is the software layer surrounding a large language model that enables it to function as an AI agent. It commonly manages prompts, context, tool use, memory, execution state, operational constraints, sandboxes, permissions, and the processing of results. The harness connects the model to internal and external computer hardware, software, data files, databases, web browsers, command-line interfaces, and application programming interfaces, while controlling how the agent accesses and uses these resources to complete multi-step tasks.
Prompt chaining: A sequence where the output of one step serves as the input for the next. Routing: Directing an input to a specialized downstream task or tool. Parallelization: The simultaneous execution of multiple tasks. Sequential processing: A fixed, linear progression of tasks through a predefined pipeline. Planner-critic: An iterative pattern where one agent generates a proposal and another evaluates it to provide feedback for refinement.
STRIDE: A Microsoft model that identifies threats across six categories: spoofing, tampering, repudiation, information disclosure, denial of service, and elevation of privilege. MITRE ATLAS: A knowledge base of adversary tactics and techniques for AI systems. OWASP GenAI Security Project: Provides guidance on vulnerabilities associated with generative AI and large language model integration, including guidelines specifically for agentic applications. MAESTRO: A framework from the Cloud Security Alliance for assessing risks in AI systems throughout their lifecycle.
DeepRetrieval - Hacking Real Search Engines & Retrievers with LLM via RL ⭐️ Star ⭐️ our repo to stay tuned with new features!! News [2025-05-19] If you're particularly interested in RAG tasks, we recommend checking out our latest work, s3 , a training-efficient framework specifically designed for RAG. [2025-05-06] You can now easily deploy our model and call the api for query rewriting. See here for more details. [2025-02-28] 🎉 We are excited to release the code for DeepRetrieval! What is DeepRetrieval? DeepRetrieval is a novel reinforcement learning approach that trains Large Language Models (LLMs) for query generation to enhance information retrieval performance. Unlike traditional methods that rely on supervised learning with labeled query-augmentation pairs, DeepRetrieval lets models learn through direct trial and error, using retrieval metrics as rewards to generate queries that maximize retrieval performance. The system works by having an LLM generate reasoning steps in a <think> section followed by the final augmented query in an <answer> section. This structured approach enables explicit chain-of-thought reasoning before committing to a query formulation. Key Features and Results No Supervision Required : Eliminates the need for expensive human-annotated or distilled reference queries Powerful Performance : Significantly outperforms previous state-of-the-art methods 65.07% recall (vs. previous SOTA 24.68%) for publication search 63.18% recall (vs. previous SOTA 32.11%) for clinical trials search Versatile Applications : Excels across diverse retrieval tasks: (1) Literature search using real-world search engines (2) Evidence-seeking retrieval (3) Classic information retrieval (4) SQL database search Parameter Efficient : Achieves superior results with only 3B parameters, outperforming larger models like GPT-4o and Claude-3.5-Sonnet Example Wandb Training Log on PubMed Search Engine ⭐️ Star our repository to stay up-to-date with exciting new features and improvements! 🌟 Table of Contents 📦 Installation ⚡️ Easy-to-use API for Query Rewriting 🫧 Get Started 🏃 Run Training 🧐 Run Evaluation 📚 Cite DeepRetrieval 📦 Installation General Installation (for all retrieval methods): conda create -n zero python=3.9 # install torch [or you can skip this step and let vllm to install the correct version for you] pip install torch==2.4.0 --index-url https://download.pytorch.org/whl/cu121 # install vllm pip3 install vllm==0.6.3 # or you can install 0.5.4, 0.4.2 and 0.3.1 pip3 install ray # verl cd code pip install -e . # flash attention 2 pip3 install flash-attn --no-build-isolation # quality of life pip install wandb IPython matplotlib huggingface_hub (If you only want to run the Search Engine Retrieval, you can skip the following steps.) If using sparse retrieval (e.g., BM25) or dense retrieval (e.g., DPR), please also install the following: # we use pyserini for efficient retrieval and evaluation pip install pyserini # the version we used is 0.22.1 # if you don't have faiss installed, install it with: pip install faiss-gpu==1.7.2 # the version we used is 1.7.2 # if you don't have java installed, install it with: pip install install-jdk && python -c "import jdk; jdk.install('11')" # support sql execution pip install func_timeout ⚡️ Easy-to-use API for Query Rewriting sh vllm_host.sh # you can specify the local port and the model to use python query_rewrite.py --query " Who built DeepRetrieval in 2025? " # Original query: Who built DeepRetrieval in 2025? # Rewritten query: (The DeepRetrieval system, which was built in 2025) 🫧 Get Started 1. Dataset Download/Preprocess We provide two options for data preparation: 🚀 Option 1: Download pre-processed datasets from Huggingface (Recommended) All preprocessed datasets are available on our Huggingface repository. You can download them using the provided script: cd code # List available datasets python download_datasets.py --list_only --repo_id DeepRetrieval/datasets # Download all datasets python download_datasets.py --repo_id DeepRetrieval/datasets --output_dir ./data # Or download specific categories/datasets python download_datasets.py --categories search_engine --datasets pubmed_32 --output_dir ./data ⛏️ Option 2: Process the data yourself For example, for PubMed: cd code python download_datasets.py --categories raw_data --datasets pubmed --output_dir ./data python data_preprocess/pubmed_32.py (This will generate the required data structures in the appropriate format, but requires raw data access and more processing time.) 2. Get Your Search Engine API Key (required if use search engine) For example, for PubMed, you may get it following the instruction here . (PubMed API is 100% ✨FREE✨ to use!) Then, put it in under code/verl/utils/reward_score/apis/ as pubmed_api.key . 3. Reward function Related (optional) Reward Design (e.g., in code/verl/utils/reward_score/pubmed.py ): Recall ≥ 0.7 ≥ 0.5 ≥ 0.4 ≥ 0.3 ≥ 0.1 ≥ 0.05 < 0.05 Reward +5.0 +4.0 +3.0 +1.0 +0.5 +0.1 -3.5 4. Customize Monitor Info (optional) modify compute_reward_metrics() in code/verl/trainer/ppo/ray_trainer.py 🏃 Run Training conda activate zero For example, for PubMed: sh scripts/train/pubmed_32.sh (if you see Out-of-vram, try add critic.model.enable_gradient_checkpointing=True to the script) Think/Query Length During Training (PubMed) 🧐 Run Evaluation sh scripts/eval/pubmed_32.sh (You can run this script without training, as it will download our trained model from Huggingface by default) Results on Search Engines Model Method Publication Recall Clinical Trials Recall Original Query - 10.36 18.01 GPT-3.5 - 11.67 9.42 w/o reasoning 18.68 13.94 GPT-4o - 17.59 16.25 w/o reasoning 19.72 14.26 Claude-3-Haiku - 11.26 10.10 w/o reasoning 20.92 24.68 Claude-3.5-Sonnet - 20.94 18.33 w/o reasoning 19.08 18.41 Mistral-7B-Inst - 7.18 8.08 LEADS-7B (SFT) - 24.68 32.11 Qwen2.5-3B-Inst - 6.59 6.09 w/o reasoning 9.46 7.97 DeepRetrieval-3B - ✨ 65.07 ✨ ✨ 63.18 ✨ w/o reasoning 51.90 53.31 *Table: Comparison of different models and methods on publication search and clinical trials search tasks. Note: LEADS-7B is a state-of-the-art literature mining LLM trained on 20K reviews and 400K publications [ https://arxiv.org/pdf/2501.16255 ] ⚠️ Commonly Encountered Issues ⚙️ Cluster Setup: CUDA and Conda Environment 💻 slurm-related Before running any training or evaluation scripts on the cluster, make sure to load the correct CUDA module and activate your Conda environment . 🧩 GPUs Allocation If your CUDA inside a SLURM job doesn’t match the CUDA seen by your Python script, you may get a warning like: UserWarning: CUDA initialization: CUDA driver initialization failed, you might not have a CUDA GPU. (Triggered internally at ../c10/cuda/CUDAFunctions.cpp:108.) return torch._C._cuda_getDeviceCount() > 0 To fix this, do not manually set your CUDA device inside the script. Instead, load the CUDA module directly inside your SLURM job: Add the following lines before running any Python commands : # --- Load CUDA module --- module load cuda/12.6 # --- Activate Conda environment --- source ~ /miniconda/etc/profile.d/conda.sh # adjust path if your conda installation differs conda activate zero If you previously specified a device inside your training script or job file (e.g., pubmed_32.sh), remove lines like: export CUDA_VISIBLE_DEVICES=4,7 This ensures CUDA is managed correctly by SLURM. ⚙️ Dependency Conflicts When setting up the environment, you might encounter pip dependency warnings such as: ERROR: pip's dependency resolver does not currently take into account all the packages that are installed. This behaviour is the source of the following dependency conflicts. matplotlib 3.9.4 requires pyparsing>=2.3.1, which is not installed. mne 1.8.0 requires decorator, which is not installed. pyhealth 1.1.4 requires bitsandbytes, which is not installed. To fix these missing dependencies, simply run: pip install pyparsing decorator bitsandbytes You may also encounter NumPy incompatibility warnings like: pyhealth 1.1.4 requires numpy<2.0, but you have numpy 2.0.2 which is incompatible. outlines 0.0.46 requires numpy<2.0.0, but you have numpy 2.0.2 which is incompatible. vllm 0.6.3 requires numpy<2.0.0, but you have numpy 2.0.2 which is incompatible. To fix these, reinstall a compatible NumPy version and re-install dependent packages: pip install " numpy<2.0.0 " --force-reinstall pip install transformers==4.46.3 pip install vllm==0.6.3 pip install verl==0.1 pip install outlines==0.0.46 pip install pyserini 🤝 Acknowledgement This implementation is mainly based on verl and PySerini . The base model during the experiment is Qwen2.5-3B-Instruct . We sincerely appreciate their contributions to the open-source community. 📚 Cite DeepRetrieval @article{jiang2025deepretrieval, title={Deepretrieval: Hacking real search engines and retrievers with large language models via reinforcement learning}, author={Jiang, Pengcheng and Lin, Jiacheng and Cao, Lang and Tian, Runchu and Kang, SeongKu and Wang, Zifeng and Sun, Jimeng and Han, Jiawei}, journal={arXiv preprint arXiv:2503.00223}, year={2025} } Thanks for your interests! 😊
DeepRetrieval is a novel reinforcement learning approach that trains Large Language Models (LLMs) for query generation to enhance information retrieval performance. Unlike traditional methods that rely on supervised learning with labeled query-augmentation pairs, DeepRetrieval lets models learn through direct trial and error, using retrieval metrics as rewards to generate queries that maximize retrieval performance.
The system works by having an LLM generate reasoning steps in a <think> section followed by the final augmented query in an <answer> section. This structured approach enables explicit chain-of-thought reasoning before committing to a query formulation.
2. Related Work, Literature Survey & Algorithmic Foundations
⭐️ Star our repository to stay up-to-date with exciting new features and improvements! 🌟
conda create -n zero python=3.9 # install torch [or you can skip this step and let vllm to install the correct version for you] pip install torch==2.4.0 --index-url https://download.pytorch.org/whl/cu121 # install vllm pip3 install vllm==0.6.3 # or you can install 0.5.4, 0.4.2 and 0.3.1 pip3 install ray # verl cd code pip install -e . # flash attention 2 pip3 install flash-attn --no-build-isolation # quality of life pip install wandb IPython matplotlib huggingface_hub
(If you only want to run the Search Engine Retrieval, you can skip the following steps.)
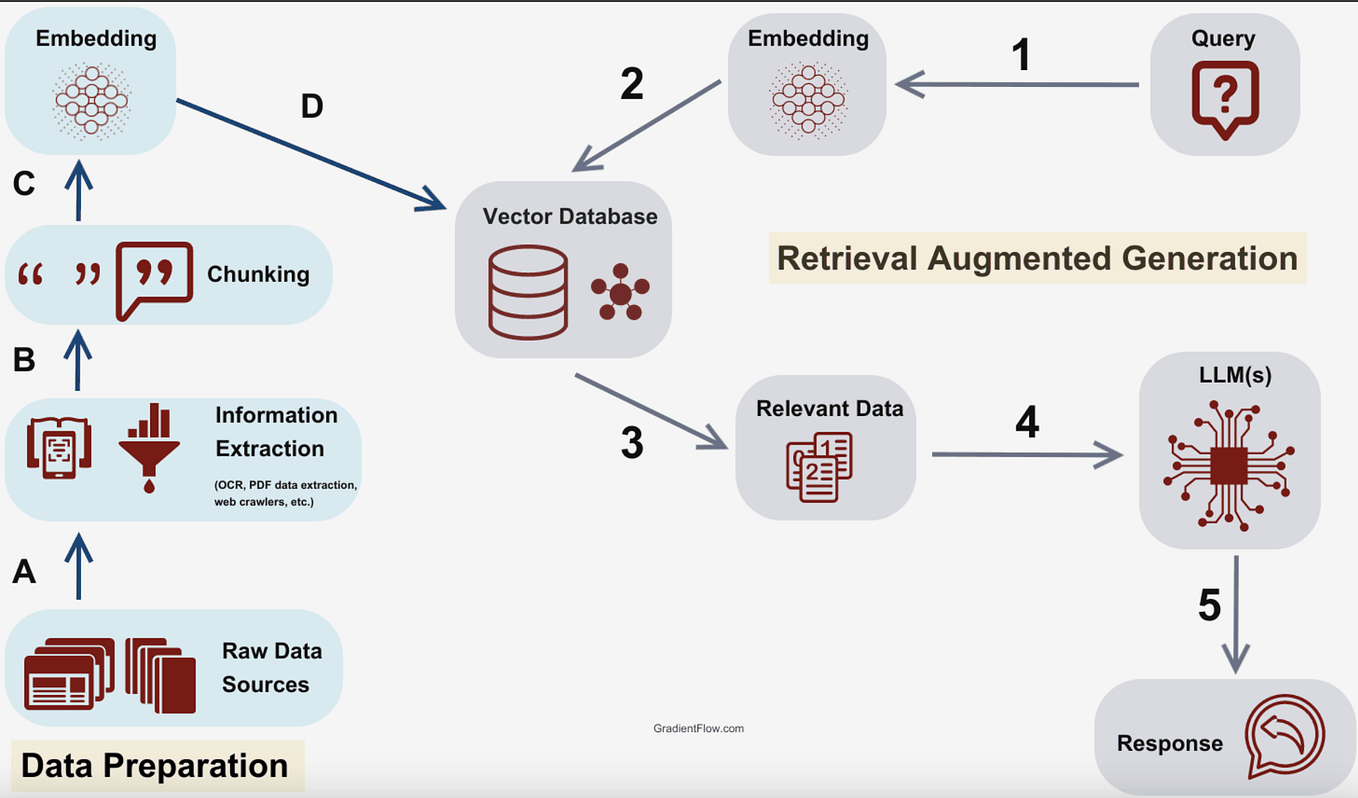
If using sparse retrieval (e.g., BM25) or dense retrieval (e.g., DPR), please also install the following:
# we use pyserini for efficient retrieval and evaluation pip install pyserini # the version we used is 0.22.1 # if you don't have faiss installed, install it with: pip install faiss-gpu==1.7.2 # the version we used is 1.7.2 # if you don't have java installed, install it with: pip install install-jdk && python -c "import jdk; jdk.install('11')" # support sql execution pip install func_timeout
sh vllm_host.sh # you can specify the local port and the model to use python query_rewrite.py --query " Who built DeepRetrieval in 2025? " # Original query: Who built DeepRetrieval in 2025? # Rewritten query: (The DeepRetrieval system, which was built in 2025)
All preprocessed datasets are available on our Huggingface repository. You can download them using the provided script:
cd code # List available datasets python download_datasets.py --list_only --repo_id DeepRetrieval/datasets # Download all datasets python download_datasets.py --repo_id DeepRetrieval/datasets --output_dir ./data # Or download specific categories/datasets python download_datasets.py --categories search_engine --datasets pubmed_32 --output_dir ./data
cd code python download_datasets.py --categories raw_data --datasets pubmed --output_dir ./data python data_preprocess/pubmed_32.py
(This will generate the required data structures in the appropriate format, but requires raw data access and more processing time.)
For example, for PubMed, you may get it following the instruction here . (PubMed API is 100% ✨FREE✨ to use!)
(if you see Out-of-vram, try add critic.model.enable_gradient_checkpointing=True to the script)
(You can run this script without training, as it will download our trained model from Huggingface by default)
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
*Table: Comparison of different models and methods on publication search and clinical trials search tasks.
Note: LEADS-7B is a state-of-the-art literature mining LLM trained on 20K reviews and 400K publications [ https://arxiv.org/pdf/2501.16255 ]
Before running any training or evaluation scripts on the cluster, make sure to load the correct CUDA module and activate your Conda environment .
If your CUDA inside a SLURM job doesn’t match the CUDA seen by your Python script, you may get a warning like:
UserWarning: CUDA initialization: CUDA driver initialization failed, you might not have a CUDA GPU. (Triggered internally at ../c10/cuda/CUDAFunctions.cpp:108.) return torch._C._cuda_getDeviceCount() > 0
To fix this, do not manually set your CUDA device inside the script. Instead, load the CUDA module directly inside your SLURM job:
# --- Load CUDA module --- module load cuda/12.6 # --- Activate Conda environment --- source ~ /miniconda/etc/profile.d/conda.sh # adjust path if your conda installation differs conda activate zero
If you previously specified a device inside your training script or job file (e.g., pubmed_32.sh), remove lines like:
ERROR: pip's dependency resolver does not currently take into account all the packages that are installed. This behaviour is the source of the following dependency conflicts. matplotlib 3.9.4 requires pyparsing>=2.3.1, which is not installed. mne 1.8.0 requires decorator, which is not installed. pyhealth 1.1.4 requires bitsandbytes, which is not installed.
pyhealth 1.1.4 requires numpy<2.0, but you have numpy 2.0.2 which is incompatible. outlines 0.0.46 requires numpy<2.0.0, but you have numpy 2.0.2 which is incompatible. vllm 0.6.3 requires numpy<2.0.0, but you have numpy 2.0.2 which is incompatible.
pip install " numpy<2.0.0 " --force-reinstall pip install transformers==4.46.3 pip install vllm==0.6.3 pip install verl==0.1 pip install outlines==0.0.46 pip install pyserini
This implementation is mainly based on verl and PySerini . The base model during the experiment is Qwen2.5-3B-Instruct . We sincerely appreciate their contributions to the open-source community.
@article{jiang2025deepretrieval, title={Deepretrieval: Hacking real search engines and retrievers with large language models via reinforcement learning}, author={Jiang, Pengcheng and Lin, Jiacheng and Cao, Lang and Tian, Runchu and Kang, SeongKu and Wang, Zifeng and Sun, Jimeng and Han, Jiawei}, journal={arXiv preprint arXiv:2503.00223}, year={2025} }
4. Neural Network Backbone, Layer Specifications & Loss Formulations
VectifyAI / PageIndex Sponsor Star 39.9k 📑 PageIndex: Document Index for Vectorless, Reasoning-based RAG information-retrieval ai retrieval agents reasoning ai-agents rag vector-database llm retrieval-augmented-generation agentic-ai context-engineering Updated Oct 29, 2026 Python
onyx-dot-app / onyx Star 33.1k Open Source AI Platform - AI Chat with advanced features that works with every LLM python information-retrieval ai nextjs self-hosted enterprise-search chatui rag vector-search ai-chat llm chatgpt gen-ai llm-ui Updated Oct 29, 2026 Python
JaidedAI / EasyOCR Star 30.1k Ready-to-use OCR with 80+ supported languages and all popular writing scripts including Latin, Chinese, Arabic, Devanagari, Cyrillic and etc. python machine-learning information-retrieval data-mining ocr deep-learning image-processing cnn pytorch lstm optical-character-recognition crnn scene-text scene-text-recognition easyocr Updated Dec 5, 2025 Python
Ready-to-use OCR with 80+ supported languages and all popular writing scripts including Latin, Chinese, Arabic, Devanagari, Cyrillic and etc.
deepset-ai / haystack Star 26.9k Open-source AI orchestration framework for building context-engineered, production-ready LLM applications. Design modular pipelines and agent workflows with explicit control over retrieval, routing, memory, and generation. Built for scalable agents, RAG, multimodal applications, semantic search, and conversational systems. python information-retrieval framework ai mcp orchestration multi-agent agents semantic-search ai-agents rag agent-framework large-language-models llm generative-ai genai retrieval-augmented-generation agentic-rag agentic-ai context-engineering Updated Oct 29, 2026 Python
Open-source AI orchestration framework for building context-engineered, production-ready LLM applications. Design modular pipelines and agent workflows with explicit control over retrieval, routing, memory, and generation. Built for scalable agents, RAG, multimodal applications, semantic search, and conversational systems.
arc53 / DocsGPT Sponsor Star 18.3k Private AI platform for agents, assistants and enterprise search. Built-in Agent Builder, Deep research, Document analysis, Multi-model support, and API connectivity for agents. react python search machine-learning natural-language-processing information-retrieval ai transformers pytorch language-model agents semantic-search hacktoberfest rag hacktoberfest-swag llm hacktoberfest2026 chatgpt agent-builder docsgpt Updated Oct 29, 2026 Python
Private AI platform for agents, assistants and enterprise search. Built-in Agent Builder, Deep research, Document analysis, Multi-model support, and API connectivity for agents.
weaviate / weaviate Star 16.9k Weaviate is an open-source vector database that stores both objects and vectors, allowing for the combination of vector search with structured filtering with the fault tolerance and scalability of a cloud-native database. search-engine information-retrieval grpc nearest-neighbor-search semantic-search-engine image-search recommender-system vectors approximate-nearest-neighbor-search semantic-search similarity-search mlops hnsw weaviate vector-search vector-database neural-search vector-search-engine hybrid-search generative-search Updated Oct 29, 2026 Go
Weaviate is an open-source vector database that stores both objects and vectors, allowing for the combination of vector search with structured filtering with the fault tolerance and scalability of a cloud-native database.
piskvorky / gensim Sponsor Star 16.5k Topic Modelling for Humans python nlp data-science machine-learning natural-language-processing information-retrieval data-mining neural-network word2vec word-embeddings topic-modeling gensim fasttext document-similarity word-similarity Updated Nov 1, 2025 Python
Unstructured-IO / unstructured Star 15.6k Convert documents to structured data effortlessly. Unstructured is open-source ETL solution for transforming complex documents into clean, structured formats for language models. Visit our website to learn more about our enterprise grade Platform product for production grade workflows, partitioning, enrichments, chunking and embedding. nlp pdf machine-learning natural-language-processing information-retrieval ocr deep-learning ml docx preprocessing pdf-to-text data-pipelines donut document-image-processing document-parser pdf-to-json document-image-analysis llm document-parsing langchain Updated Oct 29, 2026 HTML
Convert documents to structured data effortlessly. Unstructured is open-source ETL solution for transforming complex documents into clean, structured formats for language models. Visit our website to learn more about our enterprise grade Platform product for production grade workflows, partitioning, enrichments, chunking and embedding.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
neuml / txtai Star 13k 💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows python search nlp search-engine information-retrieval ai transformers embeddings language-model agents semantic-search ai-agents sentence-embeddings rag vector-search vector-database txtai large-language-models llm retrieval-augmented-generation Updated Oct 27, 2026 Python
💡 All-in-one AI framework for semantic search, LLM orchestration and language model workflows
FlagOpen / FlagEmbedding Star 12.3k Retrieval and Retrieval-augmented LLMs information-retrieval embeddings sentence-embeddings text-semantic-similarity llm retrieval-augmented-generation Updated Oct 27, 2026 Python
airweave-ai / airweave Star 6.6k Open-source context retrieval layer for AI agents search api open-source information-retrieval sdk ai integration retrieval developer-tools semantic-search search-api ai-agents data-connectors rag enterprise-data llm retrieval-augmented-generation context-retrieval ai-infrastructure agent-infrastructure Updated Jun 5, 2026 Python
apache / lucene-solr Star 4.4k Apache Lucene and Solr open-source search software search java search-engine information-retrieval backend nosql solr lucene Updated May 15, 2026
SylphAI-Inc / AdalFlow Star 4.2k AdalFlow: The library to build & auto-optimize LLM applications. python nlp agent machine-learning information-retrieval framework ai chatbot optimizer question-answering summarization trainer bm25 retriever faiss reranker rag llm generative-ai auto-prompting Updated Oct 29, 2026 Python
langroid / langroid Sponsor Star 4.1k Harness LLMs with Multi-Agent Programming information-retrieval ai llama gpt language-model agents multi-agent-systems rag openai-api gpt-4 gpt4 llm chatgpt llm-agent local-llm retrieval-augmented-generation function-calling llm-framework Updated Oct 29, 2026 Python
KittyKatt / screenFetch Sponsor Star 4.1k Fetches system/theme information in terminal for Linux desktop screenshots. shell bash information-retrieval desktop Updated Oct 9, 2026 Shell
apache / lucene Star 3.6k Apache Lucene open-source search software search java search-engine information-retrieval backend nosql lucene Updated Oct 29, 2026 Java
ashvardanian / StringZilla Star 3.6k Up to 100x faster strings for C, C++, CUDA, Python, Rust, Swift, JS, & Go, leveraging NEON, AVX2, AVX-512, SVE, GPGPU, & SWAR to accelerate search, hashing, sorting, edit distances, sketches, and memory ops 🦖 search hashing unicode parser information-retrieval string gpu hash edit-distance simd dataset levenshtein-distance string-manipulation sorting-algorithms substring string-matching string-search string-parsing Updated Oct 27, 2026 C
Up to 100x faster strings for C, C++, CUDA, Python, Rust, Swift, JS, & Go, leveraging NEON, AVX2, AVX-512, SVE, GPGPU, & SWAR to accelerate search, hashing, sorting, edit distances, sketches, and memory ops 🦖
embeddings-benchmark / mteb Star 3.5k MTEB: State-of-the-art evaluation of embeddings across languages and modalities benchmark information-retrieval retrieval text-classification clustering evaluation embeddings sts semantic-search reranking text-embedding multimodal neural-search sentence-transformers sbert multilingual-nlp low-resource-nlp bitext-mining mteb Updated Oct 29, 2026 Python
superlinked / sie Star 3.5k Open-source inference server and production cluster for all the models your agent needs. python nlp natural-language-processing information-retrieval deep-learning retrieval ml inference embeddings bge semantic-search inference-server data-pipeline reranking mlops vector-search colbert llm splade retrieval-augmented-generation Updated Oct 29, 2026 Python
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)