Complete Technical Paper Content — Llama Fine Tuning Projects
1. Executive Abstract, Problem Formulation & Background
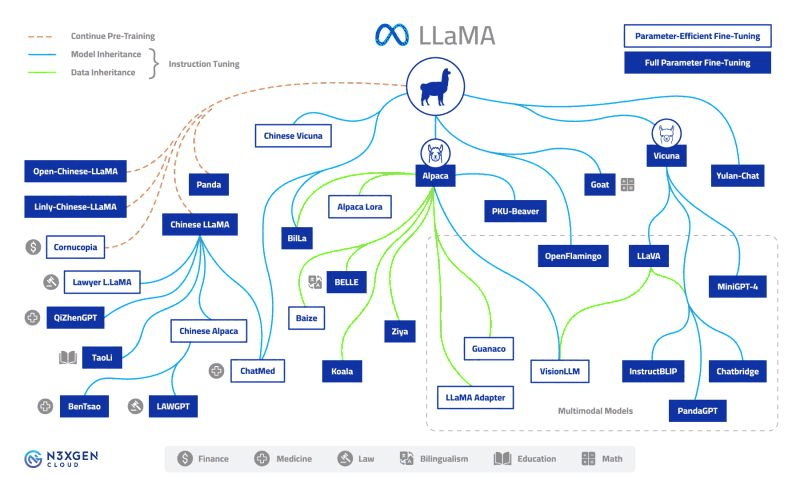
Llama ("Large Language Model Meta AI" serving as a backronym) was a family of large language models (LLMs) released by Meta AI from February 2023 to April 2025. Llama models come in different sizes, ranging from 1 billion to 2 trillion parameters. Initially only a foundation model, starting with Llama 2, Meta AI released instruction fine-tuned versions alongside foundation models. Model weights for the first version of Llama were only available to researchers on a case-by-case basis, under a non-commercial license. Unauthorized copies of the first model were shared via BitTorrent. Subsequent versions of Llama were made accessible outside academia and released under licenses that permitted some commercial use. Alongside the release of Llama 3, Meta rolled out Meta AI, an AI assistant built on Llama. Meta AI has a dedicated website and is available on Facebook and WhatsApp. The latest version is Llama 4, released in April 2025. In April 2026, Meta Superintelligence Labs released Muse Spark as a replacement for Llama powering chatbots on various Meta services.
The Llama 4 series was released in 2025. The architecture was changed to a mixture of experts where only a fraction of the model’s expert sub-networks are activated per input token. They are multimodal (text and image input, text output) and multilingual (12 languages). Specifically, on 5 April 2025, the following were released both as base and instruction-tuned versions:
Scout: 17 billion active parameter model with 16 experts, context window of 10M, with 109B parameters in total. Maverick: 17 billion active parameter model with 128 experts, context window of 1M, with 400B parameters in total. The Behemoth model was also announced, but was not released. Meta claimed it was a 288 billion active parameter model with 16 experts and around 2T parameters in total; it was still in training when Scout and Maverick were released. Maverick was codistilled from Behemoth, while Scout was trained from scratch. The training data included publicly available data, licensed data, and Meta-proprietary data such as publicly shared posts from Instagram and Facebook and people’s interactions with Meta AI. The knowledge cutoff was August 2024. Meta claimed in its release announcement that Llama 4 bested GPT-4o's score on the LMArena AI benchmark. The company also stated that Llama 4's benchmark score was achieved using an unreleased "experimental chat version" of the model that was "optimized for conversationality", which differed from the version of Llama 4 released to the public. LMArena indicated that it would change its policies to prevent this incident from reoccurring, and responded, "Meta's interpretation of our policy did not match what we expect from model providers. Meta should have made it clearer that 'Llama-4-Maverick-03-26-Experimental' was a customized model to optimize for human preference." Some users criticized Meta on social media for its use of a separate model version tailored for benchmarking, and some additionally accused Meta of training Llama 4 on test sets to further boost its benchmark scores, which Meta denied.
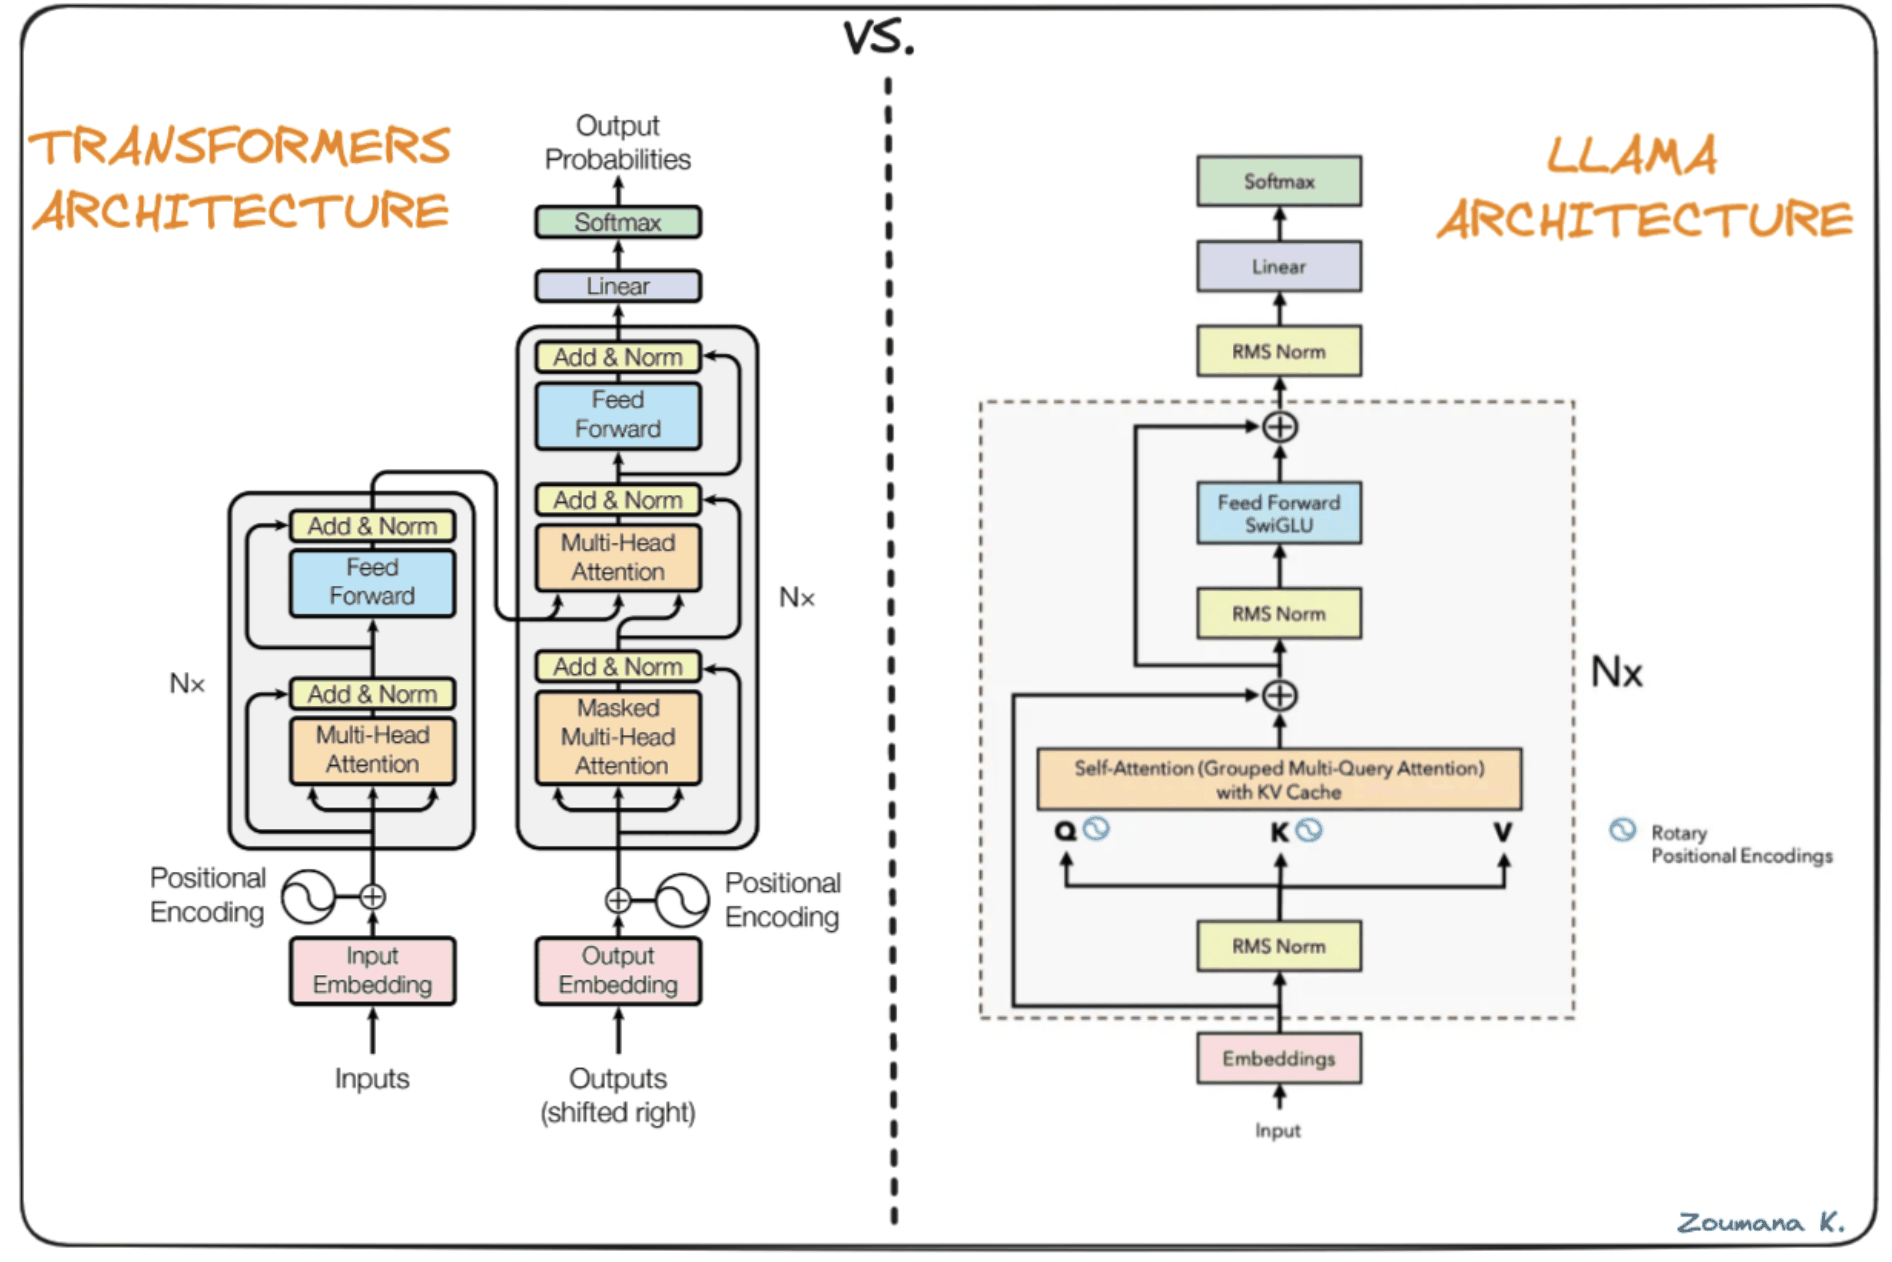
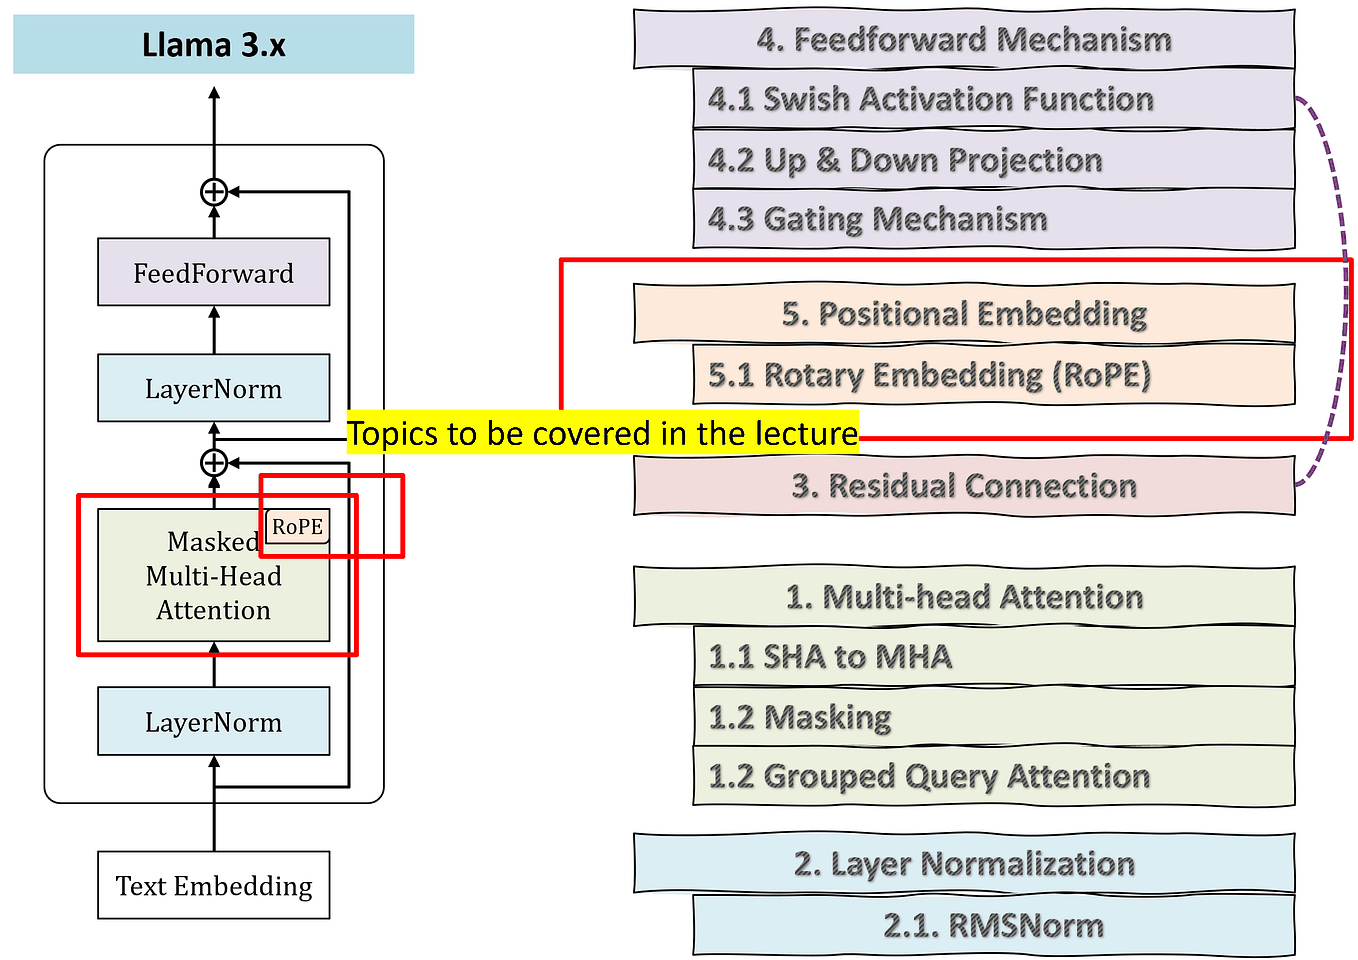
Llama uses the SwiGLU activation function instead of GPT-3's GeLU. Llama uses rotary positional embeddings (RoPE) instead of absolute positional embedding. Instead of layer normalization, Llama uses RMSNorm.
Webpages scraped by CommonCrawl Open-source repositories of source code from GitHub Wikipedia in 20 languages Public domain books from Project Gutenberg Books3 books dataset The LaTeX source code for scientific papers uploaded to ArXiv Questions and answers from Stack Exchange websites In April 2023, Together AI launched a project named RedPajama to reproduce and distribute an open-source version of the Llama dataset, initially containing approximately 1.2 trillion tokens. Llama 2 foundational models were trained on a data set with 2 trillion tokens. This data set was curated to remove Web sites that often disclose personal data of people. It also upsamples sources considered trustworthy. Llama 2 - Chat was additionally fine-tuned on 27,540 prompt-response pairs created for this project, which performed better than larger but lower-quality third-party datasets. For AI alignment, reinforcement learning with human feedback (RLHF) was used with a combination of 1,418,091 Meta examples and seven smaller datasets. The average dialog depth was 3.9 in the Meta examples, 3.0 for Anthropic Helpful and Anthropic Harmless sets, and 1.0 for five other sets, including OpenAI Summarize, StackExchange, etc. Llama 3 consists of mainly English data, with over 5% in over 30 other languages. Its dataset was filtered by a text-quality classifier, and the classifier was trained by text synthesized by Llama 2. In a lawsuit against Meta Platforms brought by authors including Richard Kadrey, Sarah Silverman, and Ta-Nehisi Coates, CEO Mark Zuckerberg was alleged to have authorized the use of copyrighted content from Library Genesis to train Llama AI models and conceal its actions by removing copyright markers from the data.
Software developer Georgi Gerganov released llama.cpp as open-source on March 10, 2023. It's a re-implementation of Llama in C++, allowing systems without a powerful GPU to run the model locally. The llama.cpp project introduced the GGUF file format, a binary format that stores both tensors and metadata. The format focuses on supporting different quantization types, which can reduce memory usage, and increase speed at the expense of lower model precision. llamafile created by Justine Tunney is an open-source tool that bundles llama.cpp with the model into a single executable file. Tunney et al. introduced new optimized matrix multiplication kernels for x86 and ARM CPUs, improving prompt evaluation performance for FP16 and 8-bit quantized data types.
These lists include projects which release their software under open-source licenses and are related to artificial intelligence projects. These include software libraries, frameworks, platforms, and tools used for machine learning, deep learning, natural language processing, computer vision, reinforcement learning, artificial general intelligence, and more.
Auto-GPT — experimental open-source autonomous GPT-based agent OpenClaw — autonomous task-executing AI agent CrewAI — framework for building and orchestrating multi-agent AI systems LangChain — framework for building applications and agents powered by large language models Theia AI — framework for integrating AI capabilities and agents into integrated development environments (IDEs).
Codex CLI – AI coding agent and command-line interface developed by OpenAI. Cline – AI coding agent for IDEs and the command line. Command Code — CLI and desktop AI agent DeepSeek Coder – large language model designed for code generation and AI-assisted software development. goose – AI coding agent for the desktop and command line. Grok Build – SpaceXAI's terminal-based AI coding agent. Hermes Agent – AI coding agent for the command line and IDE extensions. Kilo Code — CLI and IDE extension developed by Anaconda OpenCode — CLI, desktop app, web app, and IDE extensions OpenHands — AI software development agent Oh My Pi – terminal-based AI coding agent developed as a fork of Pi. Pi – terminal-based AI coding agent. Warp – agentic development environment combining a terminal, integrated coding agent, and CLI. Zed – source-code editor with integrated AI-assisted development and agentic coding features.
2. Related Work, Literature Survey & Algorithmic Foundations
EDLUT – event-driven neural network simulator for large-scale spiking networks Emergent – cognitive modeling platform implementing neural networks Encog – machine learning framework for Java and C# supporting neural networks JOONE – Java-based neural network framework with modular architecture for learning tasks Nengo – Python library for building and simulating large-scale neural systems Neuroph – lightweight Java framework for creating neural networks OpenNN – C++ library for designing, training, and deploying neural networks SNNS – Stuttgart Neural Network Simulator, supports feedforward and recurrent neural networks
ACT-R – cognitive architecture for modeling human cognition and developing cognitive agents. CLARION – Connectionist Learning with Adaptive Rule Induction On-line, hybrid connectionist/symbolic cognitive architecture. OpenCog – project that aims to build an open source artificial intelligence framework Soar – cognitive architecture for decision-making and learning in intelligent agents
AForge.NET – computer vision, artificial intelligence, and robotics library for the .NET framework Dlib – C++ library for computer vision and image processing OpenCV — library of programming functions mainly for real-time computer vision Point Cloud Library – library for point cloud processing Tesseract – optical character recognition
BigDL – distributed deep learning library for Apache Spark Caffe – deep learning framework focused on speed and modularity Deeplearning4j – Java library for deep learning algorithms on the Java virtual machine DeepSpeed – deep learning optimization library developed by Microsoft fastai – deep learning library built on top of PyTorch Fast Artificial Neural Network (FANN) – C library for feedforward neural networks Horovod – distributed deep learning framework for TensorFlow, Keras, and PyTorch Hugging Face Transformers — open-source deep learning library developed by Hugging Face Keras – Python library for artificial neural networks Microsoft Cognitive Toolkit – deep learning framework developed by Microsoft Research MXNet – deep learning framework for training and deploying deep neural networks Neuroph – object-oriented artificial neural network framework written in Java OpenNN – artificial neural network library written in C++ PlaidML – deep learning backend for neural networks and tensor computations PyTorch – deep learning framework developed by Meta AI PyTorch Lightning – high-level framework built on top of PyTorch for organizing and scaling deep learning models TensorFlow – end-to-end open-source platform for machine learning and deep learning developed by Google Brain Torch – scientific computing framework with support for machine learning and deep learning algorithms
Accord.NET — C# framework for machine learning, statistics, computer vision, and signal processing Apache Mahout — scalable machine learning library for big data built on Hadoop and Spark Apache SINGA — distributed deep learning and machine learning software Apache SystemDS — ML system for the end-to-end data science lifecycle CatBoost — machine learning library for gradient boosting on decision trees Caffe — Image classification and image segmentation Dlib — C++ machine learning and computer vision library ELKI — data mining and unsupervised learning software fastText — Word embeddings developed by Meta AI Flux — machine learning library for the Julia programming language Gensim — topic modelling and vector space model toolkit JAX — machine learning library for numerical computing and automatic differentiation H2O — machine learning and predictive analytics platform Infer.NET — probabilistic programming framework for Bayesian inference Jubatus — online machine learning and distributed computing framework KNIME — modular data pipelining LIBSVM — library for support vector machines LightGBM — machine learning framework for gradient boosting Massive Online Analysis — framework for machine learning and data mining on evolving data streams Microsoft Cognitive Toolkit — deep learning framework developed by Microsoft Research MindSpore — machine learning and deep learning framework ML.NET — machine learning framework for .NET mlpack — C++ header-only machine learning library MLX — machine learning framework for Apple silicon supporting model training, inference, and fine-tuning MXNet — deep learning framework Orange — machine learning, data mining, data visualization, and data analysis PyMC — Python framework for Bayesian modeling and probabilistic programming Scikit-learn — library built on top of NumPy, SciPy, and matplotlib Scikit-multiflow — Python framework for online and stream machine learning Shogun — C++ library for large-scale machine learning Spark MLlib — machine learning library for Apache Spark TensorFlow — machine learning and deep learning platform Theano — numerical computation library for machine learning Vowpal Wabbit — machine learning system for fast online learning Weka — collection of machine learning algorithms for data mining tasks XGBoost — machine learning library for gradient boosting
TPOT – tree-based pipeline optimization tool using genetic programming Neural Network Intelligence – Microsoft toolkit for hyperparameter tuning and neural architecture search MindsDB – AutoML platform that embeds machine learning into SQL databases and applications
Apertus – Swiss National AI Initiative LLM BERT – Google LLM BLOOM – BigScience multilingual LLM Cerebras-GPT – Cerebras Systems LLMs DeepSeek – R1 and V3 models Gemma 4 – Google LLM GLM-4.5 and later versions – Z.ai LLMs GPT-1, GPT-2, and GPT-OSS – OpenAI LLMs GPT-J, GPT-Neo, and GPT-NeoX – EleutherAI LLMs Hy – Tencent open-weight LLM Granite – IBM LLMs Grok-1 – xAI LLM Inkling – Thinking Machines Kimi (some versions) – Moonshot AI LLMs MiMo (some versions) – Xiaomi LLMs Mistral (some versions) Muse Glimmer — Meta Superintelligence Labs LLM Nemotron 3 – Nvidia open-weight models OLMo – Allen Institute for AI LLM Phi – Microsoft LLMs Qwen (some versions) – Alibaba Cloud LLMs Sarvam-M, Sarvam-105B and Sarvam-30B – Sarvam AI LLMs SmolLM – Hugging Face small language models (SLMs) Step-3.7Flash – StepFun LLM T5 – Google LLM XLNet – Google LLM
Apache OpenNLP Apertium – rule-based machine translation platform. ChatScript – natural language engine and dialog management system General Architecture for Text Engineering – information extraction Gensim – topic modeling and document similarity analysis library GloVe – unsupervised learning algorithm for obtaining vector representations of words Mallet – Java "Machine Learning for Language Toolkit" MontyLingua – libraries and programs for symbolic and statistical NLP for both Python and Java Moses – statistical machine translation engine to train statistical models of text from a source language to a target language NiuTrans – statistical machine translation NLTK – natural Language toolkit for symbolic and statistical NLP Probabilistic Action Cores – interpreter for natural-language instructions for robotic applications spaCy – Python library Spark NLP – text processing library for advanced NLP for Python, Java, and Scala. Word2vec – obtaining vector representations of words
GOLOG – logic programming language, situation calculus, first-order logical language for reasoning about action and change.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
AlphaTensor – DeepMind reinforcement-learning system for discovering efficient matrix multiplication algorithms
ConceptNet – multilingual commonsense knowledge graph used in natural-language processing and artificial-intelligence applications. DBpedia – project that extracts structured knowledge from Wikipedia using an open-source extraction framework.
Open-source artificial intelligence List of artificial intelligence algorithms List of artificial intelligence journals and List of artificial intelligence books List of artificial intelligence projects List of free and open-source software packages for artificial intelligence List of proprietary artificial intelligence software Open weights Common Crawl – nonprofit that crawls the web and freely provides its archives and datasets to the public under an MIT License Google Colab – an O-IDE Jupyter notebook environment with free access to GPUs and TPUs for machine learning and deep learning development Applications of artificial intelligence
This repository is a collection of fine-tuning experiments on various LLMs using the LoRA (Low-Rank Adaptation) technique, which optimizes model training for resource efficiency. Each project targets a unique application of LLMs, from instruction-based interactions to general-purpose conversational agents. Projects Overview Project 1: Falcon-7B Instruct with LoRA Fine-Tuning Description: Fine-tunes the Falcon-7B model for specific instruction-based queries using LoRA and Gradio for interaction. Project 2: SmolLM2 Prompt Generation Description: Fine-tunes SmolLM2-1.7B model for prompt-based text generation using OpenWebText. Project 3: Llama-2-7B Chat Fine-Tuning for Domain-Specific Tasks Description: Adapts the Llama-2-7B chat model for domain-specific text generation with OpenWebText as a base dataset. Project 4: FLAN-T5 Instructional Fine-Tuning Description: Fine-tunes FLAN-T5-XL for instruction-following using Databricks Dolly-15k, optimized for memory efficiency. Project 5: FLAN-T5 Targeted Instruction Fine-Tuning Description: This project targets instructional response accuracy for FLAN-T5-XL on Databricks Dolly-15k with LoRA for memory efficiency.
This repository is a collection of fine-tuning experiments on various LLMs using the LoRA (Low-Rank Adaptation) technique, which optimizes model training for resource efficiency. Each project targets a unique application of LLMs, from instruction-based interactions to general-purpose conversational agents.
Project 1: Falcon-7B Instruct with LoRA Fine-Tuning Description: Fine-tunes the Falcon-7B model for specific instruction-based queries using LoRA and Gradio for interaction.
Project 2: SmolLM2 Prompt Generation Description: Fine-tunes SmolLM2-1.7B model for prompt-based text generation using OpenWebText.
Project 3: Llama-2-7B Chat Fine-Tuning for Domain-Specific Tasks Description: Adapts the Llama-2-7B chat model for domain-specific text generation with OpenWebText as a base dataset.
Project 4: FLAN-T5 Instructional Fine-Tuning Description: Fine-tunes FLAN-T5-XL for instruction-following using Databricks Dolly-15k, optimized for memory efficiency.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Project 5: FLAN-T5 Targeted Instruction Fine-Tuning Description: This project targets instructional response accuracy for FLAN-T5-XL on Databricks Dolly-15k with LoRA for memory efficiency.
This repository contains fine-tuning experiments with various Large Language Models using the LoRA technique. Each project is focused on enhancing specific aspects of text generation and understanding using different LLM architectures and datasets, from conversational AI to instruction-based language models.
@miwojc Don't forget to set the max_steps parameter to -1, or it will override num_train_epochs .
@younesbelkada Very quick fix: the num_train_epochs and weight_decay are not used in TrainingArguments() .
A request, the python script does not train from the last checkpoint when the finetuning is done and the weights are merged. Any follow up training will overwrite the current checkpoint folders. Please allow for finetuning from the latest checkpoint.
### Human: write an email from John Doe using the provided inputs ### Inputs: [Name]: Mary Watson [Topics]: Congratulations on your new job [Tones]: Friendly [Urgency]: 1 ### Assistant: [Subject]: Congratulations Mary! [Body]: long email text...
I've fine-tuned llama2-7b-hf using this script but when I load it and try to use it, it doesn't output the [Subject]+[Body] format stated in my dataset, and the structure and language of the emails are very different. It looks like it's just following instructions like the regular model would do. Is there any hyperparameter I should tune? My dataset has about 1k examples.
@younesbelkada I can confirm that changing the datatype to bf16 and running training on RTX4090 not in Google collab fixed all of my issues.
If I execute python finetunellama2.py I get RuntimeError: mat1 and mat2 shapes cannot be multiplied (2048x4096 and 1x8388608)
5. Training Protocol, Convergence Behavior & Experimental Evaluation
edit: upgrading bitsandbytes to 0.40.2 and peft to 0.4.0 seems to have fixed this somehow.
Hey @abhijithnair1 , I have also the dataset in the same format, like instruction, question, and answer. So how do you resolve this problem? Can anyone know how to resolve this.?
@kw2828 Do I have to use the prompt provided in the "guanaco" dataset (i.e., ### Human or ### Assistance)?
Let's say if I use the base model name as "meta-llama/Llama-2-7b-hf" and then use a prompt something like alpaca dataset would it still work? Do I need to make any changes? Can someone provide some explanation here.
""" Use the below context to answer the question at the end accurately. ### Context: {context} ### Question: {question} ### Answer: {answer} """
Just a side note: the default learning rate could be perhaps lower. In Meta official demo , they go as low as 2e-5.
Hi, I am using 2 T4 GPUs on Kaggle for fine-tuning sharded Llama 2 model with 4-bit quantization, but still running into CUDA Out of memory issues, any fix other than upgrading the GPU? Tried varying with different batch sizes and gradients over steps.
I did that but it gives this error: ValueError: No valid checkpoint found in output directory
This error occurs both when the model is finetuned for the first time, or when there are already checkpoint folders in the directory, from earlier finetune process (but where the code was using trainer.train() ).
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)