Complete Technical Paper Content — Lora Qlora Fine Tuning
1. Executive Abstract, Problem Formulation & Background
LoRA (Low-Rank Adaptation) is a parameter-efficient fine-tuning technique for large language models and other deep neural networks. Introduced in 2021 by researchers at Microsoft, LoRA enables adaptation of pre-trained models to specific tasks while requiring significantly fewer computational resources and trainable parameters than traditional full model fine-tuning.
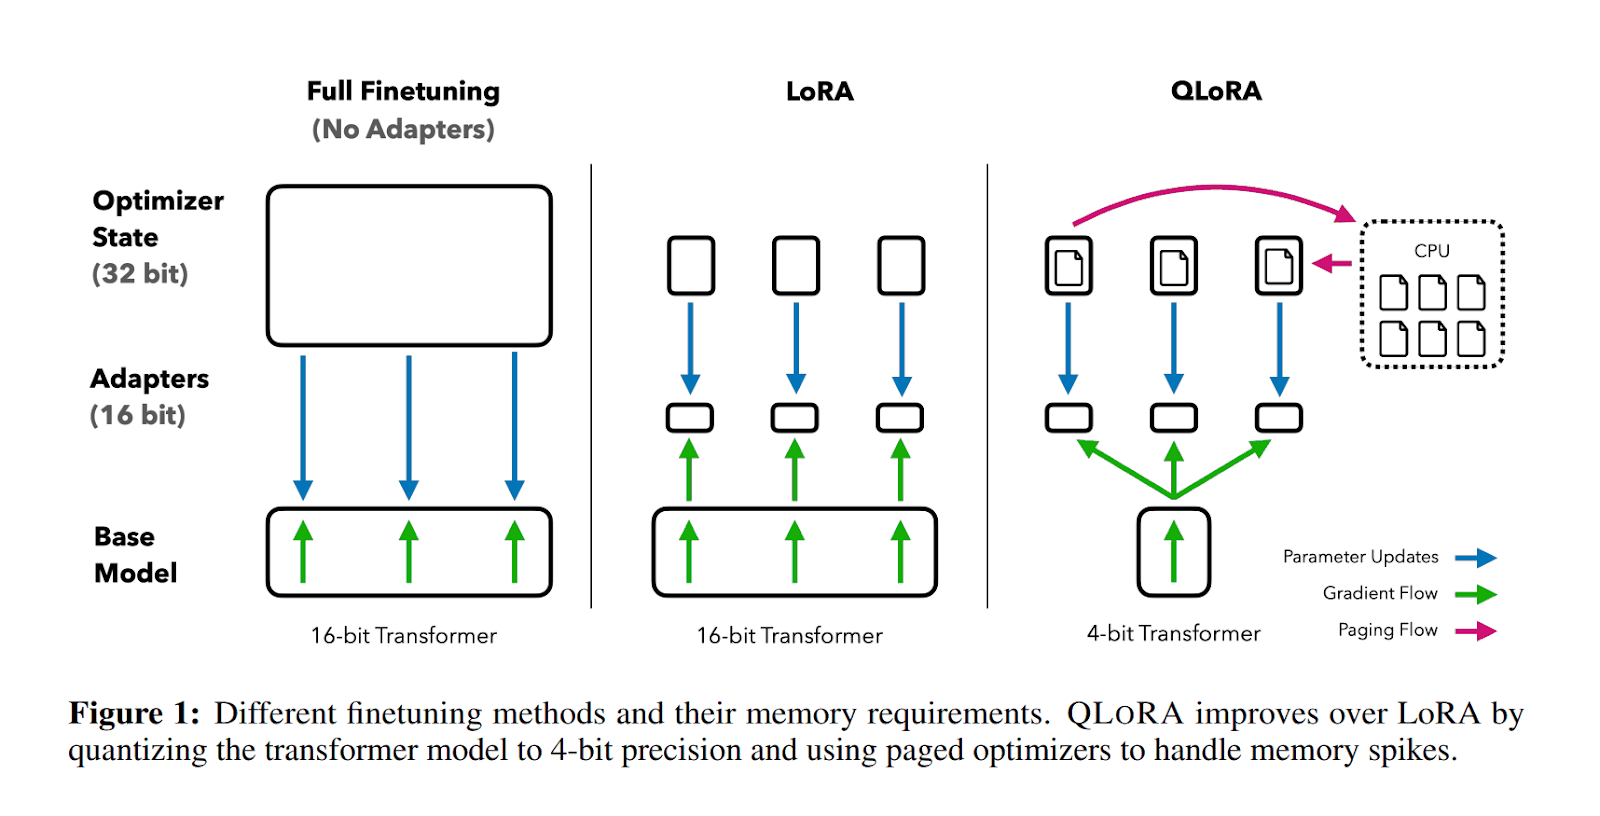
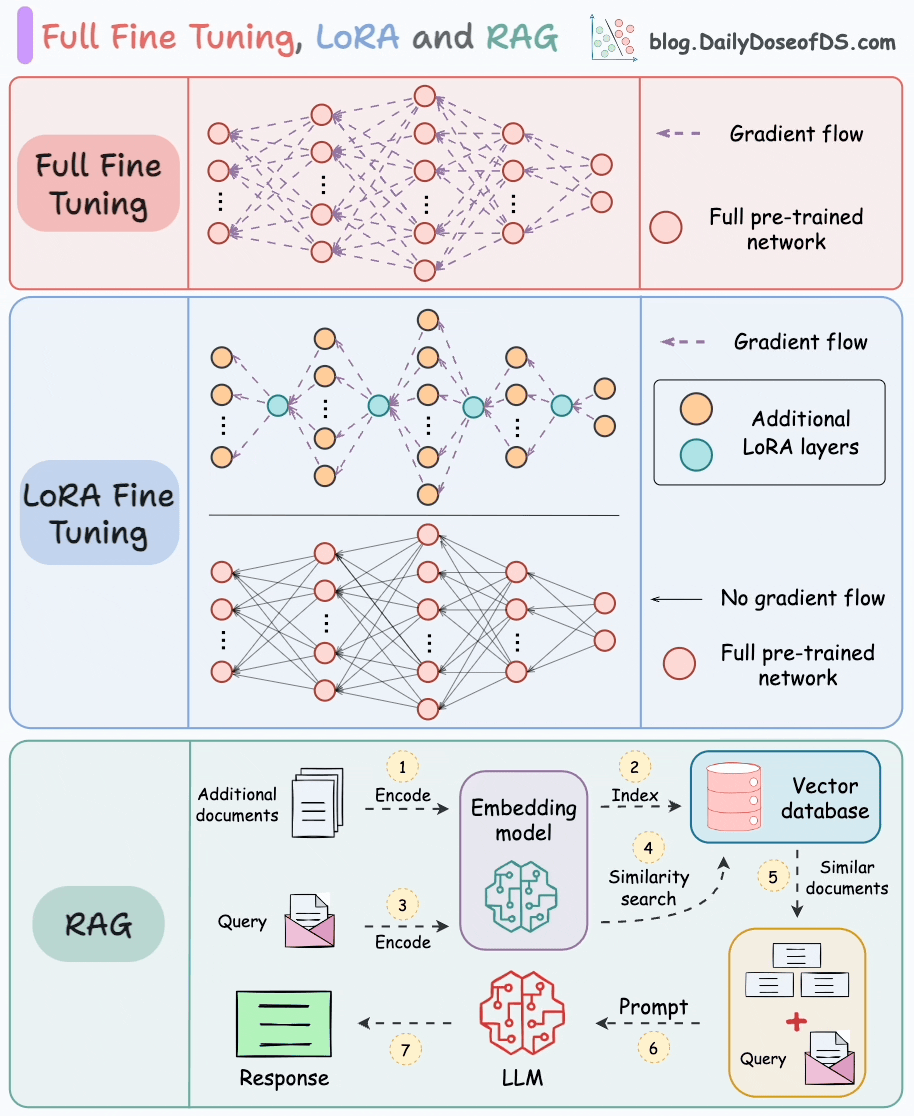
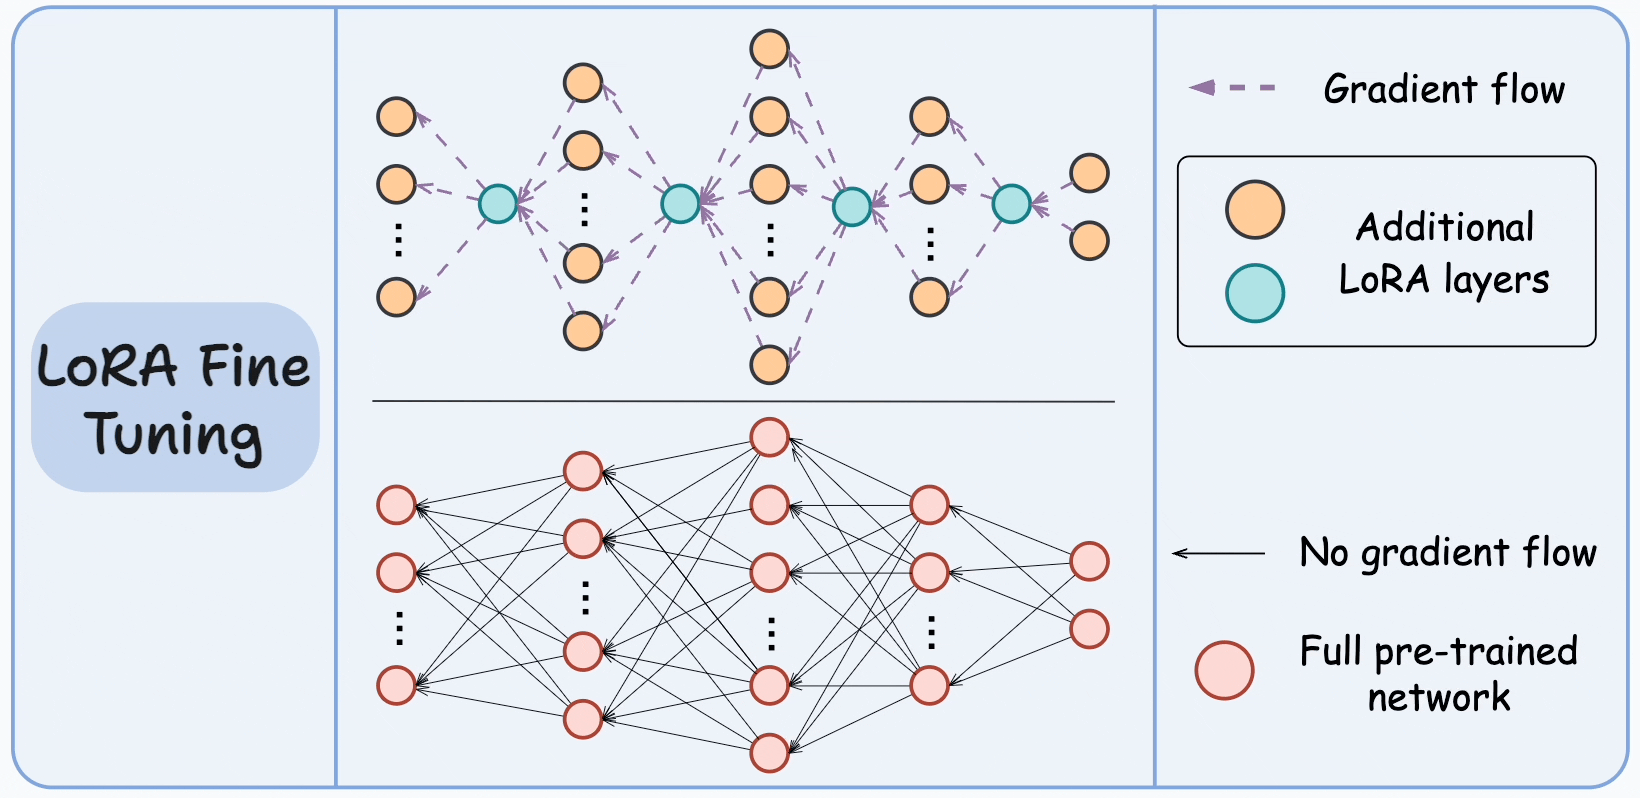
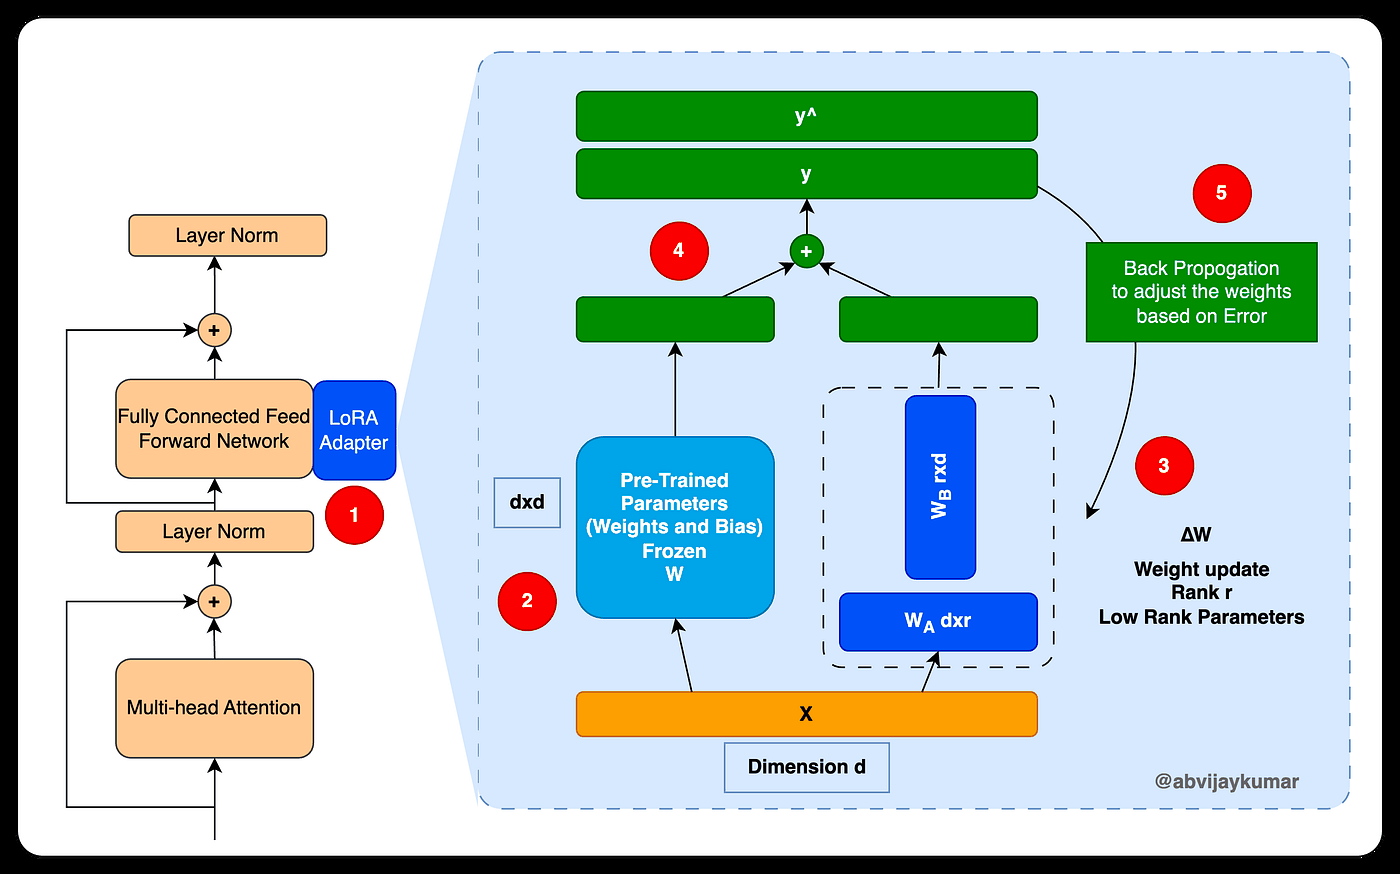
Rather than updating all parameters in a neural network during fine-tuning, LoRA freezes the pre-trained model weights and injects trainable rank decomposition matrices into each layer of the Transformer architecture. This approach is grounded in linear algebra and exploits the hypothesis that weight updates during fine-tuning have low "intrinsic rank," meaning the changes can be effectively represented with fewer parameters than the full weight matrix. When applied to GPT-3, LoRA reduced trainable parameters by approximately 10,000 times (from 175 billion to roughly 18 million) and GPU memory requirements during training by 3 times (from 1.2 terabytes to 350 gigabytes). The technique applies broadly to any dense layers in deep learning models, though it has been most extensively studied in the context of large language models. After training, LoRA adapter weights can be merged with the base model weights, resulting in no additional inference latency during deployment. LoRA has been widely adopted in post-training workflows, including integration with preference optimization methods such as direct preference optimization (DPO). Its parameter-efficient variations, such as QLoRA, enable fine-tuning of 30-billion-parameter models on a single 24 GB consumer GPU.
A large language model (LLM) is a machine learning model (typically a neural network) trained on a vast amount of text for natural language processing tasks, especially language generation. LLMs can typically generate, summarize, translate, and analyze text in many contexts. They are the basis for many modern chatbots, such as ChatGPT, Claude, Gemini, Grok, Qwen and DeepSeek. LLMs are typically based on the transformer neural network architecture. Generative pre-trained transformers (GPTs) are a type of LLM that is pre-trained to predict the next word. GPTs are then often fine-tuned to follow instructions and to behave as assistants. Biased or inaccurate training data can make an LLM's output less reliable. A software harness can provide LLMs with memory and access to tools such as web search. Benchmark evaluations for LLMs attempt to measure model reasoning, factual accuracy, alignment, and safety.
Before the emergence of transformer-based models in 2017, some language models were considered large relative to the computational and data constraints of their time. In the early 1990s, IBM's statistical models pioneered word alignment techniques for machine translation, laying the groundwork for corpus-based language modeling. In 2001, a smoothed n-gram model, such as those employing Kneser–Ney smoothing, trained on 300 million words, achieved state-of-the-art perplexity on benchmark tests. During the 2000s, with the rise of widespread internet access, researchers began compiling massive text datasets from the web ("web as corpus") to train statistical language models.
Moving beyond n-gram models, researchers started in 2000 to use neural networks as language models. Following the breakthrough of deep neural networks in image classification around 2012, similar architectures were adapted for language tasks. This shift was marked by the development of word embeddings (e.g., Word2Vec by Mikolov in 2013) and sequence-to-sequence (seq2seq) models using LSTM. In 2016, Google transitioned its translation service to neural machine translation (NMT), replacing statistical phrase-based models with deep recurrent neural networks. These early NMT systems used LSTM-based encoder-decoder architectures, as they preceded the invention of transformers. At the 2017 NeurIPS conference, Google researchers introduced the transformer architecture in their landmark paper "Attention Is All You Need". This paper's goal was to improve upon 2014 seq2seq technology, and was based mainly on the attention mechanism developed by Bahdanau et al. in 2014. The following year in 2018, BERT was introduced and quickly became "ubiquitous". Though the original transformer has both encoder and decoder blocks, BERT is an encoder-only model. Academic and research usage of BERT began to decline in 2023, following rapid improvements in the abilities of decoder-only models (such as GPT) to solve tasks via prompting. Although decoder-only GPT-1 was introduced in 2018, it was GPT-2 in 2019 that caught widespread attention because OpenAI claimed to have initially deemed it too powerful to release publicly, out of fear of malicious use. GPT-3 in 2020 went a step further and as of 2025 is available only via API with no offering of downloading the model to execute locally. But it was the consumer-facing chatbot ChatGPT in late 2022 that received extensive media coverage and public attention by 2023. The 2023 GPT-4 was praised for its increased accuracy and as a "holy grail" for its multimodal capabilities. OpenAI did not reveal the high-level architecture and the number of parameters of GPT-4. The release of ChatGPT led to an uptick in LLM usage across several research subfields of computer science, including robotics, software engineering, and societal impact work. In 2024, OpenAI released the reasoning model OpenAI o1, which generates long chains of thought before returning a final answer. Many LLMs with parameter counts comparable to those of OpenAI's GPT series have been developed. Since 2022, open-source models (those with their source code and weights made publicly available) have been gaining popularity, especially at first with BLOOM and LLaMA, though both have restrictions on the field of use. Mistral AI's open-weight models Mistral 7B and Mixtral 8x7B have a more permissive Apache License. In January 2025, DeepSeek released DeepSeek R1, a 671-billion-parameter open-weight model that performs comparably to OpenAI o1 but at a much lower price per token for users. Since 2023, many LLMs have been trained to be multimodal, having the ability to also process or generate other types of data, such as images, audio, or 3D meshes. Open-weight LLMs have become more influential since 2023. Per Vake et al. (2025), community-driven contributions to open-weight models improve their efficiency and performance via collaborative platforms such as Hugging Face.
Model family name. For example: Llama, Kimi, GPT, Gemma. Some models are derived from a more famous model family. These may be named somewhat idiosyncratically. For example, the Alpaca series was named so because they were derived from the Llama series. Version number. If the model family has several releases, a version number may be added. Like software versioning, it can have several parts (semantic versioning). For example, in DeepSeek-V4.1-Flash-1017, "DeepSeek" is the model family name, "Flash" is the relative size, "V4" is the major version number, ".1" is the minor version number, and "1017" is a patch version number meaning "released on 2026-10-17". Training stage: A model released straight out of pretraining is marked "Base". A model finetuned to follow instructions is marked "Instruct", "Chat", or "it" (instruction-tuned). A model finetuned generically is marked "SFT". Similarly for "RLHF" (reinforcement learning from human feedback) or "DPO" (direct preference optimization). For example, Mistral-7B-Instruct-v0.2, Llama-2-7b-chat, Gemma-2-9b-it. Parameter count. This is usually written as nM (n-million), nB (n-billion), or nT (n-trillion). For mixture-of-expert models, there is an optional count for active parameters. For example, "GLM-5.3-Flash (320B-A18B)" is a model with 320 billion parameters, of which 18 billion are active per forward pass. Relative size. When the members of a model family are not named by their precise parameter counts, their relative sizes might still be named. A commonly used series: Tiny, Small, Base, Big, Large, Huge. For example, the original BERT series included "Tiny", "Base", and "Large". Proprietary model families may use idiosyncratic names for the relative sizes for branding purposes, such as Haiku/Sonnet/Opus (from the Claude series), and Terra/Luna/Sol (from the GPT series). Context length. A language model may be trained specifically for contexts up to a certain length. This context length upper bound can be named as nK (n-thousand, or n times 1024) or nM (n-million, or n times 1048576). For example, "Yarn-Llama-2-13b-128k" is Llama 2 13B extended to a 128K-token context with YaRN. In "Qwen2.5-7B-Instruct-1M", the "1M" counts tokens of context, not parameters. More coarsely, it can be named "long" to indicate the mere fact that the context length has been extended. Reasoning level. A reasoning language model may be trained specifically for certain levels of reasoning efforts. A commonly used series: none, minimal, low, medium, high, xhigh, max. The mere fact that a model is a reasoning language model can be marked by "Thinking", such as in Kimi-K2-Thinking. Domain or modality. A model may be specialized for specific applications or has certain input modalities. in its name. Common tags are Code, Coder (for programming), Math, VL (vision-language). For example, Code Llama, Qwen2.5-Coder-32B-Instruct, Qwen2.5-VL-7B-Instruct, CodeLlama-7b-hf. Release stage. "Preview" or "Exp" (experimental) marks a model released ahead of a stable version. For example, DeepSeek-V3.2-Exp. Downstream finetuning. LoRA (low-rank adaptation), QLoRA (quantized LoRA), distill (distilled from another model), uncensored (fewer refusal behaviors), merged (multiple finetuned weights merged into one weight). Weight format. The weights of a model can be stored in different formats. Examples include onnx (Open Neural Network Exchange), hf (Hugging Face transformers). The quantization level can be indicated by suffix such as FP8, AWQ, GGUF. For example, Qwen3-32B-AWQ is Qwen3-32B with its weights quantized to 4 bits by AWQ. See GGUF for examples.
2. Related Work, Literature Survey & Algorithmic Foundations
Tokenization also compresses the datasets. Because LLMs generally require input to be an array that is not jagged, the shorter texts must be "padded" until they match the length of the longest one.
As an example, consider a tokenizer based on byte-pair encoding. In the first step, all unique characters (including blanks and punctuation marks) are treated as an initial set of n-grams (i.e. initial set of uni-grams). Successively the most frequent pair of adjacent characters is merged into a bi-gram and all instances of the pair are replaced by it. All occurrences of adjacent pairs of (previously merged) n-grams that most frequently occur together are then again merged into even lengthier n-gram, until a vocabulary of prescribed size is obtained. After a tokenizer is trained, any text can be tokenized by it, as long as it does not contain characters not appearing in the initial-set of uni-grams.
In the context of training LLMs, datasets are typically cleaned by removing low-quality, duplicated, or toxic data. Cleaned datasets can increase training efficiency and lead to improved downstream performance. A trained LLM can be used to clean datasets for training a further LLM. With the increasing proportion of LLM-generated content on the web, data cleaning in the future may include filtering out such content. LLM-generated content can pose a problem if the content is similar to human text (making filtering difficult) but of lower quality (degrading performance of models trained on it).
Training of largest language models might need more linguistic data than naturally available, or that the naturally occurring data is of insufficient quality. In these cases, synthetic data might be used.
An LLM is a type of foundation model trained on language. LLMs can be trained in different ways. In particular, GPT models are first pretrained to predict the next word on a large amount of data, before being fine-tuned.
Substantial infrastructure is necessary for training the largest models. The tendency towards larger models is visible in the list of large language models. For example, the training of GPT-2 (i.e. a 1.5-billion-parameter model) in 2019 cost $50,000, while training of the PaLM (i.e. a 540-billion-parameter model) in 2022 cost $8 million, and Megatron-Turing NLG 530B (in 2021) cost around $11 million. The qualifier "large" in "large language model" is inherently vague, as there is no definitive threshold for the number of parameters required to qualify as "large".
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Inference is the process of providing input to a trained large language model and receiving generated output, such as text, images, code, or other files. Hosted inference runs a language model on remote AI data centers and makes the output available to users over the Internet. Some open-weight language models can be downloaded and run locally on a personal computer. The model files are stored on local storage, while during inference the model weights and other data are held in memory for processing.
In order to find out which tokens are relevant to each other within the scope of the context window, the attention mechanism calculates "soft" weights for each token, more precisely for its embedding, by using multiple attention heads, each with its own "relevance" for calculating its own soft weights. For example, the small (i.e. 117M parameter sized) GPT-2 model has had twelve attention heads and a context window of only 1k tokens. Autoregressive models, such as GPTs, are trained to guess how a sequence continues; for example, whether the word sequence "I like to eat" is more likely to be followed by the word "bread" or the word "rocks". Masked models, such as BERT, are trained to guess parts that are missing from a sequence, such as whether the missing word in "I like to ___ roses" is more likely to be the word "smell" or the word "eat". The model's predictions are based on the properties of sequences within its training dataset.
A mixture of experts (MoE) is a machine learning architecture in which multiple specialized neural networks ("experts") work together, with a gating mechanism that routes each input to the most appropriate expert(s). Mixtures of experts can reduce inference costs, as only a fraction of the parameters are used for each input.
Typically, LLMs are trained with single or half-precision floating point numbers (float32 and float16). One float16 has 16 bits, or 2 bytes, and so one billion parameters require 2 gigabytes. The largest models typically have more than 100 billion parameters, which places them outside the range of most consumer electronics. In 2021, Google Brain released Switch Transformer, one of the first natural language processing (NLP) models to cross one trillion parameters. As of July 2026, the largest open weight frontier model is Kimi K3, developed by Moonshot AI, at 2.8 trillion parameters. According to industry estimates reported by the Financial Times, Anthropic's Claude Mythos, its most powerful model, restricted from public access, has approximately 8 trillion parameters, while its public 'Mythos-class' model Fable 5 has approximately 5 trillion parameters.
In 2020, OpenAI researchers demonstrated that their new model GPT-3 could understand what format to use given a few rounds of Q and A (or other type of task) in the input data as example. This technique, called few-shot prompting, allows LLMs to be adapted to any task without requiring fine-tuning. Also in 2022, it was found that the base GPT-3 model can generate an instruction based on user input. The generated instruction along with user input is then used as input to another instance of the model under a "Instruction: [...], Input: [...], Output:" format. The other instance is able to complete the output and often produces the correct answer in doing so. The ability to "self-instruct" makes LLMs able to bootstrap themselves toward a correct answer.
Tool use is a mechanism that enables LLMs to interact with external systems, applications, or data sources. It can allow LLMs to, for example, fetch real-time information from an API or to execute code. A program separate from the LLM watches the output stream of the LLM for a special tool-calling syntax. When these special tokens appear, the program calls the tool accordingly and feeds its output back into the LLM's input stream. Early tool-using LLMs were fine-tuned on the use of specific tools. But fine-tuning LLMs for the ability to read API documentation and call APIs correctly has greatly expanded the range of tools accessible to an LLM.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
An LLM is typically not an autonomous agent by itself, as it lacks the ability to interact with dynamic environments, recall past behaviors, and plan future actions. But it can be transformed into an agent by adding supporting elements: the role (profile) and the surrounding environment of an agent can be additional inputs to the LLM, while memory can be integrated as a tool or provided as additional input. Instructions and input patterns are used to make the LLM plan actions and tool use is used to potentially carry out these actions. In the DEPS ("describe, explain, plan and select") method, an LLM is first connected to the visual world via image descriptions. It is then prompted to produce plans for complex tasks and behaviors based on its pretrained knowledge and the environmental feedback it receives. The Reflexion method constructs an agent that learns over multiple episodes. At the end of each episode, the LLM is given the record of the episode, and prompted to think up "lessons learned", which would help it perform better at a subsequent episode. These "lessons learned" are stored as a form of long-term memory and given to the agent in the subsequent episodes. Monte Carlo tree search can use an LLM as rollout heuristic. When a programmatic world model is not available, an LLM can also be prompted with a description of the environment to act as world model. Multiple agents with memory can interact socially.
In late 2024, a new approach to LLM development emerged with "reasoning models". These are trained to generate step-by-step analysis before producing final answers, enabling better results on complex tasks, for instance in mathematics, coding and logic. OpenAI introduced this concept with their o1 model in September 2024, followed by o3 in April 2025. On the International Mathematics Olympiad qualifying exam problems, GPT-4o achieved 13% accuracy while o1 reached 83%. In January 2025, the Chinese company DeepSeek released DeepSeek-R1, a 671-billion-parameter open-weight reasoning model that achieved comparable performance to OpenAI's o1 while being significantly more cost-effective to operate. Unlike proprietary models from OpenAI, DeepSeek-R1's open-weight nature allowed researchers to study and build upon the algorithm, though its training data remained private. These reasoning models typically require more computational resources per query compared to traditional LLMs, as they perform more extensive processing to work through problems step by step.
Multimodality means having multiple modalities, where a "modality" refers to a type of input or output, such as video, image, audio, text, proprioception, etc. For example, Google PaLM model was fine-tuned into a multimodal model and applied to robotic control. LLaMA models have also been turned multimodal using the tokenization method, to allow image inputs, and video inputs. GPT-4o can process and generate text, audio and images. A common method to create multimodal models out of an LLM is to "tokenize" the output of a trained encoder. Concretely, one can construct an LLM that can understand images as follows: take a trained LLM, and take a trained image encoder E {\displaystyle E} . Make a small multilayer perceptron f {\displaystyle f} , so that for any image y {\displaystyle y} , the post-processed vector f ( E ( y ) ) {\displaystyle f(E(y))} has the same dimensions as an encoded token. That is an "image token". Then, one can interleave text tokens and image tokens. The compound model is then fine-tuned on an image-text dataset. This basic construction can be applied with more sophistication to improve the model. The image encoder may be frozen to improve stability. This type of method, where embeddings from multiple modalities are fused and the predictor is trained on the combined embeddings, is called early fusion. Another method, called intermediate fusion, involves each modality being first processed independently to obtain modality-specific representations; then these intermediate representations are fused together. In general, cross-attention is used for integrating information from different modalities. As an example, the Flamingo model uses cross-attention layers to inject visual information into its pre-trained language model.
C {\displaystyle C} : cost of pretraining (the total amount of compute used),
N {\displaystyle N} : size of the artificial neural network itself, such as number of parameters (i.e. amount of neurons in its layers, amount of weights between them and biases),
D {\displaystyle D} : size of its pretraining dataset (i.e. number of tokens in corpus). Scaling laws are empirical statistical laws that predict LLM performance based on such factors. One particular scaling law ("Chinchilla scaling") for LLM autoregressively trained for one epoch, with a log–log learning rate schedule, states that:
5. Training Protocol, Convergence Behavior & Experimental Evaluation
{ C = C 0 N D L = A N α + B D β + L 0 {\displaystyle {\begin{cases}C=C_{0}ND\\[6pt]L={\frac {A}{N^{\alpha }}}+{\frac {B}{D^{\beta }}}+L_{0}\end{cases}}} where the variables are
L {\displaystyle L} is the average negative log-likelihood loss per token (nats/token), achieved by the trained LLM on the test dataset. and the statistical hyper-parameters are
C 0 = 6 {\displaystyle C_{0}=6} , meaning that it costs 6 FLOPs per parameter to train on one token. Note that training cost is much higher than inference cost, where it costs 1 to 2 FLOPs per parameter to infer on one token.
α = 0.34 , β = 0.28 , A = 406.4 , B = 410.7 , L 0 = 1.69 {\displaystyle \alpha =0.34,\beta =0.28,A=406.4,B=410.7,L_{0}=1.69}
Performance of bigger models on various tasks, when plotted on a log–log scale, appears as a linear extrapolation of performance achieved by smaller models. However, this linearity may be punctuated by "break(s)" in the scaling law, where the slope of the line changes abruptly, and where larger models acquire "emergent abilities". They arise from the complex interaction of the model's components and are not explicitly programmed or designed. Proposed examples of emergent abilities include:
reported arithmetics decoding the International Phonetic Alphabet unscrambling a word's letters disambiguating word-in-context datasets converting spatial words cardinal directions (for example, replying "northeast" in response to a 3x3 grid of 8 zeros and a 1 in the top-right), color terms represented in text. chain-of-thought prompting: In a 2022 research paper, chain-of-thought prompting only improved the performance for models that had at least 62B parameters. Smaller models perform better when prompted to answer immediately, without chain of thought. identifying offensive content in paragraphs of Hinglish (a combination of Hindi and English), and generating a similar English equivalent of Kiswahili proverbs. Schaeffer et al. argue that the emergent abilities are not unpredictably acquired, but predictably acquired according to a smooth scaling law. The authors considered a toy statistical model of an LLM solving multiple-choice questions, and showed that this statistical model, modified to account for other types of tasks, applies to these tasks as well. Let x {\displaystyle x} be the number of parameter count, and y {\displaystyle y} be the performance of the model.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)