Complete Technical Paper Content — Mobilenet Edge Ai
1. Executive Abstract, Problem Formulation & Background
Gemini, sometimes marketed as Google Gemini and originally known as Bard, is a generative artificial intelligence chatbot and virtual assistant developed by Google. It is powered by the family of large language models (LLMs) of the same name, previously based on LaMDA and PaLM 2. The Gemini chatbot can process and generate text, computer code, images, audio, and video simultaneously. Google distributes the technology via multiple platforms, ranging from smaller on-device versions ("Nano") and more affordable, high-throughput variants ("Flash") to high-compute models designed for complex tasks ("Pro" and "Ultra"). Gemini was first announced on December 6, 2023, as part of the company's response against the launch of OpenAI's ChatGPT, and replaced existing Google branding for AI services. In February 2024, the Bard chatbot was renamed Gemini, and the "Duet AI" branding for Google Cloud and Workspace was retired in favor of the Gemini identifier. The models are accessed via the Gemini mobile app on Android devices and through the Vertex AI platform for third-party developers. At launch, Gemini was criticized for unreliable outputs. In early 2024, Google suspended the model's ability to generate images of people after users reported historical inaccuracies and bias in its depictions of human subjects. Subsequent updates, including the Gemini 1.5 and 3 series released throughout 2025, attempted to reduce hallucinations, improve latency, and improve capabilities for research and software development.
In November 2022, OpenAI launched ChatGPT, a chatbot based on the GPT-3 family of large language models (LLMs). ChatGPT gained worldwide attention, becoming a viral Internet sensation. Alarmed by ChatGPT's potential threat to Google Search, Google executives issued a "code red" alert, reassigning several teams to assist in the company's artificial intelligence (AI) efforts. Sundar Pichai, the CEO of Google and parent company Alphabet, was widely reported to have issued the alert, but Pichai later denied this to The New York Times. In a rare move, Google co-founders Larry Page and Sergey Brin, who had stepped down from their roles as co-CEOs of Alphabet in 2019, attended emergency meetings with company executives to discuss Google's response to ChatGPT. Brin requested access to Google's code in February 2023, for the first time in years. Google had unveiled LaMDA, a prototype LLM, earlier in 2021, but it was not released to the public. When asked by employees at an all-hands meeting whether LaMDA was a missed opportunity for Google to compete with ChatGPT, Pichai and Google AI chief Jeff Dean said that while the company's chatbot had similar capabilities to ChatGPT, there were risks to introducing an LLM that might spread false information, so they decided to wait. In January 2023, Google Brain's sister company DeepMind CEO Demis Hassabis hinted at plans for a ChatGPT rival, and Google employees were instructed to accelerate progress on a ChatGPT competitor, intensively testing "Apprentice Bard" and other chatbots. Pichai assured investors during Google's quarterly earnings investor call in February that the company had plans to expand LaMDA's availability and applications.
Google opened up early access for Bard on March 21, 2023, in a limited capacity, allowing users in the US and the UK to join a waitlist. Unlike Microsoft's approach with Bing Chat, Bard was launched as a standalone web application featuring a text box and a disclaimer that the chatbot "may display inaccurate or offensive information that doesn't represent Google's views". Three responses are then provided to each question, with users prompted to submit feedback on the usefulness of each answer. Google vice presidents Sissie Hsiao and Eli Collins framed Bard as a complement to Google Search and stated that the company had not determined how to make the service profitable. Among those granted early access were those enrolled in Google's "Pixel Superfans" loyalty program, users of its Pixel and Nest devices, and Google One subscribers. Bard is trained by third-party contractors hired by Google, including Appen and Accenture workers, whom Business Insider and Bloomberg News reported were placed under extreme pressure, overworked, and underpaid. Bard is also trained on data from publicly available sources, which Google disclosed by amending its privacy policy. Shortly after Bard's initial launch, Google reorganized the team behind Google Assistant, the company's virtual assistant, to focus on Bard instead. Google researcher Jacob Devlin resigned from the company after claiming that Bard had surreptitiously leveraged data from ChatGPT; Google denied the allegations. Meanwhile, a senior software engineer at the company published an internal memo warning that Google was falling behind in the AI "arms race", not to OpenAI but to independent researchers in open-source communities. Pichai revealed on March 31 that the company intended to "upgrade" Bard by basing it on PaLM, a newer and more powerful LLM from Google, rather than LaMDA. The same day, Krawczyk announced that Google had added "math and logic capabilities" to Bard. Bard gained the ability to assist in coding in April, being compatible with more than 20 programming languages at launch. Microsoft also began running advertisements in the address bar of a developer build of the Edge browser, urging users to try Bing whenever they visit the Bard web app. 9to5Google reported that Google was working to integrate Bard into its ChromeOS operating system and Pixel devices.
On December 6, 2023, Google announced Gemini, a larger, multimodal LLM. A specially tuned version of the mid-tier Gemini Pro was integrated into Bard, while the larger Gemini Ultra was used for "Bard Advanced" in 2024. The Wall Street Journal reported that Bard was then averaging around 220 million monthly visitors. Google ended its contract with Appen in January 2024, while image generation was added to Bard the next month, using Google Brain's Imagen 2 text-to-image model. On February 8, 2024, Bard and Duet AI were unified under the Gemini brand, with a mobile app launched on Android and the service integrated into the Google app on iOS. On Android, users who downloaded the app saw Gemini replace Assistant as their device's default virtual assistant, though Assistant remained a standalone service. Google also launched "Gemini Advanced with Ultra 1.0", available via a "Google One AI Premium" subscription, incorporated Gemini into its Messages app on Android, and announced a partnership with Stack Overflow. Gemini again took center stage at the 2024 Google I/O keynote. Google announced that Gemini would be integrated into several products, including Android, Chrome, Photos, and Workspace. Gemini Advanced was upgraded to the "Gemini 1.5 Pro" language model, with Google previewing Gemini Live, a voice chat mode, and Gems, the ability to create custom chatbots.
Following the Gemini 1.0 launch in December 2023, Google released successive generations of the underlying model at an accelerating pace. In February 2024, Google introduced Gemini 1.5 Pro in a limited preview, notable for its one-million-token context window, which allowed it to process roughly an hour of video, 11 hours of audio, or 30,000 lines of code in a single prompt. Gemini 1.5 Flash, a faster and more cost-efficient variant aimed at developers, was announced at Google I/O in May 2024 alongside the expansion of Gemini Advanced. On December 11, 2024, Google announced Gemini 2.0 Flash as the first model in the Gemini 2.0 generation, framing it as the beginning of an "agentic era" in which AI models could take autonomous multi-step actions. Unlike previous Gemini models, 2.0 Flash supported native multimodal outputs, including generated images and text-to-speech audio, in addition to multimodal inputs. It also introduced Deep Research for Gemini Advanced users, enabling the model to autonomously browse and synthesize information across sources. Gemini 2.0 Flash became generally available on February 5, 2025, alongside release of Gemini 2.0 Pro and the budget-oriented Gemini 2.0 Flash-Lite. Gemini 2.5 Pro Experimental was released on March 25, 2025, as Google's first explicitly designated "thinking model", capable of reasoning through steps before responding using chain-of-thought techniques. It debuted at the top of the LMArena leaderboard, a benchmark measuring human preference for AI responses, where it remained for several months. Gemini 2.5 Flash was unveiled at Google I/O in May 2025 and reached general availability in June 2025 alongside the cost-optimized Gemini 2.5 Flash-Lite. On November 18, 2025, Google launched Gemini 3 Pro, describing it as its most intelligent model to date and marking a departure from the company's previous staged release patterns, with the model made immediately available across the Gemini app, Google Search, Google AI Studio, and Vertex AI on launch day. A more capable "Deep Think" reasoning mode began rolling out to Google AI Ultra subscribers in the weeks that followed. Gemini 3 Flash, a speed-optimized variant, followed in December 2025, becoming the new default model in the Gemini app. In February 2026, Google released a major upgrade to Gemini 3 Deep Think, which it described as targeting practical applications in science, research, and engineering. On February 19, 2026, Google launched Gemini 3.1 Pro in preview, characterizing it as a step forward in core reasoning. The model achieved an ARC-AGI-2 score of 77.1 percent, more than double that of Gemini 3 Pro, and 80.6 percent on SWE-bench Verified, a benchmark for autonomous software engineering tasks.
In February 2024, social media users reported that Gemini was generating images that featured people of color and women in historically inaccurate contexts—such as Vikings, Nazi soldiers, and the Founding Fathers—and refusing prompts to generate images of white people. These images were derided on social media, including by conservatives who cited them as evidence of Google's "wokeness". The business magnate Elon Musk, whose company xAI operates the chatbot Grok, was among those who criticized Google, denouncing its suite of products as biased and racist. Musk and other users targeted Jack Krawczyk, resurfacing his past comments discussing race, leading Krawczyk to withdraw from X and LinkedIn. The conservative-leaning tabloid New York Post ran a cover story on the incident in the print edition of its newspaper. In response, Krawczyk said that Google was "working to improve these kinds of depictions immediately", and Google paused Gemini's ability to generate images of people. Raghavan released a lengthy statement addressing the controversy, explaining that Gemini had "overcompensate[d]" amid its efforts to strive for diversity and acknowledging that the images were "embarrassing and wrong". In an internal memo to employees, Pichai called the debacle offensive and unacceptable, promising structural and technical changes. Several employees in Google's trust and safety team were laid off days later. Hassabis stated that Gemini's ability to generate images of people would be restored within two weeks; it was ultimately relaunched in late August, powered by its new Imagen 3 model. The market reacted negatively, with Google's stock falling by 4.4 percent. Pichai faced growing calls to resign, including from technology analysts Ben Thompson and Om Malik. House Republicans led by Jim Jordan subpoenaed Google, accusing the company of colluding with the Biden administration to censor speech. In light of the fiasco and Google's overall response to OpenAI, Business Insider's Hugh Langley and Lara O'Reilly declared that Google was fast going "from vanguard to dinosaur". Bloomberg columnist Parmy Olson suggested that Google's "rushed" rollout of Gemini was the cause of its woes, not "wokeness". Martin Peers, writing for The Information, opined that Google needed a leader like Mark Zuckerberg to defuse the situation. Hugging Face scientist Sasha Luccioni and Surrey University professor Alan Woodward believed that the incident had "deeply embedded" roots in Gemini's training corpus and algorithms, making it difficult to rectify. Jeremy Kahn of Fortune called for researchers focused on safety and responsibility to work together to develop better guardrails. New York magazine contributor John Herrman wrote: "It's a spectacular unforced error, a slapstick rake-in-the-face moment, and a testament to how panicked Google must be by the rise of OpenAI and the threat of AI to its search business."
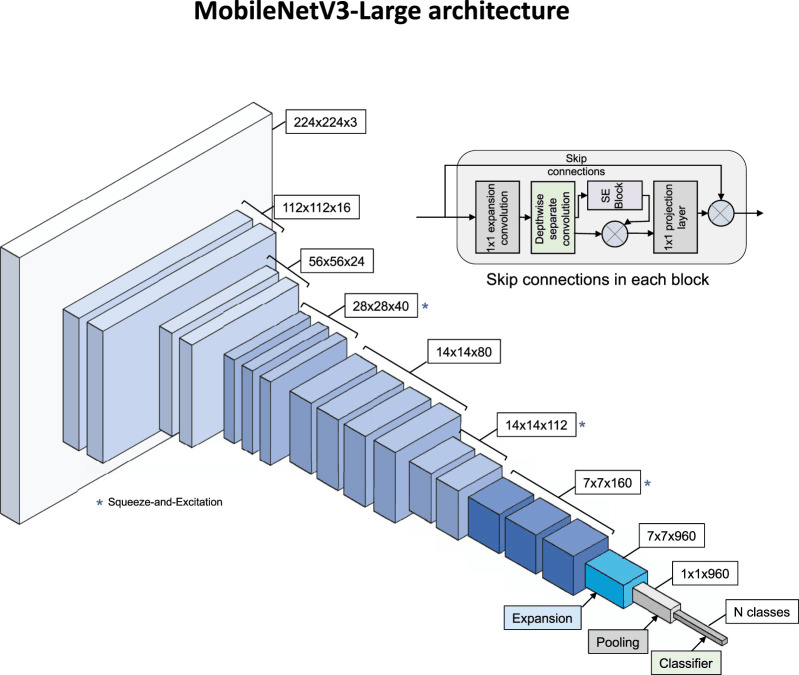
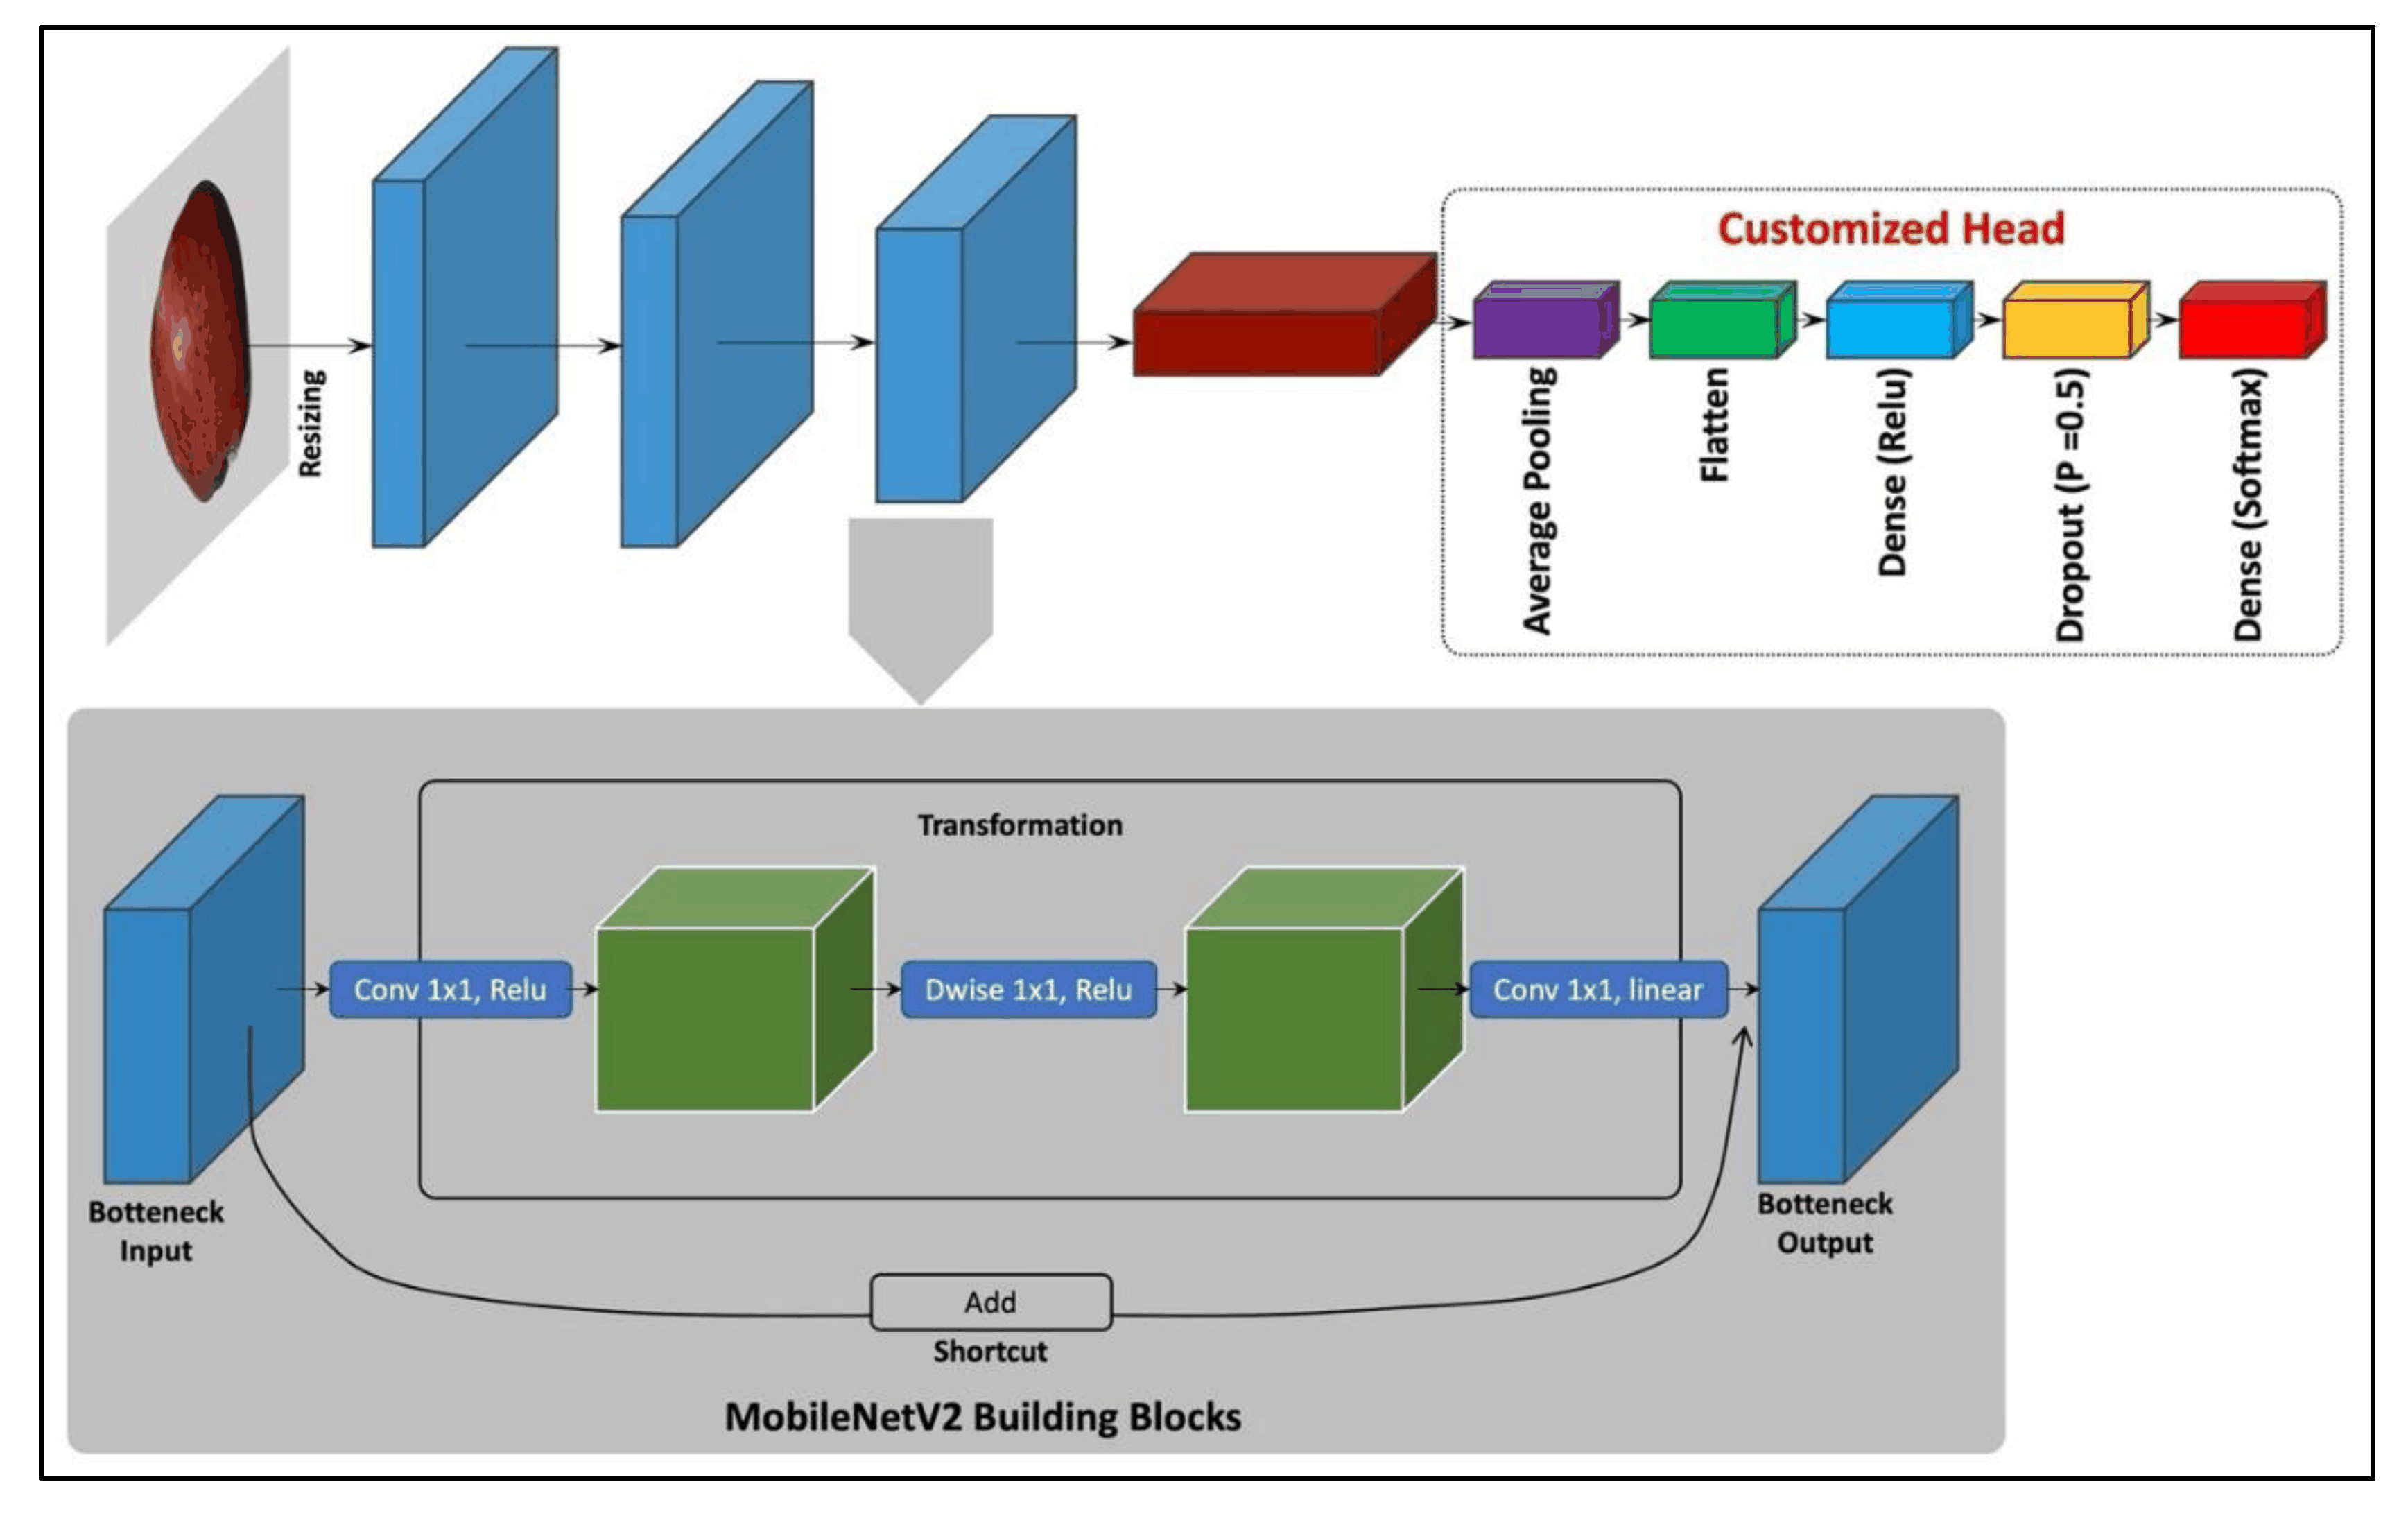
MobileNet & Edge AI AI on your phone - Depthwise Separable Convolutions 📱 The Constraint Mobile devices have limited Compute (CPU/NPU) and Battery. Standard Convolutions are too heavy. Standard Conv Cost: $D_K \cdot D_K \cdot M \cdot N \cdot D_F \cdot D_F$ $D_K$ : Kernel Size $M$ : Input Channels $N$ : Output Channels $D_F$ : Feature Map Size ✂️ Depthwise Separable Convolution Splits convolution into two steps: Depthwise Conv: Apply a single filter per input channel. (Spatial features). Cost: $D_K \cdot D_K \cdot M \cdot D_F \cdot D_F$ Pointwise Conv: $1 \times 1$ Conv to combine channels. (Channel features). Cost: $1 \cdot 1 \cdot M \cdot N \cdot D_F \cdot D_F$ Reduction: $\frac{1}{N} + \frac{1}{D_K^2}$ . For a $3 \times 3$ kernel, this is 8-9x less computation with minimal accuracy drop. 🚀 MobileNet Evolution V1: Introduced Depthwise Separable Convs. V2: Introduced Inverted Residuals and Linear Bottlenecks (Remove ReLU in the output of the bottleneck to preserve info). V3: Used Neural Architecture Search (NAS) and Hard-Swish activation (faster to compute than Sigmoid). 💻 PyTorch Implementation import torch . nn as nn class DepthwiseSeparableConv ( nn . Module ): def __init__ ( self , in_channels , out_channels ): super (). __init__ () # 1. Depthwise (groups = in_channels) self . depthwise = nn . Conv2d ( in_channels , in_channels , kernel_size = 3 , padding = 1 , groups = in_channels , bias = False ) self . pointwise = nn . Conv2d ( in_channels , out_channels , kernel_size = 1 , bias = False ) def forward ( self , x ): x = self . depthwise ( x ) x = self . pointwise ( x ) return x 🎓 Interview Focus What is the groups parameter in Conv2d? It controls connections between input and output channels. groups=1 : Standard Conv (All inputs connected to all outputs). groups=in_channels : Depthwise Conv (Each input has its own filter). Why remove ReLU in the bottleneck (MobileNetV2)? ReLU destroys information in low-dimensional manifolds (the bottleneck). Linear activation preserves it. MobileNet: Making AI ubiquitous!
Mobile devices have limited Compute (CPU/NPU) and Battery. Standard Convolutions are too heavy.
Reduction: $\frac{1}{N} + \frac{1}{D_K^2}$ . For a $3 \times 3$ kernel, this is 8-9x less computation with minimal accuracy drop.
import torch . nn as nn class DepthwiseSeparableConv ( nn . Module ): def __init__ ( self , in_channels , out_channels ): super (). __init__ () # 1. Depthwise (groups = in_channels) self . depthwise = nn . Conv2d ( in_channels , in_channels , kernel_size = 3 , padding = 1 , groups = in_channels , bias = False ) self . pointwise = nn . Conv2d ( in_channels , out_channels , kernel_size = 1 , bias = False ) def forward ( self , x ): x = self . depthwise ( x ) x = self . pointwise ( x ) return x
2. Related Work, Literature Survey & Algorithmic Foundations
Edge AI Model Optimization: Rock-Paper-Scissors This repository contains a comprehensive analysis of deep learning model optimization for Edge AI deployment, comparing MobileNetV2 and VGG16 architectures using the Rock-Paper-Scissors dataset. Technique Model Size / Compression Performance Baseline (FP32) VGG16 80.64 MB (1.0x) 96.51% Accuracy Baseline (FP32) MobileNetV2 8.63 MB (1.0x) 84.41% Accuracy TFLite INT8 MobileNetV2 2.59 MB (~3.3x) 86.88% Accuracy 4-Bit Clustering MobileNetV2 ~1.08 MB (8.0x) 0.00345 MSE 🛠️ Key Features Architecture Comparison: Benchmarking the parameter-heavy VGG16 against the mobile-optimized MobileNetV2. Post-Training Quantization: Utilizing the TFLite converter to transform models into INT8 format, achieving significant latency reductions (e.g., 15.52 ms/image for MobileNetV2). N-Bit Weight Clustering: Implementation of K-Means clustering (4-bit) to reduce theoretical weight size by 8x. Sensitivity Analysis: Identification of Depthwise Convolutional layers as the most vulnerable components to quantization and clustering distortion. 🔍 Critical Insights VGG16 provides superior accuracy but is roughly 10x larger than MobileNetV2, making it less suitable for memory-constrained devices. MobileNetV2 is the optimal candidate for Edge deployment, meeting the 75% accuracy threshold while maintaining a tiny footprint. Depthwise layers showed the highest reconstruction errors (MSE), suggesting they require careful calibration or higher precision compared to standard layers. 🚀 Getting Started Environment: Optimized for TensorFlow 2.x with GPU acceleration (e.g., Google Colab T4). Dataset: Automatically sourced via tensorflow_datasets (rock_paper_scissors). Run: Open Assignment2_Edge_AI.ipynb to execute the training, benchmarking, and quantization pipelines. requirements.txt Core Machine Learning tensorflow>=2.15.0 tensorflow-datasets>=4.9.0 Data Manipulation & Analysis pandas>=2.0.0 numpy>=1.23.5 scikit-learn>=1.2.0 Visualization matplotlib>=3.7.0 📂 How to use this in your Repo Create the file: Create a new file named requirements.txt in your root directory. Add the content: Copy and paste the block above. Install: Users can then set up their environment by running: pip install -r requirements.txt MIT License Copyright (c) 2026 Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions: The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software. THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE. This project was completed as part of the Edge AI (CP 330) course assignment at the Indian Institute of Science (IISc), Bangalore. The work involved: Architecture Benchmarking: Comparing the efficiency and accuracy of MobileNetV2 and VGG16. Model Optimization: Implementing INT8 quantization and 4-bit weight clustering to reduce memory footprint for edge deployment. Performance Analysis: Achieving 86.88% accuracy with a compressed 2.59 MB MobileNetV2 model, successfully exceeding the assignment's 75% accuracy threshold.
Edge AI Model Optimization: Rock-Paper-Scissors This repository contains a comprehensive analysis of deep learning model optimization for Edge AI deployment, comparing MobileNetV2 and VGG16 architectures using the Rock-Paper-Scissors dataset.
Technique Model Size / Compression Performance Baseline (FP32) VGG16 80.64 MB (1.0x) 96.51% Accuracy Baseline (FP32) MobileNetV2 8.63 MB (1.0x) 84.41% Accuracy TFLite INT8 MobileNetV2 2.59 MB (~3.3x) 86.88% Accuracy 4-Bit Clustering MobileNetV2 ~1.08 MB (8.0x) 0.00345 MSE
🛠️ Key Features Architecture Comparison: Benchmarking the parameter-heavy VGG16 against the mobile-optimized MobileNetV2.
Post-Training Quantization: Utilizing the TFLite converter to transform models into INT8 format, achieving significant latency reductions (e.g., 15.52 ms/image for MobileNetV2).
N-Bit Weight Clustering: Implementation of K-Means clustering (4-bit) to reduce theoretical weight size by 8x.
Sensitivity Analysis: Identification of Depthwise Convolutional layers as the most vulnerable components to quantization and clustering distortion.
🔍 Critical Insights VGG16 provides superior accuracy but is roughly 10x larger than MobileNetV2, making it less suitable for memory-constrained devices.
MobileNetV2 is the optimal candidate for Edge deployment, meeting the 75% accuracy threshold while maintaining a tiny footprint.
Depthwise layers showed the highest reconstruction errors (MSE), suggesting they require careful calibration or higher precision compared to standard layers.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
🚀 Getting Started Environment: Optimized for TensorFlow 2.x with GPU acceleration (e.g., Google Colab T4).
Run: Open Assignment2_Edge_AI.ipynb to execute the training, benchmarking, and quantization pipelines.
📂 How to use this in your Repo Create the file: Create a new file named requirements.txt in your root directory.
Install: Users can then set up their environment by running: pip install -r requirements.txt
Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
This project was completed as part of the Edge AI (CP 330) course assignment at the Indian Institute of Science (IISc), Bangalore.
Architecture Benchmarking: Comparing the efficiency and accuracy of MobileNetV2 and VGG16.
Model Optimization: Implementing INT8 quantization and 4-bit weight clustering to reduce memory footprint for edge deployment.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Performance Analysis: Achieving 86.88% accuracy with a compressed 2.59 MB MobileNetV2 model, successfully exceeding the assignment's 75% accuracy threshold.
Performance analysis and optimization of MobileNetV2 and VGG16 on the Rock-Paper-Scissors dataset. Includes implementations of TFLite INT8 quantization, linear bit-depth analysis, and K-Means weight clustering for Edge AI deployment.
MobileNetV2 Edge Deployment Overview This project investigates the deployment of lightweight deep learning models for edge AI applications using MobileNetV2. The study evaluates the effects of model pruning and quantization on classification accuracy, model size, and inference latency. Objectives Evaluate baseline MobileNetV2 performance Apply pruning techniques to reduce model complexity Apply quantization techniques to improve deployment efficiency Compare model accuracy, size, and latency Assess suitability for edge deployment Dataset CIFAR-10 dataset 10 image classes Used for benchmarking model performance under different optimization techniques Methods The following approaches were evaluated: Baseline MobileNetV2 Pruned MobileNetV2 Quantized MobileNetV2 Pruned + Quantized MobileNetV2 Tools Python PyTorch TorchVision NumPy Matplotlib Results Model Accuracy Model Size Latency Baseline 69.80% 9.19 MB 0.0092 s Pruned 59.44% 17.96 MB 0.0283 s Quantized 70.10% 9.13 MB 0.0105 s Pruned + Quantized 72.92% 9.13 MB 0.0088 s Key Findings Quantization preserved accuracy while maintaining a compact model size. The combined pruning and quantization approach achieved the highest accuracy. Optimized models demonstrated potential for deployment on resource-constrained edge devices. Future Work Deployment on Raspberry Pi and embedded systems Real-time edge inference evaluation Integration with explainable AI (XAI) techniques
Overview This project investigates the deployment of lightweight deep learning models for edge AI applications using MobileNetV2. The study evaluates the effects of model pruning and quantization on classification accuracy, model size, and inference latency.
Pruning, quantization and performance evaluation of MobileNetV2 for edge AI deployment.
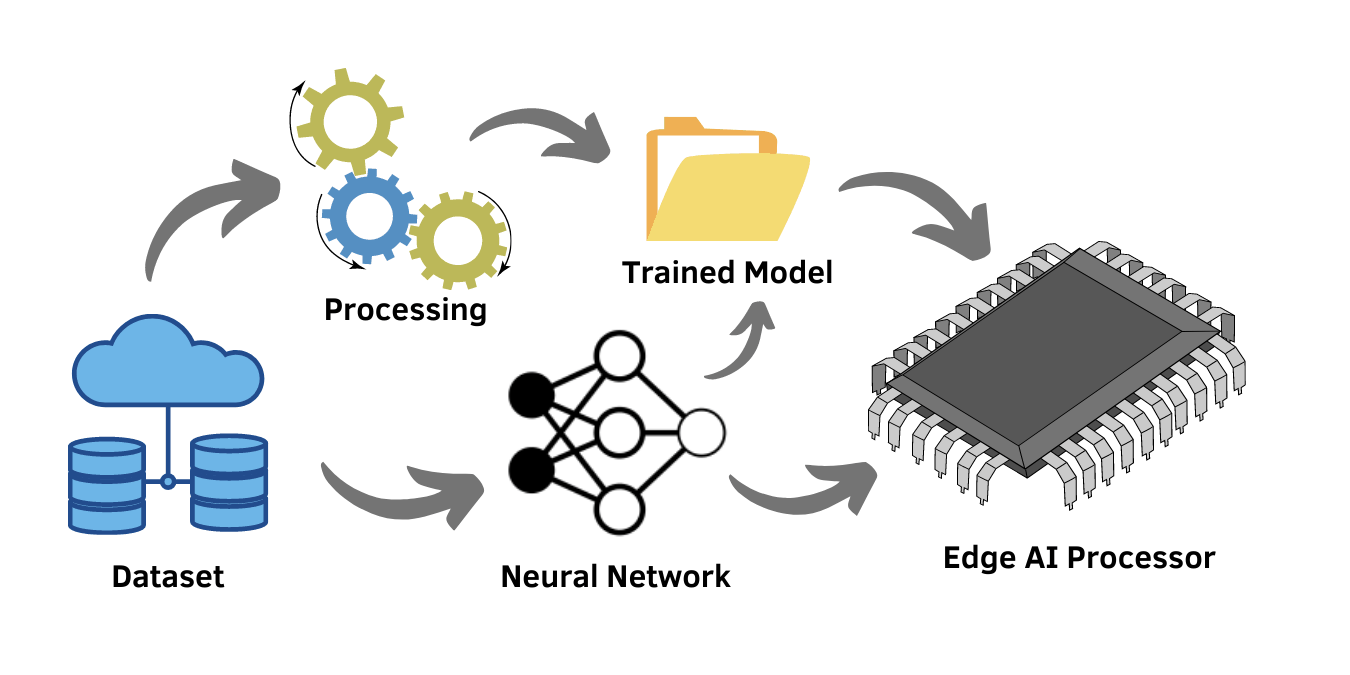
MobileNet-based Image Classification for Edge Computing This project demonstrates how to train a MobileNet-based model on the CIFAR-10 dataset, convert the trained model to TensorFlow Lite for deployment on edge devices, and simulate real-time inference using TensorFlow Lite Interpreter. It also integrates federated learning to train a model across multiple edge devices collaboratively while keeping data decentralized. Project Overview Dataset : CIFAR-10, which consists of 60,000 32x32 color images in 10 classes, with 6,000 images per class. The dataset is divided into 50,000 training images and 10,000 testing images. Model : MobileNet-based architecture (lightweight, efficient, and designed for edge devices). Framework : TensorFlow for model training and TensorFlow Lite for converting the model for edge deployment. Federated Learning : A simple federated learning setup to train the model collaboratively across multiple edge devices. Edge Simulation : The model's performance (inference speed and latency) is simulated using TensorFlow Lite Interpreter in Google Colab. Clone the Repository git clone https://github.com/elprofessor-15/Edge-Computing-MobileNet.git Install Dependencies Install the necessary Python packages required for this project Prepare the Dataset The CIFAR-10 dataset is automatically loaded using TensorFlow’s keras.datasets module. It consists of 10 classes, including animals and vehicles. Classes: • Airplane • Automobile • Bird • Cat • Deer • Dog • Frog • Horse • Ship • Truck Training data: 50,000 images Testing data: 10,000 images Train the MobileNet Model We use the MobileNet model without the top layers, adding custom classification layers for CIFAR-10. The model is trained for 5 epochs. Convert the Model to TensorFlow Lite Convert the trained model into a TensorFlow Lite model for deployment on edge devices. Simulate Edge Inference with TensorFlow Lite Use TensorFlow Lite Interpreter to simulate inference on an edge device. This step demonstrates how TensorFlow Lite can be used for real-time image classification on edge devices. Federated Learning (Optional) Federated Learning allows multiple devices to collaboratively train a model without sharing their data. Here, we simulate a simple federated learning setup for the MobileNet model. Measure Latency and Validate Edge Performance Measure the inference latency of the TensorFlow Lite model to validate how well it performs on edge devices. Conclusion This project showcases the deployment of a MobileNet-based model for image classification on edge devices using TensorFlow Lite. The integration of federated learning allows for decentralized training across multiple devices, ensuring that data privacy is maintained. Finally, the project measures the latency of the edge device inference to evaluate real-world performance.
This project demonstrates how to train a MobileNet-based model on the CIFAR-10 dataset, convert the trained model to TensorFlow Lite for deployment on edge devices, and simulate real-time inference using TensorFlow Lite Interpreter. It also integrates federated learning to train a model across multiple edge devices collaboratively while keeping data decentralized.
Dataset : CIFAR-10, which consists of 60,000 32x32 color images in 10 classes, with 6,000 images per class. The dataset is divided into 50,000 training images and 10,000 testing images.
Model : MobileNet-based architecture (lightweight, efficient, and designed for edge devices).
Framework : TensorFlow for model training and TensorFlow Lite for converting the model for edge deployment.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Federated Learning : A simple federated learning setup to train the model collaboratively across multiple edge devices.
Edge Simulation : The model's performance (inference speed and latency) is simulated using TensorFlow Lite Interpreter in Google Colab.
The CIFAR-10 dataset is automatically loaded using TensorFlow’s keras.datasets module. It consists of 10 classes, including animals and vehicles.
Classes: • Airplane • Automobile • Bird • Cat • Deer • Dog • Frog • Horse • Ship • Truck
We use the MobileNet model without the top layers, adding custom classification layers for CIFAR-10. The model is trained for 5 epochs.
Convert the trained model into a TensorFlow Lite model for deployment on edge devices.
Use TensorFlow Lite Interpreter to simulate inference on an edge device. This step demonstrates how TensorFlow Lite can be used for real-time image classification on edge devices.
Federated Learning allows multiple devices to collaboratively train a model without sharing their data. Here, we simulate a simple federated learning setup for the MobileNet model.
Measure the inference latency of the TensorFlow Lite model to validate how well it performs on edge devices.
This project showcases the deployment of a MobileNet-based model for image classification on edge devices using TensorFlow Lite. The integration of federated learning allows for decentralized training across multiple devices, ensuring that data privacy is maintained. Finally, the project measures the latency of the edge device inference to evaluate real-world performance.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)