Complete Technical Paper Content — Named Entity Recognition Nlp
1. Executive Abstract, Problem Formulation & Background
Named-entity recognition (NER) (also known as (named) entity identification, entity chunking, and entity extraction) is a subtask of information extraction that seeks to locate and classify named entities mentioned in unstructured text into pre-defined categories such as person names (PER), organizations (ORG), locations (LOC), geopolitical entities (GPE), vehicles (VEH), medical codes, time expressions, quantities, monetary values, percentages, etc. Most research on NER/NEE systems has been structured as taking an unannotated block of text, such as transducing:
Jim bought 300 shares of Acme Corp. in 2006. into an annotated block of text that highlights the names of entities:
[Jim]Person bought 300 shares of [Acme Corp.]Organization in [2006]Time. In this example, a person name consisting of one token, a two-token company name and a temporal expression have been detected and classified.
with fewer tokens than desired (for example, missing the last token of "John Smith, M.D.") with more tokens than desired (for example, including the first word of "The University of MD") partitioning adjacent entities differently (for example, treating "Smith, Jones Robinson" as 2 vs. 3 entities) assigning it a completely wrong type (for example, calling a personal name an organization) assigning it a related but inexact type (for example, "substance" vs. "drug", or "school" vs. "organization") correctly identifying an entity, when what the user wanted was a smaller- or larger-scope entity (for example, identifying "James Madison" as a personal name, when it's part of "James Madison University"). Some NER systems impose the restriction that entities may never overlap or nest, which means that in some cases one must make arbitrary or task-specific choices. One overly simple method of measuring accuracy is merely to count what fraction of all tokens in the text were correctly or incorrectly identified as part of entity references (or as being entities of the correct type). This suffers from at least two problems: first, the vast majority of tokens in real-world text are not part of entity names, so the baseline accuracy (always predict "not an entity") is extravagantly high, typically >90%; and second, mispredicting the full span of an entity name is not properly penalized (finding only a person's first name when his last name follows might be scored as ½ accuracy). In academic conferences such as CoNLL, a variant of the F1 score has been defined as follows:
2. Related Work, Literature Survey & Algorithmic Foundations
Precision is the number of predicted entity name spans that line up exactly with spans in the gold standard evaluation data. I.e. when [Person Hans] [Person Blick] is predicted but [Person Hans Blick] was required, precision for the predicted name is zero. Precision is then averaged over all predicted entity names. Recall is similarly the number of names in the gold standard that appear at exactly the same location in the predictions. F1 score is the harmonic mean of these two. It follows from the above definition that any prediction that misses a single token, includes a spurious token, or has the wrong class, is a hard error and does not contribute positively to either precision or recall. Thus, this measure may be said to be pessimistic: it can be the case that many "errors" are close to correct, and might be adequate for a given purpose. For example, one system might always omit titles such as "Ms." or "Ph.D.", but be compared to a system or ground-truth data that expects titles to be included. In that case, every such name is treated as an error. Because of such issues, it is important actually to examine the kinds of errors, and decide how important they are given one's goals and requirements. Evaluation models based on a token-by-token matching have been proposed. Such models may be given partial credit for overlapping matches (such as using the Intersection over Union criterion). They allow a finer grained evaluation and comparison of extraction systems.
GATE supports NER across many languages and domains out of the box, usable via a graphical interface and a Java API. OpenNLP includes rule-based and statistical named-entity recognition. spaCy features fast statistical NER as well as an open-source named-entity visualizer. Hand-crafted grammar-based systems typically obtain better precision, but at the cost of lower recall and months of work by experienced computational linguists. Statistical NER systems typically require a large amount of manually annotated training data. Semisupervised approaches have been suggested to avoid part of the annotation effort. In the statistical learning era, NER was usually performed by learning a simple linear regression model on engineered features, then decoded by a bidirectional Viterbi algorithm. Some commonly used features include:
Lexical items: The token itself be labeled. Stemmed lexical items. Shape: The orthographic pattern of the target word. For example, all lowercase, all uppercase, initial uppercase, mixed case, uppercase followed by a period (often indicating a middle name), contains hyphen, etc. Affixes of the target word and surrounding words. Part of speech of the word. Whether the word appears in one or more named entity lists (gazetteers). Words and/or n-grams occurring in the surrounding context. A gazetteer is a list of names and their types, such as "General Electric". It can be used to augment any system for NER. They had been often used in the era of statistical machine learning. Many different classifier types have been used to perform machine-learned NER, with conditional random fields being a typical choice. Transformers features token classification using deep learning models.
Early work in NER systems in the 1990s was aimed primarily at extraction from journalistic articles. Attention then turned to processing of military dispatches and reports. Later stages of the automatic content extraction (ACE) evaluation also included several types of informal text styles, such as weblogs and text transcripts from conversational telephone speech conversations. Since about 1998, there has been a great deal of interest in entity identification in the molecular biology, bioinformatics, and medical natural language processing communities. The most common entity of interest in that domain has been names of genes and gene products. There has been also considerable interest in the recognition of chemical entities and drugs in the context of the CHEMDNER competition, with 27 teams participating in this task. In 2001, research indicated that even state-of-the-art NER systems were brittle, meaning that NER systems developed for one domain did not typically perform well on other domains. Considerable effort is involved in tuning NER systems to perform well in a new domain; this is true for both rule-based and trainable statistical systems. As of 2007, state-of-the-art NER systems for English produce near-human performance. For example, the best system entering MUC-7 scored 93.39% of F-measure while human annotators scored 97.60% and 96.95%.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Another field that has seen progress but remains challenging is the application of NER to Twitter and other microblogs, considered "noisy" due to non-standard orthography, shortness and informality of texts. NER challenges in English Tweets have been organized by research communities to compare performances of various approaches, such as bidirectional LSTMs, Learning-to-Search, or CRFs.
Jurafsky, Daniel; Martin, James H. (2008). "13.5 Partial Parsing". Speech and Language Processing (2nd ed.). Upper Saddle River, N.J.: Prentice Hall. ISBN 978-0131873216. Jurafsky, Daniel; Martin, James H. (2008). "22.1. Named Entity Recognition". Speech and Language Processing (2nd ed.). Upper Saddle River, N.J.: Prentice Hall. ISBN 978-0131873216.
The following outline is provided as an overview of, and topical guide to, machine learning: Machine learning (ML) is a subfield of artificial intelligence within computer science that evolved from the study of pattern recognition and computational learning theory. In 1959, Arthur Samuel defined machine learning as a "field of study that gives computers the ability to learn without being explicitly programmed". ML involves the study and construction of algorithms that can learn from and make predictions on data. These algorithms operate by building a model from a training set of example observations to make data-driven predictions or decisions expressed as outputs, rather than following strictly static program instructions.
Canonical correlation analysis (CCA) Factor analysis Feature extraction Feature selection Independent component analysis (ICA) Linear discriminant analysis (LDA) Multidimensional scaling (MDS) Non-negative matrix factorization (NMF) Partial least squares regression (PLSR) Principal component analysis (PCA) Principal component regression (PCR) Projection pursuit Sammon mapping t-distributed stochastic neighbor embedding (t-SNE)
4. Neural Network Backbone, Layer Specifications & Loss Formulations
AdaBoost Boosting Bootstrap aggregating (also "bagging" or "bootstrapping") Ensemble averaging Gradient boosted decision tree (GBDT) Gradient boosting Random Forest Stacked Generalization
Q-learning State–action–reward–state–action (SARSA) Temporal difference learning (TD) Learning Automata
Averaged one-dependence estimators (AODE) Artificial neural network Case-based reasoning Gaussian process regression Gene expression programming Group method of data handling (GMDH) Inductive logic programming Instance-based learning Lazy learning Learning Automata Learning Vector Quantization Logistic Model Tree Minimum message length (decision trees, decision graphs, etc.) Nearest Neighbor Algorithm Analogical modeling Probably approximately correct learning (PAC) learning Ripple down rules, a knowledge acquisition methodology Symbolic machine learning algorithms Support vector machines Random Forests Ensembles of classifiers Bootstrap aggregating (bagging) Boosting (meta-algorithm) Ordinal classification Conditional Random Field ANOVA Quadratic classifiers k-nearest neighbor Boosting SPRINT Bayesian networks Naive Bayes Hidden Markov models Hierarchical hidden Markov model
Bayesian knowledge base Naive Bayes Gaussian Naive Bayes Multinomial Naive Bayes Averaged One-Dependence Estimators (AODE) Bayesian Belief Network (BBN) Bayesian Network (BN)
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Decision tree Classification and regression tree (CART) Iterative Dichotomiser 3 (ID3) C4.5 algorithm C5.0 algorithm Chi-squared Automatic Interaction Detection (CHAID) Decision stump Conditional decision tree ID3 algorithm Random forest SLIQ
Fisher's linear discriminant Linear regression Logistic regression Multinomial logistic regression Naive Bayes classifier Perceptron Support vector machine
Expectation-maximization algorithm Vector Quantization Generative topographic map Information bottleneck method Association rule learning algorithms Apriori algorithm Eclat algorithm
Feedforward neural network Extreme learning machine Convolutional neural network Recurrent neural network Long short-term memory (LSTM) Logic learning machine Self-organizing map
Model Figures & Evaluation Curves (4 Images)
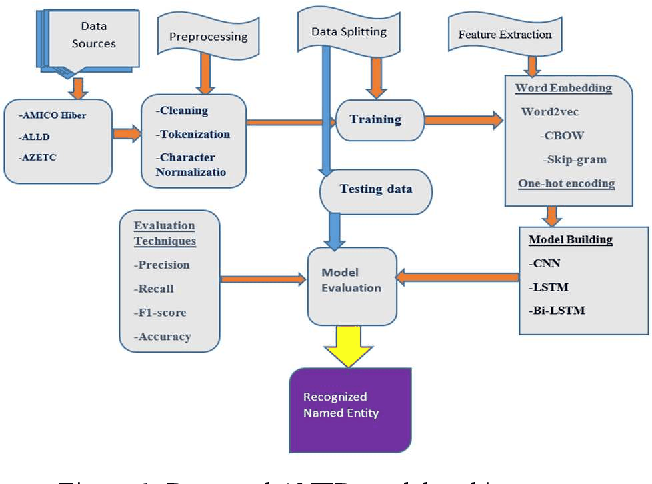
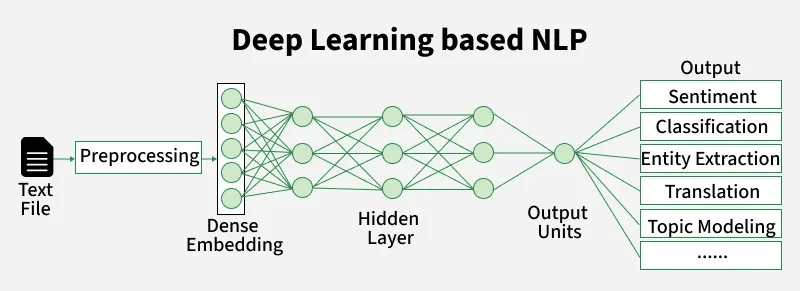
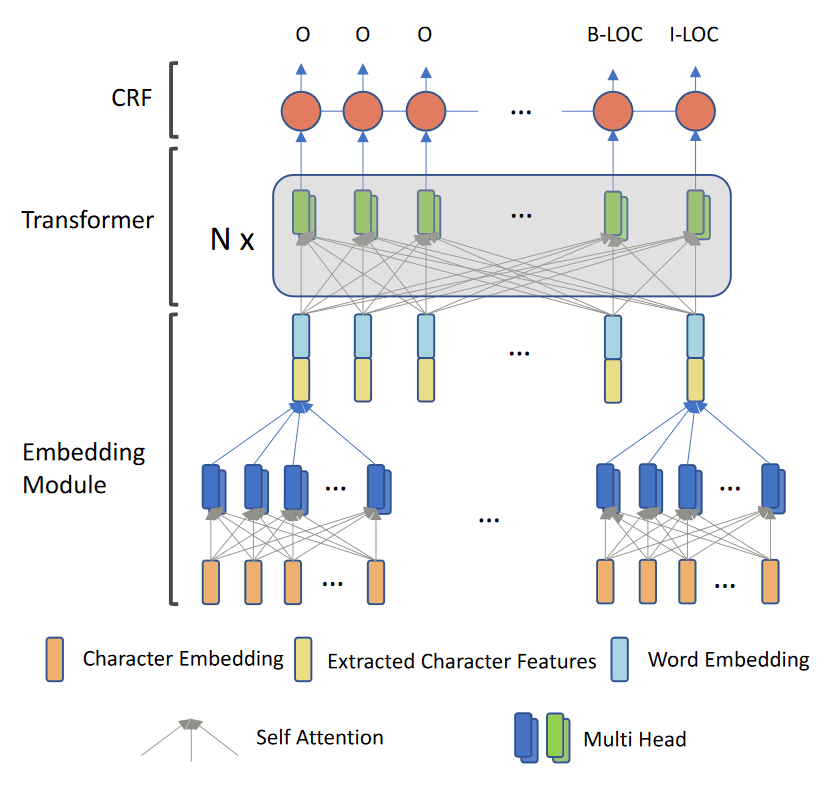
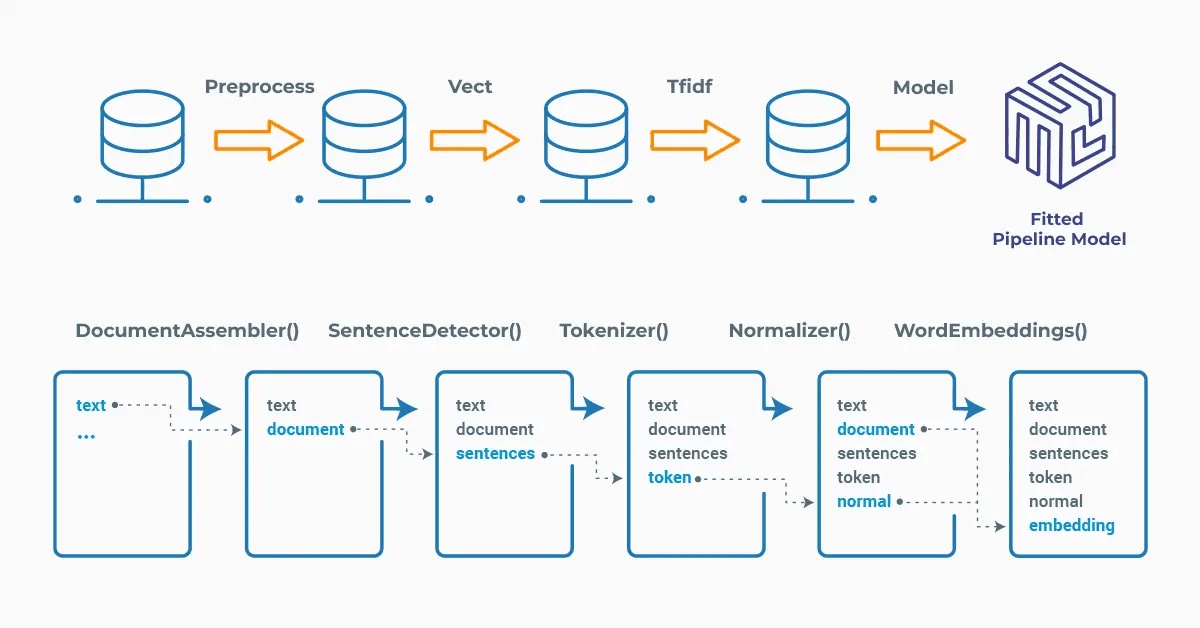
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)