Complete Technical Paper Content — Neural Network Projects
1. Executive Abstract, Problem Formulation & Background
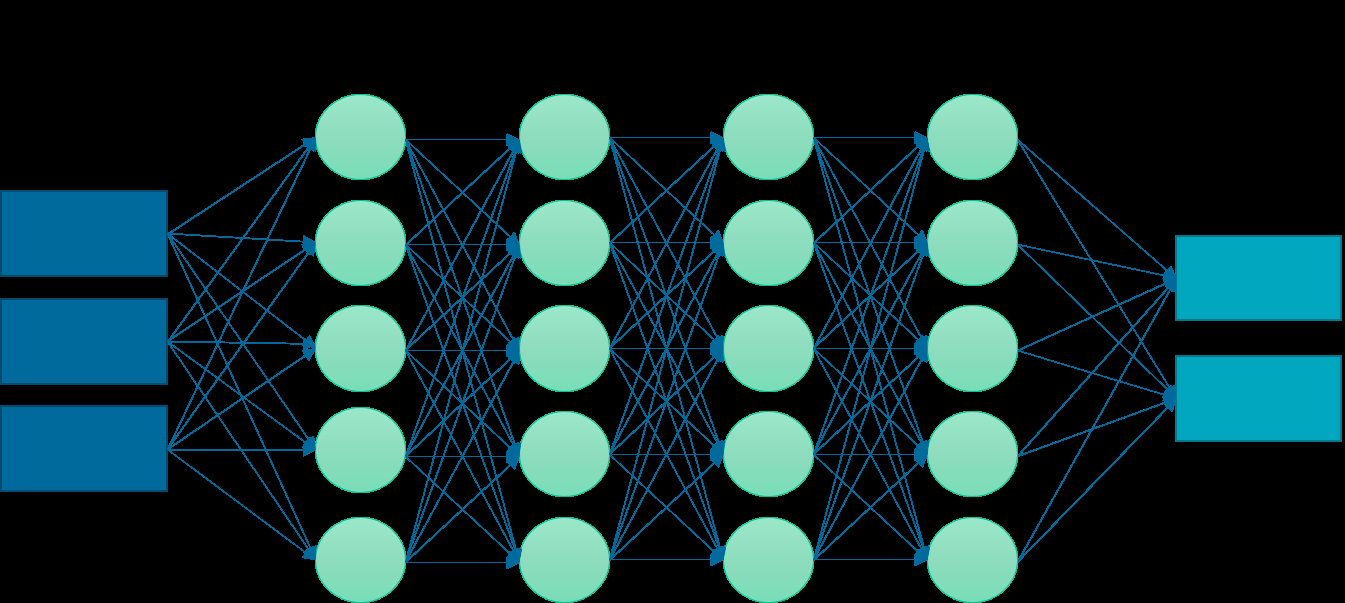
In machine learning, a neural network (NN) or artificial neural network (ANN) is a computational model inspired by the structure and functions of biological neural networks. A neural network consists of connected units or nodes called artificial neurons, which loosely model the neurons in the brain. These are connected by edges, which model the synapses in the brain. Each artificial neuron receives signals from connected neurons, then processes them and sends a signal to other connected neurons. The "signal" is a real number, and the output of each neuron is computed by some non-linear function of the totality of its inputs, called the activation function. The strength of the signal at each connection is determined by a weight, which adjusts as part of the training process. Groups of neurons are aggregated into layers. Each layer performs a transformation on its inputs. Signals travel from the first layer (the input layer) to the last layer (the output layer), typically passing through multiple intermediate layers (hidden layers). A network is typically called a deep neural network if it has at least two hidden layers. Deep neural networks are capable of learning sophisticated hierarchical representations. Training neural networks is a compute-intensive process, accelerated by the use of graphics processing units (GPUs), and large datasets.
In reality, such textures and outlines would not be represented by single nodes, but rather by associated weight patterns of multiple nodes. Architectural innovations such as convolutional neural networks (CNNs) significantly improved performance in computer vision tasks, while recurrent neural networks (RNNs) enabled modeling of sequential data such as speech and time-series information. Transformer architectures introduced attention mechanisms that allow neural networks to model long-range dependencies in data and have been the basis of large language models. Artificial neural networks are used for myriad tasks including chatbots, large-scale text, image, and video generation, and robotics.
During the 2010s, the seq2seq model was developed, and attention mechanisms were added. This led to the modern transformer architecture in 2017 in "Attention Is All You Need". It requires computation time that is quadratic in the size of the context window. Schmidhuber's fast weight controller (1992) scales linearly and was later shown to be equivalent to the unnormalized linear transformer. Transformers have increasingly become the model of choice for natural language processing. Many modern large language models such as GPT, Gemini, Grok, DeepSeek, and Qwen use this architecture.
NNs began as an attempt to replicate the architecture of the brain in the digital realm. It immediately showed promise for handling non-linear relationships, but encountered obstacles. Models soon reoriented to applying mathematical insights to improve empirical results, at the expense of biological fidelity.
NNs are composed of digital neurons, conceptually derived from biological neurons. Each neuron has one or more numerical inputs and produces a single numerical output. An input (e.g., an image) is typically parceled across the set of input neurons (each getting a piece of the image). Each neuron's inputs, weighted by the weights of the connections from each of those inputs are summed. A bias term is added to this sum. The result is then passed through a nonlinear activation function to produce the neuron's output. Small enough outputs may be zeroed out (ignored).
2. Related Work, Literature Survey & Algorithmic Foundations
Nodes are arranged in layers, with the bottom layers directly addressing raw data, while the top layers reveal the final results. Intermediate layers gradually increase the level of abstraction, so what began as for example, pixels in an image, gradually resolves into things such as object boundaries, and then into real-world objects such as letters and faces. Single layer and unlayered networks are also used. Multiple connection patterns have been used. Traditionally, they are fully connected, with every neuron in one layer connecting to every neuron in the next layer. However, in convolutional neural networks, some layers are convolutional, meaning each neuron in one layer is connected to a subset of neurons in the previous layer, such as those representing one section of an image. In most neural networks, the outputs of the neurons in one layer are connected only to neurons in the immediately following layer (directed acyclic graph), meaning information only flows forward from one layer to the next. These are known as feedforward networks. In contrast, networks that allow connections between neurons in the same or previous layers are known as recurrent networks.
Training/learning involves adjusting the weights of the network to improve the accuracy of the result. NNs typically require vast numbers of sample inputs (far more than biological brains) to achieve a given level of function. This is done by minimizing the observed errors among sample observations. Training takes place before a network is deployed, and (unlike brains) does not continue thereafter. Instead, the network may be retrained from scratch as more sample data becomes available. Empirical risk minimization adjusts node and link weights to minimize the difference (empirical risk), between the predicted output and the known values in the training samples. A defined loss function measures the degree of error. Backpropagation spreads the error (adjusts the weights) from the output nodes across the network to the input nodes. The intent is to allow the network to process data that is not included in the training samples. As long as the value of the loss function (its cost) continues to decline, the network is continuing to improve. The function typically produces a statistic whose value is only approximate. When the cost is low, the difference between the output (e.g. almost certainly a cat) and the correct answer (a cat) is small. Most learning models can be viewed as a straightforward application of optimization theory and statistical estimation. Learning typically ends when additional observations do not usefully reduce the cost. The cost typically approaches, but does not reach, 0. If no feasible amount of sample data yields a low cost, training is labeled a failure.
A loss function measures the discrepancy between a model's predictions and the desired values, usually as a non-negative number where smaller values are better and a perfect prediction incurs a loss of 0. The choice of loss function depends on the type of problem. In regression tasks, where the output is a continuous value, common choices are mean squared error and mean absolute error, which penalize the squared error and the absolute error respectively. In classification tasks, the standard choice is cross-entropy, which treats the model's output as a probability distribution over classes and is equivalent to maximizing the likelihood of the data under the model. Margin-based losses such as hinge loss are also used. Not all losses require labeled targets: self-supervised methods train on augmented views of unlabeled data, and generative models such as variational autoencoders combine a reconstruction loss with a Kullback–Leibler divergence term.
Backpropagation is a method used to adjust the connection weights to compensate for errors found during learning. The error amount is essentially divided among the connections. Technically, backpropagation calculates the gradient (the derivative) of the loss function associated with a given state with respect to the weights. The weight updates can be done via stochastic gradient descent or other methods, such as extreme learning machines, "no-prop" networks, training without backtracking, "weightless" networks, and non-connectionist neural networks.
A hyperparameter is a parameter defining any configurable part of the network and learning process whose value is set prior to training. Examples of hyperparameters include learning rate, sample batch size, number of nodes and layers, etc . The performance of a neural network is strongly influenced by hyperparameter choices, and thus may be adjusted during training (typically between training runs), a process called hyperparameter tuning or hyperparameter optimization.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
The learning rate defines the size of the corrective steps that the model takes to adjust for errors in each observation. A high learning rate shortens training time, but with lower ultimate accuracy, while a lower learning rate takes longer, but with the potential for greater accuracy. Optimizations such as quickprop are primarily aimed at accelerating learning. In order to avoid oscillations such as connection weights that cycle between high and low values, and to improve the rate of convergence, refinements use an adaptive learning rate that increases or decreases as appropriate. The concept of momentum allows the balance between the gradient and the previous change to be weighted such that the weight adjustment depends to some degree on the previous change. A momentum close to 0 emphasizes the gradient, while a value close to 1 emphasizes the last change.
In applications such as playing video games, an actor takes a string of actions, receiving a generally unpredictable response from the environment (the game) after each one. The goal is to win the game (get the highest score). The cost is the inverse of the score. In reinforcement learning, the aim is to weight the network to increase the score. After each action the game generates an observation and an instantaneous cost, according to its rules. The rules and the long-term cost can only be estimated. At any juncture, the agent decides whether to explore new actions to uncover their costs or to exploit prior learning to proceed more quickly. Formally, the environment is modeled as a Markov decision process (MDP) with states s 1 , . . . , s n ∈ S {\displaystyle \textstyle {s_{1},...,s_{n}}\in S} and actions a 1 , . . . , a m ∈ A {\displaystyle \textstyle {a_{1},...,a_{m}}\in A} . Because the state transitions (policies) are not known, probability distributions are used instead: the instantaneous cost distribution P ( c t | s t ) {\displaystyle \textstyle P(c_{t}|s_{t})} , the observation distribution P ( x t | s t ) {\displaystyle \textstyle P(x_{t}|s_{t})} and the transition distribution P ( s t + 1 | s t , a t ) {\displaystyle \textstyle P(s_{t+1}|s_{t},a_{t})} , while a policy is defined as the conditional distribution over actions given the observations. Taken together, the two define a Markov chain (MC). The aim is to discover the lowest-cost MC. NNs serve as the learning component. Dynamic programming coupled with NNs (giving neurodynamic programming) has been applied to problems such as vehicle routing, video games, natural resource management and medicine because of NNs' ability to mitigate cost even when reducing the discretization grid density for numerically approximating control tasks.
In situation s perform action a; Receive consequence situation s'; Compute emotion of being in consequence situation v(s'); Update crossbar memory w'(a,s) = w(a,s) + v(s').
The backpropagated value (secondary reinforcement) is the emotion toward the consequence situation. The CAA exists in two environments, its behavioral environment, and its genetic environment, from which it receives initial emotions (only once) about to be encountered situations in the behavioral environment. Having received the genome vector (species vector) from the genetic environment, the CAA will learn a goal-seeking behavior, in the behavioral environment that contains both desirable and undesirable situations.
Neuroevolution can create NN topologies and weights using evolutionary computation. It is competitive with gradient descent approaches. Neuroevolution may be less prone to get caught in "dead ends".
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Learning can be either stochastic or batch. Stochastic learning creates a weight adjustment for each sample. In batch learning, weights are adjusted based on a batch of inputs, accumulating errors over the batch. Stochastic learning introduces "noise" into the process, using the local gradient calculated from one data point; this reduces the chance of the network getting stuck in local minima. However, batch learning typically yields a faster, more stable descent to a local minimum, since each update is performed in the direction of the batch's average error. A common compromise is to use "mini-batches", small batches with samples in each batch selected stochastically from the entire data set.
Applications that must generalize well to unseen examples must avoid over-training. This arises in convoluted or over-specified systems when the network capacity is much larger than needed. Two approaches address over-training. Cross-validation and similar techniques can check for over-training and select appropriate hyperparameters to minimize generalization error. Regularization in a probabilistic (Bayesian) framework can be performed by selecting a larger prior probability over simpler models; but also in statistical learning theory, where the goal is to minimize two quantities: the 'empirical risk' and the 'structural risk', which roughly corresponds to the error over the training set and the predicted error in unseen data due to overfitting.
Supervised neural networks that use a mean squared error (MSE) cost function can use formal statistical methods to determine the confidence of the trained model. The MSE on a validation set can be used as an estimate for variance. This value can then be used to calculate the confidence interval of network output, assuming a normal distribution. A confidence analysis made this way is statistically valid as long as the output probability distribution stays the same and the network is not modified. By adopting a softmax activation function, a generalization of the logistic function, on the output layer of the neural network (or a softmax component in a component-based network) for categorical target variables, the outputs can be interpreted as posterior probabilities. This is useful in classification as it gives a certainty measure. The softmax activation function is:
y i = e x i ∑ j = 1 c e x j {\displaystyle y_{i}={\frac {e^{x_{i}}}{\sum _{j=1}^{c}e^{x_{j}}}}}
Function approximation, or regression analysis, (including time series prediction, fitness approximation, and modeling) Data processing (including filtering, clustering, blind source separation, and compression) Nonlinear system identification and control (including vehicle control, trajectory prediction, adaptive control, process control, and natural resource management) Pattern recognition (including radar systems, face identification, signal classification, novelty detection, 3D reconstruction, object recognition, and sequential decision making) Sequence recognition (including gesture, speech, and handwritten and printed text recognition) Sensor data analysis (including image analysis) Robotics (including directing manipulators and prostheses) Data mining (including knowledge discovery in databases) Finance (such as ex-ante models for specific financial long-run forecasts and artificial financial markets) Quantum chemistry General game playing Generative AI Data visualization Machine translation Social network filtering E-mail spam filtering Medical diagnosis Disaster response NNs have been used to diagnose cancers and to distinguish highly invasive cancer cell lines from less invasive lines using only cell shape data. NNs have been used to accelerate reliability analysis of infrastructures subject to natural disasters and to predict settling in building foundations. They are used to mitigate flooding by modelling rainfall-runoff. NNs have been used for building black-box models in geoscience: hydrology, ocean modelling and coastal engineering, and geomorphology. NNs have been employed in cybersecurity, with the objective to discriminate between legitimate and malicious activities. For example, machine learning has been used for classifying Android malware, for identifying domains belonging to threat actors and for detecting URLs posing a security risk. Research is underway on penetration testing, for detecting botnets, credit cards frauds, and network intrusions. NNs have been proposed as a tool to solve partial differential equations in physics and simulate the properties of many-body open quantum systems. In brain research NNs have studied short-term behavior of individual neurons, the dynamics of neural circuitry arise from interactions between individual neurons and how behavior can arise from abstract neural modules that represent complete subsystems. Studies considered long-and short-term plasticity of neural systems and their relation to learning and memory from the individual neuron to the system level. NNs show promise in profiling a user's interests from photos and discovering new stable materials by efficiently predicting the total energy of crystals.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Error-based monitoring: comparing current predictions against ground-truth labels. This approach directly quantifies predictive performance but may be impractical when labels are delayed or impractical to obtain. Data distribution monitoring: detecting changes in the input data distribution using statistical tests, divergence measures, or density-ratio estimation. Representation monitoring: tracking the distribution of internal embeddings or hidden-layer features. Shifts in the latent representation can indicate nonstationarity even when labels are unavailable. Statistical methods such as statistical process control charts have been adapted for this purpose.
A Brief Introduction to Neural Networks (D. Kriesel) – Illustrated, bilingual manuscript about neural networks; Topics so far: Perceptrons, Backpropagation, Radial Basis Functions, Recurrent Neural Networks, Self Organizing Maps, Hopfield Networks. Review of Neural Networks in Materials Science Archived 7 June 2015 at the Wayback Machine Artificial Neural Networks Tutorial in three languages (Univ. Politécnica de Madrid) Another introduction to NN Next Generation of Neural Networks Archived 24 January 2011 at the Wayback Machine – Google Tech Talks Performance of Neural Networks Neural Networks and Information Archived 9 July 2009 at the Wayback Machine Sanderson G (5 October 2017). "But what is a Neural Network?". 3Blue1Brown. Archived from the original on 7 November 2021 – via YouTube. Hakim MA, Alam MI (2025). "Biologically inspired neural network layer with homeostatic regulation and adaptive repair mechanisms". Scientific Reports. 15 (1). Nature Publishing Group: 33903. Bibcode:2025NatSR..1533903H. doi:10.1038/s41598-025-09114-8. ISSN 2045-2322. PMC 12484884. PMID 41028030.
In machine learning, deep learning (DL) focuses on utilizing multilayered neural networks to perform tasks such as classification, regression, and representation learning. The field takes inspiration from biological neuroscience and revolves around stacking artificial neurons into layers and "training" them to process data. The adjective "deep" refers to the use of multiple layers (ranging from three to several hundred or thousands) in the network. Methods used can be supervised, semi-supervised or unsupervised. Some common deep learning network architectures include fully connected networks, deep belief networks, recurrent neural networks, recurrent Random neural networks, convolutional neural networks, generative adversarial networks, transformers, and neural radiance fields. These architectures have been applied to fields including computer vision, speech recognition, natural language processing, machine translation, bioinformatics, drug design, medical image analysis, climate science, material inspection and board game programs, where they have produced results comparable to and in some cases surpassing human expert performance. Early forms of neural networks were inspired by information processing and distributed communication nodes in biological systems, particularly the human brain. However, current neural networks do not intend to model the brain function of organisms, and are generally seen as low-quality models for that purpose.
The universal approximation theorem for deep neural networks concerns the capacity of networks with bounded width but the depth is allowed to grow. Lu et al. proved that if the width of a deep neural network with ReLU activation is strictly larger than the input dimension, then the network can approximate any Lebesgue integrable function; if the width is smaller or equal to the input dimension, then a deep neural network is not a universal approximator. The probabilistic interpretation derives from the field of machine learning. It features inference, as well as the optimization concepts of training and testing, related to fitting and generalization, respectively. More specifically, the probabilistic interpretation considers the activation nonlinearity as a cumulative distribution function. The probabilistic interpretation led to the introduction of dropout as regularizer in neural networks. The probabilistic interpretation was introduced by researchers including Hopfield, Widrow and Narendra and popularized in surveys such as the one by Bishop.
. In recent years, new developments of the Random neural network that have large and dense clusters of recurrent neurons with Deep Learning, have resulted in highly accurate algorithms for cyberattack detection and mitigation
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)