Complete Technical Paper Content — Pose Estimation Ai
1. Executive Abstract, Problem Formulation & Background
Multi-agent reinforcement learning (MARL) is a sub-field of reinforcement learning. It focuses on studying the behavior of multiple learning agents that coexist in a shared environment. Each agent is motivated by its own rewards, and does actions to advance its own interests; in some environments these interests are opposed to the interests of other agents, resulting in complex group dynamics. Multi-agent reinforcement learning is closely related to game theory and especially repeated games, as well as multi-agent systems. Its study combines the pursuit of finding ideal algorithms that maximize rewards with a more sociological set of concepts. While research in single-agent reinforcement learning is concerned with finding the algorithm that gets the biggest number of points for one agent, research in multi-agent reinforcement learning evaluates and quantifies social metrics, such as cooperation, reciprocity, equity, social influence, language and discrimination.
A set S {\displaystyle S} of environment states. One set A i {\displaystyle {\mathcal {A}}_{i}} of actions for each of the agents i ∈ I = { 1 , … , N } {\displaystyle i\in I=\{1,\dots ,N\}} .
P a → ( s , s ′ ) = Pr ( s t + 1 = s ′ ∣ s t = s , a → t = a → ) {\displaystyle P_{\vec {a}}(s,s')=\Pr(s_{t+1}=s'\mid s_{t}=s,{\vec {a}}_{t}={\vec {a}})} is the probability of transition (at time t {\displaystyle t} ) from state s {\displaystyle s} to state s ′ {\displaystyle s'} under joint action a → {\displaystyle {\vec {a}}} .
R → a → ( s , s ′ ) {\displaystyle {\vec {R}}_{\vec {a}}(s,s')} is the immediate joint reward after the transition from s {\displaystyle s} to s ′ {\displaystyle s'} with joint action a → {\displaystyle {\vec {a}}} . In settings with perfect information, such as the games of chess and Go, the MDP would be fully observable. In settings with imperfect information, especially in real-world applications like self-driving cars, each agent would access an observation that only has part of the information about the current state. In the partially observable setting, the core model is the partially observable stochastic game in the general case, and the decentralized POMDP in the cooperative case.
In pure competition settings, the agents' rewards are exactly opposite to each other, and therefore they are playing against each other. Pure cooperation settings are the other extreme, in which agents get the exact same rewards, and therefore they are playing with each other. Mixed-sum settings cover all the games that combine elements of both cooperation and competition.
Most real-world scenarios involving multiple agents have elements of both cooperation and competition. For example, when multiple self-driving cars are planning their respective paths, each of them has interests that are diverging but not exclusive: Each car is minimizing the amount of time it's taking to reach its destination, but all cars have the shared interest of avoiding a traffic collision. Zero-sum settings with three or more agents often exhibit similar properties to mixed-sum settings, since each pair of agents might have a non-zero utility sum between them. Mixed-sum settings can be explored using classic matrix games such as prisoner's dilemma, more complex sequential social dilemmas, and recreational games such as Among Us, Diplomacy and StarCraft II. Mixed-sum settings can give rise to communication and social dilemmas.
Stefano V. Albrecht, Filippos Christianos, Lukas Schäfer. Multi-Agent Reinforcement Learning: Foundations and Modern Approaches. MIT Press, 2024. https://www.marl-book.com Kaiqing Zhang, Zhuoran Yang, Tamer Basar. Multi-agent reinforcement learning: A selective overview of theories and algorithms. Studies in Systems, Decision and Control, Handbook on RL and Control, 2021. [1] Yang, Yaodong; Wang, Jun (2020). "An Overview of Multi-Agent Reinforcement Learning from Game Theoretical Perspective". arXiv:2011.00583 [cs.MA].
2. Related Work, Literature Survey & Algorithmic Foundations
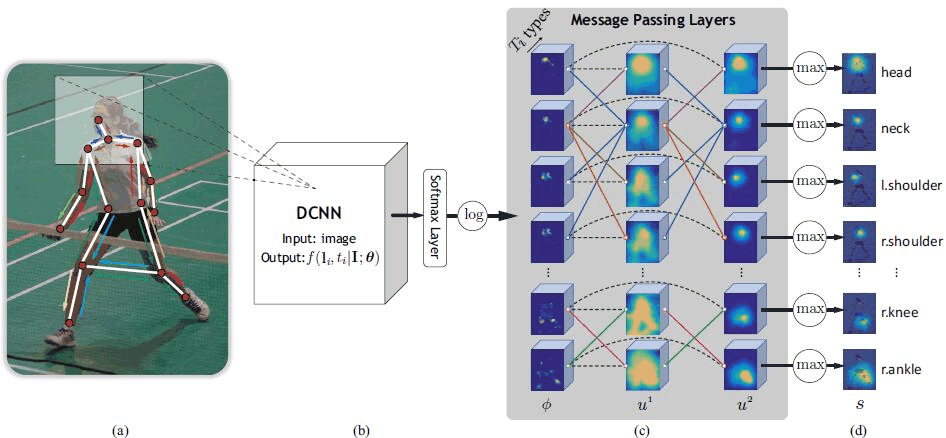
Human Pose Estimation with Deep Learning and Computer Vision A state-of-the-art implementation for human pose estimation and tracking, based on the DeeperCut and ArtTrack papers. Key Features and Techniques Deep Learning Architecture Backbone Network ResNet-101/ResNet-50 architecture ImageNet pre-training Dense prediction modifications 1/16th resolution feature maps TensorFlow Slim implementation Part Detection System Fully convolutional networks Body part confidence maps Joint location refinement Pairwise spatial relationships Multi-scale feature processing Training Innovations Advanced data augmentation Scale jittering (±15%) Random flips Global normalization Multi-stage learning Intermediate supervision Adaptive learning rates Batch normalization Computer Vision Components Multi-Person Processing Integer linear programming DeeperCut algorithm Anatomical constraint modeling Spatial relationship learning Detection Optimization Non-maximum suppression (NMS) Location refinement Multi-scale detection Joint relationship modeling Applications and Use Cases Sports Analytics Athlete performance analysis Movement pattern recognition Injury prevention Training optimization Healthcare Physical therapy monitoring Gait analysis Rehabilitation tracking Posture assessment Security and Surveillance Person tracking Behavior analysis Crowd monitoring Activity recognition Entertainment Motion capture Animation Gaming interfaces Virtual reality Virtual Clothing Try-On Real-time body measurements Accurate size estimation Virtual fitting room experience Custom garment recommendations Dynamic cloth simulation 3D body model generation Robotics Human-robot interaction Movement mimicking Safety monitoring Gesture recognition System Capabilities Single-Person Mode High-precision joint detection Real-time processing 14-point keypoint detection Robust to partial occlusion Multi-Person Mode Simultaneous multiple person tracking 17-point keypoint detection Handles person overlap Scale-invariant detection Performance Metrics PCK (Percentage of Correct Keypoints) MS COCO evaluation metrics Average Precision (AP) Average Recall (AR) Multiple IoU thresholds Quick Start Installation # Create Python environment conda create -n py36 python=3.6 conda activate py36 # Install dependencies conda install numpy scikit-image pillow scipy pyyaml matplotlib cython pip install tensorflow-gpu easydict munkres Running Demos # Single person detection cd models/mpii ./download_models.sh cd - TF_CUDNN_USE_AUTOTUNE=0 python3 demo/singleperson.py # Multi-person detection ./compile.sh cd models/coco ./download_models.sh cd - TF_CUDNN_USE_AUTOTUNE=0 python3 demo/demo_multiperson.py Dataset Support MPII Human Pose Dataset MS COCO Dataset Custom dataset training capability References Based on research from: DeeperCut (ECCV 2016) ArtTrack (CVPR 2017)
A state-of-the-art implementation for human pose estimation and tracking, based on the DeeperCut and ArtTrack papers.
# Create Python environment conda create -n py36 python=3.6 conda activate py36 # Install dependencies conda install numpy scikit-image pillow scipy pyyaml matplotlib cython pip install tensorflow-gpu easydict munkres
# Single person detection cd models/mpii ./download_models.sh cd - TF_CUDNN_USE_AUTOTUNE=0 python3 demo/singleperson.py # Multi-person detection ./compile.sh cd models/coco ./download_models.sh cd - TF_CUDNN_USE_AUTOTUNE=0 python3 demo/demo_multiperson.py
Human Pose Estimation Bible A Comprehensive Technical Reference — From Computer Vision Fundamentals to Modern Deep Learning and Real-World Applications This repository presents Human Pose Estimation Bible , a collaborative graduation-project technical reference that connects computer vision fundamentals, mathematical and geometric reasoning, deep-learning architectures, evaluation methodology, and practical inference pipelines. Across four chapters and three practical case studies, it demonstrates a research-oriented AI Engineering mindset—not simply a collection of pretrained-model demos. Read the Full HPE Bible Read the Full HPE Bible — PDF Editable / source document (DOCX) The PDF is the primary reading format; the DOCX is retained as the editable source version. Contents The Research Mindset Behind This Work Why This Technical Reference Exists Inside the Bible — Chapter by Chapter From Research to Real-World Implementation Comparing the Practical Approaches Skills and Technical Knowledge Demonstrated Read the Full HPE Bible Project Credits and Acknowledgments The Research Mindset Behind This Work I am Mostafa Khaled , a recent graduate pursuing opportunities in AI Engineering, Machine Learning, Data Science, and Computer Vision. I am developing as a research-oriented AI / Computer Vision Engineer because Human Pose Estimation exposes the full chain between visual evidence and structured understanding: pixels become features, features become anatomical keypoints, and keypoints must remain geometrically and temporally coherent. My interest is therefore not limited to calling a model API or running a pretrained checkpoint. I want to understand why different architectures work, how resolution and representation choices affect learning and inference, which assumptions break under occlusion or depth ambiguity, and how evaluation metrics should influence deployment decisions. This book was a collaborative graduation project; this repository is my portfolio-oriented presentation of that work and of the research-oriented engineering perspective I developed through it. Why This Technical Reference Exists Human Pose Estimation sits at the intersection of several disciplines: classical computer vision, 2D and 3D representations, deep learning, body modeling, geometric and kinematic reasoning, benchmarking, and practical video pipelines. These topics are often taught separately even though a production system must connect them. The reference was organized as a structured study that connects fundamentals, research evolution, modern architectures, and practical implementation—from skeletal and volumetric models, to coordinate regression and heatmaps, to multi-person association, temporal tracking, and deployment trade-offs. It offers broad coverage within its stated scope, but it is not intended to be an exhaustive survey of every HPE study or technique. What This Book Covers The four chapters move from the problem landscape and evaluation foundations, through classical and deep-learning approaches, to a taxonomy of representative architectures and three practical implementation case studies. The appendices preserve the detailed implementation material that would otherwise make a portfolio README difficult to scan. Inside the Bible — Chapter by Chapter Chapter 1 — Human Pose Estimation Landscape (HPE) Defines HPE and surveys applications in activity recognition, healthcare, robotics, animation, sports, safety, and human–computer interaction. It contrasts 2D and 3D pose, then examines occlusion, crowd complexity, depth ambiguity, scale and viewpoint variation, rare poses, annotation cost, privacy, adverse imaging conditions, and temporal inconsistency. The chapter also explains PCP, PCK, PDJ, MPJPE, OKS, AP, AR, AUC, and NME alongside benchmark datasets including MPII, COCO, LSP/LSPE, CrowdPose, Human3.6M, PoseTrack, AI Challenger, and 3DPW. Its key lesson is methodological: a score is meaningful only in the context of the dataset, representation, protocol, and metric that produced it. Chapter 2 — Human Pose Estimation Approaches Builds the modeling vocabulary needed to compare HPE systems: kinematic/skeleton-based, planar/part-based, and volumetric body models; classical and learning-based methods; coordinate regression versus heatmap localization; single-person versus multi-person estimation; and top-down versus bottom-up pipelines. For 3D HPE it covers monocular reconstruction, direct regression, 2D-to-3D lifting, volumetric heatmaps, parametric body models, and multi-view reasoning. The chapter matters because it frames architecture selection as a set of mathematical and engineering trade-offs rather than a search for one universally best model. Chapter 3 — HPE Using Deep Learning The central architecture-focused chapter studies CNN feature extraction, output representations, resolution recovery, skip connections, dilated convolutions, and multi-scale spatial reasoning. It then examines self- and cross-attention, Transformer backbones, Graph Neural Networks for skeletal structure and temporal reasoning, diffusion-based pose refinement and uncertainty, and emerging vision–language/LLM integration. The reader learns how each family addresses different limitations—localization precision, long-range context, structural consistency, ambiguity, or semantic conditioning. These subjects are analyzed in the book; they should not be read as claims that every architecture was independently implemented in the practical suite. Chapter 4 — Taxonomy of HPE Models & Practical Implementation Reviews representative systems including OpenPose, HRNet, YOLO-Pose/YOLOv8-Pose, RTMPose, ViTPose/ViTPose++, Human Mesh Recovery (HMR), PoseFormer, and MANO. It then introduces the HPE-Bible Project Suite and compares three implementation strategies. This chapter bridges model architecture study with engineering practice; Appendices A–C provide the detailed implementation material. From Research to Real-World Implementation The practical work explores different ways to solve different pose-estimation problems instead of treating one architecture as universal. Appendix A — Wide-Field Pose Estimation with YOLOv8 and Image Tiling Problem: Players in wide-field football broadcasts may occupy too few pixels for reliable fine-grained keypoint localization. Approach: Split each frame into a configurable grid, run YOLOv8-Pose on each tile, and remap local keypoints into the original coordinate system. The case study highlights tiling, coordinate offsets, small-subject localization, COCO’s 17-keypoint topology, and the resolution–compute trade-off. More spatial detail can help distant subjects, but grid size increases inference work and introduces boundary-truncation and merging concerns. Appendix B — Two-Stage Human Pose Estimation Problem: Accurate multi-person localization requires careful handling of detection, person crops, and pose inference. Pipeline: Input → YOLO person detection → bounding boxes → person crops → YOLOv8-Pose → keypoint visualization . The modular design separates detection from keypoint estimation, supports independent model sizing, filters low-quality detections, and can derive pose-based actions. Its trade-off is better per-person control at the cost of crop handling and additional computation. Appendix C — RTMPose with Multi-Person Tracking Problem: Video analysis must estimate keypoints while preserving identity across frames. Pipeline: Video frames → RTMDet → RTMPose → ByteTrack → visualization and tracking . The implementation combines OpenMMLab’s MMDetection and MMPose ecosystems with RTMPose’s coordinate-classification approach and ByteTrack’s multi-object association. It also documents practical integration concerns such as registry-scope management, track state, confidence thresholds, and temporal consistency. No independent FPS result is claimed here. Comparing the Practical Approaches Approach Primary objective Strategy Core frameworks Target use case Tracking Main trade-off YOLOv8 + tiling Recover detail for distant subjects Tile, infer locally, remap coordinates Ultralytics YOLOv8, OpenCV Wide-field sports and surveillance Not the central focus Better effective resolution, higher compute and boundary complexity YOLOv8 two-stage Improve per-person pose control Detect people, crop, then estimate pose YOLOv8, OpenCV Groups, action and fitness analysis Optional pipeline support Modular tuning and precision, but extra stages and crop overhead RTMPose + ByteTrack Efficient video pose with identity continuity Top-down detection, pose estimation, association MMDetection, MMPose, RTMPose, ByteTrack Multi-person football video and temporal analysis Integrated Strong pipeline coordination, dependency and integration complexity The right choice depends on subject scale, crowding, temporal requirements, hardware budget, and whether identity continuity matters. Architecture selection should follow the deployment constraint and evaluation protocol—not a generic assumption that one model is always superior. Skills and Technical Knowledge Demonstrated Scientific and research: literature synthesis, architecture analysis, metric and benchmark literacy, mathematical reasoning, and comparative methodology. Computer vision: 2D/3D HPE, object detection, keypoint localization, skeletal representation, video processing, and multi-person tracking. Deep learning: CNNs, Transformers, GNNs, diffusion models, and vision–language integration as studied in the reference. Engineering: modular inference pipelines, coordinate transformations, model integration, crop and bounding-box handling, tracking integration, and computational-efficiency reasoning. The practical suite specifically demonstrates YOLOv8-Pose, image tiling, two-stage detection/pose processing, RTMDet, RTMPose, ByteTrack, OpenCV, Ultralytics, MMDetection, and MMPose. GNNs, diffusion, Vision-Language Models, HMR, ViTPose, PoseFormer, and MANO are part of the technical study and taxonomy; their inclusion does not imply implementation in these three case studies. Book Navigation View the book cover Quick navigation: Chapter 1 — Landscape Chapter 2 — Approaches Chapter 3 — Deep Learning Chapter 4 — Taxonomy and Implementation Appendix A — Tiled YOLOv8 Appendix B — Two-stage YOLOv8 Appendix C — RTMPose and tracking The PDF is the recommended reading format. The DOCX remains available above for editing and source preservation. Project Credits and Acknowledgments The graduation project identifies the following contributors: Hadi Shaheen · Mostafa Khaled · Marawan Sitten · Mohamed Salah · Mosa Mohamed The collaborative source-code repository is HadiShaheen249/HPE-Bible . This repository is Mostafa Khaled’s portfolio presentation of the technical reference and the research-oriented experience developed through the project; it does not claim exclusive ownership of the team’s original implementations. Publication-Readiness Notes Before public release, review the bibliography and add complete, consistent citations for named methods, datasets, metrics, figures, and external model implementations. Also confirm usage rights and credits for the cover and embedded figures, and add a project/code license only when the contributors have authorization to do so. The README intentionally avoids unverified benchmark scores, FPS claims, citation counts, and claims of independent experiments. This work reflects how I approach Artificial Intelligence: understand the underlying science, compare alternative solutions critically, and translate that understanding into engineering decisions that can survive real-world constraints.
A Comprehensive Technical Reference — From Computer Vision Fundamentals to Modern Deep Learning and Real-World Applications
This repository presents Human Pose Estimation Bible , a collaborative graduation-project technical reference that connects computer vision fundamentals, mathematical and geometric reasoning, deep-learning architectures, evaluation methodology, and practical inference pipelines. Across four chapters and three practical case studies, it demonstrates a research-oriented AI Engineering mindset—not simply a collection of pretrained-model demos.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
The PDF is the primary reading format; the DOCX is retained as the editable source version.
I am Mostafa Khaled , a recent graduate pursuing opportunities in AI Engineering, Machine Learning, Data Science, and Computer Vision. I am developing as a research-oriented AI / Computer Vision Engineer because Human Pose Estimation exposes the full chain between visual evidence and structured understanding: pixels become features, features become anatomical keypoints, and keypoints must remain geometrically and temporally coherent.
My interest is therefore not limited to calling a model API or running a pretrained checkpoint. I want to understand why different architectures work, how resolution and representation choices affect learning and inference, which assumptions break under occlusion or depth ambiguity, and how evaluation metrics should influence deployment decisions. This book was a collaborative graduation project; this repository is my portfolio-oriented presentation of that work and of the research-oriented engineering perspective I developed through it.
Human Pose Estimation sits at the intersection of several disciplines: classical computer vision, 2D and 3D representations, deep learning, body modeling, geometric and kinematic reasoning, benchmarking, and practical video pipelines. These topics are often taught separately even though a production system must connect them.
The reference was organized as a structured study that connects fundamentals, research evolution, modern architectures, and practical implementation—from skeletal and volumetric models, to coordinate regression and heatmaps, to multi-person association, temporal tracking, and deployment trade-offs. It offers broad coverage within its stated scope, but it is not intended to be an exhaustive survey of every HPE study or technique.
The four chapters move from the problem landscape and evaluation foundations, through classical and deep-learning approaches, to a taxonomy of representative architectures and three practical implementation case studies. The appendices preserve the detailed implementation material that would otherwise make a portfolio README difficult to scan.
Defines HPE and surveys applications in activity recognition, healthcare, robotics, animation, sports, safety, and human–computer interaction. It contrasts 2D and 3D pose, then examines occlusion, crowd complexity, depth ambiguity, scale and viewpoint variation, rare poses, annotation cost, privacy, adverse imaging conditions, and temporal inconsistency. The chapter also explains PCP, PCK, PDJ, MPJPE, OKS, AP, AR, AUC, and NME alongside benchmark datasets including MPII, COCO, LSP/LSPE, CrowdPose, Human3.6M, PoseTrack, AI Challenger, and 3DPW. Its key lesson is methodological: a score is meaningful only in the context of the dataset, representation, protocol, and metric that produced it.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
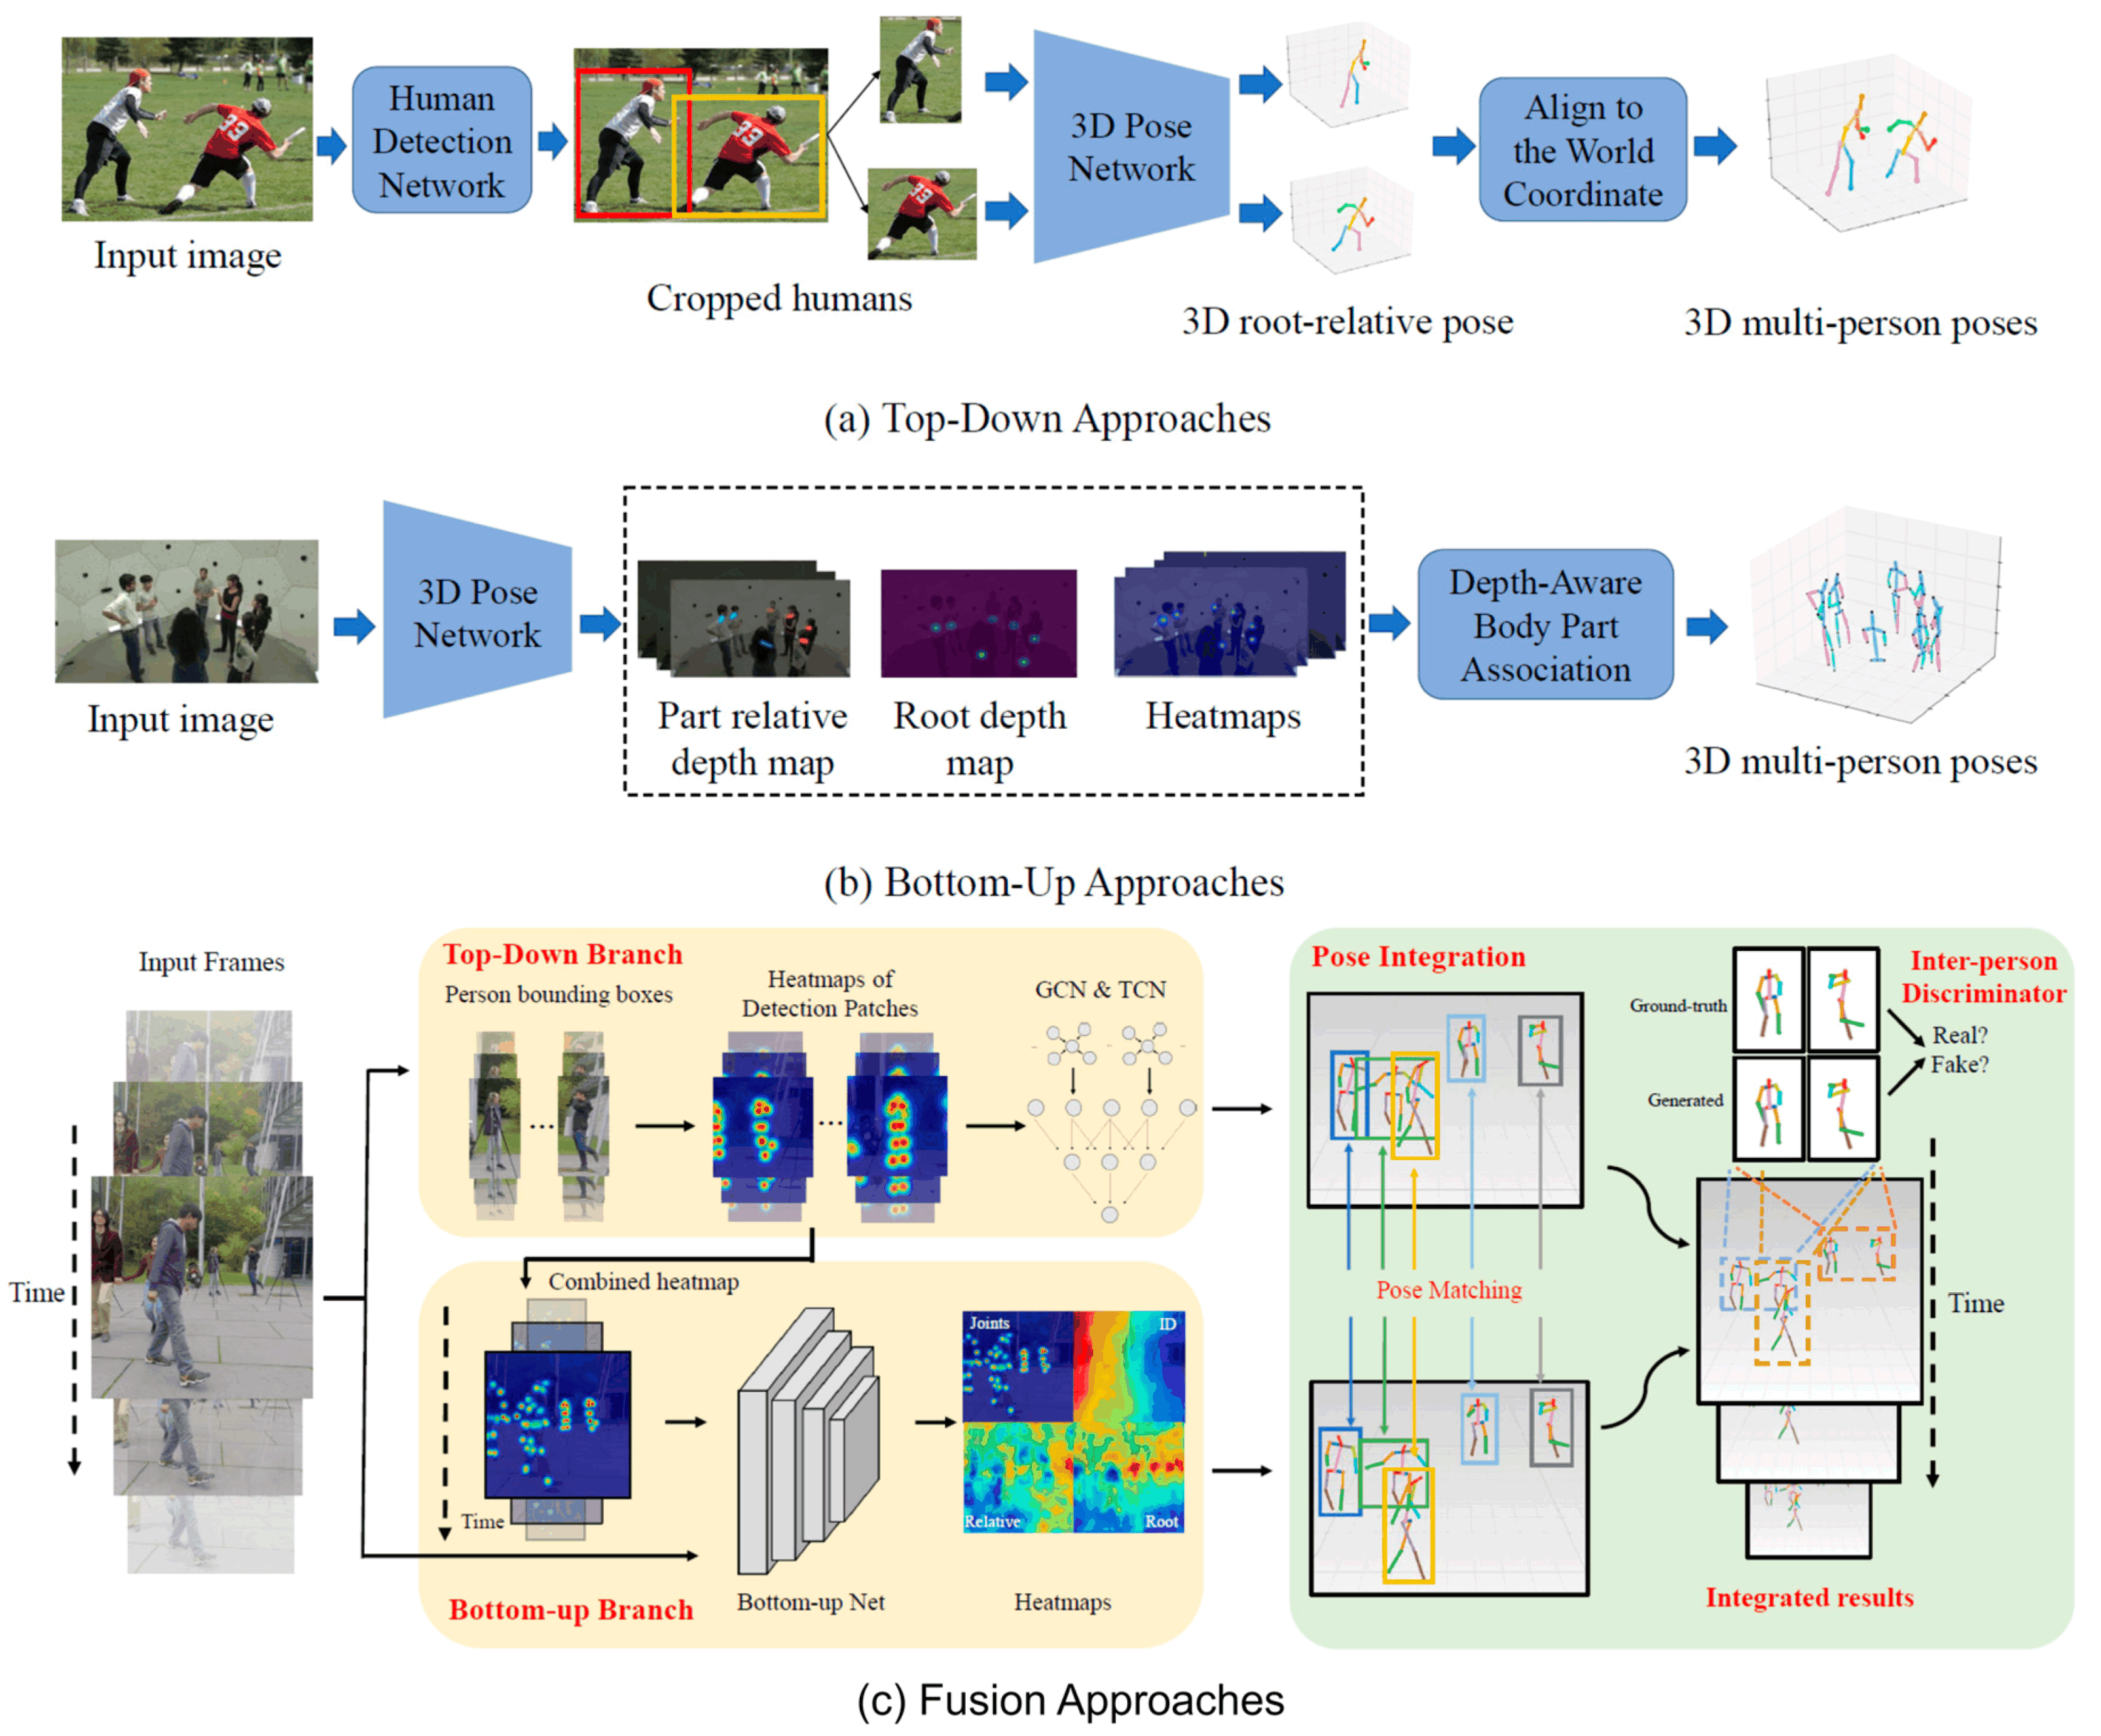
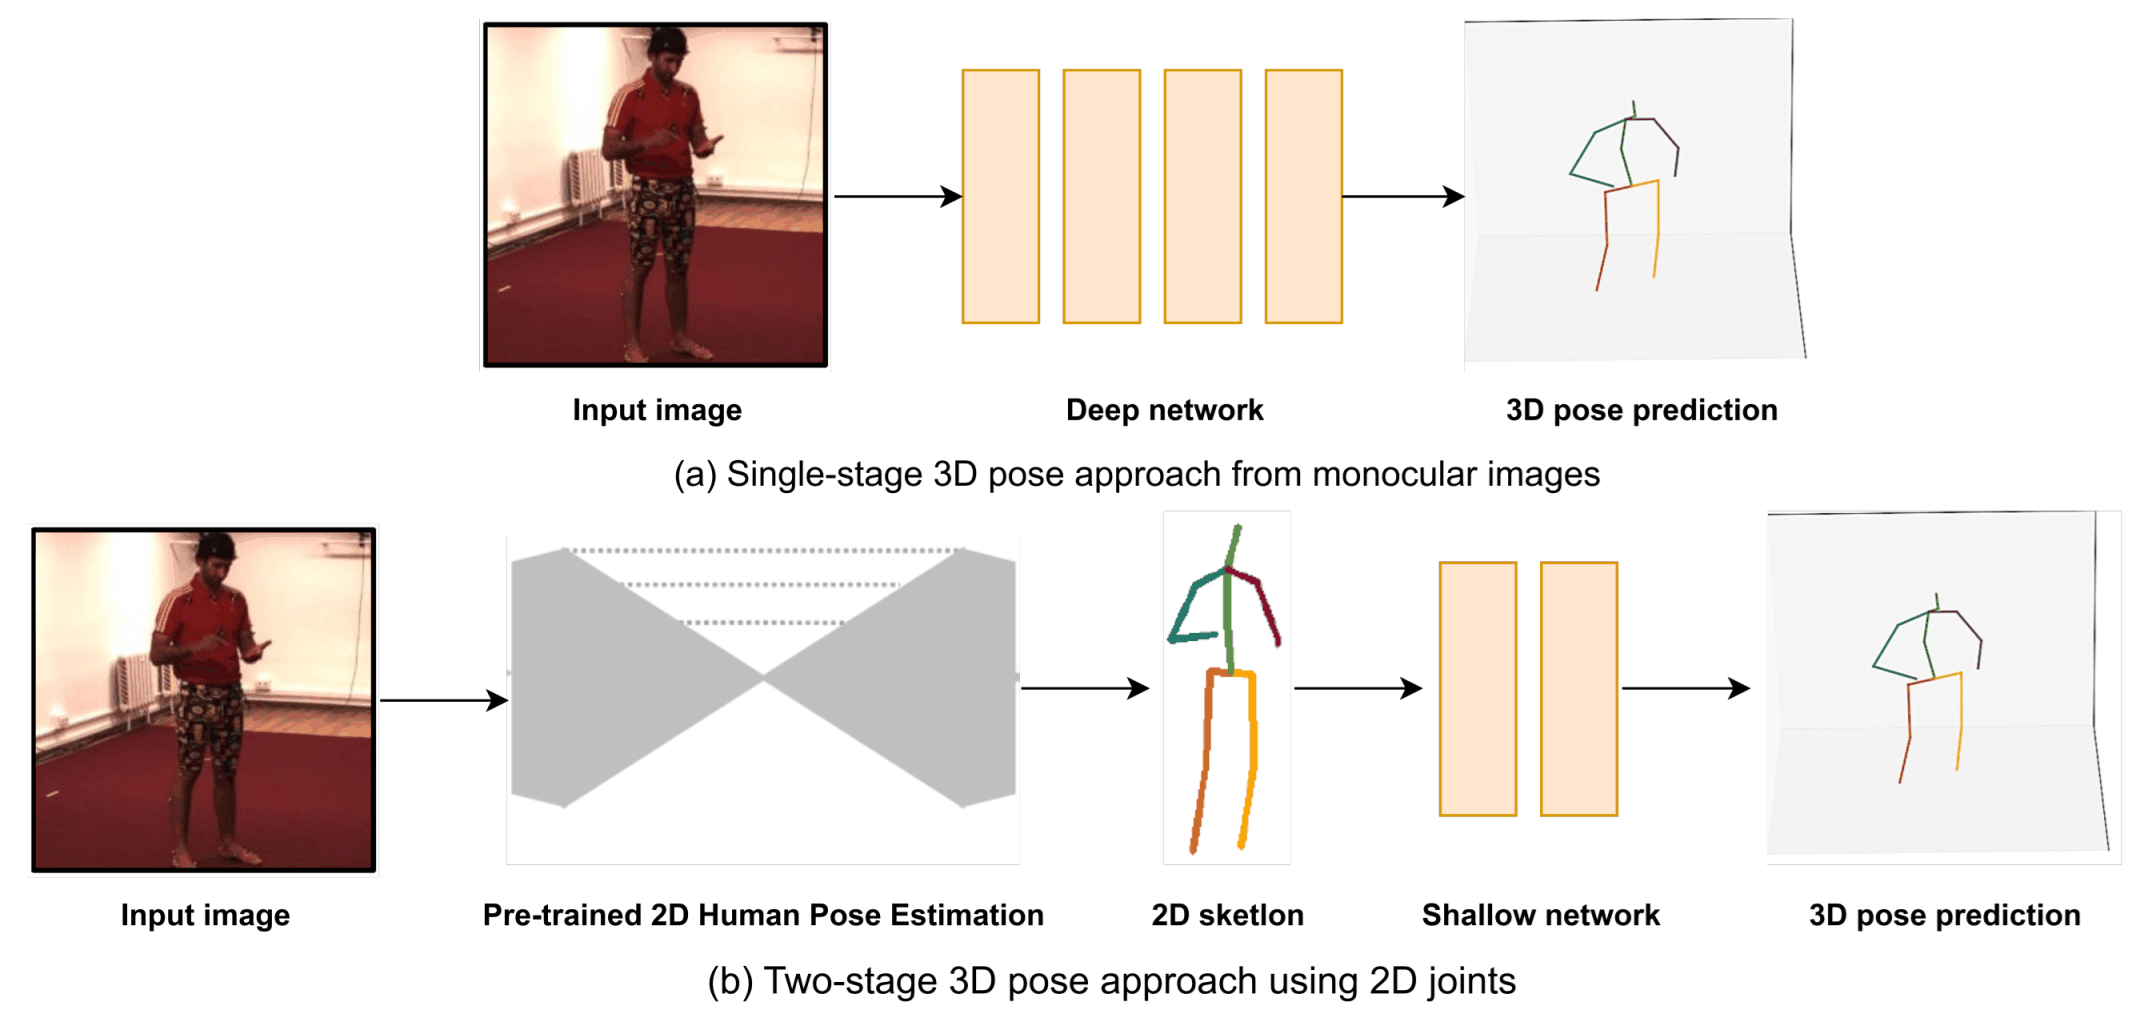
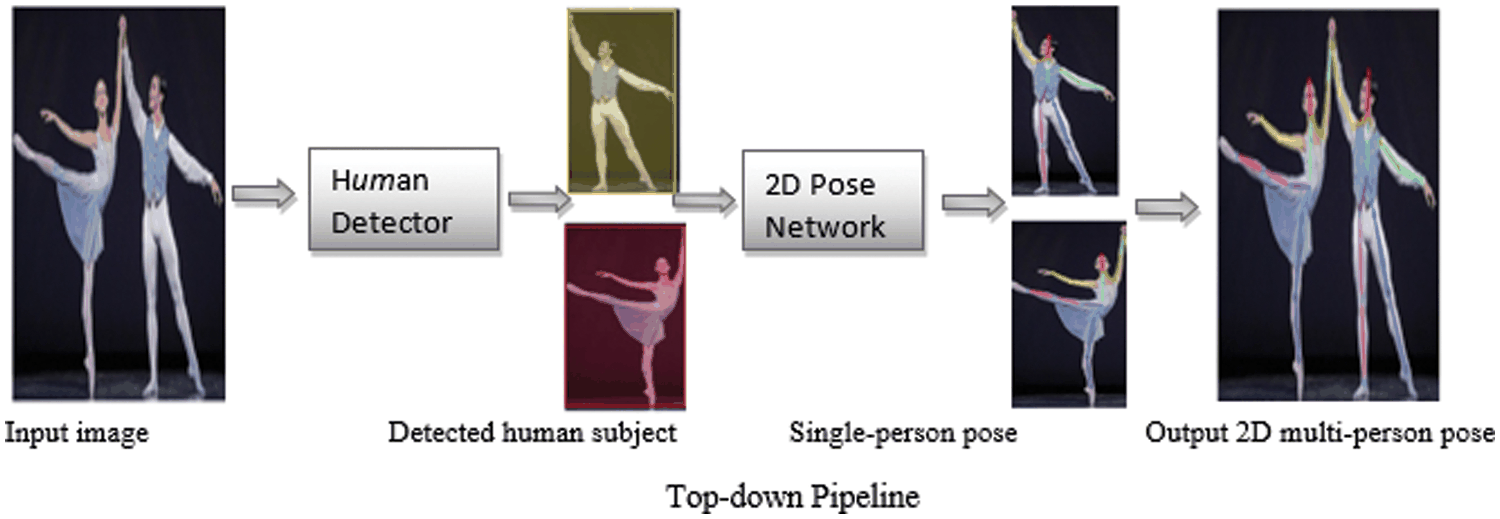
Builds the modeling vocabulary needed to compare HPE systems: kinematic/skeleton-based, planar/part-based, and volumetric body models; classical and learning-based methods; coordinate regression versus heatmap localization; single-person versus multi-person estimation; and top-down versus bottom-up pipelines. For 3D HPE it covers monocular reconstruction, direct regression, 2D-to-3D lifting, volumetric heatmaps, parametric body models, and multi-view reasoning. The chapter matters because it frames architecture selection as a set of mathematical and engineering trade-offs rather than a search for one universally best model.
The central architecture-focused chapter studies CNN feature extraction, output representations, resolution recovery, skip connections, dilated convolutions, and multi-scale spatial reasoning. It then examines self- and cross-attention, Transformer backbones, Graph Neural Networks for skeletal structure and temporal reasoning, diffusion-based pose refinement and uncertainty, and emerging vision–language/LLM integration. The reader learns how each family addresses different limitations—localization precision, long-range context, structural consistency, ambiguity, or semantic conditioning. These subjects are analyzed in the book; they should not be read as claims that every architecture was independently implemented in the practical suite.
Reviews representative systems including OpenPose, HRNet, YOLO-Pose/YOLOv8-Pose, RTMPose, ViTPose/ViTPose++, Human Mesh Recovery (HMR), PoseFormer, and MANO. It then introduces the HPE-Bible Project Suite and compares three implementation strategies. This chapter bridges model architecture study with engineering practice; Appendices A–C provide the detailed implementation material.
The practical work explores different ways to solve different pose-estimation problems instead of treating one architecture as universal.
Problem: Players in wide-field football broadcasts may occupy too few pixels for reliable fine-grained keypoint localization. Approach: Split each frame into a configurable grid, run YOLOv8-Pose on each tile, and remap local keypoints into the original coordinate system. The case study highlights tiling, coordinate offsets, small-subject localization, COCO’s 17-keypoint topology, and the resolution–compute trade-off. More spatial detail can help distant subjects, but grid size increases inference work and introduces boundary-truncation and merging concerns.
Problem: Accurate multi-person localization requires careful handling of detection, person crops, and pose inference. Pipeline: Input → YOLO person detection → bounding boxes → person crops → YOLOv8-Pose → keypoint visualization . The modular design separates detection from keypoint estimation, supports independent model sizing, filters low-quality detections, and can derive pose-based actions. Its trade-off is better per-person control at the cost of crop handling and additional computation.
Problem: Video analysis must estimate keypoints while preserving identity across frames. Pipeline: Video frames → RTMDet → RTMPose → ByteTrack → visualization and tracking . The implementation combines OpenMMLab’s MMDetection and MMPose ecosystems with RTMPose’s coordinate-classification approach and ByteTrack’s multi-object association. It also documents practical integration concerns such as registry-scope management, track state, confidence thresholds, and temporal consistency. No independent FPS result is claimed here.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
The right choice depends on subject scale, crowding, temporal requirements, hardware budget, and whether identity continuity matters. Architecture selection should follow the deployment constraint and evaluation protocol—not a generic assumption that one model is always superior.
The practical suite specifically demonstrates YOLOv8-Pose, image tiling, two-stage detection/pose processing, RTMDet, RTMPose, ByteTrack, OpenCV, Ultralytics, MMDetection, and MMPose. GNNs, diffusion, Vision-Language Models, HMR, ViTPose, PoseFormer, and MANO are part of the technical study and taxonomy; their inclusion does not imply implementation in these three case studies.
The PDF is the recommended reading format. The DOCX remains available above for editing and source preservation.
The collaborative source-code repository is HadiShaheen249/HPE-Bible . This repository is Mostafa Khaled’s portfolio presentation of the technical reference and the research-oriented experience developed through the project; it does not claim exclusive ownership of the team’s original implementations.
Before public release, review the bibliography and add complete, consistent citations for named methods, datasets, metrics, figures, and external model implementations. Also confirm usage rights and credits for the cover and embedded figures, and add a project/code license only when the contributors have authorization to do so. The README intentionally avoids unverified benchmark scores, FPS claims, citation counts, and claims of independent experiments.
This work reflects how I approach Artificial Intelligence: understand the underlying science, compare alternative solutions critically, and translate that understanding into engineering decisions that can survive real-world constraints.
Comprehensive Human Pose Estimation technical reference covering 2D/3D HPE, modern deep learning architectures, evaluation, and practical Computer Vision implementations.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)