Complete Technical Paper Content — Question Answering System Ai
1. Executive Abstract, Problem Formulation & Background
Question answering (QA) is a computer science discipline within the fields of information retrieval and natural language processing (NLP) that is concerned with building systems that automatically answer questions that are posed by humans in a natural language. A question-answering implementation, usually a computer program, may construct its answers by querying a structured database of knowledge or information, usually a knowledge base. More commonly, question-answering systems can pull answers from an unstructured collection of natural language documents. Some examples of natural language document collections used for question answering systems include reference texts, compiled newswire reports, Wikipedia pages and other World Wide Web pages.
interactivity—clarification of questions or answers answer reuse or caching semantic parsing answer presentation knowledge representation and semantic entailment social media analysis with question answering systems sentiment analysis utilization of thematic roles Image captioning for visual question answering Embodied question answering In 2011, Watson, a question answering computer system developed by IBM, competed in two exhibition matches of Jeopardy! against Brad Rutter and Ken Jennings, winning by a significant margin. Facebook Research made their DrQA system available under an open source license. This system uses Wikipedia as knowledge source. The open source framework Haystack by deepset combines open-domain question answering with generative question answering and supports the domain adaptation of the underlying language models for industry use cases. Large Language Models (LLMs)[36] like GPT-4[37], Gemini[38] are examples of successful QA systems that are enabling more sophisticated understanding and generation of text. When coupled with Multimodal[39] QA Systems, which can process and understand information from various modalities like text, images, and audio, LLMs significantly improve the capabilities of QA systems.
2. Related Work, Literature Survey & Algorithmic Foundations
Answering questions related to an article in order to evaluate reading comprehension is one of the simpler form of question answering, since a given article is relatively short compared to the domains of other types of question-answering problems. An example of such a question is "What did Albert Einstein win the Nobel Prize for?" after an article about this subject is given to the system. Closed-book question answering is when a system has memorized some facts during training and can answer questions without explicitly being given a context. This is similar to humans taking closed-book exams. Closed-domain question answering deals with questions under a specific domain (for example, medicine or automotive maintenance) and can exploit domain-specific knowledge frequently formalized in ontologies. Alternatively, "closed-domain" might refer to a situation where only a limited type of questions are accepted, such as questions asking for descriptive rather than procedural information. Question answering systems in the context of machine reading applications have also been constructed in the medical domain, for instance related to Alzheimer's disease. Open-domain question answering deals with questions about nearly anything and can only rely on general ontologies and world knowledge. Systems designed for open-domain question answering usually have much more data available from which to extract the answer. An example of an open-domain question is "What did Albert Einstein win the Nobel Prize for?" while no article about this subject is given to the system. Another way to categorize question-answering systems is by the technical approach used. There are a number of different types of QA systems, including:
rule-based systems, statistical systems, hybrid systems, and knowledge graph-based systems. Rule-based systems use a set of rules to determine the correct answer to a question. Statistical systems use statistical methods to find the most likely answer to a question. Hybrid systems use a combination of rule-based and statistical methods. Knowledge-graph-based systems identify relevant entities and relations in a knowledge graph using similarity measures or queries expressed in languages such as SPARQL.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
If the right information appears in many forms, the question answering system needs to perform fewer complex NLP techniques to understand the text. Correct answers can be filtered from false positives because the system can rely on versions of the correct answer appearing more times in the corpus than incorrect ones. Some question answering systems rely heavily on automated reasoning.
In information retrieval, an open-domain question answering system tries to return an answer in response to the user's question. The returned answer is in the form of short texts rather than a list of relevant documents. The system finds answers by using a combination of techniques from computational linguistics, information retrieval, and knowledge representation. The system takes a natural language question as an input rather than a set of keywords, for example: "When is the national day of China?" It then transforms this input sentence into a query in its logical form. Accepting natural language questions makes the system more user-friendly, but harder to implement, as there are a variety of question types and the system will have to identify the correct one in order to give a sensible answer. Assigning a question type to the question is a crucial task; the entire answer extraction process relies on finding the correct question type and hence the correct answer type. Keyword extraction is the first step in identifying the input question type. In some cases, words clearly indicate the question type, e.g., "Who", "Where", "When", or "How many"—these words might suggest to the system that the answers should be of type "Person", "Location", "Date", or "Number", respectively. POS (part-of-speech) tagging and syntactic parsing techniques can also determine the answer type. In the example above, the subject is "Chinese National Day", the predicate is "is" and the adverbial modifier is "when", therefore the answer type is "Date". Unfortunately, some interrogative words like "Which", "What", or "How" do not correspond to unambiguous answer types: Each can represent more than one type. In situations like this, other words in the question need to be considered. A lexical dictionary such as WordNet can be used for understanding the context. Once the system identifies the question type, it uses an information retrieval system to find a set of documents that contain the correct keywords. A tagger and NP/Verb Group chunker can verify whether the correct entities and relations are mentioned in the found documents. For questions such as "Who" or "Where", a named-entity recogniser finds relevant "Person" and "Location" names from the retrieved documents. Only the relevant paragraphs are selected for ranking. A vector space model can classify the candidate answers. Check if the answer is of the correct type as determined in the question type analysis stage. An inference technique can validate the candidate answers. A score is then given to each of these candidates according to the number of question words it contains and how close these words are to the candidate—the more and the closer the better. The answer is then translated by parsing into a compact and meaningful representation. In the previous example, the expected output answer is "1st Oct."
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Fact-checking if a fact is verified, by posing a question like: is fact X true or false? Customer service, Technical support, Market research, Natural language generation of reports or research.
Jev is a proprietary artificial intelligence model developed by TypeSafe AI, a San Francisco–based company founded in 2024. It was released in limited early access on 15 September 2026, alongside the announcement of a US$40 million seed round led by DCVC. Jev is a discriminative model: it is used for classification or regression, not generation. It does not generate natural-language text. It instead returns typed values together with probability estimates and confidence scores. Its output is intended to be consumed directly by software rather than read by a person. Unlike classical discriminative models, Jev does not require data-specific training. Like generative pretrained transformer models, it can perform zero-shot learning of input for categories provided at inference time, based on contextual information provided. TypeSafe describes Jev as the first of a class of models it calls "System One models", a name the company says comes from fast, intuitive System 1 thinking as popularized by Daniel Kahneman.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
A state is an entry. An entry is a string, JSON object, or array of string. Examples:A question is a JSON object. Jev allows three types of questions, all multiple-choice.
Schematically: If the state is a JSON object, the question can also refer to attributes of the state. For example:
Model Figures & Evaluation Curves (4 Images)
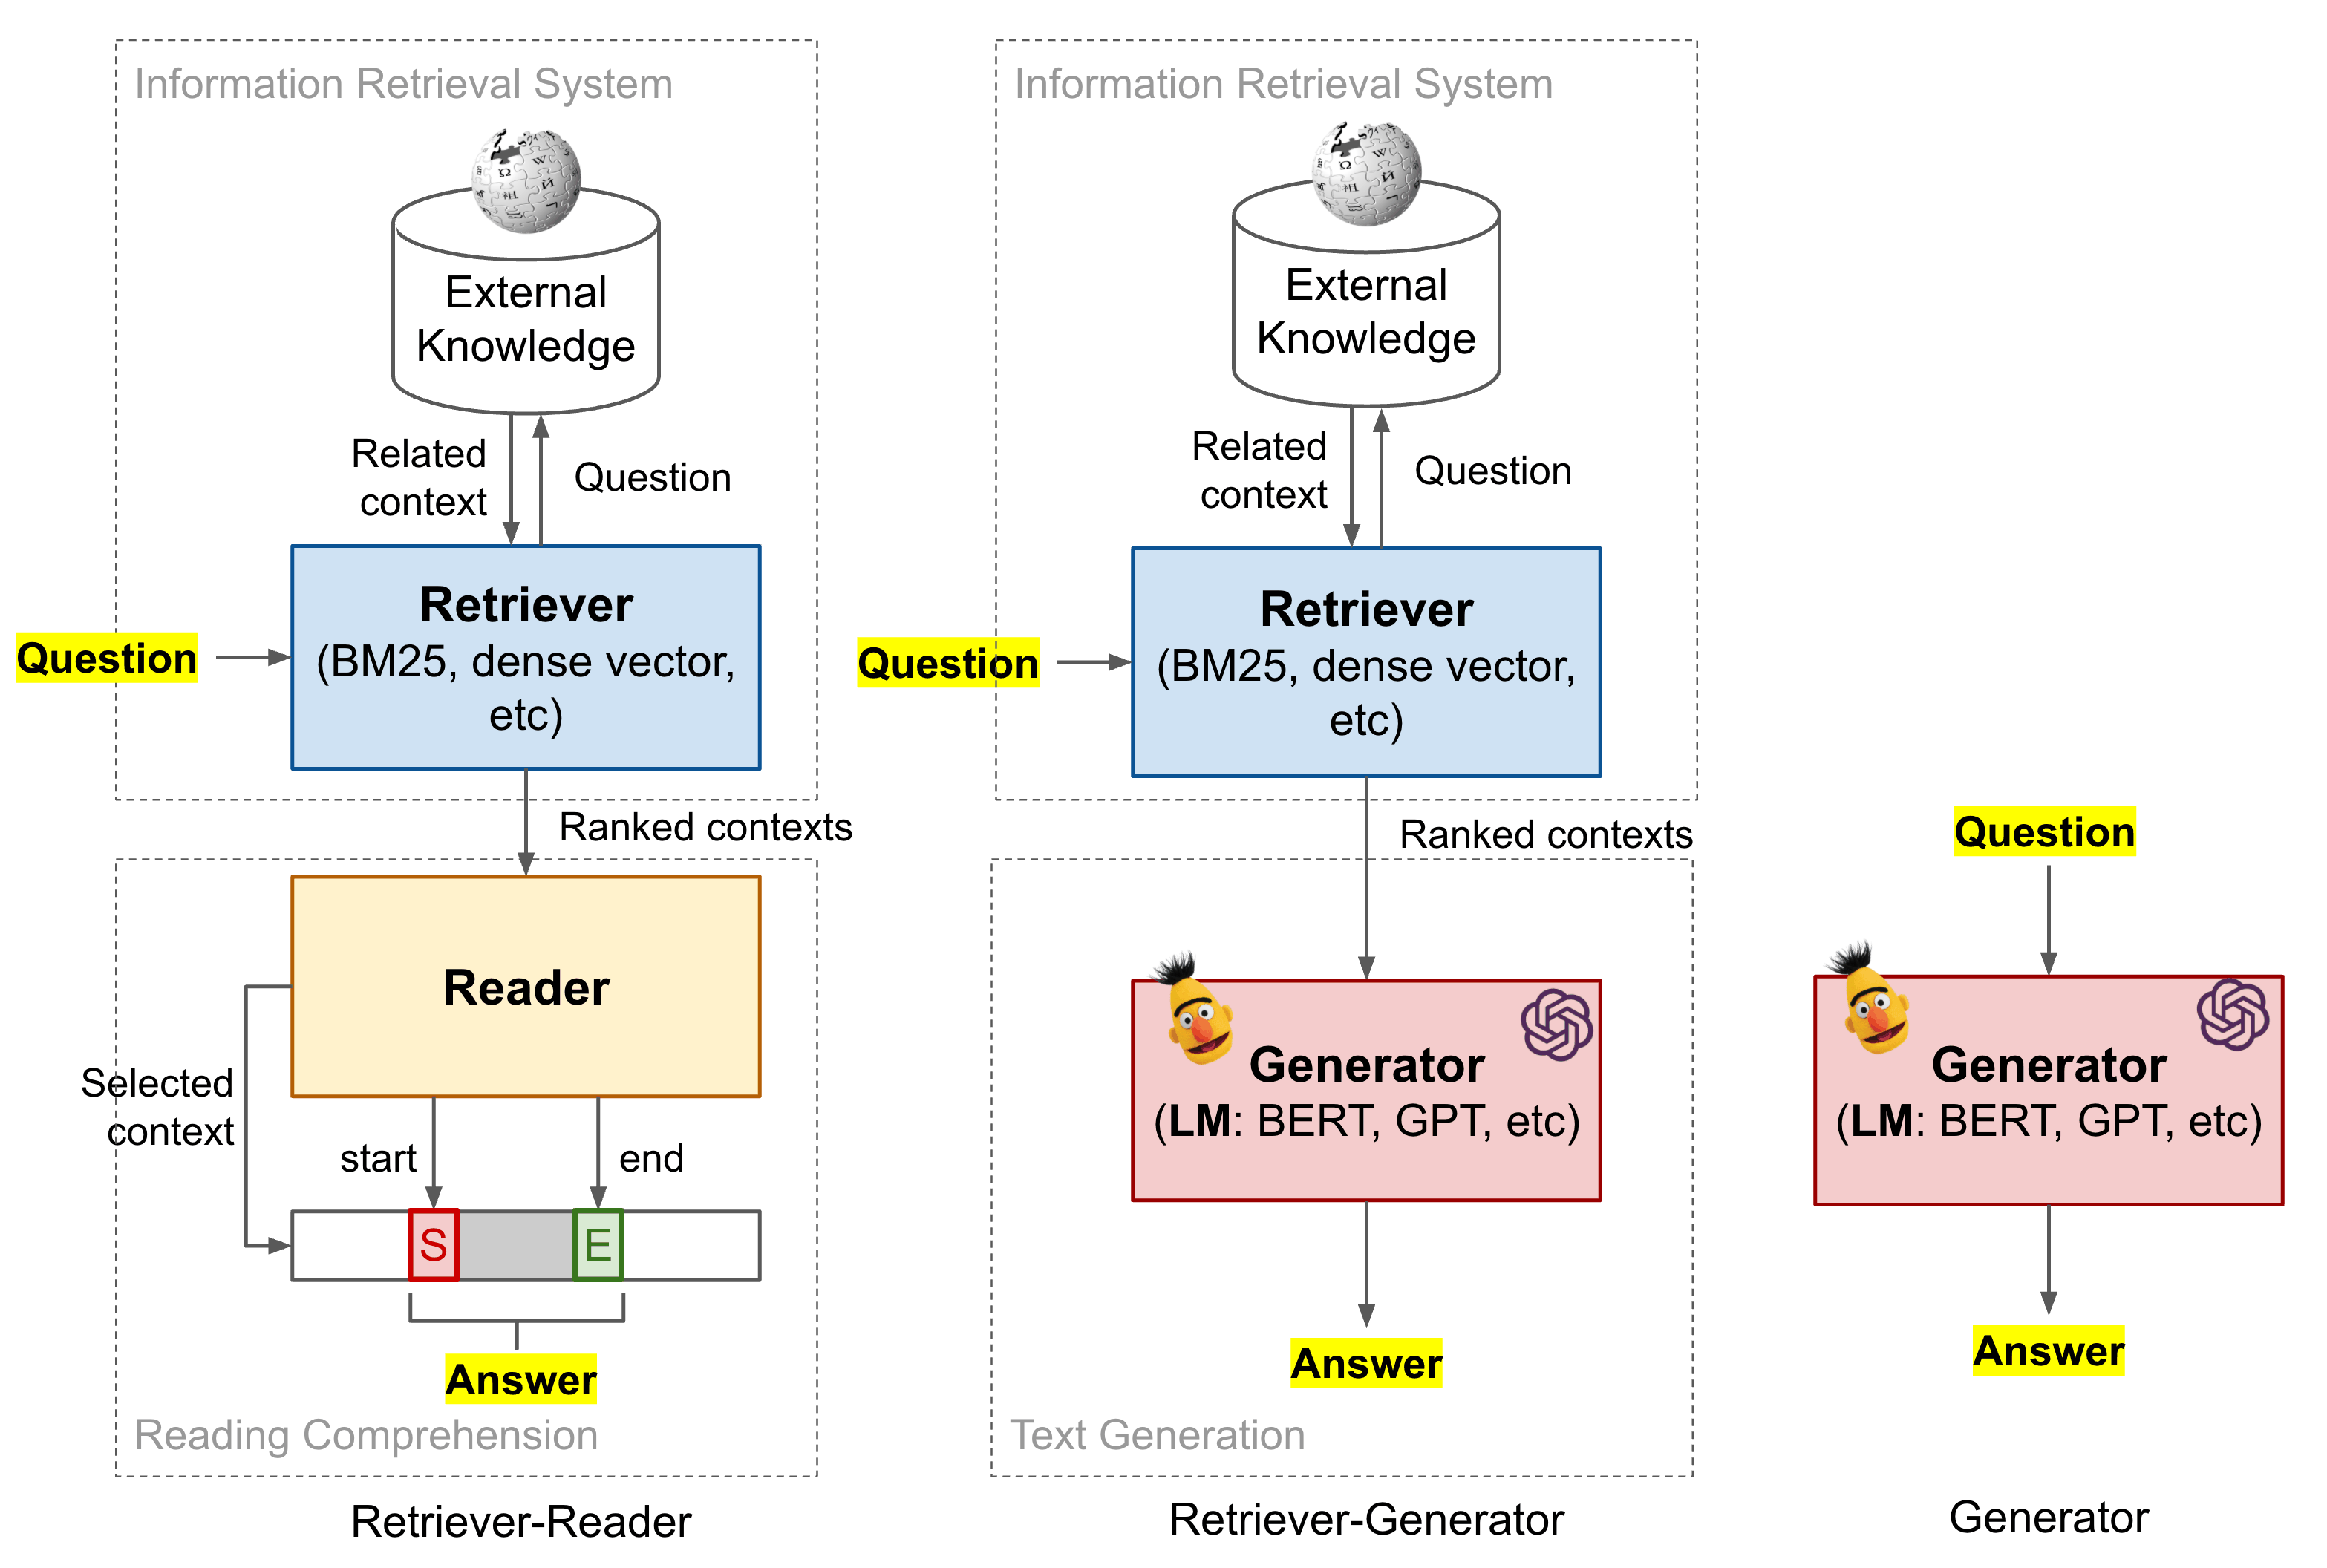
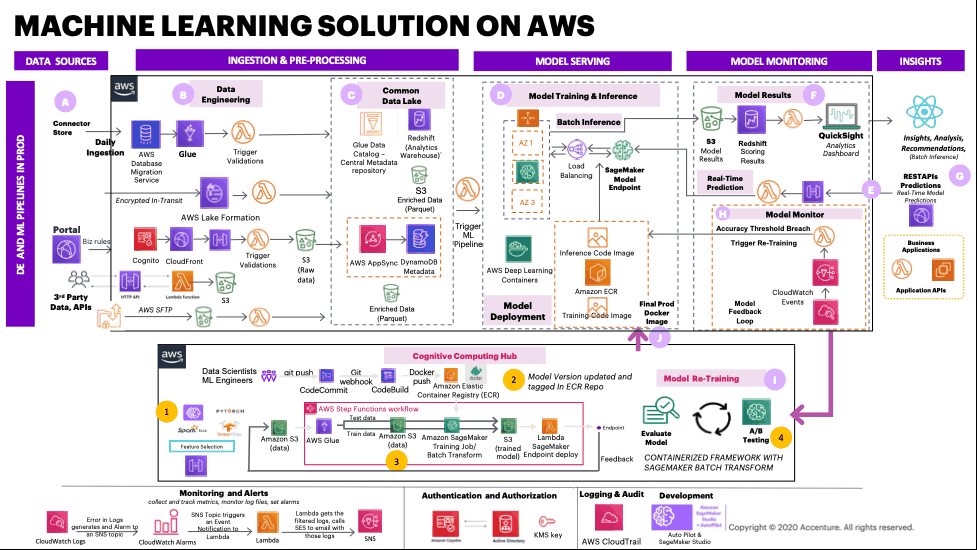
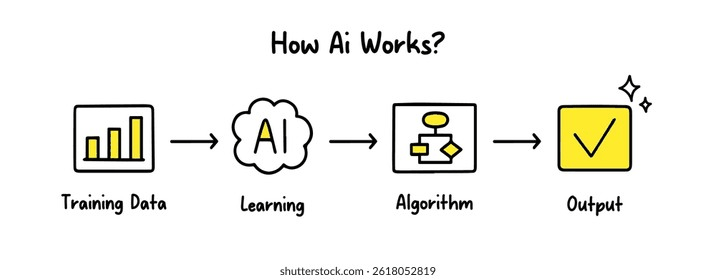
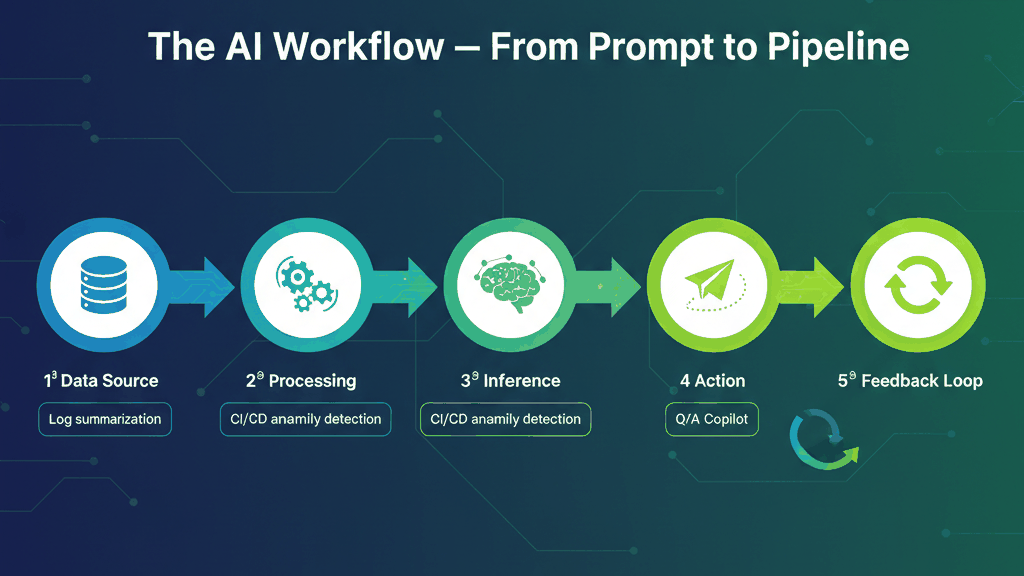
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)