Complete Technical Paper Content — Rag Retrieval Augmented Generation
1. Executive Abstract, Problem Formulation & Background
Prompt engineering is the process of structuring natural language inputs (known as prompts) to produce specified outputs from a generative AI model. Context engineering is the related area of software engineering that focuses on the management of non-prompt and prompt contexts supplied to the GenAI model, such as system instructions, metadata, API tools and tokens. It can also be defined as the practice of designing and refining input instructions given to a generative AI model to produce more accurate, relevant, or useful outputs. Effective prompt engineering involves understanding how a model interprets language, and may include techniques such as few-shot prompting, chain-of-thought prompting, and role assignment. During the 2020s AI boom, prompt engineering became regarded as a business capability across corporations and industries. Employees with the title prompt engineer were hired to create prompts that would increase productivity and efficacy, although the individual title has since become less common amid AI models that produce better prompts than humans and corporate training in prompting for general employees. Common prompting techniques include multi-shot, chain-of-thought, and tree-of-thought prompting, as well as assigning roles to the model. Automated prompt generation methods, such as retrieval-augmented generation (RAG), provide for greater accuracy and a wider scope of functions for prompt engineers. Prompt injection is a type of cybersecurity attack that targets machine learning models through malicious prompts.
Chain-of-thought (CoT) prompting is a technique that allows large language models (LLMs) to solve a problem as a series of intermediate steps before giving a final answer. In 2022, Google Brain reported that chain-of-thought prompting improves reasoning ability by inducing the model to answer a multi-step problem with steps of reasoning that mimic a train of thought. Chain-of-thought techniques were developed to help LLMs handle multi-step reasoning tasks, such as arithmetic or commonsense reasoning questions. When applied to PaLM, a 540 billion parameter language model, according to Google, CoT prompting significantly aided the model, allowing it to perform comparably with task-specific fine-tuned models on several tasks, achieving state-of-the-art results at the time on the GSM8K mathematical reasoning benchmark. It is possible to fine-tune models on CoT reasoning datasets to enhance this capability further and stimulate better interpretability. As originally proposed by Google, each CoT prompt is accompanied by a set of input/output examples—called exemplars—to demonstrate the desired model output, making it a few-shot prompting technique. However, according to a later paper from researchers at Google and the University of Tokyo, simply appending the words "Let's think step-by-step" was also effective, which allowed for CoT to be employed as a zero-shot technique. The benefits of chain-of-thought prompting vary considerably by task type. A meta-analysis covering more than 100 studies of CoT found that it delivers large gains primarily on mathematical, logical and symbolic reasoning problems, with much smaller improvements on other kinds of task, and concluded that CoT can be applied selectively in order to reduce inference costs. On tasks drawn from cognitive psychology in which deliberation is known to impair human performance, CoT has been found to reduce the accuracy of state-of-the-art models, in some cases substantially. A systematic review of structured prompting techniques similarly reports that the additional reasoning steps increase response times and interaction complexity, so that the technique is not uniformly preferable to simpler prompts for factual or low-complexity queries.
2. Related Work, Literature Survey & Algorithmic Foundations
In 2022, text-to-image models like DALL-E 2, Stable Diffusion, and Midjourney were released to the public. These models take text prompts as input and use them to generate images. Early text-to-image models typically do not understand negation, grammar and sentence structure in the same way as large language models, and may thus require a different set of prompting techniques. The prompt "a party with no cake" may produce an image including a cake.
A text-to-image prompt commonly includes a description of the subject of the art, the desired medium (such as digital painting or photography), style (such as hyperrealistic or pop-art), lighting (such as rim lighting or crepuscular rays), color, and texture. Word order also affects the output of a text-to-image prompt. Words closer to the start of a prompt may be emphasized more heavily.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
GraphRAG (coined by Microsoft Research) is a technique that extends RAG with the use of a knowledge graph to allow the model to connect disparate pieces of information, synthesize insights, and understand summarized semantic concepts over large data collections. It was shown to be effective on datasets like the Violent Incident Information from News Articles.
There are two LLMs. One is the target LLM, and another is the prompting LLM. Prompting LLM is presented with example input-output pairs, and asked to generate instructions that could have caused a model following the instructions to generate the outputs, given the inputs. Each of the generated instructions is used to prompt the target LLM, followed by each of the inputs. The log-probabilities of the outputs are computed and added. This is the score of the instruction. The highest-scored instructions are given to the prompting LLM for further variations. Repeat until some stopping criteria is reached, then output the highest-scored instructions. CoT examples can be generated by LLM themselves. In "auto-CoT", a library of questions are converted to vectors by a model such as BERT. The question vectors are clustered. Questions close to the centroid of each cluster are selected, in order to have a subset of diverse questions. An LLM does zero-shot CoT on each selected question. The question and the corresponding CoT answer are added to a dataset of demonstrations. These diverse demonstrations can then added to prompts for few-shot learning.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
MIPRO (Multi-prompt Instruction Proposal Optimizer) optimizes the instructions and few-shot demonstrations of multi-stage language model programs, proposing small changes to module prompts and retaining those that improve a downstream performance metric without access to module-level labels or gradients. GEPA (Genetic-Pareto) is a reflective prompt optimizer for compound AI systems that combines language-model-based analysis of execution traces and textual feedback with a Pareto-based evolutionary search over a population of candidate systems; across four tasks, GEPA reports average gains of about 10% over reinforcement-learning-based Group Relative Policy Optimization (GRPO) and over 10% over the MIPROv2 prompt optimizer, while using up to 35 times fewer rollouts than GRPO. Open-source frameworks such as DSPy and Opik expose these and related optimizers, allowing prompt search to be expressed as part of a programmatic pipeline rather than through manual trial and error.
Prompt injection is a cybersecurity exploit in which adversaries craft inputs that appear legitimate but are designed to cause unintended behavior in machine learning models, particularly large language models. This attack takes advantage of the model's inability to distinguish between developer-defined prompts and user inputs, allowing adversaries to bypass safeguards and influence model behaviour. While LLMs are designed to follow trusted instructions, they can be manipulated into carrying out unintended responses through carefully crafted inputs.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
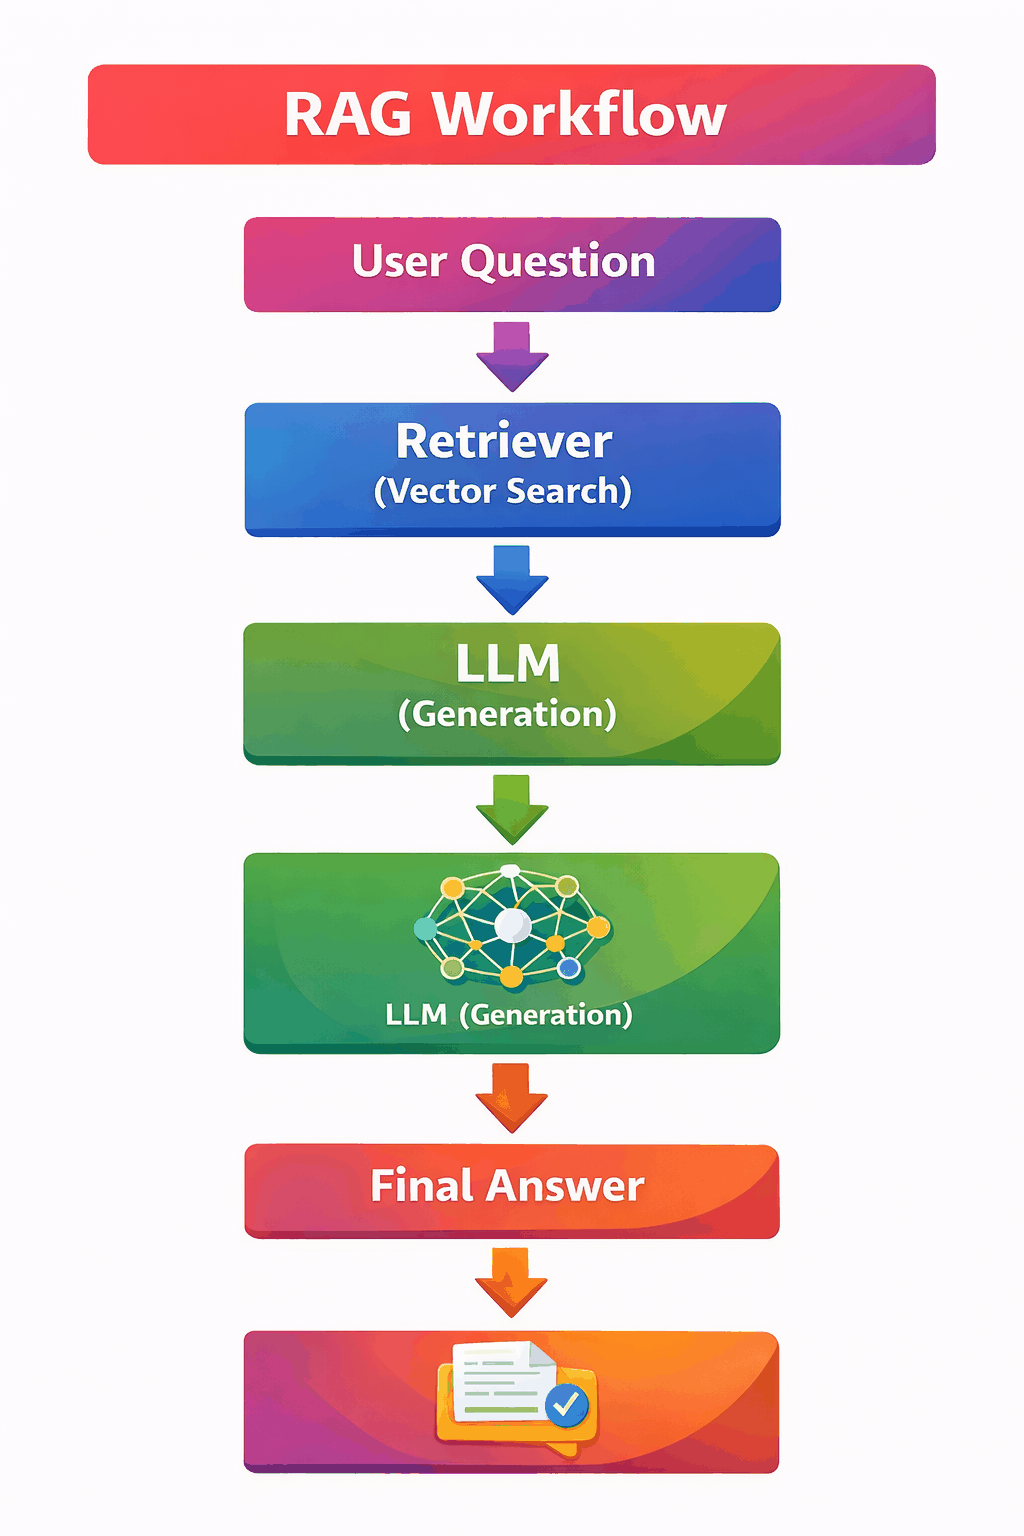
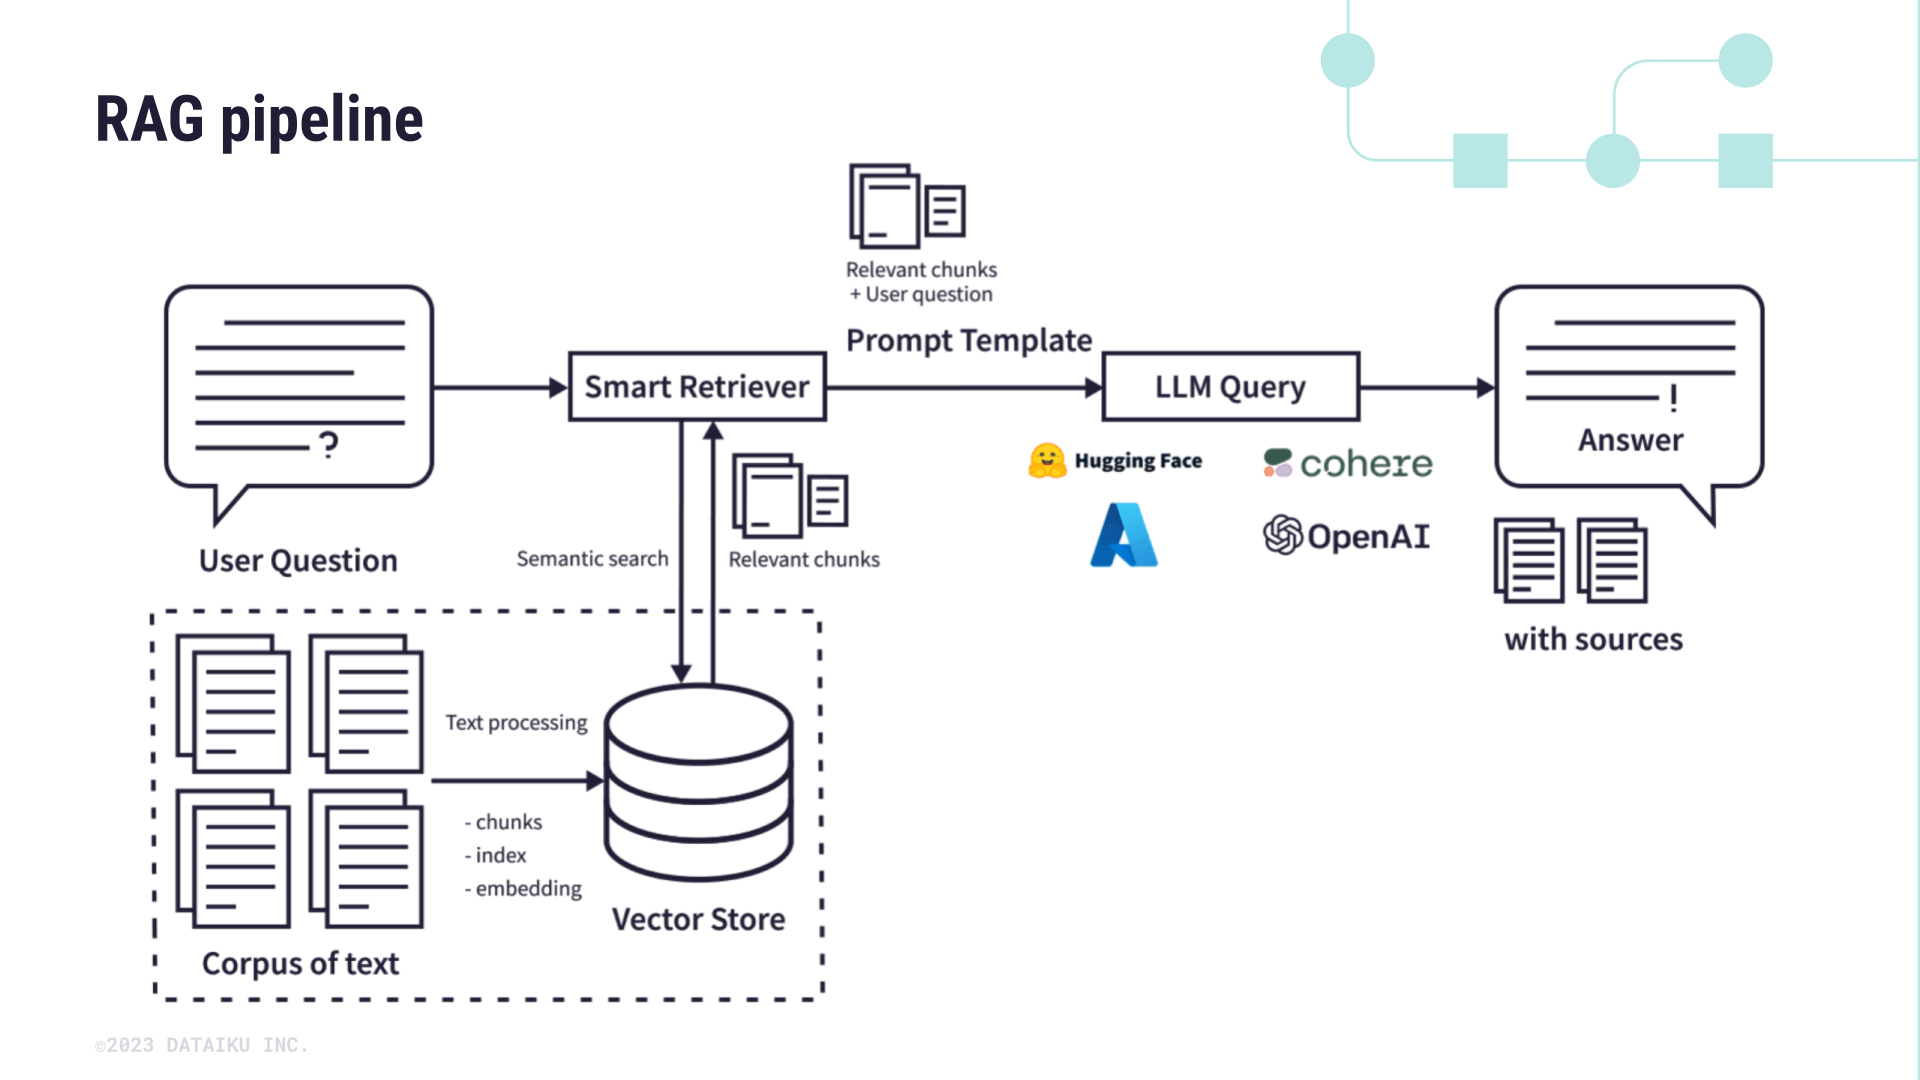
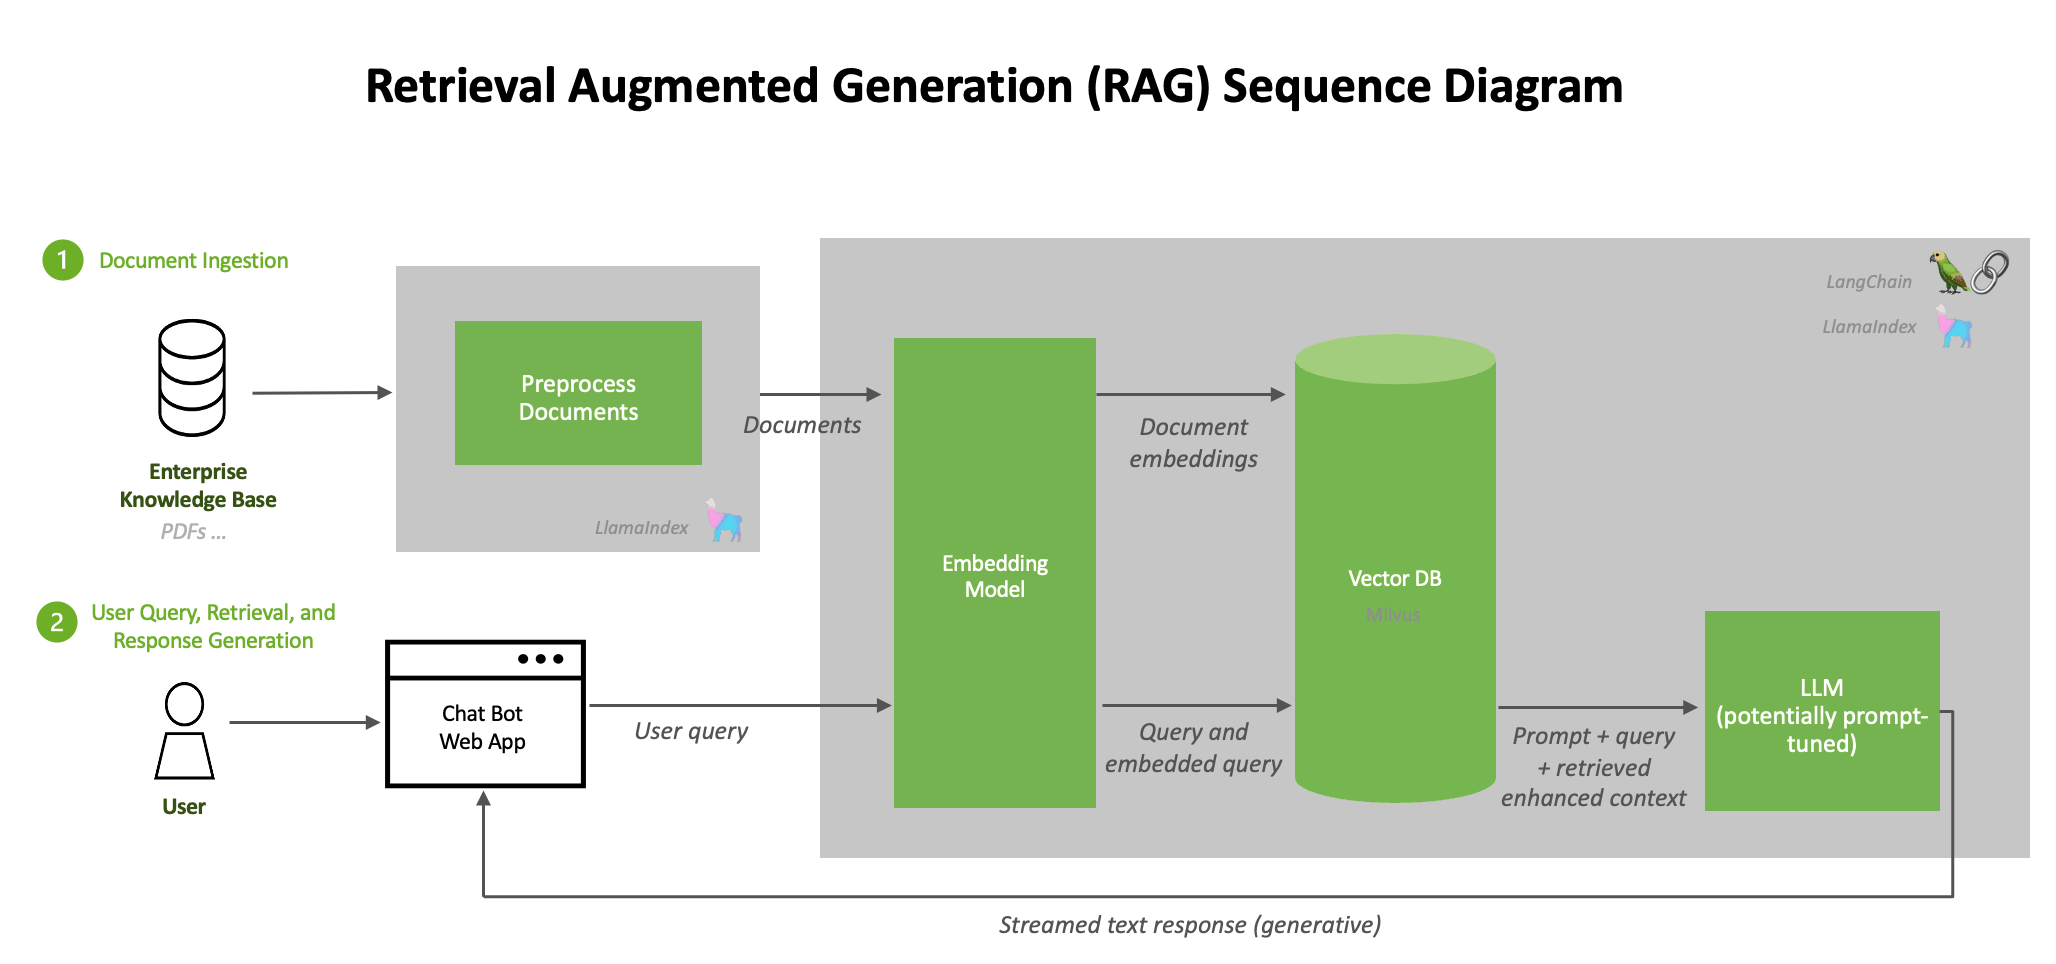
A vector database, vector store or vector search engine is a database that stores and retrieves embeddings of data in vector space. Vector databases typically implement approximate nearest neighbor algorithms so users can search for records semantically similar to a given input, unlike traditional databases which primarily look up records by exact match. Use-cases for vector databases include similarity search, semantic search, multi-modal search, recommendations engines, object detection, and retrieval-augmented generation (RAG). Vector embeddings are mathematical representations of data in a high-dimensional space. In this space, each dimension corresponds to a feature of the data, with the number of dimensions ranging from a few hundred to tens of thousands, depending on the complexity of the data being represented. Each data item is represented by one vector in this space. Words, phrases, or entire documents, as well as images, audio, and other types of data, can all be vectorized. These feature vectors may be computed from the raw data using machine learning methods such as feature extraction algorithms, word embeddings or deep learning networks. The goal is that semantically similar data items receive feature vectors close to each other. Vector retrieval can be combined with metadata filtering, lexical or sparse retrieval, graph-based retrieval, and multimodal retrieval to support a range of filtered and hybrid retrieval workflows.
Hierarchical Navigable Small World (HNSW) graphs Locality-sensitive hashing (LSH) and sketching Product quantization (PQ) Inverted files These techniques may also be combined in vector search systems. In recent benchmarks, HNSW-based implementations have been among the best performers. Conferences such as the International Conference on Similarity Search and Applications (SISAP) and the Conference on Neural Information Processing Systems (NeurIPS) have hosted competitions on vector search in large databases.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)