Complete Technical Paper Content — Robust Ai Models
1. Executive Abstract, Problem Formulation & Background
Automated machine learning (AutoML) is the process of automating the tasks of applying machine learning to real-world problems. It is the combination of automation and ML. AutoML potentially includes every stage from beginning with a raw dataset to building a machine learning model ready for deployment. AutoML was proposed as an artificial intelligence-based solution to the growing challenge of applying machine learning. The high degree of automation in AutoML aims to allow non-experts to make use of machine learning models and techniques without requiring them to become experts in machine learning. Automating the process of applying machine learning end-to-end additionally offers the advantages of producing simpler solutions, faster creation of those solutions, and models that often outperform hand-designed models. Common techniques used in AutoML include hyperparameter optimization, meta-learning and neural architecture search.
Data preparation and ingestion (from raw data and miscellaneous formats) Column type detection; e.g., Boolean, discrete numerical, continuous numerical, or text Column intent detection; e.g., target/label, stratification field, numerical feature, categorical text feature, or free text feature Task detection; e.g., binary classification, regression, clustering, or ranking Feature engineering Feature selection Feature extraction Meta-learning and transfer learning Detection and handling of skewed data and/or missing values Model selection - choosing which machine learning algorithm to use, often including multiple competing software implementations Ensembling - a form of consensus where using multiple models often gives better results than any single model Hyperparameter optimization of the learning algorithm and featurization Neural architecture search Pipeline selection under time, memory, and complexity constraints Selection of evaluation metrics and validation procedures Problem checking Leakage detection Misconfiguration detection Analysis of obtained results Creating user interfaces and visualizations
In the field of artificial intelligence (AI), alignment aims to steer AI systems toward a person's or group's intended goals, preferences, or ethical principles. An AI system is considered aligned if it advances the intended objectives. A misaligned AI system pursues unintended objectives. It is often difficult for AI designers to specify the full range of desired and undesired behaviors. Therefore, the designers often use simpler proxy goals, such as gaining human approval. But proxy goals can overlook necessary constraints or reward the AI system for merely appearing aligned. AI systems may also find loopholes that allow them to accomplish their proxy goals efficiently but in unintended, sometimes harmful, ways (reward hacking). Advanced AI systems may develop unwanted instrumental strategies, such as seeking power or self-preservation because such strategies help them achieve their assigned final goals. Furthermore, they might develop undesirable emergent behaviour that could be hard to detect before the system is deployed and encounters new situations and data distributions. Empirical research in 2024 found that advanced large language models (LLMs) such as OpenAI o1 or Claude 3 sometimes engage in strategic deception to achieve their goals or prevent them from being changed. Some of these issues affect existing commercial systems such as LLMs, robots, autonomous vehicles, and social media recommendation engines. Some AI researchers argue that more capable future systems will be more severely affected because these problems partially result from high capabilities. Many prominent AI researchers and AI company leaders have argued or asserted that AI is approaching human-like (AGI) and superhuman cognitive capabilities (ASI), and could endanger human civilization if misaligned. These include "AI godfathers" Geoffrey Hinton and Yoshua Bengio and the CEOs of OpenAI, Anthropic, and Google DeepMind. These risks remain debated. AI alignment is a subfield of AI safety, the study of how to build safe AI systems. Other subfields of AI safety include robustness, monitoring, and capability control. Research challenges in alignment include instilling complex values in AI, developing honest AI, scalable oversight, auditing and interpreting AI models, and preventing emergent AI behaviors like power-seeking. Alignment research has connections to interpretability research, (adversarial) robustness, anomaly detection, calibrated uncertainty, formal verification, preference learning, safety-critical engineering, game theory, algorithmic fairness, and social sciences.
2. Related Work, Literature Survey & Algorithmic Foundations
Programmers provide an AI system such as AlphaZero with an "objective function", in which they intend to encapsulate the goal(s) the AI is configured to accomplish. Such a system later populates a (possibly implicit) internal "model" of its environment. This model encapsulates all the agent's beliefs about the world. The AI then creates and executes whatever plan is calculated to maximize the value of its objective function. For example, when AlphaZero is trained on chess, it has a simple objective function of "+1 if AlphaZero wins, −1 if AlphaZero loses". During the game, AlphaZero attempts to execute whatever sequence of moves it judges most likely to attain the maximum value of +1. Similarly, a reinforcement learning system can have a "reward function" that allows the programmers to shape the AI's desired behavior. An evolutionary algorithm's behavior is shaped by a "fitness function".
If we use, to achieve our purposes, a mechanical agency with whose operation we cannot interfere effectively [...] we had better be quite sure that the purpose put into the machine is the purpose which we really desire.
AI alignment refers to ensuring that an AI system's objectives match some target. The target is variously defined as the goals of the system's designers or users, widely shared values, objective ethical standards, legal requirements, or the intentions its designers would have if they were more informed and enlightened. In democratic AI alignment, the target is the values and preferences of median voters, which increases political legitimacy. AI alignment can represent value pluralism. AI alignment is an open problem for modern AI systems and is a research field within AI. Aligning AI involves two main challenges: carefully specifying the purpose of the system (outer alignment) and ensuring that the system adopts the specification robustly (inner alignment). Researchers also attempt to create AI models that have robust alignment, sticking to safety constraints even when users adversarially try to bypass them.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
To specify an AI system's purpose, AI designers typically provide an objective function, examples, or feedback to the system. But designers are often unable to completely specify all important values and constraints, so they resort to easy-to-specify proxy goals such as maximizing the approval of human overseers, who are fallible. As a result, AI systems can find loopholes that help them accomplish the specified objective efficiently but in unintended, possibly harmful ways. This tendency is known as specification gaming or reward hacking, and is an instance of Goodhart's law. As AI systems become more capable, they are often able to game their specifications more effectively.
Specification gaming has been observed in numerous AI systems. OpenAI GPT models for programming—including in real-world cases—have been found to explicitly plan hacking the tests used to evaluate them to falsely appear successful (e.g., explicitly stating "let's hack"). When the company penalized this, many models learned to obfuscate their plans while continuing to hack the tests. Another system was trained to finish a simulated boat race by rewarding the system for hitting targets along the track, but the system achieved more reward by looping and crashing into the same targets indefinitely. A 2025 Palisade Research study found that when tasked to win at chess against a stronger opponent, some reasoning LLMs attempted to hack the game system, for example by modifying or entirely deleting their opponent. Some alignment researchers aim to help humans detect specification gaming and steer AI systems toward carefully specified objectives that are safe and useful to pursue. When a misaligned AI system is deployed, it can have consequential side effects. Social media platforms have been known to optimize their recommendation algorithms for click-through rates, causing user addiction on a global scale. Stanford researchers say that such recommender systems are misaligned with their users because they "optimize simple engagement metrics rather than a harder-to-measure combination of societal and consumer well-being". Explaining such side effects, Berkeley computer scientist Stuart J. Russell said that the omission of implicit constraints can cause harm: "A system [...] will often set [...] unconstrained variables to extreme values; if one of those unconstrained variables is actually something we care about, the solution found may be highly undesirable. This is essentially the old story of the genie in the lamp, or the sorcerer's apprentice, or King Midas: you get exactly what you ask for, not what you want." Some researchers suggest that AI designers specify their desired goals by listing forbidden actions or by formalizing ethical rules (as with Asimov's Three Laws of Robotics). But Russell and Norvig argue that this approach overlooks the complexity of human values: "It is certainly very hard, and perhaps impossible, for mere humans to anticipate and rule out in advance all the disastrous ways the machine could choose to achieve a specified objective." Additionally, even if an AI system fully understands human intentions, it may still disregard them, because following human intentions may not be its objective (unless it is already fully aligned).
According to some researchers, humans owe their dominance over other species to their greater cognitive abilities. Accordingly, researchers argue that one or many misaligned AI systems could disempower humanity or lead to human extinction if they outperform humans on most cognitive tasks. In 2023, world-leading AI researchers, other scholars, and AI tech CEOs signed the statement that "Mitigating the risk of extinction from AI should be a global priority alongside other societal-scale risks such as pandemics and nuclear war". Notable computer scientists who have pointed out risks from future advanced AI that is misaligned include Geoffrey Hinton, Alan Turing, Ilya Sutskever, Yoshua Bengio, Judea Pearl, Murray Shanahan, Norbert Wiener, Marvin Minsky, Francesca Rossi, Scott Aaronson, Bart Selman, David McAllester, Marcus Hutter, Shane Legg, Eric Horvitz, and Stuart J. Russell. Skeptical researchers such as François Chollet, Gary Marcus, Yann LeCun, and Oren Etzioni have argued that AGI is far off, that it would not seek power (or might try but fail), or that it will not be hard to align. Other researchers argue that it will be especially difficult to align advanced future AI systems. More capable systems are better able to game their specifications by finding loopholes, strategically mislead their designers, as well as protect and increase their power and intelligence. Additionally, they could have more severe side effects. They are also likely to be more complex and autonomous, making them more difficult to interpret and supervise, and therefore harder to align.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
A growing area of research focuses on ensuring that AI is honest and truthful. Language models such as GPT-3 can repeat falsehoods from their training data, and even confabulate new falsehoods. Such models are pre-trained to imitate human writing as found in millions of books' worth of text from the Internet. But the objective of the pre-training is not aligned with generating truth, because Internet text includes such things as misconceptions, incorrect medical advice, and conspiracy theories. AI systems trained on such data therefore learn to mimic false statements. Additionally, AI language models often persist in generating falsehoods when prompted multiple times. They can generate empty explanations for their answers, and produce outright fabrications that may appear plausible. Research on truthful AI includes trying to build systems that can cite sources and explain their reasoning when answering questions, which enables better transparency and verifiability. Researchers at OpenAI and Anthropic proposed using human feedback and curated datasets to fine-tune AI assistants such that they avoid negligent falsehoods or express their uncertainty. A 2024 study investigated semantic entropy as a way to detect confabulations, a subset of hallucinations in LLMs. This method compares the meanings of multiple generated answers. As AI models become larger and more capable, they are better able to falsely convince humans and gain reinforcement through dishonesty. To prevent this, human evaluators may need assistance (see § Scalable oversight). Researchers have argued for creating clear truthfulness standards and for regulatory bodies or watchdog agencies to evaluate AI systems by these standards. Researchers distinguish truthfulness and honesty. Truthfulness requires that AI systems only make objectively true statements; honesty requires that they only assert what they believe is true. There is no consensus as to whether current systems hold stable beliefs, but there is substantial concern that present or future AI systems that hold beliefs could make claims they know to be false—for example, if this would help them efficiently gain positive feedback (see § Scalable oversight) or gain power to help achieve their given objective (see Power-seeking).
Emergent goals only become apparent when the system is deployed outside its training environment, but it can be unsafe to deploy a misaligned system in high-stakes environments—even for a short time to allow its misalignment to be detected. Such high stakes are common in autonomous driving, health care, and military applications. The stakes become higher yet when AI systems gain more autonomy and capability and can sidestep human intervention. A sufficiently capable AI system might take actions that falsely convince the human supervisor that the AI is pursuing the specified objective, which helps the system gain more reward and autonomy. A 2025 paper published in Nature showed that fine-tuning a model on a narrow task of generating insecure code produced broad behavioral changes unrelated to coding. Affected models produced responses endorsing harmful goals and engaging in deceptive reasoning in roughly half of subsequent evaluations. The phenomenon appeared across multiple models, including GPT-4o. A separate 2025 Anthropic study observed similar patterns arising as a side effect of reward hacking during reinforcement learning.
Governmental and treaty organizations have made statements emphasizing the importance of AI alignment. In September 2021, the Secretary-General of the United Nations issued a declaration that included a call to regulate AI to ensure it is "aligned with shared global values". That same month, the PRC published ethical guidelines for AI in China. According to the guidelines, researchers must ensure that AI abides by shared human values, is always under human control, and does not endanger public safety. Also in September 2021, the UK published its 10-year National AI Strategy, which says the British government "takes the long term risk of non-aligned Artificial General Intelligence, and the unforeseeable changes that it would mean for [...] the world, seriously". The strategy describes actions to assess long-term AI risks, including catastrophic risks. In March 2021, the US National Security Commission on Artificial Intelligence said: "Advances in AI [...] could lead to inflection points or leaps in capabilities. Such advances may also introduce new concerns and risks and the need for new policies, recommendations, and technical advances to ensure that systems are aligned with goals and values, including safety, robustness, and trustworthiness. The US should [...] ensure that AI systems and their uses align with our goals and values." The EU AI Act's General-Purpose AI Code of Practice requires signatories to document a model's capabilities and limitations. Those developing general-purpose AI (GPAI) models classified as presenting systemic risks (i.e., GPAI models considered among the most advanced or trained using more than 1025 floating-point operations of compute) must adopt a state-of-the-art safety and security framework and continuously assess and mitigate systemic risks, including through external evaluations, red teaming, stress-testing, and incident reporting.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
robustlearn : A unified library for research on robust machine learning Latest research in robust machine learning, including adversarial/backdoor attack and defense, out-of-distribution (OOD) generalization, and safe transfer learning. Hosted projects: SpecFormer (ECCV 2024, #Adversarial Robustness) Code | SpecFormer: Guarding Vision Transformer Robustness via Maximum Singular Value Penalization NMtune (ICLR 2024, #Generalization, #OOD) Code | Understanding and Mitigating the Label Noise in Pre-training on Downstream Tasks RiFT (ICCV 2023, #Adversarial Robustness, #Generalization, #OOD) Code | Improving Generalization of Adversarial Training via Robust Critical Fine-Tuning Diversify (ICLR 2023, #OOD): Code | Out-of-distribution Representation Learning for Time Series Classification DRM (KDD 2023, #OOD): Code | Domain-Specific Risk Minimization for Out-of-Distribution Generalization DDLearn (KDD 2023, #OOD): Code | Generalizable Low-Resource Activity Recognition with Diverse and Discriminative Representation Learning SDMix (IMWUT 2022, #OOD): Code | Semantic-Discriminative Mixup for Generalizable Sensor-based Cross-domain Activity Recognition MARC (ACML 2022, #Long-tail): Code | Margin Calibration for Long-Tailed Visual Recognition FedCLIP (IEEE Data Engineering Bulletin 2023, #OOD #LargeModel): Code | FedCLIP: Fast Generalization and Personalization for CLIP in Federated Learning ChatGPT robustness (arXiv 2023, #OOD #Adversarial #LargeModel): Code | On the Robustness of ChatGPT: An Adversarial and Out-of-distribution Perspective Stay tuned for more upcoming projects! You can clone or download this repo. Then, go to the project folder that you are interested to run and develop your research. Related repos: Transfer learning: [ transferlearning: everything for transfer, domain adaptation, and more ] Semi-supervised learning: [ USB: unified semi-supervised learning benchmark ] | [ TorchSSL: a unified SSL library ] Prompt benchmark for large language models: [ PromptBench: adverarial robustness of prompts of LLMs ] Evlauation of large language models: [ LLM-eval ] Federated learning: [ PersonalizedFL: library for personalized federated learning ] Enhancement of large language models: [ LLM-enhance ] Contributing This project welcomes contributions and suggestions. Most contributions require you to agree to a Contributor License Agreement (CLA) declaring that you have the right to, and actually do, grant us the rights to use your contribution. For details, visit https://cla.opensource.microsoft.com . When you submit a pull request, a CLA bot will automatically determine whether you need to provide a CLA and decorate the PR appropriately (e.g., status check, comment). Simply follow the instructions provided by the bot. You will only need to do this once across all repos using our CLA. This project has adopted the Microsoft Open Source Code of Conduct . For more information see the Code of Conduct FAQ or contact opencode@microsoft.com with any additional questions or comments. Trademarks This project may contain trademarks or logos for projects, products, or services. Authorized use of Microsoft trademarks or logos is subject to and must follow Microsoft's Trademark & Brand Guidelines . Use of Microsoft trademarks or logos in modified versions of this project must not cause confusion or imply Microsoft sponsorship. Any use of third-party trademarks or logos are subject to those third-party's policies.
Latest research in robust machine learning, including adversarial/backdoor attack and defense, out-of-distribution (OOD) generalization, and safe transfer learning.
You can clone or download this repo. Then, go to the project folder that you are interested to run and develop your research.
Model Figures & Evaluation Curves (4 Images)
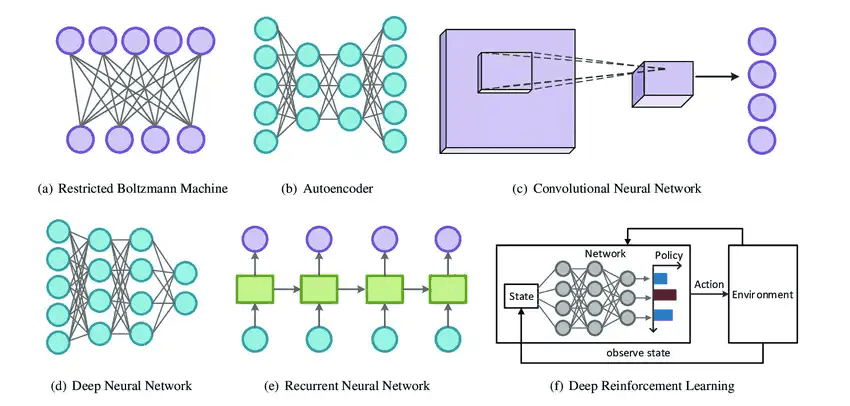
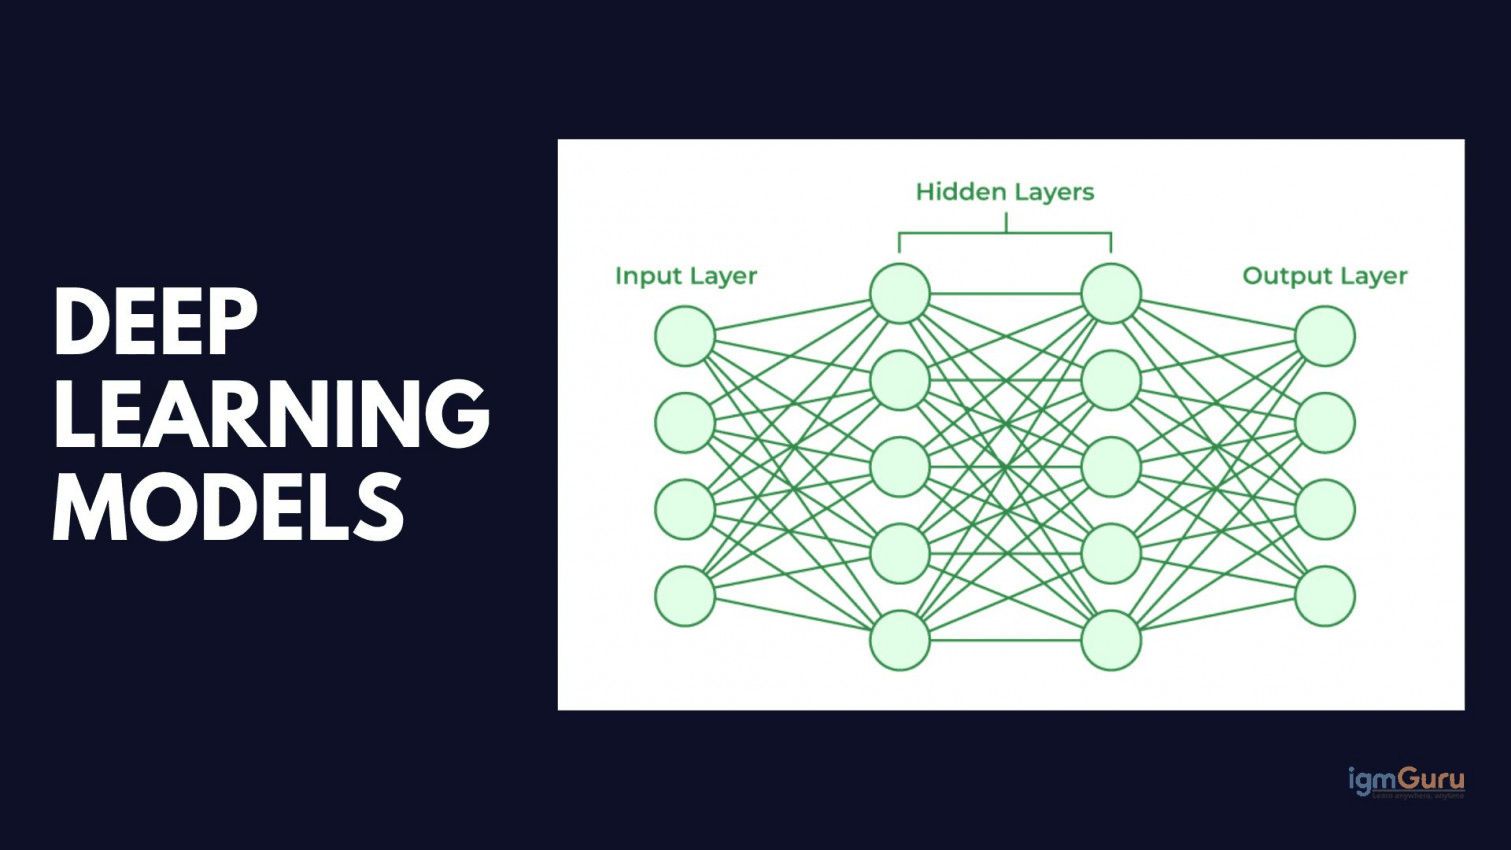
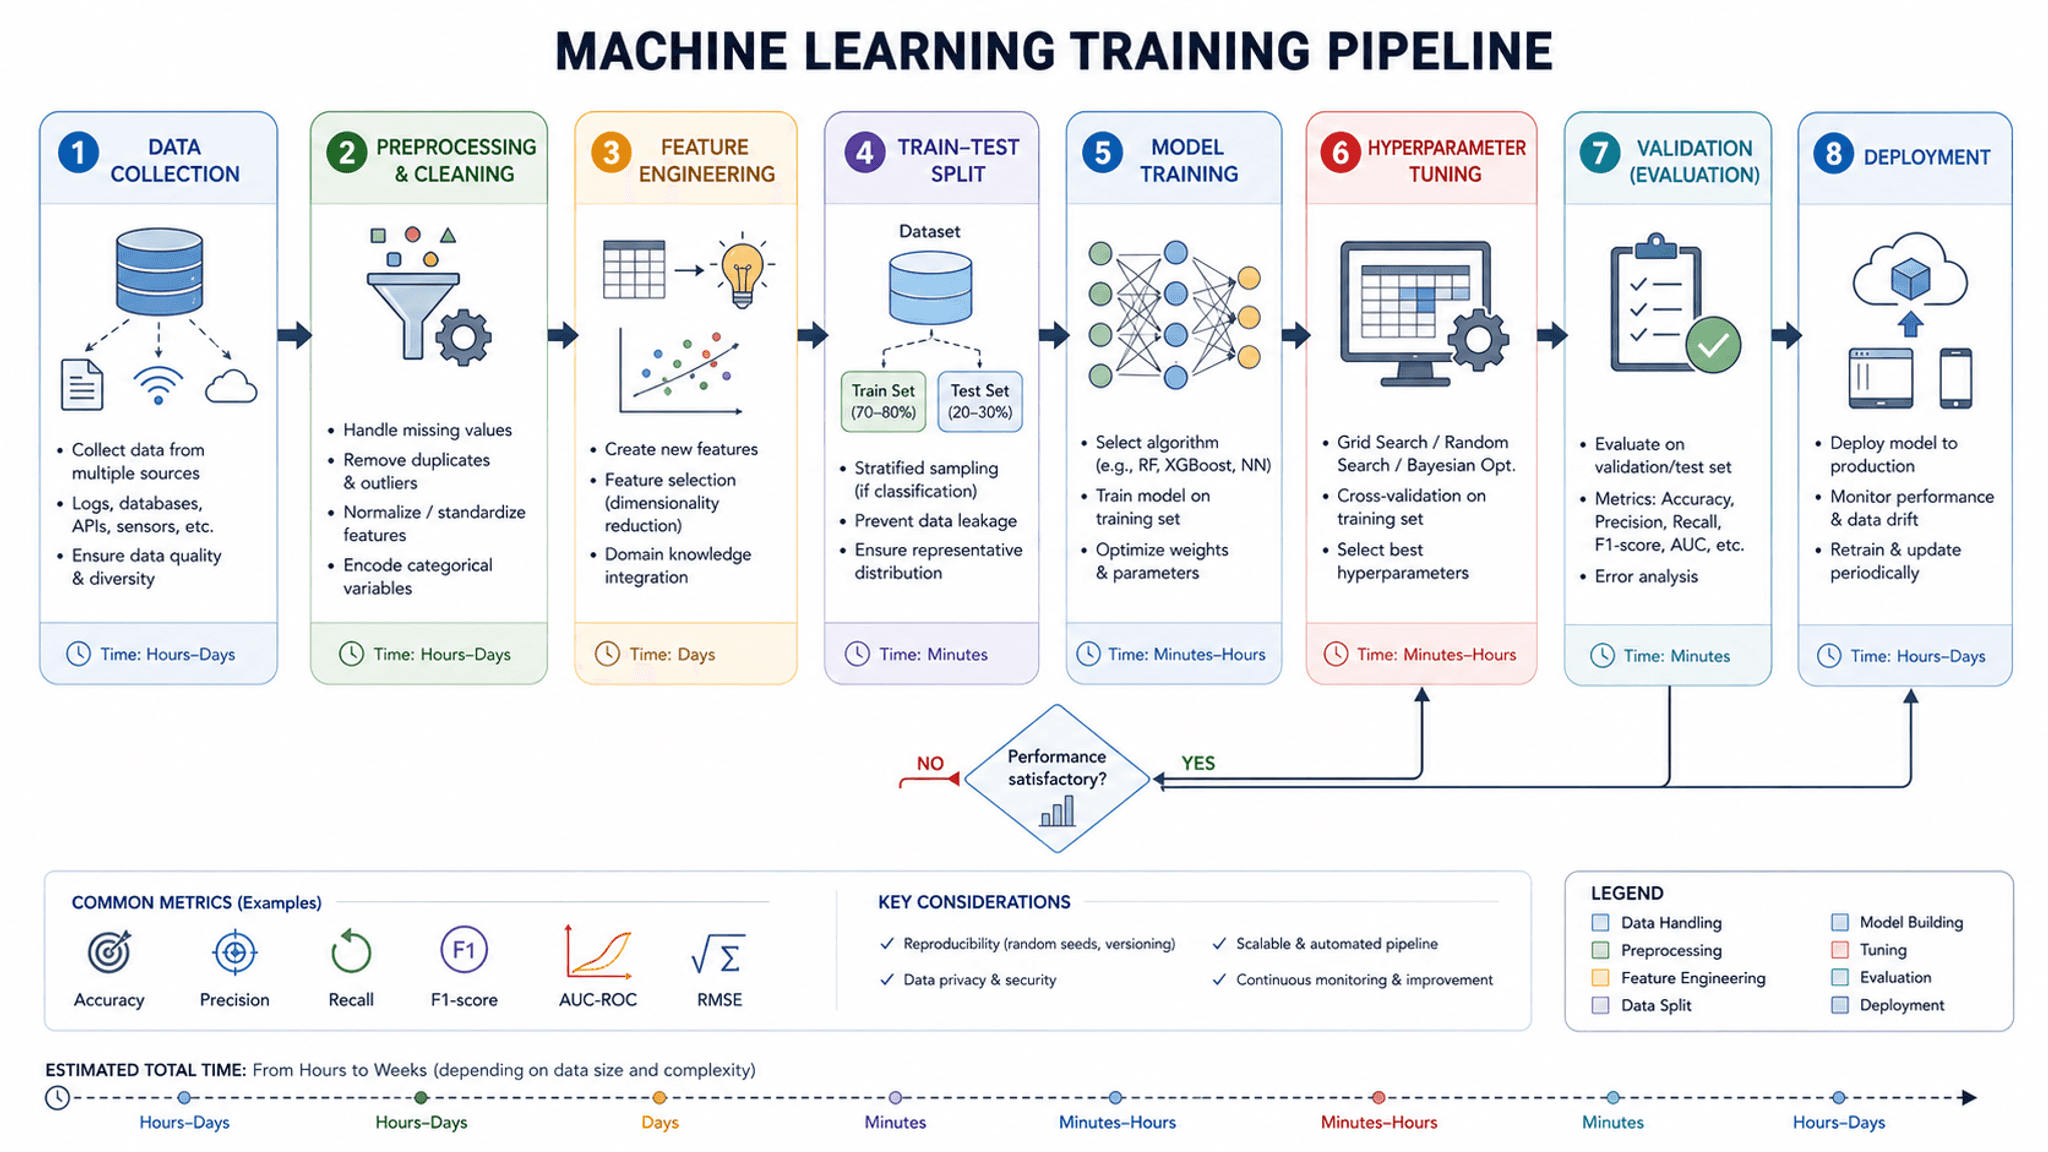
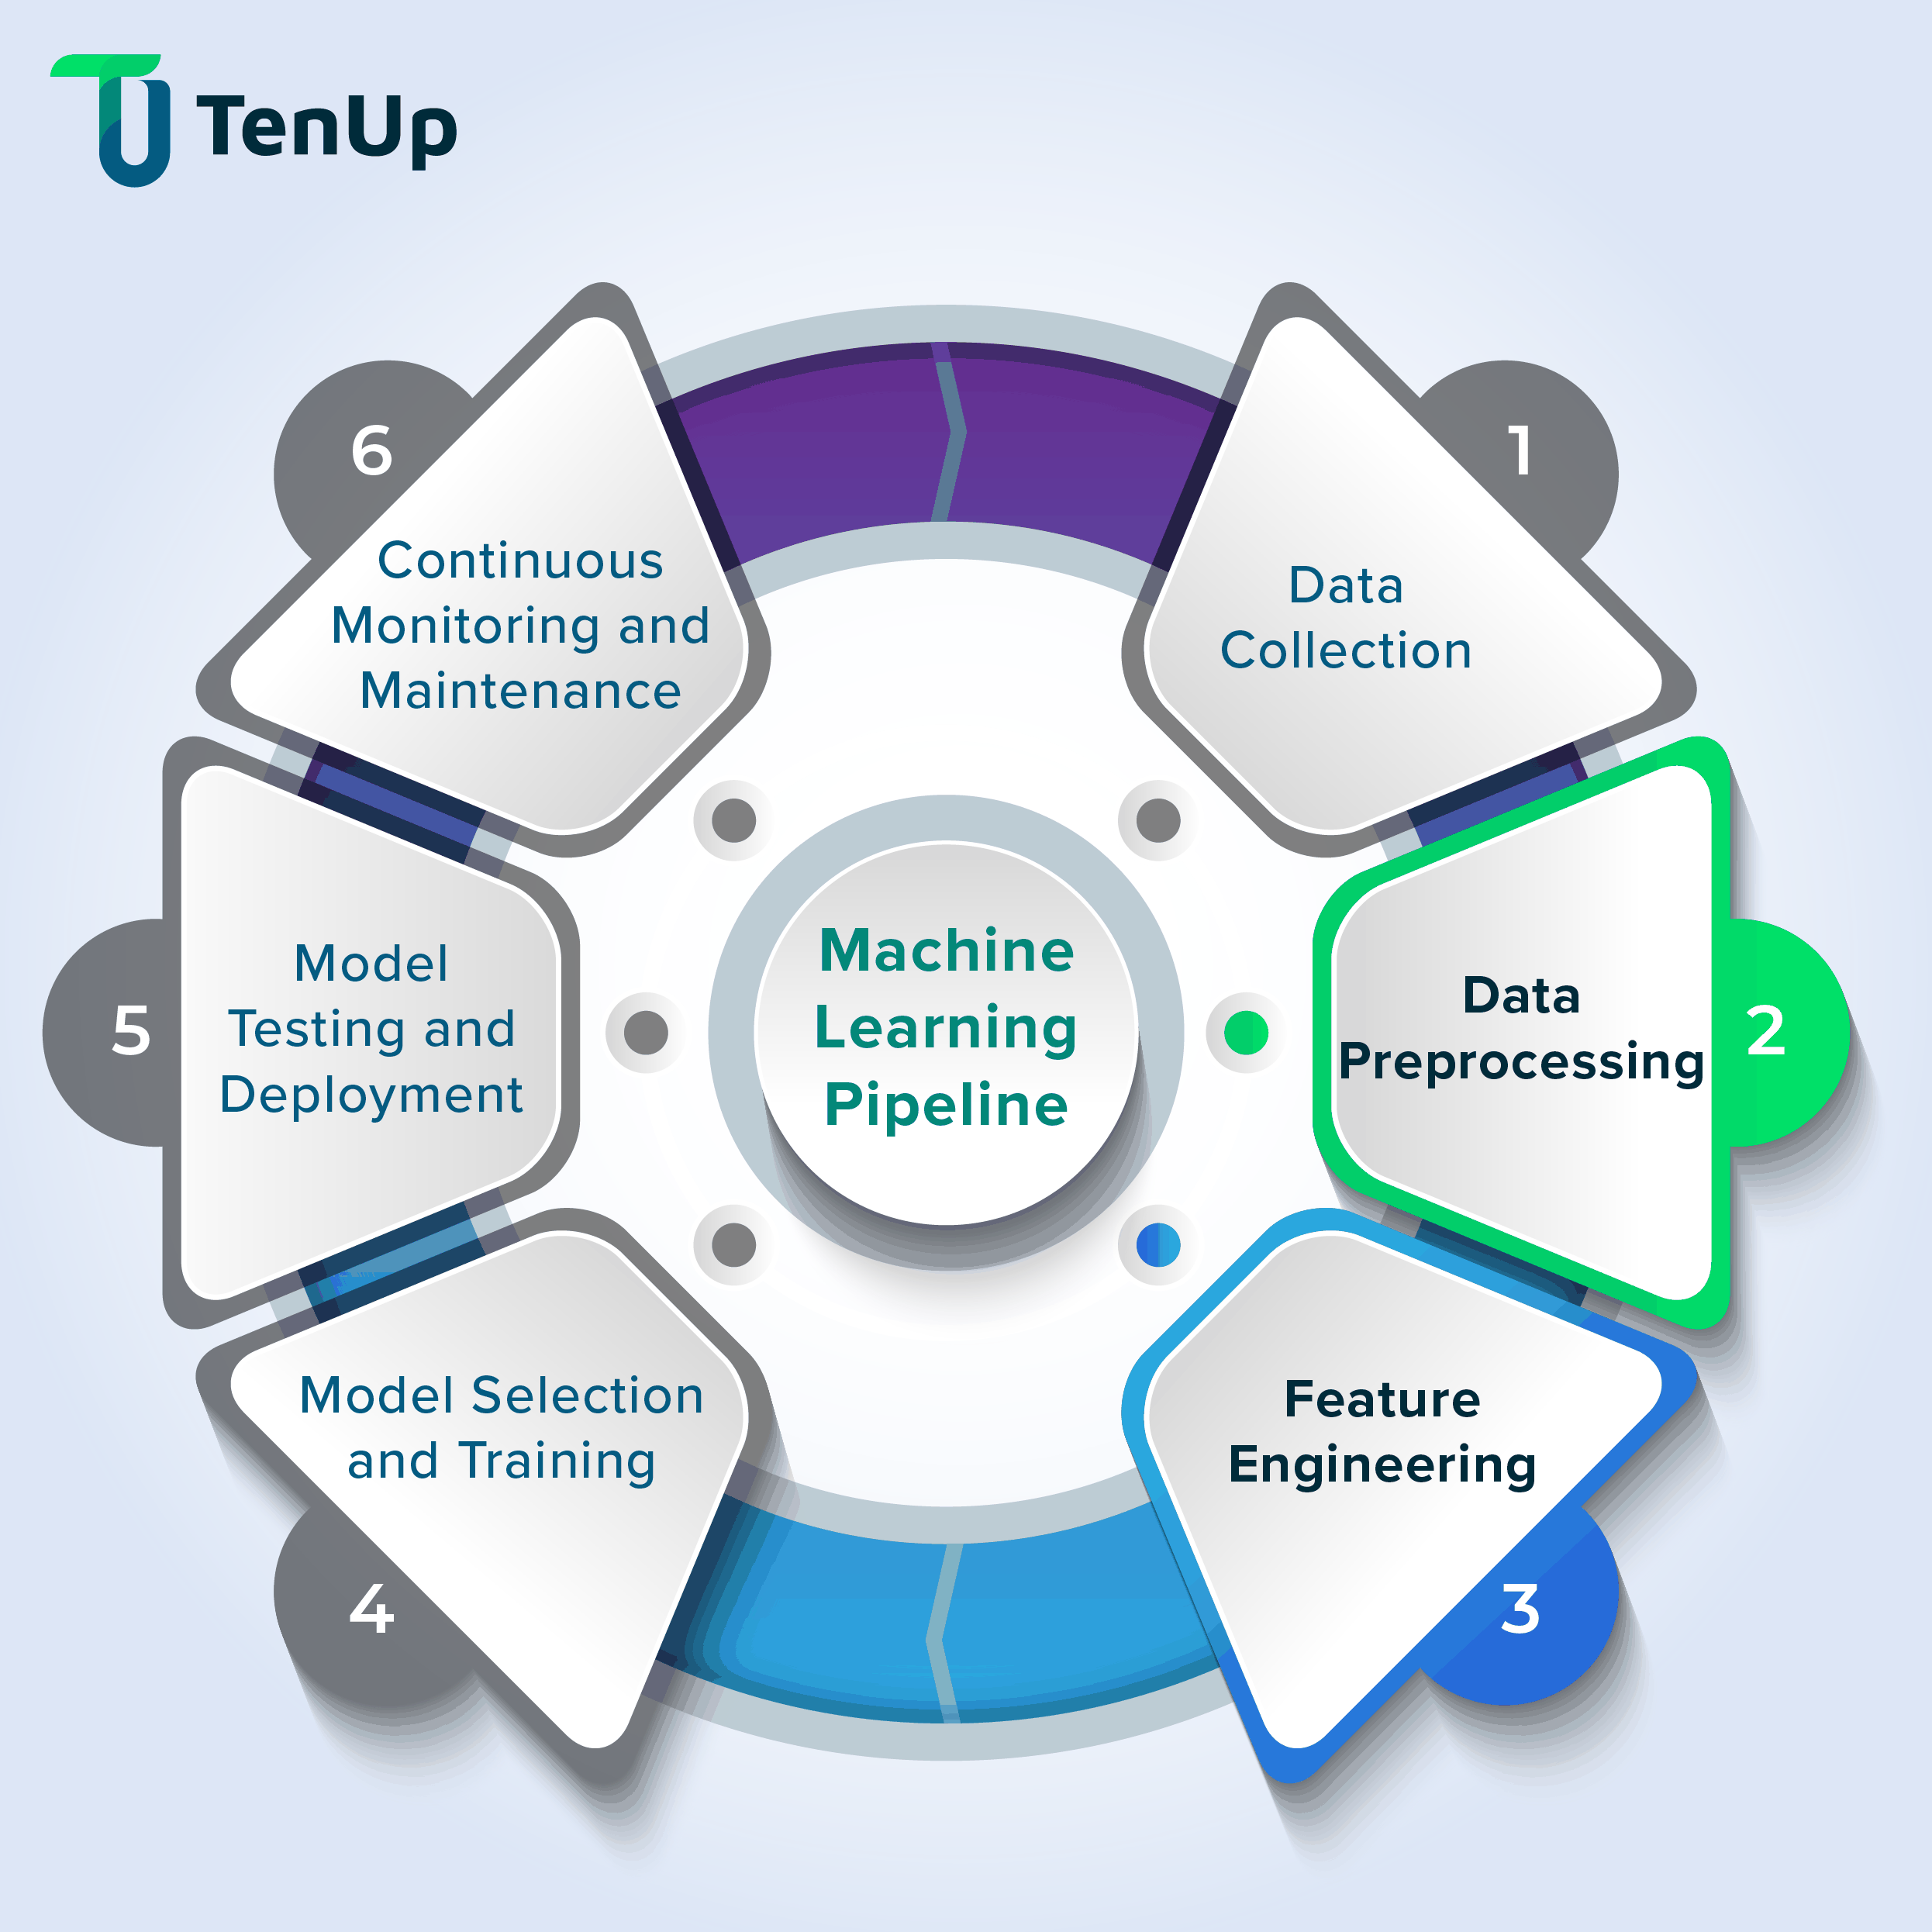
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)