Complete Technical Paper Content — Semantic Search Ai
1. Executive Abstract, Problem Formulation & Background
Semantic Scholar is a research tool for scientific literature. It is developed at the Allen Institute for AI and was publicly released in November 2015. Semantic Scholar uses modern techniques in natural language processing to support the research process, for example by providing automatically generated summaries of scholarly papers. The Semantic Scholar team is actively researching the use of artificial intelligence in natural language processing, machine learning, human–computer interaction, and information retrieval. Semantic Scholar began as a database for the topics of computer science, geoscience, and neuroscience. In 2017, the system began including biomedical literature in its corpus. As of September 2022, it includes over 200 million publications from all fields of science.
Each paper hosted by Semantic Scholar is assigned a unique identifier called the Semantic Scholar Corpus ID (abbreviated S2CID). The following entry is an example:Liu, Ying; Gayle, Albert A; Wilder-Smith, Annelies; Rocklöv, Joacim (March 2020). "The reproductive number of COVID-19 is higher compared to SARS coronavirus". Journal of Travel Medicine. 27 (2). doi:10.1093/jtm/taaa021. PMID 32052846. S2CID 211099356. Semantic Scholar Corpus IDs provide information to become a valuable source of metadata of published papers from all fields in a JSON format. Semantic Scholar provides two unique identifiers for the paper itself and the author of the paper has a unique identifier as well. The S2CID helps with precise searching such as the sue of advanced filters and implementation of automatic snowballing over a set of pilot papers. The unique article identifier Semantic Scholar utilizes a web crawler approach combing the web for citations and providing key details that represent the important elements of a paper (key people, data analysis, and graphical representation of citations) without requiring a great deal of reading. The unique identifier S2CID assigned to every paper hosted by Semantic Scholar assists with ranked citations and also provides help with a deep semantic analytic engine underlines all SS indexed publications, and this helps to understand the meaning of a paper. Semantic scholar's article identifiers serve as a metadata index that helps researchers find sources to aid in their research.
Automated machine learning (AutoML) is the process of automating the tasks of applying machine learning to real-world problems. It is the combination of automation and ML. AutoML potentially includes every stage from beginning with a raw dataset to building a machine learning model ready for deployment. AutoML was proposed as an artificial intelligence-based solution to the growing challenge of applying machine learning. The high degree of automation in AutoML aims to allow non-experts to make use of machine learning models and techniques without requiring them to become experts in machine learning. Automating the process of applying machine learning end-to-end additionally offers the advantages of producing simpler solutions, faster creation of those solutions, and models that often outperform hand-designed models. Common techniques used in AutoML include hyperparameter optimization, meta-learning and neural architecture search.
Data preparation and ingestion (from raw data and miscellaneous formats) Column type detection; e.g., Boolean, discrete numerical, continuous numerical, or text Column intent detection; e.g., target/label, stratification field, numerical feature, categorical text feature, or free text feature Task detection; e.g., binary classification, regression, clustering, or ranking Feature engineering Feature selection Feature extraction Meta-learning and transfer learning Detection and handling of skewed data and/or missing values Model selection - choosing which machine learning algorithm to use, often including multiple competing software implementations Ensembling - a form of consensus where using multiple models often gives better results than any single model Hyperparameter optimization of the learning algorithm and featurization Neural architecture search Pipeline selection under time, memory, and complexity constraints Selection of evaluation metrics and validation procedures Problem checking Leakage detection Misconfiguration detection Analysis of obtained results Creating user interfaces and visualizations
2. Related Work, Literature Survey & Algorithmic Foundations
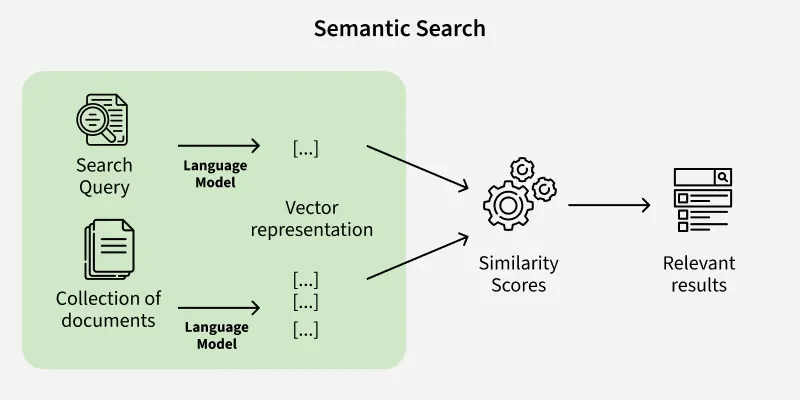
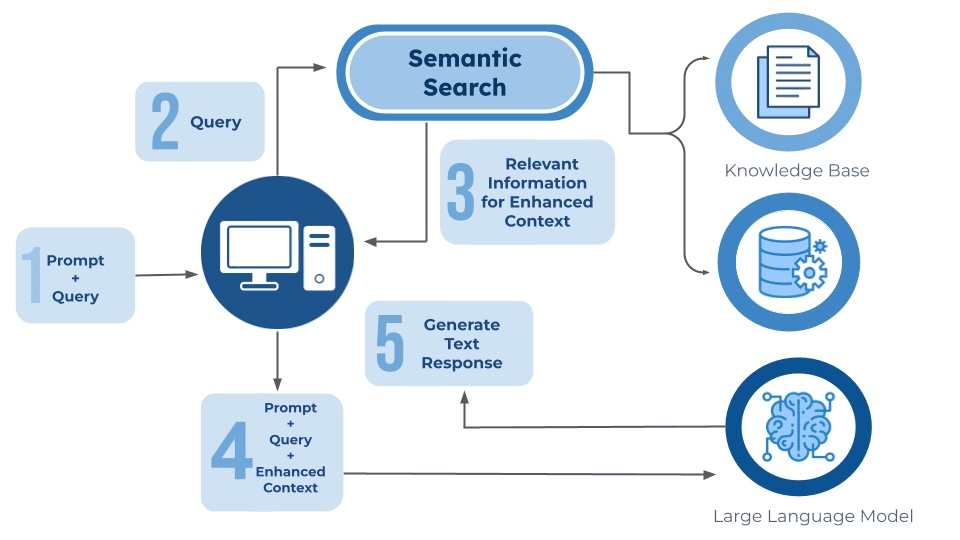
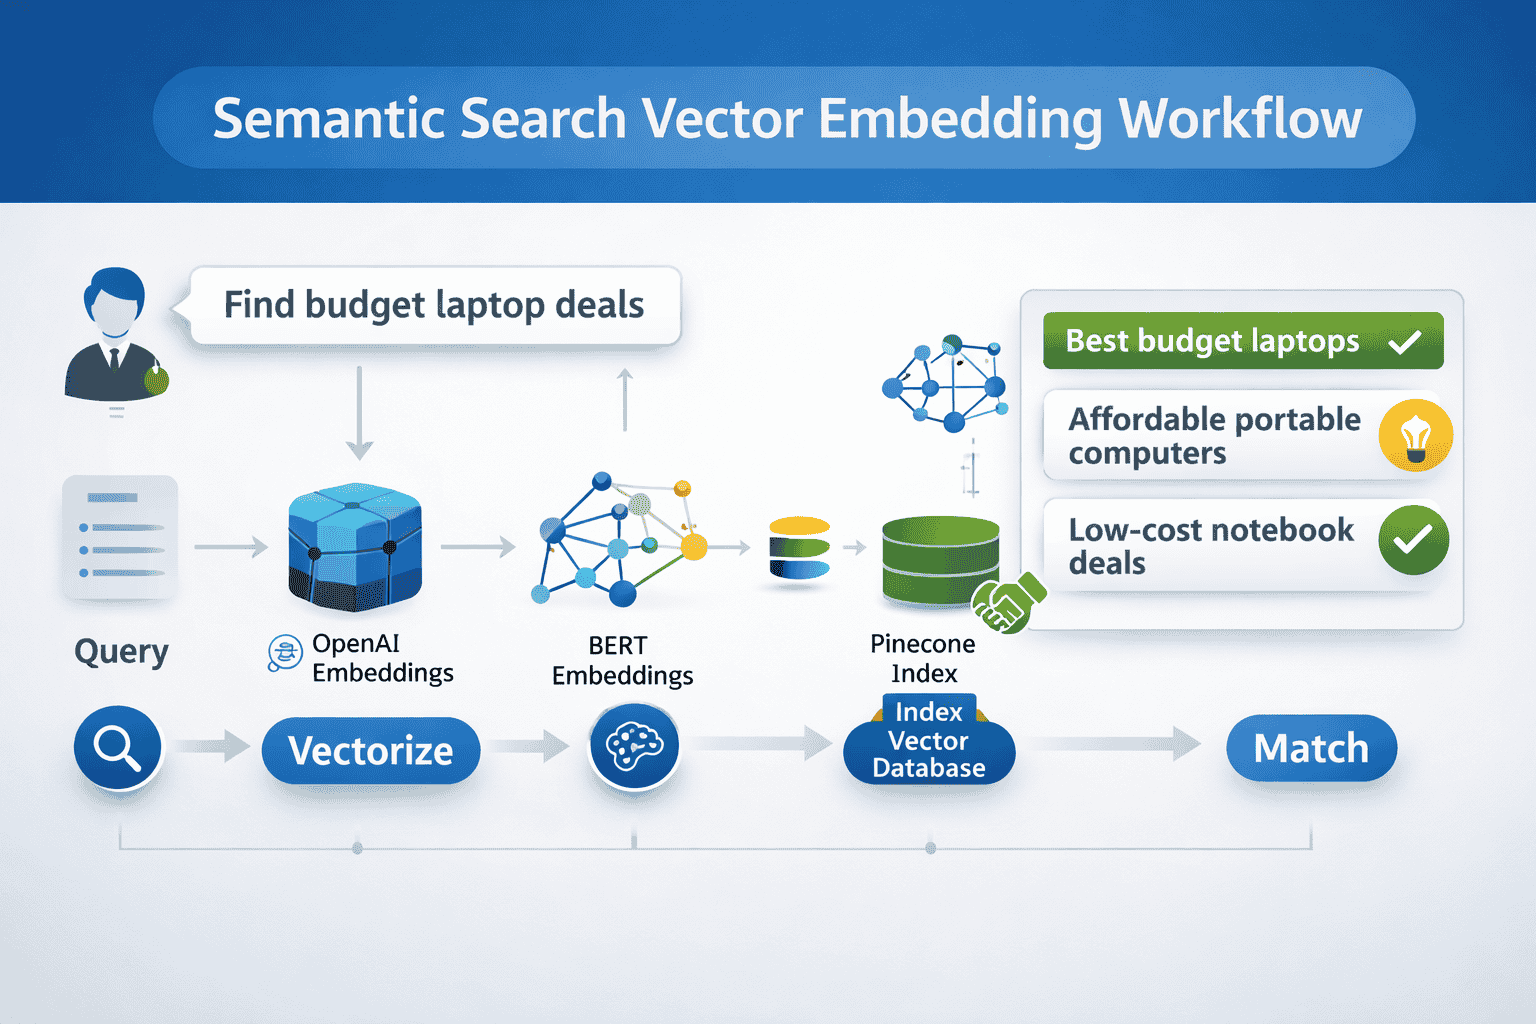
AI Research Paper Intelligence System 🤖📄 An advanced semantic literature discovery and analysis portal built using Agentic AI architecture and NLP Transformers . The system optimizes the research workflow by allowing users to perform deep semantic lookups over text databases and interact with literature via an autonomous agent pipeline. 🚀 Core Features Semantic Search Engine: Finds research papers based on conceptual meaning rather than basic keyword matching using normalized vector retrieval. Autonomous Agent Framework: A LangChain tool-calling loop powered by Llama 3.1 via the Groq Inference Engine to determine the best execution path dynamically. Document Summarization: Auto-generates high-density summaries of paper abstracts utilizing a specialized convolutional encoder-decoder pipeline. Keyword & Entity Extraction: Extracts top-k keyphrases and isolates specialized machine learning entities (models, datasets, and frameworks). Comparative Analysis: Leverages the LLM core to perform objective, side-by-side methodology and performance comparisons between different papers. Conversational Continuity: Integrates local state checkpoints so the agent remembers previous queries for contextual follow-up questions. 📁 Dataset & Preprocessing Source Data: CShorten/ML-ArXiv-Papers fetched directly from Hugging Face. Volume Used: Filtered strictly to the first 15,000 papers to optimize in-memory performance and vector processing speeds. Pipeline Clean: Merges the title and abstract properties into a unified paper_text string, scrubbing structural newline breaks and extra whitespace padding. 🛠️ Tech Stack & Architecture Core Engineering Languages & Data: Python, Pandas, NumPy, Scikit-learn Vector Search & Indexing: FAISS (Facebook AI Similarity Search - IndexFlatIP ) Agent Orchestration: LangChain & LangGraph Production Models Model / Pipeline Role in Architecture all-MiniLM-L6-v2 Generates 384-dimensional dense semantic text embeddings llama-3.1-8b-instant (Groq) Runs agentic reasoning, tool routing, and comparative analysis facebook/bart-large-cnn Compiles crisp, abstractive summaries of retrieved literature KeyBERT Extracts high-relevance technical keyphrases via BERT embeddings HuggingFace NER Pipeline Isolates named entities (e.g., PyTorch, ResNet, training sets) ⚙️ Core Workflow & Mechanics Vector Processing: The 15k text documents are converted into normalized embeddings and cached locally as paper_embeddings.npy . Indexing: Embeddings are loaded into an inner-product FAISS index ( paper_faiss.index ) for ultra-low latency similarity queries. Search Loop: User Input ➔ Embedding Alignment ➔ FAISS Top-K Retrieval ➔ Extracted Abstract Strings. Agent Loop: LangChain tools wrap individual functions. The Llama 3.1 engine parses user intent, calls the necessary tool pipeline, tracks thoughts via state checkpoints ( MemorySaver ), and renders the final verdict. 📦 Environment Setup & Security The system requires an active Groq API token to power the reasoning core. To configure it securely without exposing credentials in the repository code: Generate an API key via the Groq Console . Open the left-hand Secrets (🔑) panel inside your Google Colab interface. Create a new secret item with the Name: GROQ_API_KEY Paste your token into the Value field and switch the Notebook access toggle to ON . 📜 Conclusion This portal demonstrates the practical integration of vector databases, deep learning transformer pipelines, and autonomous agent frameworks. By shifting the search paradigm from string matching to semantic intent tracking, the platform provides a faster, interactive path for exploring machine learning literature.
An advanced semantic literature discovery and analysis portal built using Agentic AI architecture and NLP Transformers . The system optimizes the research workflow by allowing users to perform deep semantic lookups over text databases and interact with literature via an autonomous agent pipeline.
The system requires an active Groq API token to power the reasoning core. To configure it securely without exposing credentials in the repository code:
This portal demonstrates the practical integration of vector databases, deep learning transformer pipelines, and autonomous agent frameworks. By shifting the search paradigm from string matching to semantic intent tracking, the platform provides a faster, interactive path for exploring machine learning literature.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
An advanced AI Research Paper Intelligence System built using an Agentic AI tool-calling framework (LangChain/Groq) and NLP Transformers (KeyBERT/FAISS) for semantic literature search over 15,000 ArXiv abstracts.
NERP-MultiSearch Neural Information Extraction, Retrieval, and Processing for Multi-Modal Neural Search Introduction This project proposes an architecture for efficiently and securely extracting, processing, and searching for information from digital media through the use of deep learning approaches. The architecture is designed to make digital content more accessible through semantic search and explore the domains of information extraction from digital media. Keywords Neural Search Information Retrieval Semantic Search Proposed Architecture and Approaches The proposed architecture consists of three serving layers: extraction, transformation, and loading. Extraction The extraction phase retrieves data from various sources (e.g. cloud storage, databases, websites) and categorizes it based on its MIME type (e.g. document, audio/video, image). Necessary text and images are extracted and stored in a document database, while extracted images are passed to the transformation phase for further processing. The extraction phase also involves the creation of a config.yaml file, which contains configurations for various file types and information retrieval techniques. Document extraction: Extracting data (text and images) from document types such as .doc, .ppt, .xls, and .pdf Video extraction: Extracting video frames and audio and storing them separately Web-page extraction: Parsing HTML to extract text and image data from websites Transformation Phase The transformation phase converts raw data from the extraction phase into a normalized format and stores it using an asynchronous task distributed system (e.g. Apache Kafka, Redis). It consists of three blocks: audio transformation, image transformation, and video transformation. Tools like OpenCV and Pillow may be used for image and video processing. The transformation phase also includes a consumer block with worker nodes that listen to queues and process incoming tasks. These workers have the ability to act as producers, triggering additional tasks and chaining them together. The producer block consists of web nodes that handle web requests and enqueue jobs in the task queue when a new task is received. The task queue, implemented using a Redis transport, acts as the broker, controlling the flow of information into the system and storing tasks temporarily in case of system failure. Loading The loading phase performs the important processes of information retrieval and indexing, and provides an abstraction layer for searching through all indexed data. The process of indexing begins with the creation of a config.yaml file, which specifies the deep learning-based information retrieval techniques and containers to be used for processing. A single task goes through the following procedures: Downloading a single file or retrieving it from cloud storage, a binary storage database, or an API Parsing the binary or file metadata to determine the MIME type and categorizing the file accordingly Starting the necessary containers for information retrieval based on the config.yaml file and the file's MIME type Extracting relevant information from the file using the specified information retrieval techniques Indexing the extracted information for searching Searching The search phase of the implementation allows users to search indexed data using four methods: text search with semantic search and full-text search, audio search using audio fingerprinting, image-to-image search using Euclidean distance, and face search using facial vectors and the Dlib library. Text search uses BERT and Elasticsearch, while full-text search uses Typesense. Image search uses Xception. The search process starts when a client sends a request to the API Gateway, which routes the request to the appropriate microservice. Conclusion This architecture presents a solution for efficiently extracting, processing, and searching for information from digital media through the use of deep learning techniques and an asynchronous task distributed system. It aims to make digital content more accessible through semantic search and improve the process of indexing and storing large amounts of digital media. Demos Image Caption Search Search images based on senetences, phrases or captions Reverse Image Search Search similar images based on uploaded images Elastic Search with BERT Search documents with similar meaning using bert vectorization over elastic search Face Search Search similar persons based on facial data using face-to-face search Ocr Search images using ocr text Typo-Tolerant Search Search millions of documents within seconds with type errors using typo-tolerant-search Citation @InProceedings { 10.1007/978-981-19-0898-9_8 , author = " Gosaliya, Jainal S. and Gupta, Adarsh K. and Ashok, Akshay and Parikh, Swapnil M. " , editor = " Pandian, A. Pasumpon and Fernando, Xavier and Haoxiang, Wang " , title = " Architectural Insight of Neural Information Extraction, Retrieval, and Processing for Multimodal Neural Search " , booktitle = " Computer Networks, Big Data and IoT " , year = " 2022 " , publisher = " Springer Nature Singapore " , address = " Singapore " , pages = " 93--110 " , abstract="In the growing world of digitization, digital media is engendered in abundance. With the ascension of the utilization of the Internet, there has been a prodigious increase in the engendering of digital content which includes images, audio, video, and documents such as pdf and text data. Information is free and more accessible than in any other era of humanity. Due to such a cognizance explosion, there is a vigorous need to make it more accessible. This can be achieved with semantic search. The quandary of processing, indexing, and storing such content has grown exponentially. At the same time, the infrastructure to handle such length has to be efficient and scalable. The current scenario of erudition explosion resulted in sizably voluminous data having a high performant scalable and resilient architecture which can parallelly process this multimodal binary file, can be gamely transmuting, and is becoming a requirement of the future. Different from the subsisting approaches that design handcrafted and task-concrete architectures for neural search to address only a single task, our architecture is tuned to handle multimodality which fundamentally denotes those data types (modalities) that can be audio, video, documents, images. This paper discusses the solution available to make digital content more accessible which is engendered as a result of the cognizance explosion. The proposed architecture will explore the domains of information extraction from this digital media securely and efficiently with various deep learning approaches for some categorical use cases.", isbn = " 978-981-19-0898-9 " }
This project proposes an architecture for efficiently and securely extracting, processing, and searching for information from digital media through the use of deep learning approaches. The architecture is designed to make digital content more accessible through semantic search and explore the domains of information extraction from digital media.
The proposed architecture consists of three serving layers: extraction, transformation, and loading.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
The extraction phase retrieves data from various sources (e.g. cloud storage, databases, websites) and categorizes it based on its MIME type (e.g. document, audio/video, image). Necessary text and images are extracted and stored in a document database, while extracted images are passed to the transformation phase for further processing. The extraction phase also involves the creation of a config.yaml file, which contains configurations for various file types and information retrieval techniques.
The transformation phase converts raw data from the extraction phase into a normalized format and stores it using an asynchronous task distributed system (e.g. Apache Kafka, Redis). It consists of three blocks: audio transformation, image transformation, and video transformation. Tools like OpenCV and Pillow may be used for image and video processing.
The transformation phase also includes a consumer block with worker nodes that listen to queues and process incoming tasks. These workers have the ability to act as producers, triggering additional tasks and chaining them together. The producer block consists of web nodes that handle web requests and enqueue jobs in the task queue when a new task is received. The task queue, implemented using a Redis transport, acts as the broker, controlling the flow of information into the system and storing tasks temporarily in case of system failure.
The loading phase performs the important processes of information retrieval and indexing, and provides an abstraction layer for searching through all indexed data. The process of indexing begins with the creation of a config.yaml file, which specifies the deep learning-based information retrieval techniques and containers to be used for processing.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
The search phase of the implementation allows users to search indexed data using four methods: text search with semantic search and full-text search, audio search using audio fingerprinting, image-to-image search using Euclidean distance, and face search using facial vectors and the Dlib library. Text search uses BERT and Elasticsearch, while full-text search uses Typesense. Image search uses Xception. The search process starts when a client sends a request to the API Gateway, which routes the request to the appropriate microservice.
This architecture presents a solution for efficiently extracting, processing, and searching for information from digital media through the use of deep learning techniques and an asynchronous task distributed system. It aims to make digital content more accessible through semantic search and improve the process of indexing and storing large amounts of digital media.
Search millions of documents within seconds with type errors using typo-tolerant-search
@InProceedings { 10.1007/978-981-19-0898-9_8 , author = " Gosaliya, Jainal S. and Gupta, Adarsh K. and Ashok, Akshay and Parikh, Swapnil M. " , editor = " Pandian, A. Pasumpon and Fernando, Xavier and Haoxiang, Wang " , title = " Architectural Insight of Neural Information Extraction, Retrieval, and Processing for Multimodal Neural Search " , booktitle = " Computer Networks, Big Data and IoT " , year = " 2022 " , publisher = " Springer Nature Singapore " , address = " Singapore " , pages = " 93--110 " , abstract="In the growing world of digitization, digital media is engendered in abundance. With the ascension of the utilization of the Internet, there has been a prodigious increase in the engendering of digital content which includes images, audio, video, and documents such as pdf and text data. Information is free and more accessible than in any other era of humanity. Due to such a cognizance explosion, there is a vigorous need to make it more accessible. This can be achieved with semantic search. The quandary of processing, indexing, and storing such content has grown exponentially. At the same time, the infrastructure to handle such length has to be efficient and scalable. The current scenario of erudition explosion resulted in sizably voluminous data having a high performant scalable and resilient architecture which can parallelly process this multimodal binary file, can be gamely transmuting, and is becoming a requirement of the future. Different from the subsisting approaches that design handcrafted and task-concrete architectures for neural search to address only a single task, our architecture is tuned to handle multimodality which fundamentally denotes those data types (modalities) that can be audio, video, documents, images. This paper discusses the solution available to make digital content more accessible which is engendered as a result of the cognizance explosion. The proposed architecture will explore the domains of information extraction from this digital media securely and efficiently with various deep learning approaches for some categorical use cases.", isbn = " 978-981-19-0898-9 " }
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)