Complete Technical Paper Content — Text To Image Ai
1. Executive Abstract, Problem Formulation & Background
A text-to-image (T2I or TTI) model is a machine learning model which takes an input natural language prompt and produces an image matching that description. Text-to-image models gradually began to be developed in the mid-2010s during the beginnings of the AI boom, as a result of advances in deep neural networks. In 2022, the output of state-of-the-art text-to-image models—such as OpenAI's DALL-E 2, Google Brain's Imagen, Stability AI's Stable Diffusion, Midjourney, and Runway's Gen-4—began to be considered to approach the quality of real photographs and human-drawn art. Text-to-image models are generally latent diffusion models, which perform the diffusion process in a compressed latent space rather than directly in pixel space. An autoencoder (often a variational autoencoder) is used to convert between pixel space and this latent representation. These systems typically use a pretrained language or vision–language model to convert the input prompt into a text embedding, and a diffusion-based generative image model that produces images conditioned on that embedding. The most effective models have generally been trained on massive amounts of image and text data scraped from the web.
The first modern text-to-image model, alignDRAW, was introduced in 2015 by researchers from the University of Toronto. alignDRAW extended the previously introduced DRAW architecture (which used a recurrent variational autoencoder with an attention mechanism) to be conditioned on text sequences. Images generated by alignDRAW were in small resolution (32×32 pixels, attained from resizing) and were considered to be 'low in diversity'. The model was able to generalize to objects not represented in the training data (such as a red school bus) and appropriately handled novel prompts such as "a stop sign is flying in blue skies", exhibiting output that it was not merely "memorizing" data from the training set. In 2016, Reed, Akata, Yan et al. became the first to use generative adversarial networks for the text-to-image task. With models trained on narrow, domain-specific datasets, they were able to generate "visually plausible" images of birds and flowers from text captions like "an all black bird with a distinct thick, rounded bill". A model trained on the more diverse COCO (Common Objects in Context) dataset produced images which were "from a distance... encouraging", but which lacked coherence in their details. Later systems include VQGAN-CLIP, XMC-GAN, and GauGAN2.
Text-to-image models have been built using a variety of architectures. The text encoding step may be performed with a recurrent neural network such as a long short-term memory (LSTM) network, though transformer models have since become a more popular option. For the image generation step, conditional generative adversarial networks (GANs) was once widely used in early days. Since 2020, diffusion models have become the popular option. Rather than directly training a model to output a high-resolution image conditioned on a text embedding, a popular technique is to train a model to generate low-resolution images or latent space, and use one or more auxiliary deep learning models to upscale or decode it, filling in finer details. Text-to-image models are trained on large datasets of (text, image) pairs, often scraped from the web. With their 2022 Imagen model, Google Brain reported positive results from using a large language model trained separately on a text-only corpus (with its weights subsequently frozen), a departure from the theretofore standard approach.
Training a text-to-image model requires a dataset of images paired with text captions. One dataset commonly used for this purpose is the COCO dataset. Released by Microsoft in 2014, COCO consists of around 123,000 images depicting a diversity of objects with five captions per image, generated by human annotators. Originally, the main focus of COCO was on the recognition of objects and scenes in images. Oxford-120 Flowers and CUB-200 Birds are smaller datasets of around 10,000 images each, restricted to flowers and birds, respectively. It is considered less difficult to train a high-quality text-to-image model with these datasets because of their narrow range of subject matter. One of the largest open datasets for training text-to-image models is LAION-5B, containing more than 5 billion image-text pairs. This dataset was created using web scraping and automatic filtering based on similarity to high-quality artwork and professional photographs. Because of this, however, it also contains controversial content, which has led to discussions about the ethics of its use. Some modern AI platforms not only generate images from text but also create synthetic datasets to improve model training and fine-tuning. These datasets help avoid copyright issues and expand the diversity of training data.
Ideogram is a freemium text-to-image model developed by Ideogram, Inc. using deep learning methodologies to generate digital images from natural language descriptions known as prompts. The model is capable of generating legible text in the images compared to other text-to-image models.
text-to-images-generation This repository implements a text-to-image generation model, allowing users to create images directly from textual descriptions. Utilizing a powerful deep learning architecture, the system takes a natural language prompt as input and generates a corresponding visual output, enabling creative expression and exploration of diverse visual concepts 📌 Overview This project is a Text-to-Image Generation Web App built with Gradio and powered by the FLUX.1-dev model from Hugging Face. Users can enter a text prompt, and the app will generate an AI-created image in real time. 🚀 Features 📝 Enter any text prompt. 🖼️ Generate high-quality images instantly. 📊 Built-in feedback options (average, good, bad). 🌍 Shareable interface via Gradio. 📂 Project Structure . ├── app.py # Main application file ├── requirements.txt # Project dependencies ├── README.md # Documentation 🛠️ Tech Stack Python Gradio – user interface can be changed as developer can change the user interface according to their need, and for the userfriendly Hugging Face Hub – model hosting & inference FLUX.1-dev model – text-to-image generation ⚡ Installation & Setup Clone the repository: git clone https://github.com/yourusername/text-to-image-flux.git cd text-to-image-flux Create a virtual environment (optional but recommended): python -m venv venv source venv/bin/activate # Mac/Linux venv\Scripts\activate # Windows Install dependencies: pip install -r requirements.txt Set up your Hugging Face API token: Go to Hugging Face Tokens . Create a token and copy it. Replace "use your own token" in app.py with your token. Run the application: python app.py 📊 Example Usage Input: "A futuristic city skyline at sunset in cyberpunk style" Output: (An AI-generated cyberpunk skyline image) 📈 Future Enhancements Add image-to-image generation. Enable style customization (anime, photorealistic, etc.). Deploy on Hugging Face Spaces / Streamlit Cloud. Add download option for generated images. 🙌 Contributors Deepesh Manju – AI/ML Aspirant & Developer
2. Related Work, Literature Survey & Algorithmic Foundations
This repository implements a text-to-image generation model, allowing users to create images directly from textual descriptions. Utilizing a powerful deep learning architecture, the system takes a natural language prompt as input and generates a corresponding visual output, enabling creative expression and exploration of diverse visual concepts
This project is a Text-to-Image Generation Web App built with Gradio and powered by the FLUX.1-dev model from Hugging Face. Users can enter a text prompt, and the app will generate an AI-created image in real time.
📂 Project Structure . ├── app.py # Main application file ├── requirements.txt # Project dependencies ├── README.md # Documentation
Gradio – user interface can be changed as developer can change the user interface according to their need, and for the userfriendly
git clone https://github.com/yourusername/text-to-image-flux.git cd text-to-image-flux
python -m venv venv source venv/bin/activate # Mac/Linux venv\Scripts\activate # Windows
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
This repository implements a text-to-image generation model, allowing users to create images directly from textual descriptions. Utilizing a powerful deep learning architecture, the system takes a natural language prompt as input and generates a corresponding visual output, enabling creative expression and exploration of diverse visual concepts
Text-to-Image Generation with Transformers and Diffusions Generative AI is evolving rapidly, revolutionizing every aspect of our lives and work. Text-to-image models, in particular, have gained significant attention due to their ability to translate natural language into visually rich, meaningful images. Models like OpenAI’s DALL-E series, Google’s Imagen, and Stability AI’s Stable Diffusion have shown unprecedented advances in the field of generative AI, turning abstract descriptions into detailed, highly creative visual representations. I focus on two ways of generating images from text prompts: vision Transformers (ViT) and diffusion models. In the first method, we divide an image into multiple patches and treat each patch as an element in a sequence. As a result, image generation becomes a sequence prediction problem. When generating an image based on a text prompt, we ask the trained Transformer to first predict the top left patch. In the next iteration, we feed the first patch, along with the prompt, to the ViT and ask it to predict the second patch. We repeat the process until we have all the needed patches in the image. You'll use "panda with top hat reading a book" as the text prompt. You’ll learn to load up the four components of the trained model: the text tokenizer, the BART encoder, the BART decoder, and the VQGAN detokenizer. You'll see how the prompt is converted to tokens, and then indexes, which are used as inputs to the BART encoder. The encoded text is then fed to the BART decoder to predict image tokens in an autoregressive fashion (the top left image patch first, then the one to the right, and so on). The decoded image tokens are fed to the VQGAN detokenizer to convert them into a high-resolution image for you to see on your computer. The generated image based on the prompt "panda with top hat reading a book" is shown below: We also select 8 intermediate steps to visualize how the image was generated step by step, as shown below. Better yet, in an animation, you'll visualize the intermediate steps of the image generation process. What does the image look like when only 25 of the 265 patches are generated? What if 58 patches are generated? and so on. The animation to illustrate the image generation process can be seen on my website here https://gattonweb.uky.edu/faculty/lium/v/minDALLE.gif . We display 8 images in the 2 by 4 grid. An image is divided into 256 patches, organized in a 16x16 grid. The top left image shows the output when 25 image patches are generated. The second image in the top row shows the output when 58 patches are generated. The rest images show the outputs when 91, 124, ..., and 256 patches are generated. The second way of text-to-image generation is based on diffusion models. We start with an image with pure noise. We ask the trained diffusion model to denoise it slightly, conditional on the text prompt. The result is a less noisy image. We repeat the process many times until we obtain a clean image that matches the text prompt. Diffusion models have become the go-to generative model by learning progressively removing noise from noisy images. They form the foundation of the state-of-the-art text-to-image models, including Imagen, DALL-E 2 (though not DALL-E), and Stable Diffusion. When we use the prompt "a banana riding a motorcycle with sunglasses and a straw hat," the generated image is below: Better yet, you can visualize the intermediate outputs from the diffusion model. In the image below, you see the generated image at different time steps during the reverse diffusion process. The left image shows that at time step t=800, the image looks close to pure noise. As we move to the right, the image starts to match the text prompt. At time step t=0, you can see a clean image of a banana riding a motorcycle. Diffusion models are also excellent image editors. In the figure below, the original horse image is in the middle. When we use the prompt "white horse on sunny beach" to edit the image, the result is shown on the left of the figure. When we use the prompt "zebra on snowy ground" to edit the image, the result is shown on the right of the figure.
Generative AI is evolving rapidly, revolutionizing every aspect of our lives and work. Text-to-image models, in particular, have gained significant attention due to their ability to translate natural language into visually rich, meaningful images. Models like OpenAI’s DALL-E series, Google’s Imagen, and Stability AI’s Stable Diffusion have shown unprecedented advances in the field of generative AI, turning abstract descriptions into detailed, highly creative visual representations.
I focus on two ways of generating images from text prompts: vision Transformers (ViT) and diffusion models. In the first method, we divide an image into multiple patches and treat each patch as an element in a sequence. As a result, image generation becomes a sequence prediction problem. When generating an image based on a text prompt, we ask the trained Transformer to first predict the top left patch. In the next iteration, we feed the first patch, along with the prompt, to the ViT and ask it to predict the second patch. We repeat the process until we have all the needed patches in the image.
You'll use "panda with top hat reading a book" as the text prompt. You’ll learn to load up the four components of the trained model: the text tokenizer, the BART encoder, the BART decoder, and the VQGAN detokenizer. You'll see how the prompt is converted to tokens, and then indexes, which are used as inputs to the BART encoder. The encoded text is then fed to the BART decoder to predict image tokens in an autoregressive fashion (the top left image patch first, then the one to the right, and so on). The decoded image tokens are fed to the VQGAN detokenizer to convert them into a high-resolution image for you to see on your computer. The generated image based on the prompt "panda with top hat reading a book" is shown below:
We also select 8 intermediate steps to visualize how the image was generated step by step, as shown below.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Better yet, in an animation, you'll visualize the intermediate steps of the image generation process. What does the image look like when only 25 of the 265 patches are generated? What if 58 patches are generated? and so on. The animation to illustrate the image generation process can be seen on my website here https://gattonweb.uky.edu/faculty/lium/v/minDALLE.gif .
We display 8 images in the 2 by 4 grid. An image is divided into 256 patches, organized in a 16x16 grid. The top left image shows the output when 25 image patches are generated. The second image in the top row shows the output when 58 patches are generated. The rest images show the outputs when 91, 124, ..., and 256 patches are generated.
The second way of text-to-image generation is based on diffusion models. We start with an image with pure noise. We ask the trained diffusion model to denoise it slightly, conditional on the text prompt. The result is a less noisy image. We repeat the process many times until we obtain a clean image that matches the text prompt. Diffusion models have become the go-to generative model by learning progressively removing noise from noisy images. They form the foundation of the state-of-the-art text-to-image models, including Imagen, DALL-E 2 (though not DALL-E), and Stable Diffusion.
When we use the prompt "a banana riding a motorcycle with sunglasses and a straw hat," the generated image is below:
Better yet, you can visualize the intermediate outputs from the diffusion model. In the image below, you see the generated image at different time steps during the reverse diffusion process. The left image shows that at time step t=800, the image looks close to pure noise. As we move to the right, the image starts to match the text prompt. At time step t=0, you can see a clean image of a banana riding a motorcycle.
Diffusion models are also excellent image editors. In the figure below, the original horse image is in the middle. When we use the prompt "white horse on sunny beach" to edit the image, the result is shown on the left of the figure. When we use the prompt "zebra on snowy ground" to edit the image, the result is shown on the right of the figure.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Build text-to-image generative AI models from scratch with Python and PyTorch. Focus on two methods: Diffusion models, which iteratively denoise to generate image conditional on text prompt, and vision Transformers, which treat an image as a sequence of patches, and generates one patch at a time.
text-to-image-generation-project.mp4 TEXT-TO-IMAGE-GENERATION Features Text-to-Image Transformation: Generate high-quality images from textual descriptions. Cutting-Edge Deep Learning: We harness the latest advancements in deep learning, powered by PyTorch, to create our models. Open-Source: This project is open for collaboration and welcomes contributions from the community. Easy Setup: Simple installation steps and clear usage instructions make it accessible to all. Customization: Fine-tune parameters to create a wide array of images to suit your needs. Libraries Used Our project relies on a powerful set of libraries to make text-to-image generation possible: mediapy: Manipulate images and videos, enabling dynamic content creation. torch: The PyTorch framework serves as the backbone for our deep learning models. sys: Essential for system-level operations and interactions. DiffusionPipeline: Enhances data preprocessing and augmentation. random: Injects randomness into the generation process, fostering diversity in the output. Getting Started (1) Clone this Repository git clone https://github.com/kiransindam/TEXT-TO-IMAGE-GENERATION.git (2) Install Required Libraries pip install -r requirements.txt (3) Generate Images from Text Prepare your text data in a file. Run the Text-to-Image Generator: python generate_images.py --input input.txt --output output_/ --input: Path to your text file. --output: Directory to save the generated images. Voilà! Witness your textual descriptions come to life as beautiful images. Acknowledgments We extend our gratitude to the vibrant open-source community and the pioneering researchers who have made this project possible. Your contributions to the world of deep learning and AI are truly inspiring. Join us on this exciting journey of Text-to-Image Generation! If you have any questions, ideas, or feedback, don't hesitate to reach out.
Text-to-Image Transformation: Generate high-quality images from textual descriptions. Cutting-Edge Deep Learning: We harness the latest advancements in deep learning, powered by PyTorch, to create our models. Open-Source: This project is open for collaboration and welcomes contributions from the community. Easy Setup: Simple installation steps and clear usage instructions make it accessible to all. Customization: Fine-tune parameters to create a wide array of images to suit your needs.
Libraries Used Our project relies on a powerful set of libraries to make text-to-image generation possible:
mediapy: Manipulate images and videos, enabling dynamic content creation. torch: The PyTorch framework serves as the backbone for our deep learning models. sys: Essential for system-level operations and interactions. DiffusionPipeline: Enhances data preprocessing and augmentation. random: Injects randomness into the generation process, fostering diversity in the output.
Getting Started (1) Clone this Repository git clone https://github.com/kiransindam/TEXT-TO-IMAGE-GENERATION.git (2) Install Required Libraries pip install -r requirements.txt (3) Generate Images from Text Prepare your text data in a file. Run the Text-to-Image Generator: python generate_images.py --input input.txt --output output_/ --input: Path to your text file. --output: Directory to save the generated images. Voilà! Witness your textual descriptions come to life as beautiful images.
Model Figures & Evaluation Curves (4 Images)
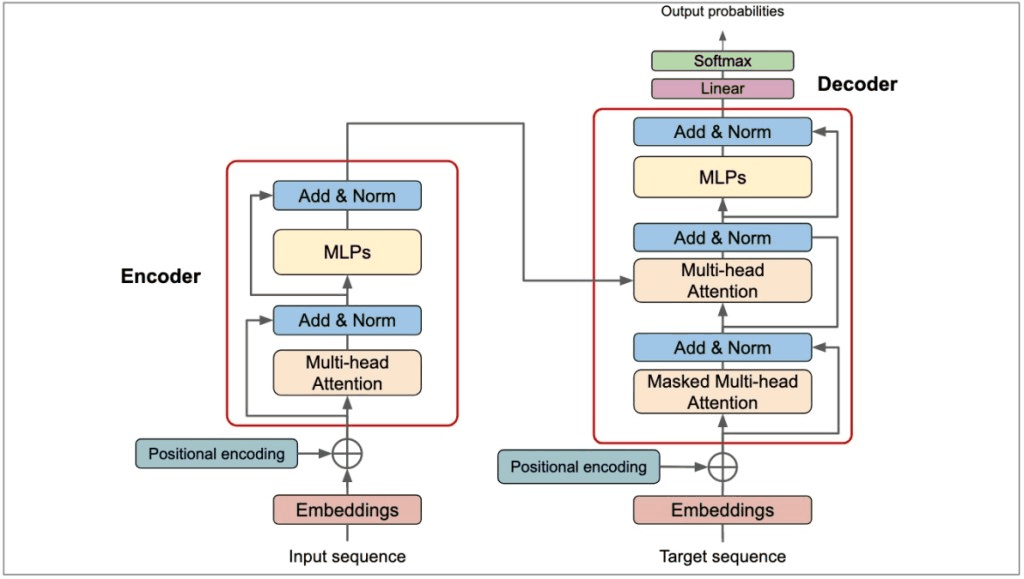
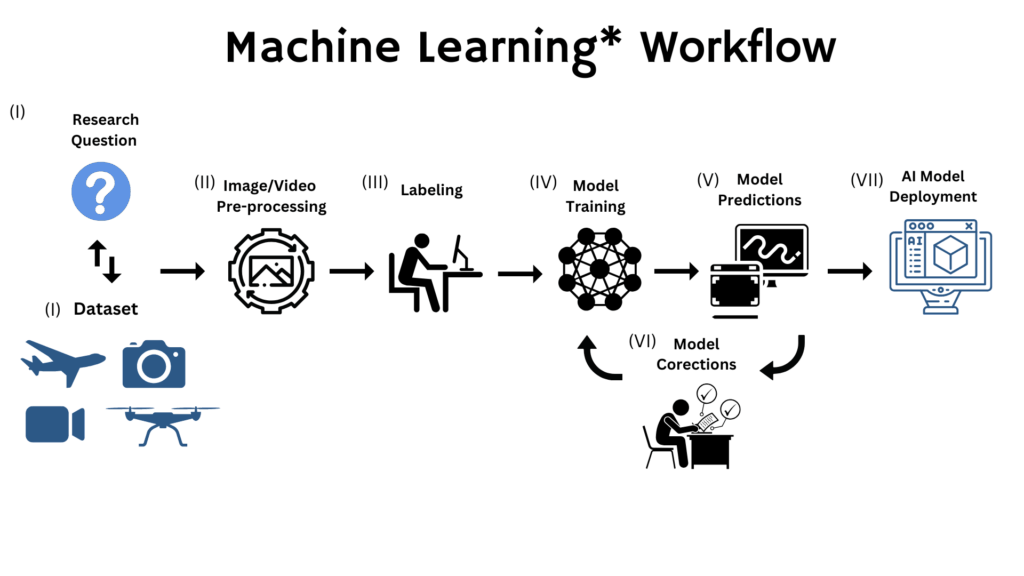
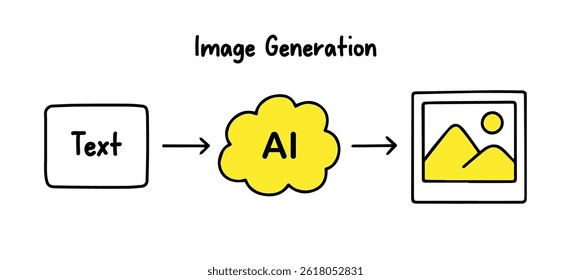
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)