Complete Technical Paper Content — Transformer Model Projects
1. Executive Abstract, Problem Formulation & Background
Plachtaa / VALL-E-X Star 7.9k An open source implementation of Microsoft's VALL-E X zero-shot TTS model. Demo is available in https://plachtaa.github.io/vallex/ text-to-speech tts gpt transformer-architecture emotional-speech voice-clone vall-e Updated Feb 11, 2024 Python
An open source implementation of Microsoft's VALL-E X zero-shot TTS model. Demo is available in https://plachtaa.github.io/vallex/
cmhungsteve / Awesome-Transformer-Attention Star 5k An ultimately comprehensive paper list of Vision Transformer/Attention, including papers, codes, and related websites computer-vision deep-learning transformers transformer awesome-list vit papers attention-mechanism attention-mechanisms self-attention transformer-architecture transformer-models detr vision-transformer transformer-cv transformer-with-cv transformer-awesome visual-transformer Updated Jul 30, 2024
An ultimately comprehensive paper list of Vision Transformer/Attention, including papers, codes, and related websites
tairov / llama2.mojo Star 2.1k Inference Llama 2 in one file of pure 🔥 performance modular mojo inference simd llama tensor vectorization parallelize transformer-architecture llama2 Updated Sep 30, 2026 Mojo
nlpodyssey / spago Star 1.9k Self-contained Machine Learning and Natural Language Processing library in Go nlp machine-learning natural-language-processing deep-learning neural-network automatic-differentiation artificial-intelligence recurrent-networks lstm computation-graph question-answering bart automatic-translation deeplearning language-model bert transformer-architecture bert-as-service named-entities-recognition Updated Apr 1, 2025 Go
Ma-Lab-Berkeley / CRATE Star 1.3k Code for CRATE (Coding RAte reduction TransformEr). compression sparsification transformer-architecture white-box-architecture Updated Oct 23, 2024 Python
awslabs / sockeye Star 1.2k Sequence-to-sequence framework with a focus on Neural Machine Translation based on PyTorch machine-learning deep-neural-networks translation deep-learning machine-translation pytorch transformer seq2seq neural-machine-translation sequence-to-sequence attention-mechanism encoder-decoder attention-model sequence-to-sequence-models attention-is-all-you-need sockeye transformer-architecture transformer-network Updated Oct 24, 2024 Python
Sequence-to-sequence framework with a focus on Neural Machine Translation based on PyTorch
berniwal / swin-transformer-pytorch Star 863 Implementation of the Swin Transformer in PyTorch. machine-learning deep-learning pytorch artificial-intelligence attention-model transformer-architecture transformer-pytorch Updated Mar 29, 2021 Python
joeynmt / joeynmt Star 712 Minimalist NMT for educational purposes education machine-translation transformer seq2seq neural-machine-translation nmt rnn-pytorch seq2seq-pytorch nmt-tutorial transformer-architecture pytorch-transformers nmt-frameworks joey-nmt Updated Jan 29, 2024 Python
linwhitehat / ET-BERT Star 681 The repository of ET-BERT, a network traffic classification model on encrypted traffic. The work has been accepted as The Web Conference (WWW) 2022 accepted paper. pytorch burst-analysis pre-training transformer-architecture mask-burst-modeling same-origin-burst-prediction encrypted-traffic-analysis Updated Jul 23, 2026 Python
The repository of ET-BERT, a network traffic classification model on encrypted traffic. The work has been accepted as The Web Conference (WWW) 2022 accepted paper.
wgcban / ChangeFormer Star 628 [IGARSS'22]: A Transformer-Based Siamese Network for Change Detection deep-learning pytorch remote-sensing satellite-imagery attention-mechanism climate-change siamese-network change-detection transformer-encoder transformer-architecture multi-temporal Updated Jan 31, 2024 Python
kyegomez / zeta Sponsor Star 604 Build high-performance AI models with modular building blocks tensorflow transformers pytorch openai attention-mechanism pytorch-tutorial attention-model pytorch-implementation transformer-architecture llms chatgpt ffns lucidrains Updated Oct 26, 2026 Python
cuiziteng / Illumination-Adaptive-Transformer Star 587 🌕 [BMVC 2022] You Only Need 90K Parameters to Adapt Light: A Light Weight Transformer for Image Enhancement and Exposure Correction. SOTA for low light enhancement, 0.004 seconds try this for pre-processing. image-reconstruction pytorch image-restoration image-enhancement low-level-vision transformer-architecture exposure-correction bmvc low-light-enhance transformer-models low-light-image-enhancement Updated Feb 27, 2024 Python
2. Related Work, Literature Survey & Algorithmic Foundations
🌕 [BMVC 2022] You Only Need 90K Parameters to Adapt Light: A Light Weight Transformer for Image Enhancement and Exposure Correction. SOTA for low light enhancement, 0.004 seconds try this for pre-processing.
google-research / maxvit Star 501 [ECCV 2022] Official repository for "MaxViT: Multi-Axis Vision Transformer". SOTA foundation models for classification, detection, segmentation, image quality, and generative modeling... image computer-vision architecture image-processing cnn transformer classification segmentation resnet object-detection mlp transformer-architecture vision-transformer Updated Jun 2, 2023 Jupyter Notebook
[ECCV 2022] Official repository for "MaxViT: Multi-Axis Vision Transformer". SOTA foundation models for classification, detection, segmentation, image quality, and generative modeling...
FudanNLP / CPT Star 492 CPT: A Pre-Trained Unbalanced Transformer for Both Chinese Language Understanding and Generation text-generation chinese pretrained-models ptms language-understanding transformer-architecture Updated Dec 30, 2022 Python
CPT: A Pre-Trained Unbalanced Transformer for Both Chinese Language Understanding and Generation
abdur75648 / Deep-Learning-Specialization-Coursera Star 477 This repo contains the updated version of all the assignments/labs (done by me) of Deep Learning Specialization on Coursera by Andrew Ng. It includes building various deep learning models from scratch and implementing them for object detection, facial recognition, autonomous driving, neural machine translation, trigger word detection, etc. nlp machine-learning computer-vision deep-learning tensorflow coursera recurrent-neural-networks lstm neural-networks face-recognition convolutional-neural-networks object-detection andrew-ng updated deep-learning-specialization deep-learning-coursera andrew-ng-machine-learning deep-learning-andrew-ng transformer-architecture unet-segmentation Updated Feb 9, 2024 Jupyter Notebook
This repo contains the updated version of all the assignments/labs (done by me) of Deep Learning Specialization on Coursera by Andrew Ng. It includes building various deep learning models from scratch and implementing them for object detection, facial recognition, autonomous driving, neural machine translation, trigger word detection, etc.
kyegomez / MultiModalMamba Sponsor Star 474 A novel implementation of fusing ViT with Mamba into a fast, agile, and high performance Multi-Modal Model. Powered by Zeta, the simplest AI framework ever. machine-learning ai ml transformers torch pytorch artificial-intelligence zeta attention-mechanism ssm mamba transformer-architecture Updated Oct 26, 2026 Python
A novel implementation of fusing ViT with Mamba into a fast, agile, and high performance Multi-Modal Model. Powered by Zeta, the simplest AI framework ever.
hkproj / transformer-from-scratch-notes Star 391 Notes about "Attention is all you need" video ( https://www.youtube.com/watch?v=bCz4OMemCcA ) notes transformer study-notes attention-model attention-is-all-you-need transformer-architecture Updated May 28, 2023
Notes about "Attention is all you need" video ( https://www.youtube.com/watch?v=bCz4OMemCcA )
sgrvinod / a-PyTorch-Tutorial-to-Transformers Star 388 Attention Is All You Need | a PyTorch Tutorial to Transformers pytorch transformer pytorch-tutorial attention-is-all-you-need transformer-architecture transformer-tutorial Updated Feb 22, 2024 Python
wjf5203 / SeqFormer Star 351 SeqFormer: Sequential Transformer for Video Instance Segmentation (ECCV 2022 Oral) transformer-architecture video-instance-segmentation Updated Aug 2, 2022 Python
ZixuanKe / PyContinual Star 323 PyContinual (An Easy and Extendible Framework for Continual Learning) natural-language-processing text-classification transfer-learning attention-mechanism knowledge-transfer capsule-network continual-learning catastrophic-forgetting transformer-architecture Updated Jan 29, 2024 Python
To associate your repository with the transformer-architecture topic, visit your repo's landing page and select "manage topics."
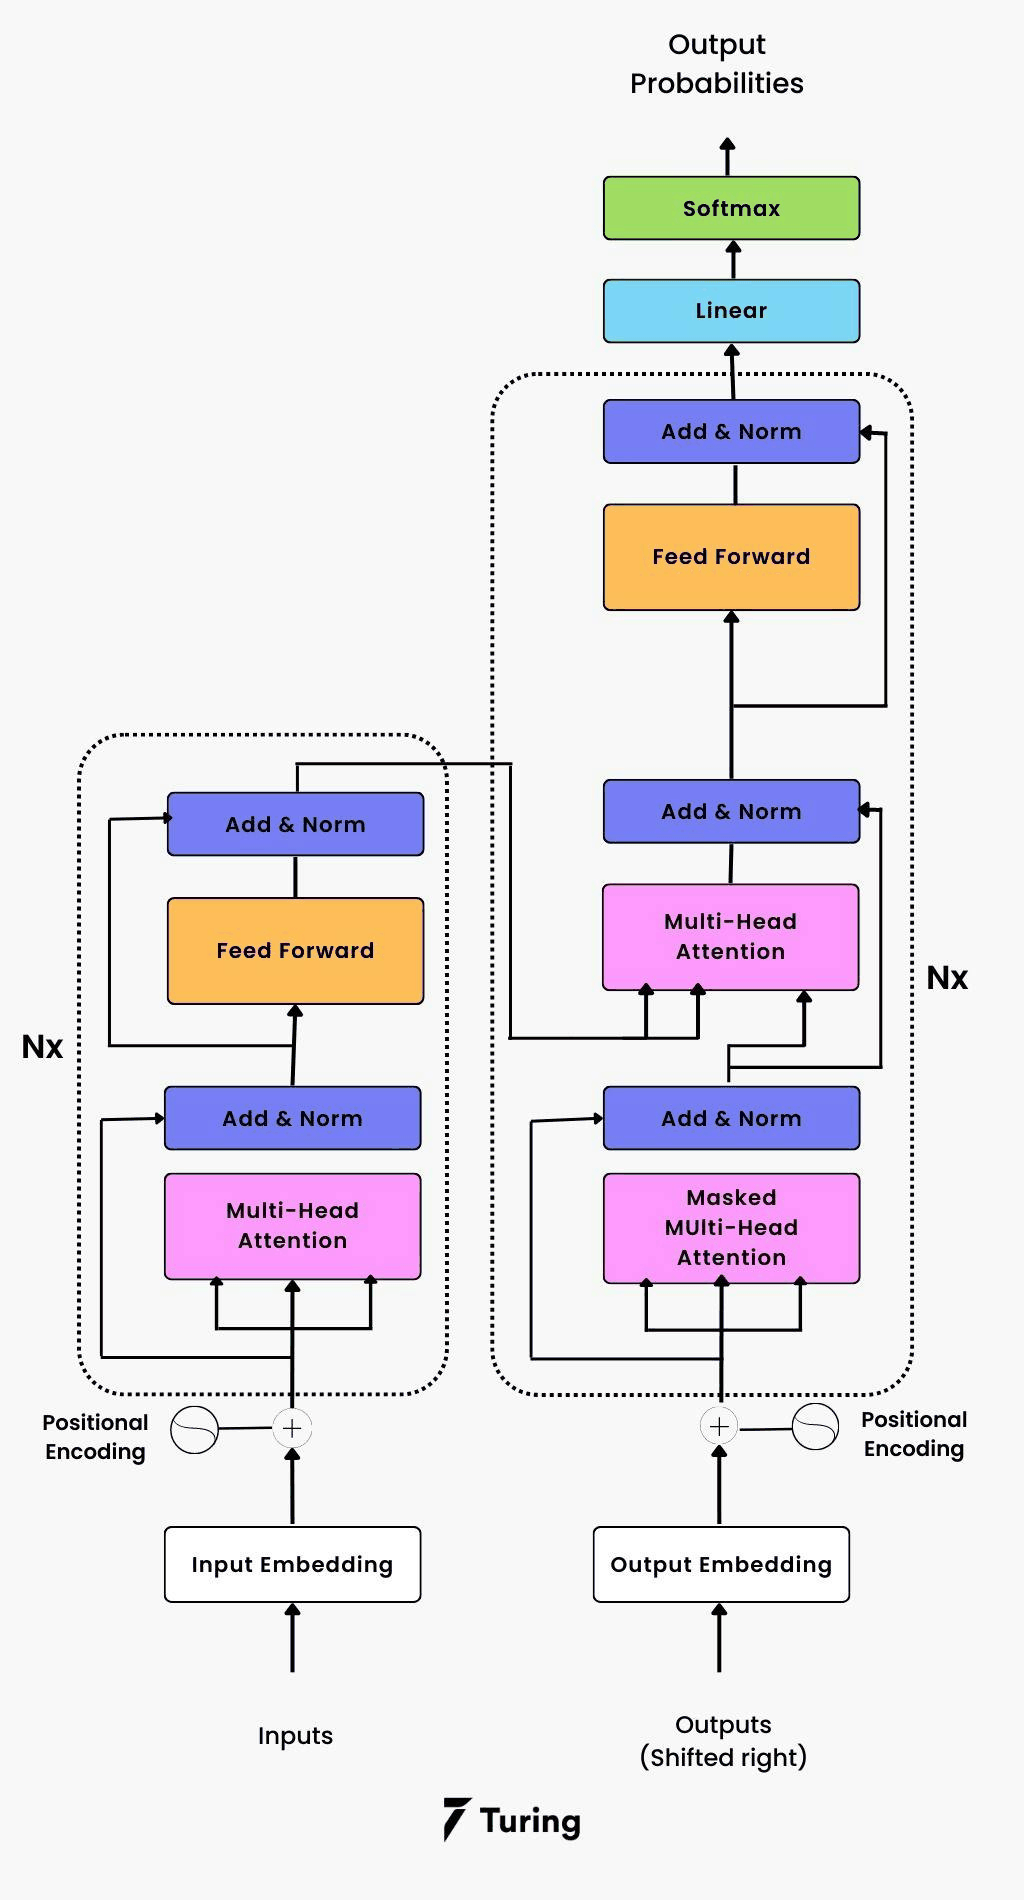
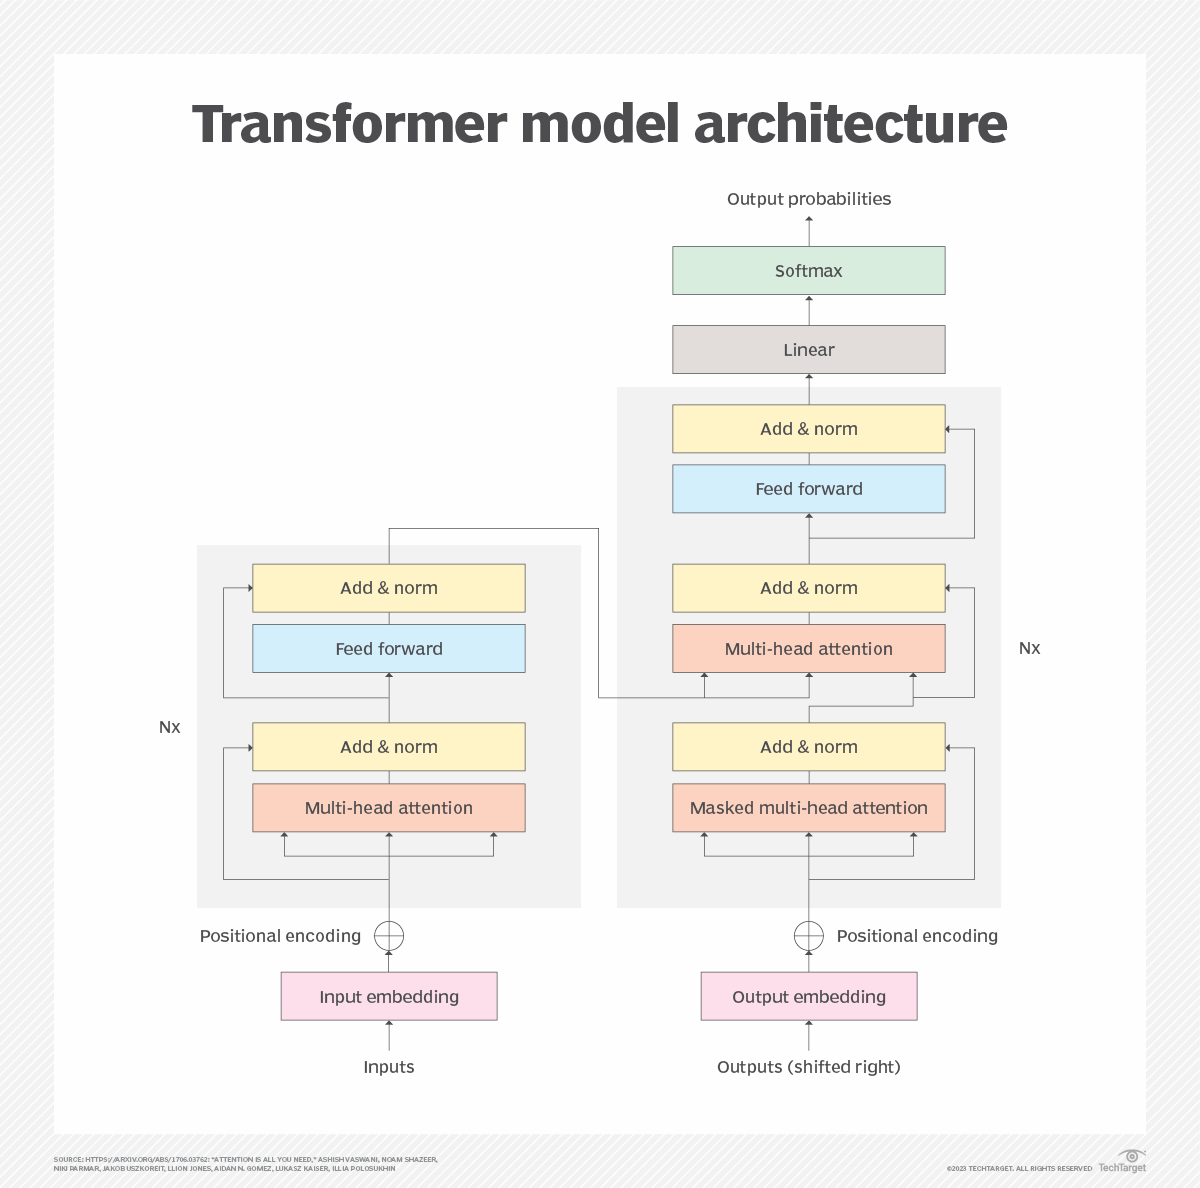
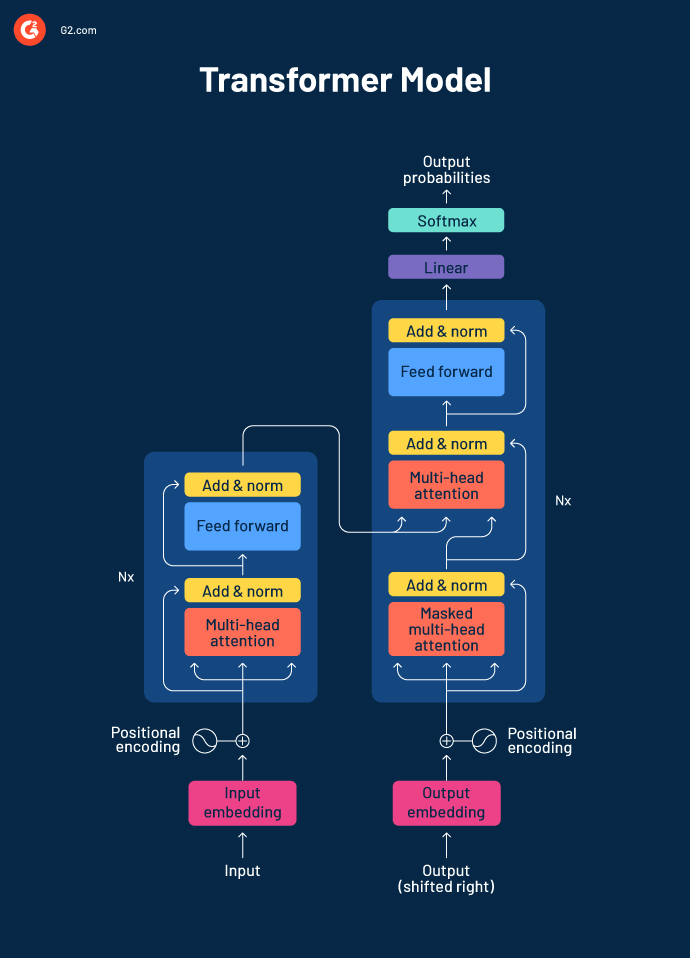
A transformer is a deep learning architecture based on self-attention mechanisms, designed to process sequential data in parallel. Transformers are the foundation of modern large language models and are widely used in natural language processing, computer vision, and generative AI.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
huggingface / transformers Star 168k 🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training. audio python nlp machine-learning natural-language-processing deep-learning pytorch transformer speech-recognition glm pretrained-models hacktoberfest gemma vlm pytorch-transformers model-hub llm qwen deepseek Updated Oct 29, 2026 Python
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
vllm-project / vllm Sponsor Star 95.8k A high-throughput and memory-efficient inference and serving engine for LLMs amd cuda inference pytorch transformer openai moe llama gpt model-serving tpu kimi blackwell llm llm-serving qwen deepseek deepseek-v3 qwen3 gpt-oss Updated Oct 29, 2026 Python
labmlai / annotated_deep_learning_paper_implementations Star 67.6k 🧑🏫 60+ Implementations/tutorials of deep learning papers with side-by-side notes 📝; including transformers (original, xl, switch, feedback, vit, ...), optimizers (adam, adabelief, sophia, ...), gans(cyclegan, stylegan2, ...), 🎮 reinforcement learning (ppo, dqn), capsnet, distillation, ... 🧠 machine-learning reinforcement-learning deep-learning transformers pytorch transformer gan neural-networks literate-programming attention lora deep-learning-tutorial optimizers Updated Oct 25, 2026 Python
🧑🏫 60+ Implementations/tutorials of deep learning papers with side-by-side notes 📝; including transformers (original, xl, switch, feedback, vit, ...), optimizers (adam, adabelief, sophia, ...), gans(cyclegan, stylegan2, ...), 🎮 reinforcement learning (ppo, dqn), capsnet, distillation, ... 🧠
ggml-org / whisper.cpp Star 54.8k Port of OpenAI's Whisper model in C/C++ inference transformer speech-recognition openai speech-to-text whisper Updated Oct 28, 2026 C++
sgl-project / sglang Star 38.3k SGLang is a high-performance serving framework for large language models and multimodal models. reinforcement-learning cuda inference transformer moe attention llama glm minimax wan diffusion vlm blackwell llm qwen deepseek gpt-oss qwen-image Updated Oct 29, 2026 Python
SGLang is a high-performance serving framework for large language models and multimodal models.
p-e-w / heretic Star 37.1k Fully automatic censorship removal for language models transformer llm abliteration Updated Oct 29, 2026 Python
fishaudio / fish-speech Star 33.5k SOTA Open Source TTS tts transformer llama valle vqvae vits vqgan Updated Oct 29, 2026 Python
open-mmlab / mmdetection Star 33k OpenMMLab Detection Toolbox and Benchmark pytorch fast-rcnn transformer yolo ssd faster-rcnn object-detection glip instance-segmentation mask-rcnn retinanet semisupervised-learning panoptic-segmentation cascade-rcnn detr vision-transformer swin-transformer convnext rtmdet grounding-dino Updated Aug 21, 2024 Python
SYSTRAN / faster-whisper Star 26.3k Faster Whisper transcription with CTranslate2 deep-learning inference transformer speech-recognition openai speech-to-text quantization whisper Updated Oct 25, 2026 Python
lukasmasuch / best-of-ml-python Star 23.8k 🏆 A ranked list of awesome machine learning Python libraries. Updated weekly. python nlp data-science machine-learning deep-learning tensorflow scikit-learn keras ml data-visualization pytorch transformer data-analysis gpt automl jax data-visualizations gpt-3 chatgpt Updated Oct 25, 2026
amusi / CVPR2026-Papers-with-Code Star 22.9k CVPR 2026 论文和开源项目合集 python machine-learning computer-vision deep-learning paper image-processing transformers transformer object-detection image-segmentation visual-tracking semantic-segmentation cvpr cvpr2020 cvpr2021 cvpr2022 cvpr2023 cvpr2024 cvpr2025 cvpr2026 Updated Mar 8, 2026
nndl / nndl Star 19.5k 邱锡鹏《神经网络与深度学习》第二版与通识版:电子书、章节目录、学习资源与勘误。 machine-learning deep-learning transformer neural-networks chinese textbook attention-mechanism Updated Sep 6, 2026
datawhalechina / leedl-tutorial Star 16.8k 《李宏毅深度学习教程》(李宏毅老师推荐👍,苹果书🍎),PDF下载地址: https://github.com/datawhalechina/leedl-tutorial/releases machine-learning tutorial reinforcement-learning deep-learning cnn transformer gan rnn pruning transfer-learning bert diffusion self-attention network-compression chatgpt leedl-tutorial Updated Oct 23, 2026 Jupyter Notebook
4. Neural Network Backbone, Layer Specifications & Loss Formulations
《李宏毅深度学习教程》(李宏毅老师推荐👍,苹果书🍎),PDF下载地址: https://github.com/datawhalechina/leedl-tutorial/releases
lukas-blecher / LaTeX-OCR Star 16.6k pix2tex: Using a ViT to convert images of equations into LaTeX code. python machine-learning ocr latex deep-learning image-processing pytorch dataset transformer vit image2text im2text im2latex im2markup math-ocr vision-transformer latex-ocr Updated Jan 18, 2025 Python
alibaba / MNN Star 16.3k MNN: A blazing-fast, lightweight inference engine battle-tested by Alibaba, powering high-performance on-device LLMs and Edge AI. machine-learning arm deep-learning vulkan ml transformer convolution embedded-devices mnn winograd-algorithm llm Updated Oct 29, 2026 C++
MNN: A blazing-fast, lightweight inference engine battle-tested by Alibaba, powering high-performance on-device LLMs and Edge AI.
GeeeekExplorer / nano-vllm Star 16.2k Nano vLLM nlp deep-learning inference pytorch transformer llm Updated Apr 26, 2026 Python
graykode / nlp-tutorial Star 14.9k Natural Language Processing Tutorial for Deep Learning Researchers nlp natural-language-processing tutorial tensorflow paper pytorch transformer attention bert Updated Feb 21, 2024 Jupyter Notebook
FlashML-org / FreeToken Star 14.8k FreeToken brings datacenter-scale model serving to your desktop. Run massive models locally, fast and efficiently. inference edge transformer moe glm minimax qwen deepseek-v4 Updated Oct 29, 2026 Python
FreeToken brings datacenter-scale model serving to your desktop. Run massive models locally, fast and efficiently.
BlinkDL / RWKV-LM Star 14.8k RWKV (pronounced RwaKuv) is an RNN with great LLM performance, which can also be directly trained like a GPT transformer (parallelizable). We are at RWKV-7 "Goose". So it's combining the best of RNN and transformer - great performance, linear time, constant space (no kv-cache), fast training, infinite ctx_len, and free sentence embedding. deep-learning transformers pytorch transformer lstm rnn gpt language-model attention-mechanism gpt-2 gpt-3 linear-attention rwkv chatgpt Updated Oct 27, 2026 Python
RWKV (pronounced RwaKuv) is an RNN with great LLM performance, which can also be directly trained like a GPT transformer (parallelizable). We are at RWKV-7 "Goose". So it's combining the best of RNN and transformer - great performance, linear time, constant space (no kv-cache), fast training, infinite ctx_len, and free sentence embedding.
EleutherAI / lm-evaluation-harness Star 14.3k A framework for few-shot evaluation of language models. transformer language-model evaluation-framework Updated Sep 14, 2026 Python
Clean uncommented version: https://gist.github.com/paulinamoskwa/e19db8eca5cfb09c775055f92e8192b1
Attention Is All You Need: Transformer from Scratch Project Aim The goal of this project is to have a deep understanding of deep learning concepts implementing a Transformer model from scratch using PyTorch. The Transformer, introduced in the groundbreaking paper "Attention Is All You Need" , revolutionized sequence modeling, especially in natural language processing (NLP) tasks like machine translation. This project walks through the steps to implement the Transformer architecture, understand its mathematical foundations, and apply it to a practical task—translating between languages using the Multi30k English-German dataset. Table of Contents Project Aim Mathematical Foundations Attention Mechanism Scaled Dot-Product Attention Multi-Head Attention Positional Encoding Encoder and Decoder Model Components Embedding Layer Multi-Head Attention Feedforward Network Encoder Decoder Transformer Setup and Installation Training Procedure Dataset Usage License Mathematical Foundations 1. Attention Mechanism The attention mechanism allows the model to focus on specific parts of the input sequence when generating output, which helps when dealing with long sequences. Each token in the input sequence is assigned a score representing its importance relative to other tokens. The attention mechanism is computed as follows: $$ \text{Attention}(Q, K, V) = \text{softmax}\left(\frac{QK^T}{\sqrt{d_k}}\right)V $$ Where: ( Q ) (Query): The matrix representing the token currently being attended to. ( K ) (Key): The matrix representing all the tokens in the sequence. ( V ) (Value): The matrix containing the values corresponding to each token. ( d_k ): The dimensionality of the keys, used to scale the dot product. 2. Scaled Dot-Product Attention The Scaled Dot-Product Attention takes the query and key matrices and computes their dot product. It is then scaled by ( \frac{1}{\sqrt{d_k}} ) to stabilize gradients during backpropagation. 3. Multi-Head Attention Multi-Head Attention allows the model to focus on multiple parts of the sequence simultaneously. Instead of performing a single attention operation, the input is split into multiple "heads," and attention is applied to each. The outputs are concatenated back together: $$ \text{MultiHead}(Q, K, V) = \text{Concat}(\text{head}_1, \text{head}_2, \dots, \text{head}_h) W^O $$ Each head is a separate instance of the Scaled Dot-Product Attention mechanism. 4. Positional Encoding Since Transformers do not have any recurrence or convolution, positional encoding is used to provide the model with information about the order of tokens in a sequence. This encoding is added to the token embeddings. $$ PE(pos, 2i) = \sin\left(\frac{pos}{10000^{2i/d_{\text{model}}}}\right) $$ $$ PE(pos, 2i+1) = \cos\left(\frac{pos}{10000^{2i/d_{\text{model}}}}\right) $$ Where: ( pos ) is the position of the token in the sequence. ( i ) is the index of the dimension. 5. Encoder and Decoder The Transformer uses an encoder-decoder architecture. Each encoder layer contains: A multi-head self-attention mechanism. A feedforward network. The decoder layers are similar but include an additional layer to attend to the encoder output. Model Components 1. Embedding Layer This layer converts input tokens into dense vectors of fixed size. 2. Multi-Head Attention The attention mechanism is split into several heads. The Scaled Dot-Product Attention is applied to each head, and the results are concatenated. 3. Feedforward Network A simple fully-connected neural network applied after each attention block to increase the model's capacity. 4. Encoder The encoder is a stack of multiple layers. Each layer contains a multi-head attention mechanism and a feedforward network. 5. Decoder The decoder is also a stack of multiple layers. In addition to the self-attention, it has an extra attention mechanism to attend to the encoder output. 6. Transformer Model Combines the encoder and decoder to form the complete model, where the encoder processes the input sequence, and the decoder generates the output sequence. Setup and Installation To run this project, you'll need to set up a Python environment and install the necessary dependencies. 1. Clone the Repository git clone https://github.com/BreaGG/Attention_Is_All_You_Need_From_Scratch cd Attention_Is_All_You_Need_From_Scratch 2. Set Up a Virtual Environment (optional) You can use Python's venv or conda to create a virtual environment for the project. python3.10 -m venv transformer-env source transformer-env/bin/activate # On Windows: .\transformer-env\Scripts\activate 3. Install Dependencies Install the required dependencies by running: pip install -r requirements.txt If you don't have the language models, install them using spaCy : python -m spacy download en_core_web_sm python -m spacy download de_core_news_sm 4. Directory Structure The key files are: data_preparation.py : Handles loading and tokenizing the dataset. train_transformer.py : Defines the training loop and the Transformer model. transformer_model.py : Contains the model implementation. requirements.txt : Defines the dependencies for the project. Training Procedure 1. Data Preparation The script data_preparation.py prepares the data using the Multi30k dataset for English-to-German translation. python data_preparation.py This script tokenizes the data, builds the vocabulary, and creates data loaders for the training process. 2. Training the Model The script train_transformer.py handles the training process: python train_transformer.py The model will be trained using the cross-entropy loss function, with padding tokens ignored. The training process uses backpropagation through time (BPTT), and the optimizer used is Adam. Dataset The Multi30k dataset is used for training and evaluation. It consists of English-German sentence pairs. The dataset is downloaded and preprocessed using torchtext . The tokenization is handled by spaCy . Usage Run Data Preparation : python data_preparation.py Train the Model : python train_transformer.py Adjust Hyperparameters : Modify the train_transformer.py script to adjust the number of epochs, learning rate, batch size, etc. License This project is licensed under the MIT License - see the LICENSE file for details.
The goal of this project is to have a deep understanding of deep learning concepts implementing a Transformer model from scratch using PyTorch. The Transformer, introduced in the groundbreaking paper "Attention Is All You Need" , revolutionized sequence modeling, especially in natural language processing (NLP) tasks like machine translation. This project walks through the steps to implement the Transformer architecture, understand its mathematical foundations, and apply it to a practical task—translating between languages using the Multi30k English-German dataset.
The attention mechanism allows the model to focus on specific parts of the input sequence when generating output, which helps when dealing with long sequences. Each token in the input sequence is assigned a score representing its importance relative to other tokens.
The Scaled Dot-Product Attention takes the query and key matrices and computes their dot product. It is then scaled by ( \frac{1}{\sqrt{d_k}} ) to stabilize gradients during backpropagation.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Multi-Head Attention allows the model to focus on multiple parts of the sequence simultaneously. Instead of performing a single attention operation, the input is split into multiple "heads," and attention is applied to each. The outputs are concatenated back together:
$$ \text{MultiHead}(Q, K, V) = \text{Concat}(\text{head}_1, \text{head}_2, \dots, \text{head}_h) W^O $$
Since Transformers do not have any recurrence or convolution, positional encoding is used to provide the model with information about the order of tokens in a sequence. This encoding is added to the token embeddings.
$$ PE(pos, 2i) = \sin\left(\frac{pos}{10000^{2i/d_{\text{model}}}}\right) $$ $$ PE(pos, 2i+1) = \cos\left(\frac{pos}{10000^{2i/d_{\text{model}}}}\right) $$
The decoder layers are similar but include an additional layer to attend to the encoder output.
The attention mechanism is split into several heads. The Scaled Dot-Product Attention is applied to each head, and the results are concatenated.
A simple fully-connected neural network applied after each attention block to increase the model's capacity.
The encoder is a stack of multiple layers. Each layer contains a multi-head attention mechanism and a feedforward network.
The decoder is also a stack of multiple layers. In addition to the self-attention, it has an extra attention mechanism to attend to the encoder output.
Combines the encoder and decoder to form the complete model, where the encoder processes the input sequence, and the decoder generates the output sequence.
To run this project, you'll need to set up a Python environment and install the necessary dependencies.
git clone https://github.com/BreaGG/Attention_Is_All_You_Need_From_Scratch cd Attention_Is_All_You_Need_From_Scratch
python3.10 -m venv transformer-env source transformer-env/bin/activate # On Windows: .\transformer-env\Scripts\activate
The script data_preparation.py prepares the data using the Multi30k dataset for English-to-German translation.
This script tokenizes the data, builds the vocabulary, and creates data loaders for the training process.
The model will be trained using the cross-entropy loss function, with padding tokens ignored. The training process uses backpropagation through time (BPTT), and the optimizer used is Adam.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)