Complete Technical Paper Content — Transformer Nlp Projects
1. Executive Abstract, Problem Formulation & Background
Awesome Transformer & Transfer Learning in NLP This repository contains a hand-curated list of great machine (deep) learning resources for Natural Language Processing (NLP) with a focus on Generative Pre-trained Transformer (GPT), Bidirectional Encoder Representations from Transformers (BERT), attention mechanism, Transformer architectures/networks, ChatGPT, and transfer learning in NLP. Transformer ( Source ) Table of Contents Expand Table of Contents Papers Articles BERT and Transformer Attention Mechanism Transformer Architecture Generative Pre-Training Transformer (GPT) ChatGPT Large Language Model (LLM) Transformer Reinforcement Learning Additional Reading Educational Tutorials AI Safety Videos BERTology Attention and Transformer Networks Official BERT Implementations Transformer Implementations By Communities PyTorch and TensorFlow PyTorch Keras TensorFlow Chainer Other Transfer Learning in NLP Books Other Resources Tools Tasks Named-Entity Recognition (NER) Classification Text Generation Question Answering (QA) Knowledge Graph Papers BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova. Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context by Zihang Dai, Zhilin Yang, Yiming Yang, William W. Cohen, Jaime Carbonell, Quoc V. Le and Ruslan Salakhutdinov. Uses smart caching to improve the learning of long-term dependency in Transformer. Key results: state-of-art on 5 language modeling benchmarks, including ppl of 21.8 on One Billion Word (LM1B) and 0.99 on enwiki8. The authors claim that the method is more flexible, faster during evaluation (1874 times speedup), generalizes well on small datasets, and is effective at modeling short and long sequences. Conditional BERT Contextual Augmentation by Xing Wu, Shangwen Lv, Liangjun Zang, Jizhong Han and Songlin Hu. SDNet: Contextualized Attention-based Deep Network for Conversational Question Answering by Chenguang Zhu, Michael Zeng and Xuedong Huang. Language Models are Unsupervised Multitask Learners by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever. The Evolved Transformer by David R. So, Chen Liang and Quoc V. Le. They used architecture search to improve Transformer architecture. Key is to use evolution and seed initial population with Transformer itself. The architecture is better and more efficient, especially for small size models. XLNet: Generalized Autoregressive Pretraining for Language Understanding by Zhilin Yang, Zihang Dai, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le. A new pretraining method for NLP that significantly improves upon BERT on 20 tasks (e.g., SQuAD, GLUE, RACE). "Transformer-XL is a shifted model (each hyper-column ends with next token) while XLNet is a direct model (each hyper-column ends with contextual representation of same token)." — Thomas Wolf . Comments from HN : A clever dual masking-and-caching algorithm. This is NOT "just throwing more compute" at the problem. The authors have devised a clever dual-masking-plus-caching mechanism to induce an attention-based model to learn to predict tokens from all possible permutations of the factorization order of all other tokens in the same input sequence. In expectation, the model learns to gather information from all positions on both sides of each token in order to predict the token. For example, if the input sequence has four tokens, ["The", "cat", "is", "furry"], in one training step the model will try to predict "is" after seeing "The", then "cat", then "furry". In another training step, the model might see "furry" first, then "The", then "cat". Note that the original sequence order is always retained, e.g., the model always knows that "furry" is the fourth token. The masking-and-caching algorithm that accomplishes this does not seem trivial to me. The improvements to SOTA performance in a range of tasks are significant -- see tables 2, 3, 4, 5, and 6 in the paper. CTRL: Conditional Transformer Language Model for Controllable Generation by Nitish Shirish Keskar, Richard Socher et al. [ Code ]. PLMpapers - BERT (Transformer, transfer learning) has catalyzed research in pretrained language models (PLMs) and has sparked many extensions. This repo contains a list of papers on PLMs. Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer by Google Brain. The group perform a systematic study of transfer learning for NLP using a unified Text-to-Text Transfer Transformer (T5) model and push the limits to achieve SoTA on SuperGLUE (approaching human baseline), SQuAD, and CNN/DM benchmark. [ Code ]. Reformer: The Efficient Transformer by Nikita Kitaev, Lukasz Kaiser, and Anselm Levskaya. "They present techniques to reduce the time and memory complexity of Transformer, allowing batches of very long sequences (64K) to fit on one GPU. Should pave way for Transformer to be really impactful beyond NLP domain." — @hardmaru Supervised Multimodal Bitransformers for Classifying Images and Text (MMBT) by Facebook AI. A Primer in BERTology: What we know about how BERT works by Anna Rogers et al. "Have you been drowning in BERT papers?". The group survey over 40 papers on BERT's linguistic knowledge, architecture tweaks, compression, multilinguality, and so on. tomohideshibata/BERT-related papers Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity by Google Brain. [Code] | [Blog post (unofficial)] Key idea: the architecture use a subset of parameters on every training step and on each example. Upside: model train much faster. Downside: super large model that won't fit in a lot of environments. An Attention Free Transformer by Apple. A Survey of Transformers by Tianyang Lin et al. Evaluating Large Language Models Trained on Code by OpenAI. Codex, a GPT language model that powers GitHub Copilot. They investigate their model limitations (and strengths). They discuss the potential broader impacts of deploying powerful code generation techs, covering safety, security, and economics. Training language models to follow instructions with human feedback by OpenAI. They call the resulting models InstructGPT . ChatGPT is a sibling model to InstructGPT. LaMDA: Language Models for Dialog Applications by Google. Training Compute-Optimal Large Language Models by Hoffmann et al. at DeepMind. TLDR: introduces a new 70B LM called "Chinchilla" that outperforms much bigger LMs (GPT-3, Gopher). DeepMind has found the secret to cheaply scale large language models — to be compute-optimal, model size and training data must be scaled equally. It shows that most LLMs are severely starved of data and under-trained. Given the new scaling law , even if you pump a quadrillion parameters into a model (GPT-4 urban myth), the gains will not compensate for 4x more training tokens. Improving language models by retrieving from trillions of tokens by Borgeaud et al. at DeepMind - The group explore an alternate path for efficient training with Internet-scale retrieval. The method is known as RETRO, for "Retrieval Enhanced TRansfOrmers". With RETRO the model is not limited to the data seen during training – it has access to the entire training dataset through the retrieval mechanism. This results in significant performance gains compared to a standard Transformer with the same number of parameters . RETRO obtains comparable performance to GPT-3 on the Pile dataset, despite using 25 times fewer parameters. They show that language modeling improves continuously as they increase the size of the retrieval database. [ blog post ] Scaling Instruction-Finetuned Language Models by Google - They find that instruction finetuning with the above aspects dramatically improves performance on a variety of model classes (PaLM, T5, U-PaLM), prompting setups (zero-shot, few-shot, CoT), and evaluation benchmarks. Flan-PaLM 540B achieves SoTA performance on several benchmarks. They also publicly release Flan-T5 checkpoints , which achieve strong few-shot performance even compared to much larger models, such as PaLM 62B. Emergent Abilities of Large Language Models by Google Research, Stanford University, DeepMind, and UNC Chapel Hill. Nonparametric Masked (NPM) Language Modeling by Meta AI et al. [ code ] - Nonparametric models with 500x fewer parameters outperform GPT-3 on zero-shot tasks. It, crucially, does not have a softmax over a fixed output vocabulary, but instead has a fully nonparametric distribution over phrases. This is in contrast to a recent (2022) body of work that incorporates nonparametric components in a parametric model. Results show that NPM is significantly more parameter-efficient, outperforming up to 500x larger parametric models and up to 37x larger retrieve-and-generate models. Transformer models: an introduction and catalog by Xavier Amatriain, 2023 - The goal of this paper is to offer a somewhat comprehensive but simple catalog and classification of the most popular Transformer models. The paper also includes an introduction to the most important aspects and innovation in Transformer models. Foundation Models for Decision Making: Problems, Methods, and Opportunities by Google Research et al., 2023 - A report of recent approaches (i.e., conditional generative modeling, RL, prompting) that ground pre-trained models (i.e., LMs) in practical decision making agents. Models can serve world dynamics or steer decisions. GPT-4 Technical Report by OpenAI, 2023. The Llama 3 Herd of Models by Llama Team, AI @ Meta, Jul 2024 - The paper, a oft-overlooked component of the project, proved to be just as vital, if not more so, than the model itself, and its significance came as a complete surprise. A masterpiece in its own right, the paper presented a treasure trove of detailed information on the model's pre-training and post-training processes, offering insights that were both profound and practical. [ Discussion ] Articles BERT and Transformer Open Sourcing BERT: State-of-the-Art Pre-training for Natural Language Processing from Google AI. The Illustrated BERT, ELMo, and co. (How NLP Cracked Transfer Learning) . Dissecting BERT by Miguel Romero and Francisco Ingham - Understand BERT in depth with an intuitive, straightforward explanation of the relevant concepts. A Light Introduction to Transformer-XL . Generalized Language Models by Lilian Weng, Research Scientist at OpenAI. What is XLNet and why it outperforms BERT Permutation Language Modeling objective is the core of XLNet. DistilBERT (from HuggingFace), released together with the blog post Smaller, faster, cheaper, lighter: Introducing DistilBERT, a distilled version of BERT . ALBERT: A Lite BERT for Self-supervised Learning of Language Representations paper from Google Research and Toyota Technological Institute. — Improvements for more efficient parameter usage: factorized embedding parameterization, cross-layer parameter sharing, and Sentence Order Prediction (SOP) loss to model inter-sentence coherence. [ Blog post | Code ] ELECTRA: Pre-training Text Encoders as Discriminators Rather Than Generators by Kevin Clark, Minh-Thang Luong, Quoc V. Le, and Christopher D. Manning - A BERT variant like ALBERT and cost less to train. They trained a model that outperforms GPT by using only one GPU; match the performance of RoBERTa by using 1/4 computation. It uses a new pre-training approach, called replaced token detection (RTD), that trains a bidirectional model while learning from all input positions. [ Blog post | Code ] Visual Paper Summary: ALBERT (A Lite BERT) Cramming: Training a Language Model on a Single GPU in One Day (paper) (2022) - While most in the community are asking how to push the limits of extreme computation, we ask the opposite question: How far can we get with a single GPU in just one day? ... Through the lens of scaling laws, we categorize a range of recent improvements to training and architecture and discuss their merit and practical applicability (or lack thereof) for the limited compute setting. What happened to BERT & T5? On Transformer Encoders, PrefixLM and Denoising Objectives by Yi Tay, Jul 2024 to recap, we don't see any scaled up xBERTs running around: BERT models got deprecated in favor of more flexible forms of denoising (autoregressive) T5 models. This is largely due to paradigm unification where people would like to perform any task with a general purpose model (as opposed to task specific model). Meanwhile, autoregressive denoising gets sometimes folded as side objectives to casual language models. Attention Mechanism Visualizing Attention, a Transformer's Heart Neural Machine Translation by Jointly Learning to Align and Translate by Dzmitry Bahdanau, KyungHyun Cho, and Yoshua Bengio, 2014 - Bahdanau invented the content-based neural attention that is now a core tool in deep-learning-based NLP (language models) . A disadvantage of fixed-length context vector design is incapability of remembering long sentences. The attention mechanism was born to resolve this problem. It was born to help memorize long input sentences in language translation. [ Bahdanau deserve the praise ] The Annotated Transformer by Harvard NLP Group - Further reading to understand the "Attention is all you need" paper. Attention? Attention! - Attention guide by Lilian Weng from OpenAI. Visualizing A Neural Machine Translation Model (Mechanics of Seq2seq Models With Attention) by Jay Alammar, an Instructor from Udacity ML Engineer Nanodegree. Making Transformer networks simpler and more efficient - FAIR released an all-attention layer to simplify the Transformer model and an adaptive attention span method to make it more efficient (reduce computation time and memory footprint). What Does BERT Look At? An Analysis of BERT’s Attention paper by Stanford NLP Group. Fast Transformer Decoding: One Write-Head is All You Need (paper) by Noam Shazeer, Google (2019) - They proposed a variant of attention type called multi-query attention (MQA). The plain multi-head attention mechanism has one query, key, and value per head; multi-query instead shares one key and value across all of the different attention "heads" . In practice, training time remains the same, but much faster to decode in inference . MQA significantly improves language models performance and efficiency. Users can get ~10x better throughput and ~30% lower latency on inference. However, MQA can lead to quality degradation, and moreover it may not be desirable to train a separate model just for faster inference. In 2022, PaLM, a decoder-style model and their use of MQA is an interesting architecture improvements over GPT. Recent models that use MQA include TII's Falcon (2023). GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints by Google Research, 2023 - They (1) propose a technique for uptraining existing multi-head attention (MHA) models into models with multi-query attention (MQA) using 5% of original pre-training compute, and (2) introduce grouped-query attention (GQA) , a generalization of MQA which uses an intermediate (more than one, less than number of query heads) number of key-value heads. GQA achieves benefits close to MHA with comparable inference speed to MQA through reduced number of key-value heads. Models that use MQA include Meta's Llama 2 (2023). [ Some Tweets ] Ring Attention with Blockwise Transformers for Near-Infinite Context by UC Berkeley, 2023 - Ring Attention is a system-level optimization technique by leveraging specific hardware architecture to make the exact attention computation more efficient. Leave No Context Behind: Efficient Infinite Context Transformers with Infini-attention by Google, 2024 - Infini-attention has an additional compressive memory with linear attention for processing infinitely long contexts. They trained a 1B parameter Transformer model that was fine-tuned on up to 5K sequence length passkey instances solves the 1M tokens input length problem. The Infini-attention mechanism presents an efficient and powerful approach for Transformer language models to process very long contexts without prohibitive increases in memory or computation. Retrieval Head Mechanistically Explains Long-Context Factuality by Wenhao Wu, Yao Fu et al., 2024 - The paper explains how LLMs actually deal with context windows. The findings: they discover LLMs have unexpectedly developed retrieval heads, they were not explicitly coded for by creators. [Code: An algorithm that statistically calculate the retrieval score of attention heads in a transformer model ] Transformer Architecture The Transformer blog post . The Illustrated Transformer by Jay Alammar, an Instructor from Udacity ML Engineer Nanodegree. Watch Łukasz Kaiser’s talk walking through the model and its details. Transformer-XL: Unleashing the Potential of Attention Models by Google Brain. Generative Modeling with Sparse Transformers by OpenAI - an algorithmic improvement of the attention mechanism to extract patterns from sequences 30x longer than possible previously. Stabilizing Transformers for Reinforcement Learning paper by DeepMind and CMU - they propose architectural modifications to the original Transformer and XL variant by moving layer-norm and adding gating creates Gated Transformer-XL (GTrXL). It substantially improve the stability and learning speed (integrating experience through time) in RL. The Transformer Family by Lilian Weng - since the paper "Attention Is All You Need", many new things have happened to improve the Transformer model. This post is about that. DETR ( DE tection TR ansformer): End-to-End Object Detection with Transformers by FAIR - 🔥 Computer vision has not yet been swept up by the Transformer revolution. DETR completely changes the architecture compared with previous object detection systems. ( PyTorch Code and pretrained models ). "A solid swing at (non-autoregressive) end-to-end detection. Anchor boxes + Non-Max Suppression (NMS) is a mess. I was hoping detection would go end-to-end back in ~2013)" — Andrej Karpathy Transformers for software engineers - This post will be helpful to software engineers who are interested in learning ML models, especially anyone interested in Transformer interpretability. The post walk through a (mostly) complete implementation of a GPT-style Transformer, but the goal will not be running code; instead, they use the language of software engineering and programming to explain how these models work and articulate some of the perspectives they bring to them when doing interpretability work. Pathways Language Model (PaLM): Scaling to 540 Billion Parameters for Breakthrough Performance - PaLM is a dense decoder-only Transformer model trained with the Pathways system, which enabled Google to efficiently train a single model across multiple TPU v4 Pods. The example explaining a joke is remarkable. This shows that it can generate explicit explanations for scenarios that require a complex combination of multi-step logical inference, world knowledge, and deep language understanding. Efficient Long Sequence Modeling via State Space Augmented Transformer (paper) by Georgia Institute of Technology and Microsoft - The quadratic computational cost of the attention mechanism limits its practicality for long sequences. There are existing attention variants that improve the computational efficiency, but they have limited ability to effectively compute global information. In parallel to Transformer models, state space models (SSMs) are tailored for long sequences, but they are not flexible enough to capture complicated local information. They propose SPADE, short for State sPace AugmenteD TransformEr, which performs various baselines, including Mega, on the Long Range Arena benchmark and various LM tasks. This is an interesting direction. SSMs and Transformers were combined a while back. DeepNet: Scaling Transformers to 1,000 Layers (paper) by Microsoft Research (2022) - The group introduced a new normalization function (DEEPNORM) to modify the residual connection in Transformer and showed that model updates can be bounded in a stable way . This improve the training stability of deep Transformers and scale the model depth by orders of magnitude (10x) compared to Gpipe (pipeline parallelism) by Google Brain (2019). (who remembers what ResNet (2015) did to ConvNet?) A Length-Extrapolatable Transformer (paper) by Microsoft (2022) [ TorchScale code ] - This improves modeling capability of scaling Transformers. Hungry Hungry Hippos (H3): Towards Language Modeling with State Space Models (SSMs) (paper) by Stanford AI Lab (2022) - A new language modeling architecture. It scales nearly linearly with context size instead of quadratically . No more fixed context windows, long context for everyone. Despite that, SSMs are still slower than Transformers due to poor hardware utilization. So, a Transformer successor? [ Tweet ] Accelerating Large Language Model Decoding with Speculative Sampling (paper) by DeepMind (2023) - Speculative sampling algorithm enable the generation of multiple tokens from each transformer call. Achieves a 2–2.5x decoding speedup with Chinchilla in a distributed setup, without compromising the sample quality or making modifications to the model itself. A Survey on Efficient Training of Transformers (paper) by Monash University et al., 2023 - The first systematic overview, covering 1) computation efficiency; optimization (i.e., sparse training) and data selection (i.e., token masking), 2) memory efficiency (i.e, data/model parallelism, offloading/use external mem) and 3) hardware/algorithm co-design (i.e, efficient attention, hardware-aware low-precisio). Deep Transformers without Shortcuts: Modifying Self-attention for Faithful Signal Propagation (paper) by DeepMind et al., 2023 Hyena Hierarchy: Towards Larger Convolutional Language Models (paper) by Stanford U et al., 2023 - Attention is great. Hyena is an alternative to attention that can learn on sequences 10x longer , up to 100x faster than optimized attention, by using implicit long convolutions and gating. [ Tweet ] FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness (paper) by Stanford University et al., 2022 - Transformers have grown deeper and wider, but training them on long sequences remains difficult. The attention layer at their heart is the compute and memory bottleneck: doubling the sequence length would quadruple the runtime and memory requirements. FlashAttention is a new algorithm to speed up attention and reduce its memory footprint—without any approximation. It enables training LLMs with longer context. [ code ] Jump to Conclusions: Short-Cutting Transformers With Linear Transformations (paper) by Google Research et al., 2023. [ Tweet ] CoLT5: Faster Long-Range Transformers with Conditional Computation (paper) by Google Research, 2023 - 64K context size for language models! This approach enables faster training and inference while maintaining or improving performance compared to LONGT5. The main components of COLT5 include routing modules, conditional feedforward layers, and conditional attention layers. Routing modules select important tokens for each input and component, while the light branches process all tokens with lower capacity operations, and heavy branches apply higher capacity operations only on selected important tokens. Additionally, COLT5 incorporates multi-query cross-attention for faster inference speed as well as UL2 pre-training objective for improved in-context learning capabilities over long inputs. [ Tweet ] google-research/meliad - The Meliad library is collection of models which are being developed as part of ongoing Google research into various architectural improvements in deep learning. The library currently consists of several transformer variations, which explore ways in which the popular transformer architecture can be extended to better support language modeling over long sequences. The variations are Memorizing Transformer, Transformer with sliding window, Block-Recurrent Transformer, and more. LongNet: Scaling Transformers to 1,000,000,000 Tokens (paper) by Microsoft Research, 2023. vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention by UC Berkeley et al., 2023 - The improved throughput comes from VRAM savings on an otherwise close to fullly utilized GPU. The Secret Sauce behind 100K context window in LLMs: all tricks in one place Unlimiformer: Long-Range Transformers with Unlimited Length Input (paper) by CMU, 2023. PaLM 2 Technical Report (PDF) by Google, 2023. Mixture-of-Depths (MoD): Dynamically allocating compute in transformer-based language models by Google DeepMind et al., 2024 - MoD method scale in depth dimension while keeping the FLOPs constant (similarly how Mixture of Experts (MoE) does it in width). MoD model can learn to route more complex tokens through more layers (similarly how experts in MoE can specialize to certain domains). The group explores how to optimize compute budget and improve efficiency without sacrificing performance. Results: MoD matches baseline performance with 66% faster training. Now, the question is, can it scale above 1B tokens. They tested on 500M tokens. [ELI5 version: Mixture of Depths Meets Mixture of Experts ] Extending Context Window of Large Language Models via Positional Interpolation by Meta Platforms, 2023 - Position Interpolation (PI) is an effective and efficient way to stably extend the context window of RoPE-based pretrained large language models such as LLaMA to much longer lengths (up to 32768) with minimal fine-tuning (within thousandth steps) while maintaining performance. PoSE: Efficient Context Window Extension of LLMs via Positional Skip-wise Training by Dawei Zhu et al., ICLR 2024 - PoSE simulates longer input sequences during training by manipulating the position indices within a fixed context window, rather than training on the full target length. This allows decoupling of the training length from the target context length, greatly reducing memory and computational requirements compared to full-length fine-tuning. PoSE successfully extended LLaMA-1 to support context lengths up to 128k tokens using only a 2k training window, with minimal performance degradation. This model uses PoSE to extend Llama-3 8B context length from 8k to 64k. PoSE has potential to scale context lengths even further, limited only by inference memory, as efficient inference techniques continue improving. [Code: PoSE ] Better & Faster Large Language Models via Multi-token Prediction by FAIR at Meta, Apr 2024 - What happens if we make language models predict several tokens ahead instead of only the next one? They show that replacing next token prediction tasks with multiple token prediction can result in substantially better code generation performance with the exact same training budget and data — while also increasing inference performance by 3x . While similar approaches have previously been used in fine-tuning to improve inference speed, this research expands to pre-training for large models, showing notable behaviors and results at these scales . nGPT: Normalized Transformer with Representation Learning on the Hypersphere by NVIDIA, Oct 2024 - A novel Transformer architecture where all vectors (embeddings, MLP, attention matrices, hidden states) are normalized to unit norm and operate on a hypersphere. Achieves 4-20x faster convergence during training compared to standard Transformers. Eliminates the need for weight decay by enforcing normalization. Normalization approach: matrix-vector multiplications become dot products bounded in [-1,1]. Architecture changes: 1) Attention mechanism - normalizes QKV projection matrices, introduces trainable scaling factors for Q-K dot products, 2) Layer structure: introduces learnable "eigen learning rates" (α) for attention and MLP blocks. Theoretical: can be interpreted in the context of Riemannian optimization. Advantages: more stable training, improved performance on downstream tasks, simplified architecture. Differential Transformer by Microsoft Research et al., Oct 2024 - They presents significant improvements over standard Transformers in multiple dimensions, with particular emphasis on attention efficiency and practical applications in LM tasks. A new architecture that improves attention mechanisms by reducing attention to irrelevant context. Achieves better performance while requiring fewer parameters and training tokens compared to standard Transformers. Solution: introduces "differential attention" mechanism that calculates attention scores as the difference between two separate softmax attention. This subtraction cancel out noise. It can be implemented efficiently using existing FlashAttention. Scaling efficiency: needs only ~65% of parameters or training tokens to match standard Transformer performance . Improvements: 1) Better performance on long sequences up to 64K tokens. 2) Better at finding key information embedded in documents. 3) ICL: more robust to prompt order permutations. 4) Reduces attention misallocation, a primary cause of hallucinations. Technical details: includes headwise normalization to handle sparse attention patterns, etc. Future: development of efficient low-bit attention kernels, potential for compressing KV caches due to sparser attention patterns, etc. [Listen to NotebookLM podcast ] Generative Pre-Training Transformer (GPT) GPT visualization Better Language Models and Their Implications . Improving Language Understanding with Unsupervised Learning - this is an overview of the original OpenAI GPT model. 🦄 How to build a State-of-the-Art Conversational AI with Transfer Learning by Hugging Face. The Illustrated GPT-2 (Visualizing Transformer Language Models) by Jay Alammar. MegatronLM: Training Billion+ Parameter Language Models Using GPU Model Parallelism by NVIDIA ADLR. OpenGPT-2: We Replicated GPT-2 Because You Can Too - the authors trained a 1.5 billion parameter GPT-2 model on a similar sized text dataset and they reported results that can be compared with the original model. MSBuild demo of an OpenAI generative text model generating Python code [video] - The model that was trained on GitHub OSS repos. The model uses English-language code comments or simply function signatures to generate entire Python functions. Cool! GPT-3: Language Models are Few-Shot Learners (paper) by Tom B. Brown (OpenAI) et al. - "We train GPT-3, an autoregressive language model with 175 billion parameters 😱, 10x more than any previous non-sparse language model, and test its performance in the few-shot setting." elyase/awesome-gpt3 - A collection of demos and articles about the OpenAI GPT-3 API. How GPT3 Works - Visualizations and Animations by Jay Alammar. GPT-Neo - Replicate a GPT-3 sized model and open source it for free. GPT-Neo is "an implementation of model parallel GPT2 & GPT3-like models, with the ability to scale up to full GPT3 sizes (and possibly more!), using the mesh-tensorflow library." [ Code ]. GitHub Copilot , powered by OpenAI Codex - Codex is a descendant of GPT-3. Codex translates natural language into code. GPT-4 Rumors From Silicon Valley - GPT-4 is almost ready. GPT-4 would be multimodal, accepting text, audio, image, and possibly video inputs. Release window: Dec - Feb. #hype New GPT-3 model: text-Davinci-003 - Improvements: Handle more complex intents — you can get even more creative with how you make use of its capabilities now. Higher quality writing — clearer, more engaging, and more compelling content. Better at longer form content generation. GPT-4 research landing page. A Comprehensive Capability Analysis of GPT-3 and GPT-3.5 Series Models by Fudan University et al., 2023. Sparks of Artificial General Intelligence: Early experiments with GPT-4 by Microsoft Research, 2023 - There are completely mind-blowing examples in the paper. ChatGPT What is ChatGPT? TL;DR: ChatGPT is a conversational web interface, backed by OpenAI's newest language model fine-tuned from a model in the GPT-3.5 series (which finished training in early 2022), optimized for dialogue. It is trained using Reinforcement Learning from Human Feedback (RLHF); human AI trainers provide supervised fine-tuning by playing both sides of the conversation. It's evidently better than GPT-3 at following user instructions and context. People have noticed ChatGPT's output quality seems to represent a notable improvement over previous GPT-3 models. For more, please take a look at ChatGPT Universe . This is my fleeting notes on everything I understand about ChatGPT and stores a collection of interesting things about ChatGPT. Large Language Model (LLM) ChatGPT among the LLMs 1 GPT-J-6B - Can't access GPT-3? Here's GPT-J — its open-source cousin. Fun and Dystopia With AI-Based Code Generation Using GPT-J-6B - Prior to GitHub Copilot tech preview launch, Max Woolf, a data scientist tested GPT-J-6B's code "writing" abilities. GPT-Code-Clippy (GPT-CC) - An open source version of GitHub Copilot. The GPT-CC models are fine-tuned versions of GPT-2 and GPT-Neo. GPT-NeoX-20B - A 20 billion parameter model trained using EleutherAI’s GPT-NeoX framework. They expect it to perform well on many tasks. You can try out the model on GooseAI playground. Metaseq - A codebase for working with Open Pre-trained Transformers (OPT) . YaLM 100B by Yandex is a GPT-like pretrained language model with 100B parameters for generating and processing text. It can be used freely by developers and researchers from all over the world. BigScience's BLOOM-176B from the Hugging Face repository [ paper , blog post ] - BLOOM is a 175-billion parameter model for language processing, able to generate text much like GPT-3 and OPT-175B. It was developed to be multilingual, being deliberately trained on datasets containing 46 natural languages and 13 programming languages. bitsandbytes-Int8 inference for Hugging Face models - You can run BLOOM-176B/OPT-175B easily on a single machine, without performance degradation. If true, this could be a game changer in enabling people outside of big tech companies being able to use these LLMs. WeLM: A Well-Read Pre-trained Language Model for Chinese (paper) by WeChat. [ online demo ] GLM-130B: An Open Bilingual (Chinese and English) Pre-Trained Model (code and paper) by Tsinghua University, China [ article ] - One of the major contributions is making LLMs cost affordable using int4 quantization so it can run in limited compute environments. The resultant GLM-130B model offers significant outperformance over GPT-3 175B on a wide range of popular English benchmarks while the performance advantage is not observed in OPT-175B and BLOOM-176B. It also consistently and significantly outperforms ERNIE TITAN 3.0 260B -- the largest Chinese language model -- across related benchmarks. Finally, we leverage a unique scaling property of GLM-130B to reach INT4 quantization, without quantization aware training and with almost no performance loss , making it the first among 100B-scale models. More importantly, the property allows its effective inference on 4×RTX 3090 (24G) or 8×RTX 2080 Ti (11G) GPUs, the most ever affordable GPUs required for using 100B-scale models . Teaching Small Language Models to Reason (paper) - They finetune a student model on the chain of thought (CoT) outputs generated by a larger teacher model. For example, the accuracy of T5 XXL on GSM8K improves from 8.11% to 21.99% when finetuned on PaLM-540B generated chains of thought. ALERT: Adapting Language Models to Reasoning Tasks (paper) by Meta AI - They introduce ALERT, a benchmark and suite of analyses for assessing language models' reasoning ability comparing pre-trained and finetuned models on complex tasks that require reasoning skills to solve. It covers 10 different reasoning skills including logistic, causal, common-sense, abductive, spatial, analogical, argument and deductive reasoning as well as textual entailment, and mathematics. Evaluating Human-Language Model Interaction (paper) by Stanford University and Imperial College London - They find that non-interactive performance does not always result in better human-LM interaction and that first-person and third-party metrics can diverge, suggesting the importance of examining the nuances of human-LM interaction. Unnatural Instructions: Tuning Language Models with (Almost) No Human Labor (paper) by Meta AI [ data ] - Fine-tuning a T5 on a large dataset collected with virtually no human labor leads to a model that surpassing the performance of models such as T0++ and Tk-Instruct across various benchmarks. These results demonstrate the potential of model-generated data as a cost-effective alternative to crowdsourcing for dataset expansion and diversification . OPT-IML (OPT + Instruction Meta-Learning) (paper) by Meta AI - OPT-IML is a set of instruction-tuned versions of OPT, on a collection of ~2000 NLP tasks — for research use cases. It boosts the performance of the original OPT-175B model using instruction tuning to improve zero-shot and few-shot generalization abilities — allowing it to adapt for more diverse language applications (i.e., answering Q’s, summarizing text). This improves the model's ability to better process natural instruction style prompts. Ultimately, humans should be able to "talk" to models as naturally and fluidly as possible. [ code (available soon), weights released ] jeffhj/LM-reasoning - This repository contains a collection of papers and resources on reasoning in Large Language Models. Rethinking with Retrieval: Faithful Large Language Model Inference (paper) by University of Pennsylvania et al., 2022 - They shows the potential of enhancing LLMs by retrieving relevant external knowledge based on decomposed reasoning steps obtained through chain-of-thought (CoT) prompting. I predict we're going to see many of these types of retrieval-enhanced LLMs in 2023. REPLUG: Retrieval-Augmented Black-Box Language Models (paper) by Meta AI et al., 2023 - TL;DR: Enhancing GPT-3 with world knowledge — a retrieval-augmented LM framework that combines a frozen LM with a frozen/tunable retriever. It improves GPT-3 in language modeling and downstream tasks by prepending retrieved documents to LM inputs. [ Tweet ] Progressive Prompts: Continual Learning for Language Models (paper) by Meta AI et al., 2023 - Current LLMs have hard time with catastrophic forgetting and leveraging past experiences. The approach learns a prompt for new task and concatenates with frozen previously learned prompts. This efficiently transfers knowledge to future tasks. [ code ] Large Language Models Can Be Easily Distracted by Irrelevant Context (paper) by Google Research et al., 2023 - Adding the instruction "Feel free to ignore irrelevant information given in the questions." consistently improves robustness to irrelevant context. Toolformer: Language Models Can Teach Themselves to Use Tools (paper) by Meta AI, 2023 - A smaller model trained to translate human intention into actions (i.e. decide which APIs to call, when to call them, what arguments to pass, and how to best incorporate the results into future token prediction). ERNIE 3.0 Titan: Exploring Larger-scale Knowledge Enhanced Pre-training for Language Understanding and Generation (paper) by Baidu et al., 2021 - ERNIE 3.0 Titan is the latest addition to Baidu's ERNIE (Enhanced Representation through kNowledge IntEgration) family. It's inspired by the masking strategy of Google's BERT. ERNIE is also a unified framework. They also proposed a controllable learning algorithm and a credible learning algorithm. They apply online distillation technique to compress their model. To their knowledge, it is the largest (260B parameters) Chinese dense pre-trained model so far. [ article ] Characterizing Attribution and Fluency Tradeoffs for Retrieval-Augmented Large Language Models (paper) by Google Research, 2023 - Despite recent progress, it has been difficult to prevent semantic hallucinations in generative LLMs. One common solution to this is augmenting LLMs with a retrieval system and making sure that the generated output is attributable to the retrieved information. Augmented Language Models (ALMs): a Survey (paper) by Meta AI, 2023 - Augmenting language models with reasoning skills and the ability to use various, non-parametric external modules for context processing and outperform traditional LMs on several benchmarks. This new research direction has the potential to address interpretability, consistency and scalability issues. A Comprehensive Survey on Pretrained Foundation Models: A History from BERT to ChatGPT (paper) by MSU et al., 2023 - My remarks: this paper raises a lot of questions around the term "foundation models", i.e., what's the model bare minimum number of parameters to qualify as foundation? It sounds to me foundation models are an "invented" concept that doesn't have good validity. Multimodal Chain-of-Thought Reasoning in Language Models (paper) by Amazon Web Service et al., 2023 - The model outperform GPT-3.5 by 16% on the ScienceQA benchmark. This work is the first to study CoT reasoning in different modalities, language (text) and vision (images). Unfortunately, they never provide ablation study on how much of that performance gain was caused by the new modalities. [ code ] RECITE: Recitation-Augmented Language Models (paper) by Google Research et al., ICLR 2023 - How can ChatGPT-like models achieve greater factual accuracy without relying on an external retrieval search engine? This paper shows that recitation can help LLMs generate accurate factual knowledge by reciting relevant passages from their own memory (by sampling) before producing final answers. The core idea is motivated by the intuition: recite-step that recollects relevant knowledge pieces helps answer-step (generation) better output. That's a recite-answer paradigm: first ask the LLM to generate the support paragraphs that contain the answer (knowledge-recitation) and then use it as additional prompt, along with the question to ask the LLM to generate the answer. They verify the effectiveness on four LLMs. They also show that recitation can be more effective than retrieval. This is important since having a retriever may lead to unpredictable behavior (i.e., Bing/Sydney). [ code ] LLaMA: Open and Efficient Foundation Language Models (paper) by Meta AI, 2023 - A collection of language models ranging from 7B to 65B parameters. LLaMA-13B outperforms GPT-3 (175B) on most benchmarks, and LLaMA-65B is competitive with the best models, Chinchilla70B and PaLM-540B. This shows that smaller models trained with more data can outperform larger models . This is not contradictory to anything in the Chinchilla paper , because it's not compute-optimally trained. GPU hours for training 7B model=82,432, 65B model=1,022,362 😱. Total time spent for all models: 2048 A100-80GB GPU for a period of approximately 5 months. The 65B model cost something in the range of ~$1-4M. Access to the model will be granted on a case-by-case basis though. People interested can apply for access. (Mar 2: they just approved access to the models , llama-7B works in Colab cedrickchee/llama ) [Takeaways: Tweet ] Language Is Not All You Need: Aligning Perception with Language Models (paper) by Microsoft, 2023 - They introduce KOSMOS-1, a Multimodal Large Language Model (MLLM) that can perceive general modalities, learn in context (i.e., few-shot), and follow instructions (i.e., zero-shot). The total number of parameters is about 1.6B. Check Your Facts and Try Again: Improving Large Language Models with External Knowledge and Automated Feedback by Microsoft Research et al - LLM-Augmenter significantly reduces ChatGPT's hallucinations without sacrificing the fluency and informativeness of its responses. The architecture and data flow: 1) Retrieve evidence from external knowledge. 2) Context and reasoning chains. 3) Give to LLM (i.e., ChatGPT). 4) Verify hallucinations. 5) If hallucinate, give feedback and revise. UL2: Unifying Language Learning Paradigms (paper) by Google Brain, 2022 - UL2 is a unified framework for pretraining models that are universally effective across datasets and setups. Takeaways: Objective matters way more than architecture. Mixture-of-Denoisers (MoD) is effective if you care about doing well on more than one type of tasks/settings. UL2 frames different objective functions for training language models as denoising tasks, where the model has to recover missing sub-sequences of a given input. During pre-training it uses Mixture-of-Denoisers (MoD) that samples from a varied set of such objectives, each with different configurations. MoD combines diverse pre-training paradigms together. They demonstrated that models trained using the UL2 framework perform well in a variety of language domains, including prompt-based few-shot learning and models fine-tuned for down-stream tasks. They open sourced UL2 20B model and checkpoints back in 2022. In 2023, they open sourced Flan-UL2 20B and released the weights. Check out: [ blog post , Tweet ]. I'm excited to see what the community does with this new model. Larger language models do in-context learning (ICL) differently (paper) by Google Research, 2023 - Overriding semantic priors when presented with enough flipped labels is an emergent ability of scale. LLMs learn better mappings when ICL labels are semantically unrelated to inputs (i.e., apple/orange, negative/positive). Fine-tuning to follow instruction helps both. [ Tweet ] The BigScience ROOTS Corpus: A 1.6TB Composite Multilingual Dataset (paper) by Hugging Face et al., 2023 - Documents the data creation and curation efforts of Responsible Open-science Open-collaboration Text Source (ROOTS) corpus, a dataset used to train BLOOM. [ Tweet ] PanGu-Σ: Towards Trillion Parameter Language Model with Sparse Heterogeneous Computing (paper) by Huawei Technologies, 2023 - They develop a system that trained a trillion-parameter language model on a cluster of Ascend 910 AI processors and MindSpore framework. This resulted in a 6.3x increase in training throughput through heterogeneous computing. Context-faithful Prompting for Large Language Models (paper) by USC et al., 2023 Llama 2: Open Foundation and Fine-Tuned Chat Models (paper) by Meta AI, 2023 - Llama 2 pretrained models are trained on 2 trillion tokens, and have double the context length than Llama 1. Its fine-tuned models have been trained on over 1 million human annotations. It outperforms other open source language models on many benchmarks. License: The model and weights are available for free for research and commercial use. It is not an open source model, rather an open approach model — for commercial use, your product cannot have more than 700 million monthly active users and requires a form to get access. Llama-2-chat is the new addition and is created through using supervised fine-tuning and then iteratively refined using RLHF. [ Nathan Lambert's summary of the paper ] Code Llama: Open Foundation Models for Code (paper) by Meta AI, 2023 - Code Llama is a family of LLMs for code based on Llama 2 providing SoTA performance among open models, infilling capabilities, support for large input contexts, and zero-shot instruction following ability for programming tasks. It is capable of generating code, and natural language about code, from both code and natural language prompts. It's available in three models: foundation models (Code Llama), Python specializations (Code Llama - Python), and instruction-following models (Code Llama - Instruct) with 7B, 13B and 34B parameters each. It outperformed publicly available LLMs benchmark on code tasks. They release it under the same permissive license (community license) as Llama 2. Introducing Llama 3: The most capable openly available LLM to date (article) by Meta AI, 2024 - In the coming months, they’ll share the Llama 3 research paper. [ Code ] Gemini 1.5: Unlocking multimodal understanding across millions of tokens of context by Google, May 2024 - The Gemini 1.5 model family technical report. Highlights: Gemini 1.5 Pro is now Google's most capable model (surpassing 1.0 Ultra), Gemini 1.5 models achieve near-perfect recall on long-context retrieval tasks across modalities, improvement in next-token prediction and near-perfect retrieval (>99%) up to at least 10M tokens. Transformer Reinforcement Learning Transformer Reinforcement Learning from Human Feedback (RLHF). Illustrating Reinforcement Learning from Human Feedback - Recent advances with language models (ChatGPT for example) have been powered by RLHF. Training a Helpful and Harmless Assistant with RLHF (paper) by Anthropic. [ code and red teaming data , tweet ] The Wisdom of Hindsight Makes Language Models Better Instruction Followers (paper) by UC Berkeley, 2023 - The underlying RLHF algo is complex and requires an additional training pipeline for reward and value networks. They consider an alternative approach, Hindsight Instruction Relabeling (HIR): converting feedback to instruction by relabeling the original one and training the model for better alignment. From r to Q∗: Your Language Model is Secretly a Q-Function by Stanford University, Apr 2024 - The paper bridges the gap between two approaches to RLHF - the standard RLHF setup and Direct Preference Optimization (DPO) - by deriving DPO as a general inverse Q-learning algorithm in a token-level MDP (Markov Decision Process). The authors provide empirical insights into the benefits of DPO, including its ability to perform credit assignment, and demonstrate improvements over the base DPO policy using simple beam search, with potential applications in multi-turn dialogue, reasoning, and agentic systems . Iterative Reasoning Preference Optimization (IRPO) by Jason Weston (Meta) et al., May 2024 - Llama-2-70B-Chat improves from 55.6% to 81.6% on GSM8K with this method. They apply iterative preference optimization to improve reasoning: generate chain-of-thought candidates with LLM, construct preference pairs based on if answer is correct or not, train with DPO + NLL, and repeat. For example, imagine a group of people trying to decide how to allocate a limited budget. Each person has their own priorities and preferences for how the money should be spent. Using the IRPO approach, the group would engage in a back-and-forth discussion, with each person adjusting their preferences based on the arguments and compromises made by the others. Over time, the group would converge on a set of preferences that everyone can accept, even if it's not exactly what any one person wanted initially. Tools for RLHF lvwerra/TRL - Train transformer language models with reinforcement learning. Open source effort towards ChatGPT: CarperAI/TRLX - Originated as a fork of TRL. It allows you to fine-tune Hugging Face language models (GPT2, GPT-NeoX based) up to 20B parameters using Reinforcement Learning. Brought to you by CarperAI (born at EleutherAI, an org part of StabilityAI family). CarperAI is developing production ready open-source RLHF tools. They have announced plans for the first open-source "instruction-tuned" LM . allenai/RL4LMs - RL for language models (RL4LMs) by Allen AI. It's a modular RL library to fine-tune language models to human preferences. Additional Reading How to Build OpenAI's GPT-2: "The AI That's Too Dangerous to Release" . OpenAI’s GPT2 - Food to Media hype or Wake Up Call? How the Transformers broke NLP leaderboards by Anna Rogers. 🔥🔥🔥 A well put summary post on problems with large models that dominate NLP these days. Larger models + more data = progress in Machine Learning research ❓ Transformers From Scratch tutorial by Peter Bloem. Real-time Natural Language Understanding with BERT using NVIDIA TensorRT on Google Cloud T4 GPUs achieves 2.2 ms latency for inference. Optimizations are open source on GitHub. NLP's Clever Hans Moment has Arrived by The Gradient. Language, trees, and geometry in neural networks - a series of expository notes accompanying the paper, "Visualizing and Measuring the Geometry of BERT" by Google's People + AI Research (PAIR) team. Benchmarking Transformers: PyTorch and TensorFlow by Hugging Face - a comparison of inference time (on CPU and GPU) and memory usage for a wide range of transformer architectures. Evolution of representations in the Transformer - An accessible article that presents the insights of their EMNLP 2019 paper. They look at how the representations of individual tokens in Transformers trained with different objectives change. The dark secrets of BERT - This post probes fine-tuned BERT models for linguistic knowledge. In particular, the authors analyse how many self-attention patterns with some linguistic interpretation are actually used to solve downstream tasks. TL;DR: They are unable to find evidence that linguistically interpretable self-attention maps are crucial for downstream performance. A Visual Guide to Using BERT for the First Time - Tutorial on using BERT in practice, such as for sentiment analysis on movie reviews by Jay Alammar. Turing-NLG: A 17-billion-parameter language model by Microsoft that outperforms the state of the art on many downstream NLP tasks. This work would not be possible without breakthroughs produced by the DeepSpeed library (compatible with PyTorch) and ZeRO optimizer , which can be explored more in this accompanying blog post . MUM (Multitask Unified Model): A new AI milestone for understanding information by Google. Based on transformer architecture but more powerful. Multitask means: supports text and images, knowledge transfer between 75 languages, understand context and go deeper in a topic, and generate content. GPT-3 is No Longer the Only Game in Town - GPT-3 was by far the largest AI model of its kind last year (2020). Now? Not so much. OpenAI's API Now Available with No Waitlist - GPT-3 access without the wait. However, apps must be approved before going live . This release also allow them to review applications, monitor for misuse, and better understand the effects of this tech. The Inherent Limitations of GPT-3 - One thing missing from the article if you've read Gwern's GPT-3 Creative Fiction article before is the mystery known as "Repetition/Divergence Sampling": when you generate free-form completions, they have a tendency to eventually fall into repetitive loops of gibberish. For those using Copilot, you should have experienced this wierdness where it generates the same line or block of code over and over again. Language Modelling at Scale: Gopher, Ethical considerations, and Retrieval by DeepMind - The paper present an analysis of Transformer-based language model performance across a wide range of model scales — from models with tens of millions of parameters up to a 280 billion parameter model called Gopher. Competitive programming with AlphaCode by DeepMind - AlphaCode uses transformer-based language models to generate code that can create novel solutions to programming problems which require an understanding of algorithms. Building games and apps entirely through natural language using OpenAI's code-davinci model - The author built several small games and apps without touching a single line of code, simply by telling the model what they want. Open AI gets GPT-3 to work by hiring an army of humans to fix GPT’s bad answers GPT-3 can run code - You provide an input text and a command and GPT-3 will transform them into an expected output. It works well for tasks like changing coding style, translating between programming languages, refactoring, and adding doc. For example, converts JSON into YAML, translates Python code to JavaScript, improve the runtime complexity of the function. Using GPT-3 to explain how code works by Simon Willison. Character AI announces they're building a full stack AGI company so you could create your own AI to help you with anything, using conversational AI research. The co-founders Noam Shazeer (co-invented Transformers, scaled them to supercomputers for the first time, and pioneered large-scale pretraining) and Daniel de Freitas (led the development of LaMDA), all of which are foundational to recent AI progress. How Much Better is OpenAI’s Newest GPT-3 Model? - In addition to ChatGPT, OpenAI releases text-davinci-003, a Reinforcement Learning-tuned model that performs better long-form writing. Example, it can explain code in the style of Eminem. 😀 OpenAI rival Cohere launches language model API - Backed by AI experts, they aims to bring Google-quality predictive language to the masses. Aidan Gomez co-wrote a seminal 2017 paper at Google Brain that invented a concept known as "Transformers". Startups competing with OpenAI's GPT-3 all need to solve the same problems - Last year, two startups released their own proprietary text-generation APIs. AI21 Labs, launched its 178-billion-parameter Jurassic-1 in Aug 2021, and Cohere, released a range of models. Cohere hasn't disclosed how many parameters its models contain. ... There are other up-and-coming startups looking to solve the same issues. Anthropic, the AI safety and research company started by a group of ex-OpenAI employees. Several researchers have left Google Brain to join two new ventures started by their colleagues. One outfit is named Character.ai, and the other Persimmon Labs. Cohere Wants to Build the Definitive NLP Platform - Beyond generative models like GPT-3. Transformer Inference Arithmetic technical write-up from Carol Chen, ML Ops at Cohere. This article presents detailed few-principles reasoning about LLM inference performance, with no experiments or difficult math. State of AI Report 2022 - Key takeaways: New independent research labs are rapidly open sourcing the closed source output of major labs. AI safety is attracting more talent... yet remains extremely neglected. OpenAI's Codex, which drives GitHub Copilot, has impressed the computer science community with its ability to complete code on multiple lines or directly from natural language instructions. This success spurred more research in this space. DeepMind revisited LM scaling laws and found that current LMs are significantly undertrained: they’re not trained on enough data given their large size. They train Chinchilla, a 4x smaller version of their Gopher, on 4.6x more data, and find that Chinchilla outperforms Gopher and other large models on BIG-bench. Reinforcement Learning from Human Feedback (RLHF) has emerged as a key method to finetune LLMs and align them with human values. This involves humans ranking language model outputs sampled for a given input, using these rankings to learn a reward model of human preferences, and then using this as a reward signal to finetune the language model with using RL. The Scaling Hypothesis by Gwern - On GPT-3: meta-learning, scaling, implications, and deep theory. AI And The Limits Of Language — An AI system trained on words and sentences alone will never approximate human understanding by Jacob Browning and Yann LeCun - What LLMs like ChatGPT can and cannot do, and why AGI is not here yet. Use GPT-3 foundational models incorrectly: reduce costs 40x and increase speed by 5x - When fine-tuning a model, it is important to keep a few things in mind. There's still a lot to learn about working with these models at scale. We need a better guide. The Next Generation Of Large Language Models - It highlights 3 emerging areas: 1) models that can generate their own training data to improve themselves, 2) models that can fact-check themselves, and 3) massive sparse expert models. GPT-4 analysis and predictions - Somehow related, in "Bing Chat is blatantly, aggressively misaligned" post, Gwern think how Bing Chat/Sydney can be so different from ChatGPT and his hypothesis: "Sydney is not a RLHF trained GPT-3 model but a GPT-4 model developed in a hurry". Some have also argued that Sydney performs better on reasoning tasks than ChatGPT/GPT-3.5 and it may be GPT-4. Mosaic LLMs (Part 2): GPT-3 quality for <$500k (2022) - They claimed their Composer PyTorch framework ease model training. Now with Colossal-AI framework, I wonder how good is their solution. Until their users train it, I guess everything is purely hypothetical. I made a transformer by hand (no training!) (2023) - Make a transformer to predict a simple sequence manually — not by training one, or using pretrained weights, but instead by assigning each weight, by hand , over an evening. Finetune Llama 3.1 on GCP for production use cases Educational transformer-explainer.mp4 Live Demo Demo Video minGPT by Andrej Karpathy - A PyTorch re-implementation of GPT, both training and inference. minGPT tries to be small, clean, interpretable and educational, as most of the currently available GPT model implementations can a bit sprawling. GPT is not a complicated model and this implementation is appropriately about 300 lines of code. nanoGPT - It's a re-write of minGPT. Still under active development. The associated and ongoing video lecture series Neural Networks: Zero to Hero , build GPT, from scratch, in code and aspire to spell everything out. Note that Karpathy's bottom up approach and fast.ai teaching style work well together. (FYI, fast.ai has both top-down ("part 1") and bottom-up ("part 2") approach.) A visual intro to large language models (LLMs) by Jay Alammar/Cohere - A high-level look at LLMs and some of their applications for language processing. It covers text generation models (like GPT) and representation models (like BERT). Interfaces for Explaining Transformer Language Models by Jay Alammar - A gentle visual to Transformer models by looking at input saliency and neuron activation inside neural networks. Our understanding of why these models work so well, however, still lags behind these developments . The GPT-3 Architecture, on a Napkin PicoGPT: GPT in 60 Lines of NumPy Video explainer about the core of transformer architecture (2023) - Read The Illustrated Transformer, but still didn't feel like you had an intuitive understanding of what the various pieces of attention were doing? In this video, a more constructive approach to explaining the transformer and attention can help you understand it better: starting from a simple convolutional neural network (CNN), the author will step you through all of the changes that need to be made to a CNN to become a transformer. A Hackers' Guide to Language Models (video) (2023) by Jeremy Howard, fast.ai - A quick run through all the basic ideas of language models, how to use them (both open models and OpenAI-based models) using code as much as possible. Tutorials How to train a new language model from scratch using Transformers and Tokenizers tutorial by Hugging Face. 🔥 AI Safety Interpretability research and AI alignment research. Transformer Circuits Thread project by Anthropic - Can we reverse engineer transformer language models into human-understandable computer programs? Interpretability research benefits a lot from interactive articles. As part of their effort, they've created several other resources besides their paper like "A Mathematical Framework for Transformer Circuits" and "toy models of superposition" . Discovering Language Model Behaviors with Model-Written Evaluations (paper) by Anthropic et al. - They automatically generate evaluations with LMs. They discover new cases of inverse scaling where LMs get worse with size. They also find some of the first examples of inverse scaling in RLHF, where more RLHF makes LMs worse. Transformers learn in-context by gradient descent (paper) by J von Oswald et al. [ AI Alignment Forum ] Why Can GPT Learn In-Context? Language Models Secretly Perform Gradient Descent as Meta-Optimizers (paper) by Microsoft Research. Cognitive Biases in Large Language Models Tracr: Compiled Transformers as a Laboratory for Interpretability (paper) (2023) by DeepMind - TRACR (TRAnsformer Compiler for RASP) is a compiler for converting RASP programs (DSL for Transformers) into weights of a GPT-like model. Usually, we train Transformers to encode algorithms in their weights. With TRACR, we go in the reverse direction; compile weights directly from explicit code. Why do this? Accelerate interpretability research. Think of it like formal methods (from software eng.) on Transformers. It can be difficult to check if the explanation an interpretability tool provides is correct. [ Tweet , code ] Yann LeCun's unwavering opinion on current (auto-regressive) LLMs (Tweet) Core Views on AI Safety: When, Why, What, and How by Anthropic, 2023. Personalisation within bounds: A risk taxonomy and policy framework for the alignment of large language models with personalised feedback by University of Oxford, 2023. [ Tweet ] GPTs are GPTs: An Early Look at the Labor Market Impact Potential of Large Language Models (paper) by OpenAI et al., 2023 - The paper argues GPT is a General Purpose Technology. Videos BERTology XLNet Explained by NLP Breakfasts. Clear explanation. Also covers the two-stream self-attention idea. The Future of NLP by 🤗 Dense overview of what is going on in transfer learning in NLP currently, limits, and future directions. The Transformer neural network architecture explained by AI Coffee Break with Letitia Parcalabescu. High-level explanation, best suited when unfamiliar with Transformers. Attention and Transformer Networks Sequence to Sequence Learning Animated (Inside Transformer Neural Networks and Attention Mechanisms) by learningcurve. General Trials and tribulations of OPT-175B training by Susan Zhang at Meta - In this talk, they walk through the development lifecycle of OPT-175B, covering infrastructure and training convergence challenges faced at scale, along with methods of addressing these issues going forward. Amazing that they managed to pull off such a feat. Key takeaway: data matters a lot! Super deep understanding of neural networks nuts&bolts (LR, SGD, etc.) and engineering. Even more than usual time spend staring at the loss curves. Understanding the Chinchilla's scaling law of how the new architecture/algorithms works as you scale up. [ LLM training log ] Official BERT Implementations google-research/bert - TensorFlow code and pre-trained models for BERT. Transformer Implementations By Communities GPT and/or BERT implementations. PyTorch and TensorFlow 🤗 Hugging Face Transformers (formerly known as pytorch-transformers and pytorch-pretrained-bert ) provides state-of-the-art general-purpose architectures (BERT, GPT-2, RoBERTa, XLM, DistilBert, XLNet, CTRL...) for Natural Language Understanding (NLU) and Natural Language Generation (NLG) with over 32+ pretrained models in 100+ languages and deep interoperability between TensorFlow 2.0 and PyTorch. [ Paper ] spacy-transformers - a library that wrap Hugging Face's Transformers, in order to extract features to power NLP pipelines. It also calculates an alignment so the Transformer features can be related back to actual words instead of just wordpieces. FasterTransformer - Transformer related optimization, including BERT and GPT. This repo provides a script and recipe to run the highly optimized transformer-based encoder and decoder component, and it is tested and maintained by NVIDIA. PyTorch codertimo/BERT-pytorch - Google AI 2018 BERT pytorch implementation. innodatalabs/tbert - PyTorch port of BERT ML model. kimiyoung/transformer-xl - Code repository associated with the Transformer-XL paper. dreamgonfly/BERT-pytorch - A PyTorch implementation of BERT in "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding". dhlee347/pytorchic-bert - A Pytorch implementation of Google BERT. pingpong-ai/xlnet-pytorch - A Pytorch implementation of Google Brain XLNet. facebook/fairseq - RoBERTa: A Robustly Optimized BERT Pretraining Approach by Facebook AI Research. SoTA results on GLUE, SQuAD and RACE. NVIDIA/Megatron-LM - Ongoing research training transformer language models at scale, including: BERT. deepset-ai/FARM - Simple & flexible transfer learning for the industry. NervanaSystems/nlp-architect - NLP Architect by Intel AI. Among other libraries, it provides a quantized version of Transformer models and efficient training method. kaushaltrivedi/fast-bert - Super easy library for BERT based NLP models. Built based on 🤗 Transformers and is inspired by fast.ai. NVIDIA/NeMo - Neural Modules is a toolkit for conversational AI by NVIDIA. They are trying to improve speech recognition with BERT post-processing . facebook/MMBT from Facebook AI - Multimodal transformers model that can accept a transformer model and a computer vision model for classifying image and text. dbiir/UER-py from Tencent and RUC - Open Source Pre-training Model Framework in PyTorch & Pre-trained Model Zoo (with more focus on Chinese). lucidrains/x-transformers - A simple but complete full-attention transformer with a set of promising experimental features from various papers (good for learning purposes). There is a 2021 paper rounding up Transformer modifications, Do Transformer Modifications Transfer Across Implementations and Applications? . Keras Separius/BERT-keras - Keras implementation of BERT with pre-trained weights. CyberZHG/keras-bert - Implementation of BERT that could load official pre-trained models for feature extraction and prediction. bojone/bert4keras - Light reimplement of BERT for Keras. TensorFlow guotong1988/BERT-tensorflow - BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. kimiyoung/transformer-xl - Code repository associated with the Transformer-XL paper. zihangdai/xlnet - Code repository associated with the XLNet paper. Chainer soskek/bert-chainer - Chainer implementation of "BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding". Other llama.cpp - Port of Facebook's LLaMA model in C/C++. Cformers - SoTA Transformers with C-backend for fast inference on your CPU. Transformers.js - Run 🤗 Transformers in your browser. Alpaca.cpp - Run a fast ChatGPT-like model locally on your device. LLaMA compatible port Apple Neural Engine (ANE) Transformers - Transformer architecture optimized for Apple Silicon. Transfer Learning in NLP NLP finally had a way to do transfer learning probably as well as Computer Vision could. As Jay Alammar put it: The year 2018 has been an inflection point for machine learning models handling text (or more accurately, Natural Language Processing or NLP for short). Our conceptual understanding of how best to represent words and sentences in a way that best captures underlying meanings and relationships is rapidly evolving. Moreover, the NLP community has been putting forward incredibly powerful components that you can freely download and use in your own models and pipelines (It's been referred to as NLP's ImageNet moment , referencing how years ago similar developments accelerated the development of machine learning in Computer Vision tasks). One of the latest milestones in this development is the release of BERT , an event described as marking the beginning of a new era in NLP. BERT is a model that broke several records for how well models can handle language-based tasks. Soon after the release of the paper describing the model, the team also open-sourced the code of the model, and made available for download versions of the model that were already pre-trained on massive datasets. This is a momentous development since it enables anyone building a machine learning model involving language processing to use this powerhouse as a readily-available component – saving the time, energy, knowledge, and resources that would have gone to training a language-processing model from scratch. BERT builds on top of a number of clever ideas that have been bubbling up in the NLP community recently – including but not limited to Semi-supervised Sequence Learning (by Andrew Dai and Quoc Le ), ELMo (by Matthew Peters and researchers from AI2 and UW CSE ), ULMFiT (by fast.ai founder Jeremy Howard and Sebastian Ruder ), the OpenAI transformer (by OpenAI researchers Radford , Narasimhan , Salimans , and Sutskever ), and the Transformer ( Vaswani et al ). ULMFiT: Nailing down Transfer Learning in NLP ULMFiT introduced methods to effectively utilize a lot of what the model learns during pre-training – more than just embeddings, and more than contextualized embeddings. ULMFiT introduced a language model and a process to effectively fine-tune that language model for various tasks. NLP finally had a way to do transfer learning probably as well as Computer Vision could. MultiFiT: Efficient Multi-lingual Language Model Fine-tuning by Sebastian Ruder et al. MultiFiT extends ULMFiT to make it more efficient and more suitable for language modelling beyond English. ( EMNLP 2019 paper ) Books Transfer Learning for Natural Language Processing - A book that is a practical primer to transfer learning techniques capable of delivering huge improvements to your NLP models. Natural Language Processing with Transformers by Lewis Tunstall, Leandro von Werra, and Thomas Wolf - This practical book shows you how to train and scale these large models using Hugging Face Transformers. The authors use a hands-on approach to teach you how transformers work and how to integrate them in your applications. Other Resources Expand Other Resources hanxiao/bert-as-service - Mapping a variable-length sentence to a fixed-length vector using pretrained BERT model. brightmart/bert_language_understanding - Pre-training of Deep Bidirectional Transformers for Language Understanding: pre-train TextCNN. algteam/bert-examples - BERT examples. JayYip/bert-multiple-gpu - A multiple GPU support version of BERT. HighCWu/keras-bert-tpu - Implementation of BERT that could load official pre-trained models for feature extraction and prediction on TPU. whqwill/seq2seq-keyphrase-bert - Add BERT to encoder part for https://github.com/memray/seq2seq-keyphrase-pytorch xu-song/bert_as_language_model - BERT as language model, a fork from Google official BERT implementation. Y1ran/NLP-BERT--Chinese version yuanxiaosc/Deep_dynamic_word_representation - TensorFlow code and pre-trained models for deep dynamic word representation (DDWR). It combines the BERT model and ELMo's deep context word representation. yangbisheng2009/cn-bert Willyoung2017/Bert_Attempt Pydataman/bert_examples - Some examples of BERT. run_classifier.py based on Google BERT for Kaggle Quora Insincere Questions Classification challenge. run_ner.py is based on the first season of the Ruijin Hospital AI contest and a NER written by BERT. guotong1988/BERT-chinese - Pre-training of deep bidirectional transformers for Chinese language understanding. zhongyunuestc/bert_multitask - Multi-task. Microsoft/AzureML-BERT - End-to-end walk through for fine-tuning BERT using Azure Machine Learning. bigboNed3/bert_serving - Export BERT model for serving. yoheikikuta/bert-japanese - BERT with SentencePiece for Japanese text. nickwalton/AIDungeon - AI Dungeon 2 is a completely AI generated text adventure built with OpenAI's largest 1.5B param GPT-2 model. It's a first of it's kind game that allows you to enter and will react to any action you can imagine. turtlesoupy/this-word-does-not-exist - "This Word Does Not Exist" is a project that allows people to train a variant of GPT-2 that makes up words, definitions and examples from scratch. We've never seen fake text so real. Tools jessevig/bertviz - Tool for visualizing attention in the Transformer model. FastBert - A simple deep learning library that allows developers and data scientists to train and deploy BERT based models for NLP tasks beginning with text classification. The work on FastBert is inspired by fast.ai. gpt2tc - A small program using the GPT-2 LM to complete and compress texts. It has no external dependency, requires no GPU and is quite fast. The smallest model (117M parameters) is provided. Larger models can be downloaded as well. (no waitlist, no sign up required). Tasks Named-Entity Recognition (NER) Expand NER kyzhouhzau/BERT-NER - Use google BERT to do CoNLL-2003 NER. zhpmatrix/bert-sequence-tagging - Chinese sequence labeling. JamesGu14/BERT-NER-CLI - Bert NER command line tester with step by step setup guide. sberbank-ai/ner-bert mhcao916/NER_Based_on_BERT - This project is based on Google BERT model, which is a Chinese NER. macanv/BERT-BiLSMT-CRF-NER - TensorFlow solution of NER task using Bi-LSTM-CRF model with Google BERT fine-tuning. ProHiryu/bert-chinese-ner - Use the pre-trained language model BERT to do Chinese NER. FuYanzhe2/Name-Entity-Recognition - Lstm-CRF, Lattice-CRF, recent NER related papers. king-menin/ner-bert - NER task solution (BERT-Bi-LSTM-CRF) with Google BERT https://github.com/google-research . Classification Expand Classification brightmart/sentiment_analysis_fine_grain - Multi-label classification with BERT; Fine Grained Sentiment Analysis from AI challenger. zhpmatrix/Kaggle-Quora-Insincere-Questions-Classification - Kaggle baseline—fine-tuning BERT and tensor2tensor based Transformer encoder solution. maksna/bert-fine-tuning-for-chinese-multiclass-classification - Use Google pre-training model BERT to fine-tune for the Chinese multiclass classification. NLPScott/bert-Chinese-classification-task - BERT Chinese classification practice. fooSynaptic/BERT_classifer_trial - BERT trial for Chinese corpus classfication. xiaopingzhong/bert-finetune-for-classfier - Fine-tuning the BERT model while building your own dataset for classification. Socialbird-AILab/BERT-Classification-Tutorial - Tutorial. malteos/pytorch-bert-document-classification - Enriching BERT with Knowledge Graph Embedding for Document Classification (PyTorch) Text Generation Expand Text Generation asyml/texar - Toolkit for Text Generation and Beyond. Texar is a general-purpose text generation toolkit, has also implemented BERT here for classification, and text generation applications by combining with Texar's other modules. Plug and Play Language Models: a Simple Approach to Controlled Text Generation (PPLM) paper by Uber AI. Question Answering (QA) Expand QA matthew-z/R-net - R-net in PyTorch, with BERT and ELMo. vliu15/BERT - TensorFlow implementation of BERT for QA. benywon/ChineseBert - This is a Chinese BERT model specific for question answering. xzp27/BERT-for-Chinese-Question-Answering facebookresearch/SpanBERT - Question Answering on SQuAD; improving pre-training by representing and predicting spans. Knowledge Graph Expand Knowledge Graph sakuranew/BERT-AttributeExtraction - Using BERT for attribute extraction in knowledge graph. Fine-tuning and feature extraction. The BERT-based fine-tuning and feature extraction methods are used to extract knowledge attributes of Baidu Encyclopedia characters. lvjianxin/Knowledge-extraction - Chinese knowledge-based extraction. Baseline: bi-LSTM+CRF upgrade: BERT pre-training. License Expand License This repository contains a variety of content; some developed by Cedric Chee, and some from third-parties. The third-party content is distributed under the license provided by those parties. I am providing code and resources in this repository to you under an open source license. Because this is my personal repository, the license you receive to my code and resources is from me and not my employer. The content developed by Cedric Chee is distributed under the following license: Code The code in this repository, including all code samples in the notebooks listed above, is released under the MIT license . Read more at the Open Source Initiative . Text The text content is released under the CC-BY-SA 4.0 license. Read more at Creative Commons . Footnotes Infographic by AIM. ↩
2. Related Work, Literature Survey & Algorithmic Foundations
Transformers 🚀 Welcome to the Transformers repository — a hands-on project focused on understanding and implementing Transformer-based deep learning models for Natural Language Processing (NLP). This project explores how transformer architectures power modern AI systems like chatbots, translation models, and text generation tools. 🎯 Objective The goal of this repository is to: Understand Transformer architecture deeply Implement NLP models using Transformers Work with pre-trained models and fine-tuning Apply Transformers to real-world text tasks 🧠 What are Transformers? Transformers are deep learning models designed to process sequential data (like text) using attention mechanisms , enabling them to understand context better than traditional models. They are the backbone of modern AI systems like: ChatGPT-like models Translation systems Text summarization tools ⚙️ Features Text classification using Transformers Text generation experiments Pre-trained model usage Fine-tuning workflows Embedding generation Attention mechanism exploration 🛠️ Tech Stack Python 🐍 PyTorch / TensorFlow Hugging Face Transformers 🤗 NumPy & Pandas Jupyter Notebooks (optional) 📂 Project Structure models/ transformer_model.py notebooks/ training.ipynb inference.ipynb datasets/ sample_data.csv utils/ preprocess.py tokenizer.py main.py requirements.txt 🚀 Getting Started 1. Clone the repository git clone https://github.com/your-username/transformers.git cd transformers 2. Install dependencies pip install -r requirements.txt 3. Run the project python main.py 💡 Use Cases Sentiment analysis Text summarization Chatbot development Language translation AI text generation 📚 Learning Goals Understand attention mechanisms Learn how Transformers process text Work with pre-trained models Build end-to-end NLP pipelines 🤝 Contributions Contributions are welcome! How to contribute: Fork the repository Create a new branch Add your model, improvement, or notebook Submit a pull request 📋 Guidelines Keep code clean and modular Add proper documentation Avoid large unnecessary dependencies Ensure reproducibility 🌟 Maintained by vhbuyio ⭐ If you find this project helpful, don’t forget to star the repository!
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
What is Transformers in NLP? https://jalammar.github.io/illustrated-transformer/ https://jalammar.github.io/visualizing-neural-machine-translation-mechanics-of-seq2seq-models-with-attention/ Concepts Attention Encoder-Decoder Attention : Attention between the input sequence and the output sequence. Self attention in the input sequence : Attends to all the words in the input sequence. Self attention in the output sequence: One thing we should be wary of here is that the scope of self attention is limited to the words that occur before a given word. This prevents any information leaks during the training of the model. This is done by masking the words that occur after it for each step. So for step 1, only the first word of the output sequence is NOT masked, for step 2, the first two words are NOT masked and so on. Videos https://www.youtube.com/watch?v=rURRYI66E54 Introduction, language models in general (include RNN, LSTM) https://www.youtube.com/watch?v=TQQlZhbC5ps Transformer architecture Papers Attention is All You Need Transformer was proposed in the paper Attention is All You Need , 2017. The dominant sequence transduction models are based on complex recurrent or convolutional neural networks in an encoder-decoder configuration. The best performing models also connect the encoder and decoder through an attention mechanism. We propose a new simple network architecture, the Transformer, based solely on attention mechanisms, dispensing with recurrence and convolutions entirely. Experiments on two machine translation tasks show these models to be superior in quality while being more parallelizable and requiring significantly less time to train. Our model achieves 28.4 BLEU on the WMT 2014 English-to-German translation task, improving over the existing best results, including ensembles by over 2 BLEU. On the WMT 2014 English-to-French translation task, our model establishes a new single-model state-of-the-art BLEU score of 41.8 after training for 3.5 days on eight GPUs, a small fraction of the training costs of the best models from the literature. We show that the Transformer generalizes well to other tasks by applying it successfully to English constituency parsing both with large and limited training data.![] http://nlp.seas.harvard.edu/2018/04/03/attention.html IndoNLU https://arxiv.org/abs/2009.05387 , 2020 Although Indonesian is known to be the fourth most frequently used language over the internet, the research progress on this language in the natural language processing (NLP) is slow-moving due to a lack of available resources. In response, we introduce the first-ever vast resource for the training, evaluating, and benchmarking on Indonesian natural language understanding (IndoNLU) tasks. IndoNLU includes twelve tasks, ranging from single sentence classification to pair-sentences sequence labeling with different levels of complexity. The datasets for the tasks lie in different domains and styles to ensure task diversity. We also provide a set of Indonesian pre-trained models (IndoBERT) trained from a large and clean Indonesian dataset Indo4B collected from publicly available sources such as social media texts, blogs, news, and websites. We release baseline models for all twelve tasks, as well as the framework for benchmark evaluation, and thus it enables everyone to benchmark their system performances. Tutorial: https://indobenchmark.github.io/tutorials/pytorch/deep%20learning/nlp/2020/10/18/basic-pytorch-en.html
4. Neural Network Backbone, Layer Specifications & Loss Formulations
FRAMEWORKS, TOOLKITS, MODELS, APPLICATIONS https://github.com/tensorflow/tensorflow https://github.com/keras-team/keras https://github.com/deepmind/sonnet - TensorFlow-based neural network library. https://github.com/tensorflow/mesh - Mesh TensorFlow: Model Parallelism Made Easier https://github.com/keras-team/keras-applications/ - It provides model definitions and pre-trained weights for a number of popular archictures, such as VGG16, ResNet50, Xception, MobileNet, and more. https://github.com/tensorflow/tensor2tensor - library of deep learning models and datasets designed to make deep learning more accessible and accelerate ML research. https://github.com/tflearn/tflearn - Deep learning library featuring a higher-level API for TensorFlow. https://github.com/fchollet/keras-resources - Directory of tutorials and open-source code repositories for working with Keras, the Python deep learning library https://github.com/tensorlayer/tensorlayer TensorLayer is a novel TensorFlow-based deep learning and reinforcement learning library designed for researchers and engineers. It provides an extensive collection of customizable neural layers to build advanced AI models quickly, based on this, the community open-sourced mass tutorials and applications. TensorLayer is awarded the 2017 Best Open Source Software by the ACM Multimedia Society. This project can also be found at iHub and Gitee. https://github.com/pytorch https://github.com/fastai/fastai fastai is a deep learning library which provides practitioners with high-level components that can quickly and easily provide state-of-the-art results in standard deep learning domains, and provides researchers with low-level components that can be mixed and matched to build new approaches. fastai includes: A new type dispatch system for Python along with a semantic type hierarchy for tensors A GPU-optimized computer vision library which can be extended in pure Python An optimizer which refractors out the common functionality of modern optimizers into two basic pieces, allowing optimization algorithms to be implemented in 4-5 lines of code A novel 2-way callback system that can access any part of the data, model, or optimizer and change it at any point during training A new data block API https://github.com/PyTorchLightning/pytorch-lightning - The lightweight PyTorch wrapper for high-performance AI research. Scale your models, not the boilerplate. https://github.com/pytorch/examples - A set of examples around pytorch in Vision, Text, Reinforcement Learning, etc. https://github.com/jettify/pytorch-optimizer - torch-optimizer -- collection of optimizers for Pytorch. https://github.com/silvandeleemput/memcnn - PyTorch Framework for Developing Memory Efficient Deep Invertible Networks. https://github.com/davda54/ada-hessian - Easy-to-use AdaHessian optimizer (PyTorch). https://github.com/huggingface/pytorch_block_sparse - Fast Block Sparse Matrices for Pytorch. https://github.com/fkodom/fft-conv-pytorch - Implementation of 1D, 2D, and 3D FFT convolutions in PyTorch. Much faster than direct convolutions for large kernel sizes. https://github.com/facebookresearch/functorch - functorch is a prototype of JAX-like composable function transforms for PyTorch. https://github.com/apache/incubator-mxnet https://github.com/deepmind/deepmind-research - This repository contains implementations and illustrative code to accompany DeepMind publications. https://github.com/facebookresearch/faiss - Faiss is a library for efficient similarity search and clustering of dense vectors. Faiss contains several methods for similarity search. It assumes that the instances are represented as vectors and are identified by an integer, and that the vectors can be compared with L2 (Euclidean) distances or dot products. Vectors that are similar to a query vector are those that have the lowest L2 distance or the highest dot product with the query vector. It also supports cosine similarity, since this is a dot product on normalized vectors. https://github.com/torch/torch8 - Torch is a scientific computing framework with wide support for machine learning algorithms that puts GPUs first. https://github.com/NVIDIA/TensorRT - TensorRT is a C++ library for high performance inference on NVIDIA GPUs and deep learning accelerators. https://developer.nvidia.com/tensorrt https://github.com/NVIDIA/DALI - A library containing both highly optimized building blocks and an execution engine for data pre-processing in deep learning applications https://docs.nvidia.com/deeplearning/… https://github.com/pluskid/Mocha.jl - Deep Learning framework for Julia https://github.com/FluxML/Flux.jl - Relax! Flux is the ML library that doesn't make you tensor https://fluxml.ai/ https://github.com/microsoft/DeepSpeed - DeepSpeed is a deep learning optimization library that makes distributed training easy, efficient, and effective. www.deepspeed.ai . https://github.com/pjreddie/darknet - Darknet is an open source neural network framework written in C and CUDA. It is fast, easy to install, and supports CPU and GPU computation. https://github.com/josephmisiti/awesome-machine-learning - A curated list of awesome Machine Learning frameworks, libraries and software. https://github.com/EthicalML/awesome-production-machine-learning - A curated list of awesome open source libraries to deploy, monitor, version and scale your machine learning https://github.com/pjreddie/TopDeepLearning - A list of popular github projects related to deep learning https://github.com/rasbt/deeplearning-models - A collection of various deep learning architectures, models, and tips https://github.com/tensorflow/models - Models and examples built with TensorFlow. https://github.com/lucidrains/g-mlp-pytorch - Implementation of gMLP, an all-MLP replacement for Transformers, in Pytorch Pay Attention to MLPs by Quoc Le et al, https://arxiv.org/abs/2105.08050 Here we propose a simple network architecture, gMLP, based on MLPs with gating, and show that it can perform as well as Transformers in key language and vision applications. https://github.com/martinarjovsky/WassersteinGAN - Code accompanying the paper "Wasserstein GAN", https://arxiv.org/abs/1701.07875 hhttps://github.com/facebookresearch/dlrm - An implementation of a deep learning recommendation model (DLRM) ttps://github.com/domluna/memn2n - Implementation of "End-To-End Memory Networks" with sklearn-like interface using Tensorflow. Tasks are from the bAbl dataset. https://github.com/nitishsrivastava/deepnet - Implementation of some deep learning algorithms. http://www.cs.toronto.edu/~nitish/ Built on top of the cudamat library by Vlad Mnih and cuda-convnet library by Alex Krizhevsky. https://github.com/lucidrains/glom-pytorch - An attempt at the implementation of Glom, Geoffrey Hinton's new idea that integrates concepts from neural fields, top-down-bottom-up processing, and attention (consensus between columns), for emergent part-whole heirarchies from data. https://github.com/RedditSota/state-of-the-art-result-for-machine-learning-problems This repository provides state of the art (SoTA) results for all machine learning problems. We do our best to keep this repository up to date. If you do find a problem's SoTA result is out of date. https://github.com/hyperopt/hyperopt - Distributed Asynchronous Hyperparameter Optimization in Python http://hyperopt.github.io/hyperopt https://github.com/lutzroeder/netron - Visualizer for neural network, deep learning and machine learning models https://www.lutzroeder.com/ai https://github.com/mlflow/mlflow - MLflow is a platform to streamline machine learning development, including tracking experiments, packaging code into reproducible runs, and sharing and deploying models. MLflow offers a set of lightweight APIs that can be used with any existing machine learning application or library (TensorFlow, PyTorch, XGBoost, etc). https://github.com/optuna/optuna - A hyperparameter optimization framework. https://github.com/clab/dynet DyNet is a neural network library developed by Carnegie Mellon University and many others. It is written in C++ (with bindings in Python) and is designed to be efficient when run on either CPU or GPU, and to work well with networks that have dynamic structures that change for every training instance. For example, these kinds of networks are particularly important in natural language processing tasks, and DyNet has been used to build state-of-the-art systems for syntactic parsing, machine translation, morphological inflection, and many other application areas. https://github.com/RJT1990/pyflux PyFlux is an open source time series library for Python. The library has a good array of modern time series models, as well as a flexible array of inference options (frequentist and Bayesian) that can be applied to these models. By combining breadth of models with breadth of inference, PyFlux allows for a probabilistic approach to time series modelling https://github.com/flashlight/flashlight - Flashlight is a fast, flexible machine learning library written entirely in C++ from the Facebook AI Research Speech team and the creators of Torch and Deep Speech. Its core features include: Just-in-time kernel compilation with modern C++ with the ArrayFire tensor library. CUDA and CPU backends for GPU and CPU training. An emphasis on efficiency and scale. https://github.com/horovod/horovod - Distributed training framework for TensorFlow, Keras, PyTorch, and Apache MXNet. The primary motivation for this project is to make it easy to take a single-GPU training script and successfully scale it to train across many GPUs in parallel. https://github.com/thangbui/geepee - A collection of Gaussian process models. https://github.com/deepmind/learning-to-learn - Learning to Learn in TensorFlow, https://arxiv.org/abs/1606.04474 https://github.com/Spijkervet/BYOL - Bootstrap Your Own Latent: A New Approach to Self-Supervised Learning, https://arxiv.org/abs/2006.07733 . https://github.com/lucidrains/byol-pytorch - Usable Implementation of "Bootstrap Your Own Latent" self-supervised learning, from Deepmind, in Pytorch. https://github.com/hibayesian/awesome-automl-papers - A curated list of automated machine learning papers, articles, tutorials, slides and projects. https://github.com/ray-project/ray - An open source framework that provides a simple, universal API for building distributed applications. Ray is packaged with RLlib, a scalable reinforcement learning library, and Tune, a scalable hyperparameter tuning library. https://github.com/google/automl - Google Brain AutoML https://github.com/maxpumperla/hyperas - Keras + Hyperopt: A very simple wrapper for convenient hyperparameter optimization http://maxpumperla.com/hyperas/ https://github.com/keras-team/keras-tuner - Hyperparameter tuning for humans https://github.com/keras-team/autokeras - An AutoML system based on Keras http://autokeras.com/ https://github.com/tensorflow/adanet - Fast and flexible AutoML with learning guarantees. https://github.com/microsoft/nni - An open source AutoML toolkit for automate machine learning lifecycle, including feature engineering, neural architecture search, model compression and hyper-parameter tuning. https://github.com/ray-project/ray - An open source framework that provides a simple, universal API for building distributed applications. Ray is packaged with RLlib, a scalable reinforcement learning library, and Tune, a scalable hyperparameter tuning library. COMPUTATION https://github.com/HiPerCoRe/KTT KTT is a autotuning framework for OpenCL, CUDA kernels and GLSL compute shaders. Version 1.3 which introduces public searcher API and user-provided compute queues and buffers is now available. https://github.com/google/tangent - Source-to-Source Debuggable Derivatives in Pure Python. https://github.com/numba/numba - A Just-In-Time Compiler for Numerical Functions in Python https://github.com/google/jax - JAX is Autograd and XLA, brought together for high-performance machine learning research. With its updated version of Autograd, JAX can automatically differentiate native Python and NumPy functions. It can differentiate through loops, branches, recursion, and closures, and it can take derivatives of derivatives of derivatives. https://github.com/onnx/onnx - ONNX provides an open source format for AI models, both deep learning and traditional ML. It defines an extensible computation graph model, as well as definitions of built-in operators and standard data types. https://github.com/cupy/cupy - CuPy is an implementation of NumPy-compatible multi-dimensional array on CUDA. CuPy consists of the core multi-dimensional array class, cupy.ndarray, and many functions on it. It supports a subset of numpy.ndarray interface. https://github.com/cornellius-gp/gpytorch - A highly efficient and modular implementation of Gaussian Processes in PyTorch. https://github.com/titu1994/tfdiffeq - Tensorflow implementation of Ordinary Differential Equation Solvers with full GPU support. https://github.com/rtqichen/torchdiffeq - Differentiable ODE solvers with full GPU support and O(1)-memory backpropagation. https://arxiv.org/abs/1806.07366 https://arxiv.org/abs/2011.03902 https://github.com/pyro-ppl/pyro - Deep universal probabilistic programming with Python and PyTorch. https://github.com/lmcinnes/umap - Uniform Manifold Approximation and Projection, https://arxiv.org/abs/1802.03426 , https://www.biorxiv.org/content/10.1101/2020.05.12.077776v1 Uniform Manifold Approximation and Projection (UMAP) is a dimension reduction technique that can be used for visualisation similarly to t-SNE, but also for general non-linear dimension reduction. The algorithm is founded on three assumptions about the data: The data is uniformly distributed on a Riemannian manifold; The Riemannian metric is locally constant (or can be approximated as such); The manifold is locally connected. https://github.com/fmfn/BayesianOptimization - A Python implementation of global optimization with gaussian processes. https://github.com/mackelab/autohmm - Hidden Markov Models (HMMs) with tied states and autoregressive observations. https://github.com/jmschrei/pomegranate - Fast, flexible and easy to use probabilistic modelling in Python. Models: Probability Distributions General Mixture Models Hidden Markov Models Naive Bayes and Bayes Classifiers Markov Chains Discrete Bayesian Networks Discrete Markov Networks https://github.com/jolibrain/deepdetect - Deep Learning API and Server in C++14 support for Caffe, Caffe2, PyTorch,TensorRT, Dlib, NCNN, Tensorflow, XGBoost and TSNE. https://github.com/arogozhnikov/einops - Flexible and powerful tensor operations for readable and reliable code. Supports numpy, pytorch, tensorflow, jax, and others. https://github.com/dask/dask - Dask provides advanced parallelism for analytics, enabling performance at scale for the tools you love https://github.com/TheAlgorithms/Python - All Algorithms implemented in Python https://github.com/waylonflinn/weblas - GPU accelerated Javascript. Numerical computing in your browser with performance comparable to native. https://github.com/google-research/fast-soft-sort - Fast Differentiable Sorting and Ranking, https://arxiv.org/abs/2002.08871 The sorting operation is one of the most commonly used building blocks in computer programming. In machine learning, it is often used for robust statistics. However, seen as a function, it is piecewise linear and as a result includes many kinks where it is non-differentiable. More problematic is the related ranking operator, often used for order statistics and ranking metrics. It is a piecewise constant function, meaning that its derivatives are null or undefined. While numerous works have proposed differentiable proxies to sorting and ranking, they do not achieve the O(nlogn) time complexity one would expect from sorting and ranking operations. AWESOME KNOWLEDGE, TUTORIALS https://github.com/kjw0612/awesome-rnn - A curated list of resources dedicated to recurrent neural networks (closely related to deep learning). https://github.com/ChristosChristofidis/awesome-deep-learning - A curated list of awesome Deep Learning tutorials, projects and communities. https://github.com/dennybritz/deeplearning-papernotes - Summaries and notes on Deep Learning research papers https://github.com/terryum/awesome-deep-learning-papers - The most cited deep learning papers https://github.com/oxford-cs-deepnlp-2017/lectures - Oxford Deep NLP 2017 course https://github.com/lexfridman/mit-deep-learning - Tutorials, assignments, and competitions for MIT Deep Learning related courses. https://deeplearning.mit.edu https://github.com/yunjey/pytorch-tutorial - PyTorch Tutorial for Deep Learning Researchers. https://github.com/floodsung/Deep-Learning-Papers-Reading-Roadmap - Deep Learning papers reading roadmap for anyone who are eager to learn this amazing tech! https://github.com/vdumoulin/conv_arithmetic - A technical report on convolution arithmetic in the context of deep learning. https://github.com/FrancescoSaverioZuppichini/PyTorch-Deep-Learning-Template - This template aims to make it easier for you to start a new deep learning computer vision project with PyTorch. https://github.com/mnielsen/neural-networks-and-deep-learning - Code samples for my book "Neural Networks and Deep Learning" https://github.com/Hvass-Labs/TensorFlow-Tutorials - TensorFlow Tutorials with YouTube Videos https://github.com/deepmind/learning-to-learn - Learning to Learn in TensorFlow https://github.com/fastai/course-v3 - The 3rd edition of course.fast.ai. See the nbs folder for the notebooks. https://github.com/NVIDIA/DeepLearningExamples - This repository provides the latest deep learning example networks for training. These examples focus on achieving the best performance and convergence from NVIDIA Volta Tensor Cores. https://github.com/ageron/handson-ml - A series of Jupyter notebooks that walk you through the fundamentals of Machine Learning and Deep Learning in python using Scikit-Learn and TensorFlow. https://github.com/fastai/fastbook - The fastai book, published as Jupyter Notebooks. https://github.com/graykode/distribution-is-all-you-need - The basic distribution probability Tutorial for Deep Learning Researchers. https://github.com/huggingface/neuralcoref - ast Coreference Resolution in spaCy with Neural Networks, https://medium.com/huggingface/state-of-the-art-neural-coreference-resolution-for-chatbots-3302365dcf30 https://github.com/vi3k6i5/flashtext - This module can be used to replace keywords in sentences or extract keywords from sentences. It is based on the FlashText algorithm, https://arxiv.org/abs/1711.00046 https://github.com/eriklindernoren/ML-From-Scratch - Machine Learning From Scratch. Bare bones NumPy implementations of machine learning models and algorithms with a focus on accessibility. Aims to cover everything from linear regression to deep learning. https://github.com/Chillee/CS344_2021 - Udacity CS344 Introduction to Parallell Programming ( https://classroom.udacity.com/courses/cs344 ), with assignments/materials updated to build in 2021. NLP https://github.com/graykode/nlp-tutorial - Natural Language Processing Tutorial for Deep Learning Researchers https://github.com/nlptown/nlp-notebooks - A collection of notebooks for Natural Language Processing from NLP Town http://www.nlp.town https://github.com/ines/spacy-course - Advanced NLP with spaCy: A free online course. https://github.com/bentrevett/pytorch-seq2seq - Tutorials on implementing a few sequence-to-sequence (seq2seq) models with PyTorch and TorchText. https://github.com/RaRe-Technologies/gensim - Gensim is a Python library for topic modelling, document indexing and similarity retrieval with large corpora. Target audience is the natural language processing (NLP) and information retrieval (IR) community https://github.com/allenai/allennlp - An open-source NLP research library, built on PyTorch. http://www.allennlp.org/ https://github.com/flairNLP/flair - Flair is: A powerful NLP library. Flair allows you to apply our state-of-the-art natural language processing (NLP) models to your text, such as named entity recognition (NER), part-of-speech tagging (PoS), sense disambiguation and classification. Multilingual. Thanks to the Flair community, we support a rapidly growing number of languages. We also now include 'one model, many languages' taggers, i.e. single models that predict PoS or NER tags for input text in various languages. A text embedding library. Flair has simple interfaces that allow you to use and combine different word and document embeddings, including our proposed Flair embeddings, BERT embeddings and ELMo embeddings. A PyTorch NLP framework. Our framework builds directly on PyTorch, making it easy to train your own models and experiment with new approaches using Flair embeddings and classes. https://github.com/explosion/spaCy - Industrial-strength Natural Language Processing (NLP) in Python spaCy is a library for advanced Natural Language Processing in Python and Cython. It's built on the very latest research, and was designed from day one to be used in real products. https://github.com/sebastianruder/NLP-progress - Tracking Progress in Natural Language Processing https://github.com/IsaacChanghau/DL-NLP-Readings - My Reading Lists of Deep Learning and Natural Language Processing https://github.com/keon/awesome-nlp - A curated list of resources dedicated to Natural Language Processing (NLP) https://github.com/mihail911/nlp-library - Curated collection of papers for the nlp practitioner. https://github.com/msgi/nlp-journey - Documents, papers and codes related to NLP, including Topic Model, Word Embedding, Named Entity Recognition, Text Classificatin, Text Generation, Text Similarity, Machine Translation),etc. All codes are implemented intensorflow 2.0. https://github.com/msgi/nlp-journey https://github.com/graykode/nlp-roadmap - ROADMAP(Mind Map) and KEYWORD for students those who have interest in learning NLP. https://github.com/NervanaSystems/nlp-architect - A model library for exploring state-of-the-art deep learning topologies and techniques for optimizing Natural Language Processing neural networks https://github.com/microsoft/nlp-recipes - Natural Language Processing Best Practices & Examples https://github.com/microsoft/unilm Pre-trained (foundation) models across tasks (understanding, generation and translation), languages (100+ languages), and modalities (language, image, audio, vision + language, audio + language, etc.). https://github.com/roomylee/awesome-relation-extraction - A curated list of awesome resources dedicated to Relation Extraction, one of the most important tasks in Natural Language Processing (NLP). https://github.com/Separius/awesome-sentence-embedding - A curated list of pretrained sentence and word embedding models https://github.com/philipperemy/keras-attention-mechanism - Attention mechanism Implementation for Keras. https://www.cs.cmu.edu/~./hovy/papers/16HLT-hierarchical-attention-networks.pdf https://arxiv.org/abs/1508.04025 https://arxiv.org/abs/1409.0473 https://github.com/huggingface/tokenizers - Fast State-of-the-Art Tokenizers optimized for Research and Production. https://github.com/facebookresearch/XLM - PyTorch original implementation of Cross-lingual Language Model Pretraining, https://arxiv.org/abs/1901.07291 https://github.com/facebookresearch/fastText - Library for fast text representation and classification. https://github.com/sloria/TextBlob TextBlob is a Python (2 and 3) library for processing textual data. It provides a simple API for diving into common natural language processing (NLP) tasks such as part-of-speech tagging, noun phrase extraction, sentiment analysis, classification, translation, and more. TextBlob stands on the giant shoulders of NLTK and Pattern, and plays nicely with both. https://github.com/dmlc/gluon-nlp - NLP made easy http://gluon-nlp.mxnet.io https://github.com/erickrf/nlpnet - A neural network architecture for NLP tasks, using cython for fast performance. Currently, it can perform POS tagging, SRL and dependency parsing. http://nilc.icmc.usp.br/nlpnet/ https://github.com/attardi/deepnl - deepnl is a Python library for Natural Language Processing tasks based on a Deep Learning neural network architecture. The library currently provides tools for performing part-of-speech tagging, Named Entity tagging and Semantic Role Labeling. https://github.com/Hironsan/anago - anaGo is a Python library for sequence labeling(NER, PoS Tagging,...), implemented in Keras. https://github.com/BrikerMan/Kashgari - Kashgari is a production-level NLP Transfer learning framework built on top of tf.keras for text-labeling and text-classification, includes Word2Vec, BERT, and GPT2 Language Embedding. https://github.com/HIT-SCIR/ELMoForManyLangs - Pre-trained ELMo Representations for Many Languages https://github.com/mikelkl/TF2-QA - 21th place (top2%) solution for kaggle TensorFlow 2.0 Question Answering. https://github.com/facebookresearch/StarSpace - Learning embeddings for classification, retrieval and ranking. https://github.com/brightmart/text_classification - The purpose of this repository is to explore text classification methods in NLP with deep learning. https://github.com/PAIR-code/lit - The Language Interpretability Tool: Interactively analyze NLP models for model understanding in an extensible and framework agnostic interface. https://github.com/BlinkDL/RWKV-LM - The RWKV Language Model with Token-shift. Better and Faster than usual transformer / GPT. https://github.com/huggingface/tokenizers - Fast State-of-the-Art Tokenizers optimized for Research and Production. https://github.com/princeton-nlp/SimCSE - EMNLP'2021: SimCSE: Simple Contrastive Learning of Sentence Embeddings. https://github.com/lucidrains/mlm-pytorch - An implementation of masked language modeling for Pytorch, made as concise and simple as possible. https://github.com/lucidrains/coco-lm-pytorch - Implementation of COCO-LM, Correcting and Contrasting Text Sequences for Language Model Pretraining, in Pytorch. https://github.com/lucidrains/marge-pytorch - Implementation of Marge, Pre-training via Paraphrasing, in Pytorch. https://github.com/lucidrains/mixture-of-experts - A Pytorch implementation of Sparsely-Gated Mixture of Experts, for massively increasing the parameter count of language models. NLG, GPT https://github.com/elyase/awesome-gpt3 - Awesome GPT-3 is a collection of demos and articles about the OpenAI GPT-3 API. https://github.com/openai/gpt-2 - Code for the paper "Language Models are Unsupervised Multitask Learners" GPT-2 https://github.com/microsoft/DialoGPT - A State-of-the-Art Large-scale Pretrained Response Generation Model (DialoGPT) https://github.com/karpathy/minGPT - A minimal PyTorch re-implementation of the OpenAI GPT (Generative Pretrained Transformer) training. https://github.com/graykode/gpt-2-Pytorch - Simple Text-Generator with OpenAI gpt-2 Pytorch Implementation https://github.com/minimaxir/gpt-2-simple - Python package to easily retrain OpenAI's GPT-2 text-generating model on new texts https://github.com/lucidrains/token-shift-gpt - Implementation of Token Shift GPT - An autoregressive model that solely relies on shifting the sequence space for mixing. https://github.com/lucidrains/g-mlp-gpt - GPT, but made only out of MLPs. https://github.com/tokenmill/awesome-nlg - There is a wide spectrum of different technologies addressing parts or the whole of the NLG process. This list aims to represent this deversity of NLG applications and techniques by providing links to various projects, tools, research papers, and learning materials. https://github.com/google/sentencepiece - Unsupervised text tokenizer for Neural Network-based text generation. https://github.com/guxd/DialogWAE - Source Code for DialogWAE: Multimodal Response Generation with Conditional Wasserstein Autoencoder ( https://arxiv.org/abs/1805.12352 ). https://github.com/hassyGo/NLG-RL - Accelerated Reinforcement Learning for Sentence Generation by Vocabulary Prediction, of paper https://arxiv.org/abs/1809.01694 https://github.com/google/seq2seq - A general-purpose encoder-decoder framework for Tensorflow that can be used for Machine Translation, Text Summarization, Conversational Modeling, Image Captioning, and more. https://github.com/bytedance/lightseq - LightSeq: A High Performance Library for Sequence Processing and Generation https://github.com/karpathy/char-rnn - Multi-layer Recurrent Neural Networks (LSTM, GRU, RNN) for character-level language models in Torch. https://github.com/sherjilozair/char-rnn-tensorflow - Multi-layer Recurrent Neural Networks (LSTM, RNN) for character-level language models in Python using Tensorflow. https://github.com/jcjohnson/torch-rnn - Efficient, reusable RNNs and LSTMs for torch. https://github.com/hunkim/word-rnn-tensorflow - Multi-layer Recurrent Neural Networks (LSTM, RNN) for word-level language models in Python using TensorFlow. https://github.com/jsuarez5341/Recurrent-Highway-Hypernetworks-NIPS - Implementation for paper: Character-Level Language Modeling with Recurrent Highway Hypernetworks https://github.com/pytorch/fairseq - Facebook AI Research Sequence-to-Sequence Toolkit written in Python. https://github.com/minimaxir/textgenrnn - Easily train your own text-generating neural network of any size and complexity on any text dataset with a few lines of code. https://github.com/UFAL-DSG/tgen - A statistical natural language generator for spoken dialogue systems. https://github.com/bjascob/pyInflect - A python module for word inflections designed for use with spaCy. https://github.com/rsennrich/subword-nmt - Unsupervised Word Segmentation for Neural Machine Translation and Text Generation. https://github.com/jiweil/Neural-Dialogue-Generation This project contains the code or part of the code for the dialogue generation part in the following papers: [1] J.Li, M.Galley, C.Brockett, J.Gao and B.Dolan. "A Diversity-Promoting Objective Function for Neural Conversation Models". NAACL2016. [2] J.Li, M.Galley, C.Brockett, J.Gao and B.Dolan. "A persona-based neural conversation model". ACL2016. [3] J.Li, W.Monroe, T.Shi, A.Ritter, D.Jurafsky. "Adversarial Learning for Neural Dialogue Generation " arxiv [4] J.Li, W.Monroe, D.Jurafsky. "Learning to Decode for Future Success" arxiv [5] J.Li, W.Monroe, D.Jurafsky. "A Simple, Fast Diverse Decoding Algorithm for Neural Generation" arxiv [6] J.Li, W.Monroe, D.Jurafsky. "Data Distillation for Controlling Specificity in Dialogue Generation (to appear on arxiv)" https://github.com/tsenghungchen/dialog-generation-paper - A list of recent papers regarding dialogue generation. https://github.com/wiseodd/generative-models - Collection of generative models, e.g. GAN, VAE in Pytorch and Tensorflow. Generative Adversarial Nets (GAN) Vanilla GAN, Conditional GAN, InfoGAN, Wasserstein GAN, Mode Regularized GAN, Coupled GAN, Auxiliary Classifier GAN, Least Squares GAN, Boundary Seeking GAN, Energy Based GAN, f-GAN, Generative Adversarial Parallelization, DiscoGAN, Adversarial Feature Learning & Adversarially Learned Inference, Boundary Equilibrium GAN, Improved Training for Wasserstein GAN, DualGAN, MAGAN: Margin Adaptation for GAN, Softmax GAN, GibbsNet Variational Autoencoder (VAE) Vanilla VAE, Conditional VAE, Denoising VAE, Adversarial Autoencoder, Adversarial Variational Bayes, Restricted Boltzmann Machine (RBM) Binary RBM with Contrastive Divergence Binary RBM with Persistent Contrastive Divergence Helmholtz Machine Binary Helmholtz Machine with Wake-Sleep Algorithm https://github.com/mikelkl/TF2-QA - 21th place (top2%) solution for kaggle TensorFlow 2.0 Question Answering. https://github.com/OceanskySun/GraftNet - This is the implementation of GraftNet described in EMNLP 2018 paper Open Domain Question Answering Using Early Fusion of Knowledge Bases and Text, https://arxiv.org/abs/1809.00782 https://github.com/ryankiros/skip-thoughts - Sent2Vec encoder and training code from the paper "Skip-Thought Vectors", https://arxiv.org/abs/1506.06726 https://github.com/bjascob/pySimpleNLG - A python port of SimpleNLG. https://github.com/asyml/texar - Toolkit for Machine Learning, Natural Language Processing, and Text Generation, in TensorFlow. This is part of the CASL project: http://casl-project.ai/ https://github.com/martiansideofthemoon/hurdles-longform-qa - Official repository with code and data accompanying the NAACL 2021 paper "Hurdles to Progress in Long-form Question Answering" ( https://arxiv.org/abs/2103.06332 ). BERT, TRANSFORMERS https://github.com/google-research/bert - TensorFlow code and pre-trained models for BERT https://github.com/hanxiao/bert-as-service - Using BERT model as a sentence encoding service, i.e. mapping a variable-length sentence to a fixed-length vector https://github.com/Separius/BERT-keras - Keras implementation of BERT with pre-trained weights https://github.com/codertimo/BERT-pytorch - Google AI 2018 BERT pytorch implementation. https://github.com/jeongukjae/pytorch-bert - An implementation of BERT using PyTorch's TransformerEncoder. https://github.com/CyberZHG/keras-bert - Implementation of BERT that could load official pre-trained models for feature extraction and prediction https://github.com/bojone/bert4keras - light reimplement of bert for keras. https://github.com/jayparks/transformer - A Pytorch Implementation of "Attention is All You Need" and "Weighted Transformer Network for Machine Translation" https://github.com/jadore801120/attention-is-all-you-need-pytorch - A PyTorch implementation of the Transformer model in "Attention is All You Need". https://github.com/huggingface/transformers - Transformers: State-of-the-art Natural Language Processing for TensorFlow 2.0 and PyTorch. https://huggingface.co/transformers https://github.com/huggingface/accelerate - A simple way to train and use PyTorch models with multi-GPU, TPU, mixed-precision. https://github.com/zihangdai/xlnet - XLNet: Generalized Autoregressive Pretraining for Language Understanding https://github.com/graykode/xlnet-Pytorch - Simple XLNet implementation with Pytorch Wrapper, https://arxiv.org/abs/1906.08237 https://github.com/graykode/ALBERT-Pytorch - Pytorch Implementation of ALBERT(A Lite BERT for Self-supervised Learning of Language Representations), https://arxiv.org/abs/2010.02480 https://github.com/UKPLab/sentence-transformers - Sentence Transformers: Multilingual Sentence Embeddings using BERT / RoBERTa / XLM-RoBERTa & Co. with PyTorch https://github.com/kimiyoung/transformer-xl - This repository contains the code in both PyTorch and TensorFlow for our paper, https://arxiv.org/abs/1901.02860 https://github.com/openai/finetune-transformer-lm - Code and model for the paper "Improving Language Understanding by Generative Pre-Training". https://github.com/openai/sparse_attention - Examples of using sparse attention, as in "Generating Long Sequences with Sparse Transformers" https://github.com/allenai/longformer - Longformer: The Long-Document Transformer, https://arxiv.org/abs/2004.05150 https://github.com/salesforce/ctrl - Conditional Transformer Language Model for Controllable Generation, https://arxiv.org/abs/1909.05858 https://github.com/samsucik/knowledge-distil-bert - Master's thesis project in collaboration with Rasa, focusing on knowledge distillation from BERT into different very small networks and analysis of the students' NLP capabilities. https://github.com/lucidrains/vit-pytorch - Implementation of Vision Transformer, a simple way to achieve SOTA in vision classification with only a single transformer encoder, in Pytorch https://github.com/lucidrains/memformer - Implementation of Memformer, a Memory-augmented Transformer, in Pytorch. https://github.com/lucidrains/reformer-pytorch This is a Pytorch implementation of Reformer https://openreview.net/pdf?id=rkgNKkHtvB It includes LSH attention, reversible network, and chunking. It has been validated with an auto-regressive task (enwik8). https://github.com/lucidrains/performer-pytorch - An implementation of Performer, a linear attention-based transformer, in Pytorch. https://github.com/lucidrains/x-transformers - A simple but complete full-attention transformer with a set of promising experimental features from various papers. Augmenting Self-attention with Persistent Memory, https://arxiv.org/abs/1907.01470 Memory Transformers, https://arxiv.org/abs/2006.11527 Transformers Without Tears, https://arxiv.org/abs/1910.05895 GLU Variants Improve Transformer, https://arxiv.org/abs/2002.05202 ReLU2, https://arxiv.org/abs/2109.08668 Rezero Is All You Need, https://arxiv.org/abs/2003.04887 Explicit Sparse Transformer: Concentrated Attention Through Explicit Selection, https://arxiv.org/abs/1912.11637 Talking-Heads Attention, https://arxiv.org/abs/2003.02436 Collaborative Attention, https://arxiv.org/abs/2006.16362 Attention on Attention for Image Captioning, https://arxiv.org/abs/1908.06954 Intra-attention Gating on Values Improving Transformer Models by Reordering their Sublayers, https://arxiv.org/abs/1911.03864 ... https://github.com/lucidrains/triton-transformer - Implementation of a Transformer, but completely in Triton. https://github.com/ofirpress/attention_with_linear_biases - Code for our ALiBi method for transformer language models. https://github.com/jessevig/bertviz - Tool for visualizing attention in the Transformer model (BERT, GPT-2, Albert, XLNet, RoBERTa, CTRL, etc.). https://github.com/EleutherAI/gpt-neo - An implementation of model parallel GPT-2 and GPT-3-style models using the mesh-tensorflow library. https://github.com/EleutherAI/gpt-neox/ - An implementation of model parallel autoregressive transformers on GPUs, based on the DeepSpeed library. https://github.com/Separius/awesome-fast-attention - list of efficient attention modules. https://github.com/lucidrains/fast-transformer-pytorch - Implementation of Fast Transformer in Pytorch, https://arxiv.org/abs/2108.09084 . https://github.com/lucidrains/routing-transformer - Fully featured implementation of Routing Transformer, https://arxiv.org/abs/2003.05997 https://github.com/lucidrains/uformer-pytorch - https://arxiv.org/abs/2106.03106 https://github.com/lucidrains/segformer-pytorch - Implementation of Segformer, Attention + MLP neural network for segmentation, in Pytorch, https://arxiv.org/abs/2105.15203 https://github.com/lucidrains/rotary-embedding-torch - Implementation of Rotary Embeddings, from the Roformer paper, in Pytorch https://github.com/lucidrains/local-attention - An implementation of local windowed attention for language modeling. https://github.com/lucidrains/charformer-pytorch - Implementation of the GBST block from the Charformer paper, in Pytorch. https://github.com/lucidrains/nystrom-attention - Implementation of NystrC6m Self-attention, from the paper NystrC6mformer, https://arxiv.org/abs/2102.03902 . https://github.com/lucidrains/memory-transformer-xl - A variant of Transformer-XL where the memory is updated not with a queue, but with attention. https://github.com/lucidrains/feedback-transformer-pytorch - Implementation of Feedback Transformer in Pytorch. https://github.com/lucidrains/memory-compressed-attention - Implementation of Memory-Compressed Attention, from the paper "Generating Wikipedia By Summarizing Long Sequences". https://github.com/lucidrains/conformer - Implementation of the convolutional module from the Conformer paper, for use in Transformers. CHATBOT https://github.com/RasaHQ/rasa - Open source machine learning framework to automate text- and voice-based conversations: NLU, dialogue management, connect to Slack, Facebook, and more - Create chatbots and voice assistants https://rasa.com/docs/ https://github.com/RasaHQ/nlu-hyperopt - Find the best hyperparameters for your Rasa NLU model. https://github.com/RasaHQ/awesome-rasa - list of Rasa resources curated by Rasa and the community https://github.com/invocable/awesome-bots - The most awesome list about bots https://github.com/fendouai/Awesome-Chatbot - https://github.com/fendouai/Awesome-Chatbot https://github.com/facebookresearch/ParlAI - A framework for training and evaluating AI models on a variety of openly available dialogue datasets. https://github.com/dennybritz/chatbot-retrieval - Dual LSTM Encoder for Dialog Response Generation https://github.com/gunthercox/ChatterBot - ChatterBot is a machine learning, conversational dialog engine for creating chat bots https://github.com/howdyai/botkit - Botkit is an open source developer tool for building chat bots, apps and custom integrations for major messaging platforms. https://github.com/lukalabs/cakechat - CakeChat: Emotional Generative Dialog System https://github.com/NVIDIA/NeMo - NeMo: a toolkit for conversational AI https://nvidia.github.io/NeMo/ https://github.com/alfredfrancis/ai-chatbot-framework - A python chatbot framework with Natural Language Understanding and Artificial Intelligence https://github.com/ricsinaruto/Seq2seqChatbots - A wrapper around tensor2tensor to flexibly train, interact, and generate data for neural chatbots. https://github.com/jakesgordon/javascript-state-machine - A javascript finite state machine library. https://github.com/macabdul9/CASA-Dialogue-Act-Classifier PyTorch implementation of the paper "Dialogue Act Classification with Context-Aware Self-Attention" for dialogue act classification with a generic dataset class and PyTorch-Lightning trainer. https://github.com/ColingPaper2018/DialogueAct-Tagger - A resource to create a multi domain Dialog Act Tagger for conversational agents using publicly available data. https://github.com/gigasquid/speech-acts-classifier - Speech act classifier for text based on Stanford CoreNLP and Weka. CHATBOT CLIENT, CHAT SERVER https://github.com/botfront/rasa-webchat - A feature-rich chat widget for Rasa and Botfront. https://github.com/tinode/chat - Instant messaging platform. Backend in Go. Clients: Swift iOS, Java Android, JS webapp, scriptable command line; chatbots. https://github.com/tdlib/td - TDLib (Telegram Database library) is a cross-platform library for building Telegram clients. It can be easily used from almost any programming language. https://github.com/FaridSafi/react-native-gifted-chat - The most complete chat UI for React Native https://gifted.chat - The most complete chat UI for React Native https://gifted.chat . https://github.com/hubotio/hubot - Hubot is a framework to build chat bots, modeled after GitHub's Campfire bot of the same name, hubot. https://github.com/python-telegram-bot/python-telegram-bot - We have made you a wrapper you can't refuse. https://github.com/LonamiWebs/Telethon - Telethon is an asyncio Python 3 MTProto library to interact with Telegram's API as a user or through a bot account (bot API alternative). https://github.com/xmppjs/xmpp.js XMPP is an open technology for real-time communication, which powers a wide range of applications including instant messaging, presence, multi-party chat, voice and video calls, collaboration, lightweight middleware, content syndication, and generalized routing of XML data. https://github.com/bluszcz/awesome-xmpp https://github.com/processone/ejabberd - ejabberd is a distributed, fault-tolerant technology that allows the creation of large-scale instant messaging applications. The server can reliably support thousands of simultaneous users on a single node and has been designed to provide exceptional standards of fault tolerance. As an open source technology, based on industry-standards, ejabberd can be used to build bespoke solutions very cost effectively. https://github.com/feross/simple-peer https://www.kurento.org/whats-kurento - Kurento is a WebRTC media server and a set of client APIs making simple the development of advanced video applications for WWW and smartphone platforms. https://github.com/chatwoot/chatwoot - Open-source customer engagement suite, an alternative to Intercom, Zendesk, Salesforce Service Cloud etc. How to echobot with XMPP, BOSH, and Strophe - https://gist.github.com/sysang/ed255cbba4d5ca92ba8a8886d58c5b08 https://github.com/RocketChat/Rocket.Chat - The communications platform that puts data protection first. https://github.com/jitsi/jitsi-meet - Jitsi Meet - Secure, Simple and Scalable Video Conferences that you use as a standalone app or embed in your web application. https://github.com/feross/simple-peer - Simple WebRTC video, voice, and data channels. TEXT-TO-SPEECH, SPEECH-TO-TEXT https://github.com/syoyo/tacotron-tts-cpp - Text-to-speech in (partially) C++ using Tacotron model + Tensorflow https://github.com/CorentinJ/Real-Time-Voice-Cloning This repository is an implementation of Transfer Learning from Speaker Verification to Multispeaker Text-To-Speech Synthesis (SV2TTS) with a vocoder that works in real-time. https://github.com/mozilla/TTS - Deep learning for Text to Speech (Discussion forum: https://discourse.mozilla.org/c/tts ). https://github.com/mozilla/DeepSpeech - DeepSpeech is an open source embedded (offline, on-device) speech-to-text engine which can run in real time on devices ranging from a Raspberry Pi 4 to high power GPU servers. https://github.com/buriburisuri/speech-to-text-wavenet - A tensorflow implementation of speech recognition based on DeepMind's WaveNet: A Generative Model for Raw Audio. (Hereafter the Paper) https://github.com/NVIDIA/OpenSeq2Seq - Toolkit for efficient experimentation with Speech Recognition, Text2Speech and NLP https://nvidia.github.io/OpenSeq2Seq https://github.com/kaldi-asr/kaldi - Kaldi Speech Recognition Toolkit. https://github.com/mravanelli/pytorch-kaldi - pytorch-kaldi is a project for developing state-of-the-art DNN/RNN hybrid speech recognition systems. The DNN part is managed by pytorch, while feature extraction, label computation, and decoding are performed with the kaldi toolkit. https://github.com/TensorSpeech/TensorFlowTTS - TensorFlowTTS: Real-Time State-of-the-art Speech Synthesis for Tensorflow 2 (supported including English, French, Korean, Chinese, German and Easy to adapt for other languages). VIETNAMESE https://github.com/vncorenlp/VnCoreNLP - A Vietnamese natural language processing toolkit (NAACL 2018) https://github.com/phuonglh/vn.vitk - A Vietnamese Text Processing Toolkit COMPUTER VISION https://github.com/kjw0612/awesome-deep-vision - A curated list of deep learning resources for computer vision. https://github.com/davidsandberg/facenet - Face recognition using Tensorflow. https://github.com/matterport/Mask_RCNN - Mask R-CNN for object detection and instance segmentation on Keras and TensorFlow. https://github.com/karpathy/neuraltalk2 - Efficient Image Captioning code in Torch, runs on GPU. https://github.com/facebookresearch/vissl - VISSL is FAIR's library of extensible, modular and scalable components for SOTA Self-Supervised Learning with images. https://github.com/haltakov/natural-language-image-search - Search photos on Unsplash using natural language. https://github.com/KaimingHe/deep-residual-networks - Deep Residual Learning for Image Recognition, https://arxiv.org/abs/1512.03385 https://github.com/qubvel/efficientnet - Implementation of EfficientNet model. Keras and TensorFlow Keras. https://github.com/facebookresearch/maskrcnn-benchmark - Fast, modular reference implementation of Instance Segmentation and Object Detection algorithms in PyTorch. https://github.com/openai/CLIP - It can be instructed in natural language to predict the most relevant text snippet, given an image, without directly optimizing for the task, similarly to the zero-shot capabilities of GPT-2 and 3. https://github.com/mlfoundations/open_clip - An open source implementation of CLIP. https://github.com/lucidrains/DALLE-pytorch - Implementation / replication of DALL-E (paper), OpenAI's Text to Image Transformer, in Pytorch. It will also contain CLIP for ranking the generations. https://github.com/CompVis/taming-transformers - Taming Transformers for High-Resolution Image Synthesis. https://github.com/facebookresearch/detectron2 - Detectron2 is FAIR's next-generation platform for object detection, segmentation and other visual recognition tasks. https://github.com/google-research/simclr - SimCLRv2 - Big Self-Supervised Models are Strong Semi-Supervised Learners, arxiv.org/abs/2006.10029. https://github.com/OlafenwaMoses/ImageAI - A python library built to empower developers to build applications and systems with self-contained Computer Vision capabilities. https://github.com/Spijkervet/SimCLR - PyTorch implementation of SimCLR: A Simple Framework for Contrastive Learning of Visual Representations by T. Chen et al. https://github.com/sthalles/SimCLR - PyTorch implementation of SimCLR: A Simple Framework for Contrastive Learning of Visual Representations. https://github.com/zzd1992/Image-Local-Attention - A better PyTorch implementation of image local attention which reduces the GPU memory by an order of magnitude. GEOMETRIC DEEP LEARNING, GRAPH ALGORITHMS https://github.com/shaoxiongji/knowledge-graphs - A collection of research on knowledge graphs. https://github.com/dmlc/dgl - Python package built to ease deep learning on graph, on top of existing DL frameworks. https://github.com/geomstats/geomstats - Computations and statistics on manifolds with geometric structures. https://github.com/DeepGraphLearning/LiteratureDL5Graph - A comprehensive collection of recent papers on graph deep learning. https://github.com/deepmind/graph_nets - Build Graph Nets in Tensorflow. https://github.com/HazyResearch/hyperbolics Hyperbolic embedding implementations of Representation Tradeoffs for Hyperbolic Embeddings + product embedding implementations of Learning Mixed-Curvature Representations in Product Spaces https://dawn.cs.stanford.edu/2019/10/10/noneuclidean/ https://github.com/jcyk/gtos - Code for AAAI2020 paper "Graph Transformer for Graph-to-Sequence Learning", https://arxiv.org/abs/1911.07470v2 https://github.com/facebookresearch/poincare-embeddings - PyTorch implementation of the NIPS-17 paper "PoincarC) Embeddings for Learning Hierarchical Representations", https://papers.nips.cc/paper/7213-poincare-embeddings-for-learning-hierarchical-representations https://github.com/lateral/poincare-embeddings - A multi-threaded C++ implementation of Nickel & Kiela's "Poincare Embeddings" paper from NIPS 2017, following the implementation of the authors. https://github.com/williamleif/GraphSAGE - Representation learning on large graphs using stochastic graph convolutions. https://github.com/lucidrains/adjacent-attention-network - Graph neural network message passing reframed as a Transformer with local attention. https://github.com/pyg-team/pytorch_geometric - Graph Neural Network Library for PyTorch https://github.com/graph4ai/graph4nlp - Graph4nlp is the library for the easy use of Graph Neural Networks for NLP. Welcome to visit our DLG4NLP website ( https://dlg4nlp.github.io/index.html ) for various learning resources! https://github.com/benedekrozemberczki/pytorch_geometric_temporal - PyTorch Geometric Temporal: Spatiotemporal Signal Processing with Neural Machine Learning Models (CIKM 2021) https://github.com/HazyResearch/hgcn - Hyperbolic Graph Convolutional Networks in PyTorch. https://github.com/dalab/hyperbolic_nn - Source code for the paper "Hyperbolic Neural Networks", https://arxiv.org/abs/1805.09112 https://github.com/daiquocnguyen/Graph-Transformer - Transformer for Graph Classification (Pytorch and Tensorflow) https://github.com/weihua916/powerful-gnns - How Powerful are Graph Neural Networkso https://github.com/vuptran/graph-representation-learning - Autoencoders for Link Prediction and Semi-Supervised Node Classification (DSAA 2018) https://github.com/THUDM/GCC - GCC: Graph Contrastive Coding for Graph Neural Network Pre-Training https://github.com/bluer555/KernelGCN - Codes for NIPS 2019 Paper: Rethinking Kernel Methods for Node Representation Learning on Graphs https://github.com/williamleif/GraphSAGE - Representation learning on large graphs using stochastic graph convolutions. https://github.com/phanein/deepwalk - DeepWalk - Deep Learning for Graphs. https://github.com/shenweichen/GraphEmbedding - Implementation and experiments of graph embedding algorithms. https://github.com/benedekrozemberczki/karateclub - Karate Club: An API Oriented Open-source Python Framework for Unsupervised Learning on Graphs (CIKM 2020). https://github.com/gordicaleksa/pytorch-GAT - This repo contains a PyTorch implementation of the original GAT paper (Graph Attention Network byVeličković et al.). It's aimed at making it easy to start playing and learning about GAT and GNNs in general. EVOLOTUION ALGORITHMS https://github.com/uber-research/deep-neuroevolution - This repo contains distributed implementations of the algorithms described in: https://arxiv.org/abs/1712.06567 https://arxiv.org/abs/1712.06560 https://eng.uber.com/deep-neuroevolution/ REINFORCEMENT LEARNING https://github.com/YuhangSong/Arena-Baselines Arena is a general evaluation platform and building toolkit for single/multi-agent intelligence. As a part of Arena project, this repository is to provide implementation of state-of-the-art deep single/multi-agent reinforcement learning baselines. https://github.com/keras-rl/keras-rl - keras-rl implements some state-of-the art deep reinforcement learning algorithms in Python and seamlessly integrates with the deep learning library Keras. https://github.com/junhyukoh/deep-reinforcement-learning-papers - A list of recent papers regarding deep reinforcement learning https://github.com/dennybritz/reinforcement-learning - Implementation of Reinforcement Learning Algorithms. Python, OpenAI Gym, Tensorflow. Exercises and Solutions to accompany Sutton's Book and David Silver's course. https://github.com/openai/gym - A toolkit for developing and comparing reinforcement learning algorithms. https://github.com/openai/universe - Universe: a software platform for measuring and training an AI's general intelligence across the world's supply of games, websites and other applications. https://github.com/openai/spinningup - An educational resource to help anyone learn deep reinforcement learning. https://spinningup.openai.com/ https://github.com/tensorforce/tensorforce - Tensorforce: a TensorFlow library for applied reinforcement learning https://github.com/openai/baselines - OpenAI Baselines: high-quality implementations of reinforcement learning algorithms. https://github.com/BY571/Munchausen-RL - PyTorch implementation of the Munchausen Reinforcement Learning Algorithms M-DQN and M-IQN DATASETS https://github.com/huggingface/datasets - The largest hub of ready-to-use datasets for ML models with fast, easy-to-use and efficient data manipulation tools. https://pile.eleuther.ai/ - The Pile is a 825 GiB diverse, open source language modelling data set that consists of 22 smaller, high-quality datasets combined together. https://github.com/awesomedata/awesome-public-datasets - A topic-centric list of HQ open datasets. https://github.com/niderhoff/nlp-datasets - Alphabetical list of free/public domain datasets with text data for use in Natural Language Processing (NLP). https://github.com/ad-freiburg/large-qa-datasets - A collection of large datasets containing questions and their answers for use in Natural Language Processing tasks like question answering (QA). Datasets are sorted by year of publication. https://github.com/makcedward/nlpaug - Data augmentation for NLP Generate synthetic data for improving model performance without manual effort Simple, easy-to-use and lightweight library. Augment data in 3 lines of code Plug and play to any machine leanring/ neural network frameworks (e.g. scikit-learn, PyTorch, TensorFlow) Support textual and audio input https://github.com/scrapy/scrapy - Scrapy, a fast high-level web crawling & scraping framework for Python. https://github.com/chiphuyen/lazynlp - Library to scrape and clean web pages to create massive datasets. https://github.com/rodrigopivi/Chatito - Generate datasets for AI chatbots, NLP tasks, named entity recognition or text classification models using a simple DSL! https://github.com/snorkel-team/snorkel - A system for quickly generating training data with weak supervision. https://github.com/clips/pattern - Web mining module for Python, with tools for scraping, natural language processing, machine learning, network analysis and visualization. https://github.com/lorien/awesome-web-scraping - List of libraries, tools and APIs for web scraping and data processing. https://github.com/attardi/wikiextractor - A tool for extracting plain text from Wikipedia dumps. https://github.com/coqui-ai/open-speech-corpora - A list of accessible speech corpora for ASR, TTS, and other Speech Technologies https://github.com/first20hours/google-10000-english - This repo contains a list of the 10,000 most common English words in order of frequency, as determined by n-gram frequency analysis of the Google's Trillion Word Corpus. https://github.com/robvanvolt/DALLE-datasets - This is a summary of easily available datasets for generalized DALLE-pytorch training. https://github.com/facebookresearch/AugLy - A data augmentations library for audio, image, text, and video. OTHERS https://github.com/spencermountain/compromise - compromiseis ajavascript library that interprets andpre-parsestext. https://github.com/mindsdb/mindsdb/ - Predictive AI layer for existing databases. Predictive AI layer for existing databases. AI Tables. Move your models instantly to production, reduce resources, and overhead costs with AI Tables that deliver the results as database tables. Explainable AI. Use MindsDB Studio to interpret predictions made by the model. Identify potential data biases, evaluate and visualize model accuracy using the Explainable AI. https://github.com/jina-ai/jina/ Jina is an open-source deep-learning powered search framework, empowering developers to create cross-modal or multi-modal search systems for text, images, video, and audio. Jina is a cloud-native project, and provides long-term support from a full-time, venture-backed team. https://github.com/EpistasisLab/tpot - A Python Automated Machine Learning tool that optimizes machine learning pipelines using genetic programming. https://github.com/bqplot/bqplot - Plotting library for IPython/Jupyter notebooks. https://github.com/rushter/MLAlgorithms - Minimal and clean examples of machine learning algorithms implementations. https://github.com/openai/baselines - OpenAI Baselines: high-quality implementations of reinforcement learning algorithms. https://github.com/hundredblocks/semantic-search - This repository contains a barebones implementation of a semantic search engine. The implementation is based on leveraging pre-trained embeddings from VGG16 (trained on Imagenet), and GloVe (trained on Wikipedia). It allows you to: Find similar images to an input image Find similar words to an input word Search through images using any word Generate tags for any image https://github.com/hora-search/hora - efficient approximate nearest neighbor search algorithm collections library written in Rust. https://github.com/rom1504/awesome-semantic-search - Semantic search with embeddings: index anything. https://github.com/Agrover112/awesome-semantic-search - A curated list of awesome resources related to Semantic Search and Semantic Similarity tasks. https://github.com/jina-ai/jina - Jina is a neural search framework that empowers anyone to build SOTA and scalable deep learning search applications in minutes. https://github.com/jina-ai/examples HASKELL https://github.com/mikeizbicki/HLearn - Homomorphic machine learning https://github.com/brunjlar/neural - Neural Nets in native Haskell https://github.com/creswick/chatter - A library of Natural Language Processing algorithms for Haskell. https://github.com/roelvandijk/numerals - Convert numbers to number words https://github.com/mrkkrp/megaparsec - Industrial-strength monadic parser combinator library. PROLOG https://github.com/terminusdb/terminusdb - TerminusDB is an open source knowledge graph and document store. Use it to build versioned data products. Remark! It's implmented by Prolog, thus it's greate case to learn how to code using Prolog TerminusDB is an open source knowledge graph and document store. https://github.com/aarroyoc/postgresql-prolog - A Prolog library to connect to PostgreSQL databases NEW PHILOSOPHY (DL) https://github.com/Chen-Cai-OSU/awesome-equivariant-network - Paper list for equivariant neural network https://github.com/lucidrains/lie-transformer-pytorch - Implementation of Lie Transformer, Equivariant Self-Attention, in Pytorch. https://github.com/Guillemdb/FractalAI - Celular automaton-based calculus for the masses https://github.com/guillemdb/fragile - Framework for building algorithms based on FractalAI theory. https://github.com/lolemacs/pytorch-eventprop - A PyTorch implementation of EventProp [ https://arxiv.org/abs/2009.08378 ], a method to train Spiking Neural Networks. https://github.com/EpistasisLab/tpot - A Python Automated Machine Learning tool that optimizes machine learning pipelines using genetic programming. https://github.com/opencog - AGI - Machine Learning, Language, Reasoning, Robotics https://github.com/openai/triton - This is the development repository of Triton, a language and compiler for writing highly efficient custom Deep-Learning primitives. The aim of Triton is to provide an open-source environment to write fast code at higher productivity than CUDA, but also with higher flexibility than other existing DSLs. The foundations of this project are described in the following MAPL2019 publication, http://www.eecs.harvard.edu/~htk/publication/2019-mapl-tillet-kung-cox.pdf https://github.com/JonathanSalwan/Triton Triton is a Dynamic Binary Analysis (DBA) framework. It provides internal components like a Dynamic Symbolic Execution (DSE) engine, a dynamic taint engine, AST representations of the x86, x86-64, ARM32 and AArch64 Instructions Set Architecture (ISA), SMT simplification passes, an SMT solver interface and, the last but not least, Python bindings.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Transformer from Scratch for NLP This repository is a guide and showcase for building a Transformer with PyTorch. It is intended for intermediate ML practitioners who want to understand how to implement a Transformer from scratch (if you are a beginner, I recommend starting with the CNN-Architecture-Guide . The Transformer is a deep learning architecture introduced in the 2017 paper “Attention Is All You Need” [ 1 ] , based on the multi-head self-attention mechanism. Large Language Models (LLMs) , such as GPT, are direct descendants of this architecture. By scaling parameters, data, and compute, they have revolutionized NLP and enabled breakthroughs from machine translation to conversational AI. In this project, I have implemented SimpleTransformer following the original paper’s design, and applied it to Machine Translation . This repository is built for learning purposes, combining theoretical background with practical implementation, to help those who want to start coding Transformers for NLP (Natural Language Processing) tasks. 🚀 Quick Start Clone the repository: git clone https://github.com/Bengal1/Transformer-From-Scratch-NLP.git cd Transformer-From-Scratch-NLP Install the dependencies: pip install -r requirements.txt Run the project: python main.py Note: Model architecture, training parameters, and experiment settings can be configured in config.py . 📌 Project Overview This project implements a complete encoder-decoder Transformer from scratch in PyTorch and applies it to English-to-French machine translation. The implementation follows the core architecture introduced in Attention Is All You Need , while adapting the training setup to the smaller IWSLT14 dataset and available compute. Component Details Task English → French Machine Translation Framework PyTorch Dataset IWSLT14 En–Fr (~180K sentence pairs) Architecture Encoder–Decoder Transformer Model Variants d_model = 512 and d_model = 1024 Optimization Adam + Noam Learning Rate Scheduler Training Teacher Forcing, Padding Masks, Gradient Accumulation Decoding Beam Search with Length Normalization Evaluation Cross-Entropy Loss and BLEU Best BLEU Score 35.785 Implemented Components Multi-Head Self-Attention Masked Decoder Self-Attention Encoder–Decoder Cross-Attention Token Embeddings Sinusoidal Positional Encoding Position-Wise Feed-Forward Networks Residual Connections and Layer Normalization Padding and Causal Attention Masks Teacher Forcing Noam Learning Rate Scheduling Beam Search with Length Normalization 📊 Results The model performances are evaluated by two primary metrics Loss (training, validation & test) and BLEU . In Optimizations problem, ML training, the Loss is the core signal guiding optimization. it measures how far model's predictions are from the targets, while optimization algorithms adjust model parameters to minimize it. Training loss is computed on the data used to update the model, reflecting how well it’s fitting that set, while validation loss is computed on unseen data to gauge generalization; a growing gap between them often signals overfitting. BLEU (Bilingual Evaluation Understudy) is a metric for judging machine-generated text by comparing it to reference texts using n-gram overlaps. It combines these overlaps with a brevity penalty to avoid rewarding short outputs. Scores range from 0 to 1 (or 0–100%), with higher scores indicating closer matches, though it only measures exact wording matches. Evaluation on Test Dataset Model Variant Test Loss BLEU Score Simple Transformer 512 3.29 35.347 Simple Transformer 1024 3.377 35.785 Training & Validation Loss Bilingual Evaluation Understudy (BLEU) 🔬 Comparison with the Original Transformer In my experiments, I focus on a single-model comparison using the IWSLT14 dataset, which contains approximately 180,000 sentence pairs, to evaluate how well the Transformer architecture performs under resource-constrained conditions. For reference, the original Transformer models reported by Vaswani et al. (2017) were trained on the WMT 2014 dataset, which includes roughly 36 million sentence pairs, with a test set of about 3,000 sentences. In that setup, the Base model achieved a BLEU score of 38.1 and the Big model reached 41.0. While the paper also reports a Big Ensemble model achieving 41.8, ensembles are not within the scope of my comparison. By focusing on a smaller dataset, I establish a fair baseline for translation quality under data-limited conditions, highlighting the impact of training scale rather than architectural differences. My model differs from the original Transformer in several key aspects. I train a single-model Transformer on IWSLT14 using a single NVIDIA A100-SXM4-40GB GPU (Google Colab environment). I apply weight decay for regularization and adjust the batch size according to hardware limitations. To achieve a larger effective batch size without exceeding memory capacity, I use gradient accumulation, where gradients are accumulated over several smaller batches before performing an optimizer step. During inference, I rely on beam search with a length penalty to balance fluency and adequacy. These adjustments help stabilize training and improve generalization on the smaller dataset, while other architectural details such as the number of layers, embedding dimensions, attention heads, and weight initialization strategy remain consistent with the original paper. Model Variant BLEU Score Dataset Trainable Parameters Original Transformer Base (512) 38.1 WMT 2014 En-Fr (~36M samples) 65M parameters Original Transformer Big (1024) 41.0 WMT 2014 En-Fr (~36M samples) 213M parameters Simple Transformer 512 35.35 IWSLT14 En-Fr (~180K samples) 147.8M parameters Simple Transformer 1024 35.785 IWSLT14 En-Fr (~180K samples) 383.6M parameters In comparing my model to both the Base and Big configurations of the original Transformer, I consider not only architectural scale (d_model, d_ff, num_heads) but also differences in parameter count and overall complexity. The Base model uses d_model=512 , d_ff=2048 , and num_heads=8 , while the Big model doubles these values with d_model=1024 , d_ff=4096 , and num_heads=16 . This scaling increases capacity and computational cost, but yields higher translation quality when sufficient data is available. As shown in the table above, my implementation also differs in parameter count for two main reasons: Weight tying : The original Transformer shares parameters between source embeddings, target embeddings, and the output projection. I keep them separate, increasing the parameter count but allowing distinct representations for each component. Vocabulary size : The original uses a joint ~37K vocabulary, while I use separate vocabularies (~56K source, ~73K target), which increases the size of embedding and output layers but captures each language more precisely. As a result, even when configured like Transformer-Base, my model contains more parameters, reflecting design choices that emphasize richer vocabulary coverage under data-limited conditions. When evaluating our implementation against the original Transformer, it is important to note the stark difference in dataset size: the IWSLT14 corpus (~180K sentences) is only about 0.5% of the scale of WMT14 (~36M sentences). Despite this limitation, the Simple Transformer 512 achieved roughly 93% of the BLEU score of the original Base model, demonstrating that even with a much smaller dataset, a moderately sized model can generalize well. In contrast, the Simple Transformer 1024 reached only about 87% of the BLEU score of the original Big model. This suggests that while the larger model has substantially higher capacity, its complexity far exceeds the available data, leading to underutilization and diminished relative performance. In other words, the 512 variant strikes a better balance between model size and dataset scale, whereas the 1024 variant highlights the need for substantially more training data to fully leverage its capacity. If you look at the training and validation curves presented in the following Evaluation section, they further illustrate these observations.. For the 512-dimensional model, both training and validation loss decrease steadily and stabilize without large divergence, while BLEU scores quickly plateau near their maximum, indicating efficient learning and good generalization. In contrast, the 1024-dimensional model shows a wider gap between training and validation loss, with validation loss plateauing at a higher value and BLEU scores improving more slowly. This reflects over-parameterization relative to the dataset size: the larger model can fit the training data better, but its higher capacity cannot be fully utilized given the limited training samples, leading to slower convergence and reduced generalization. Overall, these graphs confirm that the 512 variant achieves a better trade-off between complexity and dataset scale, while the 1024 variant would benefit from more data or stronger regularization. 🏗️ The Transformer Architecture The Transformer is a deep learning architecture introduced by Google researchers in the 2017 paper “Attention Is All You Need.” This paper not only proposed the Transformer architecture but also established the attention mechanism as a powerful alternative to recurrence and convolution for sequence modeling. The model is built around multi-head attention, enabling it to efficiently capture complex relationships and long-range dependencies in sequences. The Transformer consists of an encoder and a decoder, each composed of stacked layers that include multi-head attention, feed-forward networks, residual connections, and layer normalization. The encoder encodes the input sequence into context-aware representations, while the decoder generates the output sequence step by step, using masked self-attention to preserve autoregressive decoding and applying cross-attention over the encoder’s context representations. The Transformer revolutionized sequence modeling by replacing recurrence and convolution with attention, allowing models to capture long-range dependencies more effectively and process sequences in parallel. Its architecture enables rich, context-aware representations and dramatically improves performance across tasks like translation, summarization, and language understanding. These capabilities set the stage for exploring its attention mechanism and core components, which are at the heart of its success. Attention The Attention (Scaled Dot-Product Attention) mechanism is the heart of the Transformer and, it is a machine learning method that determines the relative importance of each component in a sequence relative to the other components in that sequence. In this method the learnable (trainable) parameters are the weights: $W_{Q}, W_{K}, W_{V}, W_{out}(optional)$ , which creates $Q, K, V$ . Given: $W_{Q}∈ℝ^{E×d_k}$ , $W_{K}∈ℝ^{E×d_k}$ , $W_{V}∈ℝ^{E×d_v}$ and Input $X∈ℝ^{M×E}$ : $$ X·W_{Q} = Q ; X·W_{K} = K ; X·W_{V} = V $$ When $E$ is the model/embedding dimension, $d_k$ is the dimension of the key and query vectors that control how similarities are computed, and $d_v$ is the dimension of the value vectors whose weighted sum forms the output. Each token in the input sequence is represented using three matrices: Query (Q) : Represents the word we are currently processing and is used to find relevant words in the input. Key (K) : Represents all words in the input sequence and is used to compare with the query to determine relevance. Value (V) : Holds the actual word representations, which are combined based on attention scores to form the final output. To determine which words are most relevant to the current query, we compute a dot product between $Q$ and $K$ , and in order to prevent extreme values we scale it, this is called the Attention Score : $$\frac{Q·K^{T}}{\sqrt{d}}$$ To execute the attention we apply $Softmax$ and multiply with $V$ and get the Attention Weights : $$Attention(Q,K,V) = Softmax \Bigg(\frac{Q K^{T}}{\sqrt{d}} \Bigg)·V$$ Self-Attention vs. Cross-Attention Self-Attention is the simplest way of attention. we use the input sequence and the weights to create the query matrix, $Q$ , the key matrix, $K$ , and the value matrix, $V$ , and then execute the attention. This will tell us the affinity between vectors(tokens/words). In Cross-Attention , $Q$ comes from the decoder's input (e.g., previously generated tokens or a prompt), while $K$ and $V$ come from the encoder's output, allowing the decoder to focus on relevant information from the input sequence. This means self-attention captures dependencies within a sequence, while cross-attention links information between two different sequences. Feature Self-Attention Cross-Attention Q (Query) Source From the same sequence (input or decoder tokens) From the decoder’s conditional input (generated tokens or prompt) K (Key) Source From the same sequence From the encoder’s output (context representations) V (Value) Source From the same sequence From the encoder’s output (context representations) Purpose Captures dependencies within the same sequence Links information between encoder and decoder Example Text summarization, sentiment analysis, language modeling Machine translation, text-to-text generation, question answering Given an Input : $X∈ℝ^{M×E}$ and a Conditional Input : $C∈ℝ^{L×E}$ , when $M$ is max_length of the input, $E$ is embedding_dimension and $L$ is the conditional input sequence length. We compute the matrices of the attention: $Q$ , $K$ and $V$ : Self-Attention: Cross-Attention: $X·W_{q} = Q∈ℝ^{M×d_k}$ $X·W_q = Q∈ℝ^{M×d_k}$ $X·W_{k} = K∈ℝ^{M×d_k}$ $C·W_k = K∈ℝ^{L×d_k}$ $X·W_{v} = V∈ℝ^{M×d_v}$ $C·W_v = V∈ℝ^{L×d_v}$ After computing the attention components, the rest of the process converges and is carried out in the same manner: $$Attention(Q,K,V) = Softmax \Bigg(\frac{Q K^{T}}{\sqrt{d}} \Bigg)·V = ΔX'∈ℝ^{M×d_v}$$ In case of: $d_v \ne E$ then we use the out matrix $W_{out}∈ℝ^{d_v×E}$ to set the output in the right size. This matrix is also a weight matrix (has trainable parameters) it is also used to make the model more complex. $$ → ΔX'·W_{out} = ΔX∈ℝ^{M×E} $$ $$ ⇨ Y = ΔX + X (Residual - Connection) $$ $d_{k}$ (Key dimension) : The size of each key vector, which affects the scaling factor in the dot-product attention $d_{v}$ (Value dimension) : The size of each value vector, determining the dimension of the weighted sum used as the attention output. Residual connection : is a shortcut path that adds the input of the attention layer directly to its output before passing it to the next layer. This helps preserve the original input information, aids in gradient flow, and prevents vanishing gradients. In Transformers, the residual connection is followed by layer normalization to stabilize training. Masked-Attention Masked attention is a variant of self-attention where certain positions in the attention matrix are masked (set to -∞ before softmax, Since $e^{−∞}=0$ , so softmax turns the masked positions into zero attention) to prevent the model from attending to specific tokens. In Transformer decoders, causal masking is used to ensure that a token can only attend to previous tokens (not future ones), enabling autoregressive generation. $$Masked-Attention(Q,K,V) = Softmax \Bigg(\frac{Q K^{T}}{\sqrt{d}} + Mask \Bigg)·V$$ Multi-Head Attention Multi-head attention is an extension of the attention mechanism that allows the model to focus on different parts of the input sequence simultaneously, using multiple attention heads. Each head computes attention independently, and the results are combined to form a more comprehensive representation. Instead of performing a single attention operation, multi-head attention runs multiple attention operations in parallel (with different parameterized projections) and then concatenates the results. Each head learns a different representation by attending to different parts of the input sequence. This allows the model to capture various kinds of dependencies in the input sequence simultaneously. $$head_i = Attention(QW_{Q_{i}},KW_{K_{i}},VW_{V_{i}})$$ $$MultiHead-Attention = Concat(head_1,...,head_h)·W_{out}$$ Where $W_{Q_{i}}, W_{K_{i}}, W_{V_{i}}$ and $W_{out}$ are learnable weight matrices. For more information on Transformer and Attention there is a video series 3Blue 1Brown Feed-Forward Network A Feed-Forward Neural Network (FNN) is a type of artificial neural network where connections between the nodes do not form cycles. The network consists of an input layer, one or more hidden layers, and an output layer. Information flows in one direction—from input to output—hence the name "feedforward." The Layers of the FeedForward Network consist of Dense layer, also called the fully-connected layer, and is used for abstract representations of input data. In this layer, neurons connect to every neuron in the preceding layer. In Multilayer Perceptron networks, these layers are stacked together. In our model the Feed-Forward network compose of 2 fully-connected layers and a ReLU activation that applied between them. I also applied Dropout according to "Attention Is All You Need". For a single Network 'layer', the output is calculated as: $$y = f(W_{1}·x+b_{1})·W_{2} + b_{2}$$ Where: $x$ is the input vector. $W_i$ is the weight matrix of layer i . $b_i$ is the bias vector of layer i . $f$ is the activation function - ReLU. The Dropout applies after the activation function. Activation Functions The activation function introduces non-linearity into the network, allowing it to learn complex patterns. Common activation functions: $ReLU$ (Rectified Linear Unit): $f(x) = max(0,x)$ . $Sigmoid$ : $f(x) = {1 \over {1+e^{-x}}}$ . $Tanh$ : $f(x)=tanh(x)$ . $GELU$ (Gaussian Error Linear Unit): $f(x) = x \cdot \frac{1}{2} \big[ 1 + \text{erf}\left(\frac{x}{\sqrt{2}}\right) \big]$ Positional Encoding Positional encoding is a technique used in sequence-based models (such as transformers) to provide information about the positions or order of tokens in a sequence. Since transformers process entire sequences in parallel and lack an inherent mechanism for handling sequential order (unlike RNNs or LSTMs), positional encoding helps the model differentiate between tokens that appear in different positions within the sequence. Positional encodings are added to token embeddings, enabling the model to process both the semantic meaning and position of tokens in the sequence. $$ PE(k, 2i) = \sin\left( \frac{k}{n^{2i/d}} \right) \quad \text{;} \quad PE(k, 2i+1) = \cos\left( \frac{k}{n^{2i/d}} \right) $$ k - Position of an object in the input sequence, $0 \le k <M-1$ (M=sequence length). n - User defined scalar. Set to 10,000 in the article "Attention Is All You Need". d - Dimension of the model. i - Used for mapping column's/object's indices, $0 \le i < \frac{2}{d}$ . PE(k,j) - Positional encoding of thr j-th index in the k-th object in the input sequence. Example : Lets us note sequence length as $M$ ( $M$ objects/tokens). For sequence length $M$ and model dimension $d$ , the positional encoding vector for position $k$ is defined as: $$ PE(k) = \Big[ \sin\Big(\tfrac{k}{10000^{0/d}}\Big), \cos\Big(\tfrac{k}{10000^{0/d}}\Big), \sin\Big(\tfrac{k}{10000^{2/d}}\Big), \cos\Big(\tfrac{k}{10000^{2/d}}\Big), \ldots, \sin\Big(\tfrac{k}{10000^{(d-2)/d}}\Big), \cos\Big(\tfrac{k}{10000^{(d-2)/d}}\Big) \Big] $$ Stacking the vectors $PE(k)$ for every position $k = 0, \dots, M-1$ forms the full positional encoding matrix used in the model: $$ PE = \begin{bmatrix} \sin\frac{0}{10000^{0/d}} & \cos\frac{0}{10000^{0/d}} & \sin\frac{0}{10000^{2/d}} & \cos\frac{0}{10000^{2/d}} & \cdots & \sin\frac{0}{10000^{(d-2)/d}} & \cos\frac{0}{10000^{(d-2)/d}} \\ \sin\frac{1}{10000^{0/d}} & \cos\frac{1}{10000^{0/d}} & \sin\frac{1}{10000^{2/d}} & \cos\frac{1}{10000^{2/d}} & \cdots & \sin\frac{1}{10000^{(d-2)/d}} & \cos\frac{1}{10000^{(d-2)/d}} \\ \sin\frac{2}{10000^{0/d}} & \cos\frac{2}{10000^{0/d}} & \sin\frac{2}{10000^{2/d}} & \cos\frac{2}{10000^{2/d}} & \cdots & \sin\frac{2}{10000^{(d-2)/d}} & \cos\frac{2}{10000^{(d-2)/d}} \\ \vdots & \vdots & \vdots & \vdots & \ddots & \vdots & \vdots \\ \sin\frac{M-1}{10000^{0/d}} & \cos\frac{M-1}{10000^{0/d}} & \sin\frac{M-1}{10000^{2/d}} & \cos\frac{M-1}{10000^{2/d}} & \cdots & \sin\frac{M-1}{10000^{(d-2)/d}} & \cos\frac{M-1}{10000^{(d-2)/d}} \end{bmatrix} $$ After calculating the positional encoding vectors, $[p_0, p_1, p_2,..., p_{M-1}]$ , we add them to the embedding vectors, $[e_0, e_1, e_2,..., e_{M-1}]$ : $$ [e_0 + p_0,\hspace{0.3em} e_1 + p_1,\hspace{0.3em} e_2 + p_2,\hspace{0.2em}...,\hspace{0.2em} e_{M-1} + p_{M-1}] $$ Layer Normalization Normalization Layer is used to stabilize and accelerate training by normalizing the inputs to each layer. For each input vector (for each token in a sequence), subtract the mean and divide by the standard deviation of the vector's values. This centers the data around 0 with unit variance: $$\hat{x} = \frac{(x - μ)}{\sqrt{σ^{2} + ε}}$$ where μ is the mean and σ is the standard deviation of the input vector. Then apply scaling (gamma) and shifting (beta) parameters (trainable): γ (scale): A parameter to scale the normalized output. β (shift): A parameter to shift the normalized output. $$⇨ y = γ·\hat{x} + β$$ 🗂️ Data & NLP Pipeline The IWSLT14 dataset is a multilingual parallel corpus created for machine translation tasks, specifically focusing on spoken language translation. It is part of the International Workshop on Spoken Language Translation (IWSLT) 2014 challenge. The dataset consists of TED Talks transcriptions and their translations, making it especially useful for training models that handle conversational and informal language. The IWSLT14 English-French (En-Fr) dataset is a part of the International Workshop on Spoken Language Translation (IWSLT). The IWSLT14 dataset is specifically designed for Machine Translation tasks and contains parallel sentences in English and French. The dataset consists of sentence pairs aligned between English and French. Each sentence pair is a translation from one language to the other. In this repository we load the dataset using Hugging Face's Dataset Library . Dataset size: Training Set: Around 179,000 sentence pairs. Validation Set: About 903 sentence pairs. Test Set: Roughly 3,670 sentence pairs. This dataset consists of 56K unique english tokens (vocabulary) and 73K unique french tokens. Tokenization In order to prepare the data for training, we need tokenization converting words or sentences into tokens. The computer doesn't know what to do with words. When you feed it the sentence "This Simple Transformer Guide!", it doesn't understand the meaning of the words or the relationships between them. So what do computers understand? They understand numbers. At the core, computers deal with binary values (V low and V high ), but at higher levels, they work with numbers and tensors (vectors, matrices, 3D tensors, and beyond) and the mathematical relationships between them. To make text workable, we first split the sentence into tokens and then map each token to a unique numerical ID from the vocabulary. These token IDs are what the model actually processes. Finally, these IDs are transformed into dense vectors through a process called embedding, which allows the model to learn semantic and syntactic relationships between tokens during training. sentence = "This is Simple Transformer Guide!" ⇨ tokenized_sentence = [ 'This' , 'is' , 'Simple' , 'Transformer' , 'Guide' , '!' ] ⇨ sentence_of_tokenIDs = [ 73 , 4 , 871 , 1082 , 2374 , 91 ] Before embedding, we would like to structure the data in such a way that it is easy for the transformer to receive it, so we will define a fixed length to sentences (input sequence) max_length , and then we pad sentence that are shorter (This is the method in use here). Alternative method : use max length 95% of the data. meaning 95% of the data will fit with no problem and 5% will be truncated according to size (the percentage can be changed, for example 90%). This approach allows you to handle the majority of the data, while avoiding excessively long sequences. Sacrificing 10% of data integrity to make the model smaller and more efficient. In order to give the model contextual sign and mange the data better, we use special tokens special_tokens = ['<pad>', '<bos>', '<eos>', '<unk>'] <pad> - use for padding. <bos> - beginning of sentence. <eos> - end of sentence. <unk> - unknown words. We sets <unk> as the default. After sentence tokenization, we put before the sentence the beginning of sentence token, <bos> , and after it the end of sentence token, <eos> , and pad with padding token, <pad> , the remainder of the sentence up to max_length . The unknown word token , <unk> , use for words that are not in the vocabulary and dealing with failures, and for that reason we sets <unk> as the default. sentence_tokenized = [ 'This' , 'is' , 'Simple' , 'Transformer' , 'Guide' , '!' ] ⇨ sentence_for_embedding [ max_length ] = [ '<bos>' , 'This' , 'is' , 'Simple' , 'Transformer' , 'Guide' , '!' , '<eos>' , '<pad>' , ... , '<pad>' ] ⇨ tokenIDs_for_embedding [ max_length ] = [ 1 , 73 , 4 , 871 , 1082 , 2374 , 91 , 2 , 0 , ... , 0 ] Embedding Embeddings are representations of values or objects like text, images, and audio that are designed to be consumed by machine learning models and semantic search algorithms. Embeddings translate objects like these into a mathematical form according to the preset factors, enable machine learning models to interact with various data types. Word embedding [ 3 ] is a technique used in Natural Language Processing (NLP) to represent words as dense numerical vectors. These vectors capture semantic relationships between words based on their context in large text corpora. In our case we get a tokenized sequence (sentence, M=max_length ) and we convert every token to a vector in the $ℝ^{E}$ ( E=embedding_dim , for more information on Real Vector Space ) and we get for every sequence a matrix of size $ℝ^{M×E}$ . Intuitive understanding of Embedding This explanation is for intuitive understanding of Embedding. To best understand it, you will need a very basic vector analysis knowledge. Lets assume we have the tokens {'king', 'queen', 'man', 'woman'} and we convert them to embedding vectors: $\Big\{ e_{king}, e_{queen}, e_{man}, e_{woman} \Big\}$ . So for example we would expect a good embedding, the next mathematical semantic connection: $$e_{king} - e_{queen} = e_{man} - e_{woman}$$ From the tokens 'king' and 'queen' we can assume royalty and gender of every token. from the tokens 'man' and 'woman' we can assume only gender. So if we subtract 'man' and 'woman' we get a gender difference vector, as well with 'king' and 'queen', because when we subtract them the will subtract the royalty direction (vector) of each other. We can interpret it as the gender difference between the vectors, meaning in the $ℝ^{E}$ embedding space (Lets assume E is big), there is a direction of gender, the more manly attributes the token has the further the vector will go in that direction and the same for womanly attributes in the opposite direction. We can also look at this mathematical semantic connection: $$e_{king} - e_{man} = e_{queen} - e_{woman}$$ We can interpret it as if we strip the king from his gender then the vector that we get is the status/Royal vector as well as for the queen, meaning a royal direction. It also expected to get from the king vector to the queen vector we will use vector calculus and do: $$e_{king} - e_{man} + e_{woman} = e_{queen}$$ How Can $ℝ^{E}$ Holds Rich Language Semantics? In Reality that is not what exactly happening. There is no equality in the mathematical connection, probably because there is more for king part to gender and royalty, but a rough axis direction can be noticed. We can interpret, that for a some large vocabulary and $ℝ^{E}$ , large embedding space, there will be semantic direction in this space. We expect them to be orthogonal, so that an object in this space when getting shifted in the 'Royal' would do it with adding the 'Royal' vector (with scalar multiplication), and it would not be shifted in unrelated direction like 'Size', 'Metallic', 'Temperature' etc. Meaning larger the embedding space the more semantics it can hold. However, a $ℝ^{E}$ can hold only E orthogonal directions (vectors) and there are a lot of semantic in a language (in a large vocabulary). We would like the embedding space to hold relevant semantics as much as it can, however increasing E will result in space and computing cost. Nevertheless, we can see that not so large embedding spaces supply the semantics demand, and there is a hypothesis that tries to explain this phenomenon. According to Johnson–Lindenstrauss lemma if we "cram" more vectors in the space and ease the rigid demand of Orthogonality a little bit and allow a slight deviation, $0<ε<1$ . Meaning we can arrange the vectors, not in exactly 90° between each other, but in a range of $90°-ε \le ∡e_{i}e_{j} \le 90°+ε$ between them, each vector will have an angle of $[90°-ε , 90°+ε]$ with all other vectors. Then the lemma tells us we can arrange $D$ vectors in $ℝ^{E}$ , when $D$ ≈ $O\big( exp(E·ε^2) \big)$ . For example in $ℝ^{100}$ we can arrange ~exp(100· $0.9^2$ ) ≈ $1.5·10^{35}$ vectors/directions/semantics and that is a lot of semantics! ⚙️ Training and Optimization Adam Optimizer Adam is an adaptive optimization algorithm that combines momentum with per-parameter learning-rate scaling based on the first and second moments of the gradients. This generally provides stable and efficient optimization for deep neural networks. For parameter $\theta$ , Adam maintains moving averages of the gradient and squared gradient: $$ m_t = \beta_1 m_{t-1} + (1-\beta_1)g_t \qquad v_t = \beta_2 v_{t-1} + (1-\beta_2)g_t^2 $$ After bias correction, the parameters are updated using these estimates. In this project, weight decay is also applied as a regularization method to reduce overfitting. Noam Learning Rate NoamLR scheduler was introduced in the original Transformer paper "Attention Is All You Need". Schedulers in deep learning are used to adjust the learning rate during training to improve convergence and performance. It sets the learning rate to increase linearly for a set number of warm-up steps and then decay proportionally to the inverse square root of the training step: $$ lr=d_{model}^{−0.5}×\hspace{0.5em}min\bigg(Step^{−0.5},\hspace{0.1em}Step\hspace{0.3em}×\hspace{0.3em}Warmup^{−1.5}\bigg) $$ Where: $lr$ is the next learning rate. $d_{model}$ is the model dimension (embedding dimension). $Warmup$ is predefined hyperparameter. $Step$ is optimizer current step. This approach helps stabilize training in the early stages and allows the model to learn efficiently by avoiding large or unstable updates initially, while gradually reducing the learning rate to fine-tune the model later in training. Cross Entropy Loss Function The Cross Entropy Loss Function is widely used for classification tasks, as it measures the difference between the predicted probability distribution and the true distribution. Given a predicted probability vector $\hat{y}$ and a one-hot encoded target vector $y$ , the loss for a single example is defined as: $$ \mathcal{L}_{CE} = - \sum_{i} y_i \log \hat{y}_i $$ This loss penalizes confident incorrect predictions more heavily than less certain ones, encouraging the model to assign higher probabilities to the correct classes. Minimizing cross-entropy effectively maximizes the likelihood of the correct labels under the model’s predicted distribution. Teacher forcing Teacher Forcing [ 4 ] is a training strategy used in sequence-to-sequence (seq2seq) models, especially in tasks like machine translation, text generation, and speech recognition. During training, the model is fed the actual ground truth output from the previous time step instead of its own predicted output. This helps the model learn faster and improves convergence. During inference, it must generate each token from its own previous outputs, which can lead to cascading errors if one prediction is wrong — that's exposure bias. Given an input: This is Simple Transformer Guide! and a target: Ceci est un guide simple du Transformer! , every iteration we will feed input from target: Mistake at one step can lead to poor outputs later — exposure bias. Padding Mask A padding mask in Transformers is a binary mask used to prevent the model from attending to tokens that were added to sequences to make them the same length in a batch. Without masking, the attention mechanism would treat these padding positions as valid input, potentially introducing meaningless information into the context. In practice, the padding mask has 0 (or False) where real tokens are and 1 (or True) where padding occurs, and it is applied before the softmax in the attention score computation by adding large negative values ( float('-inf') ) to the padded positions. This ensures the model focuses only on actual tokens when computing attention, improving both training stability and output quality. Beam Search Beam Search [ 4 ] is a decoding algorithm used to generate the most likely output sequence by keeping multiple hypotheses (beams) at each step, instead of just the best one (like greedy decoding). This decoding strategy balances exploration and exploitation by keeping track of the top-k most likely partial sequences (beams) at each decoding step, rather than committing to the single most likely token as in greedy decoding. In greedy decoding, you pick the highest-probability token at each step, which is fast but can lead to suboptimal results because early mistakes cannot be corrected. Beam search instead expands all possible next tokens for each current beam, scores them (often using log-probabilities), and keeps only the best k sequences, allowing it to explore multiple promising paths in parallel. This often produces higher-quality translations or generations than greedy decoding, especially in Transformers, where the self-attention mechanism captures long-range dependencies that beam search can exploit to avoid short, repetitive, or incoherent outputs. However, beam search is slower than greedy decoding and can sometimes favor overly safe, generic sequences unless combined with techniques like length normalization or diverse beam search. Length Normalization Length normalization is a technique used in sequence generation (including Transformer decoding with beam search) to counteract the bias toward shorter outputs that arises when summing log-probabilities of tokens—since probabilities are less than 1, longer sequences naturally accumulate lower scores. Without normalization, the decoder might prefer prematurely ending the sequence with an token. Length normalization adjusts the total log-probability by dividing it by a function of the sequence length, like in this project, where the effective sequence length is first computed as the position of the first token (or the full length if is absent) and then passed through a penalty formula $\Big(\frac{(5+L)}{6}\Big)^α$ , where L is the effective length and α controls the penalty strength. This ensures that beam search compares candidate sequences more fairly, allowing well-formed longer outputs to compete with shorter ones without being unfairly penalized by raw probability sums. In beam search (or any sequence decoding), the log-probability of a candidate sequence is calculated by summing the log-probabilities of the tokens in that sequence: $$\log P(y_{1:T} \mid x) = \sum_{t=1}^T \log P(y_t \mid y_{1:t-1}, x)$$ where: $y_{1:T}$ is the output sequence of length T. $x$ is the input (e.g., source sentence). $P(y_{t}∣_{y1:t−1},x)$ is the model’s predicted probability of token ytyt given the previous tokens and input. In beam search with length normalization (like in your project), the score for each beam is: $$\text{score}(y_{1:T}) = \frac{\sum_{t=1}^T \log P\left(y_t \mid y_{1:t-1}, x\right)} {\text{length\_penalty}(T)}$$ where the $\text{length\_penalty}(T)$ is $\Big(\frac{(5+L)}{6}\Big)^α$ , as described above. This means beam search ranks sequences by their average (length-adjusted) log-probability rather than just raw probability sums, avoiding the bias toward short outputs. The embedding layers are initialized with scaled normal distribution. Embedding normal distribution initialization means initializing embedding vectors by sampling each element from a normal (Gaussian) distribution with a small standard deviation (e.g., mean 0, std 0.01). This gives embeddings small random values before training begins, ensuring no initial bias toward any specific token. 📚 References [1] Attention Is All You Need [2] Adam: A Method for Stochastic Optimization [3] Efficient Estimation of Word Representations in Vector Space [4] Sequence to Sequence Learning with Neural Networks
Model Figures & Evaluation Curves (4 Images)
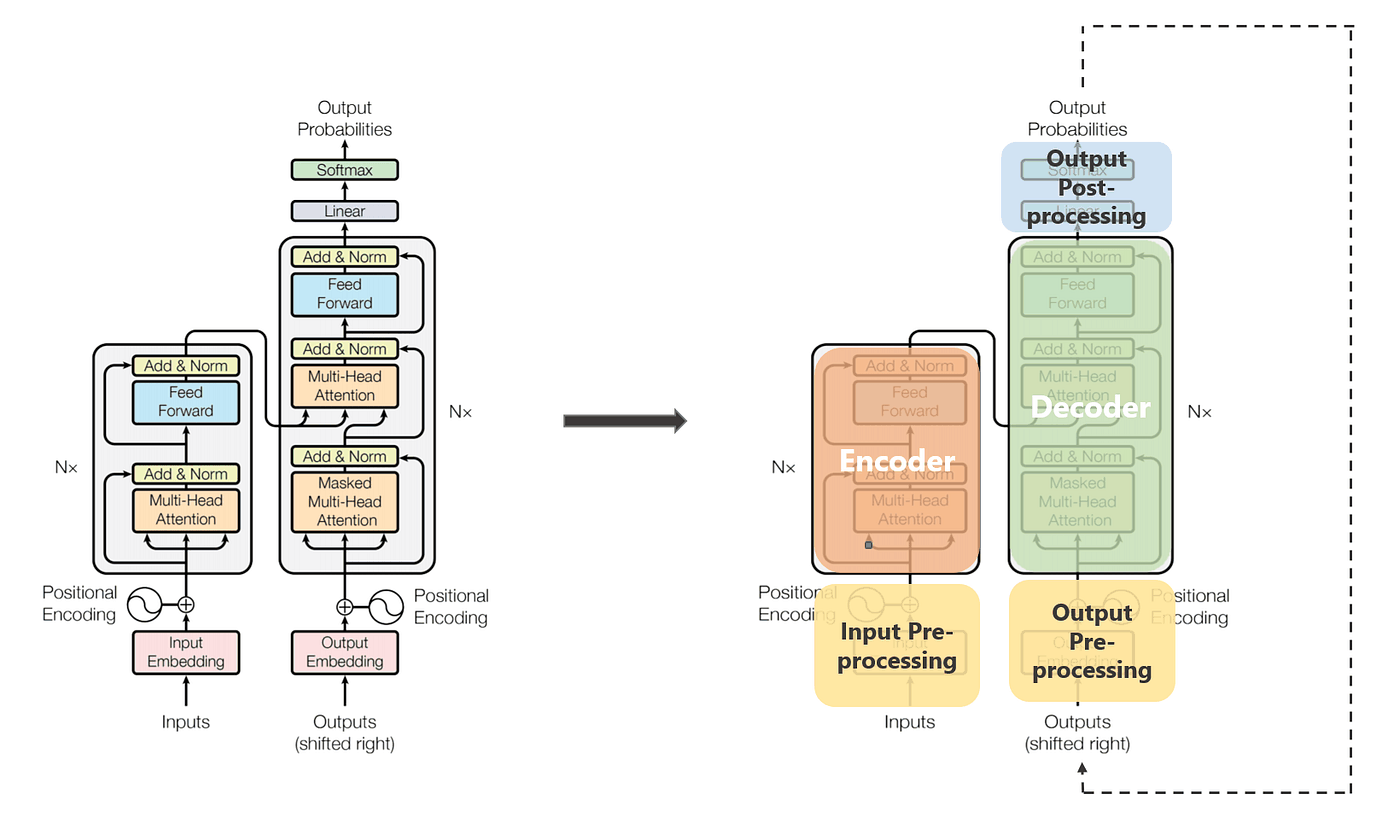
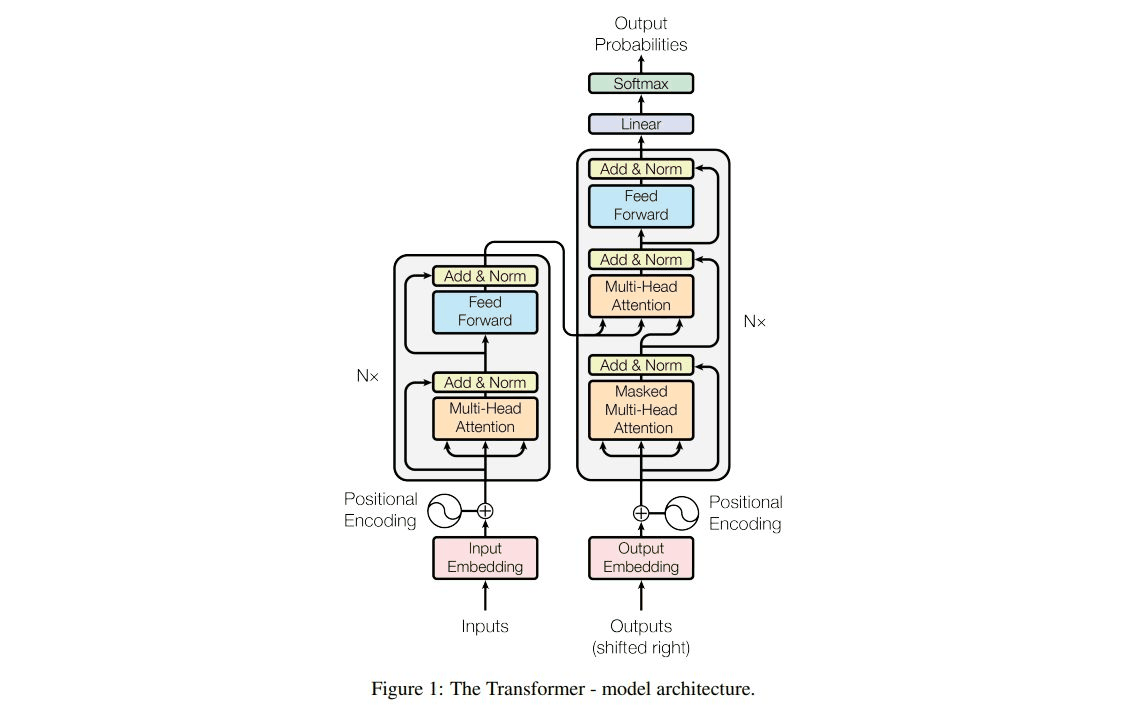
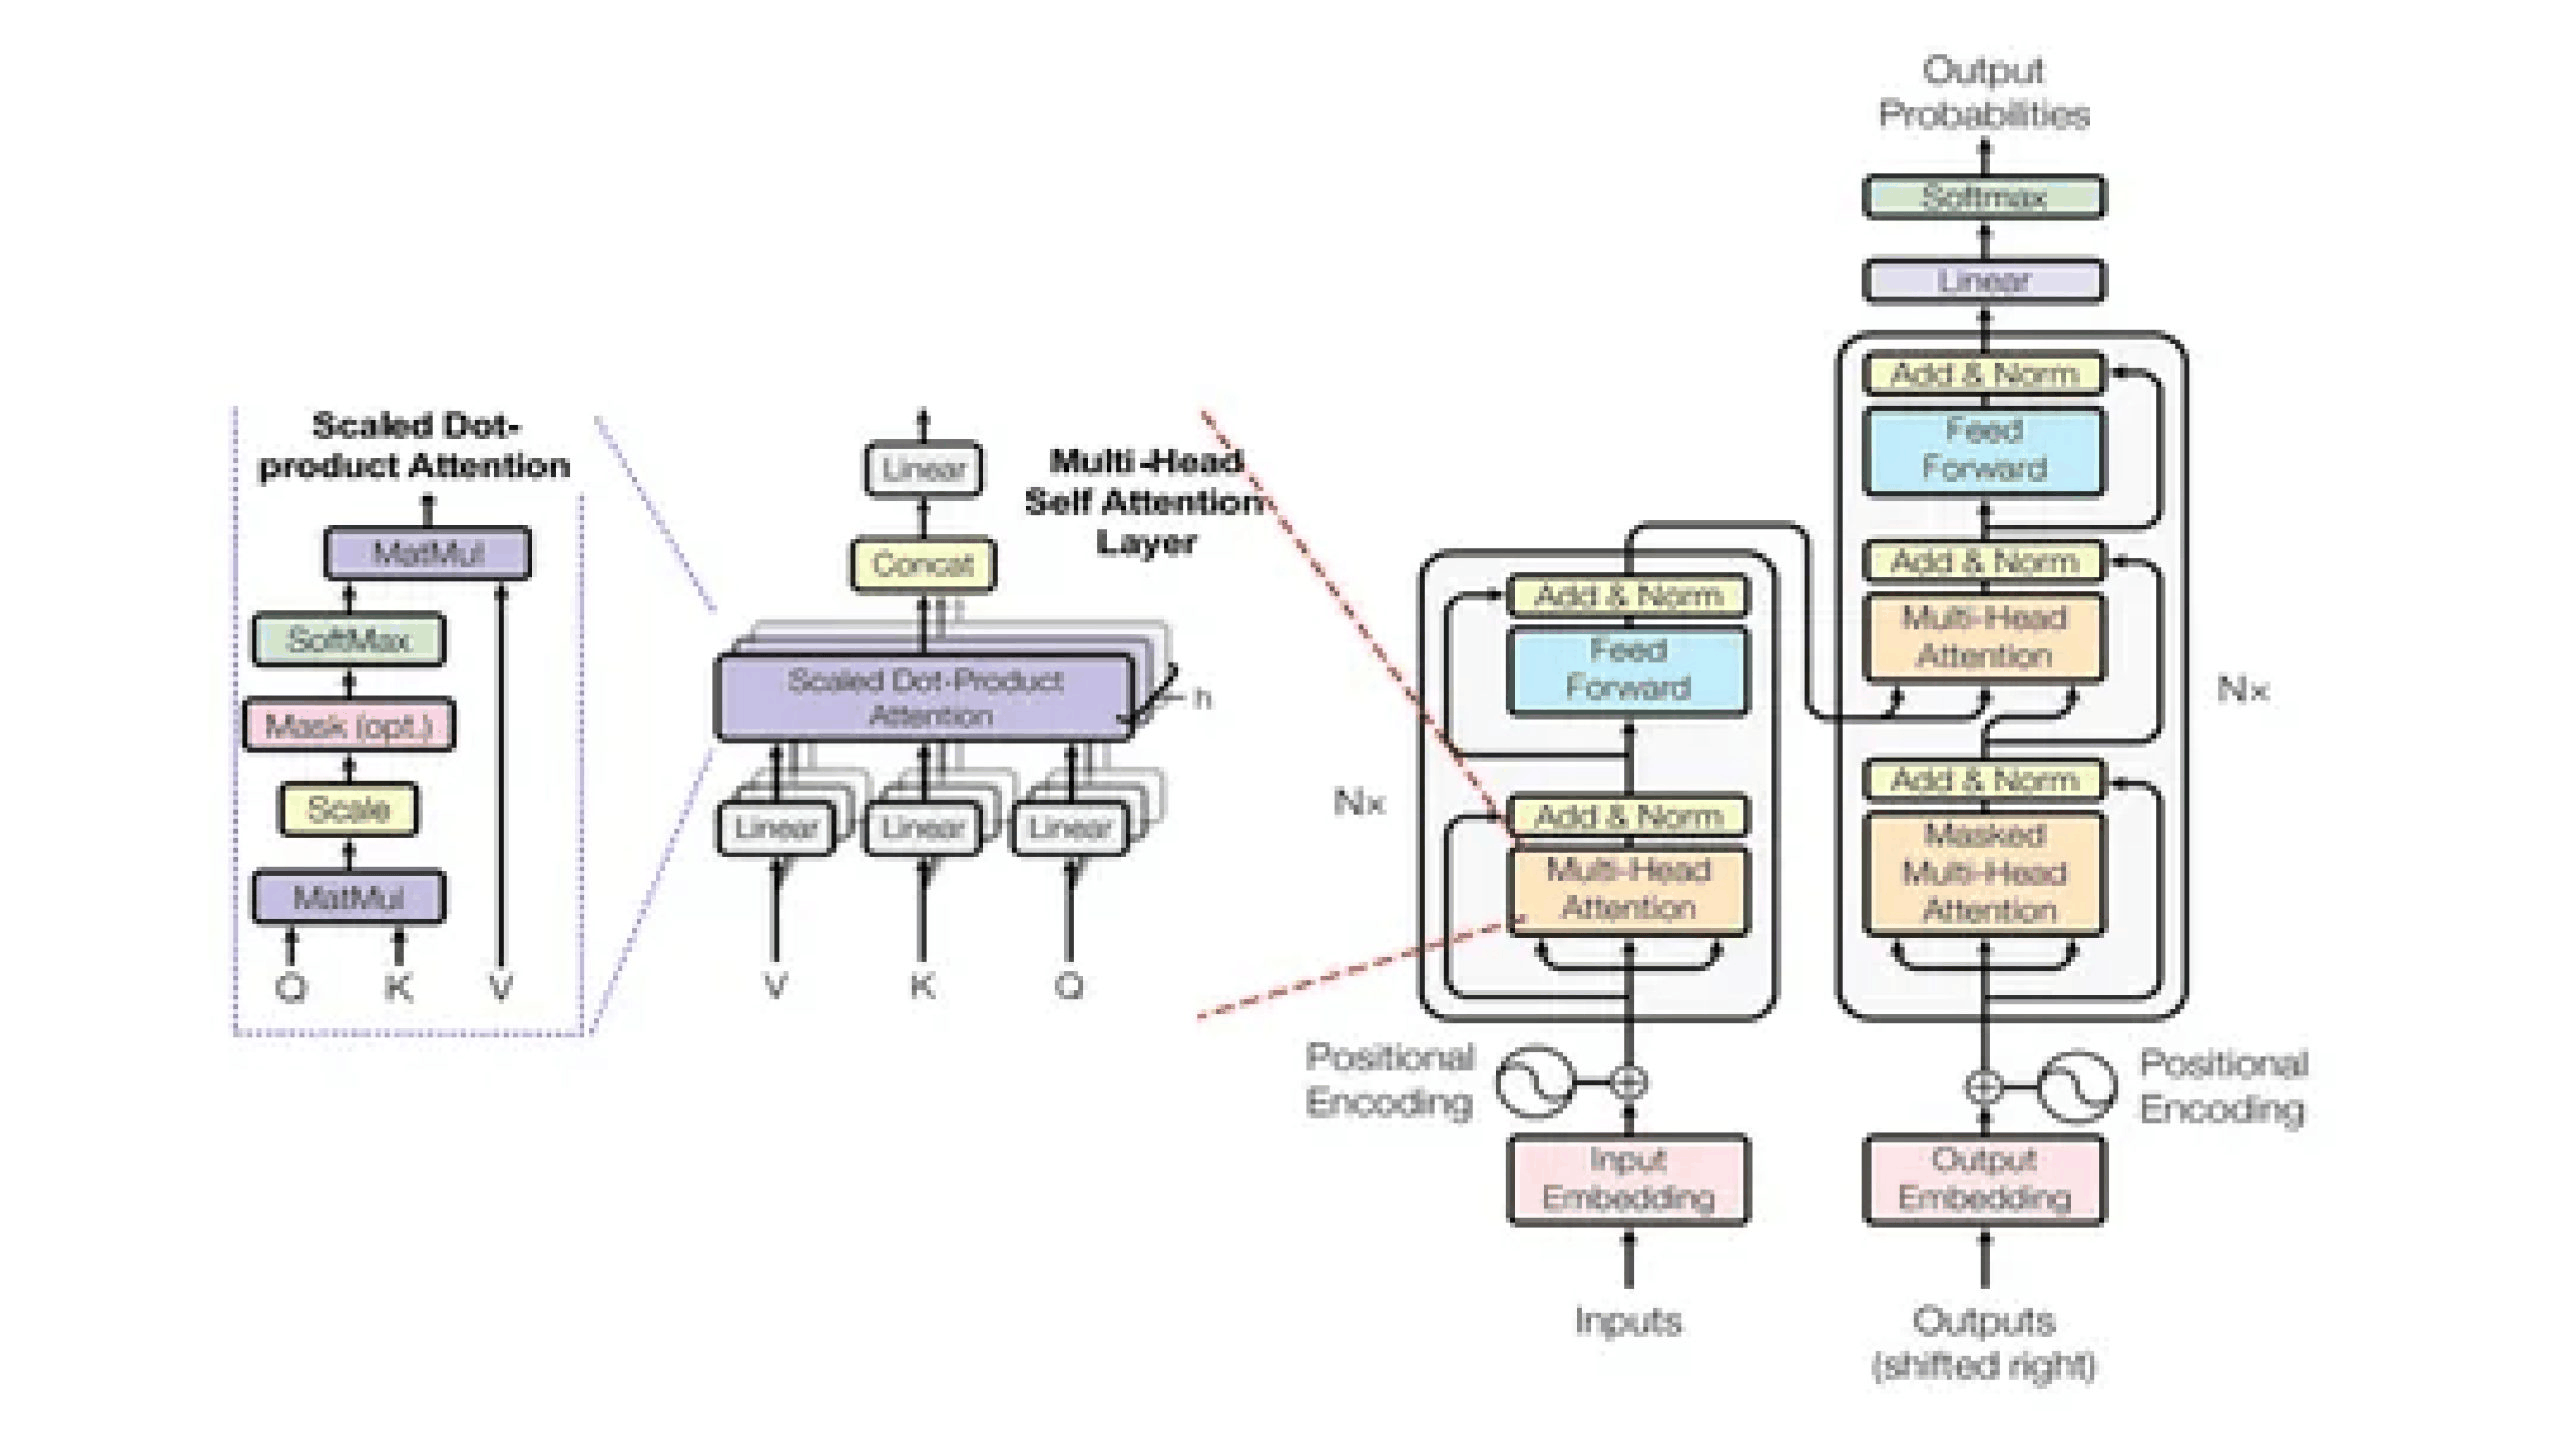
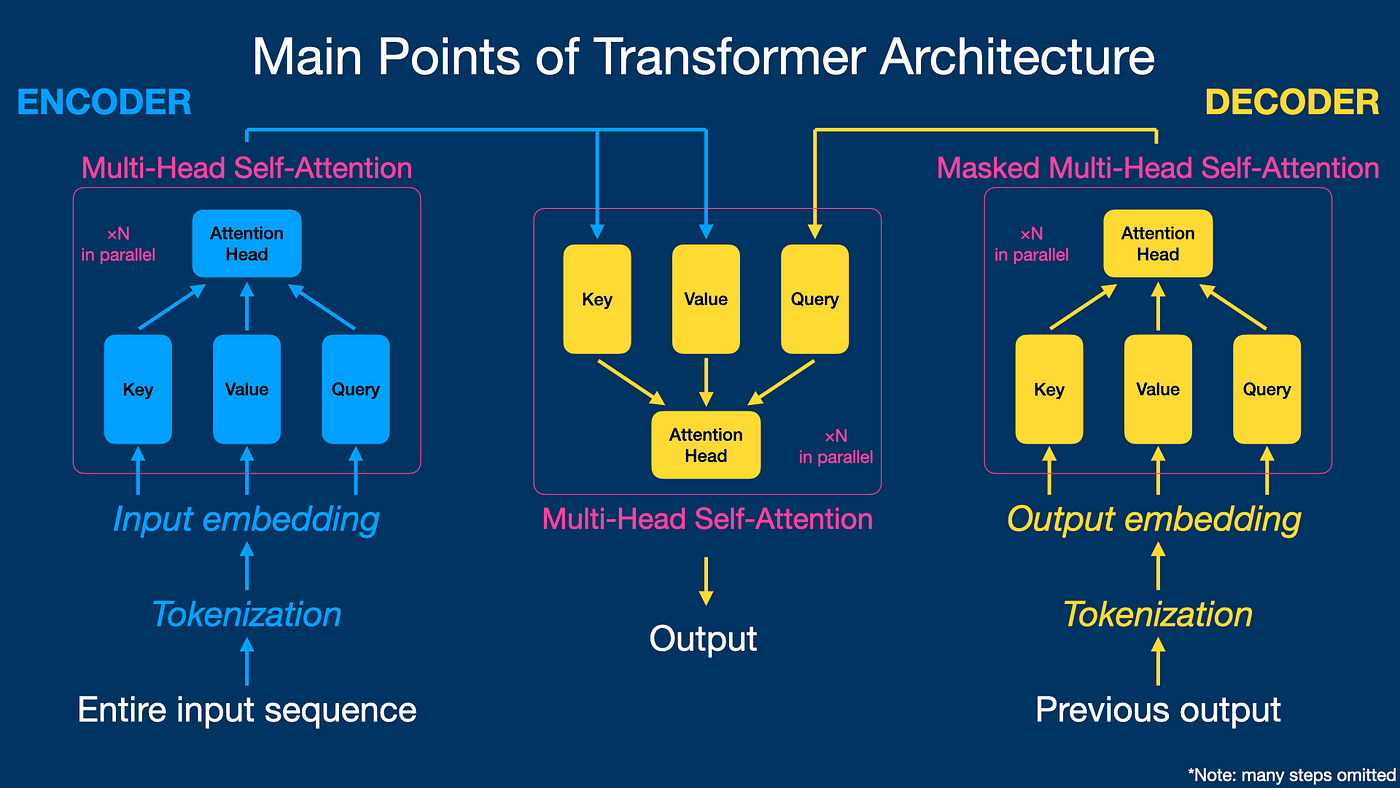
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)