Complete Technical Paper Content — Vertical Federated Learning
1. Executive Abstract, Problem Formulation & Background
Federated learning (also known as collaborative learning) is a machine learning technique in a setting where multiple entities (often called clients) collaboratively train a model while keeping their data decentralized, rather than centrally stored. A defining characteristic of federated learning is data heterogeneity. Because client data is decentralized, data samples held by each client may not be independently and identically distributed. Federated learning is generally concerned with and motivated by issues such as data privacy, data minimization, and data access rights. Its applications involve a variety of research areas including defence, telecommunications, the Internet of things, and pharmaceuticals.
f ( x 1 , … , x K ) = 1 K ∑ i = 1 K f i ( x i ) {\displaystyle f(\mathbf {x} _{1},\dots ,\mathbf {x} _{K})={\dfrac {1}{K}}\sum _{i=1}^{K}f_{i}(\mathbf {x} _{i})}
where K {\displaystyle K} is the number of nodes, x i {\displaystyle \mathbf {x} _{i}} are the weights of model as viewed by node i {\displaystyle i} , and f i {\displaystyle f_{i}} is node i {\displaystyle i} 's local objective function, which describes how model weights x i {\displaystyle \mathbf {x} _{i}} conforms to node i {\displaystyle i} 's local dataset. The goal of federated learning is to train a common model on all of the nodes' local datasets, in other words:
2. Related Work, Literature Survey & Algorithmic Foundations
Optimizing the objective function f ( x 1 , … , x K ) {\displaystyle f(\mathbf {x} _{1},\dots ,\mathbf {x} _{K})} . Achieving consensus on x i {\displaystyle \mathbf {x} _{i}} . In other words, x 1 , … , x K {\displaystyle \mathbf {x} _{1},\dots ,\mathbf {x} _{K}} converge to some common x {\displaystyle \mathbf {x} } at the end of the training process.
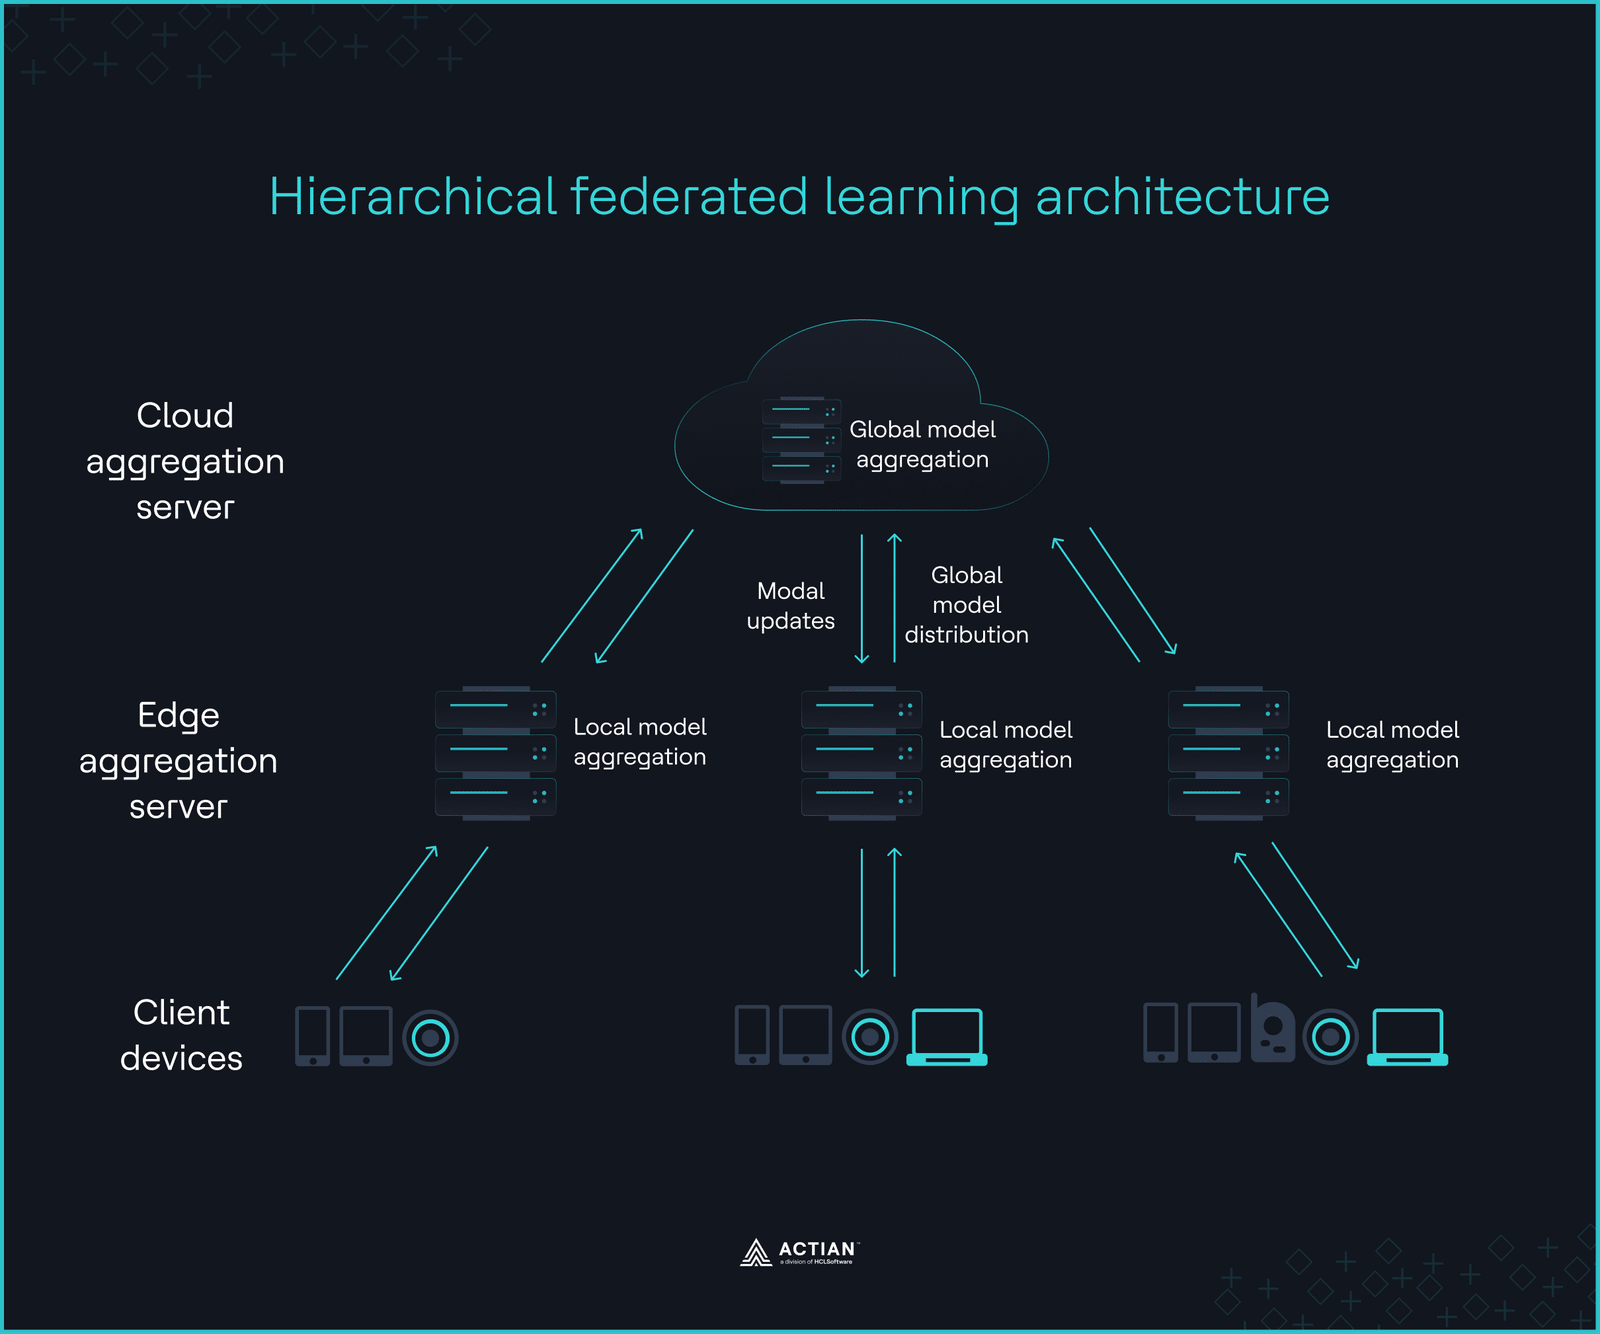
Initialization: according to the server inputs, a machine learning model (e.g., linear regression, neural network, boosting) is chosen to be trained on local nodes and initialized. Then, nodes are activated and wait for the central server to give the calculation tasks. Client selection: a fraction of local nodes are selected to start training on local data. The selected nodes acquire the current statistical model while the others wait for the next federated round. Configuration: the central server orders selected nodes to undergo training of the model on their local data in a pre-specified fashion (e.g., for some mini-batch updates of gradient descent). Reporting: each selected node sends its local model to the server for aggregation. The central server aggregates the received models and sends back the model updates to the nodes. It also handles failures for disconnected nodes or lost model updates. The next federated round is started returning to the client selection phase. Termination: once a pre-defined termination criterion is met (e.g., a maximum number of iterations is reached or the model accuracy is greater than a threshold) the central server aggregates the updates and finalizes the global model. The procedure considered before assumes synchronized model updates. Recent federated learning developments introduced novel techniques to tackle asynchronicity during the training process, or training with dynamically varying models. Compared to synchronous approaches where local models are exchanged once the computations have been performed for all layers of the neural network, asynchronous ones leverage the properties of neural networks to exchange model updates as soon as the computations of a certain layer are available. These techniques are also commonly referred to as split learning and they can be applied both at training and inference time regardless of centralized or decentralized federated learning settings.
Covariate shift: local nodes may store examples that have different statistical distributions compared to other nodes. An example occurs in natural language processing datasets where people typically write the same digits/letters with different stroke widths or slants. Prior probability shift: local nodes may store labels that have different statistical distributions compared to other nodes. This can happen if datasets are regional and/or demographically partitioned. For example, datasets containing images of animals vary significantly from country to country. Concept drift (same label, different features): local nodes may share the same labels but some of them correspond to different features at different local nodes. For example, images that depict a particular object can vary according to the weather condition in which they were captured. Concept shift (same features, different labels): local nodes may share the same features but some of them correspond to different labels at different local nodes. For example, in natural language processing, the sentiment analysis may yield different sentiments even if the same text is observed. Unbalanced: the amount of data available at the local nodes may vary significantly in size. The loss in accuracy due to non-iid data can be bounded through using more sophisticated means of doing data normalization, rather than batch normalization.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Number of federated learning rounds: T {\displaystyle T}
Total number of nodes used in the process: K {\displaystyle K}
Fraction of nodes used at each iteration for each node: C {\displaystyle C}
4. Neural Network Backbone, Layer Specifications & Loss Formulations
Local batch size used at each learning iteration: B {\displaystyle B}
Number of iterations for local training before pooling: N {\displaystyle N}
Those parameters have to be optimized depending on the constraints of the machine learning application (e.g., available computing power, available memory, bandwidth). For instance, stochastically choosing a limited fraction C {\displaystyle C} of nodes for each iteration diminishes computing cost and may prevent overfitting, in the same way that stochastic gradient descent can reduce overfitting.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
Heterogeneity between the different local datasets: each node may have some bias with respect to the general population, and the size of the datasets may vary significantly; Temporal heterogeneity: each local dataset's distribution may vary with time; Interoperability of each node's dataset is a prerequisite; Each node's dataset may require regular curations; Hiding training data might allow attackers to inject backdoors into the global model; Lack of access to global training data makes it harder to identify unwanted biases entering the training e.g. age, gender, sexual orientation; Partial or total loss of model updates due to node failures affecting the global model; Lack of annotations or labels on the client side. Heterogeneity between processing platforms
A further governance-related issue concerns the distribution of value among participants as multi-party federated learning systems scale. As more clients contribute to training, model accuracy may approach a performance threshold, after which additional contributions yield diminishing marginal utility. This dynamic can create tensions within collaborative arrangements, as early participants may perceive later contributions as offering reduced value while still benefiting from the shared model. Such asymmetries may affect incentives to join or remain in a consortium and complicate the design of fair participation, ownership, or reward structures. Establishing transparent rules for contribution assessment and benefit allocation is therefore an important organisational challenge and represents a direction for future research.
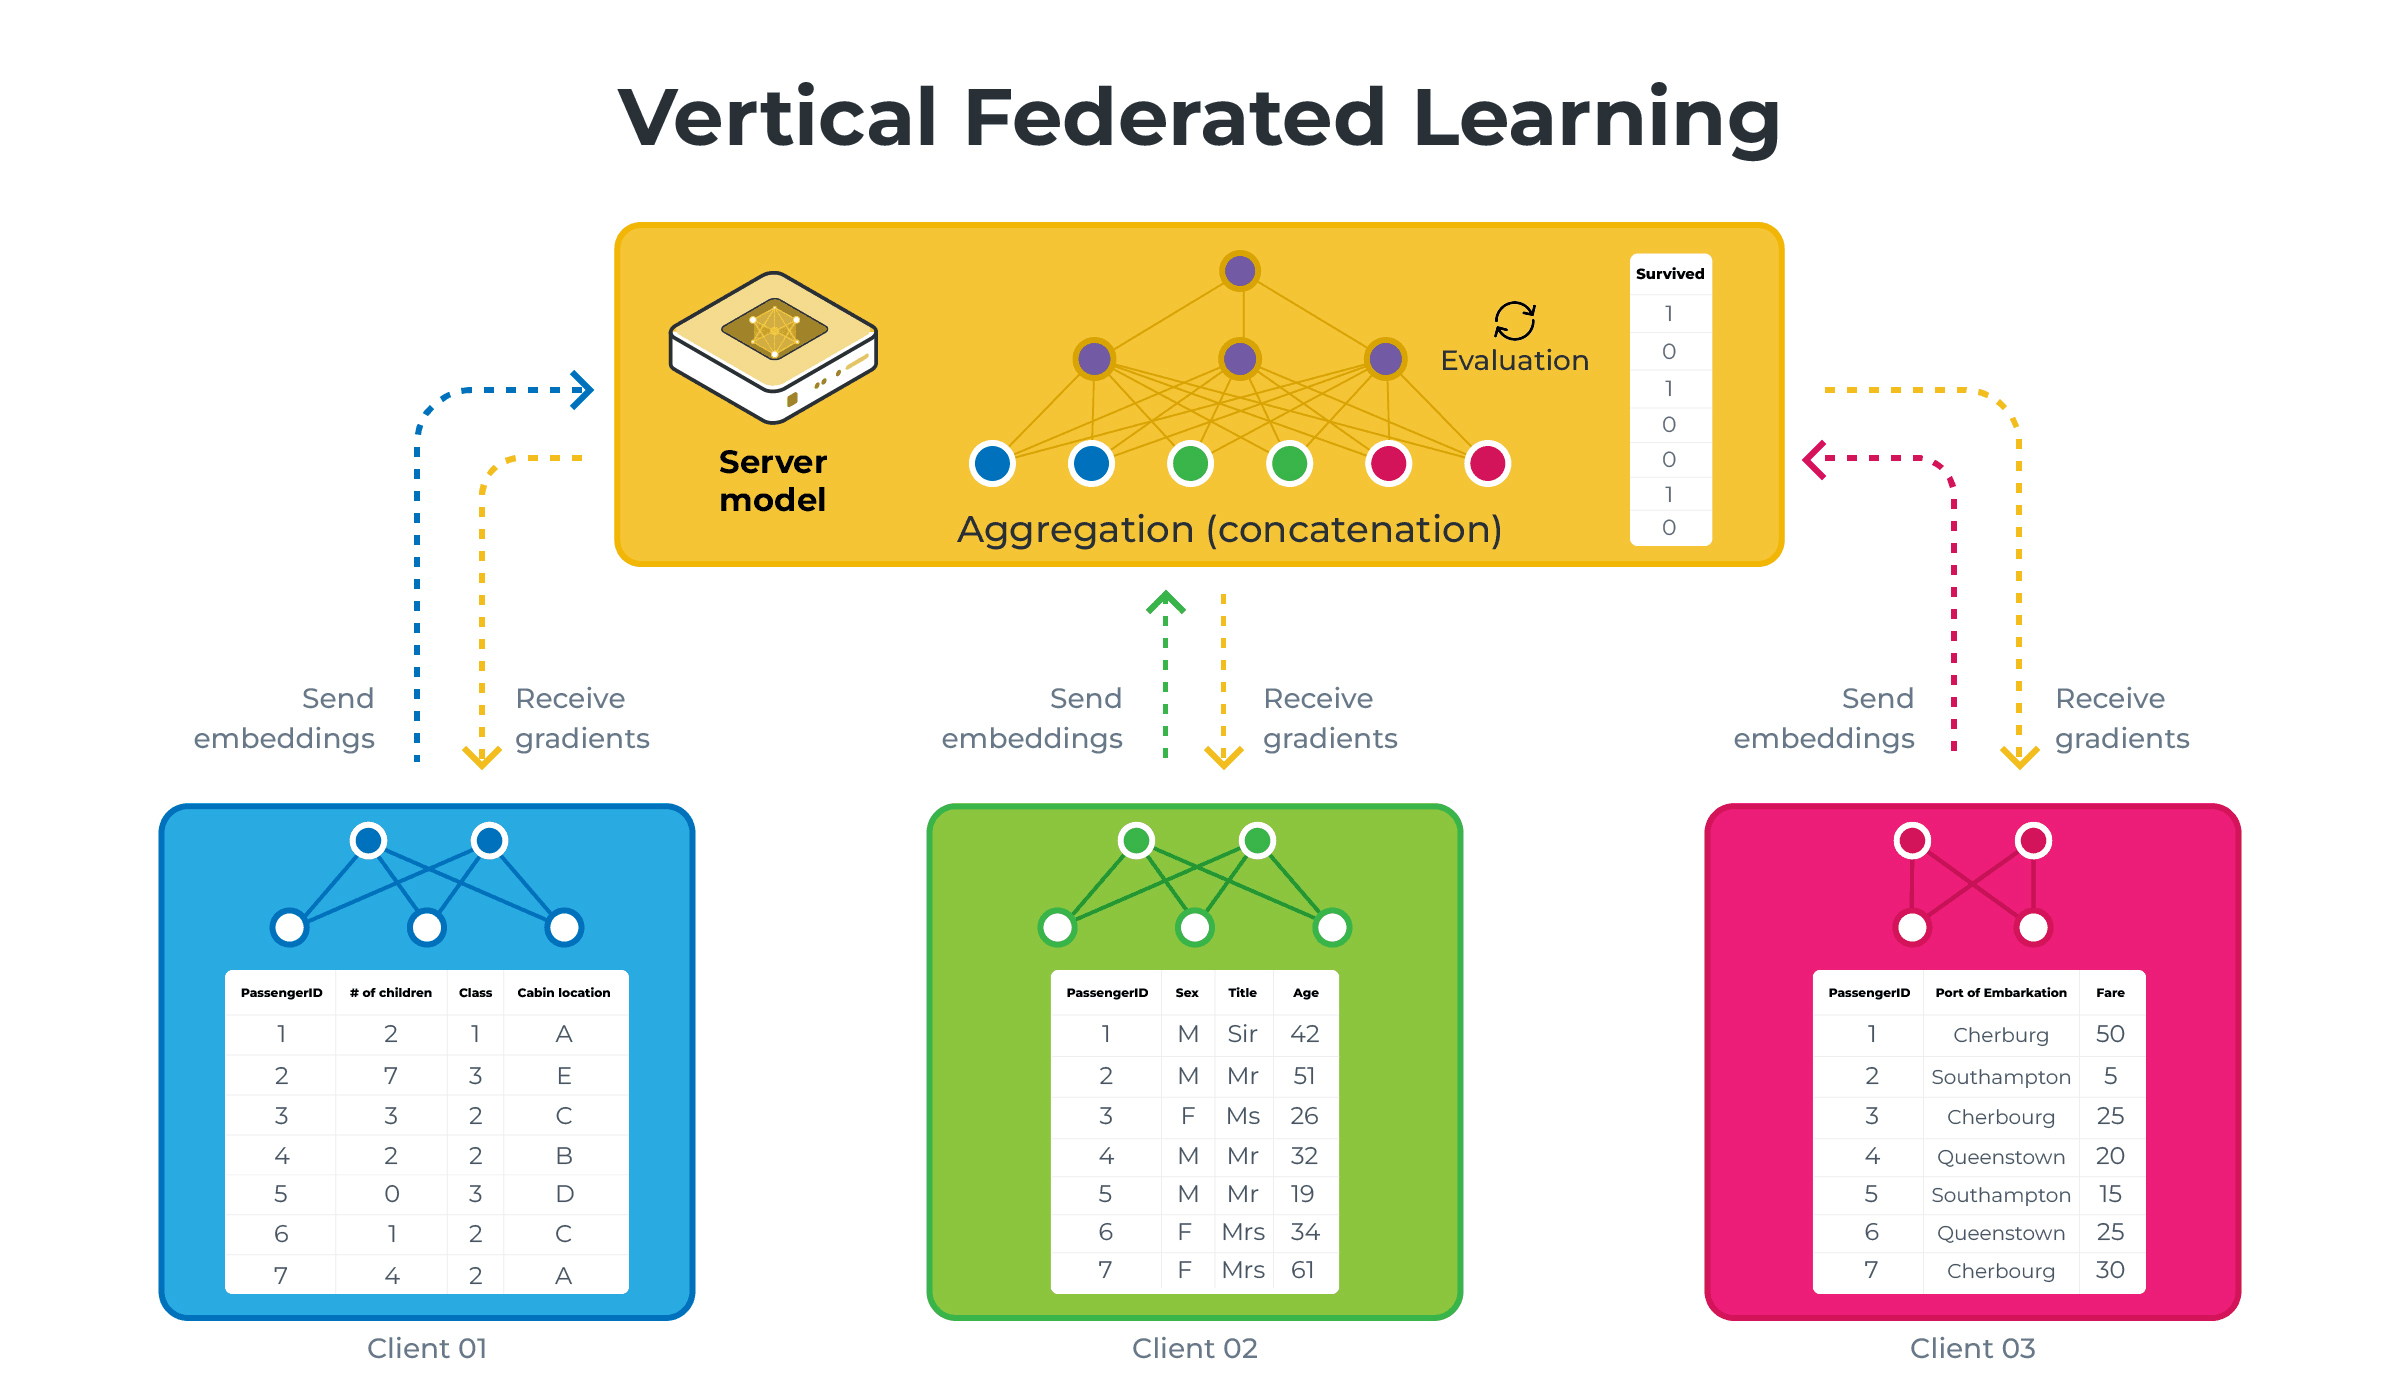
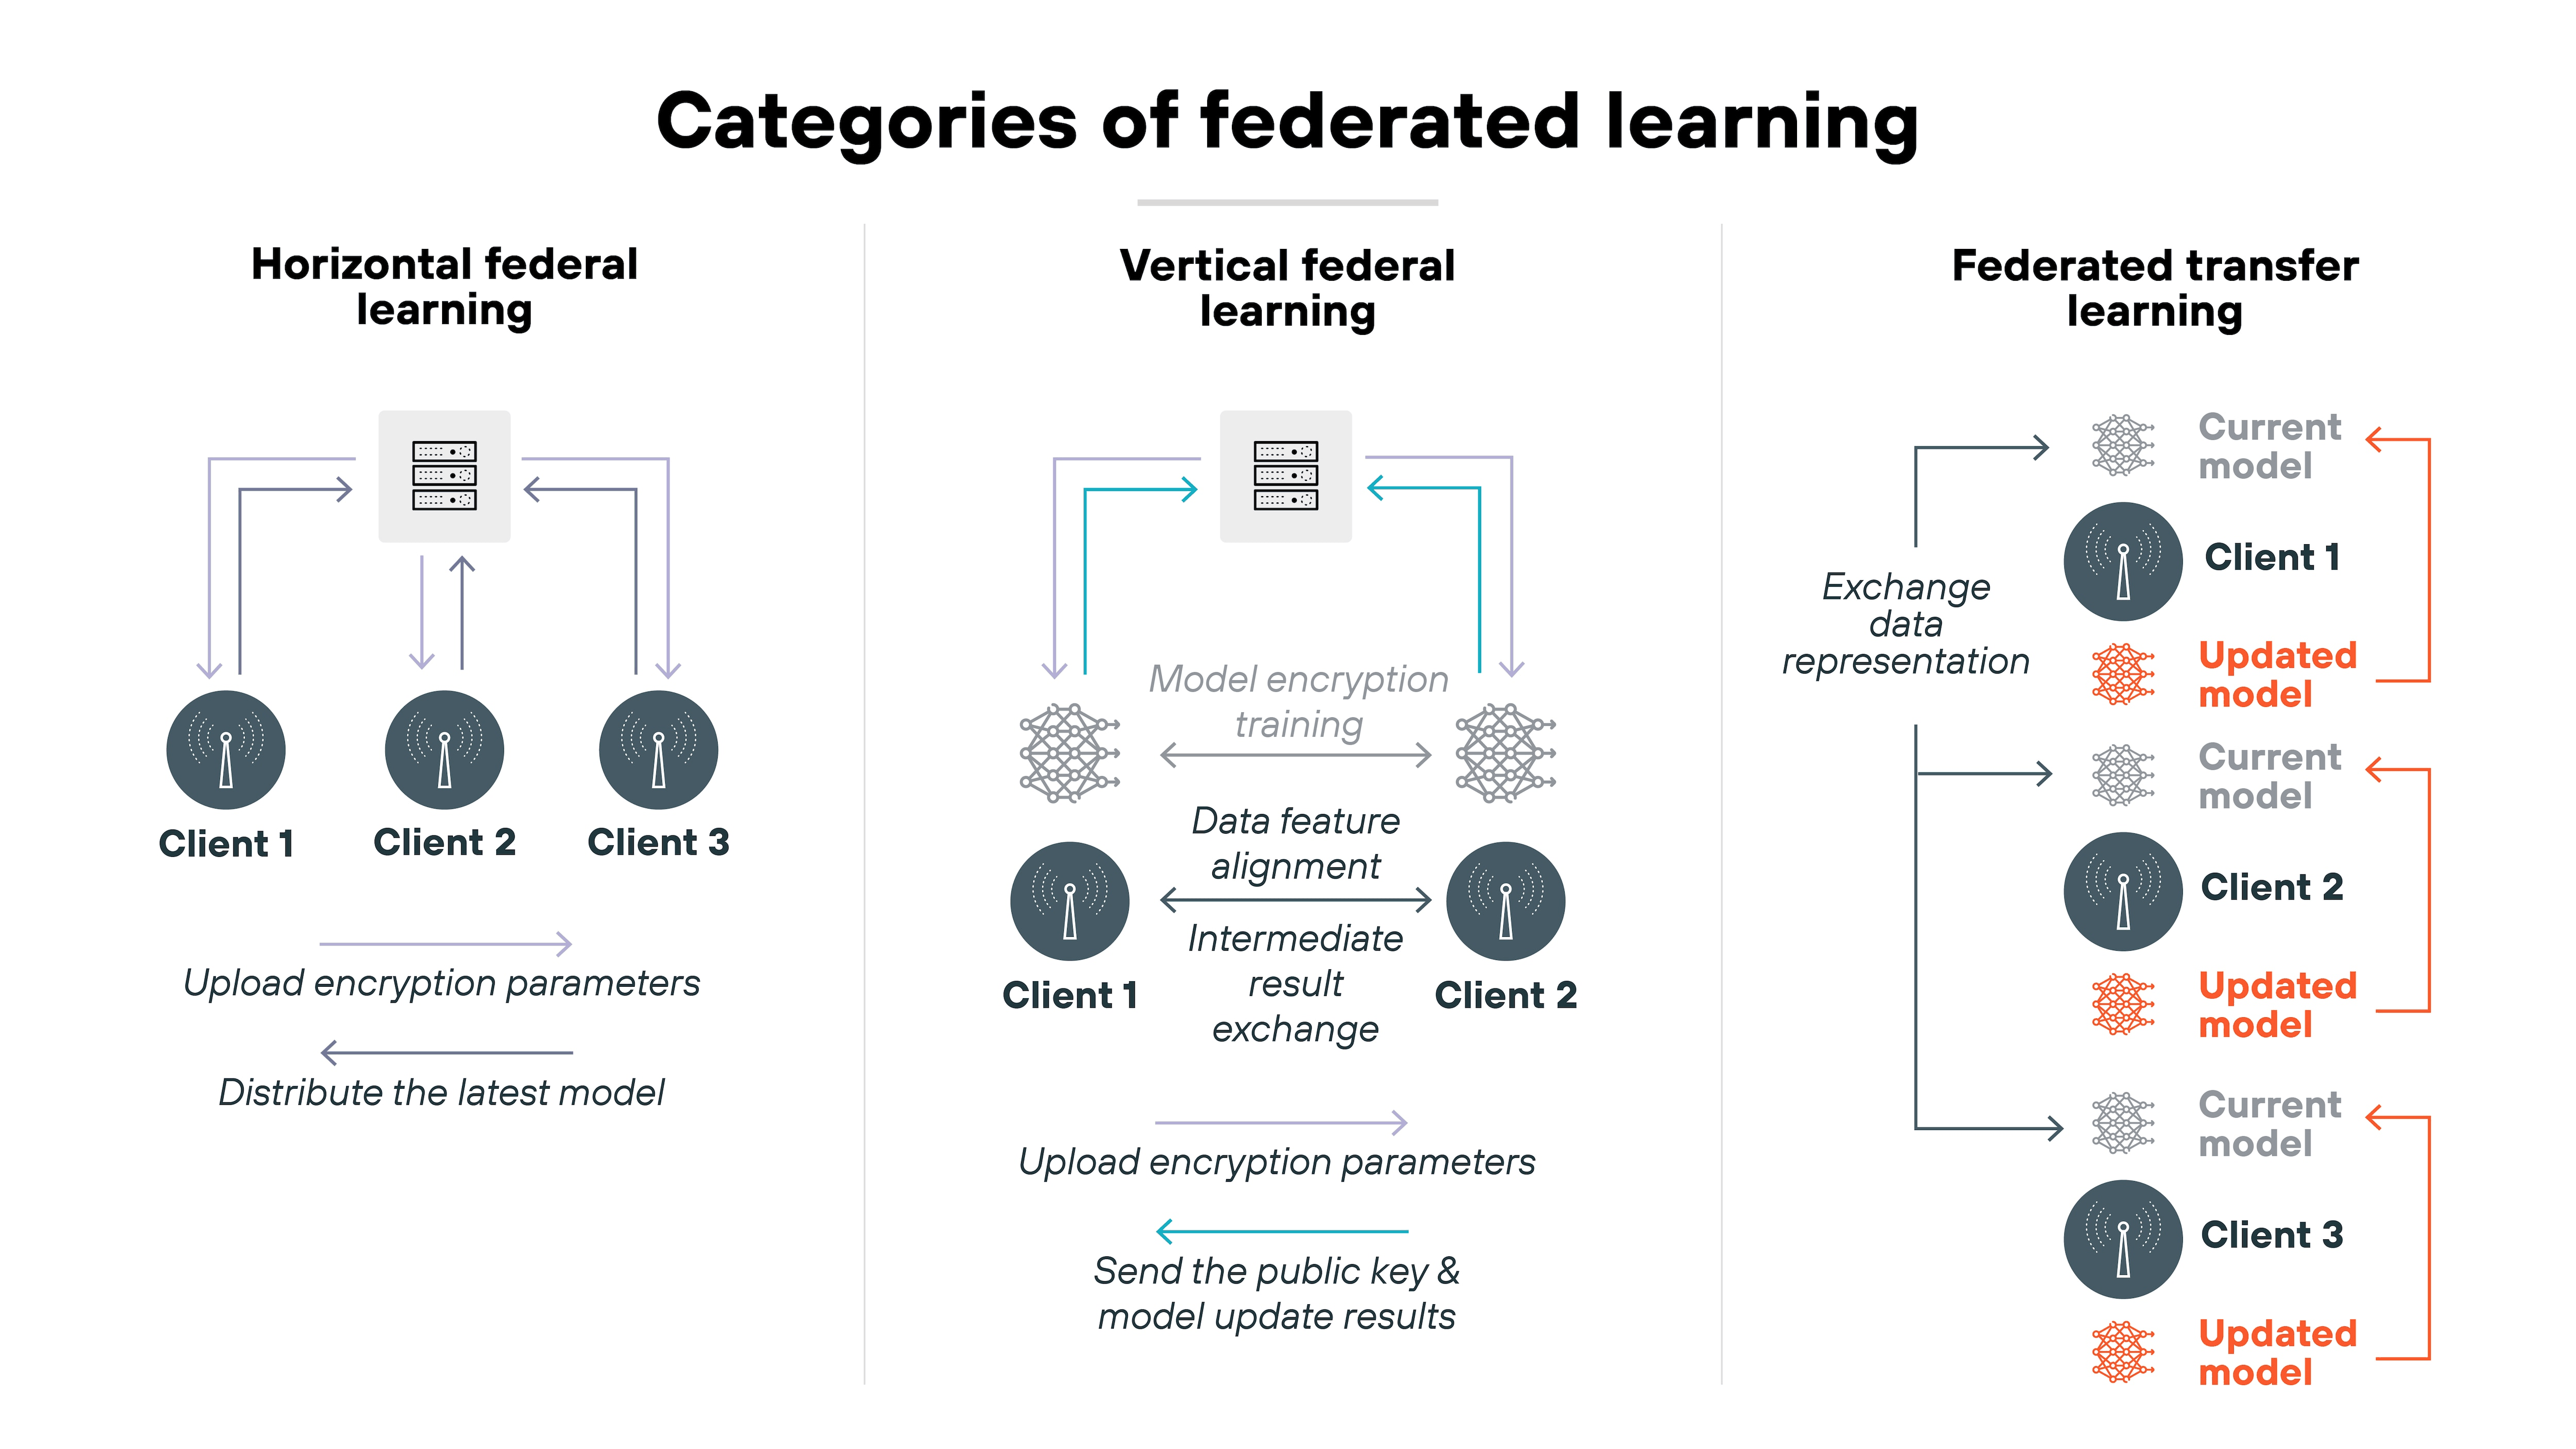
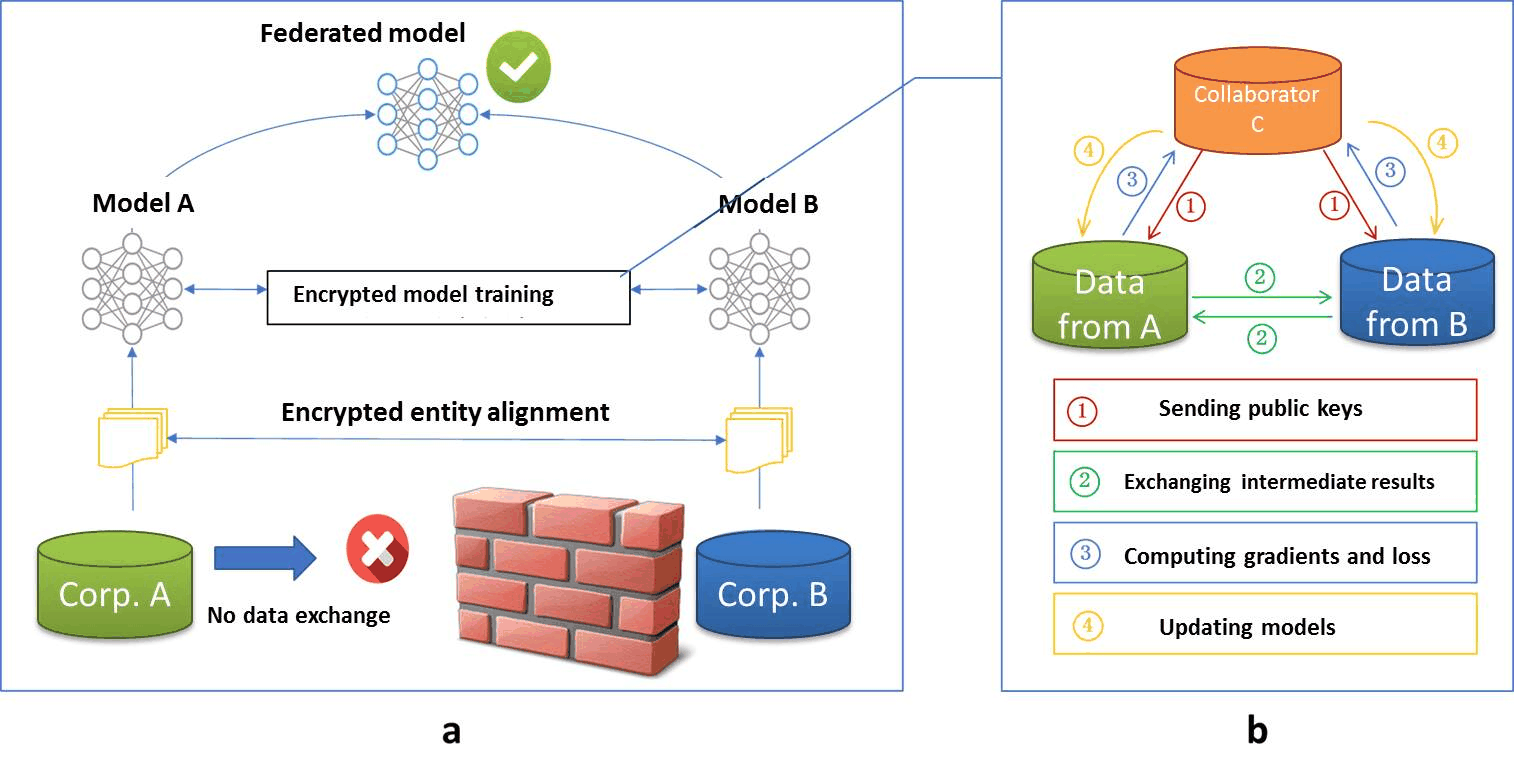
HyFDCA is a provably convergent primal-dual algorithm for hybrid FL in at least the following settings. Hybrid Federated Setting with Complete Client Participation Horizontal Federated Setting with Random Subsets of Available Clients The authors show HyFDCA enjoys a convergence rate of O(1⁄t) which matches the convergence rate of FedAvg (see below). Vertical Federated Setting with Incomplete Client Participation The authors show HyFDCA enjoys a convergence rate of O(log(t)⁄t) whereas FedBCD exhibits a slower O(1⁄sqrt(t)) convergence rate and requires full client participation. HyFDCA provides the privacy steps that ensure privacy of client data in the primal-dual setting. These principles apply to future efforts in developing primal-dual algorithms for FL. HyFDCA empirically outperforms HyFEM and FedAvg in loss function value and validation accuracy across a multitude of problem settings and datasets (see below for more details). The authors also introduce a hyperparameter selection framework for FL with competing metrics using ideas from multiobjective optimization. There is only one other algorithm that focuses on hybrid FL, HyFEM proposed by Zhang et al. (2020). This algorithm uses a feature matching formulation that balances clients building accurate local models and the server learning an accurate global model. This requires a matching regularizer constant that must be tuned based on user goals and results in disparate local and global models. Furthermore, the convergence results provided for HyFEM only prove convergence of the matching formulation not of the original global problem. This work is substantially different from HyFDCA's approach which uses data on local clients to build a global model that converges to the same solution as if the model was trained centrally. Furthermore, the local and global models are synchronized and do not require the adjustment of a matching parameter between local and global models. However, HyFEM is suitable for a vast array of architectures including deep learning architectures, whereas HyFDCA is designed for convex problems like logistic regression and support vector machines. HyFDCA is empirically benchmarked against the aforementioned HyFEM as well as the popular FedAvg in solving convex problem (specifically classification problems) for several popular datasets (MNIST, Covtype, and News20). The authors found HyFDCA converges to a lower loss value and higher validation accuracy in less overall time in 33 of 36 comparisons examined and 36 of 36 comparisons examined with respect to the number of outer iterations. Lastly, HyFDCA only requires tuning of one hyperparameter, the number of inner iterations, as opposed to FedAvg (which requires tuning three) or HyFEM (which requires tuning four). In addition to FedAvg and HyFEM being quite difficult to optimize hyperparameters in turn greatly affecting convergence, HyFDCA's single hyperparameter allows for simpler practical implementations and hyperparameter selection methodologies.
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)