Complete Technical Paper Content — Wildlife Detection Ai
1. Executive Abstract, Problem Formulation & Background
Technologies in wildlife conservation are technical tools and scientific systems used to support the protection, monitoring, and management of wild species and their habitats. These technologies are used to address species declines, habitat loss, conflicts between humans and wildlife, and unlawful exploitation of wildlife in both terrestrial and aquatic environments. Over time, advances in scientific equipment and data analysis have enabled conservation practitioners to gather information with higher accuracy and with less direct disturbance to animals than traditional methods. A variety of modern tools are used in wildlife conservation, including remote sensing systems, devices that track animal movements, automated camera systems, drones or unmanned aerial vehicles (UAVs), methods that detect environmental DNA (eDNA), geographic information systems (GIS), and software platforms that process large datasets.
Multi-agent reinforcement learning (MARL) is a sub-field of reinforcement learning. It focuses on studying the behavior of multiple learning agents that coexist in a shared environment. Each agent is motivated by its own rewards, and does actions to advance its own interests; in some environments these interests are opposed to the interests of other agents, resulting in complex group dynamics. Multi-agent reinforcement learning is closely related to game theory and especially repeated games, as well as multi-agent systems. Its study combines the pursuit of finding ideal algorithms that maximize rewards with a more sociological set of concepts. While research in single-agent reinforcement learning is concerned with finding the algorithm that gets the biggest number of points for one agent, research in multi-agent reinforcement learning evaluates and quantifies social metrics, such as cooperation, reciprocity, equity, social influence, language and discrimination.
A set S {\displaystyle S} of environment states. One set A i {\displaystyle {\mathcal {A}}_{i}} of actions for each of the agents i ∈ I = { 1 , … , N } {\displaystyle i\in I=\{1,\dots ,N\}} .
P a → ( s , s ′ ) = Pr ( s t + 1 = s ′ ∣ s t = s , a → t = a → ) {\displaystyle P_{\vec {a}}(s,s')=\Pr(s_{t+1}=s'\mid s_{t}=s,{\vec {a}}_{t}={\vec {a}})} is the probability of transition (at time t {\displaystyle t} ) from state s {\displaystyle s} to state s ′ {\displaystyle s'} under joint action a → {\displaystyle {\vec {a}}} .
R → a → ( s , s ′ ) {\displaystyle {\vec {R}}_{\vec {a}}(s,s')} is the immediate joint reward after the transition from s {\displaystyle s} to s ′ {\displaystyle s'} with joint action a → {\displaystyle {\vec {a}}} . In settings with perfect information, such as the games of chess and Go, the MDP would be fully observable. In settings with imperfect information, especially in real-world applications like self-driving cars, each agent would access an observation that only has part of the information about the current state. In the partially observable setting, the core model is the partially observable stochastic game in the general case, and the decentralized POMDP in the cooperative case.
In pure competition settings, the agents' rewards are exactly opposite to each other, and therefore they are playing against each other. Pure cooperation settings are the other extreme, in which agents get the exact same rewards, and therefore they are playing with each other. Mixed-sum settings cover all the games that combine elements of both cooperation and competition.
Most real-world scenarios involving multiple agents have elements of both cooperation and competition. For example, when multiple self-driving cars are planning their respective paths, each of them has interests that are diverging but not exclusive: Each car is minimizing the amount of time it's taking to reach its destination, but all cars have the shared interest of avoiding a traffic collision. Zero-sum settings with three or more agents often exhibit similar properties to mixed-sum settings, since each pair of agents might have a non-zero utility sum between them. Mixed-sum settings can be explored using classic matrix games such as prisoner's dilemma, more complex sequential social dilemmas, and recreational games such as Among Us, Diplomacy and StarCraft II. Mixed-sum settings can give rise to communication and social dilemmas.
Stefano V. Albrecht, Filippos Christianos, Lukas Schäfer. Multi-Agent Reinforcement Learning: Foundations and Modern Approaches. MIT Press, 2024. https://www.marl-book.com Kaiqing Zhang, Zhuoran Yang, Tamer Basar. Multi-agent reinforcement learning: A selective overview of theories and algorithms. Studies in Systems, Decision and Control, Handbook on RL and Control, 2021. [1] Yang, Yaodong; Wang, Jun (2020). "An Overview of Multi-Agent Reinforcement Learning from Game Theoretical Perspective". arXiv:2011.00583 [cs.MA].
🦁 WildEye — Real-Time Wildlife Detection System YOLOv8 · FastAPI · React · WebSocket · Multi-Camera AI Surveillance 🚀 Quick Start (Frontend Only — Works Immediately) The frontend runs completely standalone with realistic simulated data. No backend needed to see the full UI experience. cd wild/frontend npm install npm run dev Open: http://localhost:3000 Demo Credentials: Admin: admin@wildeye.ai / admin123 Ranger: ranger@wildeye.ai / ranger123 📁 Full Project Structure wild/ ├── frontend/ # React + Vite + TailwindCSS │ ├── src/ │ │ ├── pages/ │ │ │ ├── HomePage.jsx # 3D animated forest homepage │ │ │ ├── LoginPage.jsx # Auth pages │ │ │ ├── SignupPage.jsx │ │ │ ├── LiveFeedPage.jsx # Camera feeds with YOLO overlay │ │ │ ├── AlertsPage.jsx # Alert management │ │ │ ├── DetectionPage.jsx# Detection log table │ │ │ ├── LocationPage.jsx # Map tracking │ │ │ └── AnalyticsPage.jsx# Charts & insights │ │ ├── components/ │ │ │ └── layout/ │ │ │ └── DashboardLayout.jsx │ │ ├── hooks/ │ │ │ └── useAuth.jsx │ │ ├── utils/ │ │ │ └── mockData.js │ │ └── styles/ │ │ └── globals.css │ ├── package.json │ ├── vite.config.js │ └── tailwind.config.js │ ├── backend/ # FastAPI Python │ ├── main.py # App entry point │ ├── requirements.txt │ ├── Dockerfile │ ├── .env.example │ └── app/ │ ├── api/ │ │ ├── auth.py │ │ ├── detections.py │ │ ├── cameras.py │ │ ├── alerts.py │ │ └── websocket.py # Real-time streaming │ ├── models/ │ │ └── schemas.py │ └── services/ │ └── yolo_service.py # YOLOv8 integration │ └── docker-compose.yml # Full stack deployment 🖥️ VS Code Setup Guide Prerequisites Install these first: Node.js 20+ Python 3.11+ VS Code Recommended VS Code Extensions Install these in VS Code (Ctrl+Shift+X): ES7+ React/Redux/React-Native snippets Tailwind CSS IntelliSense Python Pylance REST Client 🎯 Frontend Setup (Step by Step) # 1. Open terminal in VS Code (Ctrl+`) # 2. Navigate to frontend cd wild/frontend # 3. Install dependencies npm install # 4. Start development server npm run dev # 5. Open browser # http://localhost:3000 That's it! The frontend has full simulation built-in. ⚙️ Backend Setup (Optional — for full API) # 1. Open a new terminal # 2. Navigate to backend cd wild/backend # 3. Create Python virtual environment python -m venv venv # 4. Activate virtual environment # On Windows: venv \S cripts \a ctivate # On Mac/Linux: source venv/bin/activate # 5. Install dependencies pip install -r requirements.txt # 6. Copy environment file cp .env.example .env # 7. Start the API server python main.py # OR uvicorn main:app --reload --port 8000 # API Docs: http://localhost:8000/docs # WebSocket: ws://localhost:8000/ws/detections 🐳 Docker (Full Stack) cd wild docker-compose up --build Services: Frontend: http://localhost:3000 Backend API: http://localhost:8000 API Docs: http://localhost:8000/docs PostgreSQL: localhost:5432 Redis: localhost:6379 MongoDB: localhost:27017 🤖 YOLOv8 Integration The system uses YOLOv8 for detection. To enable real detection: cd wild/backend # Install PyTorch (CPU) pip install torch torchvision --index-url https://download.pytorch.org/whl/cpu # Install Ultralytics pip install ultralytics # Download YOLOv8 model (auto-downloads on first run) python -c " from ultralytics import YOLO; YOLO('yolov8n.pt') " In .env : YOLO_MODEL_PATH=yolov8n.pt YOLO_CONFIDENCE=0.5 📡 WebSocket Events Connect to ws://localhost:8000/ws/detections to receive: { "type" : " detection " , "data" : { "id" : " DET-A1B2C3D4 " , "animal" : " Tiger " , "confidence" : 94 , "camera" : " CAM-001 " , "danger" : true , "trackId" : " TRK-5821 " , "timestamp" : " 2024-01-15T14:30:00 " , "bbox" : { "x" : 120 , "y" : 80 , "w" : 180 , "h" : 200 } } } 🎨 UI Features Page Features Home 3D animated forest, fireflies, moving animals, radar widget Login/Signup Glassmorphism, demo credentials, role selection Live Feed 3-camera canvas simulation, YOLO bounding boxes, detection panel Alerts Real-time alerts, severity filter, acknowledge system Detections Full sortable table, CSV export, live updating Locations SVG tracking map, animal path tracking, camera zones Analytics Area charts, bar charts, pie charts, KPI cards 🌐 Deployment Frontend → Vercel cd wild/frontend npm install -g vercel vercel --prod Backend → Railway / Render # Push to GitHub, then connect to Railway.app # Set environment variables in Railway dashboard 🔧 Troubleshooting npm install fails: npm install --legacy-peer-deps Port 3000 already in use: # Change port in vite.config.js server: { port: 3001 } Python venv issues on Windows: Set-ExecutionPolicy -ExecutionPolicy RemoteSigned -Scope CurrentUser YOLO model download fails: # Manual download wget https://github.com/ultralytics/assets/releases/download/v0.0.0/yolov8n.pt 📊 Tech Stack Layer Technology Frontend React 18, Vite, TailwindCSS, Framer Motion Charts Recharts Routing React Router v6 Backend FastAPI, Python 3.11 AI YOLOv8 (Ultralytics) Tracking DeepSORT / ByteTrack Database PostgreSQL + MongoDB + Redis WebSocket FastAPI WebSockets Deployment Vercel (FE) + Docker (BE) Built with ❤️ by WildEye AI Team · Senior Production Grade
2. Related Work, Literature Survey & Algorithmic Foundations
The frontend runs completely standalone with realistic simulated data. No backend needed to see the full UI experience.
wild/ ├── frontend/ # React + Vite + TailwindCSS │ ├── src/ │ │ ├── pages/ │ │ │ ├── HomePage.jsx # 3D animated forest homepage │ │ │ ├── LoginPage.jsx # Auth pages │ │ │ ├── SignupPage.jsx │ │ │ ├── LiveFeedPage.jsx # Camera feeds with YOLO overlay │ │ │ ├── AlertsPage.jsx # Alert management │ │ │ ├── DetectionPage.jsx# Detection log table │ │ │ ├── LocationPage.jsx # Map tracking │ │ │ └── AnalyticsPage.jsx# Charts & insights │ │ ├── components/ │ │ │ └── layout/ │ │ │ └── DashboardLayout.jsx │ │ ├── hooks/ │ │ │ └── useAuth.jsx │ │ ├── utils/ │ │ │ └── mockData.js │ │ └── styles/ │ │ └── globals.css │ ├── package.json │ ├── vite.config.js │ └── tailwind.config.js │ ├── backend/ # FastAPI Python │ ├── main.py # App entry point │ ├── requirements.txt │ ├── Dockerfile │ ├── .env.example │ └── app/ │ ├── api/ │ │ ├── auth.py │ │ ├── detections.py │ │ ├── cameras.py │ │ ├── alerts.py │ │ └── websocket.py # Real-time streaming │ ├── models/ │ │ └── schemas.py │ └── services/ │ └── yolo_service.py # YOLOv8 integration │ └── docker-compose.yml # Full stack deployment
# 1. Open terminal in VS Code (Ctrl+`) # 2. Navigate to frontend cd wild/frontend # 3. Install dependencies npm install # 4. Start development server npm run dev # 5. Open browser # http://localhost:3000
# 1. Open a new terminal # 2. Navigate to backend cd wild/backend # 3. Create Python virtual environment python -m venv venv # 4. Activate virtual environment # On Windows: venv \S cripts \a ctivate # On Mac/Linux: source venv/bin/activate # 5. Install dependencies pip install -r requirements.txt # 6. Copy environment file cp .env.example .env # 7. Start the API server python main.py # OR uvicorn main:app --reload --port 8000 # API Docs: http://localhost:8000/docs # WebSocket: ws://localhost:8000/ws/detections
cd wild/backend # Install PyTorch (CPU) pip install torch torchvision --index-url https://download.pytorch.org/whl/cpu # Install Ultralytics pip install ultralytics # Download YOLOv8 model (auto-downloads on first run) python -c " from ultralytics import YOLO; YOLO('yolov8n.pt') "
{ "type" : " detection " , "data" : { "id" : " DET-A1B2C3D4 " , "animal" : " Tiger " , "confidence" : 94 , "camera" : " CAM-001 " , "danger" : true , "trackId" : " TRK-5821 " , "timestamp" : " 2024-01-15T14:30:00 " , "bbox" : { "x" : 120 , "y" : 80 , "w" : 180 , "h" : 200 } } }
# Push to GitHub, then connect to Railway.app # Set environment variables in Railway dashboard
# Manual download wget https://github.com/ultralytics/assets/releases/download/v0.0.0/yolov8n.pt
An AI-powered Wildlife Detection System built with YOLOv8 and OpenCV for real-time animal detection, species recognition, tracking, and intelligent monitoring using computer vision and deep learning technologies.
3. Dataset Ingestion, Preprocessing & Stochastic Augmentations
Wildlife detection. This repo contains the final project involving wildlife detection for UC Berkeley - w251 - Deep Learning at the Cloud & Edge. Contributors: Alex Heaton, Jeff Li, Tina Huang, Yuriy Shevchenko Project Inspiration and Overview In this project we used deep learning (computer vision) to automate animal monitoring to generate insights that can be acted upon by humans or another computer process. Potential Applications Using AI to monitor animal behavior can be used to aid animal preservation and develop new business opportunities. Our research was motivated by monitoring live camera feed that is installed at Big Bear Lake, CA to monitor California Bald Eagles nest. The site was monitored 24 hours a day but the project relied on humans to monitor the feed and manually record the activity. The year the eagles laid eggs but they did not survive and the researchers do not know the reason. Potentially by using AI to create a larger scale monitoring program researchers could understand the behavior and conditions that would help more wildlife survive. In commercial applications, we see an increase in smart pet products using AI to create automated cat feeders, bird feeders that identify birds, and robots that will follow your pet to monitor them and keep them company. Solutions Overview Our goal was to create an end-to-end workflow that could be followed by others to accomplish similar tasks. he steps of this workflow are to Collect video recordings (data) Label video frames Train custom Yolo model Perform object detection on Jetson using live video Send output to the cloud for analysis At the end of the project we were able to deploy an object detection model that can run on an edge device to identify squirrels and nuts in a live video feed. Dataset We trained our model using a custom dataset of videos we recorded at a site where squirrels often come to feed. We placed nuts outside the window and captured squirrels and birds that came to the window to pick up nuts. Data Collection We collected several weeks of sample videos that we used to develop our model. To collect the videos we used the Shinobi open source CCTV monitoring software installed on a Jetson device, which was monitoring the stream from an IP camera pointed at the feeding area. Shinobi has built-in motion detection capabilities that we configured and tuned so that video would only be recorded when a squirrel came to visit. This limited the time that we needed to spend watching video recordings looking for relevant frames of squirrel activity. While motion is detected, Shinobi would automatically start recording the video and then save it to an AWS S3 storage bucket. We captured over 100 videos. Data Labeling & Annotation To label the videos we used AWS SageMaker Ground Truth. Ground truth has several powerful features that led us to use that tool. User friendly UI for drawing bounding boxes that can work with files stored in S3 and store the labels back to S3. Split video files into frames (using FFmpeg behind the scenes). Distribute labeling tasks amongst team members. Convert Labels to Yolo v5 Format The one con of Ground Truth was that it saves the labels in a proprietary format and additional transformations are required to convert it to the Yolo format. AWS has published a blog and sample code on github to convert the Ground Truth annotations to Yolo format. However, the samples only covered static images and not video files. The sample code did not work for annotating videos because the frames and annotations are spread across multiple directories (one for each video) so custom code was required to convert the annotations to Yolo format. We plan to make this code available to others who need to label videos in Ground Truth. Model We divided the labeled images into 70% (219) training, 20% (63) validation, and 10% (31) testing sets and used the images collected to retrain the YOLOv5 model. We trained the model on Google Colab with GPU using Roboflow custom YOLOv5 notebook. We choose YOLOv5s because its small size can reduce space required on the Jetson and lower running time. We made improvements using augmentation including grey scale and angle change. We also improved the model performance by increasing training time from 100 epochs to 300 epochs to 1000 epochs. (See below figure for 100 epochs training stats) We saw noticeable improvement from 300 epochs to 1000 epochs. Below is an example of a testing image. The left image is with the inference result of 300 epochs, in which only the nuts are detected but not the squirrel. The right image is the same image but with the inference result of 1000 epochs, in which both squirrel and nuts are detected. We reached 0.803 for overall precision, 0.829 for squirrel class precision, and 0.777 for nut class precision. (See below table for final model stats) Class Squirrel Nut All Precision 0.829 0.777 0.803 Recall 0.894 0.817 0.856 mAP@.5 0.878 0.84 0.859 mAP@.5:.95 0.473 0.255 0.364 Jetson/Model Implementation Jetson deployment Our intention was to implement the model onto a Nvidia Jetson NX. The NX is a lightweight device that will run the model continuously and perform inference based on video coming in over the local network. We utilized a Docker file to standardize deployments across numerous Jetson devices. The container is based off of Nvidia’s L4T. Inference is then performed across each frame. If an object has been detected in the frame, we utilize MQTT messaging to send a result of the captured object to AWS. Integration Architecture AWS IoT MQTT Broker Amazon Internet of Things is a cloud based service that provides a convenient integration solution to connect any smart devices such as Jetson and others to other AWS and cloud services. In this project we are utilizing AWS IoT Mosquitto Broker service to capture all events that are published for jetsoneventstopic and store them in the cloud repository for further processing and analysis. Here is the format of the data that MQTT Broker receives from Jetson: AWS DynamoDB Amazon DynamoDB is a key-value and document-based high performance database that is easily scalable and fully managed on the cloud. It fits our purpose perfectly to capture and store triggered events from Jetson for further review and analysis. As a key for each record, it was decided to utilize a timestamp of the triggered event and use Class Id of the event as a sorting key in DynamoDB. The rest of the data is stored as a payload text in a JSON format. Results Review Future Improvements -Change model to lite to speed up inference -Standardize labeling & increase training data set for better accuracy -Expand to other wild animals -Train models to recognize animal faces to separate animals of the same species -Train model to recognize food consumption -Overlay collected data with public weather and air quality data for patterns recognition -Connect to an automated feeding system to feed when all nuts are gone References -Shinobi Open Source CCTV Solution https://shinobi.video/ -Roboflow-Custom-YOLOv5: https://colab.research.google.com/drive/1gDZ2xcTOgR39tGGs-EZ6i3RTs16wmzZQ
This repo contains the final project involving wildlife detection for UC Berkeley - w251 - Deep Learning at the Cloud & Edge.
In this project we used deep learning (computer vision) to automate animal monitoring to generate insights that can be acted upon by humans or another computer process.
Using AI to monitor animal behavior can be used to aid animal preservation and develop new business opportunities.
Our research was motivated by monitoring live camera feed that is installed at Big Bear Lake, CA to monitor California Bald Eagles nest. The site was monitored 24 hours a day but the project relied on humans to monitor the feed and manually record the activity. The year the eagles laid eggs but they did not survive and the researchers do not know the reason. Potentially by using AI to create a larger scale monitoring program researchers could understand the behavior and conditions that would help more wildlife survive.
In commercial applications, we see an increase in smart pet products using AI to create automated cat feeders, bird feeders that identify birds, and robots that will follow your pet to monitor them and keep them company.
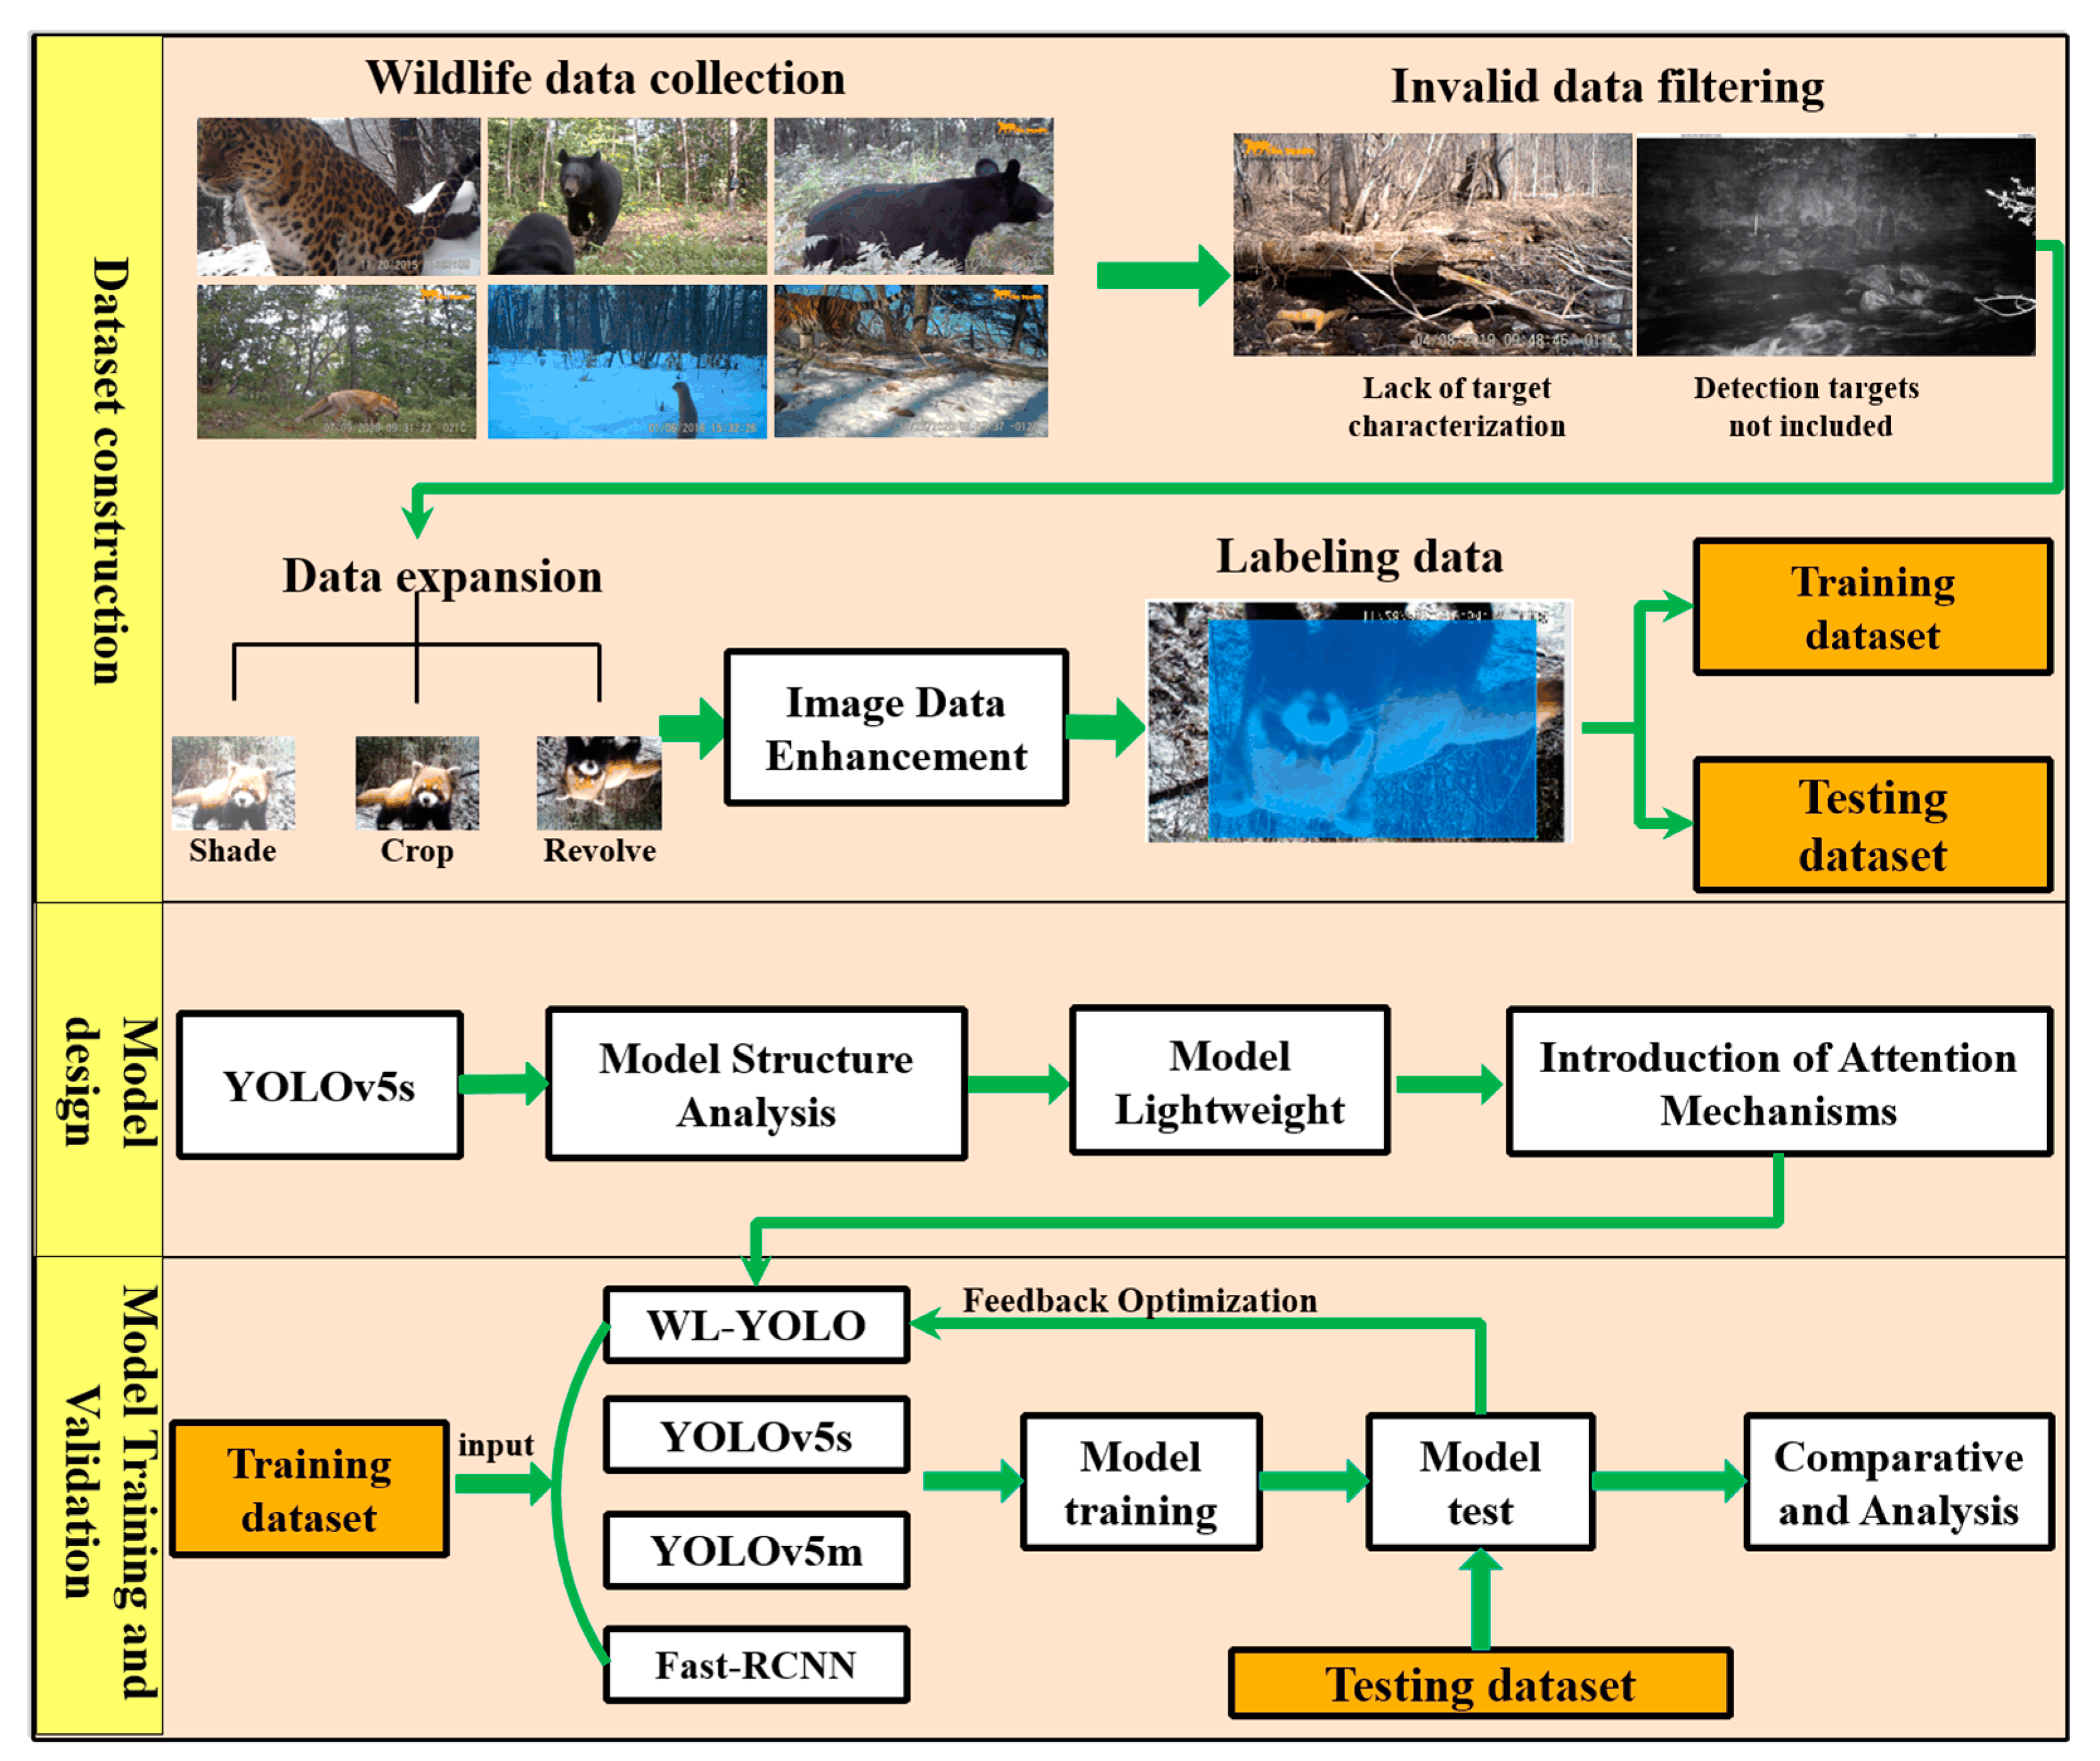
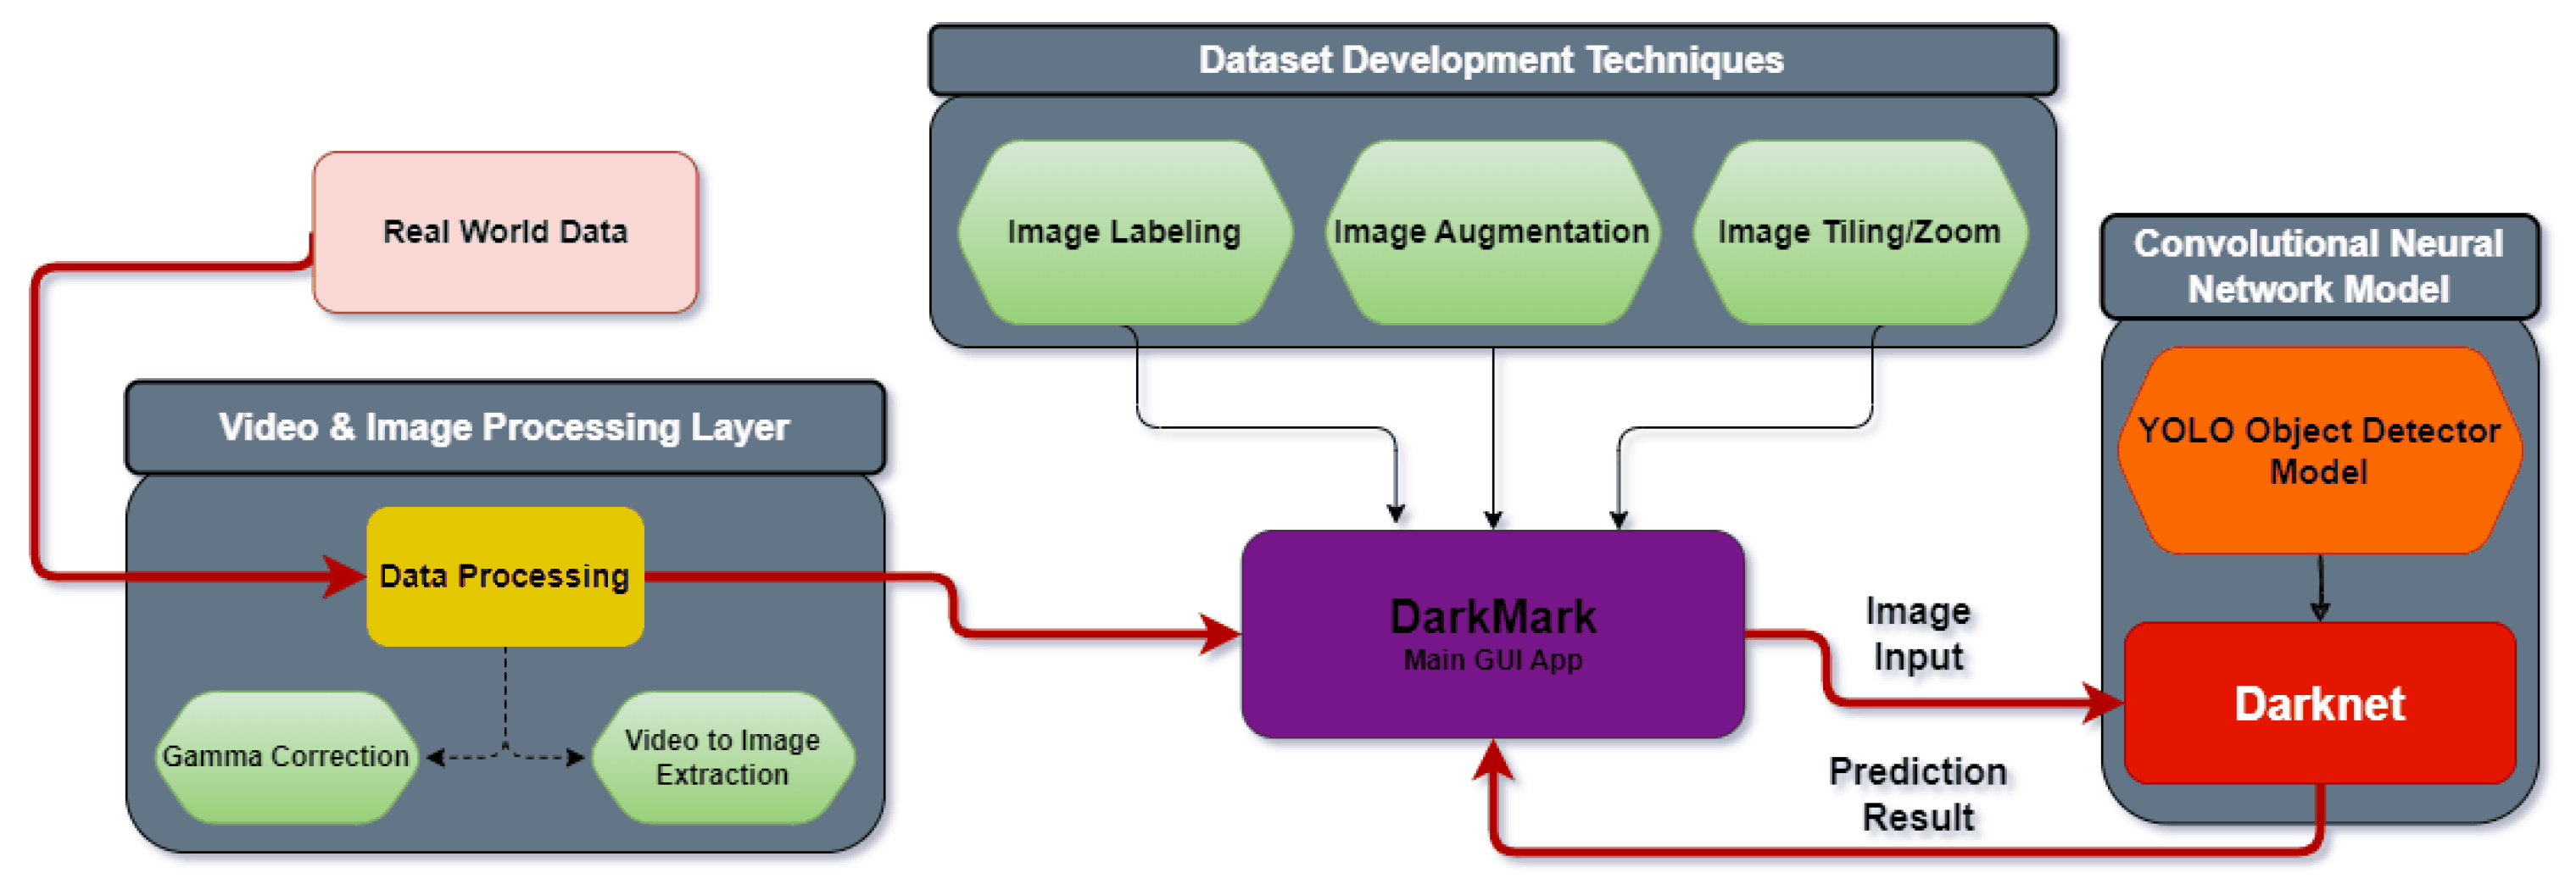
Our goal was to create an end-to-end workflow that could be followed by others to accomplish similar tasks. he steps of this workflow are to Collect video recordings (data) Label video frames Train custom Yolo model Perform object detection on Jetson using live video Send output to the cloud for analysis
At the end of the project we were able to deploy an object detection model that can run on an edge device to identify squirrels and nuts in a live video feed.
We trained our model using a custom dataset of videos we recorded at a site where squirrels often come to feed. We placed nuts outside the window and captured squirrels and birds that came to the window to pick up nuts.
4. Neural Network Backbone, Layer Specifications & Loss Formulations
We collected several weeks of sample videos that we used to develop our model. To collect the videos we used the Shinobi open source CCTV monitoring software installed on a Jetson device, which was monitoring the stream from an IP camera pointed at the feeding area.
Shinobi has built-in motion detection capabilities that we configured and tuned so that video would only be recorded when a squirrel came to visit. This limited the time that we needed to spend watching video recordings looking for relevant frames of squirrel activity. While motion is detected, Shinobi would automatically start recording the video and then save it to an AWS S3 storage bucket. We captured over 100 videos.
To label the videos we used AWS SageMaker Ground Truth. Ground truth has several powerful features that led us to use that tool. User friendly UI for drawing bounding boxes that can work with files stored in S3 and store the labels back to S3. Split video files into frames (using FFmpeg behind the scenes). Distribute labeling tasks amongst team members. Convert Labels to Yolo v5 Format The one con of Ground Truth was that it saves the labels in a proprietary format and additional transformations are required to convert it to the Yolo format. AWS has published a blog and sample code on github to convert the Ground Truth annotations to Yolo format. However, the samples only covered static images and not video files. The sample code did not work for annotating videos because the frames and annotations are spread across multiple directories (one for each video) so custom code was required to convert the annotations to Yolo format. We plan to make this code available to others who need to label videos in Ground Truth.
We divided the labeled images into 70% (219) training, 20% (63) validation, and 10% (31) testing sets and used the images collected to retrain the YOLOv5 model. We trained the model on Google Colab with GPU using Roboflow custom YOLOv5 notebook. We choose YOLOv5s because its small size can reduce space required on the Jetson and lower running time.
We made improvements using augmentation including grey scale and angle change. We also improved the model performance by increasing training time from 100 epochs to 300 epochs to 1000 epochs. (See below figure for 100 epochs training stats)
We saw noticeable improvement from 300 epochs to 1000 epochs. Below is an example of a testing image. The left image is with the inference result of 300 epochs, in which only the nuts are detected but not the squirrel. The right image is the same image but with the inference result of 1000 epochs, in which both squirrel and nuts are detected.
We reached 0.803 for overall precision, 0.829 for squirrel class precision, and 0.777 for nut class precision.
Our intention was to implement the model onto a Nvidia Jetson NX. The NX is a lightweight device that will run the model continuously and perform inference based on video coming in over the local network.
We utilized a Docker file to standardize deployments across numerous Jetson devices. The container is based off of Nvidia’s L4T. Inference is then performed across each frame.
5. Training Protocol, Convergence Behavior & Experimental Evaluation
If an object has been detected in the frame, we utilize MQTT messaging to send a result of the captured object to AWS.
Amazon Internet of Things is a cloud based service that provides a convenient integration solution to connect any smart devices such as Jetson and others to other AWS and cloud services.
In this project we are utilizing AWS IoT Mosquitto Broker service to capture all events that are published for jetsoneventstopic and store them in the cloud repository for further processing and analysis.
Amazon DynamoDB is a key-value and document-based high performance database that is easily scalable and fully managed on the cloud. It fits our purpose perfectly to capture and store triggered events from Jetson for further review and analysis.
As a key for each record, it was decided to utilize a timestamp of the triggered event and use Class Id of the event as a sorting key in DynamoDB. The rest of the data is stored as a payload text in a JSON format.
-Overlay collected data with public weather and air quality data for patterns recognition
-Roboflow-Custom-YOLOv5: https://colab.research.google.com/drive/1gDZ2xcTOgR39tGGs-EZ6i3RTs16wmzZQ
Wildlife-detection-using-deep-learning This project aims to tackle the critical issue of wildlife conservation by employing state of the art deep learning techniques. Leveraging the YOLOv4 algorithm, we have developed a robust system capable of detecting various wildlife species in images and video streams and a IOT based alerting system using telegram bot Key Features: 1.YOLOv4 Implementation: We have implemented the YOLOv4 architecture, known for its exceptional accuracy and speed in object detection tasks, tailored specifically for wildlife detection. 2.Multi-Class Detection: Our system is trained to detect a wide range of wildlife species, including but not limited to mammals, birds, reptiles, and insects, making it versatile for diverse conservation efforts. 3.Dataset Annotation: We provide tools and scripts for annotating wildlife datasets, enabling researchers to create custom datasets for training and evaluation purposes. 4.Pre-trained Models: Users can benefit from pre-trained YOLOv4 models on large-scale wildlife datasets, facilitating rapid deployment and experimentation. 5.Performance Metrics: We evaluate model performance using standard metrics such as precision, recall, and mAP (mean Average Precision), ensuring transparency and reproducibility of results. 6.Customization and Fine-tuning: Our project encourages users to fine-tune the pre-trained models on specific wildlife species or environments, empowering researchers to adapt the system to their unique conservation challenges. 7.Real time implementaion: By the use of Node MCU ,cameras An alerting system using Telegram bot is created. 8.Community Support: We foster a vibrant community where researchers, developers, and conservationists can collaborate, share insights, and contribute to the advancement of wildlife conservation through deep learning technology. By making our project open-source on GitHub, we aspire to democratize access to cutting-edge technology for wildlife conservation, ultimately contributing to the protection and preservation of our planet's precious biodiversity. Join us in the fight to safeguard wildlife populations for future generations.
This project aims to tackle the critical issue of wildlife conservation by employing state of the art deep learning techniques. Leveraging the YOLOv4 algorithm, we have developed a robust system capable of detecting various wildlife species in images and video streams and a IOT based alerting system using telegram bot
Model Figures & Evaluation Curves (4 Images)
Deep Learning Execution Pipeline
(Preprocessing)
(Feature Extraction)
(Self-Attention)
(Loss Optimization)