Abstract
Coverage analysis is critical in pre-silicon verification of hardware designs for assessing the completeness of verification and identifying inadequately exercised areas of the design. It is widely integrated in the simulation based verification flow in the hardware industry. In this thesis, we provide solutions to enable effective coverage analysis in assertion based and emulation based verification.
We introduce two practical and effective code coverage metrics for assertions: one inspired by the test suite code coverage reported by Register Transfer Level (RTL) simulators and the other by assertion correctness in the context of formal verification. We present efficient algorithms to compute coverage with respect to the proposed metrics by analyzing the Control Flow Graph (CFG) constructed from the RTL source code. We apply our technique to a USB 2.0 design and an OpenRISC processor design and show that our coverage evaluation is efficient and scalable. We also present a technique to evaluate and rank automatically generated assertions based on fault coverage.
We present a novel technique to extract code coverage from emulation plat- map them to other statements in the code. Triggering of decision nodes is recorded using additional trigger logic during emulation and mapped back to the source code to obtain coverage information. We apply our technique to an industrial de- sign and show that it can efficiently provide fairly accurate code coverage statistics with minimal overheads during emulation.
Iii
First of all, I would like to thank my adviser Professor Shobha Vasudevan, for her support and encouragement throughout my graduate work. She always believed in me and inspired me to take on new challenges. It is only because of her that graduate school has been such a great learning experience.
I would like to thank Sam Hertz, without whose help and insights the code coverage work would not have been possible. I would also like to thank Darshan Jaitly and Vijay Ganesan from Qualcomm for motivating the coverage work with a real world problem and for their ideas and constant support in exploring its various solutions. I would like to thank Dave Sheridan for his valuable help with GoldMine. Lastly, special thanks to Jayanand Asok Kumar, Lingyi Liu and Parth Sagdeo for the many research-related and other discussions we had that always helped and motivated me.
Ntroduction . . . . . . . . . . . . . . . . . . . . . .
Pre-Silicon Verification . . Role of Coverage in Verification . Coverage Metrics .
Proposed Solutions for Coverage Analysis . .
Overage In Verification
. Assertions . Coverage Analysis for Assertions .
Fault Coverage and Criticality Evaluation . . Emulation and Prototyping in Verification and Coverage .
Static Analysis and Control Flow Graphs . .
Ode Coverage Analysis Of Assertions . . . .
Introduction . . Verilog RTL Source Code as a Control Flow Graph . Defining Code Coverage Metrics for Assertions .
Simulation Based Code Coverage Computation . . Correctness Based Code Coverage Computation . Experimental Results .
Fault Coverage Analysis Of Assertions . . . .
Introduction . . Theoretical Framework . GoldMine Assertions as Fault Detectors .
Resources
. Using the Code Coverage Tool . Using the Fault Coverage Tool .
Pre-Silicon Verification
With advances in semiconductor process technology, modern chips have become extremely complex, containing a few billion transistors and integrating a variety of hardware modules on a single die. Due to this ever increasing design complexity coupled with the huge costs associated with correcting hardware bugs, it is crucial to ensure design correctness prior to putting it in silicon. As a result, pre-silicon design verification today consumes the most computational resources and time in the chip development life cycle . Its main objective is to ascertain that the design is behaving correctly, i.e. according to its specification. This objective is achieved by taking the design through various steps such as simulation or dynamic validation, formal verification, emulation and prototyping.
Most pre-silicon verification activities employ hardware designs described at the Register Transfer Level (RTL). At this level, Hardware Description Languages (HDLs) such as Verilog and VHDL are used to describe the design.
Simulation based verification involves running a set of tests1 or a test suite through software simulation of RTL designs. The simulation output is checked against expected results with the help of variety of testbench checkers to deter- mine whether the design is behaving correctly. The tests can be generated by pseudo-random test generators or are handwritten by the designers or verification engineers based on the functional specification of the design . The latter are known as directed tests. Simulation based verification remains the most impor- tant component in the pre-silicon verification phase in the hardware industry .
Assertions represent desirable properties that a designs should satisfy. Assertion Based Verification (ABV) [6, 7] involves the use of assertions in formal verifica- tion as well as simulation to check if a design complies with its specification.
1Here we refer to pre-silicon verification stimuli and not post-manufacturing tests. Formal verification statically analyzes the state space of the design to check if an assertion can ever be violated. When an assertion fails, formal verification tools provide a counterexample to show how the assertion can be violated. In simula- tion, assertions are continuously checked and an error is flagged when any asser- tion is violated. Synthesized assertions can also be used in emulation and silicon debug . With increasing design complexity and the advent of modern Hardware Verification Languages (HVLs) such as Property Specification Language and SystemVerilog , ABV has steadily gained popularity in recent years .
Emulation and prototyping platforms such as those based on Field Programmable Gate Arrays (FPGAs) have gained popularity to accelerate verification in recent years . The primary motivation for using these platforms is speed: runtime of a test during emulation is orders of magnitude lower compared to simulation.
For example, we found that for an industrial design, running a test in emulation was up to 360x faster than in simulation. The difference in runtimes becomes even more pronounced with increasing design complexity. The downside of emulation, however, is that it fails to provide complete visibility into the design.
Role Of Coverage In Verification
Verification aims to ensure correctness of a design with respect to its specifica- tion. However, verification is only as effective as the test suite and the set of assertions used. For example, consider a test suite for a design containing a large number of tests, all exercising the True branch of an if condition in the de- sign source code. Even if all the tests pass (produce correct output), the False branch is never exercised. Therefore, a bug existing in that portion of the code can escape the verification efforts. This leads to the following important ques- tions: Is the test suite sufficient to ensure correctness? Have enough assertions been written and verified? How much of the design behavior has been verified? With ever increasing design complexity leading to enormous design state spaces, these questions are very difficult to answer. As a result, coverage achieved during verification plays a key role in determining the quality and completeness of veri- fication results. Coverage analysis helps in quantifying verification completeness and identifying unexplored and untested parts of the design .
Each test in simulation based verification induces a different execution of the design, and a design can be guaranteed to be correct if it behaves as required for all such possible tests. However, due to extremely high design complexity, only a subset all possible executions of a design can be checked in practice. Although the test suite is chosen so that the verification would be as exhaustive as possible, design errors in the untested parts of the design may still escape the verification process. As a result, measuring the exhaustiveness of the test suite becomes criti- cal to judge verification progress. Coverage analysis proves to be an effective tool for this task.
A related problem in formal verification is to measure the exhaustiveness or completeness of specification as defined by the set of assertions. An erroneous design behavior can escape the formal checks if it is not captured by the specifi- cation. Indeed in the majority of cases, the specification is manually written by a designer, due to which its quality depends on the competence of the designer.
Determining the behaviors covered by the specification is therefore indispensable in this case as well. Coverage of a test suite or assertions is a broad term encompassing different aspects of the design that are verified. For example, it may correspond to the parts of the design source code exercised by a test suite, or to the fraction of design states or state transitions. It may even correspond directly to important design behaviors as identified by a designer. This has led to a wide variety of coverage metrics often orthogonal to each other . We survey the various metrics in Section 1.3.
Coverage analysis not only helps in quantifying the progress of various veri- fication activities, but can identify inadequately verified design aspects as well. Identification of such coverage holes guides future verification efforts in the right direction. Additional tests or assertions can then be written to fill these holes.
Such a coverage guided approach leads to more systematic verification efforts and ensures optimal use of resources. From a more philosophical point of view, coverage analysis provides an answer to the fundamental question: Does the de- sign meet its specification completely? The ultimate goal is to achieve coverage closure, i.e. to exhaustively verify the entire design behavior.
Overage Metrics For A Test Suite
For conventional simulation based verification, a wide variety of coverage met- rics have been proposed and are currently in use in the hardware industry. The coverage metrics for a test suite can be broadly classified into six categories as follows .
• Code coverage metrics: Code coverage identifies the different structure classes of the HDL program for the design that are exercised during sim- ulation. The structure classes considered are statements, branches and ex- pressions, each giving rise to a different metric. Code coverage metrics are largely derived from software testing . Since code coverage can be easily related to the source code, it is relatively easier to fill the identified coverage holes. Additionally, measuring code coverage adds little overhead to simulation. Therefore, these are the most popular coverage metrics and serve as a key sign-off criteria for ASIC tapeout in the hardware indus- try. However, due to the inherent concurrency present in hardware designs, achieving 100% code coverage does not guarantee complete functional cor- rectness and more complex coverage metrics are required.
• Metrics based on circuit structure: These metrics refer to the circuit that describes the design and identify physical parts of the circuit (e.g. latches) that are not exercised during simulation . Measuring coverage w.r.t.
these metrics is easy; however, it is much more difficult to write tests to fill the coverage holes. Eliminating false negatives in this case is also a challenging task .
• Finite state machine based metrics: Finite State Machine (FSM) metrics require state, transition or limited path coverage on an FSM description of the design. Analyzing such a description for the full system is rarely feasible; hence, these metrics are applied to smaller abstract FSMs either hand-written by designers [21, 22] or automatically extracted from the de- sign description . Metrics in this category are superior to the code or circuit based coverage metrics due to their ability to capture, albeit partially, the sequential behavior of the design. However, it is not straightforward to interpret the coverage reports and write tests to improve coverage.
• Functional coverage metrics: For this class of metrics, a list of error- prone scenarios or functionality fragments (also known as coverpoints) is manually constructed by verification engineers or automatically extracted from the RTL description of the design . Coverage is computed based on the fraction of the coverpoints exercised during simulation. Identifying such coverpoints, however, is a laborious manual task requiring in-depth understanding of the design. Since coverpoints can be thought of as asser- tions, functional coverage is also referred to as assertion coverage, not to be confused with the coverage of the assertions themselves.
• Observability coverage metrics: The coverage categories described thus far are based on the activation of different aspects of the design during sim- ulation. These collectively determine controllability coverage of verifica- tion . On the other hand, observability coverage checks if the effects of errors activated by tests can be observed at the design outputs .
These are relatively recent coverage metrics. • Fault coverage metrics: Fault (error) coverage analysis involves injecting faults into the design according to different models and checking if it causes erroneous behavior . The fault coverage of a test denotes the fraction of faults for which the test fails, or catches the fault. These metrics model a design error by a local mutation in a design description format such as a net list, HDL code fragment, or state transition diagram. They are inspired from software testing and post-manufacturing testing of hardware .
Table 1.1 summarizes the most widely used coverage metrics for pre-silicon verification in the hardware industry. Determination of the coverage of a test suite when it is applied to a design being emulated in a “black box” emulation environment is a daunting practical challenge. Standard emulation platforms and tools are unsuitable for measuring code coverage. In spite of this, some complex tests are run on emulators alone, due to extremely long simulation runtimes. Currently, such tests are only used to check functional correctness of the design but not for coverage. Since emulation Table 1.1: Summary of important coverage metrics for a test suite. For more details and comparison between the different metrics, see and .
Ode
Statements executed during simulation.
Ounts The Number Of Times A Circuit Node
toggles, i.e. changes from 0 to 1 or 1 to 0.
Easures The Number Of Times Each State
and state transition is exercised.
Fied Error-Prone Scenario And Functional-
ity fragment is exercised. is able to run tests in a fraction of the time required for simulation, it should be leveraged for coverage analysis as well.
Overage Metrics For Assertions
Traditionally, coverage metrics for assertions (properties) in the context of formal verification reason about the FSM model of a design . Essentially, cover- age is measured in terms of the number of states in the FSM model covered by the assertions. The pioneering approaches of Hoskote et al. and Katz et al.
propose two distinct directions in defining and computing the state space based coverage. The approach in is based on mutations applied to the FSM. A state is covered by a property if modifying the value of a variable in the that state causes the property to fail formal verification. Katz et al. define coverage based on a comparison between the FSM and a reduced tableau of the property.
Fault or mutation coverage metrics have also been proposed for properties [36, 37]. These metrics use the number of faults or mutations detected as a notion of coverage.
Modern verification flows integrate conventional simulation based verification and formal property verification . In order to get a unified picture of coverage achieved during verification, it is valuable to define assertion coverage metrics on the lines of test suite coverage metrics and provide efficient methods to compute them. Similarly to test suites, such analysis can direct verification engineers to inadequately verified parts of the design for which more assertions need to be written. Chockler et al. present an important step in this direction by provid- ing new coverage metrics in the context of formal verification corresponding to the ones used for a test suite. The support provided by commercial tools in this direction is limited (exceptions include ).
Apart from judging verification completeness, coverage analysis of assertions is essential to evaluate and rank the assertions themselves. This can help in identify- ing a small set of high-quality assertions that can then be used in various stages of the design cycle including simulation, formal verification, emulation and Silicon debug. Such ranking is particularly valuable when assertions are automatically generated .
Proposed Solutions For Coverage Analysis
In this work, we address the issues identified in Section 1.3 for coverage analysis in the context of emulation and assertion based verification and provide effective solutions for each of them.
Overage In Assertion Based Verification
Firstly, we define two practical and effective code coverage metrics for assertions, one for each setting in which assertions are primarily used: simulation and formal verification. The simulation based coverage metric defines the coverage of an assertion in terms of the code coverage of tests that trigger that assertion. The correctness based coverage metric for an assertion focuses on the statements that affect the correctness of that assertion. We thus focus on statement coverage of assertions.
We present algorithms to compute coverage according to the proposed cover- age metrics. The algorithms rely on statically analyzing Verilog RTL source code for the design as a Verilog program [41, 42]. To facilitate this analysis, the de- sign source code is represented as a Control Flow Graph (CFG) extended with the information about variable dependencies which is required for coverage compu- tation.
Our coverage definition and computation technique has key merits over the state space based methods. Firstly, the constructed CFG is linear in the size of RTL source code. Therefore, the cost of building a CFG is far less than a state transition graph, and any manipulations of the CFG are also more scalable. Sec- ondly, coverage reported in terms of lines of RTL source code is closer to the designer and easier to interpret. On the other hand, state space coverage is not easily translatable to source code. Lastly, in practical verification environments, bridging coverage holes in an assertion suite can be easier when coverage infor- mation is available in the form of lines of code. Since verification is a resource and time intensive process, it is valuable to make coverage information easy to understand and use. In addition, our technique can help in quickly determining how modifications to an assertion suite can affect coverage.
We evaluate our correctness based coverage metric and analysis technique us- ing a USB 2.0 protocol design and OpenRISC processor design from . We inject mutations into the covered statements and see if the assertion fails formal verification in the mutated design. These experiments help show that the tech- nique is scalable and efficient and correctly computes coverage according to the proposed definition.
Finally, we study the use of fault coverage, or the number of faults detected by assertions, as a metric to evaluate the assertions automatically generated by the GoldMine tool . We model Single Event Upset (SEU) faults in the design through mutation of the design source code. If an assertion is formally verified true in the original fault-free design but fails formal verification in the faulty de- sign, it is said to detect the injected fault. Moreover, the number of assertions detecting a particular fault can be used to estimate the criticality of that fault w.r.t.
design outputs. We present a formal analysis to explain how GoldMine assertions detect the in- jected SEUs. We also show the effectiveness of our approach through experiments on the SpaceWire communication controller design.
Overage In Emulation Based Verification
We apply our simulation based code coverage computation technique for asser- tions to address the problem of coverage extraction from emulation and prototyp- corresponding set of statements using static analysis. These statements are such that during running of a test, the condition evaluating to true during running of a test ensures execution of the set of statements. Extra logic is added to the design to record the evaluation of these conditions during emulation. The recorded in- formation is post-processed to find the statements executed or covered during the emulation. In order to limit the area overheads of the additional logic, the set of conditions is optimized prior to emulation.
Our technique is targeted towards computing the statement coverage metric for a test. Branch coverage can also be derived from the output of our technique. Moreover, it should be noted that although we mainly consider FPGA based emu- lation platforms, the technique can be readily applied to other hardware emulators.
This is due to the fact that the trigger logic to be added is expressed as synthesiz- able Verilog code. We demonstrate our technique on an industrial design emulated on a Xilinx FPGA platform. The runtime of our technique was within 30 seconds for the de- sign with a few thousand lines of source code, which shows that the technique is scalable and efficient. The code coverage reported using our technique is com- pared to that from an RTL simulator. We find that with around 10% FPGA usage overhead, the error in reported coverage by our technique is within 2% on average.
Moreover, using optimization, the overhead can be reduced at the cost of slightly higher error.
Summary
In summary, the main contributions of this thesis are as follows. • We propose two code coverage metrics for assertions, applicable in each of the two use cases: simulation and formal verification.
• We present an efficient technique to compute code coverage of assertions by statically analyzing the RTL source code. Our technique presents statement coverage, which is easier to interpret for the designer as compared to state space coverage.
• We provide an objective evaluation of automatically generated assertions from the GoldMine tool based on fault detection and show how the same analysis can also be employed to estimate criticality of faults.
• We provide a practical and efficient solution to the problem of extracting code coverage from emulation and prototyping platforms using static anal- ysis of design source code.
The rest of the thesis is organized as follows. Chapter 2 discusses previous work related to the different components of the thesis. In Chapter 3, we describe our approach of code coverage analysis for assertions. It includes definitions of the proposed code coverage metrics, our CFG framework and the coverage com- putation algorithms that utilize the framework. Chapter 4 explains our approach of ranking assertions based on fault detection and estimating criticality of faults.
Our technique of code coverage extraction from emulation and prototyping plat- forms is next explained in Chapter 5. Through a motivating example, we show how CFG based static analysis can help extract code coverage efficiently. This is followed by a detailed description of our methodology and experimental results on an industrial design. We conclude in Chapter 7.
Related Work
We consider previous work related to various parts of the thesis including cover- age in verification, assertions and coverage analysis for assertions, fault criticality evaluation, coverage during emulation and prototyping, and static analysis.
Overage In Verification
As explained in Chapter 1, coverage analysis is indispensable to evaluate the ex- haustiveness and quality of verification of hardware designs. Therefore coverage metrics and coverage analysis techniques have been widely studied and incorporated in industrial design flows .
Tasiran and Keutzer survey the myriad of coverage metrics for test suites currently employed in simulation based verification. Code coverage metrics [31, 45] such as statement coverage and branch coverage refer to parts of the HDL source for the design exercised during simulation. Metrics such as toggle coverage identify physical parts of the circuit such as latches that are not fully exercised . FSM metrics measure coverage in terms of states and state transitions of an abstract FSM model of the design. The model can be either hand-written by designers or automatically extracted from the design description [23,46– 48]. Hoskote et al. present a technique of automatically extracting the control flow of a design on the basis of the underlying mathematical model, independent of the circuit description style. Other approaches select state variables for the automatically extracted FSM based on architectural information. Functional coverage involves checking if manually or automatically identified error scenarios are covered during simulation . More recent metrics take into account observability information to determine whether effects of errors activated by a test can be observed at the circuit outputs. Metrics based on fault models injecting faults into the design and checking whether it causes erroneous behavior .
Code and circuit coverage statistics are readily reported by most commercial RTL simulators . Code coverage analysis is done through instrumentation based or dumpfile based techniques . Instrumentation based techniques utilize the Programming Language Interface (PLI) of simulators to measure the execution statistics of the source code during simulation. Dumpfile based techniques com- pute coverage statistics by post-processing of Value Change Dump (VCD) files generated during simulation. Among the two methods, dumpfile based methods incur much lower performance overhead during simulation, and different cover- age metrics can easily be computed from the same dumpfiles.
Code, mutation and even functional coverage metrics are used in software test- ing to evaluate the exhaustiveness of the test suite [20, 52, 53]. Zhu et al. survey the extensive research in this area. The code coverage metrics for simula- tion based hardware verification are largely derived from those used in software testing.
In Integrated Circuit (IC) manufacturing testing, fault coverage is used as a met- ric to evaluate the effectiveness of test patterns to isolate a defective chip . Guo et al. compare the various fault models, e.g. stuck-at fault, bridging fault and N-defect, used in post-manufacturing testing through analysis of large amounts of production test data. Some of these fault models such as stuck-at fault are also used in the context of pre-silicon verification. Moundanos et al.
propose a unified framework for verification and post-manufacturing testing. It is shown that the same abstraction techniques can aid Automatic Test Pattern Gener- ation (ATPG) tools to attack hard-to-detect faults as well as provide a meaningful measure of coverage for design verification.
Assertions
The idea of an assertion or property for checking correctness can be traced back to Turing , where an approach of partitioning a large verification problem into a set of assertions was first presented. Use of assertions to formally specify and reason about programs was proposed by Floyd and Hoare . The onset of HDLs first introduced assertions in the context of hardware design verifica- tion. For instance, VHDL ‘assert’ keyword provides a way of express- ing a condition as property and checking if it is ever violated during execution.
Model checking was proposed around the same time to formally check the correctness of a design w.r.t. specifications expressed in the form of assertions. Modern verification processes involve the use of powerful HVLs such as PSL and SystemVerilog that allow expressing complex assertions. Many commer- cial tools now provide support for assertion based verification, where assertions expressed in these HVLs are used in conjunction with simulation and formal ver- ification .
Writing assertions manually is a very difficult and laborious task. Various au- tomatic assertion generation techniques have been proposed for software and hardware [40, 65–67] to alleviate this problem. These techniques use a dy- namic or static analysis approach or their combination for assertion generation.
Early work with software assertion generation focused on extracting loop in- variants or properties that hold across iterations of a while or for loop in the program . DIDUCE is an online technique to learn invariants on variables in the program at specific program points. Ammons et al. present a machine discovers invariants by analyzing program execution traces and inferring invari- ants based on predefined templates such as comparison with constant value, linear relationships and ordering.
The IODINE tool employs a template based dynamic approach similar to Daikon to generate assertions for hardware. The templates used include one-hot, mutual exclusion and request-acknowledge. A sequential data mining approach to extract hardware assertions is proposed in . GoldMine uses a novel combination of data mining and static analysis to generate assertions. The formal verification step in GoldMine ensures that the generated assertions are true system invariants. In this thesis, we evaluate and rank GoldMine assertions on the basis of fault coverage.
Overage Analysis For Assertions
Assertion or property coverage in the context of formal verification has been tra- ditionally expressed in terms of the fraction of design states covered . Coverage computation in this case typically depends on the analysis of the state transition graph of the design or its variants. Hoskote et al. present a mutation based approach where a state is covered by a property if modifying the value of a variable in that state causes the property to fail formal verification. This work was followed up in . Katz et al. propose the use of a comparison be- tween the FSM and a reduced tableau of the property to define coverage. In our coverage analysis technique, we do not construct a state transition graph from the RTL design, but instead perform an analysis of the Verilog Hardware Description Language (HDL) source code for the design considered as a Verilog program as in .
Recent approaches attempt to relate coverage metrics from formal and simulation based verification. For each of the simulation based coverage metrics, presents a corresponding metric suitable for assertions in formal verification.
To compute coverage of an assertion, statements in the code are removed one at a time, and the assertion is checked for vacuity in the mutant design. Although a pioneering approach to code coverage of assertions, it becomes intractable as size of the design source increases. In contrast, our technique does not require mutating every line and, since we analyze the CFG, the technique naturally scales.
In , the authors propose the use of a test plan language as a formal basis for unifying the coverage goals for simulation and formal property verification. However, the approach does not provide a way to map assertions to the design source.
Some commercial formal verification tools have recently started providing code coverage statistics for assertions in the context of formal verification through anal- ysis of the state transition graph of the design . We provide different cover- age metrics for assertions applicable in simulation and formal verification. Based on source code analysis, we also give efficient techniques of coverage computa- tion which are inherently more scalable.
Fault Coverage And Criticality Evaluation
Simulation based approaches are typically used for fault experiments to determine fault coverage of assertions . Since our fault coverage evaluation method uses formal techniques for all fault experiments, it accurately identifies the faults detected by assertions. In [71, 72], formal methods have been used to inject soft errors in RTL design and evaluate fault coverage, but the authors only consider manually written assertions. We use an approach similar to to evaluate the automatically generated assertions from the GoldMine tool .
Our SEU fault criticality analysis can be thought of as a part of Soft Error Rate (SER) determination for digital circuits, which is widely studied at circuit, gate and architectural levels . Most approaches are simulation based and study the probability of a transient fault at a circuit node getting latched in a flip- flop/latch or the effect of soft errors visible at the architectural level. We define the criticality of an SEU fault at a flip-flop/latch in terms of the number of paths through which it can propagate to a design module output and use formal meth- ods for criticality estimation. In , an analytical method is presented to ana- lyze multi-cycle error propagation behavior to find fault criticality. Although the method accurately computes propagation probabilities, the analysis is performed at gate level. We reuse automatically generated RTL assertions for criticality esti- mation.
Overage
Use of emulation and prototyping platforms such as those based on Field Pro- grammable Gate Arrays (FPGAs) to accelerate verification in the hardware indus- try is widely studied . Ray and Hoe present a case study in developing a synthesizable high-level model of a superscalar processor and producing a work- ing prototype in FPGA. Emulation and prototyping is now commonly integrated in industrial verification flows . For instance, Gateley et al. discuss the experiences in applying emulation based techniques to aid design verification of the UltraSPARC-I processor.
To the best of our knowledge, no previous approaches exist for extracting code coverage from emulation platforms and which apply static analysis for this pur- pose. The VN-Cover Emulator tool enables code coverage extraction from some emulation platforms such as Cadence Palladium and Cobalt using code in- strumentation similar to coverage analysis by RTL simulators. Through the CFG based analysis and decision node optimization, our technique for coverage extrac- tion from emulation efficiently provides coverage statistics with minimal over- heads.
Static Analysis And Control Flow Graphs
In software, static analysis encompasses a family of techniques for automatically computing information about the behavior of a program without executing it . Static analysis techniques are used in a variety of fields including compiler opti- mization , debugging , security , formal verification and invariant generation . Many of these construct a Control Flow Graph (CFG) or its vari- ants (e.g. Program Dependence Graph (PDG) ) from the program to facilitate the program analysis. Program slicing , a static analysis technique that iden- tifies program statements relevant to a particular computation, also uses CFGs.
High-level synthesis converts a system-level behavioral description into an RTL description optimized for energy, power or area . Control Data Flow Graphs (CDFG) commonly serve as the intermediate representation of the system in this case.
Static program analysis techniques have been adapted for hardware by treating the HDL source for a design as a program . Clarke et al. propose using a PDG to represent each of the concurrent processes in the HDL source. The PDG captures both control and data dependencies and thus is an extension of a CFG. We use an extended CFG framework similar to a PDG for our code coverage analysis techniques.
Ntroduction
In this chapter, we present our work on code coverage analysis of assertions. In particular, we consider statements coverage for assertions. We start by describing our Control Flow Graph (CFG) framework to facilitate static analysis of Verilog source code as a program (Section 3.2). We then define simulation based and correctness based code coverage metrics relevant to each of the two use cases of assertions, viz. simulation and formal verification (Section 3.3). Using the CFG framework, we present algorithms to compute coverage according to each of the proposed metrics (Sections 3.4 and 3.5). We demonstrate experimental results on a USB protocol design and the OpenRISC processor design in Section 5.4.
Our CFG framework consists of a CFG for each of the concurrent processes in the design source. The CFG is further augmented with data flow information in the form of variable dependencies. CFG for the design consists of the union of CFGs for all processes in each of the design modules. Statements in the code correspond to CFG nodes while branches correspond to edges. Thus, the CFG is linear in the size of the design source.
Among the proposed coverage metrics, simulation based coverage metric de- fines the coverage of an assertion to closely approximate the coverage of the tests that trigger that assertion. On the other hand, the correctness based coverage metric focuses on the statements that affect the correctness of that assertion.
In simulation based coverage computation, we identify the set of statements such that triggering of the assertion (i.e. its antecedent evaluating to true) en- sures execution of these statements. This set consists of the statements that must be executed for the decision node to trigger (backward cone) and the statements conditioned on the decision node (forward cone). The analysis is performed in a way that the coverage from our technique closely approximates the code coverage reported by a simulator.
Correctness based coverage computation consists of an execution phase and a coverage extraction phase. In the execution phase, assuming the antecedent of the assertion holds, the CFG is used to explore all possible executions of the RTL design over the number of cycles spanned by the assertion. During the CFG traversal, important dependency information between statements is stored in the form of triggers. These triggers are used in the coverage extraction phase to find statements covered by the assertion.
We evaluate our correctness based coverage metric and analysis technique us- ing a USB 2.0 protocol design and OpenRISC processor design from . We find that on average, only about 8% of the total statements were reported as cov- ered by each assertion, which shows that our technique can effectively find the statements truly relevant to the correctness of an assertion. We inject mutations in the covered statements and see if the assertion fails formal verification in the mu- tated design. These experiments help show that the technique correctly computes coverage according to the proposed definition. For every assertion, mutations at almost all covered statements were detected. Careful analysis of the source code with the assertion shows that the mutations are not detected only in cases listed in Section 3.5.
The simulation based coverage analysis is evaluated by applying it to solve the
Graph
In order to facilitate analysis of the Verilog source code, we represent it as a Con- trol Flow Graph (CFG). Each statement in the code is mapped to a node in the CFG. A design is made up of a set of modules. Each module in turn consists of a set of concurrently running always processes and assign statements. The CFG for the module consists of the union of CFGs for each of these processes.
The set of CFGs for all modules thus completely captures the structure of the design. It is similar to a Process Dependence Graph described in . Each node in the CFG stores the number of the line in the RTL code it corre- sponds to, as well as an expression for the RTL statement at that line.
An assignment node represents a blocking or non-blocking assignment in the Verilog code such as ‘a = 2’b01’ or ‘b <= 1’b1’. A decision node repre- sents conditional statements, i.e. if and case statements in the source code.
Nodes other than assignment and decision nodes correspond to begin, end, Edges in the CFG represent the control flow between RTL statements. Each assignment node has one outgoing edge that points to the node corresponding to the next line in the RTL code. Each decision node has two outgoing edges left and right that point to the RTL statements executed if the corresponding condition is true or false, respectively.
The CFG is a purely syntactic representation of the RTL code. For effective coverage estimation of assertions, we need to track dependencies between vari- ables. The CFG is therefore extended with additional data flow information. The resulting extended CFG is similar to the System Dependence Graph (SDG) for VHDL introduced in where the additional dependencies are represented as flow edges. However, the data flow information we store is simpler and mainly targeted towards the coverage estimation algorithm described later, in Section 3.5.
We store a list of variables used in the RTL code. The variables are classified into inputs, outputs, internals and parameters. The dependence information for a variable v is recorded in the form of initial assignment, decisions and assignments as described below.
• Initial assignment: This is only valid if v is an internal or an output vari- able of Verilog reg type. It points to the CFG node where the variable is assigned its initial value. This is typically the value when the reset signal is asserted, or in general, any value fully defined by inputs.
• Decisions: These are decision nodes which use v in the corresponding con- dition in the RTL. • Assignments: These are assignment nodes with assignments to v, or in gen- eral, all assignments with v in the left hand side.
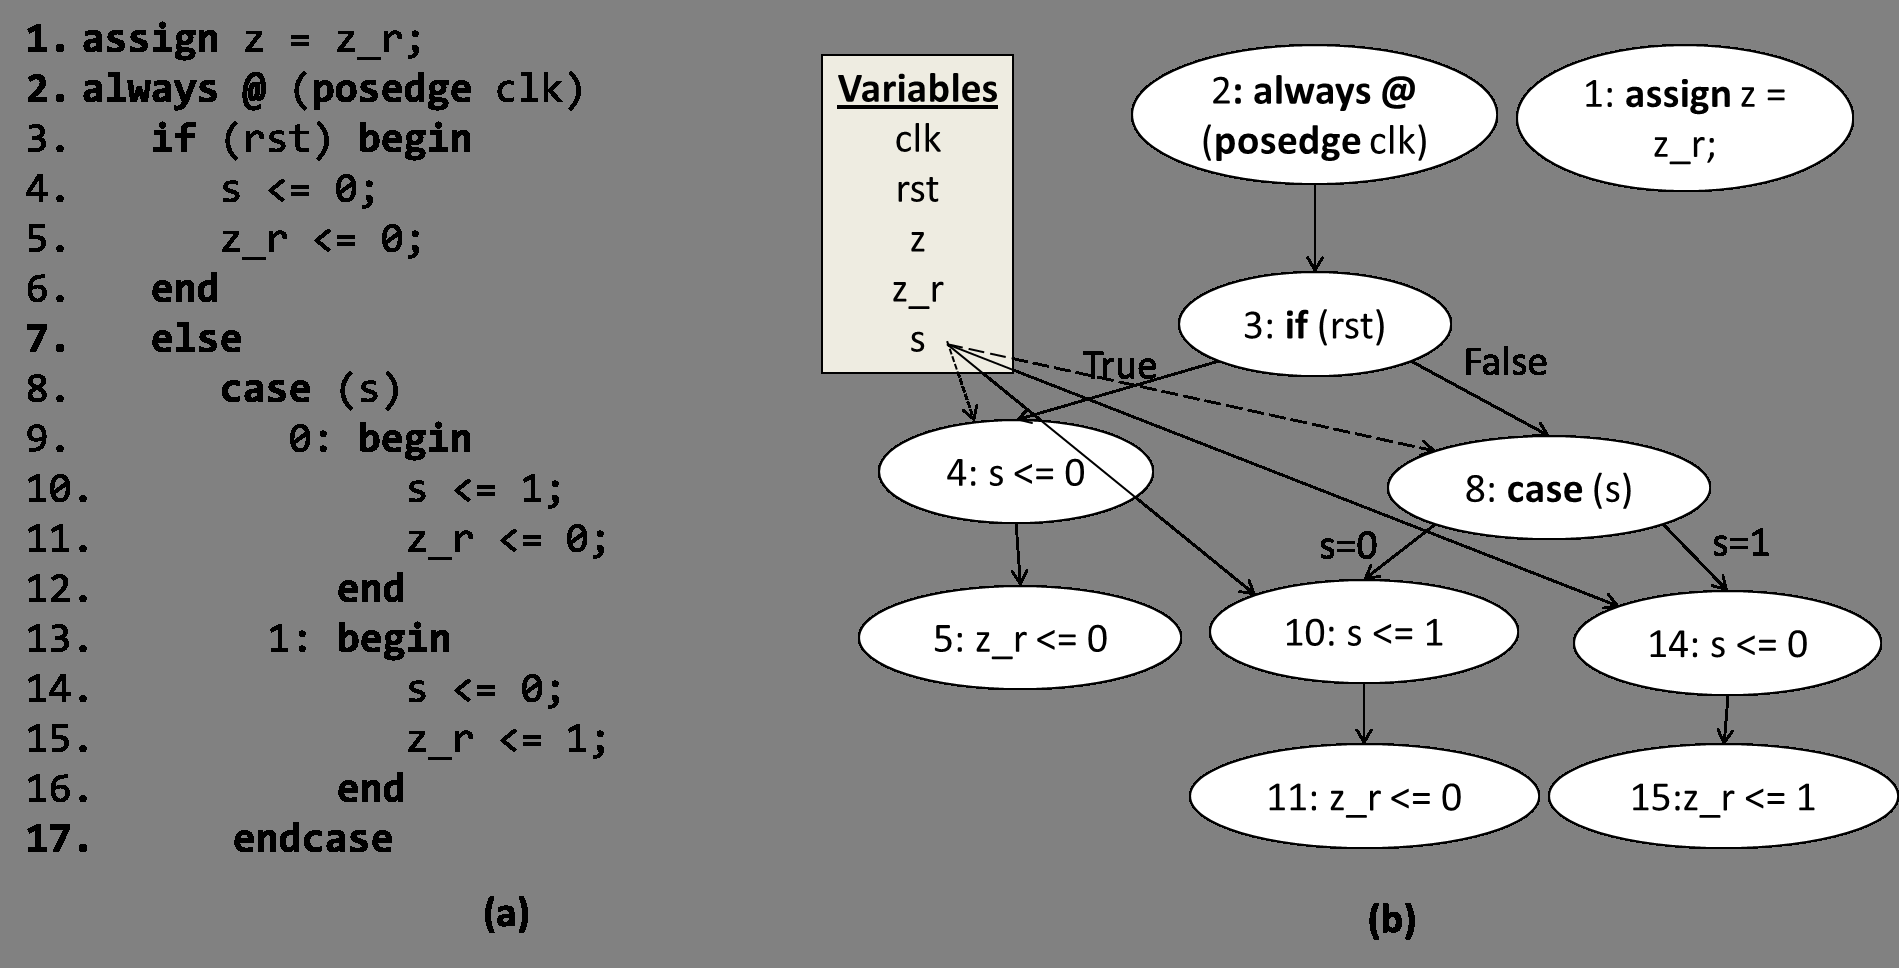
Example 1 Figure 3.1 illustrates the terms defined above with the help of an example Verilog RTL code. The CFG for the module consists of the CFGs for the two processes, viz. the continuous assignment on line 1 and the always process starting at line 2.
Figure 3.1: (a) Example Verilog RTL code for a design with inputs clk, rst, output z and internal variables s, z r. (b) Control flow graph for the example RTL design augmented with variable dependency information in the form of assignments (solid lines) and decisions (dashed line) and initial assignment (dotted line) for variables. For clarity, nodes containing only keywords such as begin and end are not shown. Also, variable dependency information is shown only for the internal variable s.
It can be seen that each statement in the RTL code is mapped to a node in the CFG. Nodes corresponding to if (rst) and case (s) are decision nodes. Each of these has corresponding end nodes which are not shown for clarity.
The data flow information in the form of variable dependencies is also shown in Figure 3.1. Again for clarity, only the information for internal variable s is shown. The node corresponding to statement s <= 0 on line 4 forms initial assignment for variable s (dotted line). Variable s is used in the decision corresponding to case (s) (dashed line) and assignments on lines 10 and 14 (solid lines).
Efining Code Coverage Metrics For Assertions
In this section, we define the two code coverage metrics for an assertion. We start We consider assertions of the form ant ⇒con, where the antecedent ant is a conjunction of propositions and con is a single proposition. A proposition here is of the form v == val where v is a variable in the RTL code. We also con- sider temporal assertions, which are assertions spanning multiple clock cycles.
Assertions are represented in Linear Temporal Logic (LTL) format. For example, following is an assertion for the design in Example 1.
¬Rst ∧S ⇒X(Z)
In words, this assertion expresses the property: ‘if rst == 0 and s == 1 then in the next cycle, z should evaluate to 1’. An assertion is said to trigger when its antecedent evaluates to true.
We call the set of statements reported as covered by the assertion ‘a’ according to our definition the result set of a. Therefore the proposed coverage metrics provide a notion of statement coverage of an assertion.
Simulation Based Code Coverage
We define the simulation based code coverage of an assertion such that it closely approximates the simulator statement coverage of a test that triggers the assertion. Our coverage definition as well as coverage analysis ensures that the coverage reported by our technique is an under-approximation or a conservative estimate of the simulator coverage. In other words, if a statement is reported as covered by our technique, it must be reported as covered by the simulator as well, while the converse may or may not be true.
Definition 1 (Simulation based coverage) A statement s is covered by an asser- tion a if it belongs to one of the following categories. (1) s must be executed in order for the antecedent of a to evaluate to true.
(2) s is executed because the antecedent of a evaluates to true. (3) s is executed irrespective of the evaluation of the antecedent of a. (4) s does not belong to the above three categories, but execution of a statement from (1) or (2) ensures the execution of s.
We call the set of statements falling in categories (1) and (2) as the backward cone and the forward cone of the assertion, respectively. We use the term ancillary cone to denote the statements belonging to categories (3) and (4).
Note that (3) includes continuous assignments as well as unconditionally ex- ecuted statements in each always process. As an example of a statement in category (4), consider the following code snippet.
End
Suppose that s1 belongs to the backward cone of a decision node, but not s2. However during simulation, s2 must be executed if s1 is executed. We include s2 in the ancillary cone of the decision node.
Note that we include only those statements which are definitely executed, when- ever a given assertion is triggered. As a result, if a test triggers a, the result set of a is a subset of the set of lines covered by the test. If multiple tests trigger the same assertion a, the result set is an intersection of the sets of lines covered by each of the tests.
Since this definition depends only on triggering of an assertion, the consequent as well as the correctness of the assertion is irrelevant to the coverage. For the RTL design from Example 1, consider the following assertion: a : ¬rst ∧s ⇒X(z).
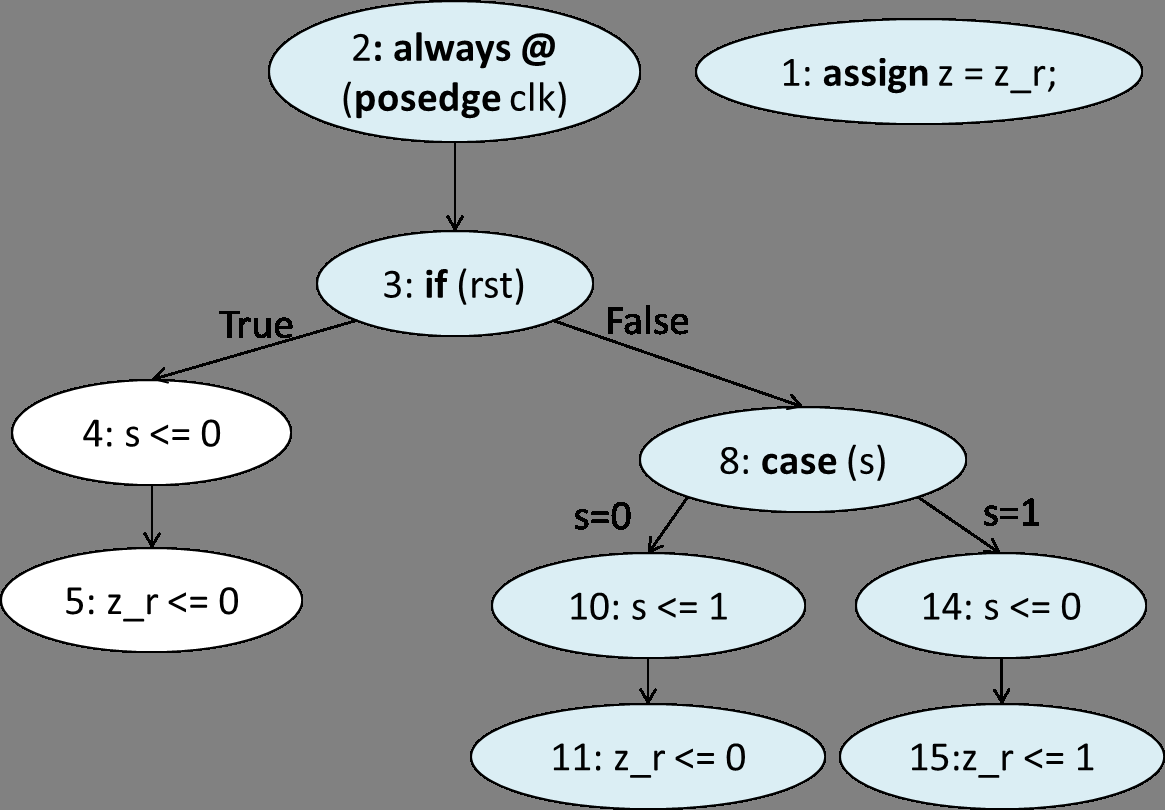
The assertion a triggers when the antecedent ¬rst ∧s evaluates to true. It can be concluded from Figure 3.1 that statements on lines 3, 8, 9 and 10 must be executed prior to variable s getting the value 1. These belong to the backward cone of a.
Statements on lines 3, 8, 13, 14 and 15 are executed due to the triggering of a, i.e. due to the variables rst and s evaluating to 0 and 1, respectively. Therefore, these statements are included in the forward cone of a.
Assign Z = Z R; Are Executed Irre-
spective of the triggering of a and therefore belong to category (3) from Defini-
Z R <= 0; Is Executed Whenever Line 10 Is Exe-
cuted and therefore belongs to category (4) from Definition 1. These statements constitute the ancillary cone of a. Figure 3.2 shows the CFG nodes covered by a in this case.
Figure 3.2: CFG nodes covered by a according to the simulation based coverage definition.
Orrectness Based Code Coverage
In the context of formal verification, we define the coverage of an assertion based on its correctness. Essentially, a statement is said to be covered if its correct execution is necessary for the correctness of the assertion.
Definition 2 (Correctness based coverage) A statement s in the RTL source code is said to be covered by assertion a if for some error or mutation injected at s, a fails formal verification in the mutated design.
In this context, an error or mutation represents a logical bug such as an incorrect value assigned to a variable. Since this definition depends on the correctness of the assertion, the number of cycles spanned by the assertion as well as the consequent are relevant to the coverage.
In , a mutation based definition of code coverage of an assertion is pre- sented. However, the mutation considered involves removing the statement, and coverage is computed by checking if the assertion becomes vacuous in the mutant design. We consider logical bugs as mutations and compute coverage through analysis of the CFG for the RTL source code as described in Section 3.5.
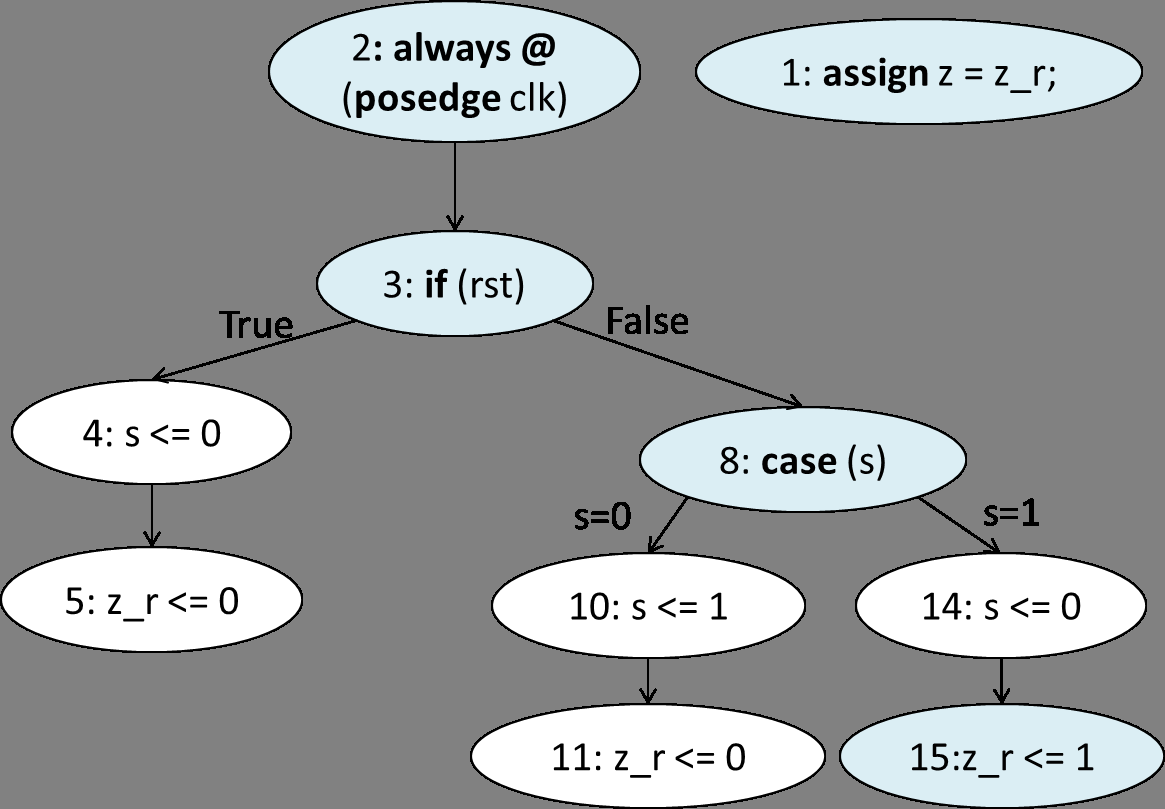
Consider again the assertion a above for the code in Example 1. Statements on lines 1, 3, 8, 13 and 15 are included in the result set of a according to the correctness based definition.
Figure 3.3 shows the CFG nodes covered by a according to this definition. Figure 3.3: CFG nodes covered by a according to the correctness based coverage definition.
Given that the antecedent ¬rst ∧s holds, an error in one of these statements can make the consequent false and therefore make the assertion fail. For example, if the antecedent holds and either z r or z is not assigned to the correct value, it will make the assertion fail.
A comparison between the result sets of a according to the two definitions show that statements on lines 9, 10 and 14 are included in simulation based coverage but not in correctness based coverage. Lines 9 and 10 fall in this category because they are executed prior to the antecedent becoming true and hence are irrelevant to the correctness of a. Line 14 is also unable to affect the correctness of a, and therefore it is not included in correctness based coverage.
Simulation Based Code Coverage Computation
We now describe our algorithm to compute the coverage of an assertion according to the simulation based coverage metric. Let a be an assertion for an RTL module M with CFG G. Let Ba, Fa and Aa be the sets of statements in backward, forward and ancillary cones of a, respectively. Let Sa be the result set of a. Then Sa = Ba ∪Fa ∪Aa.
Backward Cone
In order to find the statements in the backward cone of a, we look at each propo- sition in a individually. We find the statements that must be executed for the proposition to evaluate to true. Since a is a conjunction of such propositions, each of these propositions must evaluate to true for a to trigger. Therefore, if a state- ment must be executed for any of these propositions to evaluate to true, it must be executed for a to trigger. As a result, the union of backward cones of propositions gives the backward cone of a. We only consider propositions involving internal variables or outputs in this analysis.
Procedure 1 describes how we obtain the backward cone of each proposition. Consider a proposition p : (v == val). We first find CFG nodes which assign the value val to variable v in GetMatchingAssignments() (Procedure 2). Apart from direct assignment v <= val, we also look for indirect assignments, that is, assignments of the form v <= v′ such that v′ in turn is assigned val directly or indirectly. If val happens to be the initial value of v, the CFG node corresponding to the initial assignment is immediately returned without further processing.
It is possible that v can be assigned val in multiple statements of a process. Since our goal is to find the statements that must be executed for a to trigger, we stop the backward traversal in such cases. Thus, we do not consider all possible execution paths that lead to v being assigned the value val.
When there is exactly one matching assignment n, it is included in B. If it is an indirect assignment, e.g. of the form v <= v′, a recursive call is made for a new proposition p′ : (v′ == val).
Finally, all decision nodes that lie on the path from top level CFG node to the node corresponding to n are also included in B.
Forward Cone
To compute Fa, we use the information provided by a in the form of propositions. Since we assume that a has triggered, we have available a list of values L for some of the variables.
We look at all always processes containing a decision involving some v ∈L. For each such process, we traverse the CFG starting from the top level node. When a decision node is encountered, we attempt to evaluate the corresponding conditional expression using the values in L. If it can be evaluated, we take the re- Procedure 1 Extract backward cone of proposition p : (v == val) in RTL module M
Getbackconeproposition(G, P)
Input: Extended CFG G of M, proposition p : (v == val) Output: Set of statements B in backward cone of proposition p
: B ←Φ
2: N ←GetMatchingAssignments(p) {Find assignments that make p true}
:
{Continue if exactly one matching assignment exists}
: End If
Procedure 2 Get CFG nodes with assignments matching proposition p
Getmatchingassignments(G, P)
Input: Extended CFG G of M, proposition p : (v == val) Output: Set of CFG N nodes containing assignments matching p
: End If
spective traverse along the respective edge. If the expression cannot be evaluated, we stop the traversal. The statements mapped to the nodes encountered during this traversal are included in Fa.
When the conditional expression for a cannot be represented as a conjunction of propositions, we simply start at a and traverse downwards until another deci- sion node is encountered. The statements corresponding to the visited nodes are included in Fa.
Ancillary Cone
Extracting ancillary cone Aa consists of the following two steps, one for each of the categories (3) and (4) from Definition 1. i. Firstly, all continuous assignments are included in Aa. Then, starting at the top level CFG node of each process, we traverse the CFG until a decision node is encountered. Statements corresponding to all visited nodes are in- cluded in Aa, since those are always executed irrespective of triggering of a.
ii. For each assignment node in Ba, we first traverse the CFG upwards until a decision node is reached. Statements corresponding to the visited nodes are included in Aa, since those lines are executed whenever the original assignment corresponding is executed. The same procedure is then repeated for downward traversal starting from the assignment node.
Orrectness Based Code Coverage Computation
This section describes our algorithm to extract the result set of an assertion ac- cording to the correctness based coverage definition. It consists of two phases, viz. the execution phase and coverage extraction phase.
Consider an assertion a : ant ⇒con for module M, that spans k cycles. Let V be the set of variables in M. For a k cycle assertion, con is of the form XX . . X(ktimes)(vout) or XX . X(ktimes)(¬vout), where vout ∈V . Our goal is to find Ca, the result set of a according to the correctness based coverage definition. Procedure 3 describes how we compute Ca.
Procedure 3 Extract correctness based coverage of assertion a : ant ⇒con in RTL
Nput: Extended Cfg For M (G), Assertion A
Output: Set of lines Ca covered by a according to correctness based coverage definition 1: Btop ←ConstructV alueTable(G, a) {Execution phase: Construct a tree of value
Tables For N Cycles And Record Triggers}
2: Ca ←ExtractCoverage(G, Btop) {Coverage extraction phase: Find coverage of a
Execution Phase
In this phase, we execute the RTL for k cycles starting with the information in a (Procedure 4). In this process, we record the following information: • We construct ∥V ∥×k tables of values of variables in k cycles. In particular the entry B[v, i] in a value table B contains the value of variable v in cycle i.
In other words, a value table is a table of propositions (variable-value pairs) in each of the k cycles. Multiple value tables correspond to different pos- sible values of conditions corresponding to the decision nodes encountered during execution that cannot be evaluated to true or false.
• Apart from value tables, we also record triggers for each decision or assign- ment node that is visited. Triggers for a decision node are assignment nodes that make the decision true. Triggers for an assignment node include other assignment nodes which affect it and decisions nodes on which it depends.
When an assignment node n : (v <= rhs) is encountered during execution, the value table B is updated with the value rhs if it is a constant. If it is not a constant, assignments to rhs encountered thus far are added to the set of triggers of n. The decision nodes on which this assignment depends are also added to the set of triggers of n. Essentially, these are the decision nodes that lie on the path in the CFG from n to a top-level node.
When a decision node n is encountered, we attempt to evaluate the condition in n using the values available in B. If it evaluates to true, we update its triggers and take the true branch in the CFG. If it evaluates to false, we take the false branch without updating the triggers. If the decision is unknown due to a lack of sufficient data in the value table, we split B into Bleft and Bright corresponding to the true and false evaluations of n, respectively. As a result, at the end of the execution phase, we obtain a tree of value tables rooted at Btop.
Procedure 4 Construct a tree of value tables rooted at Btop using assertion a and record
Nput: Extended Cfg For M (G), Assertion A
Output: Tree of value tables rooted at Btop, triggers recorded in G 1: Initialize(Btop, a) {Initialize root table of values (Btop) using a}
Overage Extraction Phase
In the coverage extraction phase (Procedure 5), we look at each leaf B of the tree of value tables in turn. If vout is assigned in cycle k in B and its value agrees with con, we have found a possible execution starting from ant that makes con true. We then include RTL lines for all nodes visited during this execution in Ca. We use the triggers recorded during the execution phase to traverse backwards recursively and obtain such nodes. This is implemented by the BackwardTraversal() procedure on line 7. Pseudocode for that procedure is not shown due to space constraints.
Procedure 5 Extract correctness based coverage from value table tree and triggers
Extractcoverage (G, Btop, A)
Input: Extended CFG for M (G), tree of value tables rooted at Btop, assertion a : ant ⇒
Con
Output: Set of lines Ca covered by a according to correctness based coverage definition
: Let P : (Vout, Val) ←Con
3: for all Leaf tables B in tree rooted at Btop do
:
{Value of vout exists and matches the consequent of a}
: End For
Our correctness based coverage computation technique is guaranteed to find all statements such that erroneous execution of these statements causes the assertion to fail during formal verification. In some cases, our technique can report a state- ment as covered, but no mutation to that statement can cause the assertion to fail formal verification. This can only happen in the following two situations: 1. The mutation causes the assertion to be vacuously true. In this case, due to the injected mutation, the antecedent of the assertion never evaluates to true.
2. The mutation is masked by the logic and fails to affect the consequent and hence the correctness of the assertion. In these situations, our technique computes a superset of the target result set of the assertion.
Table 3.1: Number of lines of RTL code, number of RTL statements and the number of assertions written for each module under consideration.
Experimental Results
In this section, we evaluate our correctness based coverage computation technique on a USB 2.0 protocol design and the OpenRISC processor design both from . We demonstrate the simulation based correctness computation technique on an industrial design in Chapter 5, where we apply it to solve the problem of coverage In the USB design, we consider the packet assembler (usbf pa), the packet disassembler (usbf pd), the protocol engine (usbf pe) and the internal DMA engine (usbf idma) modules which form the protocol layer along with the wish- bone interface module (usbf wb). We consider the data cache controller (or1200 dc fsm) and the exception unit (or1200 except) from the Open- RISC design. All experiments were performed on an Intel Core 2 Quad with 16GB RAM. Cadence Incisive Formal Verifier was used as the formal verifier.
Table 3.1 shows the number of lines of code and the number of RTL statements relevant for code coverage for each module considered. The statements include assignments and if and case conditional statements. For each of the seven modules, we manually wrote 3 to 5 assertions spanning up to 7 cycles for a total of 27 assertions. All assertions were formally verified against the corresponding design modules.
For each assertion, we extracted the set of statements covered according to the correctness based definition. Covered statements were mutated and the assertion was run through the formal verifier again along with the mutated designs. Follow- ing mutations were injected for each type of statement: if conditions: The condition was negated, or in other words, the true and false branches were flipped.
case conditions: Code block corresponding to one case was interchanged with that for another case. Assignments: Right hand side of the assignment was changed, e.g. b = 0 was changed to b = 1.
Table 3.2 shows detailed results for all assertions considered in this experiment. Time and memory usage for coverage computation of every assertion is shown. We also give the maximum depth of the value table tree constructed during the execution phase (Section 3.5.1). Finally, we show the number of statements cov- ered and number of statements such that a mutation injected at the statement is detected, or in other words, the assertion fails formal verification with the mutated design.
Recall that the value table tree depth is determined by the number of unknown decisions encountered during the execution phase. The memory usage of coverage computation can be attributed mainly to the CFG and the value table tree. As the value table tree depth increases, the value table tree contributes towards most of the memory usage. The current implementation of coverage computation is such that the size of the value table tree is exponential in its depth. As a result, we can see that for a given module, the total memory usage also increases exponentially with the value table tree depth. For example, in the case of usbf pa, the memory usage increases from 361 kB for value table tree depth of 1 (a3) to 1.24 GB for value table tree depth of 14 (a4). In the future, we aim to make the value table tree implementation more efficient and avoid this exponential memory cost.
The memory usage of coverage computation for a module averaged over all assertions is found to increase with the size of the module. This can be attributed to the larger CFG and value tables for larger modules with higher numbers of variables.
Runtime of coverage computation also behaves in a way similar to memory usage in that it increases with the size of the module and for a given module, with the value table tree depth.
It can be seen that on average, only about 8% of total statements were reported as covered by each assertion, which shows that our technique can effectively find the statements truly relevant to the correctness of an assertion.
For every assertion, mutations at almost all covered statements were detected. On careful analysis of the source code with the assertion, we find that the muta- tions are not detected in only the situations mentioned in Section 3.5.
Table 3.2: Results for each of the 27 assertions. Column three gives the length in number of cycles of each assertion while column four gives the maximum depth of the value table tree during coverage computation for that assertion. The time and memory usage during coverage computation and the number of statements covered are shown in the next three columns. Number of statements such that the mutation injected in the statement was detected is shown in the last column.
Authors:
Peder EZ Larson 1, 2,* , Jenna ML Bernard1, James A Bankson 3, Nikolaj Bøgh 4, Robert A Bok1, Albert P. Chen 5, Charles H Cunningham 6,7, Jeremy Gordon1, Jan-Bernd Hövener 8, Christoffer Laustsen 4, Dirk Mayer 9,10, Mary A McLean11 12, Franz Schilling13, James Slater1, Jean-Luc Vanderheyden5, 14, Cornelius von Morze 15, Daniel B Vigneron1, 2, Duan Xu1, 2, and the HP 13C
94143, Usa.
Denmark. 5 GE Healthcare, Menlo Park, California, USA. 6 Physical Sciences, Sunnybrook Research Institute, Toronto, Ontario, Canada.
8 Section Biomedical Imaging, Molecular Imaging North Competence Center (MOIN CC), Medicine, Baltimore, MD, USA. Cambridge, United Kingdom.
14Jlvmi Consulting Llc, Dousman, Wi, Usa
#See Acknowledgements for a list of all HP 13C MRI Consensus Group Members This work was supported by the ISMRM Hyperpolarized Media MR Study Group, the ISMRM Hyperpolarization Methods & Equipment Study Group, and the Hyperpolarized MRI Technology Resource Center (NIH/NIBIB grant P41EB013598).

Abstract
MRI with hyperpolarized (HP) 13C agents, also known as HP 13C MRI, can measure processes such as localized metabolism that is altered in numerous cancers, liver, heart, kidney diseases, and more. It has been translated into human studies during the past 10 years, with recent rapid growth in studies largely based on increasing availability of hyperpolarized agent preparation methods suitable for use in humans. This paper aims to capture the current successful practices for HP MRI human studies with [1-13C]pyruvate - by far the most commonly used agent, which sits at a key metabolic junction in glycolysis. The paper is divided into four major topic areas: (1) HP 13C-pyruvate preparation, (2) MRI system setup and calibrations, (3) data acquisition and image reconstruction, and (4) data analysis and quantification. In each area, we identified the key components for a successful study, summarized both published studies and current practices, and discuss evidence gaps, strengths, and limitations. This paper is the output of the “HP 13C MRI Consensus Group” as well as the ISMRM Hyperpolarized Media MR and Hyperpolarized Methods & Equipment study groups. It further aims to provide a comprehensive reference for future consensus building as the field continues to advance human studies with this metabolic imaging modality.

Keywords: Hyperpolarized MRI, metabolic imaging, carbon-13, pyruvate, dissolution dynamic
Introduction
MRI with hyperpolarized 13C agents, also known as hyperpolarized (HP) 13C MRI, has shown great potential as a novel imaging modality, particularly for its ability to probe metabolic processes in real time. The first human studies with HP [1-13C]pyruvate were performed in 2011 in prostate cancer patients (1).

Since then, there have been over 60 papers published with imaging results of human subjects from 13 different sites, with applications including prostate cancer, brain tumors, breast cancer, kidney cancer, pancreatic cancer, metastatic disease, liver disease, ischemic heart disease, diabetes and cardiomyopathies. The vast majority of these studies used [1-13C]pyruvate (1–63), where [2-13C]pyruvate (64) and 13C-urea (56) have been demonstrated too.

As clinical HP 13C MRI advances, there is a growing need to build consensus for best practices, which are critical for comparing data across sites, performing multi-site trials,deploying methods to new sites, partnering with vendors, and potentially for obtaining broader regulatory approvals.

In March 2022, we initiated an effort to build consensus within the HP 13C MRI community with this opportunity in mind, and it was greeted with strong enthusiasm. The “HP 13C MRI Consensus Group”, containing over 55 members from 27 sites, identified the area of greatest need and opportunity for consensus building to be HP [1-13C]pyruvate human
●
Pyruvate is the most mature and widely used HP agent and has the most significant translational evidence emphasizing the potential clinical impact.
●
Clinical trials, particularly multi-site trials, have the strongest need for consensus methods to ensure that data can be combined across sites. This work is a Position Paper for which the goal is to describe current successful practices and study methods for HP [1-13C]pyruvate human studies along with justification to support those practices. This is divided into four major topic areas: (1) HP 13C-pyruvate preparation, (2) MRI system setup and calibrations, (3) data acquisition and image reconstruction, and (4) data analysis and quantification (Fig. 1). The current successful practices and study methods include a literature review of published peer-reviewed journal papers showing human HP [1-13C]pyruvate study data, up to September 2022 (1–63), as well as new unpublished information from surveys of HP 13C study sites. Based on this information, we also highlight the evidence gaps, strengths, and limitations of current practices which are summarized at the end of each section.

Figure 1: Illustration of the HP 13C MRI human study process, including the 4 major areas covered in this paper: Hyperpolarized 13C-pyruvate preparation, MRI system setup and calibration, Acquisition and Reconstruction, and Data Analysis and Quantification.

Figure 2: Anatomical targets of HP [1-13C]pyruvate MRI human studies published up to September 2022.
Hyperpolarized 13C-Pyruvate Preparation
This section covers the processes for creating the HP agent, 13C pyruvate, and will include many aspects and considerations that are needed to safely and effectively prepare doses for metabolic imaging studies in human subjects. These include material, personnel, equipment and facility, fluid path preparation, quality control, and release.

It is helpful to understand that the specifications of a dose of 13C pyruvate suitable for in vivo MR HP metabolic imaging were shaped in part by early preclinical studies performed by GE HealthCare summarized in Ref. (65). In short, the safety of the two novel drug components, 13C pyruvate and the electron paramagnetic agent (EPA) AH111501, were demonstrated in those studies. The more precise formulation of the dose suitable for human use was then determined from clinical studies (66) that included two Phase 1 clinical trials in young and elderly healthy volunteers without hyperpolarization of the 13C nuclei and another Phase 1/2a dose escalation and imaging feasibility study with HP 13C pyruvate in 31 prostate cancer patients at the With the exception of the first HP 13C imaging clinical trial, which utilized a prototype device in a cleanroom (1), all HP 13C studies performed in humans to date have utilized the SPINlab polarizer (manufactured by GE HealthCare). Consequently all doses of the HP 13C pyruvate delivered by SPINlab have been produced using the “SPINlab Pharmacy Kit” that serves as the container-closure system for the various drug components (13C pyruvic acid and EPA mixture, dissolution medium, and neutralization and dilution medium) during sample polarization, dissolution and quality control (QC) processes. Thus many aspects of the HP sample preparation considerations discussed below are related to the SPINlab instrument and the consumables designed to be used with it (67).
General Considerations
While more than 860 patients or healthy subjects having been injected with HP 13C pyruvate as of January 2022 without reports of any serious adverse events (68), HP 13C pyruvate injection remains an investigational MR contrast agent and can only be administered by those with Investigational New Drug (IND) exemption from the Food and Drug Administration (FDA) in the USA, a Clinical Trial Application (CTA) in Canada, approval from National Research Ethics Committee Services in the UK, or approval from the relevant local regulatory body. Thus, methods and processes involved to produce a dose should have patient safety as the first priority. Since utilizing dissolution dynamic nuclear polarization (dissolution-DNP) for human use is still a relatively new development, there are no existing published regulatory guidelines specifically for this method.
There are two major production styles that determine how various sites approach the agent preparation. In the US, the most common approach is to rely on a sterilizing filter (“Terminal Sterilization”) to ensure sterility of the final product, akin to PET tracer production, where a starting molecule with a radioisotope is processed using various other ingredients to make the final, desired and injectable contrast agent within a necessarily short amount of time (69). For these sites, sterilization of the components and accessories upstream of this filter are not required, although many of them were manufactured and tested following Good Manufacturing Practice (GMP) or Good Laboratory Practice (GLP) requirements. The filling process is usually performed under an ISO 5 laminar flow hood, but a clean room or an isolator is not required.
This approach is typically accompanied by testing the integrity of the sterilizing filter prior to release of the dose for injection. Typically, post release endotoxin and sterility tests are performed using an aliquot reserved from each released dose.
In the UK and EU, the most common approach is to more-closely follow sterile pharmaceutical compounding guidelines (70), where all components and ingredients are required to be sterile or manufactured under GMP guidelines and are assembled and filled within a clean room environment or an isolator system (“Sterile Preparation”). Typically a batch of Pharmacy Kits for HP 13C pyruvate injection are prepared together. The sterility of the final dose is also ensured by batch validation testing, in addition to the sterility of the ingredients and the sterile compounding process. The endotoxin and sterility testing are performed for the process validation but are not performed for each injected dose.
Some institutions fill and assemble the Pharmacy Kit required for a specific study on the same day or the day prior to polarization, dissolution, and patient administration, but others have also demonstrated the feasibility of preparing a batch of kits, keeping them in a -20ºC freezer and using them over a period of a few months.
Beyond the obvious requirements that the process and the facility has to ultimately produce a dose that is safe to inject into a human, regulatory authorities will also focus on the question “Are you in control of your processes?”. To be in control of your process requires an in-depth and broad understanding of all processes involved in pre, post, and during the production process.
Personnel
It is typical and may be required to have licensed personnel involved in the production process depending on local regulations.Typically a pharmacist, radiopharmacist or other similarly qualified person (QP), in charge of the facility where the Pharmacy Kit filling and preparation is taking place, is responsible for the overall process and the release of the injectable dose.
Qualified cleanroom technicians are often involved in the Pharmacy Kit filling under the supervision of the pharmacist or QP. As is required for pharmaceutical compounding or PET tracer production, training requirements and training records for all personnel need to be maintained and available for audit by the FDA or equivalent.
Equipment And Facility
The facility and all equipment need to have standard operating procedures (SOPs) that describe how equipment is used, maintained, and calibrated to comply with relevant legislation. Currently, almost all the filling of the Pharmacy Kit takes place within a compounding laminar flow hood or isolator (typically ISO 5). At some sites, the filling is conducted within a cleanroom, while at others, it is conducted in a dedicated non-cleanroom space, reflecting differences in cleanroom approach and specifications between regulators worldwide (71). Some equipment or facilities, such as the compounding hood or cleanroom, may require external certified laboratories for testing.
Material Handling
Material handling guidelines (69,70) require SOPs detailing a system to track all of the materials involved in the HP production process for a particular patient dose, similar to current good manufacturing practice (cGMP) requirements for material handling for drug compounding. This includes acceptance standards, storage conditions, amount used in the patient dose for each ingredient and materials used in the assembly of the fluid path and Pharmacy Kit. Currently some users choose to open and inspect and sometimes modify the Pharmacy Kits upon arrival, but some users keep them in the sealed packaging until they are required for dose preparation.
Pharmacy Kit Filling And Assembling
As required by an IND or its equivalent, the preparation of the doses of HP 13C agent are detailed in the Chemistry, Manufacturing, and Control (CMC) section of an applicable regulatory submission; an example of this has been made available (72). It describes the processes of filling the Pharmacy Kit with the different components that make up the final drug product, and of assembling the final kit for either storage or immediate use in the polarizer. Special attention should be given to the laser welding process in order to satisfy installation qualification (IQ) and operational qualification (OQ). Typically, the final developed process is validated by process qualification (PQ) runs, during which 3 or more Pharmacy Kits are filled and used and the final HP 13C products are tested for endotoxin and sterility and to confirm that they meet the dose specifications for injections (usually including pyruvate concentration, residual EPA concentration, pH, liquid state polarization level and dose temperature). The data from 3 consecutive PQ runs are submitted as part of the IND submission (or its equivalent), and are often also reviewed by the Institutional Review Board (IRB) where the studies are conducted.
Quality Control And Dose Release
The quality control (QC) and dose release can be separated into two aspects: one is the QC and release of the filled Pharmacy Kit, and second is the QC and release of the HP 13C agent for injection, after polarization and dissolution. For institutions filling a batch of kits and storing them to use over a period of time, typically the batch can be released based on initial validation, environmental monitoring data from the day of kit production, and if filters are used during preparation of any of the components, filter integrity testing. But in some cases one or more kits are used for validation before the batch of kits are released for future use. For institutions that fill only the kits required for specific studies shortly before the experiment, the filled kits often do not go through separate release tests before they are used.
The quality control of the HP 13C pyruvate solution post dissolution is primarily performed to ensure that the agent meets the dose specifications (Table 1) before it is administered to the subject. These specifications target both safety (pH, residual EPA, temperature) and efficacy (pyruvate concentration, polarization, volume). Typically, the pyruvate concentration, residual EPA concentration, pH, dose temperature, dose volume, and liquid state polarization are measured by the QC accessory associated with the SPINlab polarizer. Some users perform a secondary measurement for one of the parameters, such as pH, using a different instrument or pH paper. For sites that do not go through a separate release testing process for batch filled kits, the integrity of the sterilization assurance filter, a part of the Pharmacy Kit, is typically tested as a part of the dose release. It is also common for these users to preserve an aliquot of the final HP 13C pyruvate solution for post-release endotoxin and sterility testing. This testing cannot be completed fast enough to test an individual dose prior to injection, but this is why other processes such as PQ runs and validation testing are done to minimize the chance a subject could be injected with a contaminated dose.
The Final Dose Release And Injection
should be done under the supervision of a licensed professional, based on local regulations.
Some Key Challenges
Many of the challenges associated with HP 13C pyruvate preparation can be attributed to the conditions required for the dissolution-DNP method of high magnetic field (~3-7 T) and very low temperature (~1 K) during polarization, with pressurized and superheated water necessary for the rapid dissolution event. These extreme conditions are quite challenging for the design of the container-closure and fluid path system. In particular, the cryogenic temperature in the polarizer requires special attention to any moisture or ambient (moist) air introduced into that portion of the fluid path, which can form an ice block at ~1 K. This ice can lead to flow restriction during the dissolution event and reduce the strength of the laser welded bond between the cryovial and its cap. This can ultimately produce failures in the dissolution step, including variations in final pyruvate concentration and pH that may fail to meet QC release criteria as well as fluid path ruptures that provide no available dose and result in polarizer down-time.
The polarization of the HP 13C pyruvate sample decays quickly over the span of a few minutes after dissolution, and thus the process of dissolution, QC for release, and injection should be completed as fast as possible to preserve the high polarization level achieved. Any delays in the preparation process, such as transportation time or equipment malfunction, can significantly reduce the final polarization and result in lower quality imaging data.
Current Practices
A summary of data collected from all sites performing clinical trials with HP 13C-pyruvate is shown in Fig. 3 and Table 1, including the specification of the final dose and how the quality control and release of the final dose are performed. There is a split in the Production Style, described in the General Considerations section above, with 8/13 sites using Sterile Preparation versus 5/13 using Terminal Sterilization. While many of the dose specifications show notable differences in acceptable ranges, all of these variations listed in tables have been successfully and safely been used to perform HP 13C pyruvate studies in humans. Their differences depend on the institutions’ preferences, resources and their particular regulatory situation. There is high similarity in pyruvate ranges, temperature ranges, EPA limits, and volume limits. There is modest variability in pH ranges and large variability in the endotoxin test limit. There is a 3-fold difference in acceptable polarization levels, which are measured to ensure a futile dose is not injected since the polarization is directly proportional to SNR. This reflects the decision by several sites to believe that useful data can be still be obtained with suboptimal polarizations.
Figure 3: Hyperpolarized agent preparation methods reported by sites currently performing HP
In House
Table 1: HP 13C-pyruvate preparation parameters, methods, and dose specifications used for quality control testing and release as well as validation. These were obtained from a survey of all sites performing clinical trials with HP [1-13C]pyruvate. The parameters used for product release are noted in bold text, otherwise these parameters are measured for batch validation or other QC measurements. The endotoxin and sterility testing are performed during process validation of the batch and/or post-injection, and largely depends on the agent production approach.
Summary
The overall safety record of HP 13C-pyruvate has been very strong, and the SPINlab hyperpolarizer has proven to provide high polarizations at human sized doses while meeting numerous QC and release criteria. A weakness remains the failure modes of the SPINlab Phamacy Kits (e.g. ice blocks, path ruptures), which are placed under extreme requirements particularly during dissolution. The preparation process still requires a high degree of expertise.
Therefore, there is a significant need to improve the reliability, robustness, and ease of operation for generating HP 13C-pyruvate doses for human studies. Furthermore, there is a divide between manufacturing and sterile compounding style preparation as well as other site-specific practices, resulting in variations in SOPs and justification required to relevant regulatory bodies. There have also been no comparisons between these approaches. It is also unclear what release criteria and QC parameters are truly required to ensure patient safety.
However, all of the reported methods are acceptable and approved by the appropriate regulatory authorities, and have led to the rapid expansion of successful human studies in recent years.
Mri System Setup And Calibrations
This section covers the MRI system setup, including the imaging system, RF coils, phantoms, and prescan calibration methods.
Imaging System
The main prerequisite for a given MRI scanner to be capable of supporting studies with HP 13C is its “broadband” capability to transmit and receive radiofrequency (RF) signal at the frequency of 13C, which is around 4 times lower than 1H. This does not come as a default on clinical MR devices. The transmit power of the broadband amplifier should also be sufficient to support the intended flip angle and RF pulse shape with the employed transmission RF coil(s) for 13C. Most studies to date use relatively low flip angles (< 90 degrees) for HP 13C in order to preserve polarization for time-resolved imaging. The capability to receive 13C signal on multiple channels is also desirable to increase SNR, as discussed further in the “RF coils” section.
The choice of magnetic field strength is primarily dependent on the metabolites’ frequency separation due to chemical shift dispersion and 1H imaging. High field strengths do not enhance hyperpolarized 13C signal as they do for 1H because the signal strength in a HP experiment relies on manipulating the population of quantum energy states outside of the MRI scanner.
However, the injected HP 13C-pyruvate and its metabolic products have greater frequency separation at higher fields, and it may thus be easier to separate and quantify these resonances at higher fields. This comes at the cost of a reduction in the achievable T2* and often reduced T1. As the initial polarization is independent of the imaging field strength it has been proposed that the increased T2* at 1.5T can potentially be exploited to increase SNR by adapting the acquisition bandwidth or reduce off-resonance imaging effects in cases when the decay of the transverse magnetization is dominated by T2* (73). In practice, 3T has been used in all published human 13C-pyruvate studies surveyed (Supporting Table S1), and comprises the majority of scanners currently in use for human studies (Table 3). A field strength of 3T is well-suited for 1H MRI anatomical reference and correlative imaging.
Stronger and more rapidly slewing magnetic field gradients support more rapid spatial encoding, particularly for metabolite-specific single-shot imaging using echo-planar imaging (EPI) or spiral imaging (See “Acquisition and Reconstruction”). Although the spatial resolution acquired for HP 13C imaging is typically much coarser than for 1H MRI, the factor of ~4 in gyromagnetic ratio leads to the same reduction factor in performance of the gradient system, so 13C experiments are potentially more limited by gradient hardware performance. To date, all human studies have used the commercially-available integrated gradient systems provided in clinical MRI scanners.
Optimization of scanner design has understandably focused on minimization of artifacts in 1H MRI, where devices such as room lights, the gradient amplifiers, and the motors driving the patient bed are checked to ensure that they do not produce RF interference at the 1H frequency, but artifacts may arise at other frequencies. Eddy current compensation is also not always appropriately adjusted for nuclei at other frequencies (74). In order to optimize for 13C, many sites have performed checks on phantoms for RF interference, gradient artifacts, and eddy currents (74), including the use of post-hoc gradient impulse response function characterisation and correction, and some vendors have fixed these issues as well.
Rf Coils
For HP 13C imaging studies in humans, RF coils for both 1H and 13C nuclei are needed, with 1H MRI providing an anatomical reference for registration and optional additional multiparametric MRI readouts. At the Larmor frequency of 13C nuclei, the relative contributions from coil noise compared to sample noise increase compared to 1H (73,75), although sample noise still is likely the dominant contributor for human-sized coils at 32.1MHz - the resonance frequency of 13C nuclei at 3T.
The key requirement for human 13C-pyruvate RF coils are that the coil geometry and sensitive volume must cover the volume of interest in the subject. Table 2 and Figure 4 shows coil configurations that have been used and optimized for applications in different anatomic regions.
Volume resonators are most commonly used for transmit, as they surround the subject to
Provide B1 Transmit Across The Fov (B1
+). While 1H relies on a large birdcage (“body”) coil built into the scanner, 13C transmit coils must be placed inside the bore. This takes up valuable space within the magnet, and also has led to the use of designs with relatively inhomogeneous
B1
+. Many human studies have used Helmholz pair resonators for transmit, including the “clamshell coil”, which has a notably inhomogeneous B1
+ Profile But Has Been Used Because Of
relatively easy integration into the scanner bore. B1
+ Variation Results In Variations In The Flip
angles that control the use of the hyperpolarized magnetization and creates errors in common HP metrics (9,76). The exception are head coils, where birdcage designs with highly
Homogeneous B1
+ can be placed around the head while easily fitting inside the bore. As with 1H MRI, higher SNR can typically be achieved by smaller receive coil elements, such as surface coils or phased arrays, and the majority of 13C receive coils used have layouts similar to 1H phased arrays.
RF coil quality control is important to ensure proper functioning of the coils to provide consistent imaging quality, especially with limited natural abundance 13C signal in vivo. It typically involves 1) a physical integrity check of the coil cables and connectors and 2) phantom SNR tests to check the coil’s performance and to monitor it over time (see Phantoms below). An useful reference for RF coil quality control is outlined in the MRI accreditation program of the American College of Radiology (77) and can be adapted for 13C coils.
Notably, configurations for brain and prostate studies used dual-tuned 1H/13C coil designs, which greatly simplify workflow and registration of 1H and 13C images, as no switching of coils is needed.
Table 2: RF coil configurations reported for human HP [1-13C]pyruvate studies.
Tx = Transmit
coil, RX = receive coil. The commonly used “clamshell” TX coil is a Helmholz pair design. For 1H RF configurations, all used the Body coil for TX unless otherwise noted, and “repositioned” indicates the 13C coil was removed for 1H imaging. One representative reference is listed for each configuration. The RF coil configurations reported in the reviewed papers are shown in Supporting Table S1.
Figure 4: Examples of RF coil configurations used for human HP [1-13C]pyruvate brain studies. (A,B) 13C Clamshell TX (Helmholz pair) and 2× 4-channel paddle RX arrays. (C) 13C Birdcage volume TX and 32-channel RX array (RX array slides into TX coil). (D) 13C Birdcage volume TX and 24-channel RX array, combined with a 1H 8-channel RX array. Image reproduced with permission from Ref (16).
Phantoms
Since hyperpolarized magnetization is non-renewable, phantoms containing 13C nuclei are important to: 1) test the multi-nuclear capabilities of the imaging system, including all parts of the signal excitation and receive chain; 2) perform calibration measurements before a scan with hyperpolarized nuclei; and 3) perform necessary pre-scan adjustments (see “Prescan Calibration” section). The phantoms currently in use are listed in Table 3. Their composition must provide sufficient 13C signal, with additional considerations of conductivity, stability, chemical shift(s) present, potential for dynamic imaging, and cost. The phantom geometries are typically either compact, in order to be used alongside the subject during a HP scan, or large enough to mimic the inner volume of a RF coil for system testing.
One popular compact design contains enriched 13C-urea at high concentration, typically 8 M, which provides a single resonance, placed inside a small container ~1 mL. The most common recipe mixes 13C-urea in a 90% water/10% glycerol solution, with glycerol used to increase the urea solubility and doping with a Gd-based contrast agent to shorten T1 which increases the potential SNR per unit time. For example, when Dotarem is added at a 3:1000 volume ratio the 13C-urea T1 is around 500 ms and T2 is around 100 ms. However, when testing pulse sequences influenced by T1 and T2, doping should be used carefully. This phantom is suitable for frequency calibration, transmit gain calibration, sequence testing, and as a fiducial marker when placed next to a patient. However, enriched 13C-urea has a relatively high cost compared to natural abundance compounds.
For larger volumes (>100 ml), the phantoms most often used contain undiluted ethylene glycol, glycerol, or dimethyl silicone. These compounds have sufficiently high carbon concentrations to provide sufficient 13C signal even with the 1.1% natural abundance of 13C. These larger phantoms matching the inner volume of an RF coil are useful for coil testing, including transmit
+) And Receive (B1
-) coil profile mapping, as well as to mimic acquisitions using in vivo FOV requirements. In this case, size and conductivity should match the expected subject size in order to mimic coil loading and get a realistic estimation of B1+. Large-volume natural abundance urea phantoms have also been used by some sites, but suffer from higher conductivity compared to biological tissues. Typically, it is easier to increase the conductivity and hence coil loading of the non-conductive phantom by adding NaCl to match physiological loading (16,78).
Dynamic phantoms that aim to mimic metabolite kinetics have also been developed (79–81), and have the potential to more closely mimic the HP experiment, but so far these are not widely used.
Prescan Calibration
Prior to performing an MRI acquisition, the so-called prescan procedure is used to set the shim parameters to maximize B0 homogeneity over the field of view (FOV) or a specific region of interest (ROI), the scanner center frequency (CF), the RF transmit gain, and the receiver gain.
While this calibration procedure is usually automated for 1H, the lack of sufficient natural abundance 13C signal prevents use of automated methods. (Although natural abundance 13C lipid signal has been detected, there are so far no reports on using this signal for prescan.) Table 3 shows current practices across sites.
Maximizing B0 homogeneity is independent of the nucleus and is therefore performed prior to 13C imaging using the 1H water signal and existing shimming tools, such as by a standard automated process (“Auto Shimming”) or using high order shimming routines. Similarly, the 13C CF can be calculated from the 1H CF using a predetermined scaling factor that depends on the target chemical shift (82). Another common approach used is to have a small, high-concentration 13C phantom, e.g. 8M 13C-urea, integrated in the RF coil or placed next to the scan subject (1). The reference frequency can also be based on real-time measurements after the HP injection but prior to imaging (83). Both the CF and B0 shimming are critical when using spectrally-selective RF pulses, as inmetabolite-specific imaging methods, where the desired excitation bandwidths are typically very narrow and frequency offsets can lead to a failure mode that is only apparent after injection.
The calibration of the RF transmit power is typically performed on a small, high-concentration 13C phantom placed near the region of interest during the scan or on a large 13C phantom of similar size and coil loading as the subject, prior to the subject scan. Reference power is often done by sweeping the power in a pulse-acquire sequence (53,62), or the Bloch-Siegert method (52,84). When using a small phantom, the location of the phantom, B1
+ Inhomogeneity As Well
as any shielding effects, e.g., when the phantom is integrated into a coil (1), may degrade the accuracy. Other methods include real-time Bloch-Siegert method measurements after the HP injection (83), and using the stronger natural abundance 23Na signal that is close enough to the 13C resonance frequency to be detected by 13C coils (82).
The receiver gain is predetermined, either systematically based on independent phantom measurements and assuming the dose and polarization of the HP compound is known prior to injection, or based on past HP imaging studies.
Power [Kw]
Phantom(s) - during study Phantom(s) - before study 13C Frequency
13C-bicarbonate doped with dimethyl silicone, various
Maximum Values
Table 3: Summary of the imaging systems, phantoms, and prescan procedures used at sites currently performing HP 13C-pyruvate human studies. These were obtained from a survey of all sites performing clinical trials with HP [1-13C]pyruvate. *Previously performed studies with a Siemens 3T Tim Trio. The imaging systems, phantoms, and prescan procedures reported in the reviewed papers are shown in Supporting Table S1.
Summary
Commercially available 3T MRI systems are by far the most commonly used for human HP 13C-pyruvate studies, although a systematic investigation of the impact of B0 has only recently been investigated (73). The multi-nuclear RF transmit and receive chain has proven sufficient for current acquisition strategies, although many sites have observed artifacts due to RF interference, gradient interference, and residual eddy currents when operating at the 13C frequency. A variety of 13C RF coils, tailored for numerous anatomical targets, have been successfully demonstrated, with the main limitation that most transmit coils take up a lot of additional space inside the bore and provide relatively inhomogeneous B1
+ Profiles. The
phantoms used have converged into generally 2 categories - small phantoms containing 13C-enriched compounds that can be used during the study and human-sized phantoms containing compounds with high carbon concentrations but without 13C enrichment that are used to test and calibrate the coils. There are no standardized compositions or geometry, and dynamic phantoms that recapitulate in vivo kinetics would be desirable but are still an emerging area. Prescan calibration procedures were not well defined in most publications, so we surveyed individual sites to determine current practices. Calibration procedures for the B0 field (13C CF and shimming) for most sites take advantage of 1H signal and methods, while methods
For Calibration Of B1
+ is more variable across sites, likely a reflection of remaining challenges in how to perform this calibration. Standardization of both phantoms and calibration procedures would synergistically improve the robustness and reproducibility of HP 13C studies.
Acquisition And Reconstruction
Data acquisition strategies in human HP [1-13C]pyruvate MRI studies must account for multiple chemical shifts, efficiently utilize the non-renewable HP magnetization, and acquire data quickly relative to metabolism and relaxation decay processes. These studies require spectral encoding to separate metabolites, necessitating pulse sequences that efficiently encode up to 5D data (3 spatial + 1 spectral + 1 temporal dimension). RF pulses must efficiently sample without immediately saturating the non-renewable HP magnetization, and sequences must acquire data quickly and be robust to both experimental and physiologic variation (e.g. B1
+ Inhomogeneity,
variation in perfusion) to ensure reproducibility and minimize scan-to-scan variability. This section covers current successful practices for data acquisition in human [1-13C]pyruvate studies, and accompanying 1H imaging, from different anatomic regions, including scan parameters and image reconstruction.
Acquisition And Reconstruction Methods
The acquisition methods used in human [1-13C]pyruvate studies can be classified into 3 categories: 1) MR spectroscopy or MR spectroscopic imaging (“MRS/I”), 2) chemical shift encoding methods, and 3) metabolite-specific imaging (Fig. 5).
Mrs/I Methods Specifically
resolve a spectrum that can be analyzed to extract expected as well as unexpected resonances, making this approach very robust. It was used in many initial studies (1).
Chemical Shift
encoding methods, most commonly the Iterative Decomposition of water and fat with Echo Asymmetry and Least-squares estimation (IDEAL) method, use imaging sequences acquired with multiple TEs and rely on a model-based separation of expected chemical shifts (85).
Metabolite-specific imaging methods use specialized RF pulses that are spatially and spectrally selective to excite individual metabolites which are then typically imaged with fast k-space trajectories such as echo planar imaging (EPI) or spirals (86).
Their Application To Different
organ systems is described below. The image reconstruction methods used in human [1-13C]pyruvate studies have typically been conventional methods (e.g. FFT, non-uniform FFT, or equivalent). The incorporation of accelerated imaging and advanced reconstruction methods including parallel imaging (4,57,87) and compressed sensing (7) has also been applied in human studies for improved spatial resolution, temporal resolution and coverage, but have the potential for additional artifacts as well as SNR losses due to ill-conditioning of the reconstruction (e.g. g-factor).
The Majority Of
published studies do not use accelerated imaging indicating the resolution and coverage achievable without acceleration is currently adequate for successful data collection. Performing coil combination, even with fully sampled data has also been shown to have specific challenges for HP human images: using naive sum-of-squares methods suffer from high noise amplification in the relatively low SNR regime of HP [1-13C]pyruvate (compared to 1H), motivating several HP 13C-specific methods that include data-driven coil sensitivity estimation which have shown obvious improvements over sum-of-squares (11).
More recently denoising techniques have been applied as post-processing of human HP data(41,42,44). The techniques applied are based on spatial-temporal singular value decomposition for unsupervised estimation of signal and noise components. They have shown improvements in apparent SNR in the brain and liver, while care must be taken to choose parameters such as the rank threshold to avoid oversmoothing and overfitting to the estimated signal components.
Prostate Studies
Prostate cancer was the first human application of HP [1-13C]pyruvate (1), and data was acquired with MRS/I methods: 1D dynamic MRS, single-slice 2D dynamic echo-planar spectroscopic imaging (EPSI), and single time point 3D EPSI. Advances in imaging strategies led to the development and application of new acquisition schemes, including undersampled 3D EPSI with compressed-sensing (7), model-based chemical shift encoding methods that use a priori information (47,59), and metabolite-specific EPI (10), all of which can provide volumetric whole-organ coverage and dynamic acquisitions.
The pyruvate bolus arrival in the prostate can vary by ± 10 s between patients, necessitating dynamic imaging to reliably and consistently capture the pyruvate bolus (18). For this reason, all currently ongoing studies acquire dynamic data. While MRS/I, chemical shift encoding, and metabolite-specific imaging can all achieve dynamic imaging, chemical shift encoding and metabolite-specific imaging provide greater dynamic and volumetric coverage (85). For scan prescriptions, the FOV is designed to provide full prostate coverage and typically to match the orientation of the anatomic imaging used for registration. Flip angles used in current studies are constant through time, as quantification with a variable-through-time flip scheme is highly sensitive to bolus timing (8) and errors in the RF transmit (B1 +) field (76).
Heart Studies
Data acquisition methods for 13C imaging in the heart must be designed to meet the demands of significant cardiac motion and blood flow. To cope with the periodic cardiac motion, most human heart studies to date used gating to the diastolic window, the longest cardiac cycle interval, which has reduced motion (2,22,28,30,35,36,38,45,52). The duration of the diastolic window limits the available data sampling time, making cardiac acquisitions the most time-constrained of the HP 13C MRI applications. The most common acquisition approach is metabolite-specific imaging with spiral k-space trajectories (2). Their single-shot imaging capability makes these methods particularly robust to motion effects. Furthermore, spiral k-space trajectories provide rapid k-space coverage and relatively benign flow and motion artifacts. The majority of studies have used 2D multi-slice acquisitions, but 3D encoding has also been used successfully (35).
Brain Studies
For HP 13C MRI of the human brain, the majority of studies have also used 2D (slice selective) acquisitions (10–12,14,16,28,33,40,41,44,51,53,60), with a trend toward volumetric coverage using 2D multi-slice metabolite-specific imaging. 3D metabolite-specific imaging of the whole brain, with phase encoding of the slice direction (34,57), has been shown to provide similar SNR efficiency (88) compared with multislice imaging. A number of studies have employed MRS/I (5,6,29,31–33,50,55) resulting in a spectrum from each voxel, which has the advantage of not requiring a priori information about which peaks to encode. This was important in early brain studies when it was not known which peaks would be detectable. Chemical shift encoding, using a set of images with different echo times and an iterative reconstruction of the individual resonances (i.e. the IDEAL approach (85)), has also been used (12,49,54), with the drawback that coverage in the slice direction was limited due to the time required to acquire multiple echo time images.
Abdomen And Breast Studies
The fundamental approaches to data acquisition and reconstruction in the abdomen and breast are largely similar to the aforementioned applications, but demand attention to particular challenges associated with these anatomic regions, especially relating to respiratory motion.
Although it has been shown that a basic 2D MRSI approach based on phase encoding and FID readout can be successfully applied for HP 13C imaging in breast (15) and kidney (13), major advantages in terms of spatiotemporal resolution and coverage have been realized using tailored approaches based on metabolite-specific imaging (43,62) and chemical shift encoding (43), which have facilitated multi-slice or 3D dynamic acquisitions over large FOVs in the abdomen (4,37,46).
The significant respiratory motion encountered in these regions can directly blur 13C images, and has further favored these rapid acquisition strategies. Motion also degrades B0 homogeneity, which can shift frequency-selective excitation profiles and introduce artifacts into rapid imaging readouts. This makes accurate determination of the acquisition center frequency and shimming essential in these regions which often cover large FOVs. (See “Prescan Calibration” section for more information). In some studies, breath-holding was used to minimize motion effects and enforce frame-to-frame data consistency (42). A pragmatic and reasonably effective approach for dealing with respiratory motion during 13C data acquisition is an initial breath-hold (as long as can be tolerated), followed by free-breathing (46,62).
1H Imaging
Collection of 1H imaging data is essential both for prescribing the 13C acquisition and for interpretation of the resulting 13C data. Multi-planar 1H scouts are acquired prior to 13C acquisition to enable graphical prescription of the 13C imaging region. All human HP 13C-pyruvate imaging studies acquire conventional MRI scans (e.g. T1- and T2-weighted volumes) for anatomic reference, aiming to cover at least the full 13C FOV. Acquiring these anatomic scans as close as possible to the time of 13C imaging (immediately before or after) minimizes potential misregistration between the data sets. Depending on the application, other advanced 1H sequences are also acquired (e.g. diffusion-weighted imaging for cancer imaging).
When contrast-enhanced data is acquired, it is done after 13C imaging, as paramagnetic contrast agents will accelerate 13C relaxation.
Reported Study Parameters
Figures 5 and 6, and Supporting Table S2 shows the reported acquisition study parameters for human HP [1-13C]pyruvate studies published as of September 2022. Figure 5 shows a mixture of MRS/I, metabolite-specific imaging, and chemical shift encoding methods have been successfully used, where spectroscopy-based methods have become less prevalent in recent studies. Figure 6 shows the acquisition timing, including the important start time and interval/temporal resolution, is quite variable across studies.
Figure 5: Acquisition methods used in published HP [1-13C]pyruvate human studies published up to September 2022, classified into: MR spectroscopy and spectroscopy imaging (MRS/I); chemical shift encoding methods, such as IDEAL, that use multiple TEs and model-based reconstructions; and metabolite-specific imaging methods that use spectrally-selective excitation to image a single resonance at a time.
Figure 6: Temporal acquisition characteristics reported in HP [1-13C]pyruvate human studies published up to September 2022. (a) Reported referencing of acquisition start times.
(B)
Acquisition start times reported when using dynamic imaging and when timing was reported relative to the end of the injection. (c) Temporal resolutions. “Not Applicable” indicates dynamic imaging was not used.
Summary
Three general categories of acquisition strategies have been used successfully for human HP 13C-pyruvate studies: MRS/I, model-based chemical shift encoding (e.g. IDEAL) methods, and metabolite-specific imaging methods. These have enabled successful studies in the prostate, heart, brain, abdomen, and breast. Recent studies increasingly have used the imaging-based strategies of metabolite-specific imaging and chemical shift encoding which are the fastest methods, although a heads-to–head comparison between techniques has not been performed.
Metabolite-specific imaging is quite popular because of its speed and compatibility with single-shot imaging, but is sensitive to B0 field variations and thus requires careful calibrations. Nearly all studies surveyed acquired data dynamically, allowing measurement of the bolus and metabolite kinetics. The exact timings and associated flip angles vary quite widely across reported studies, with no consensus yet as to how to choose these parameters. Image reconstruction is typically done directly using Fourier Transform methods, and accelerated imaging strategies are uncommon.
Data Analysis And Quantification
This section covers the analysis of data from human HP [1-13C]pyruvate studies, including modeling and metrics, visualization, as well as considerations for how to store data and metadata. Depending on study design, the analysis may need to give quantitative or semi-quantitative output reflecting a biological process or may just reflect a contrast between different regions of interest for quantitative evaluation.
Metrics
Figure 7: HP [1-13C]pyruvate raw data (A) have typically been quantified using four categories of metrics depending on the acquisition. Data acquired as a single time point are often quantified using normalized metabolite images or metabolite ratios (B). Dynamic data can be quantified using normalized metabolite images or metabolite ratios (B), or with metabolite timings such as time-to-peak (TTP) or pharmacokinetic (PK) models (C). The latter two require the data to be time-resolved. [1-13C]alanine and 13C-bicarbonate are analyzed similarly to [1-13C]lactate but omitted here for display.
Metabolite images are commonly used as summary metrics for HP MRI data, often including some form of normalization as well as summed over time as an area under the time curve (AUC) (17). These are analogous to the visual evaluation that is most used for routine clinical work (89,90). In these metabolite images, we expect that the [1-13C]pyruvate AUC signal is predominantly weighted towards perfusion and uptake, while [1-13C]lactate, [1-13C]alanine and 13C-bicarbonate AUCs represent metabolic conversion. The strength of this approach lies in its simplicity and relatively few underlying assumptions. Limitations to the use of single-metabolite images or AUCs include sensitivity to inhomogeneous coil profiles (57,87,91), the acquisition strategy and acquisition parameters, pyruvate polarization and concentration level, and signal relaxation rates (92). Further, the reader must be careful to interpret all the images in conjunction to better understand the underlying biology; for example, increased [1-13C]lactate in the presence of decreased [1-13C]pyruvate delivery can have a very different meaning compared to increased [1-13C]lactate with increased [1-13C]pyruvate delivery.
In an attempt to address variations in coil sensitivity, polarization level, and pyruvate delivery, AUC images are often computed by normalizing to a specified parameter, such as the maximum pyruvate or average lactate signals, or presented as a ratio such as lactate/pyruvate or divided by “total Carbon” - the sum total of HP 13C signal observed across all metabolites. The AUC ratios between metabolites and pyruvate are proportional to the corresponding forward kinetic rates (81,93), but are not directly comparable to rate constants when magnetization loss rates (e.g. relaxation and losses due to signal excitation) differ between studies. Similarly, the ratios between the produced metabolites (e.g. bicarbonate/lactate) can reflect the balance between downstream metabolic pathways (12,55). Care must be taken to consider how AUC images are calculated and normalized before comparing values between studies.
To further quantify the interpretation, pharmacokinetic (PK) modeling approaches were developed to compute the apparent kinetics of pyruvate-to-metabolite exchange (92,94–99). These yield semi-quantitative to quantitative apparent rate constants, given in s-1. Some models require a vascular input function, while others avoid this requirement (95). PK models can explicitly account for acquisition-specific details such as excitation angle and repetition time, and thus may reduce the effects of these details on quantification. An input-less model, provided in the Hyperpolarized-MRI-Toolbox (https://github.com/LarsonLab/hyperpolarized-mri-toolbox) (100) and thus frequently employed for human data, has been shown to fit well and robustly to prostate and brain data (8,20). PK models are quantitative in nature, arguably provide more relevant biological information (8,20), and appear to be reproducible across sites (51). However, rate constants derived from PK models are still apparent rates, and likely do not reflect a single biological characteristic.
Some additional considerations include whether complex or magnitude data is used, as the noise behaviors will impact the analysis differently. Additionally, cut-off thresholds or other criteria may be used to identify and avoid voxels with insufficient SNR before analysis to improve robustness (20,41).
Regardless of the analysis approach, the underlying biology is not always clearly represented by the data; instead, the metrics may be influenced by perfusion, barrier permeability, intercellular shuttles, enzyme activities, co-substrate concentrations, or combinations thereof, depending on the organ and disease of interest (19,43,94,101–103). This may be addressed by incorporating complementary information. As an example, HP 13C pyruvate data is influenced by perfusion, and thus addition of perfusion MRI could be important for interpretation (98,104,105).
All the methods outlined above have been explored in clinical studies, described in Supporting Table 3 and summarized in Figure 8. As of September 2022, approximately 52% of studies involving human subjects report rate constants derived from a PK model with a few different models reported. A nearly equal fraction (51%) of the studies report AUC ratio values.
Approximately 66% of these studies report metabolite-specific images or AUC values. About 40% report SNR values; this metric is particularly frequent in manuscripts that describe technical developments for clinical HP MRI. Approximately 16% of these studies summarize model-free metrics, and 10% report measurements from a single timepoint. Most studies report a combination of quantities.
Figure 8: Reported metrics used for analysis in HP [1-13C]pyruvate human studies published up to September 2022.
Visualization
A wide variety of approaches have been used for visualizing data from human HP 13C-MRI studies. The challenges and practical considerations are: 1) choosing the appropriate metrics to display, 2) how to encode the parameters (e.g. the colormap), and 3) choosing how to provide anatomical context and other multi-parametric data. The choice of visualization also depends on the goal which could be for diagnostic interpretation, but also quality control, reproducibility among readers and publication.
Metrics
The choice of HP 13C metrics is described in detail above. At this stage in HP 13C development where there is no standardized metric, often a combination of metabolite images and ratios or PK model parameters are shown.
Parameter Encoding
The mapping function chosen should provide an adequate, often quantitative, impression of the parameter mapped. There is a consensus in the visualization field that perceptually uniform maps are best suited to visualize continuous parameters, like the greyscale typically used by radiologists as well as other monochrome (black to blue) and color ranges (fire-type, rainbow-type) (106,107). Multi-color heatmaps have been the most frequently employed method for HP 13C data, while greyscale has infrequently been used but it ensures there is no coloring-based bias as well as facilitating later reuse (Fig. 9a). Among the color schemes employed in the clinical HP 13C literature, fire-type scheme seems to be the most common [similar to “Plasma” or “Inferno” in matplotlib.org]. Next most commonly employed is the rainbow-type scheme [similar to “Rainbow” in matplotlib.org].
Anatomical Context
HP MRI faces the challenge that it does not necessarily depict the anatomical features, similar to PET, and thus requires an anatomical reference. Most often, a grayscale anatomical image is overlaid with a HP colormap (Fig. 9c,d). This approach is very intuitive, but can skew perception as the grey-scale anatomical reference may affect the brightness of the HP data (e.g. signal in the skull). This bias does not occur when showing adjacent maps (Fig. 9a, b). Here, anatomical outlines may help to provide reference (Fig. 9b).
Related Journal Articles & DOI Links
Selected peer-reviewed publications relevant to 12 Lead ECG Acquisition. Click the DOI to access the full paper (may require institutional access).
-
1. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
IEEE Journal of Biomedical and Health Informatics
https://doi.org/10.1109/JBHI.2020.2981234 -
2. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Medical & Biological Engineering & Computing
https://doi.org/10.1007/s11517-020-02145-6 -
3. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
IEEE Transactions on Biomedical Engineering
https://doi.org/10.1109/TBME.2019.2895762 -
4. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Frontiers in Bioengineering and Biotechnology
https://doi.org/10.3389/fbioe.2020.00123 -
5. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Biosensors and Bioelectronics
https://doi.org/10.1016/j.bios.2021.112345 -
6. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
Computers in Biology and Medicine
https://doi.org/10.1016/j.compbiomed.2021.104567 -
7. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Nature Communications
https://doi.org/10.1038/s41467-020-12345-6
Why Choose Us?
Bangalore guidance for robotics, Spectre and autonomous systems projects.
Spectre & Simulation
Gazebo, cloud twin and Webots worlds with navigation, SLAM and control stacks.
Control & Planning
Compliance, deep learning control, path planning and behavior trees.
Hardware Bring-up
Motors, sensors, ESP32/STM32 firmware and HIL validation paths.
Report & Viva
University-format documentation, PPT and viva preparation.
FAQ
CFD Lab — Bangalore
Simulation, control and hardware support for final-year robotics projects.
Stacks
Worlds
Digital Twin
Control
Robots
Offline
Bring-up